
The official repo for the paper "VeCLIP: Improving CLIP Training via Visual-enriched Captions"
Jupyter Notebook
256
15 commits
updated Sep 11, 2026
README
[ECCV-2024] VeCLIP: Improving CLIP Training via Visual-enriched Captions
- A novel CLIP training scheme that achieves the SoTA performance on zero-shot ImageNet classification and COCO image text retreival using limited visual-enriched captions. * [Paper]
Zhengfeng Lai*, Haotian Zhang* , Bowen Zhang, Wentao Wu, Haoping Bai, Aleksei Timofeev, Xianzhi Du, Zhe Gan, Jiulong Shan, Chen-Nee Chuah, Yinfei Yang, Meng Cao [*: equal contribution]
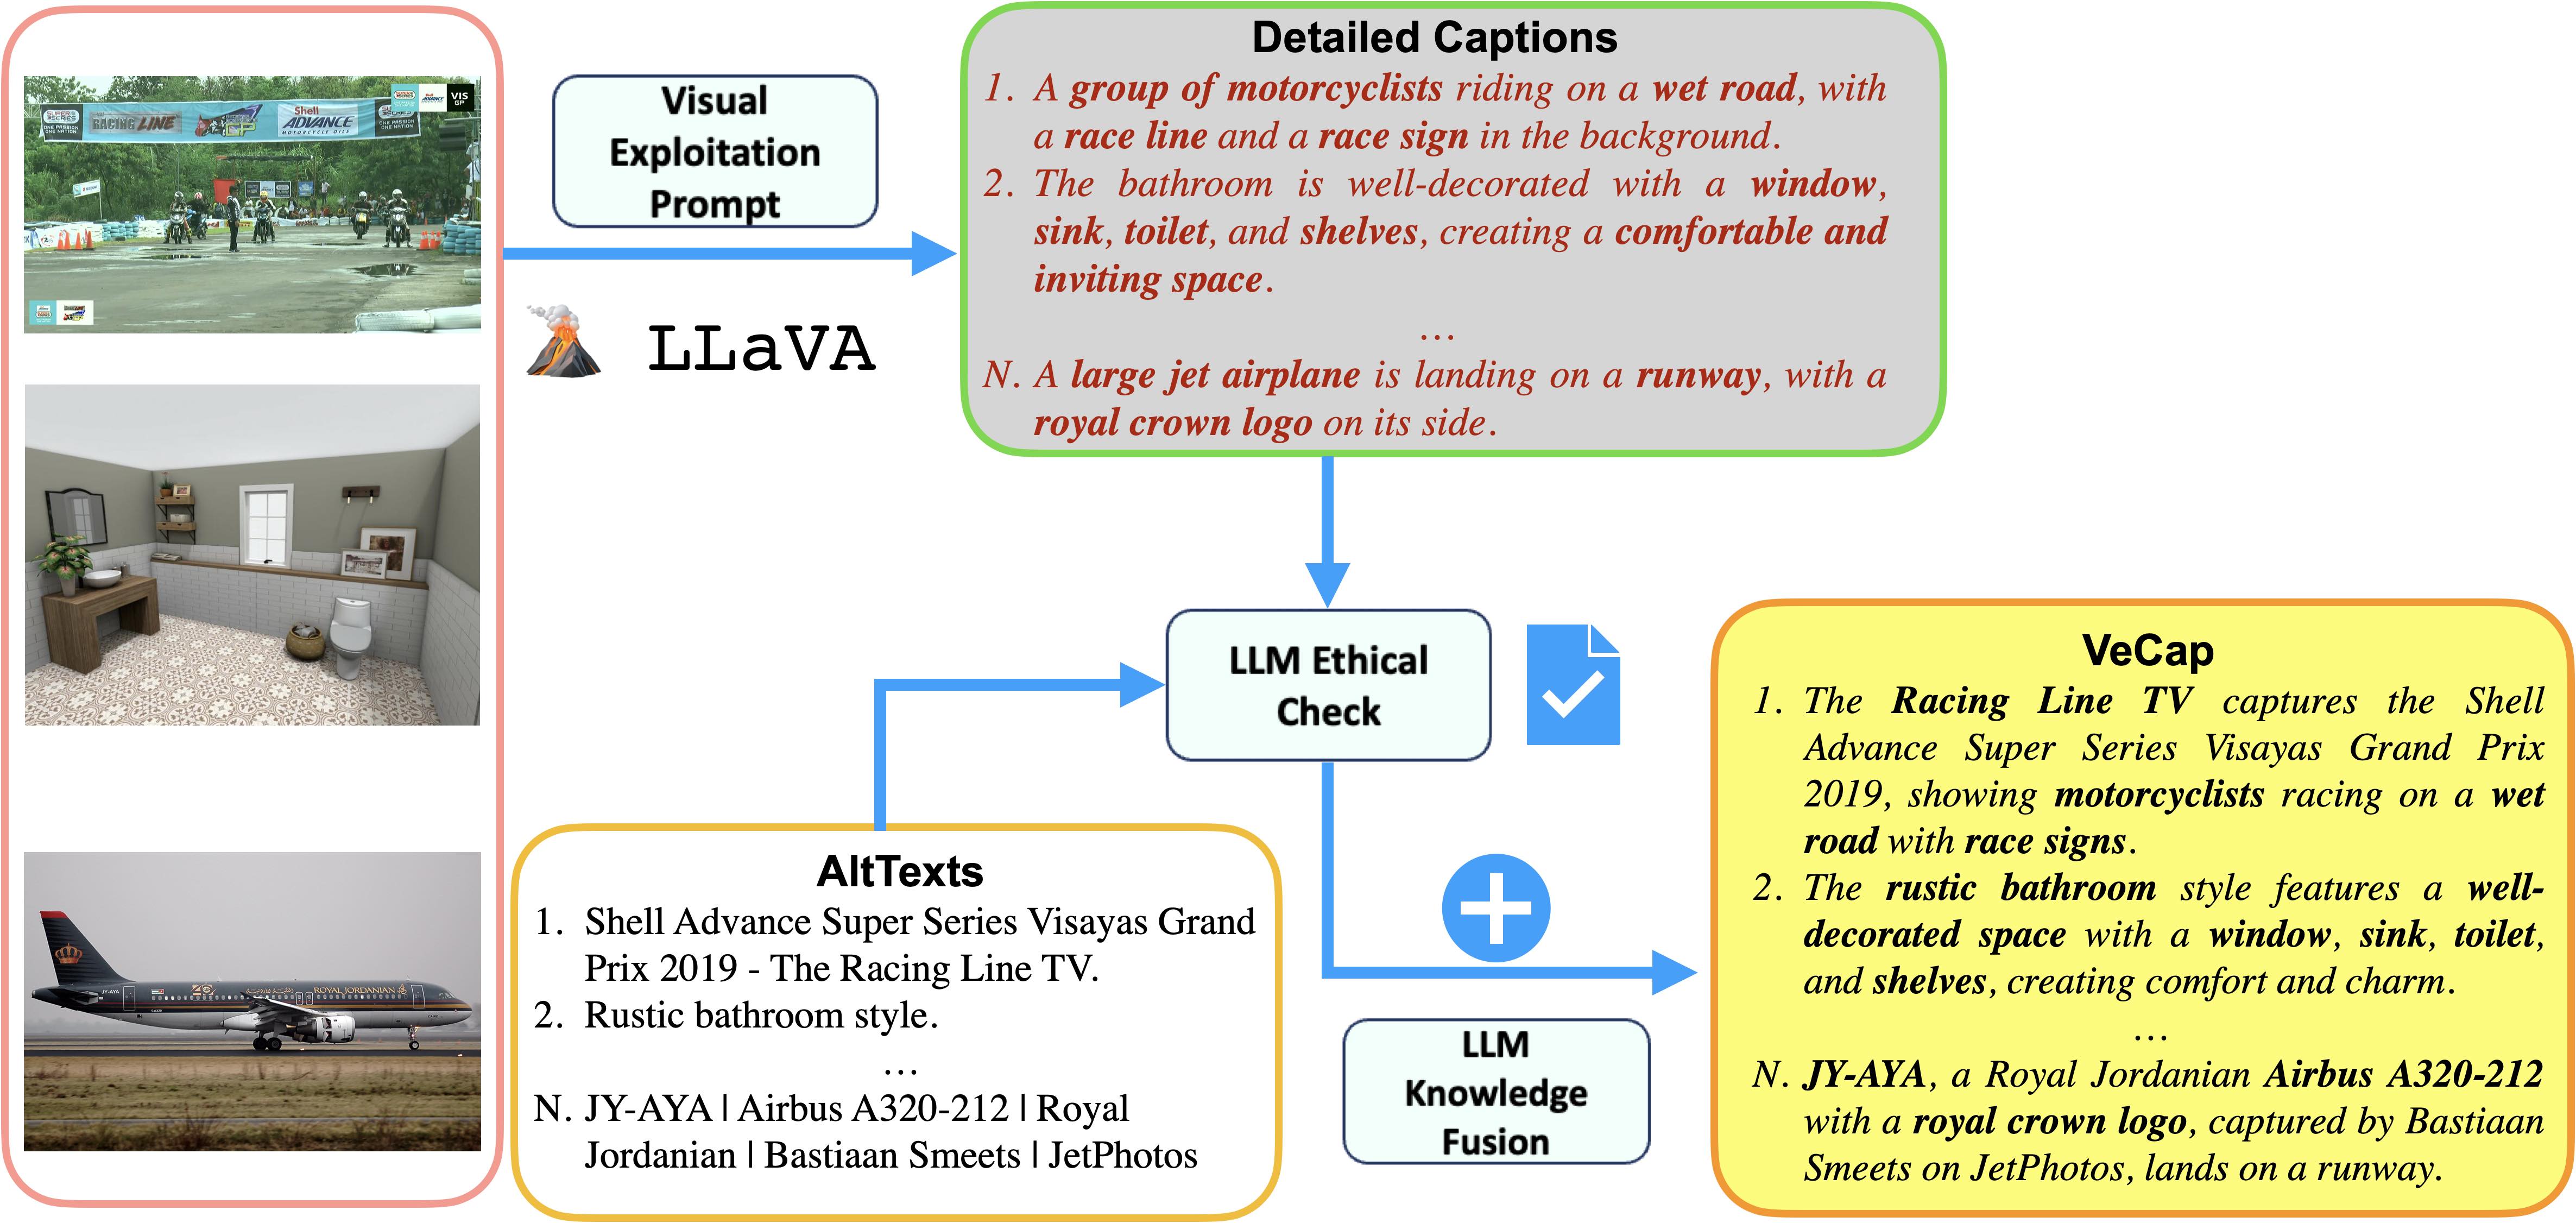
Diagram of VeCap.
Release
- [10/03/2024] 🔥🔥🔥 We release VeCap-V2: Revisit Large-Scale Image-Caption Data in Pre-training Multimodal Foundation Models.
- [08/23/2024] 🔥🔥🔥 We release our VeCap-300M dataset.
- [07/01/2024] 🔥 Our paper is accepted by ECCV 2024.
- [03/06/2024] 🔥 We released the VeCLIP & VeCap-DFN checkpoints.
Contents
Install
- Clone this repository
git clone https://github.com/apple/ml-veclip
cd ml-veclip
- Create an environment and install related packages
conda create -n veclip python=3.9 -y
conda activate veclip
pip install -r requirements.txt
Getting Started
See the example notebook for details on how to simply load the different checkpoints using HuggingFace transformers.
VeCap-300M Download
We split our 300M data into 10 jsons: for each image, we save the web link and our caption.
wget -i vecap300m.txt -b -c
Checkpoints
We release the checkpoints for VeCLIP, which are trained from scratch on visual-enriched captions VeCap 3M/12M/100M/200M/300M, as reported in the paper. The models are evaluated on COCO/Flickr30k image-text retrieval and ImageNet/ImageNetv2 classification in a zero-shot fashion. Use wget or curl to download the below checkpoints.
| Data | Model | Resolution | COCO (R@1) | Flickr30k (R@1) | ImageNet | ImageNetv2 | ||
|---|---|---|---|---|---|---|---|---|
| I2T | T2I | I2T | T2I | |||||
| VeCap 3M | CLIP-B/16 | 224x224 | 5.46 | 3.28 | 12.20 | 6.36 | 5.46 | 7.09 |
| VeCLIP-B/16 | 224x224 | 22.30 | 13.01 | 40.60 | 27.58 | 15.98 | 13.51 | |
| VeCap 12M | CLIP-B/16 | 224x224 | 24.52 | 14.28 | 44.70 | 290.6 | 31.60 | 27.03 |
| VeCLIP-B/16 | 224x224 | 47.78 | 31.62 | 73.90 | 55.68 | 38.11 | 32.53 | |
| VeCap 100M | CLIP-B/16 | 224x224 | 47.24 | 30.61 | 74.40 | 57.16 | 58.64 | 50.96 |
| VeCLIP-B/16 | 224x224 | 64.82 | 46.12 | 89.30 | 73.10 | 60.77 | 54.17 | |
| VeCap 200M | CLIP-B/16 | 224x224 | 52.20 | 34.97 | 80.90 | 63.26 | 63.72 | 56.84 |
| VeCLIP-B/16 | 224x224 | 67.20 | 48.40 | 91.10 | 76.32 | 64.64 | 57.67 | |
We further found our VeCap can also be complementary to other well-established filtering methods, e.g., Data Filtering Network (DFN). We also provide thosse checkpoints (referred to as VeCap-DFN) and report their performance below.
| Backbone | Resolution | Data | COCO (R@1) | Flickr30k (R@1) | ImageNet | ImageNetV2 | ||
|---|---|---|---|---|---|---|---|---|
| I2T | T2I | I2T | T2I | |||||
| VeCap-DFN-B/16 | 224x224 | DFN | 62.96 | 43.20 | 87.10 | 70.44 | 76.15 | 68.19 |
| VeCap 300M | 64.74 | 44.58 | 90.10 | 73.14 | 46.43 | 41.15 | ||
| DFN + VeCap 300M | 66.28 | 45.12 | 88.80 | 73.56 | 76.19 | 69.58 | ||
| VeCap-DFN-L/14 | 224x224 | DFN + VeCap 300M | 71.06 | 51.13 | 93.10 | 80.96 | 81.95 | 75.48 |
| VeCap-DFN-H/14 | 336x336 | DFN + VeCap 300M | 72.78 | 52.33 | 93.60 | 82.64 | 83.07 | 76.37 |
Citation
If you find VeCLIP useful, please cite using this BibTeX:
@misc{lai2024veclip,
      title={VeCLIP: Improving CLIP Training via Visual-enriched Captions},
      author={Zhengfeng Lai and Haotian Zhang and Bowen Zhang and Wentao Wu and Haoping Bai and Aleksei Timofeev and Xianzhi Du and Zhe Gan and Jiulong Shan and Chen-Nee Chuah and Yinfei Yang and Meng Cao},
      year={2024},
      eprint={2310.07699},
      archivePrefix={arXiv},
      primaryClass={cs.CV}
}
@misc{lai2024revisitlargescaleimagecaptiondata,
      title={Revisit Large-Scale Image-Caption Data in Pre-training Multimodal Foundation Models},
      author={Zhengfeng Lai and Vasileios Saveris and Chen Chen and Hong-You Chen and Haotian Zhang and Bowen Zhang and Juan Lao Tebar and Wenze Hu and Zhe Gan and Peter Grasch and Meng Cao and Yinfei Yang},
      year={2024},
      eprint={2410.02740},
      archivePrefix={arXiv},
      primaryClass={cs.CV},
      url={https://arxiv.org/abs/2410.02740},
}
@article{fang2023data,
  title={Data filtering networks},
  author={Fang, Alex and Jose, Albin Madappally and Jain, Amit and Schmidt, Ludwig and Toshev, Alexander and Shankar, Vaishaal},
  journal={arXiv preprint arXiv:2309.17425},
  year={2023}
}
Acknowledgement
- axlearn: the codebase we use to train the models.
- huggingface transformers: Transformers provides APIs to load our trained models.
Significant stargazers

30 followers · starred Mar 2024

175 followers · starred Mar 2024
Similar repos


Languages
Jupyter Notebook
99.7%
The official repo for the paper "VeCLIP: Improving CLIP Training via Visual-enriched Captions"
Jupyter Notebook
256
15 commits
updated Sep 11, 2026
README
[ECCV-2024] VeCLIP: Improving CLIP Training via Visual-enriched Captions
- A novel CLIP training scheme that achieves the SoTA performance on zero-shot ImageNet classification and COCO image text retreival using limited visual-enriched captions. * [Paper]
Zhengfeng Lai*, Haotian Zhang* , Bowen Zhang, Wentao Wu, Haoping Bai, Aleksei Timofeev, Xianzhi Du, Zhe Gan, Jiulong Shan, Chen-Nee Chuah, Yinfei Yang, Meng Cao [*: equal contribution]
Diagram of VeCap.
Release
- [10/03/2024] 🔥🔥🔥 We release VeCap-V2: Revisit Large-Scale Image-Caption Data in Pre-training Multimodal Foundation Models.
- [08/23/2024] 🔥🔥🔥 We release our VeCap-300M dataset.
- [07/01/2024] 🔥 Our paper is accepted by ECCV 2024.
- [03/06/2024] 🔥 We released the VeCLIP & VeCap-DFN checkpoints.
Contents
Install
- Clone this repository
git clone https://github.com/apple/ml-veclip
cd ml-veclip
- Create an environment and install related packages
conda create -n veclip python=3.9 -y
conda activate veclip
pip install -r requirements.txt
Getting Started
See the example notebook for details on how to simply load the different checkpoints using HuggingFace transformers.
VeCap-300M Download
We split our 300M data into 10 jsons: for each image, we save the web link and our caption.
wget -i vecap300m.txt -b -c
Checkpoints
We release the checkpoints for VeCLIP, which are trained from scratch on visual-enriched captions VeCap 3M/12M/100M/200M/300M, as reported in the paper. The models are evaluated on COCO/Flickr30k image-text retrieval and ImageNet/ImageNetv2 classification in a zero-shot fashion. Use wget or curl to download the below checkpoints.
| Data | Model | Resolution | COCO (R@1) | Flickr30k (R@1) | ImageNet | ImageNetv2 | ||
|---|---|---|---|---|---|---|---|---|
| I2T | T2I | I2T | T2I | |||||
| VeCap 3M | CLIP-B/16 | 224x224 | 5.46 | 3.28 | 12.20 | 6.36 | 5.46 | 7.09 |
| VeCLIP-B/16 | 224x224 | 22.30 | 13.01 | 40.60 | 27.58 | 15.98 | 13.51 | |
| VeCap 12M | CLIP-B/16 | 224x224 | 24.52 | 14.28 | 44.70 | 290.6 | 31.60 | 27.03 |
| VeCLIP-B/16 | 224x224 | 47.78 | 31.62 | 73.90 | 55.68 | 38.11 | 32.53 | |
| VeCap 100M | CLIP-B/16 | 224x224 | 47.24 | 30.61 | 74.40 | 57.16 | 58.64 | 50.96 |
| VeCLIP-B/16 | 224x224 | 64.82 | 46.12 | 89.30 | 73.10 | 60.77 | 54.17 | |
| VeCap 200M | CLIP-B/16 | 224x224 | 52.20 | 34.97 | 80.90 | 63.26 | 63.72 | 56.84 |
| VeCLIP-B/16 | 224x224 | 67.20 | 48.40 | 91.10 | 76.32 | 64.64 | 57.67 | |
We further found our VeCap can also be complementary to other well-established filtering methods, e.g., Data Filtering Network (DFN). We also provide thosse checkpoints (referred to as VeCap-DFN) and report their performance below.
| Backbone | Resolution | Data | COCO (R@1) | Flickr30k (R@1) | ImageNet | ImageNetV2 | ||
|---|---|---|---|---|---|---|---|---|
| I2T | T2I | I2T | T2I | |||||
| VeCap-DFN-B/16 | 224x224 | DFN | 62.96 | 43.20 | 87.10 | 70.44 | 76.15 | 68.19 |
| VeCap 300M | 64.74 | 44.58 | 90.10 | 73.14 | 46.43 | 41.15 | ||
| DFN + VeCap 300M | 66.28 | 45.12 | 88.80 | 73.56 | 76.19 | 69.58 | ||
| VeCap-DFN-L/14 | 224x224 | DFN + VeCap 300M | 71.06 | 51.13 | 93.10 | 80.96 | 81.95 | 75.48 |
| VeCap-DFN-H/14 | 336x336 | DFN + VeCap 300M | 72.78 | 52.33 | 93.60 | 82.64 | 83.07 | 76.37 |
Citation
If you find VeCLIP useful, please cite using this BibTeX:
@misc{lai2024veclip,
      title={VeCLIP: Improving CLIP Training via Visual-enriched Captions},
      author={Zhengfeng Lai and Haotian Zhang and Bowen Zhang and Wentao Wu and Haoping Bai and Aleksei Timofeev and Xianzhi Du and Zhe Gan and Jiulong Shan and Chen-Nee Chuah and Yinfei Yang and Meng Cao},
      year={2024},
      eprint={2310.07699},
      archivePrefix={arXiv},
      primaryClass={cs.CV}
}
@misc{lai2024revisitlargescaleimagecaptiondata,
      title={Revisit Large-Scale Image-Caption Data in Pre-training Multimodal Foundation Models},
      author={Zhengfeng Lai and Vasileios Saveris and Chen Chen and Hong-You Chen and Haotian Zhang and Bowen Zhang and Juan Lao Tebar and Wenze Hu and Zhe Gan and Peter Grasch and Meng Cao and Yinfei Yang},
      year={2024},
      eprint={2410.02740},
      archivePrefix={arXiv},
      primaryClass={cs.CV},
      url={https://arxiv.org/abs/2410.02740},
}
@article{fang2023data,
  title={Data filtering networks},
  author={Fang, Alex and Jose, Albin Madappally and Jain, Amit and Schmidt, Ludwig and Toshev, Alexander and Shankar, Vaishaal},
  journal={arXiv preprint arXiv:2309.17425},
  year={2023}
}
Acknowledgement
- axlearn: the codebase we use to train the models.
- huggingface transformers: Transformers provides APIs to load our trained models.
Similar repos
Significant stargazers
30 followers · starred Mar 2024
175 followers · starred Mar 2024
Languages
Jupyter Notebook
99.7%