
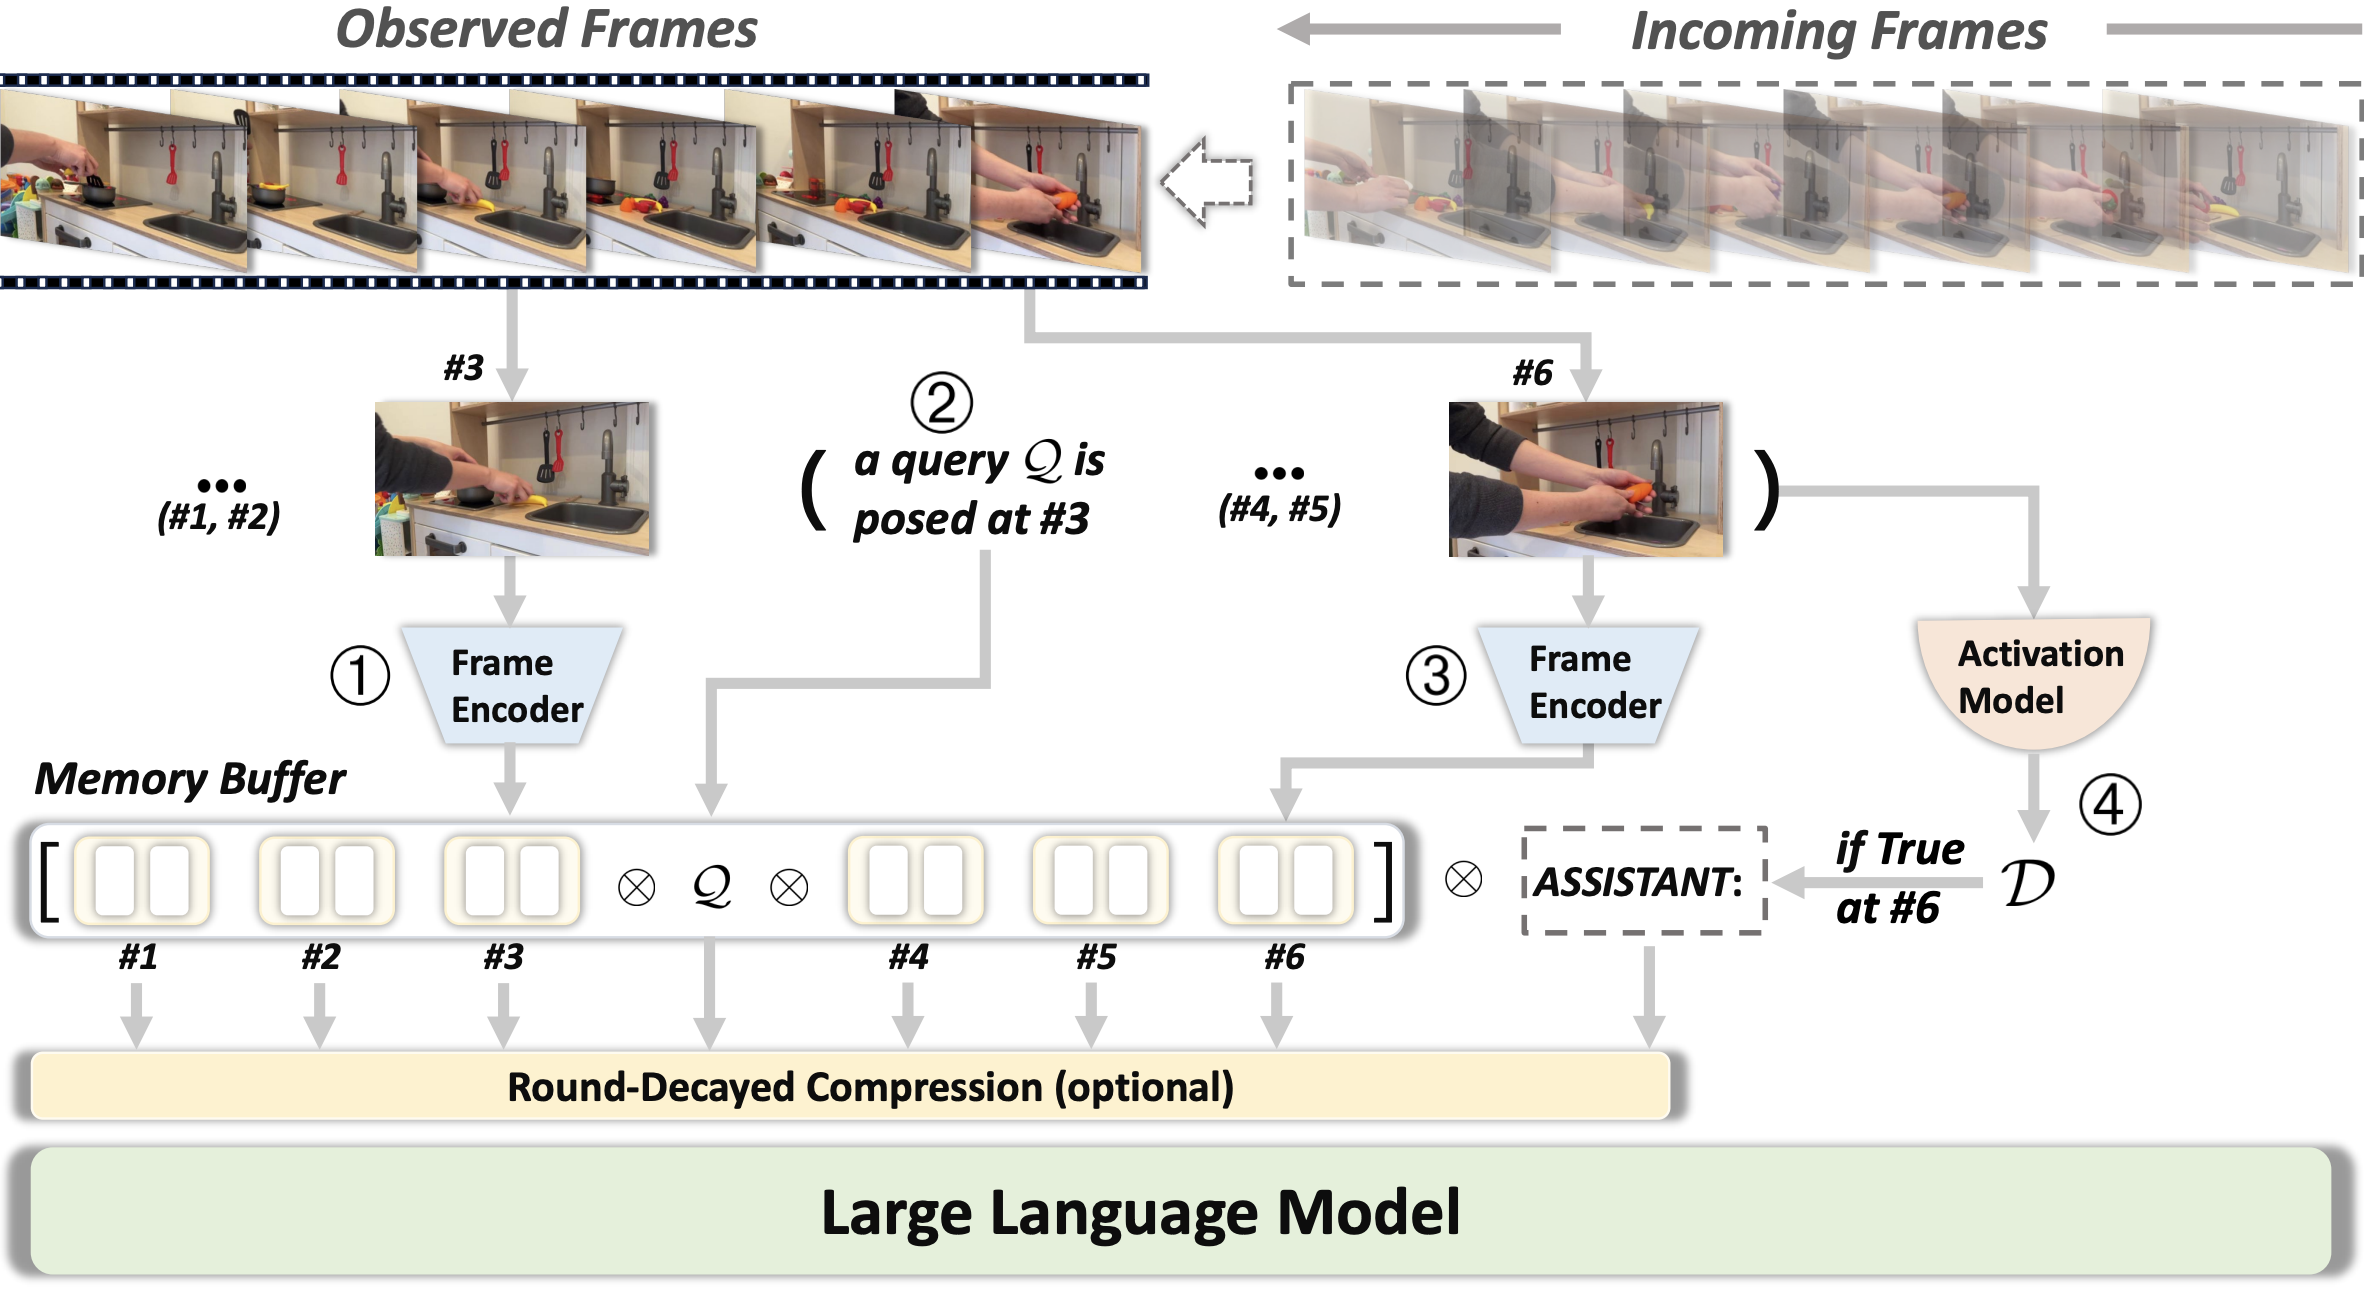
🌟 StreamBridge is a simple yet powerful framework that enables offline Video-LLMs to perform effectively in streaming scenarios. It features:
[!IMPORTANT] For copyright reasons, we can’t release model weights trained on YouTube or other videos that may contain IP-protected content. However, we’re open-sourcing the model implementation and the synthetic data used for training.
git clone https://github.com/apple/ml-streambridge
cd ml-streambridge
conda create -n ml-streambridge python=3.10.14
conda activate ml-streambridge
pip install -e .
pip install flash-attn==2.3.3 --no-build-isolation
├── /your/path/to/checkpoints
│   └── llava-onevision-qwen2-0.5b-ov-hf-seperated
│   └── activation_0.5_ratio_anet_coin_yc2_s2s_fa_mhego_hacs_cha_et_llava-ov_epoch_5.pth
│   └── LLaVA-OV-7B-du2e2hjxik
│   └── Oryx-1.5-7B-jfsvkb3hn8
│   └── Qwen2-VL-7B-jh6p673iyp
your_weight_path in demo.py to match the weight directory above:python demo.py # activation threshold is set for the response frequency
18 seconds:  Pour the cooked noodles.
32 seconds:  Cut the lemon.
44 seconds:  Cut the olives in half.
55 seconds:  Chop the parsley.
68 seconds:  Squeeze the lemon juice into the measuring cup.
78 seconds:  Pound the chicken.
...
├── /your/path/to/ovo_bench
│   └── videos
│   └── ovo_bench.json
│   └── ...
├── /your/path/to/videomme
│   └── videos
│   └── videomme.json
│   └── ...
ovo_bench.json and VideoMME's videomme.json in ./assets.ANNO_PATH and VIDEO_PATH in scripts/eval.sh for the OVO-Bench and VideoMME you download above, and then run:bash scripts/eval.sh
MODEL and CKPT in the script.NUM_GPUS and MAX_IMG_TOKEN to reduce memory usage.python eval/metric_report.py
| Model Name | OVO-Bench-Real-Time (OCR/ACR/ATR/STU/FPD/OJR/AVG.) | VideoMME (w/o subs) |
|---|---|---|
| Qwen2-VL-StreamBridge | 85.24/67.89/75.00/52.25/70.30/72.28/70.49 | 63.0 |
| Oryx-1.5-StreamBridge | 81.21/70.64/70.69/49.44/74.26/68.48/69.12 | 64.2 |
| LLaVA-OV-StreamBridge | 74.50/78.90/72.41/52.81/78.22/68.68/70.89 | 61.0 |
GROUP_LEN:import json
def load_json(path):
with open(path) as f:
data = json.load(f)
return data
GROUP_LEN = 10
anns = load_json("/your/path/to/qa_groups.json")
groups = [i for i in range(len(anns))]
groups = [groups[i : i + GROUP_LEN] for i in range(0, len(groups), GROUP_LEN)]
grouped_anns = []
for group in groups:
if len(group) != GROUP_LEN:
continue
grouped_anns.append(
{
"video_ids": [anns[i]["video_id"] for i in group],
"video_files": [anns[i]["video_file"] for i in group],
"captions": [anns[i]["caption"] for i in group],
"questions": [anns[i]["question"] for i in group],
"answers": [anns[i]["answer"] for i in group],
"options": [anns[i]["options"] for i in group],
"types": [anns[i]["type"] for i in group],
}
)
print(grouped_anns[0])
This software and accompanying data and models have been released under the following licenses:
If you find our paper and code useful in your research, please consider giving a star ⭐ and citation 📝.
@article{wang2025streambridge,
  title={StreamBridge: Turning Your Offline Video Large Language Model into a Proactive Streaming Assistant},
  author={Wang, Haibo and Feng, Bo and Lai, Zhengfeng and Xu, Mingze and Li, Shiyu and Ge, Weifeng and Dehghan, Afshin and Cao, Meng and Huang, Ping},
  journal={arXiv preprint arXiv:2505.05467},
  year={2025}
}



