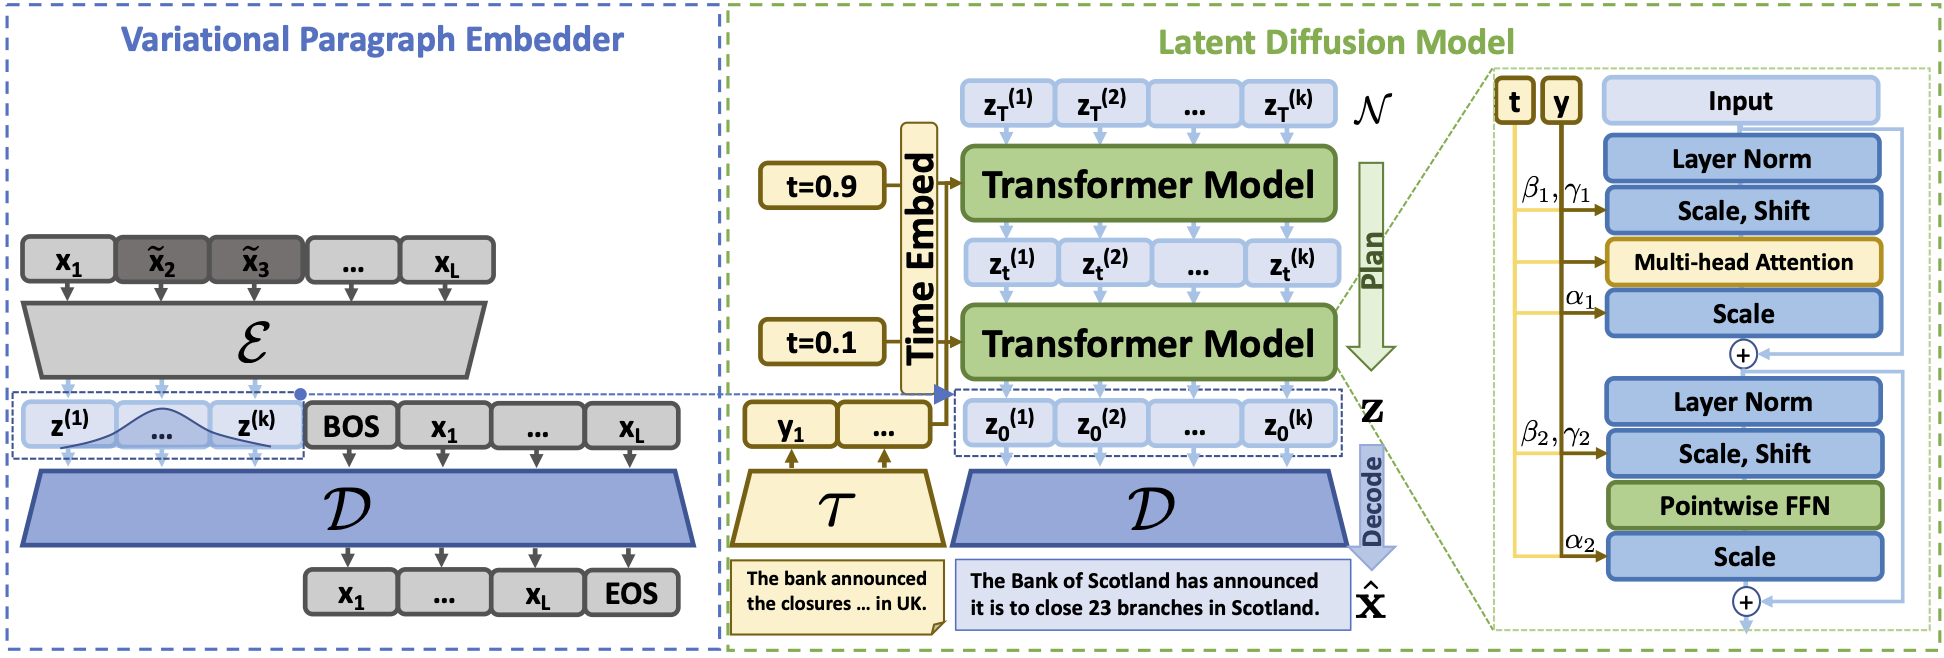
This software project accompanies the research paper, PLANNER: Generating Diversified Paragraph via Latent Language Diffusion Model, published on NeurIPS 2023.
For further information, you can refer to our research highlight post on the latent language diffusion model.
Please generally follow the setup command in below.
bash setup.sh
This step involves tokenizing the dataset in a specified folder that contains .json files, and then saving it into a folder parsed_raw_pre containing three .pt files of train, dev and test.
python text_autoencoder/prepro.py --corpus data-bin/dummy_data
See examples for training a variational paragraph embedder in below.
bash ./bash/ae/run_ae.sh
/autoencoder/train.py Script:--seed: Seed for random number generation.--lr, --enc_lr, --dec_lr: Initial learning rates for the overall model, encoder, and decoder, respectively.--epochs: Number of training epochs.--batch_size: Batch size for training.--valid_size: Size of the validation set.--lr_decay_interval: Interval (in epochs) for learning rate decay.--dropout: Dropout ratio to prevent overfitting.--gradient_accumulation_steps: Number of steps for gradient accumulation.--enc_model: Encoder model to be used (bert-large-uncased, google/flan-t5-xl, etc.).--dec_model: Decoder model (gpt2-medium, gpt2-large, etc.).--latent_size: Size of the latent variable.--n_head: Size of the attention head.--num_layer: Number of layers in the model.--save_dir: Directory path where model snapshots are saved.--train_pt_dir, --dev_pt_dir: Paths for training and development data.--resume_ckpt: Path to resume training from a specific checkpoint.--exp_name: Name of the experiment.--out_layer: Last layer choice for deconvolution (pred_token, pred_emb, lm_head).--reg_layer: Regularization layer (bn, ln, none).--embed_dim: Number of embedding dimensions.--filter_size: Filter size for convolution.--filter_shape: Shape of the filter to use for convolution.--tau: Temperature parameter for training.--noiser, --noiser_ratio: Noise type and ratio for data corruption.--h_noiser, --h_noiser_ratio: Hidden noise type and ratio.--world_size: Total number of distributed processes.--gpus: Number of GPUs to use.Again, .pt files of train, dev and test need to be created for the (source, target) dataset. For example, for creating a dataset for summarization. First concatenate the document and summary into single tsv files by
cd data-bin/dummy_sum_data
for file in *.document; do
    base=$(basename "$file" .document)
    if [[ -e "$base.summary" ]]; then
        paste "$base.document" "$base.summary" > "$base.txt"
    fi
done
cd -
Then run the following command:
python text_autoencoder/prepro_ground.py --corpus ./data-bin/dummy_sum_data/
This will create three folders (train,dev,test) under data-bin/dummy_sum_data/parsed_raw_pre.
bash ./bash/diffusion/run_diffusion.sh
bash ./bash/diffusion/pipeline_cond_gen.sh
Please consider citing our work if it is helpful to your research.
@inproceedings{zhang2023planner,
  title={PLANNER: Generating Diversified Paragraph via Latent Language Diffusion Model},
  author={Zhang, Yizhe and Gu, Jiatao and Wu, Zhuofeng and Zhai, Shuangfei and Susskind, Josh and Jaitly, Navdeep},
  booktitle = {NeurIPS},
  year={2023}
}
**PLANNER** poster for NeurIPS 2023.
102 followers · starred Oct 2025
546 followers · starred Mar 2024
This software project accompanies the research paper, PLANNER: Generating Diversified Paragraph via Latent Language Diffusion Model, published on NeurIPS 2023.
For further information, you can refer to our research highlight post on the latent language diffusion model.
Please generally follow the setup command in below.
bash setup.sh
This step involves tokenizing the dataset in a specified folder that contains .json files, and then saving it into a folder parsed_raw_pre containing three .pt files of train, dev and test.
python text_autoencoder/prepro.py --corpus data-bin/dummy_data
See examples for training a variational paragraph embedder in below.
bash ./bash/ae/run_ae.sh
/autoencoder/train.py Script:--seed: Seed for random number generation.--lr, --enc_lr, --dec_lr: Initial learning rates for the overall model, encoder, and decoder, respectively.--epochs: Number of training epochs.--batch_size: Batch size for training.--valid_size: Size of the validation set.--lr_decay_interval: Interval (in epochs) for learning rate decay.--dropout: Dropout ratio to prevent overfitting.--gradient_accumulation_steps: Number of steps for gradient accumulation.--enc_model: Encoder model to be used (bert-large-uncased, google/flan-t5-xl, etc.).--dec_model: Decoder model (gpt2-medium, gpt2-large, etc.).--latent_size: Size of the latent variable.--n_head: Size of the attention head.--num_layer: Number of layers in the model.--save_dir: Directory path where model snapshots are saved.--train_pt_dir, --dev_pt_dir: Paths for training and development data.--resume_ckpt: Path to resume training from a specific checkpoint.--exp_name: Name of the experiment.--out_layer: Last layer choice for deconvolution (pred_token, pred_emb, lm_head).--reg_layer: Regularization layer (bn, ln, none).--embed_dim: Number of embedding dimensions.--filter_size: Filter size for convolution.--filter_shape: Shape of the filter to use for convolution.--tau: Temperature parameter for training.--noiser, --noiser_ratio: Noise type and ratio for data corruption.--h_noiser, --h_noiser_ratio: Hidden noise type and ratio.--world_size: Total number of distributed processes.--gpus: Number of GPUs to use.Again, .pt files of train, dev and test need to be created for the (source, target) dataset. For example, for creating a dataset for summarization. First concatenate the document and summary into single tsv files by
cd data-bin/dummy_sum_data
for file in *.document; do
    base=$(basename "$file" .document)
    if [[ -e "$base.summary" ]]; then
        paste "$base.document" "$base.summary" > "$base.txt"
    fi
done
cd -
Then run the following command:
python text_autoencoder/prepro_ground.py --corpus ./data-bin/dummy_sum_data/
This will create three folders (train,dev,test) under data-bin/dummy_sum_data/parsed_raw_pre.
bash ./bash/diffusion/run_diffusion.sh
bash ./bash/diffusion/pipeline_cond_gen.sh
Please consider citing our work if it is helpful to your research.
@inproceedings{zhang2023planner,
  title={PLANNER: Generating Diversified Paragraph via Latent Language Diffusion Model},
  author={Zhang, Yizhe and Gu, Jiatao and Wu, Zhuofeng and Zhai, Shuangfei and Susskind, Josh and Jaitly, Navdeep},
  booktitle = {NeurIPS},
  year={2023}
}
**PLANNER** poster for NeurIPS 2023.
102 followers · starred Oct 2025
546 followers · starred Mar 2024



