Amundsen is a metadata driven application for improving the productivity of data analysts, data scientists and engineers when interacting with data.
Python
4,785
2,514 commits
updated Sep 10, 2026


Amundsen is a data discovery and metadata engine for improving the productivity of data analysts, data scientists and engineers when interacting with data. It does that today by indexing data resources (tables, dashboards, streams, etc.) and powering a page-rank style search based on usage patterns (e.g. highly queried tables show up earlier than less queried tables). Think of it as Google search for data. The project is named after Norwegian explorer Roald Amundsen, the first person to discover the South Pole.
Amundsen is hosted by the LF AI & Data Foundation. It includes three microservices, one data ingestion library and one common library.


We want your input about what is important, for that, add your votes using the 👍 reaction:
Please note that the mock images only served as demonstration purpose.
Landing Page: The landing page for Amundsen including 1. search bars; 2. popular used tables;
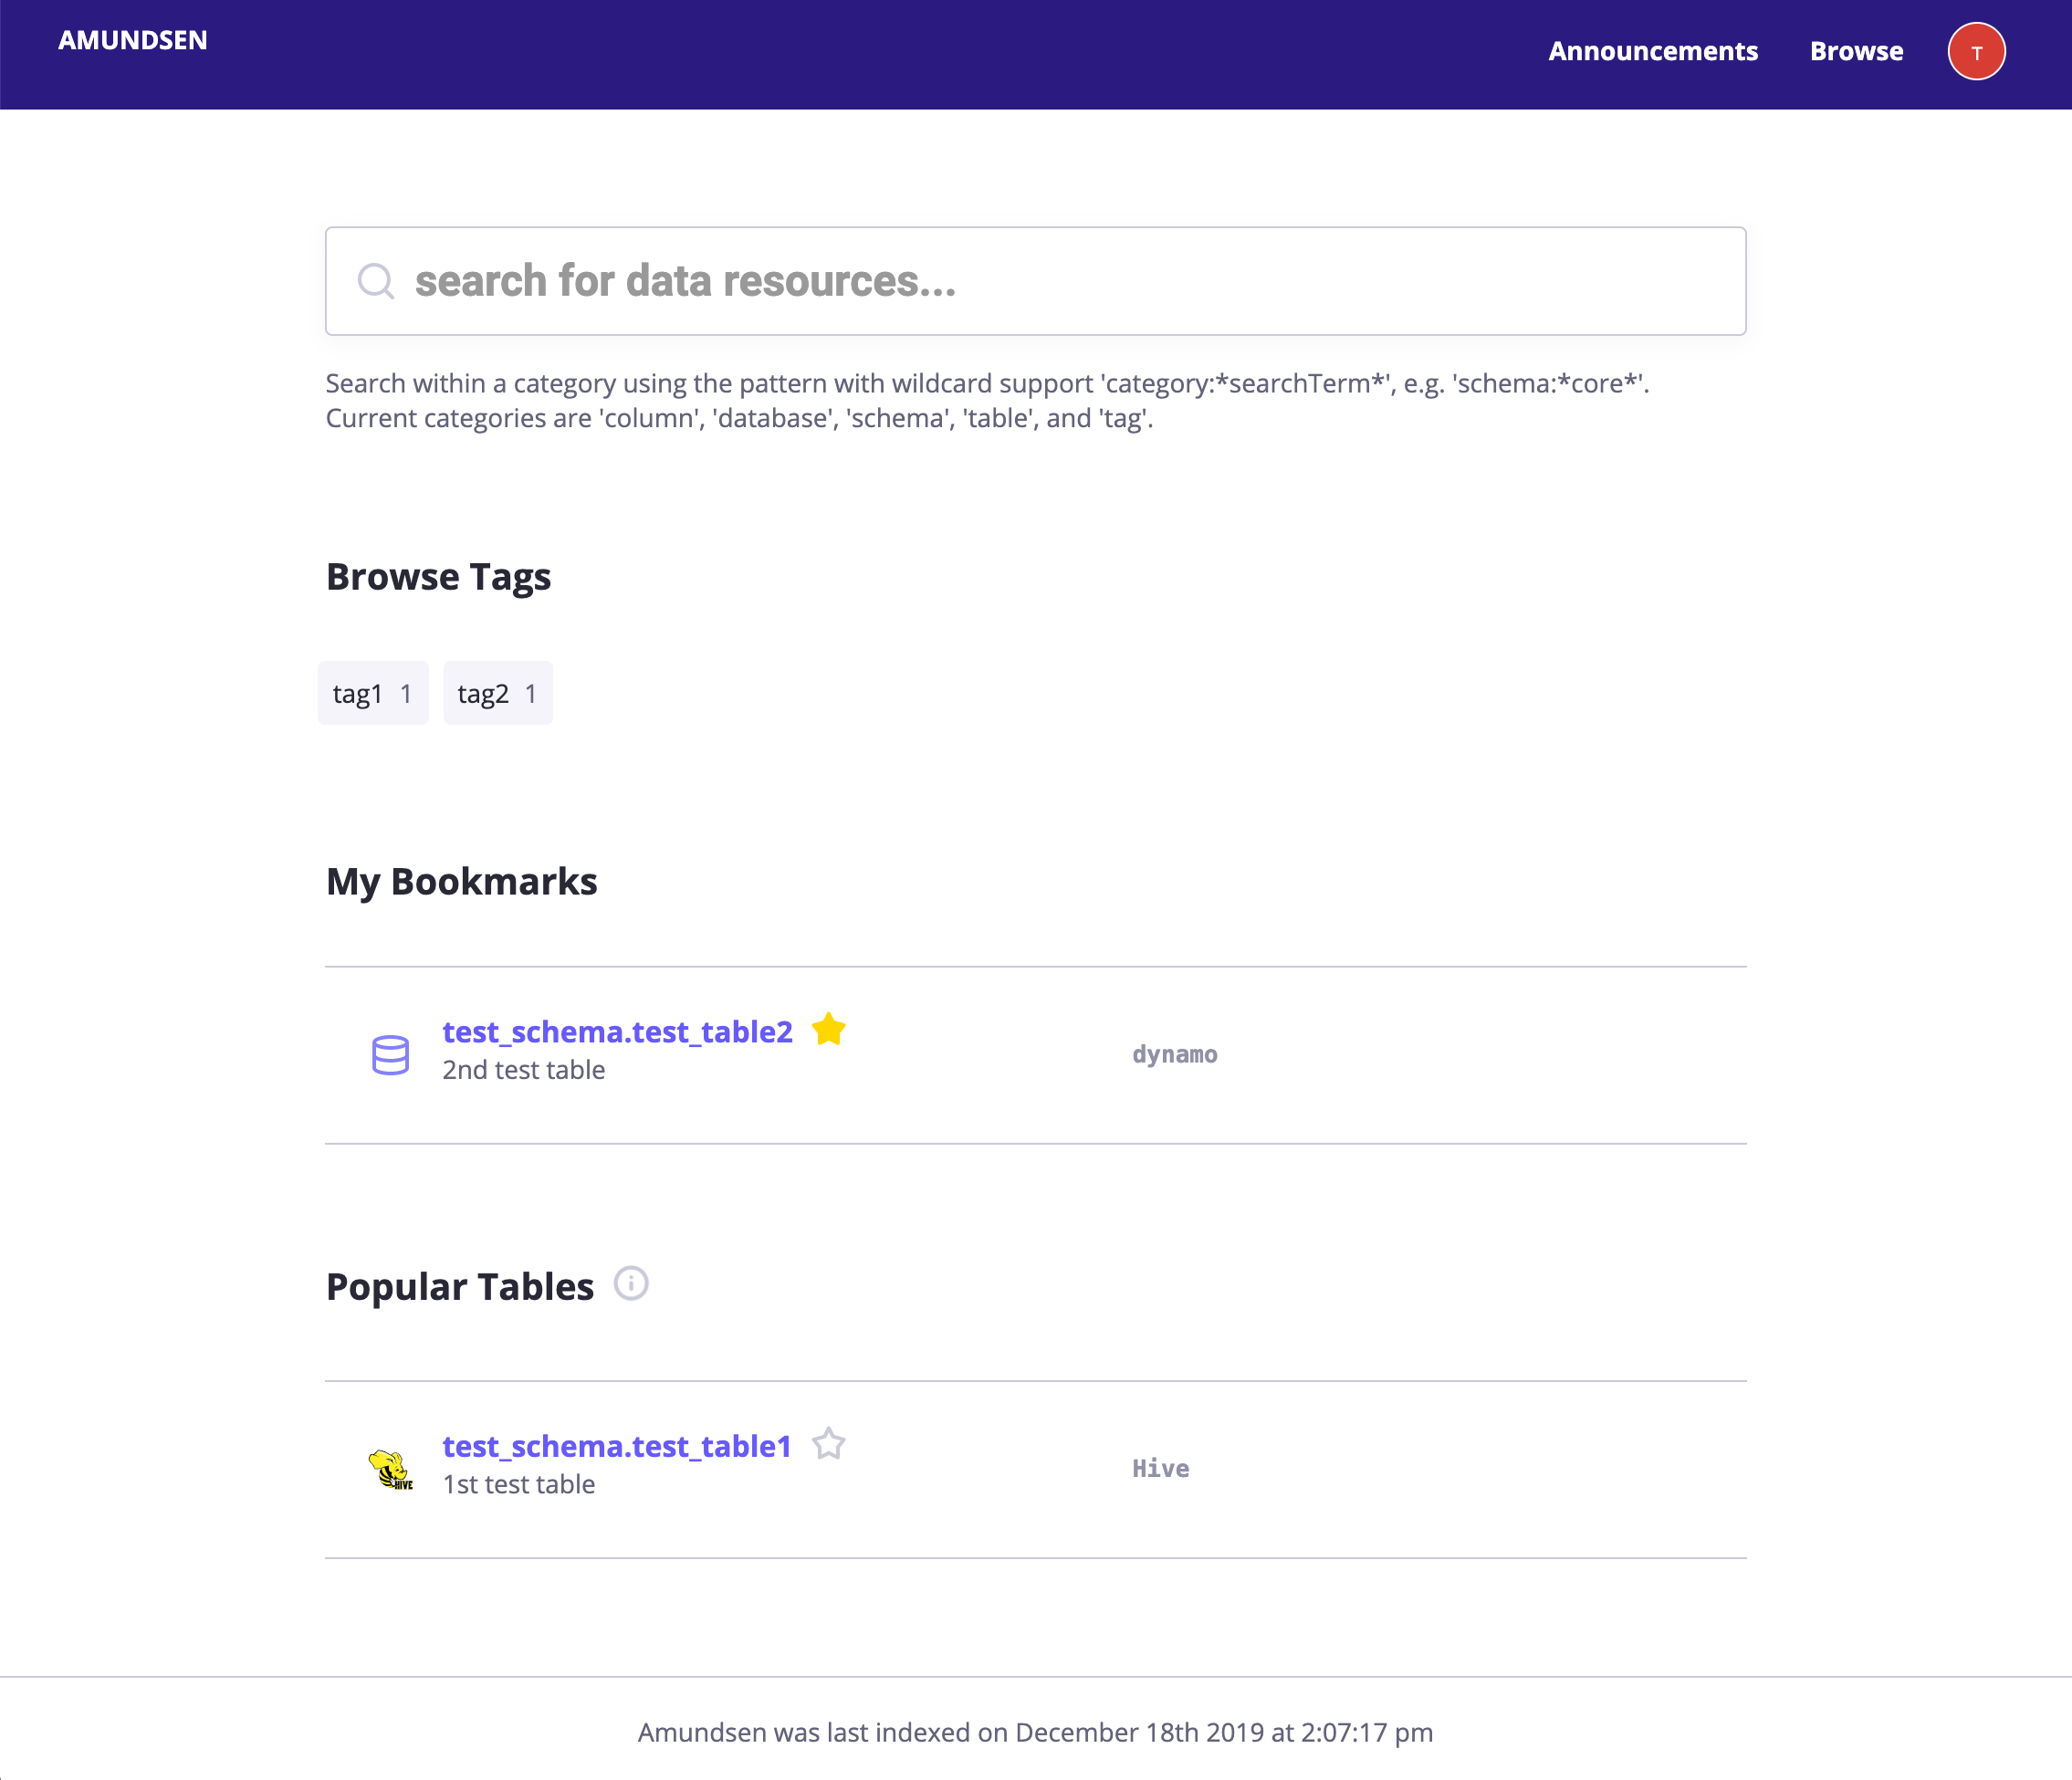
Search Preview: See inline search results as you type
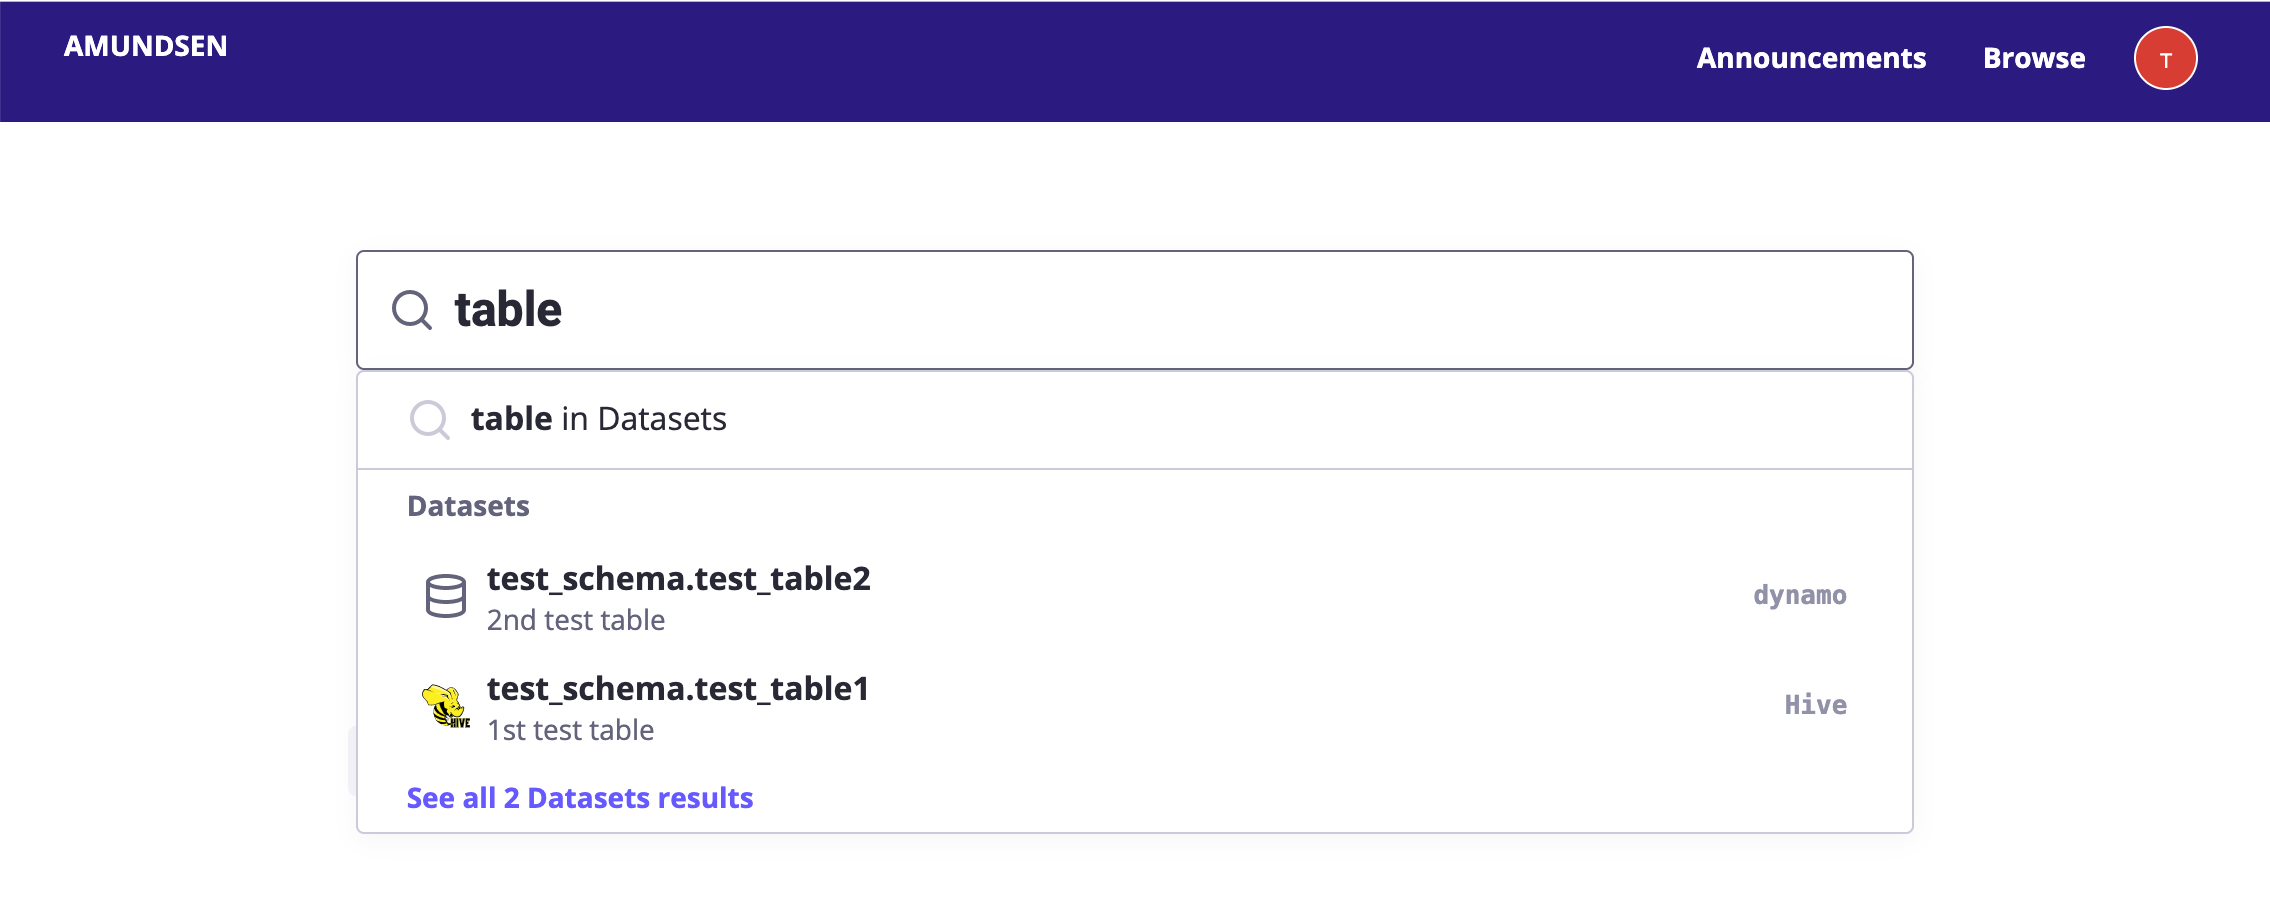
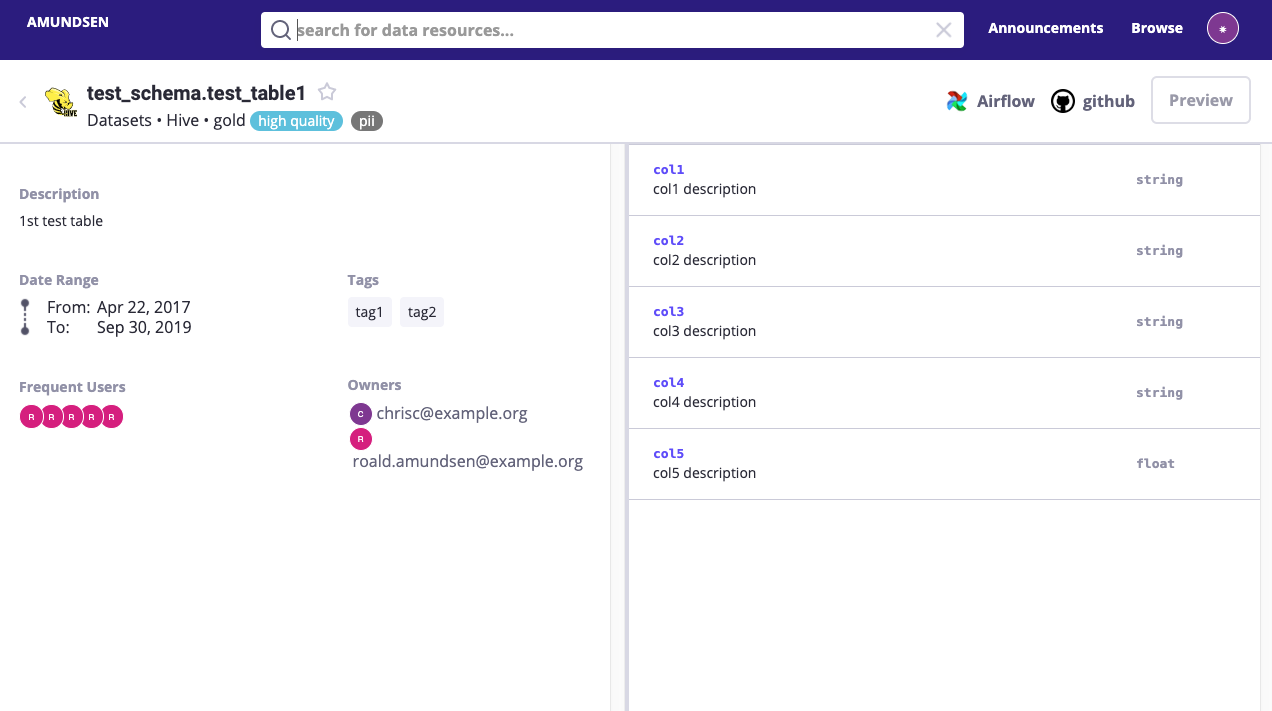
Table Detail Page: Visualization of a Hive / Redshift table
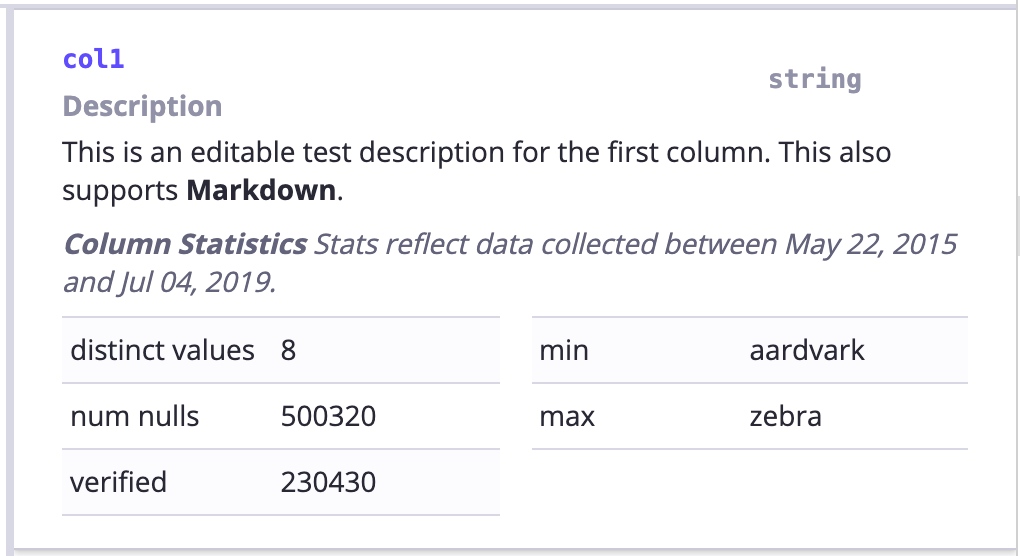
Column detail: Visualization of columns of a Hive / Redshift table which includes an optional stats display
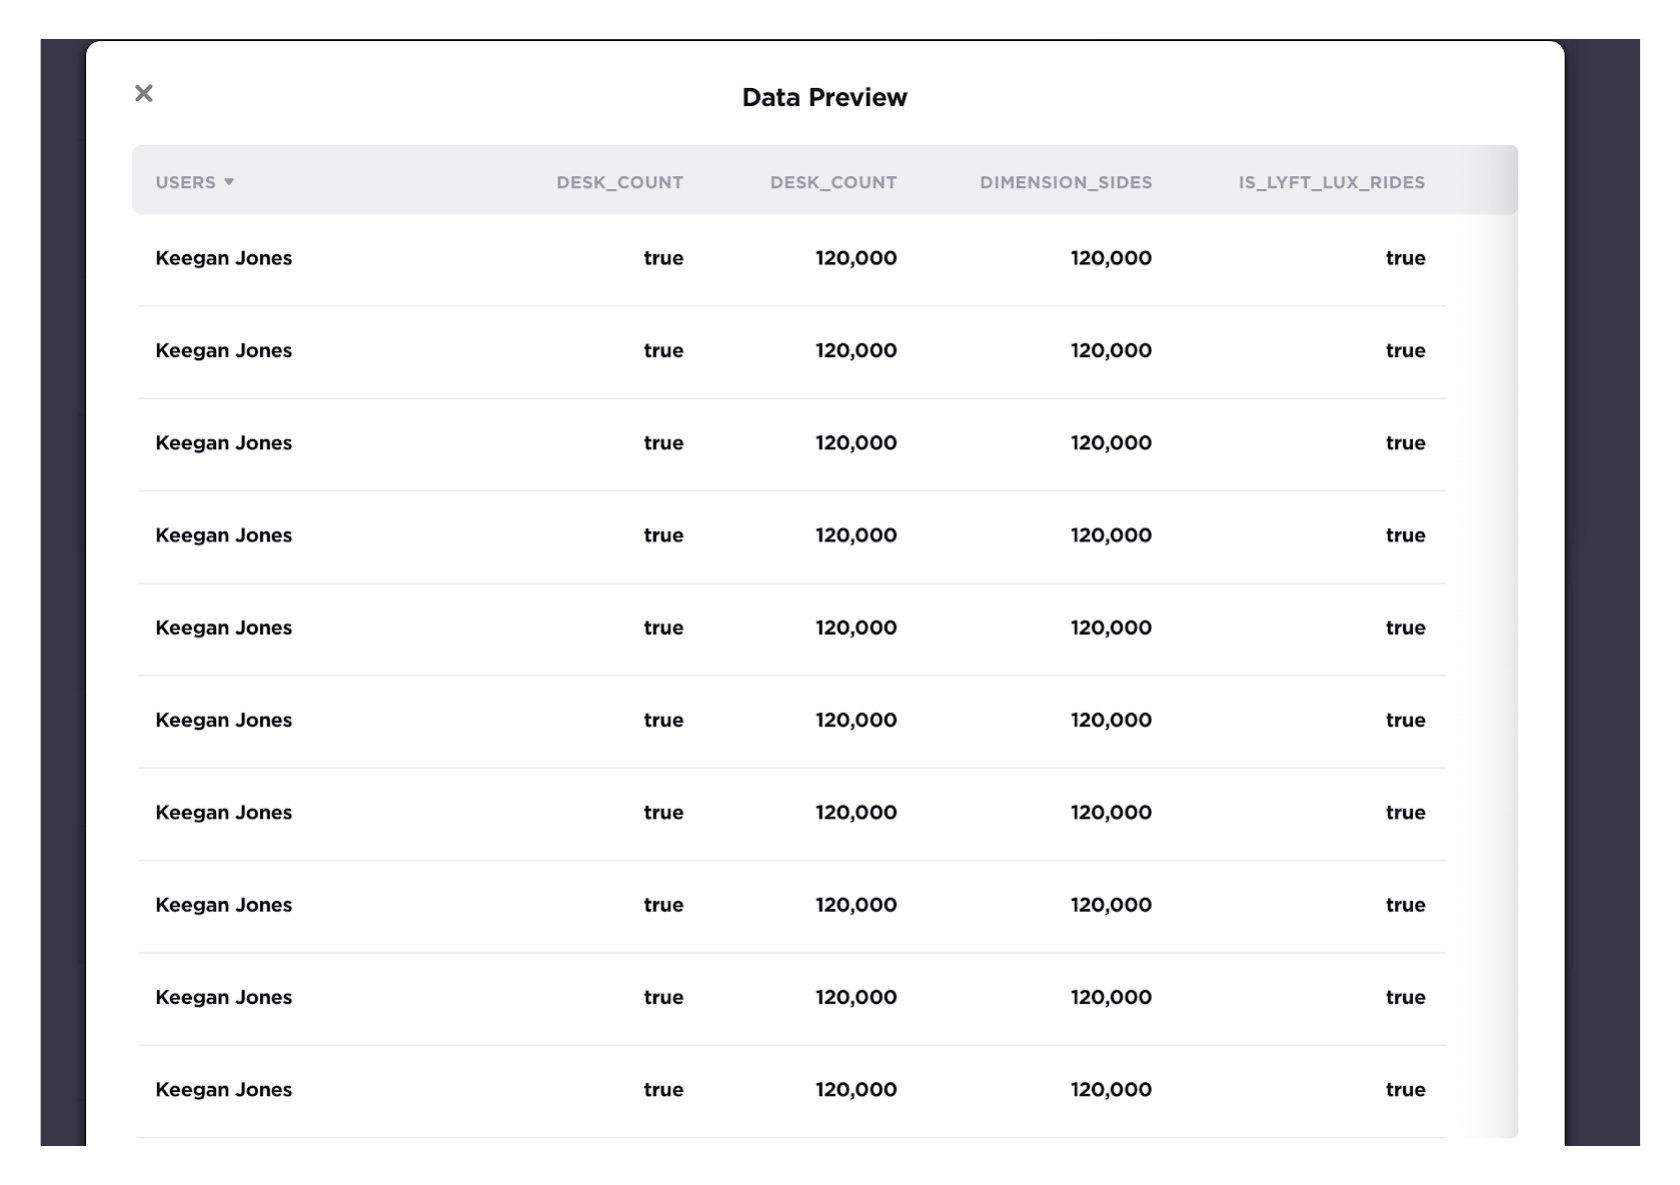
Data Preview Page: Visualization of table data preview which could integrate with Apache Superset or other Data Visualization Tools.
Please visit the Amundsen installation documentation for a quick start to bootstrap a default version of Amundsen with dummy data.
Amundsen can also connect to any database that provides dbapi or sql_alchemy interface (which most DBs provide).
Want help or want to help? Use the button in our header to join our slack channel.
Contributions are also more than welcome! As explained in CONTRIBUTING.md there are many ways to contribute, it does not all have to be code with new features and bug fixes, also documentation, like FAQ entries, bug reports, blog posts sharing experiences etc. all help move Amundsen forward. If you find a security vulnerability, please follow this guide.
Please visit Architecture for Amundsen architecture overview.
Community meetings are held on the first Thursday of every month at 9 AM Pacific, Noon Eastern, 6 PM Central European Time. Link to join
You can the exact date for the next meeting and the agenda a few weeks before the meeting in this doc.
Notes from all past meetings are available here.
Here is the list of organizations that are officially using Amundsen today. If your organization uses Amundsen, please file a PR and update this list.
Thanks goes to these incredible people:
(top 24 of 35)
2,403 followers · starred Mar 2021
1,449 followers · starred Nov 2019
81 followers · starred Oct 2020
402 followers · starred Apr 2021
Amundsen is a metadata driven application for improving the productivity of data analysts, data scientists and engineers when interacting with data.
Python
4,785
2,514 commits
updated Sep 10, 2026
Amundsen is a data discovery and metadata engine for improving the productivity of data analysts, data scientists and engineers when interacting with data. It does that today by indexing data resources (tables, dashboards, streams, etc.) and powering a page-rank style search based on usage patterns (e.g. highly queried tables show up earlier than less queried tables). Think of it as Google search for data. The project is named after Norwegian explorer Roald Amundsen, the first person to discover the South Pole.
Amundsen is hosted by the LF AI & Data Foundation. It includes three microservices, one data ingestion library and one common library.
We want your input about what is important, for that, add your votes using the 👍 reaction:
Please note that the mock images only served as demonstration purpose.
Landing Page: The landing page for Amundsen including 1. search bars; 2. popular used tables;
Search Preview: See inline search results as you type
Table Detail Page: Visualization of a Hive / Redshift table
Column detail: Visualization of columns of a Hive / Redshift table which includes an optional stats display
Data Preview Page: Visualization of table data preview which could integrate with Apache Superset or other Data Visualization Tools.
Please visit the Amundsen installation documentation for a quick start to bootstrap a default version of Amundsen with dummy data.
Amundsen can also connect to any database that provides dbapi or sql_alchemy interface (which most DBs provide).
Want help or want to help? Use the button in our header to join our slack channel.
Contributions are also more than welcome! As explained in CONTRIBUTING.md there are many ways to contribute, it does not all have to be code with new features and bug fixes, also documentation, like FAQ entries, bug reports, blog posts sharing experiences etc. all help move Amundsen forward. If you find a security vulnerability, please follow this guide.
Please visit Architecture for Amundsen architecture overview.
Community meetings are held on the first Thursday of every month at 9 AM Pacific, Noon Eastern, 6 PM Central European Time. Link to join
You can the exact date for the next meeting and the agenda a few weeks before the meeting in this doc.
Notes from all past meetings are available here.
Here is the list of organizations that are officially using Amundsen today. If your organization uses Amundsen, please file a PR and update this list.
Thanks goes to these incredible people:
(top 24 of 35)
2,403 followers · starred Mar 2021
1,449 followers · starred Nov 2019
81 followers · starred Oct 2020
402 followers · starred Apr 2021