
Animating on Twos: Training Keyframe-Animation Adapters on a Pretrained Video Model — Alvdansen Labs, August 2026
HTML
49
7 commits
updated Aug 30, 2026
See what people are saying
README
Animating on Twos
Training Keyframe-Animation Adapters on a Pretrained Video Model
A methodology paper from Alvdansen Labs by Minta Carlson and Timothy Bielec — August 2026.
Live site: alvdansen.github.io/animating-on-twos Weights: huggingface.co/alvdansen/h3-keyframe-animation
Abstract
Large pretrained video models can render photoreal motion and, increasingly, illustrated motion. They are nonetheless poor animators. The failure is easy to miss, because every individual frame can look right. What breaks is the motion style: the physics of how a drawing moves. It drifts between and even within generations, sliding without warning between vector interpolation, digital easing, anime limited-animation, and traditional hand-drawn cadence. In hand-drawn animation, motion style is a load-bearing storytelling channel. It is the instrument and the actor; the exact nature of how a character performs physically in a scene in large part defines them.
This paper describes a methodology for teaching one such model, the open-weights MiniMax H3 (a 33-billion-parameter video diffusion transformer), to animate in a consistent and cross-stylistic hand-drawn cadence, using small LoRA adapters trained from a private hand-drawn animation corpus. We work backwards from how animators actually key a scene rather than from what the model finds conveniently on distribution, and arrive at three sibling adapters: extremes (hero), inbetweens (tween), and short held sequences (sequence), distinguished by how many reference drawings each is conditioned on and what the distance between those drawings is asked to mean.
We also give a portable caption dialect built from real animation vocabulary, a chained subset-rotation training schedule, and the exact tensor surgery required to make a conventionally-trained LoRA apply to this model's fused attention projections.
Finally we argue that the standard video-generation metrics are blind to the one axis that matters here, cadence, and describe the cadence and comparison instrumentation we built instead. That instrumentation has a hard limit: it measures the magnitude of motion, never its quality, and the quality judgement stays with a human.
This is a methodology paper: a working process and its instrumentation, with the validated, in-progress, and still-open parts marked as such.
The three adapters
Same architecture, same training schedule. What separates them is the conditioning contract: how many reference drawings each takes, and what the distance between those drawings is asked to mean. In every clip below the left half is the untrained baseline and the right half is the adapter at step 12,000 — same inputs, same seed.
hero — 1 reference
Draw the natural next hero key.
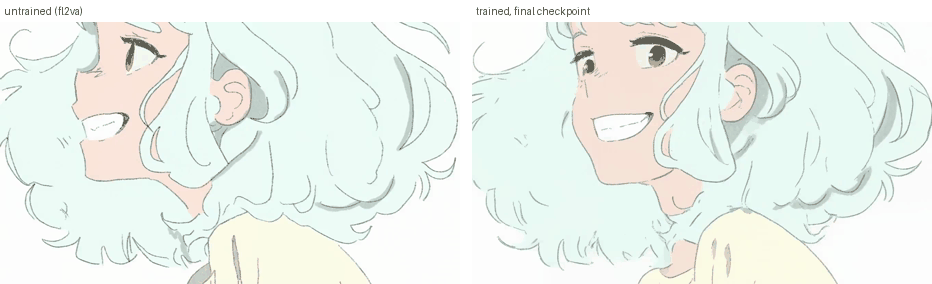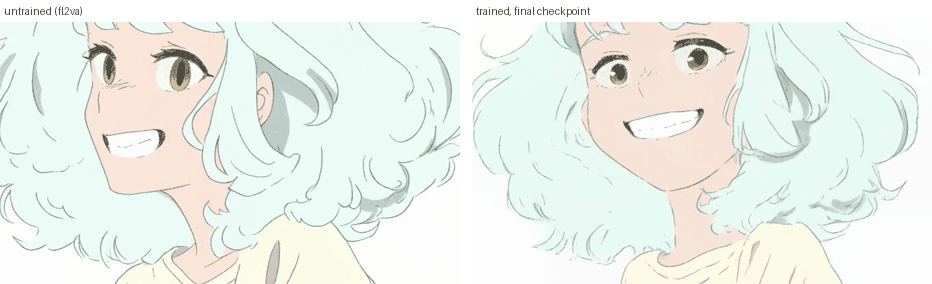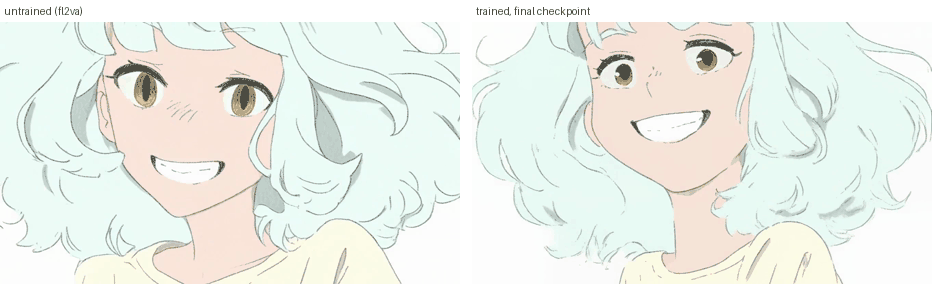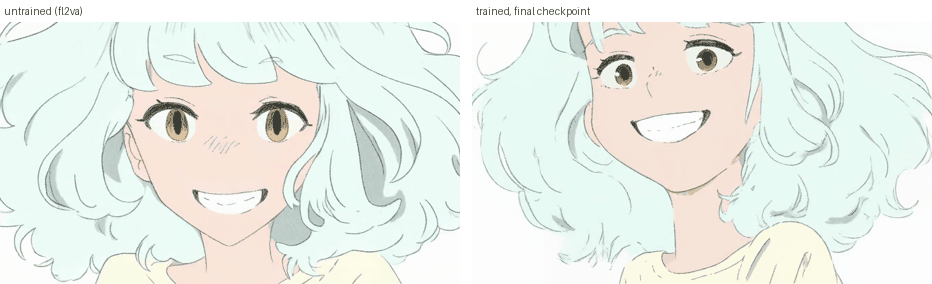
Conditioned on the current hero key, and nothing else. There is deliberately no second reference: where the action goes next is the question being asked, so showing the model a destination would be showing it the answer.
tween — 2 references
Draw the next inbetween, advancing the motion one small step.
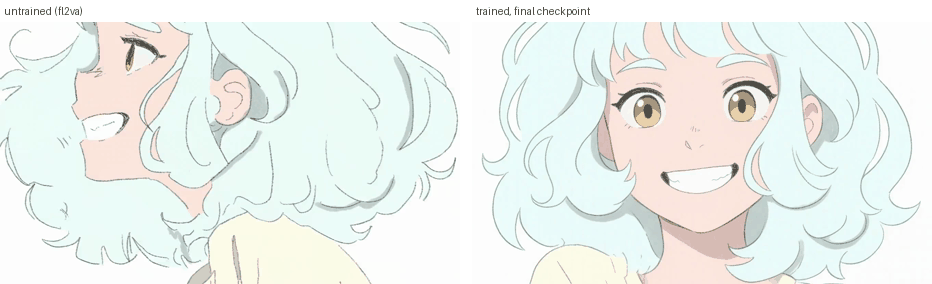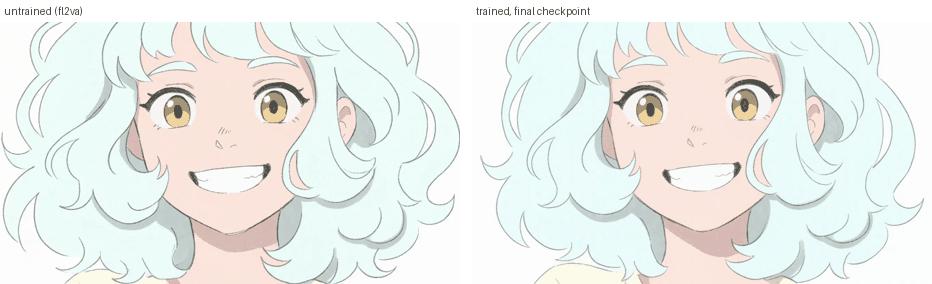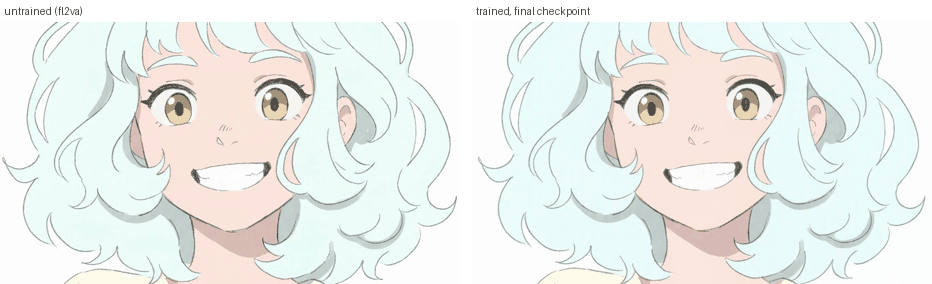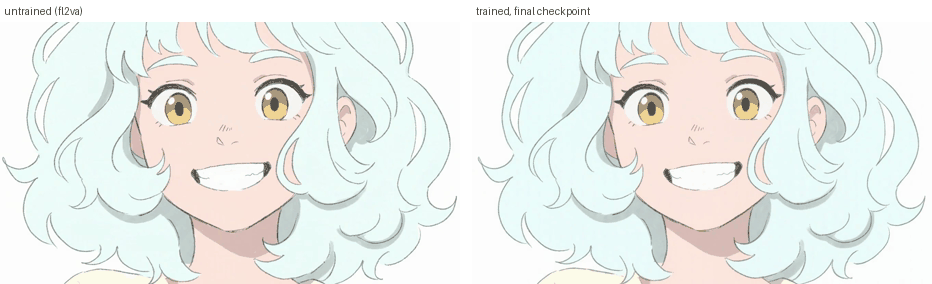
Conditioned on a rolling current frame plus the beat's distant end extreme, held fixed for the whole chain. The far reference is context, not an interpolation target — it tells the next inbetween which way to lean.
sequence — 2 references
Surface a short, self-contained held sequence.
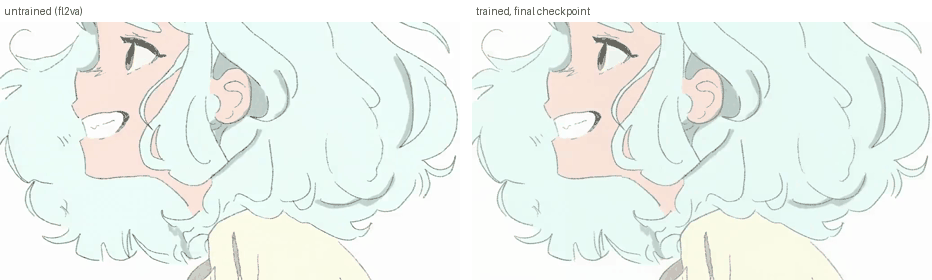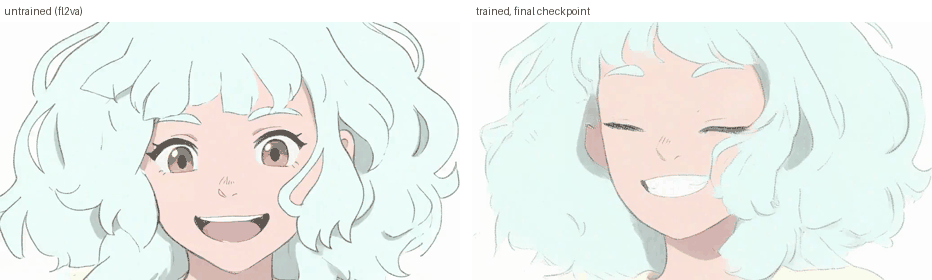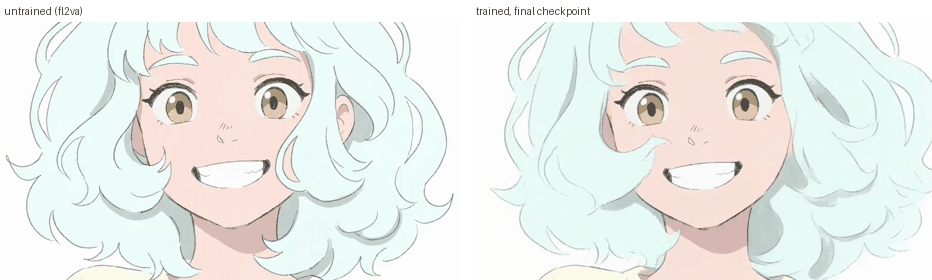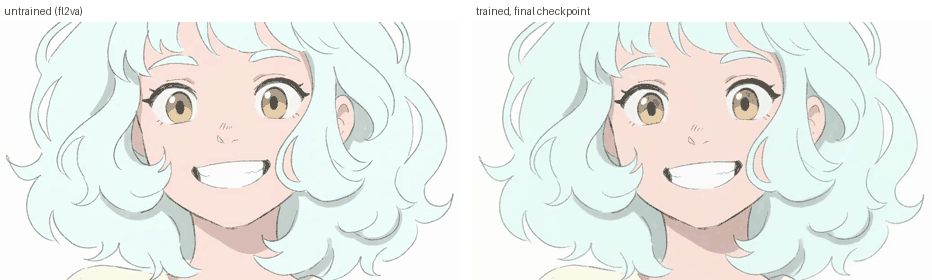
Conditioned on the window's first drawing and the window's own natural end. This one does not teach the model a new mapping; hand-drawn held animation already sits somewhere in the base distribution, and the adapter's job is to surface it consistently.
The reference count is fixed per adapter and is not a tuning knob — supplying the wrong number does not raise an error, it silently conditions the model outside the regime it was trained in.
Running them
workflows/h3_seq_r2v.json is a ready-to-load ComfyUI graph —
drag it onto the canvas. It ships configured for one reference, the hero contract; for
tween or sequence, un-bypass the second LoadImage and swap the adapter. The reference
image and the prompt that drives it are on the
model card under examples/quickstart/.
Weights, per-adapter inference settings, and the caption dialect that is the actual inference interface live in the model card.
Repository contents
| File | Description |
|---|---|
index.html | The publication HTML — what gets served at the live site. |
paper.md | The source-of-truth article markdown. |
figures/ | The figures referenced by the page. |
build_paper.py | Regenerates index.html from paper.md, injecting figures at anchor phrases. |
build_paper.py is a reproducibility breadcrumb rather than a build pipeline. It needs
only markdown; run it from this directory and it rewrites index.html in place.
Citation
@article{carlson2026animating,
  title   = {Animating on Twos: Training Keyframe-Animation Adapters on a Pretrained Video Model},
  author  = {Carlson, Minta and Bielec, Timothy},
  year    = {2026},
  month   = {August},
  journal = {Alvdansen Labs},
  url     = {https://alvdansen.github.io/animating-on-twos/}
}
License
- Article text and figures — Creative Commons Attribution 4.0 International (CC BY 4.0). You may copy, redistribute, remix, and build on the work in any medium or format, including commercially, provided you give appropriate credit and link to the license.
- Code (
build_paper.py) — MIT. - The trained adapter weights are not covered by either of the above. They are distributed separately under the H3 Keyframe Animation Adapter License 1.0.0, a source-available license that is free for individuals, researchers, nonprofits, and small organizations. See the weights repository.
The adapters modify MiniMax H3, whose own license binds you directly and imposes obligations — including territorial restrictions — that we cannot waive on your behalf.
Credits
The adapter training for this project ran on Modal, whose sponsored GPU credits made its development and validation possible.
Significant stargazers

108 followers · starred Aug 2026
Similar repos




Languages
HTML
85.5%
Python
14.5%
Animating on Twos: Training Keyframe-Animation Adapters on a Pretrained Video Model — Alvdansen Labs, August 2026
HTML
49
7 commits
updated Aug 30, 2026
See what people are saying
README
Animating on Twos
Training Keyframe-Animation Adapters on a Pretrained Video Model
A methodology paper from Alvdansen Labs by Minta Carlson and Timothy Bielec — August 2026.
Live site: alvdansen.github.io/animating-on-twos Weights: huggingface.co/alvdansen/h3-keyframe-animation
Abstract
Large pretrained video models can render photoreal motion and, increasingly, illustrated motion. They are nonetheless poor animators. The failure is easy to miss, because every individual frame can look right. What breaks is the motion style: the physics of how a drawing moves. It drifts between and even within generations, sliding without warning between vector interpolation, digital easing, anime limited-animation, and traditional hand-drawn cadence. In hand-drawn animation, motion style is a load-bearing storytelling channel. It is the instrument and the actor; the exact nature of how a character performs physically in a scene in large part defines them.
This paper describes a methodology for teaching one such model, the open-weights MiniMax H3 (a 33-billion-parameter video diffusion transformer), to animate in a consistent and cross-stylistic hand-drawn cadence, using small LoRA adapters trained from a private hand-drawn animation corpus. We work backwards from how animators actually key a scene rather than from what the model finds conveniently on distribution, and arrive at three sibling adapters: extremes (hero), inbetweens (tween), and short held sequences (sequence), distinguished by how many reference drawings each is conditioned on and what the distance between those drawings is asked to mean.
We also give a portable caption dialect built from real animation vocabulary, a chained subset-rotation training schedule, and the exact tensor surgery required to make a conventionally-trained LoRA apply to this model's fused attention projections.
Finally we argue that the standard video-generation metrics are blind to the one axis that matters here, cadence, and describe the cadence and comparison instrumentation we built instead. That instrumentation has a hard limit: it measures the magnitude of motion, never its quality, and the quality judgement stays with a human.
This is a methodology paper: a working process and its instrumentation, with the validated, in-progress, and still-open parts marked as such.
The three adapters
Same architecture, same training schedule. What separates them is the conditioning contract: how many reference drawings each takes, and what the distance between those drawings is asked to mean. In every clip below the left half is the untrained baseline and the right half is the adapter at step 12,000 — same inputs, same seed.
hero — 1 reference
Draw the natural next hero key.
Conditioned on the current hero key, and nothing else. There is deliberately no second reference: where the action goes next is the question being asked, so showing the model a destination would be showing it the answer.
tween — 2 references
Draw the next inbetween, advancing the motion one small step.
Conditioned on a rolling current frame plus the beat's distant end extreme, held fixed for the whole chain. The far reference is context, not an interpolation target — it tells the next inbetween which way to lean.
sequence — 2 references
Surface a short, self-contained held sequence.
Conditioned on the window's first drawing and the window's own natural end. This one does not teach the model a new mapping; hand-drawn held animation already sits somewhere in the base distribution, and the adapter's job is to surface it consistently.
The reference count is fixed per adapter and is not a tuning knob — supplying the wrong number does not raise an error, it silently conditions the model outside the regime it was trained in.
Running them
workflows/h3_seq_r2v.json is a ready-to-load ComfyUI graph —
drag it onto the canvas. It ships configured for one reference, the hero contract; for
tween or sequence, un-bypass the second LoadImage and swap the adapter. The reference
image and the prompt that drives it are on the
model card under examples/quickstart/.
Weights, per-adapter inference settings, and the caption dialect that is the actual inference interface live in the model card.
Repository contents
| File | Description |
|---|---|
index.html | The publication HTML — what gets served at the live site. |
paper.md | The source-of-truth article markdown. |
figures/ | The figures referenced by the page. |
build_paper.py | Regenerates index.html from paper.md, injecting figures at anchor phrases. |
build_paper.py is a reproducibility breadcrumb rather than a build pipeline. It needs
only markdown; run it from this directory and it rewrites index.html in place.
Citation
@article{carlson2026animating,
  title   = {Animating on Twos: Training Keyframe-Animation Adapters on a Pretrained Video Model},
  author  = {Carlson, Minta and Bielec, Timothy},
  year    = {2026},
  month   = {August},
  journal = {Alvdansen Labs},
  url     = {https://alvdansen.github.io/animating-on-twos/}
}
License
- Article text and figures — Creative Commons Attribution 4.0 International (CC BY 4.0). You may copy, redistribute, remix, and build on the work in any medium or format, including commercially, provided you give appropriate credit and link to the license.
- Code (
build_paper.py) — MIT. - The trained adapter weights are not covered by either of the above. They are distributed separately under the H3 Keyframe Animation Adapter License 1.0.0, a source-available license that is free for individuals, researchers, nonprofits, and small organizations. See the weights repository.
The adapters modify MiniMax H3, whose own license binds you directly and imposes obligations — including territorial restrictions — that we cannot waive on your behalf.
Credits
The adapter training for this project ran on Modal, whose sponsored GPU credits made its development and validation possible.
Similar repos
Significant stargazers
108 followers · starred Aug 2026
Languages
HTML
85.5%
Python
14.5%