Self-tuning multi-agent AI trading system. 8-source signal fusion, Bull/Bear/Judge debate on Claude Opus 4.7, Kelly + ATR position sizing. Python · Kalshi + Polymarket adapters.
See the code
8-source signal fusion · 10 ML models incl. Kronos · Bull/Bear/Judge debate on Claude Opus 4.7
Polymarket + Kalshi prediction markets vote alongside ML models. Weights adapt to per-source accuracy automatically.
Different from other AI-trading repos. Orallexa isn't a hedge-fund simulator. It's a calibrated multi-agent decision system with a published Brier log, a FinPos-style Risk Sizer that keeps direction and position sizing on separate agents, and a hard kill switch. Paper-only. Real money is gated behind a written Brier improvement, not vibes.




Live Demo · Presentation · Evaluation Report · 中文
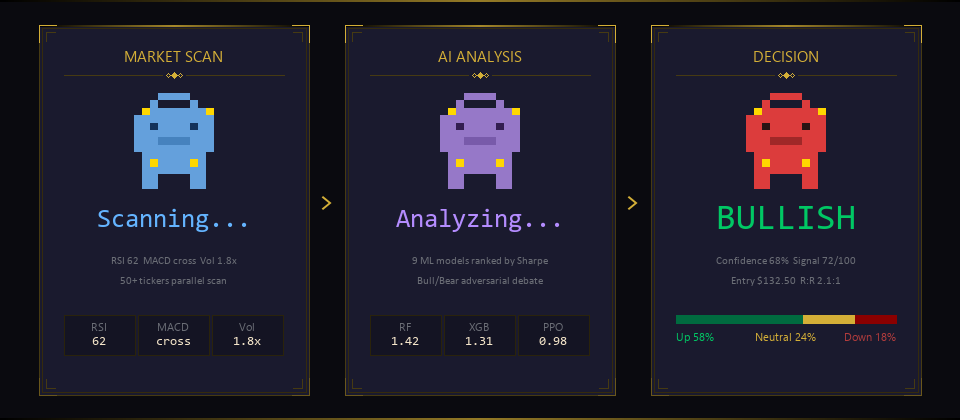
Most AI trading projects: feed data into a model, get a signal, done.
Orallexa runs a multi-agent intelligence pipeline. 4 AI analysts with different risk profiles debate the trade. A 20-agent swarm simulates market reactions. 5 independent signal sources vote. A bias tracker corrects the system's own mistakes. Then it executes.
Market Data → 9 ML Models → 4-Role Panel + Bull/Bear Debate
    → 8-Source Signal Fusion → Judge Verdict → What-If Scenarios
    → Risk Plan → Portfolio Manager → Paper Execution → Dashboard → Social Content
Every stage automated. Every stage observable. The system learns from itself.
Open Live Demo — demo mode, no API key needed. Click NVDA, TSLA, or QQQ to see a full analysis.
Or run locally:
git clone https://github.com/alex-jb/orallexa-ai-trading-agent.git
cd orallexa-ai-trading-agent
pip install -r requirements.txt
echo "ANTHROPIC_API_KEY=your_key" > .env

# Terminal 1: API
python api_server.py


## ⚠️ Educational research, not financial advice

This repository is published for educational and research purposes. Nothing
here is investment, trading, or financial advice. The models, signals, and
outputs shown are experimental and may be wrong. Past performance does not
predict future results. Do not use any output as the basis for a real
trading, investment, or hedging decision without independent professional
verification. The author accepts no liability for losses.

# Terminal 2: UI
cd orallexa-ui && npm install && npm run dev
Docker: docker compose up --build — that's it.
| Strategy | Ticker | OOS Sharpe | Verdict | p-value |
|---|---|---|---|---|
| rsi_reversal | INTC | 1.41 | PASS | 0.002 |
| dual_thrust | NVDA | 0.96 | PASS | 0.001 |
| alpha_combo | NVDA | 0.92 | PASS | 0.016 |
| macd_crossover | NVDA | 0.91 | PASS | 0.003 |
| ensemble_vote | NVDA | 0.90 | PASS | 0.001 |
| trend_momentum | NVDA | 0.74 | PASS | 0.005 |
| double_ma | GOOG | 0.64 | PASS | 0.049 |
| ensemble_vote | META | 0.31 | MARGINAL | 0.324 |
90 strategy-ticker pairs across 10 tickers and 9 strategies (including ensemble vote and regime-aware ensemble). 1 STRONG PASS, 7 PASS, 33 MARGINAL. Full report →
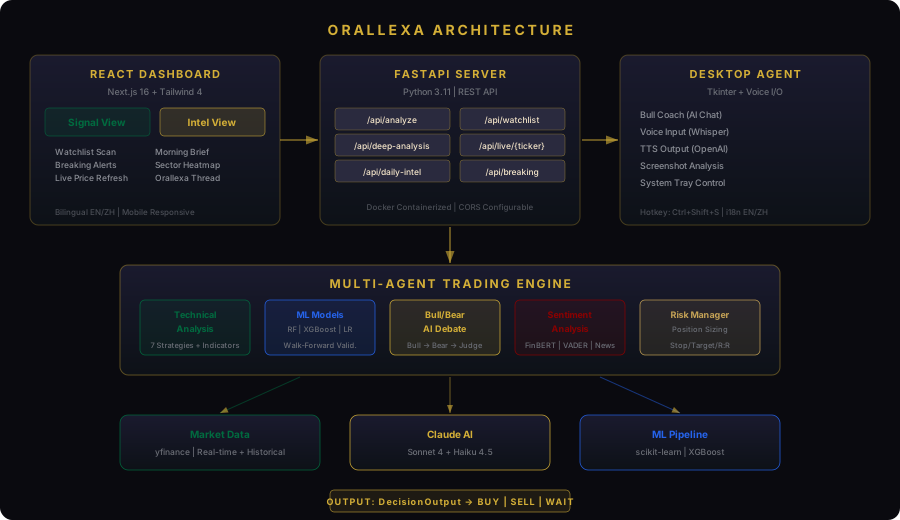
Intelligence Layer
|
Execution Layer
|
What one NVDA analysis produces:
┌─────────────────────────────────────────────────────────────────┐
│  DECISION: BUY                    Confidence: 68%               │
│  Risk: MEDIUM                     Signal: 72/100                │
├─────────────────────────────────────────────────────────────────┤
│                                                                 │
│  BULL CASE:                                                     │
│  • Price above MA20 > MA50 — full bullish alignment             │
│  • RSI at 62 — strong momentum, not yet overbought              │
│  • Volume 1.8x average — institutional participation likely     │
│                                                                 │
│  BEAR CASE:                                                     │
│  • ADX at 32 but declining — trend may be exhausting            │
│  • Bollinger %B at 0.85 — extended near upper band              │
│  • Earnings in 12 days — vol crush after event                  │
│                                                                 │
│  JUDGE VERDICT:                                                 │
│  "Bull case is stronger. BUY with tight stop at MA20."          │
│                                                                 │
│  PROBABILITIES: Up 58% | Neutral 24% | Down 18%                │
│  RISK PLAN:                                                     │
│  Entry: $132.50 | Stop: $128.40 | Target: $141.00 | R:R 2.1:1  │
└─────────────────────────────────────────────────────────────────┘
Not just a number. A structured argument with transparent reasoning and an actionable risk plan.
Every analysis runs all available models. The ML Scoreboard shows Sharpe, return, win rate side by side.
| Model | Type | What It Does |
|---|---|---|
| Random Forest | Classification | 28 technical features → 5-day direction |
| XGBoost | Gradient Boosting | Same features, different optimization |
| Logistic Regression | Linear | Regularized baseline |
| EMAformer | Transformer | iTransformer + Embedding Armor (AAAI 2026) |
| MOIRAI-2 | Foundation | Salesforce zero-shot time series forecaster |
| Chronos-2 | Foundation | Amazon T5-based probabilistic forecaster |
| DDPM Diffusion | Generative | 50 possible price paths → VaR and confidence intervals |
| PPO RL Agent | Reinforcement | Gymnasium env, Sharpe-based reward |
| GNN (GAT) | Graph | 17-stock relationship graph, inter-stock signal propagation |
All models run on CPU.
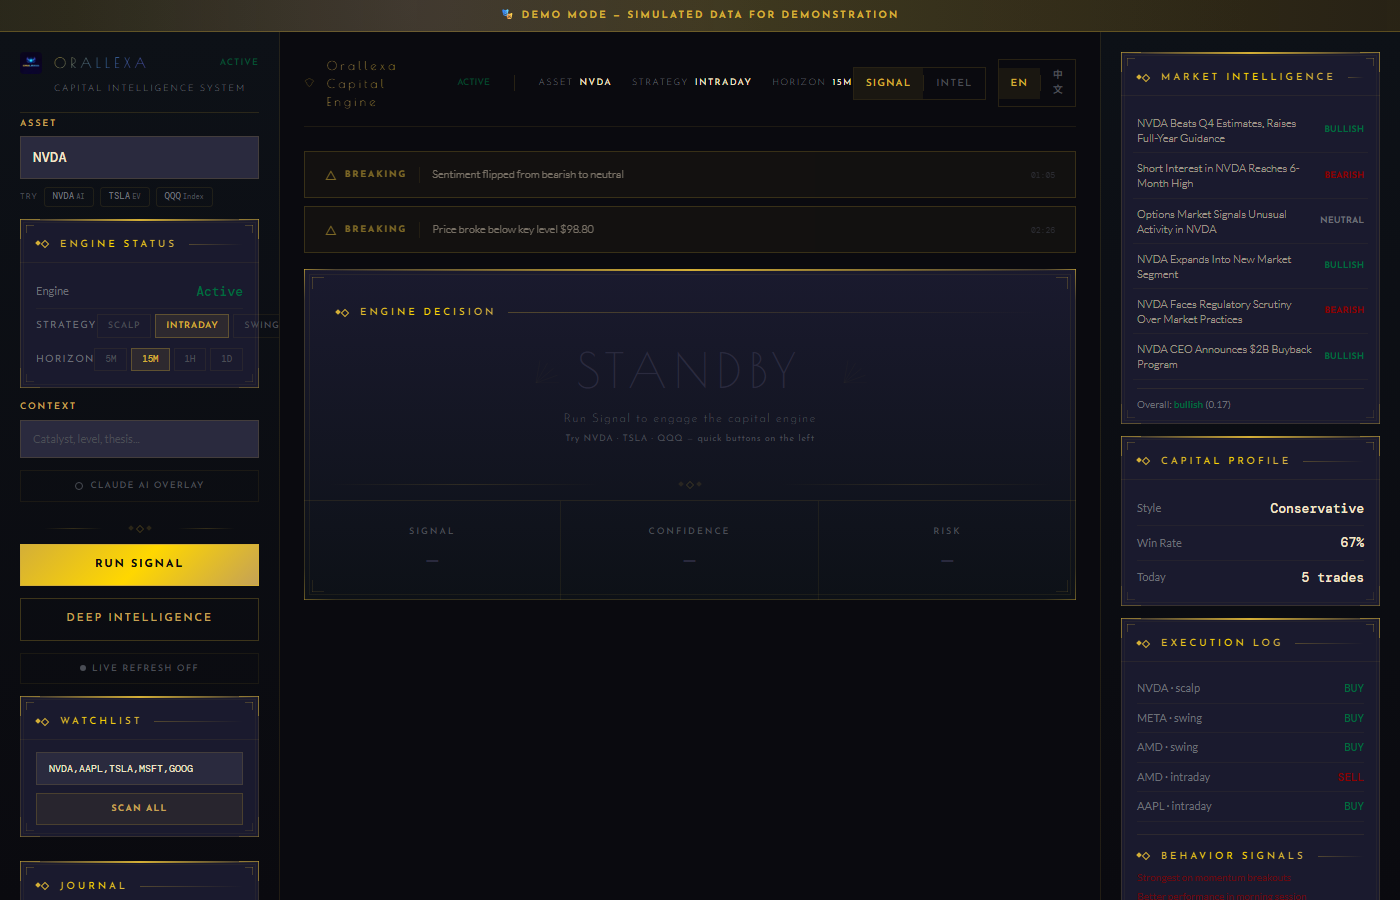
Signal View — Decision card, probability bars, Bull/Bear debate, ML scoreboard, risk plan.
Intel View — Morning brief, gainers/losers, sector heatmap, volume spikes, AI picks, social thread.
Art Deco theme. Polymarket-inspired probability display. Mobile responsive. EN/ZH bilingual.
A floating pixel bull that lives on your desktop:
Not every task needs the expensive model:
| Task | Model | Cost |
|---|---|---|
| Bull/Bear arguments | Haiku 4.5 | ~$0.001 |
| 4-Role perspective panel | Haiku 4.5 | ~$0.002 |
| Judge verdict | Sonnet 4.6 | ~$0.005 |
| Deep market report | Sonnet 4.6 | ~$0.005 |
| What-if scenario | Sonnet 4.6 | ~$0.005 |
| Signal fusion + swarm | Local (no LLM) | $0 |
| Bias tracking | Local (no LLM) | $0 |
One full analysis: ~$0.005. One daily intel report: ~$0.05.
ORALLEXA_USE_CACHE=1 short-circuits every daily-grain yfinance call (earnings calendar, PEAD stats, watchlist volume, SPY 6-month, GNN per-ticker features, MarketDataSkill). Cache hits cost nothing and complete in milliseconds. Intraday and fast_info paths intentionally bypass — those need real-time data.
ORALLEXA_MULTIMODAL_SAMPLE=0.0..1.0 controls vision-augmented debate sampling. Default 0 is off (zero behavior change vs text-only). Setting e.g. 0.2 runs the Quant Researcher with both text and a K-line chart on ~20% of deep-analysis calls; the per-call diff is stashed on decision_log.extra.multimodal_diff and the nightly Multimodal Lift — Vision vs Text Eval workflow rolls it into a ship/reject verdict. Vision adds ~5× cost per sampled call, so 0.1–0.2 is the recommended prod range.
Two patterns from this repo have been extracted as standalone Python packages + Claude Code skills:
- claude-tier-router — the Haiku/Sonnet dual-tier routing (
pip install claude-tier-router)- claude-debate — the Bull/Bear/Judge adversarial decision pattern, generalized (
pip install claude-debate)
| Problem | Typical Approach | Orallexa |
|---|---|---|
| Isolated signals | One model, one prediction | 8 sources fused: technical + ML + news + options + institutional + social + earnings + prediction markets |
| No reasoning | "BUY 73%" — why? | 4 analysts debate, Bull/Bear argue, Judge decides with evidence |
| No self-correction | Same mistakes repeated | Bias tracker detects overconfidence, auto-adjusts future calls |
| Static analysis | Can't test hypotheticals | "What if Fed hikes 50bp?" — scenario simulation with swarm |
| Expensive AI | Every call hits GPT-4 | Haiku for 80%, Sonnet only where reasoning matters |
| Manual workflow | Notebook → read → decide → execute | Automated: signal → debate → risk plan → paper order |
| No context | Each stock analyzed alone | GNN propagates signals across 17 related stocks |
| Not shareable | Screenshot your terminal | "Copy for X" on every section |
Inspired by ai-hedge-fund. We share the multi-agent philosophy but take different approaches:
| Feature | ai-hedge-fund | Orallexa |
|---|---|---|
| ML Models | 0 (LLM-only) | 9 (RF, XGB, EMAformer, MOIRAI-2, Chronos-2, DDPM, PPO RL, GNN, LR) |
| Model Ranking | No | Auto-ranked by Sharpe ratio |
| LLM Providers | OpenAI, Groq, Anthropic, DeepSeek | Claude Sonnet + Haiku (dual-tier routing) |
| Cost per Analysis | ~$0.03+ (single-tier) | ~$0.003 (80% Haiku, 20% Sonnet) |
| Real-time Dashboard | Basic web UI | Next.js 16 with WebSocket, Art Deco theme |
| Paper Trading | No execution | Alpaca bracket orders (stop-loss + take-profit) |
| Daily Intelligence | No | 50+ tickers, sector rotation, AI morning brief |
| Desktop Assistant | No | Pixel bull with voice (Whisper + TTS) |
| Social Content | No | One-click "Copy for X" on every section |
| Walk-Forward Eval | No | 70 strategy-ticker pairs, OOS Sharpe |
| Tests | Limited | 698 automated (261 frontend + 437 backend) |
| Bilingual | No | EN/ZH |
| Frontend | Next.js 16, React 19, Tailwind CSS 4, PWA |
| Backend | FastAPI, Python 3.11, WebSocket |
| AI | Claude Sonnet 4.6 + Haiku 4.5 (dual-tier routing) |
| ML | scikit-learn, XGBoost, PyTorch (EMAformer, DDPM, GAT, PPO) |
| Data | yfinance (real-time + historical), parquet cache layer (`ORALLEXA_USE_CACHE=1`) |
| NLP | FinBERT, VADER, TextBlob |
| Trading | Alpaca paper trading (bracket orders) |
| Orchestration | LangGraph (stateful debate pipeline) |
| Deploy | Docker, GitHub Actions CI/CD, Vercel |
922 backend tests + 245 frontend = 1,167 total. 0 failures. CI on every push. 0 open issues.
python -m pytest tests/ -v             # Backend (922 tests)
cd orallexa-ui && npm test             # Frontend (245 unit tests)
cd orallexa-ui && npm run test:coverage # Frontend with coverage
cd orallexa-ui && npx playwright test   # E2E (16+ specs)
| Suite | Tests | Coverage |
|---|---|---|
| Engine Core | 62 | Backtest, 10 strategies, market analyst |
| Engine Integration | 34 | TA indicators, strategies, backtest, brain routing |
| ML/RL Signals | 20 | Feature extraction, RL env, PPO trainer |
| ML Regression | 13 | All 9 models — ensures upgrades don't degrade |
| API E2E + Healthz | 21 | Every endpoint via FastAPI TestClient + liveness probe |
| Unit Tests | 47 | DecisionOutput, BehaviorMemory, risk, scalping |
| Desktop Agent | 30 | Intent detection, ticker/mode/TF extraction |
| i18n (en/zh/ja) | 14 | Trilingual coverage + placeholder consistency |
| Daily Intel | 10 | Price fetch, constants, cache path |
| Sentiment | 21 | FinBERT/VADER fallbacks, rag/news mocks |
| VWAP Reversion | 13 | Signal gates, threshold band, edge cases |
| Historical Cache | 37 | get_prices, period helper, 4 wired call sites |
| Debate Stash | 7 | Bull/Bear/Judge → decision_log → eval-set extraction |
| DSPy Phase B Harness | 24 | Synthesizer, splitter, evaluator, readiness gates, loader |
| DSPy Judge | 13 | Phase A + load_compiled_judge with stubbed dspy |
| Backend Other | 67 | Monte Carlo, walk-forward, regime, ensemble, statistics |
| Backend Misc | 488 | Param optimizer, strategy evolver, breaking signals, … |
| UI Components | 245 | All 14 component suites + hooks + mock data |
| Playwright E2E | 16+ | Dashboard, components, responsive, offline |
| Total | 1,167 | 922 backend + 245 frontend |
| Method | Endpoint | Description |
|---|---|---|
POST | /api/analyze | Fast signal analysis (scalp/intraday/swing) |
POST | /api/deep-analysis | Multi-agent deep analysis with debate |
POST | /api/chart-analysis | Screenshot chart analysis (Claude Vision) |
POST | /api/watchlist-scan | Parallel multi-ticker scan |
GET | /api/daily-intel | Daily market intelligence (cached) |
GET | /api/news/{ticker} | News + sentiment scores |
GET | /api/profile | Trader behavior profile |
GET | /api/journal | Decision execution log |
POST | /api/scenario | What-if scenario simulation |
GET | /api/bias-profile | Prediction bias analysis |
GET | /api/role-memory | Role learning progress |
POST | /api/swarm-sim | Agent swarm simulation |
POST | /api/evolve-strategies | LLM strategy evolution |
GET | /api/alpaca/account | Paper trading account |
POST | /api/alpaca/execute | Execute signal as paper order |
WS | /ws/live | Real-time price + signal stream |
GET | /healthz | Liveness probe for Docker / K8s (no auth, no I/O) |
This repo includes .claude/skills/ — drop the folder into any Claude Code project and the agent learns these patterns automatically:
.claude/skills/tier-router/ — route Haiku for structured, Sonnet for reasoning (standalone).claude/skills/adversarial-debate/ — Advocate/Critic/Judge over any decision (standalone)Both skills are self-contained: copy the folder, no install needed.
orallexa/
├── api_server.py               # FastAPI + WebSocket server
├── docker-compose.yml          # One-click deployment
│
├── engine/                     # Trading engine (9 models + intelligence)
│   ├── multi_agent_analysis.py # Multi-agent pipeline (debate + panel + fusion + token-budget gates)
│   ├── signal_fusion.py        # 8-source signal fusion (tech/ML/news/options/institutional/social/earnings/polymarket)
│   ├── source_accuracy.py      # Per-source accuracy ledger (JSONL)
│   ├── dynamic_weights.py      # Accuracy → weight scaling for fusion
│   ├── token_budget.py         # Client-side token + USD budget enforcer
│   ├── context_compressor.py   # Extractive / LLM compression of chained agent text
│   ├── kronos_signal.py        # Kronos foundation-model wrapper (10th ML voice)
│   ├── shared_memory.py        # CORAL-style read aggregator (role + layered memory)
│   ├── historical_cache.py     # Prices / earnings / options cache schema
│   ├── news_aggregator.py      # Google News + Yahoo RSS dedupe
│   ├── layered_memory.py       # FinMem-style short/mid/long memory tiers
│   ├── regime_strategist.py    # Regime → strategy + params recipe
│   ├── portfolio_manager.py    # Final approval gate — concentration, sector, sizing
│   ├── earnings.py             # Earnings calendar + PEAD drift stats
│   ├── scenario_sim.py         # What-if scenario simulation (Opus 4.7 + xhigh)
│   ├── bias_tracker.py         # Prediction bias self-correction
│   ├── role_memory.py          # Persistent role memory & learning
│   ├── micro_swarm.py          # 20-agent Monte Carlo swarm
│   ├── ml_signal.py            # Model comparison framework
│   ├── strategies.py           # 7 rule-based strategies
│   ├── emaformer.py            # EMAformer Transformer
│   ├── diffusion_signal.py     # DDPM probabilistic forecasting
│   ├── gnn_signal.py           # Graph Attention Network
│   ├── rl_agent.py             # PPO reinforcement learning
│   ├── strategy_evolver.py     # LLM strategy evolution
│   └── sentiment.py            # FinBERT / VADER
│
├── llm/                        # AI reasoning
│   ├── claude_client.py        # Tier routing (FAST/DEEP/OPUS) + DEEP_EFFORT=xhigh
│   ├── call_logger.py          # JSONL log + PostHog + Langfuse triple sink
│   ├── provider.py             # Multi-provider abstraction (Anthropic + OpenAI)
│   ├── debate.py               # Bull/Bear debate (Judge on Opus 4.7 + xhigh)
│   ├── perspective_panel.py    # 4-role analyst panel with memory
│   ├── regime_llm.py           # Claude-backed regime strategy llm_fn
│   └── dspy_judge.py           # DSPy Phase A scaffold (lazy import, no compile)
│
├── orallexa-ui/                # Dashboard (Next.js 16)
│   ├── app/components/         # 13 UI components (incl. RegimeCard, PortfolioManagerCard)
│   ├── app/__tests__/          # 245 unit tests (vitest)
│   └── e2e/                    # 14 E2E tests (Playwright)
├── desktop_agent/              # Desktop AI coach
├── bot/                        # Execution layer (Alpaca)
├── tests/                      # ~800 backend tests
├── scripts/                    # Demo + eval + cron utilities
│   ├── demo_pipeline_e2e.py    # Live fusion → decision → PM smoke test
│   ├── compare_fusion_variants.py  # 5-src vs 8-src on identical inputs
│   ├── backtest_fusion_partial.py  # Synthetic time-series weight-policy A/B
│   ├── eval_context_compression.py # Compression safety harness
│   └── update_source_outcomes.py   # Daily forward-return backfill
├── docs/                       # Architecture + module catalogs
│   ├── NEW_MODULES.md          # 11+ Phase 7/8/9 modules with enable steps
│   ├── DSPY_MIGRATION.md       # 3-phase plan to compile prompts via MIPROv2
│   └── SESSION_2026-04-24.md   # Resumable state for continuation work
└── .github/workflows/          # CI (lint/test/build/E2E) + source-outcomes cron
Anthropic Claude · yfinance · Polymarket · Alpaca
MIT License — see LICENSE
Disclaimer: Research and educational project. Not financial advice.
Built with conviction, not hype.
Self-tuning multi-agent AI trading system. 8-source signal fusion, Bull/Bear/Judge debate on Claude Opus 4.7, Kelly + ATR position sizing. Python · Kalshi + Polymarket adapters.
See the code
8-source signal fusion · 10 ML models incl. Kronos · Bull/Bear/Judge debate on Claude Opus 4.7
Polymarket + Kalshi prediction markets vote alongside ML models. Weights adapt to per-source accuracy automatically.
Different from other AI-trading repos. Orallexa isn't a hedge-fund simulator. It's a calibrated multi-agent decision system with a published Brier log, a FinPos-style Risk Sizer that keeps direction and position sizing on separate agents, and a hard kill switch. Paper-only. Real money is gated behind a written Brier improvement, not vibes.
Live Demo · Presentation · Evaluation Report · 中文
Most AI trading projects: feed data into a model, get a signal, done.
Orallexa runs a multi-agent intelligence pipeline. 4 AI analysts with different risk profiles debate the trade. A 20-agent swarm simulates market reactions. 5 independent signal sources vote. A bias tracker corrects the system's own mistakes. Then it executes.
Market Data → 9 ML Models → 4-Role Panel + Bull/Bear Debate
    → 8-Source Signal Fusion → Judge Verdict → What-If Scenarios
    → Risk Plan → Portfolio Manager → Paper Execution → Dashboard → Social Content
Every stage automated. Every stage observable. The system learns from itself.
Open Live Demo — demo mode, no API key needed. Click NVDA, TSLA, or QQQ to see a full analysis.
Or run locally:
git clone https://github.com/alex-jb/orallexa-ai-trading-agent.git
cd orallexa-ai-trading-agent
pip install -r requirements.txt
echo "ANTHROPIC_API_KEY=your_key" > .env

# Terminal 1: API
python api_server.py


## ⚠️ Educational research, not financial advice

This repository is published for educational and research purposes. Nothing
here is investment, trading, or financial advice. The models, signals, and
outputs shown are experimental and may be wrong. Past performance does not
predict future results. Do not use any output as the basis for a real
trading, investment, or hedging decision without independent professional
verification. The author accepts no liability for losses.

# Terminal 2: UI
cd orallexa-ui && npm install && npm run dev
Docker: docker compose up --build — that's it.
| Strategy | Ticker | OOS Sharpe | Verdict | p-value |
|---|---|---|---|---|
| rsi_reversal | INTC | 1.41 | PASS | 0.002 |
| dual_thrust | NVDA | 0.96 | PASS | 0.001 |
| alpha_combo | NVDA | 0.92 | PASS | 0.016 |
| macd_crossover | NVDA | 0.91 | PASS | 0.003 |
| ensemble_vote | NVDA | 0.90 | PASS | 0.001 |
| trend_momentum | NVDA | 0.74 | PASS | 0.005 |
| double_ma | GOOG | 0.64 | PASS | 0.049 |
| ensemble_vote | META | 0.31 | MARGINAL | 0.324 |
90 strategy-ticker pairs across 10 tickers and 9 strategies (including ensemble vote and regime-aware ensemble). 1 STRONG PASS, 7 PASS, 33 MARGINAL. Full report →
Intelligence Layer
|
Execution Layer
|
What one NVDA analysis produces:
┌─────────────────────────────────────────────────────────────────┐
│  DECISION: BUY                    Confidence: 68%               │
│  Risk: MEDIUM                     Signal: 72/100                │
├─────────────────────────────────────────────────────────────────┤
│                                                                 │
│  BULL CASE:                                                     │
│  • Price above MA20 > MA50 — full bullish alignment             │
│  • RSI at 62 — strong momentum, not yet overbought              │
│  • Volume 1.8x average — institutional participation likely     │
│                                                                 │
│  BEAR CASE:                                                     │
│  • ADX at 32 but declining — trend may be exhausting            │
│  • Bollinger %B at 0.85 — extended near upper band              │
│  • Earnings in 12 days — vol crush after event                  │
│                                                                 │
│  JUDGE VERDICT:                                                 │
│  "Bull case is stronger. BUY with tight stop at MA20."          │
│                                                                 │
│  PROBABILITIES: Up 58% | Neutral 24% | Down 18%                │
│  RISK PLAN:                                                     │
│  Entry: $132.50 | Stop: $128.40 | Target: $141.00 | R:R 2.1:1  │
└─────────────────────────────────────────────────────────────────┘
Not just a number. A structured argument with transparent reasoning and an actionable risk plan.
Every analysis runs all available models. The ML Scoreboard shows Sharpe, return, win rate side by side.
| Model | Type | What It Does |
|---|---|---|
| Random Forest | Classification | 28 technical features → 5-day direction |
| XGBoost | Gradient Boosting | Same features, different optimization |
| Logistic Regression | Linear | Regularized baseline |
| EMAformer | Transformer | iTransformer + Embedding Armor (AAAI 2026) |
| MOIRAI-2 | Foundation | Salesforce zero-shot time series forecaster |
| Chronos-2 | Foundation | Amazon T5-based probabilistic forecaster |
| DDPM Diffusion | Generative | 50 possible price paths → VaR and confidence intervals |
| PPO RL Agent | Reinforcement | Gymnasium env, Sharpe-based reward |
| GNN (GAT) | Graph | 17-stock relationship graph, inter-stock signal propagation |
All models run on CPU.
Signal View — Decision card, probability bars, Bull/Bear debate, ML scoreboard, risk plan.
Intel View — Morning brief, gainers/losers, sector heatmap, volume spikes, AI picks, social thread.
Art Deco theme. Polymarket-inspired probability display. Mobile responsive. EN/ZH bilingual.
A floating pixel bull that lives on your desktop:
Not every task needs the expensive model:
| Task | Model | Cost |
|---|---|---|
| Bull/Bear arguments | Haiku 4.5 | ~$0.001 |
| 4-Role perspective panel | Haiku 4.5 | ~$0.002 |
| Judge verdict | Sonnet 4.6 | ~$0.005 |
| Deep market report | Sonnet 4.6 | ~$0.005 |
| What-if scenario | Sonnet 4.6 | ~$0.005 |
| Signal fusion + swarm | Local (no LLM) | $0 |
| Bias tracking | Local (no LLM) | $0 |
One full analysis: ~$0.005. One daily intel report: ~$0.05.
ORALLEXA_USE_CACHE=1 short-circuits every daily-grain yfinance call (earnings calendar, PEAD stats, watchlist volume, SPY 6-month, GNN per-ticker features, MarketDataSkill). Cache hits cost nothing and complete in milliseconds. Intraday and fast_info paths intentionally bypass — those need real-time data.
ORALLEXA_MULTIMODAL_SAMPLE=0.0..1.0 controls vision-augmented debate sampling. Default 0 is off (zero behavior change vs text-only). Setting e.g. 0.2 runs the Quant Researcher with both text and a K-line chart on ~20% of deep-analysis calls; the per-call diff is stashed on decision_log.extra.multimodal_diff and the nightly Multimodal Lift — Vision vs Text Eval workflow rolls it into a ship/reject verdict. Vision adds ~5× cost per sampled call, so 0.1–0.2 is the recommended prod range.
Two patterns from this repo have been extracted as standalone Python packages + Claude Code skills:
- claude-tier-router — the Haiku/Sonnet dual-tier routing (
pip install claude-tier-router)- claude-debate — the Bull/Bear/Judge adversarial decision pattern, generalized (
pip install claude-debate)
| Problem | Typical Approach | Orallexa |
|---|---|---|
| Isolated signals | One model, one prediction | 8 sources fused: technical + ML + news + options + institutional + social + earnings + prediction markets |
| No reasoning | "BUY 73%" — why? | 4 analysts debate, Bull/Bear argue, Judge decides with evidence |
| No self-correction | Same mistakes repeated | Bias tracker detects overconfidence, auto-adjusts future calls |
| Static analysis | Can't test hypotheticals | "What if Fed hikes 50bp?" — scenario simulation with swarm |
| Expensive AI | Every call hits GPT-4 | Haiku for 80%, Sonnet only where reasoning matters |
| Manual workflow | Notebook → read → decide → execute | Automated: signal → debate → risk plan → paper order |
| No context | Each stock analyzed alone | GNN propagates signals across 17 related stocks |
| Not shareable | Screenshot your terminal | "Copy for X" on every section |
Inspired by ai-hedge-fund. We share the multi-agent philosophy but take different approaches:
| Feature | ai-hedge-fund | Orallexa |
|---|---|---|
| ML Models | 0 (LLM-only) | 9 (RF, XGB, EMAformer, MOIRAI-2, Chronos-2, DDPM, PPO RL, GNN, LR) |
| Model Ranking | No | Auto-ranked by Sharpe ratio |
| LLM Providers | OpenAI, Groq, Anthropic, DeepSeek | Claude Sonnet + Haiku (dual-tier routing) |
| Cost per Analysis | ~$0.03+ (single-tier) | ~$0.003 (80% Haiku, 20% Sonnet) |
| Real-time Dashboard | Basic web UI | Next.js 16 with WebSocket, Art Deco theme |
| Paper Trading | No execution | Alpaca bracket orders (stop-loss + take-profit) |
| Daily Intelligence | No | 50+ tickers, sector rotation, AI morning brief |
| Desktop Assistant | No | Pixel bull with voice (Whisper + TTS) |
| Social Content | No | One-click "Copy for X" on every section |
| Walk-Forward Eval | No | 70 strategy-ticker pairs, OOS Sharpe |
| Tests | Limited | 698 automated (261 frontend + 437 backend) |
| Bilingual | No | EN/ZH |
| Frontend | Next.js 16, React 19, Tailwind CSS 4, PWA |
| Backend | FastAPI, Python 3.11, WebSocket |
| AI | Claude Sonnet 4.6 + Haiku 4.5 (dual-tier routing) |
| ML | scikit-learn, XGBoost, PyTorch (EMAformer, DDPM, GAT, PPO) |
| Data | yfinance (real-time + historical), parquet cache layer (`ORALLEXA_USE_CACHE=1`) |
| NLP | FinBERT, VADER, TextBlob |
| Trading | Alpaca paper trading (bracket orders) |
| Orchestration | LangGraph (stateful debate pipeline) |
| Deploy | Docker, GitHub Actions CI/CD, Vercel |
922 backend tests + 245 frontend = 1,167 total. 0 failures. CI on every push. 0 open issues.
python -m pytest tests/ -v             # Backend (922 tests)
cd orallexa-ui && npm test             # Frontend (245 unit tests)
cd orallexa-ui && npm run test:coverage # Frontend with coverage
cd orallexa-ui && npx playwright test   # E2E (16+ specs)
| Suite | Tests | Coverage |
|---|---|---|
| Engine Core | 62 | Backtest, 10 strategies, market analyst |
| Engine Integration | 34 | TA indicators, strategies, backtest, brain routing |
| ML/RL Signals | 20 | Feature extraction, RL env, PPO trainer |
| ML Regression | 13 | All 9 models — ensures upgrades don't degrade |
| API E2E + Healthz | 21 | Every endpoint via FastAPI TestClient + liveness probe |
| Unit Tests | 47 | DecisionOutput, BehaviorMemory, risk, scalping |
| Desktop Agent | 30 | Intent detection, ticker/mode/TF extraction |
| i18n (en/zh/ja) | 14 | Trilingual coverage + placeholder consistency |
| Daily Intel | 10 | Price fetch, constants, cache path |
| Sentiment | 21 | FinBERT/VADER fallbacks, rag/news mocks |
| VWAP Reversion | 13 | Signal gates, threshold band, edge cases |
| Historical Cache | 37 | get_prices, period helper, 4 wired call sites |
| Debate Stash | 7 | Bull/Bear/Judge → decision_log → eval-set extraction |
| DSPy Phase B Harness | 24 | Synthesizer, splitter, evaluator, readiness gates, loader |
| DSPy Judge | 13 | Phase A + load_compiled_judge with stubbed dspy |
| Backend Other | 67 | Monte Carlo, walk-forward, regime, ensemble, statistics |
| Backend Misc | 488 | Param optimizer, strategy evolver, breaking signals, … |
| UI Components | 245 | All 14 component suites + hooks + mock data |
| Playwright E2E | 16+ | Dashboard, components, responsive, offline |
| Total | 1,167 | 922 backend + 245 frontend |
| Method | Endpoint | Description |
|---|---|---|
POST | /api/analyze | Fast signal analysis (scalp/intraday/swing) |
POST | /api/deep-analysis | Multi-agent deep analysis with debate |
POST | /api/chart-analysis | Screenshot chart analysis (Claude Vision) |
POST | /api/watchlist-scan | Parallel multi-ticker scan |
GET | /api/daily-intel | Daily market intelligence (cached) |
GET | /api/news/{ticker} | News + sentiment scores |
GET | /api/profile | Trader behavior profile |
GET | /api/journal | Decision execution log |
POST | /api/scenario | What-if scenario simulation |
GET | /api/bias-profile | Prediction bias analysis |
GET | /api/role-memory | Role learning progress |
POST | /api/swarm-sim | Agent swarm simulation |
POST | /api/evolve-strategies | LLM strategy evolution |
GET | /api/alpaca/account | Paper trading account |
POST | /api/alpaca/execute | Execute signal as paper order |
WS | /ws/live | Real-time price + signal stream |
GET | /healthz | Liveness probe for Docker / K8s (no auth, no I/O) |
This repo includes .claude/skills/ — drop the folder into any Claude Code project and the agent learns these patterns automatically:
.claude/skills/tier-router/ — route Haiku for structured, Sonnet for reasoning (standalone).claude/skills/adversarial-debate/ — Advocate/Critic/Judge over any decision (standalone)Both skills are self-contained: copy the folder, no install needed.
orallexa/
├── api_server.py               # FastAPI + WebSocket server
├── docker-compose.yml          # One-click deployment
│
├── engine/                     # Trading engine (9 models + intelligence)
│   ├── multi_agent_analysis.py # Multi-agent pipeline (debate + panel + fusion + token-budget gates)
│   ├── signal_fusion.py        # 8-source signal fusion (tech/ML/news/options/institutional/social/earnings/polymarket)
│   ├── source_accuracy.py      # Per-source accuracy ledger (JSONL)
│   ├── dynamic_weights.py      # Accuracy → weight scaling for fusion
│   ├── token_budget.py         # Client-side token + USD budget enforcer
│   ├── context_compressor.py   # Extractive / LLM compression of chained agent text
│   ├── kronos_signal.py        # Kronos foundation-model wrapper (10th ML voice)
│   ├── shared_memory.py        # CORAL-style read aggregator (role + layered memory)
│   ├── historical_cache.py     # Prices / earnings / options cache schema
│   ├── news_aggregator.py      # Google News + Yahoo RSS dedupe
│   ├── layered_memory.py       # FinMem-style short/mid/long memory tiers
│   ├── regime_strategist.py    # Regime → strategy + params recipe
│   ├── portfolio_manager.py    # Final approval gate — concentration, sector, sizing
│   ├── earnings.py             # Earnings calendar + PEAD drift stats
│   ├── scenario_sim.py         # What-if scenario simulation (Opus 4.7 + xhigh)
│   ├── bias_tracker.py         # Prediction bias self-correction
│   ├── role_memory.py          # Persistent role memory & learning
│   ├── micro_swarm.py          # 20-agent Monte Carlo swarm
│   ├── ml_signal.py            # Model comparison framework
│   ├── strategies.py           # 7 rule-based strategies
│   ├── emaformer.py            # EMAformer Transformer
│   ├── diffusion_signal.py     # DDPM probabilistic forecasting
│   ├── gnn_signal.py           # Graph Attention Network
│   ├── rl_agent.py             # PPO reinforcement learning
│   ├── strategy_evolver.py     # LLM strategy evolution
│   └── sentiment.py            # FinBERT / VADER
│
├── llm/                        # AI reasoning
│   ├── claude_client.py        # Tier routing (FAST/DEEP/OPUS) + DEEP_EFFORT=xhigh
│   ├── call_logger.py          # JSONL log + PostHog + Langfuse triple sink
│   ├── provider.py             # Multi-provider abstraction (Anthropic + OpenAI)
│   ├── debate.py               # Bull/Bear debate (Judge on Opus 4.7 + xhigh)
│   ├── perspective_panel.py    # 4-role analyst panel with memory
│   ├── regime_llm.py           # Claude-backed regime strategy llm_fn
│   └── dspy_judge.py           # DSPy Phase A scaffold (lazy import, no compile)
│
├── orallexa-ui/                # Dashboard (Next.js 16)
│   ├── app/components/         # 13 UI components (incl. RegimeCard, PortfolioManagerCard)
│   ├── app/__tests__/          # 245 unit tests (vitest)
│   └── e2e/                    # 14 E2E tests (Playwright)
├── desktop_agent/              # Desktop AI coach
├── bot/                        # Execution layer (Alpaca)
├── tests/                      # ~800 backend tests
├── scripts/                    # Demo + eval + cron utilities
│   ├── demo_pipeline_e2e.py    # Live fusion → decision → PM smoke test
│   ├── compare_fusion_variants.py  # 5-src vs 8-src on identical inputs
│   ├── backtest_fusion_partial.py  # Synthetic time-series weight-policy A/B
│   ├── eval_context_compression.py # Compression safety harness
│   └── update_source_outcomes.py   # Daily forward-return backfill
├── docs/                       # Architecture + module catalogs
│   ├── NEW_MODULES.md          # 11+ Phase 7/8/9 modules with enable steps
│   ├── DSPY_MIGRATION.md       # 3-phase plan to compile prompts via MIPROv2
│   └── SESSION_2026-04-24.md   # Resumable state for continuation work
└── .github/workflows/          # CI (lint/test/build/E2E) + source-outcomes cron
Anthropic Claude · yfinance · Polymarket · Alpaca
MIT License — see LICENSE
Disclaimer: Research and educational project. Not financial advice.
Built with conviction, not hype.



