
An LLM coding terminal interface written entirely in Java
Java
0
7 commits
updated Sep 30, 2026
See what people are saying
README
CadetCoder
CadetCoder is a Java 17+ command-line coding assistant. Point it at a model provider. It then reads, searches, edits and commits files in your project, either from a direct command or from a request in plain English. It ships connectors for 23 providers, among them Anthropic, OpenAI, OpenRouter, Google, Amazon Bedrock, GitHub Copilot, Groq and a local OpenAI-compatible endpoint.
The agent loops (chat, agent and workers) search the codebase, propose
edits and run checks. Uber mode makes the model confirm that the work is
finished before a run ends. CadetCoder also ships a full-screen interactive
shell, timers, background jobs, sessions, themes and prompt templates. Requests
ask providers for zero data retention by default.
Build it with mvn clean package -DskipTests. The jar lands at
target/CadetCoder-1.0-SNAPSHOT.jar.
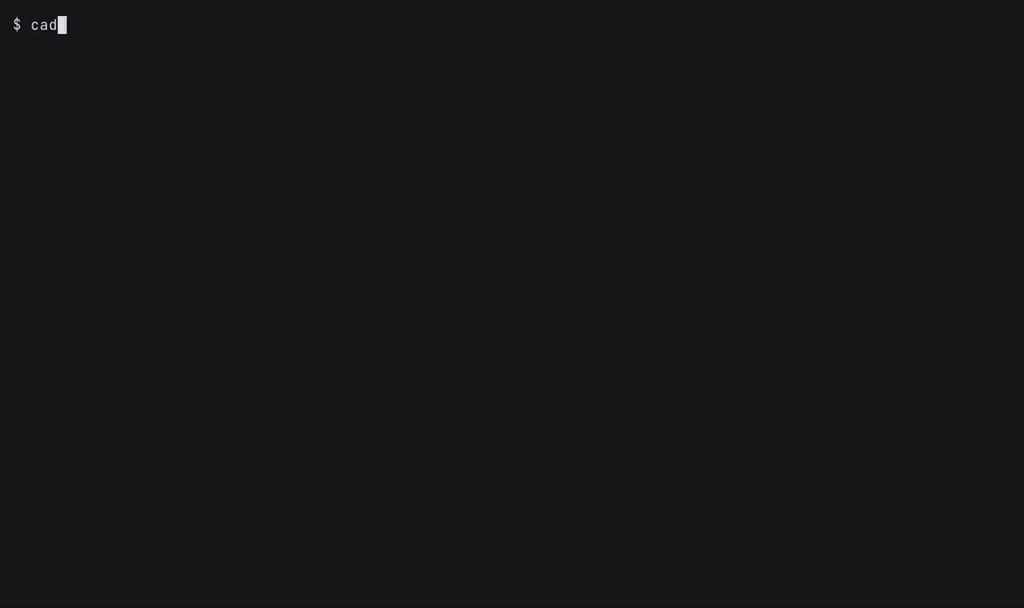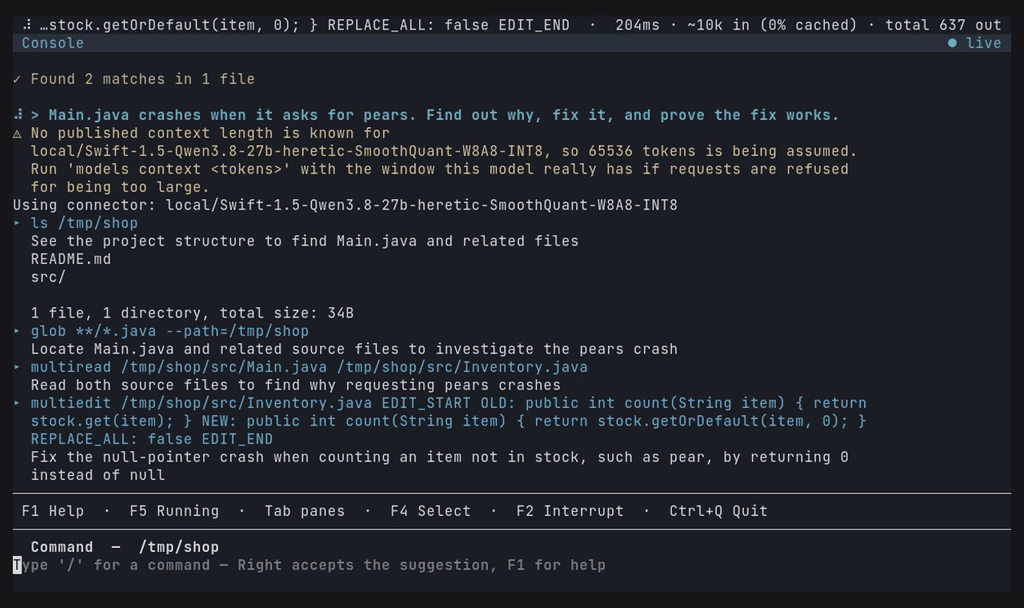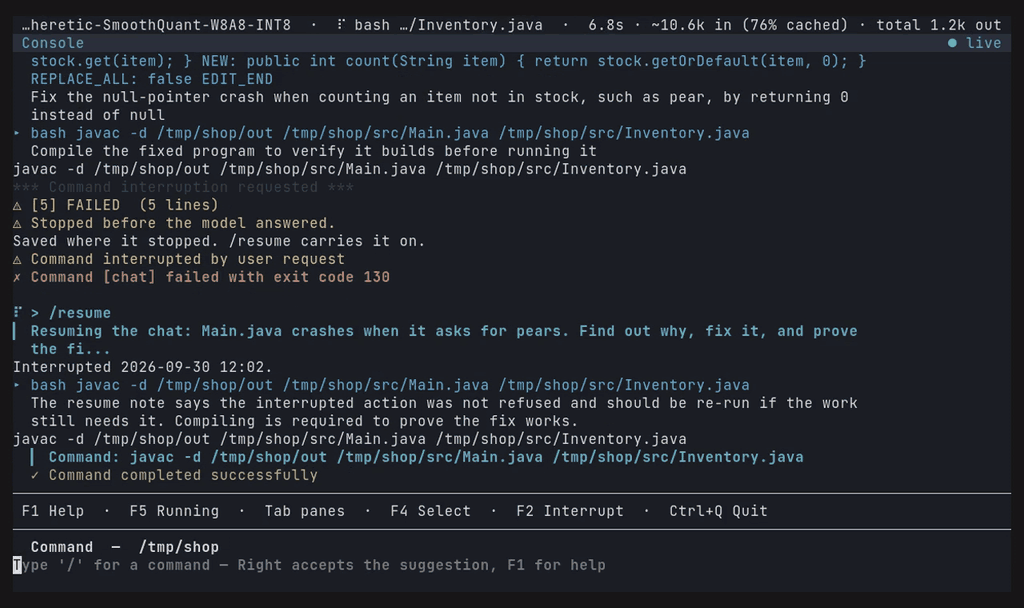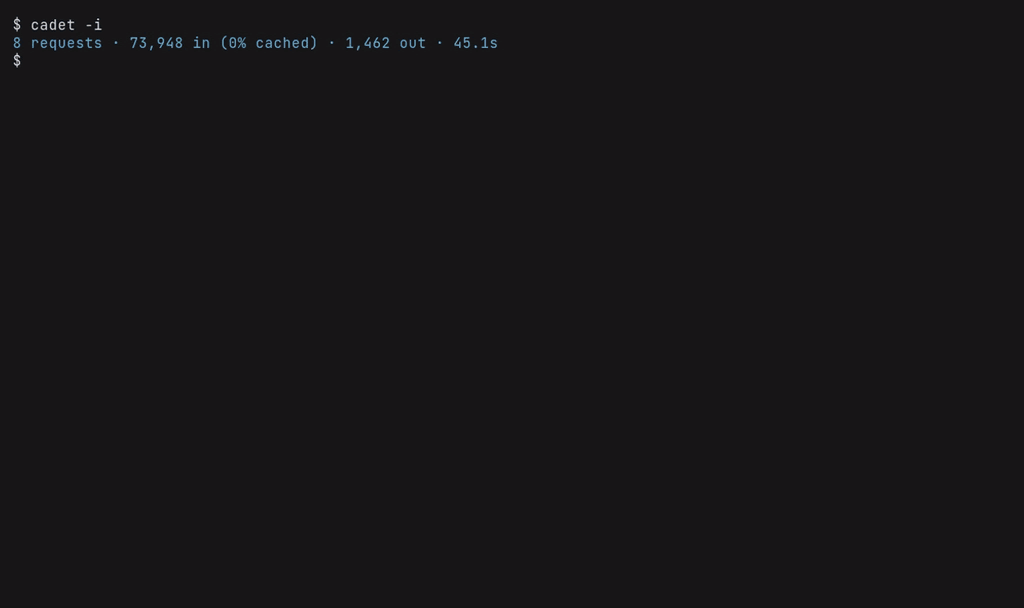
The tour runs a local model. The waits for the model play at up to three times normal speed.
Contents
- Requirements
- Install
- Set up a provider
- Your first task
- The agent harness
- Workers
- Timers
- Background jobs
- Uber mode
- Resume an interrupted run
- Read the output
- Command output
- How commands are dispatched
- Command reference
- Global options
- Configuration
- Interactive shell
- Themes and templates
- Limitations
- Build and test
- Project layout
- Further documentation
- Licence
Requirements
| Requirement | Detail |
|---|---|
| Java | 17 or newer. Built and tested on 17 and 21. |
| Maven | Needed to build. Needs network access to Maven Central and the Central snapshot repository. See Install. |
| Git | Optional. Needed for commit, push and undo, and for auto-commit. |
| A model provider | An API key for one connector, or a local OpenAI-compatible server. The default local endpoint is http://localhost:8012. |
A native access warning on JDK 22 and newer
The jar bundles JLine's terminal provider for java.lang.foreign, the API that
became final in JDK 22. On JDK 17 and JDK 21 the shell starts without any
warning; both were tested. On JDK 22 and newer the JVM may print a notice like
this before the program starts. JDK 22 was not available to test, so this is
not confirmed.
WARNING: A restricted method in java.lang.foreign.Linker has been called
WARNING: java.lang.foreign.Linker::downcallHandle has been called by the unnamed module
WARNING: Use --enable-native-access=ALL-UNNAMED to avoid a warning for this module
The JVM prints that text, and no code inside the program can suppress it. Pass
--enable-native-access=ALL-UNNAMED before -jar to silence it.
Install
git clone <repository-url> cadetcoder
cd cadetcoder
mvn clean package -DskipTests
The executable jar lands at target/CadetCoder-1.0-SNAPSHOT.jar. Define an
alias for the examples below.
alias cadet='java -jar /absolute/path/to/target/CadetCoder-1.0-SNAPSHOT.jar'
On a machine with several JDKs, pin 17 in the alias.
alias cadet='/usr/lib/jvm/java-17-openjdk/bin/java -jar /absolute/path/to/target/CadetCoder-1.0-SNAPSHOT.jar'
CadetCoder writes its state to ~/.cadet/ on first run. That covers the
config, sessions, logs, index and model cache.
If the build cannot resolve TamboUI
The interactive shell depends on dev.tamboui:*:0.5.0-SNAPSHOT. That artifact
is published only to the Central snapshot repository, which pom.xml declares
as central-snapshots. A catch-all mirror in your ~/.m2/settings.xml
intercepts that repository too, and the build then fails to resolve TamboUI.
<mirror><id>nexus</id><mirrorOf>*</mirrorOf><url>https://nexus.example.com/...</url></mirror>
Fix it in one of two ways. Either make the mirror proxy the Central snapshot repository, or exclude the snapshot repository from the mirror.
<mirrorOf>*,!central-snapshots</mirrorOf>
Set up a provider
CadetCoder needs a model before it can do anything AI-driven. Three commands
cover the setup. Run models to see what exists, login to authenticate, and
models use to select. All three work from the command line.
1. See what is available
cadet models              # catalog summary, then the 23 connectors
cadet models providers    # connector table: protocol, auth scheme, env vars
cadet models anthropic    # the models one provider offers
cadet models find claude  # search model ids and names across every provider
A wire protocol is the request and response shape a provider accepts.
CadetCoder implements four: OpenAI Chat Completions, Anthropic Messages, Google
Generative AI (generateContent), and Amazon Bedrock Converse with SigV4
signatures.
cadet models providers names the exact environment variable each connector
reads, along with its protocol, auth scheme and retention control.
anthropic              Anthropic                  ANTHROPIC_MESSAGES              X_API_KEY       provider default  ANTHROPIC_API_KEY
google                 Google                     GOOGLE_GENERATIVE_AI            X_GOOG_API_KEY  provider default  GEMINI_API_KEY,GOOGLE_GENERATIVE_AI_API_KEY
amazon-bedrock         Amazon Bedrock             BEDROCK_CONVERSE                AWS_SIGV4       provider default  AWS_BEARER_TOKEN_BEDROCK,AWS_ACCESS_KEY_ID,AWS_SECRET_ACCESS_KEY
openai                 OpenAI                     OPENAI_CHAT                     BEARER          no storage        OPENAI_API_KEY
openrouter             OpenRouter                 OPENAI_CHAT                     BEARER          zero retention    OPENROUTER_API_KEY
commandcode            Command Code               OPENAI_CHAT/ANTHROPIC_MESSAGES  BEARER          zero retention    COMMAND_CODE_API_KEY,CMD_API_KEY
local                  Local (OpenAI-compatible)  OPENAI_CHAT                     NONE            provider default  -
The full list of 23 also covers xAI, Azure OpenAI, Cloudflare AI Gateway, Cloudflare Workers AI, GitHub Copilot, OpenCode Zen, OpenCode Go, Groq, DeepSeek, Cerebras, Fireworks AI, Together AI, Baseten, DeepInfra, Mistral and Perplexity.
A connector normally speaks one protocol for every model it offers. A gateway
that resells several vendors need not. Command Code serves its Claude models
only from the Anthropic Messages endpoint and everything else only from Chat
Completions, and each endpoint refuses the other's models. CadetCoder therefore
chooses the protocol per model rather than per provider. Run
cadet models commandcode to list what that gateway currently offers.
CadetCoder asks the gateway directly, because models.dev carries no entry for
it.
2. Provide a credential
Option A is an environment variable. It works everywhere and stores nothing.
Export the variable that models providers listed, and the connector picks it
up.
export ANTHROPIC_API_KEY=sk-ant-...
cadet models use anthropic claude-sonnet-4-5
Option B is login, which saves the key into ~/.cadet/config.json.
cadet login              # pick a provider from a numbered list, then authenticate
cadet login anthropic    # authenticate one provider directly
cadet login status       # per-connector credential status; keys are never printed
cadet login logout openai
login reads the key with System.console().readPassword(...), so the
terminal does not echo it and your shell history does not record it. This needs
a real terminal. System.console() returns null when output is piped, under
CI, and on the interactive shell's prompt line. In those cases login refuses
to read the key rather than echo it, and it names the environment variable
instead.
⚠ Cannot read the API key here without showing it on screen, so it will not be
  requested on this prompt for security.
Export ANTHROPIC_API_KEY before starting, then run 'login anthropic' again.
Alternatively, run the 'login anthropic' command from a real terminal (outside the TUI) where the key can be typed without being echoed.
That refusal is intended. Use Option A in any context without a terminal.
GitHub Copilot takes no API key. Run cadet login github-copilot or
cadet copilot login to start the OAuth device flow. The command prints a user
code and then waits for you to authorise it in a browser. CadetCoder caches the
token in ~/.cadet/copilot-auth.json.
Disclaimer. CadetCoder is not affiliated with or endorsed by GitHub. The Copilot login uses the OAuth client ID of GitHub's own Copilot editor integrations, because GitHub does not issue one to other tools. GitHub's terms may not permit that use. GitHub could revoke access or restrict your account. Use the Copilot connector at your own risk. The login shows this notice before it contacts GitHub.
After a successful login, CadetCoder offers to make that provider active and to
pick a model. Set it later with models use if you decline.
3. Select the active model
cadet models use openai gpt-4o    # set provider and model directly
cadet models use anthropic        # set provider, then prompt for a model (needs a TTY)
cadet models select               # interactive: pick provider, then model (needs a TTY)
cadet models current              # show what is active, and whether it has a credential
models use <provider> <model> is the non-interactive form. Use it in scripts.
4. Verify
cadet models current
▎ Active model
  Provider: anthropic (Anthropic)
  Model:    claude-sonnet-4-5
  Window:   200,000 input tokens (published for anthropic/claude-sonnet-4-5)
  Auth:     configured (saved key)
Window: gives the model's input window and where that figure came from. Run
models context <tokens> to set the window for the active model. Run
models context clear to remove that setting.
Auth: reports one of six states.
configured (saved key)configured (env <VAR>)authenticated (device flow)for GitHub Copilot after a loginnot logged infor GitHub Copilot before a loginno key requiredfor thelocalconnectorno credential
With no connector selected, models current prints
No connector provider is configured (falling back to the legacy local/API client). CadetCoder then sends requests to ai.localEndpoint, which defaults
to http://localhost:8012. Every AI command fails with
java.net.ConnectException when nothing listens there.
Per-invocation override
You need not persist anything.
cadet --provider groq --model llama-3.3-70b-versatile --provider-key "$GROQ_API_KEY" "..."
cadet --provider anthropic --model claude-sonnet-4-5 "summarize Main.java"
Amazon Bedrock takes its credentials from the standard AWS chain.
export AWS_ACCESS_KEY_ID=... AWS_SECRET_ACCESS_KEY=... AWS_REGION=us-east-1
cadet --provider amazon-bedrock --model anthropic.claude-3-5-sonnet-20240620-v1:0 "..."
Zero data retention
Every request carries the files, diffs and prompts of whatever you work on, so
ai.zeroDataRetention is on by default. CadetCoder asks each provider not to
retain the request wherever the provider accepts such a request. Where no
control exists, nothing changes, so the setting costs nothing on those
providers.
Three connectors implement a control, and they do not all promise the same
thing. The Retention column of cadet models providers reports which is which.
| Connector | How CadetCoder asks | What you get |
|---|---|---|
| Command Code | x-cmd-zdr: 1 header, on both of its protocols | zero retention: the gateway refuses the request rather than route it to an upstream that would keep it |
| OpenRouter | provider.zdr in the request body | zero retention: routed only to upstreams that agreed not to keep it |
| OpenAI | store: false in the request body | no storage, which is weaker. See below. |
OpenAI offers no per-request zero retention. store: false keeps the exchange
out of the stored history that the account can read back. OpenAI still retains
abuse-monitoring logs for up to thirty days, and no request parameter turns
that off. OpenAI arranges true zero retention for an organisation or project
rather than per request. CadetCoder therefore reports "no storage" for OpenAI
and "zero retention" for the other two.
CadetCoder sends OpenRouter provider.zdr rather than
provider.data_collection: deny. The second field is a promise about training
rather than about retention, and sending it would report a guarantee that
nobody gave.
A provider can refuse the request. A gateway that resells a model whose upstream
will not agree to zero retention answers with an error rather than retain the
request quietly. Command Code answers 422, and the message names both ways
out.
Provider 'commandcode' has no zero-retention upstream for model 'Qwen/Qwen3.8-Flash' (HTTP 422),
so it refused the request rather than retain it. Either choose a model whose upstream does promise
it, or allow retention deliberately with `cadet config ai.zeroDataRetention false`.
Most models have a zero-retention upstream. Prefer a switch of model over a change to the setting, because the setting is global and the gap is usually specific to one model.
Your first task
Non-AI commands work with no provider configured. Start there to confirm the install.
$ cd ~/my-project
$ cadet ls -l
-rw-rw-rw-      86B   2 min ago  Foo.java
-rw-rw-rw-      12B   2 min ago  README.md

 2 files, 0 directories, total size: 98B

$ cadet grep -n class
▎ Foo.java
    1: public class Foo { ... }

✓ Found 1 match in 1 file

$ cadet read Foo.java
Substituted path: 'Foo.java' -> './Foo.java'
▎ File: /home/you/my-project/Foo.java
     1	public class Foo { ... }
Then try a real AI task, once a provider is set up.
$ cadet "add a null check to the constructor in Foo.java and explain what you changed"
The first word is no recognised command, so CadetCoder routes the whole string
to chat. chat runs an agentic loop. It may call glob and grep to locate
files, read them, propose edits as SEARCH/REPLACE blocks, and ask before it
writes. bash and write ask for confirmation unless you pass -f.
There is no iteration limit. A task runs until it completes, fails, or stops making progress. A fixed ceiling is the wrong stop condition in both directions. It cuts off long tasks that work steadily, and it does nothing about a run stuck on step three.
The loop guard ends a stuck run. It refuses only repetition that cannot produce new information. It refuses an action in three cases:
- The same command with the same arguments already produced the same result twice.
- A multi-step sequence repeats with identical results.
- Ten consecutive commands return nothing that was not already seen.
Normal work is never blocked. That covers reads of many different files, several different searches, and a re-read of a file after an edit. On a refusal, CadetCoder tells the model which invocation repeated and what to do instead. The run stops once the guard refuses several proposed actions in a row.
Ten commands propose no actions: explain, analyze, refactor, suggest,
search, commit, edit, multiedit, webfetch and websearch. The same
principle applies to what the model returns for those. When a
reply repeats the one before it, the next request carries a short note that
says so, plus a unique id, so a provider that answers deterministically cannot
return the same bytes again. The run stops when the reply still repeats after a
few turns.
You can still impose your own budget. Use cadet agent -m <steps> or
-t <seconds>, or set -Dcadet.iterative.maxIterations=<n>, where 0 means
unlimited. None of them is set by default.
CadetCoder batches reads. multiread returns several files in a single call,
so five files cost one model round trip instead of five.
Request metrics
Every request prints one line when it completes.
~5,460 in (5,348 cached · 112 new) · ~340 out · 4.2s · 1,300 in/s · 81 out/s (47 over 5s)
in (cached · new)splits the input. cached is the provider's own count of cached input tokens when the provider reports one. Otherwise it is the leading part of this request that is byte-identical to the previous one, which is the part a provider can serve from a cached prefix. new is the rest. See prompt reuse.outcounts the tokens the model produced. CadetCoder reports input and output separately, because providers price them differently and the two move independently. A run can shed input through compaction while its output stays flat, and the two numbers say which one is the problem.4.2sis the wall-clock time for the request.1,300 in/sis the input processed per second for that request.81 out/sis the generation speed for that request alone. The figure in brackets is the trailing five-second session rate.
The shell shows the same figures as they accumulate while a request is in flight.
4.2s · ~5.6k in (96% cached) · total ~3.1k out
The elapsed time ticks, so you can tell a slow provider from a hung one. The cached share is a percentage rather than a count, because the count is not yet final. The output figure is the session total, because the current request's own output is unknown until it arrives.
A leading ~ marks an estimated figure. CadetCoder uses the provider's own
token counts where the provider reports them, and then omits the ~. Where the
provider reports none, CadetCoder estimates at roughly four characters per
token, because it talks to four wire protocols and ships none of their
tokenizers. Treat a marked figure as a relative measure rather than a billing
one. The in-flight line above always carries the mark, because a provider sends
its counts with the response. Suppress the line with
-Dcadet.metrics.show=false.
CadetCoder prints a cumulative summary at exit when the run made at least one request.
Prompt reuse
CadetCoder builds every turn's prompt append-only. Turn N+1 is turn N plus the new exchange. Prompt caching needs that property, because a provider can then serve the shared leading prefix from cache and process only the tail.
Measured over an eight-turn conversation, the reusable region beyond the system prompt grows by roughly one exchange per turn. The system prompt is stable for the whole run.
Keep this invariant if you change how CadetCoder assembles prompts. Nothing
volatile may go anywhere except the very end. That covers a timestamp, an
iteration counter and a re-computed snippet. The transcript may only ever be
appended to. PromptCachePrefixTest fails if that stops holding.
Cache breakpoints
A stable prefix is necessary but not sufficient. Some providers cache automatically. Others cache only what the request explicitly marks.
| Provider or protocol | What CadetCoder sends | Why |
|---|---|---|
| Anthropic Messages | cache_control: {"type":"ephemeral"} on the system block and the user block | Anthropic caches nothing without a breakpoint |
| Bedrock Converse | a {"cachePoint":{"type":"default"}} block after the system and user content | the same, in Converse's spelling |
| OpenRouter | cache_control inside the content parts | OpenRouter forwards it to the Anthropic and Gemini models it proxies |
| OpenAI and OpenAI-compatible providers | nothing | these match a shared prefix automatically, and an unrecognised field would risk a rejection |
| Google Generative AI | nothing | implicit caching is automatic, and the explicit mode is a separate stateful cachedContents resource rather than a per-request marker |
CadetCoder uses two breakpoints where they apply: the system prompt, which is stable for the whole run, and the end of the conversation so far. The second breakpoint writes the whole prompt into the cache. The next turn appends to it, reads everything from cache, and pays only for what it added.
Breakpoint support depends on the model rather than on the provider alone.
Bedrock rejects cachePoint outright for models that do not implement it.
CadetCoder therefore treats caching as an optimisation that may fail. A
rejection that names a cache field disables breakpoints for that provider and
model for the rest of the process, retries once without them, and warns. A
rejection for any other reason passes through untouched. Disable breakpoints
up front with -Dcadet.cache.breakpoints=false. CadetCoder sends no breakpoint
on a prompt shorter than 4,096 characters, because providers ignore a cache
marker on a prefix that short.
When a request fails
CadetCoder retries only failures that can plausibly change outcome on a second try: 408, 429, 5xx, and transport errors. It does not retry a 400 or a 401, because a repeat of a malformed or unauthorised request produces the same answer more slowly.
A 200 is not automatically a success. Status codes describe the HTTP exchange rather than the provider behind it. Two things arrive under a 200 and mean "try again": a gateway in front of the model answers with its own error payload, and a body is cut off in flight. Both look like "the model replied with nothing" under a check of the status alone, which is terminal, so a run that had already made twenty good requests would die on a blip.
The check is structural rather than a search of the body text. A completion's
text is arbitrary. Ask this tool why a provider rate-limits you, and the
correct answer contains every word that a naive scan looks for. CadetCoder
therefore reads failure wording only inside a top-level error node, which a
successful response does not have. It tells an unparseable body apart the same
way. A body that starts as JSON and stops was truncated in flight, so
CadetCoder retries it. A body that was never JSON means the endpoint does not
speak the protocol, which is a misconfiguration that no retry can fix.
CadetCoder bounds every request rather than completions alone. The health probes, the models.dev catalog fetch and the OAuth device flow all go through one helper that cannot block forever. A probe that hangs at startup stops the CLI as dead as a completion that hangs mid-run.
Two timeouts apply, because they bound different things. HttpRequest.timeout
in the JDK covers the wait for response headers only. That was measured rather
than assumed: a two-second timeout let a six-second body through untouched.
The split suits a completion, because time-to-first-byte is predictable while
generation time scales with the answer. On its own it leaves a hole. Once
headers arrive, a body that stops mid-flight without a closed connection blocks
forever, and the run freezes with no timeout and no retry.
cadet.llm.responseDeadlineSeconds is the backstop for that case. Set it far
above any real generation time rather than as a latency budget.
CadetCoder drops pooled connections before the far end drops them. The JDK keeps an idle connection for 1200 seconds by default. Almost nothing in front of a model API holds one that long: an AWS load balancer closes at 60 seconds and nginx at 75. The pool then hands back sockets that the far end closed minutes ago, and the next request fails as an unreachable provider. An agentic run makes that routine, because its gaps are exactly this long. CadetCoder sets 50 seconds instead, below the tightest of them. A lost reuse costs one TLS handshake. A dead connection costs a request.
The retried set is exactly the set that rewards persistence, so the budget is generous. CadetCoder makes 10 attempts by default, with exponential backoff from 500 ms, capped at 20 s per wait and jittered so that concurrent runs do not resynchronise. The worst case is roughly a minute and a half of waiting before a run gives up, and about half that in practice.
The shell offers one more attempt once the automatic attempts are spent. It does so only when a terminal exists to ask, and only for a failure that a retry can fix. A rejected key gets no offer.
✗ AI request failed: 503 Service Unavailable
Enter to retry, or 'stop' to end the run >>>
Enter, retry, or y tries again. Anything else ends the run. The alternative
discards a run that already made twenty successful requests, because the
twenty-first hit a provider that was briefly down. A script, a pipe and CI have
nobody to ask, so the failure propagates as before and the exit code does not
change. End-of-input counts as "stop" for the same reason, because a loop on an
EOF that will never change would hang. Suppress the prompt on a terminal with
-Dcadet.manualRetry=false.
| Property | Default | Effect |
|---|---|---|
cadet.llm.maxAttempts | 10 | total attempts including the first; clamped to 20 |
cadet.llm.retry.baseDelayMs | 500 | first backoff, doubled from there |
cadet.llm.retry.maxDelayMs | 20000 | ceiling on a single wait |
cadet.manualRetry | true | offer Enter-to-retry once the budget is spent |
cadet.llm.connectTimeoutSeconds | 10 | establish the TCP and TLS connection |
ai.completionTimeoutSeconds (config) | 300 | wait for response headers, which is the whole generation because nothing streams |
cadet.llm.responseDeadlineSeconds | 600 | whole exchange including the body; a stall backstop |
jdk.httpclient.keepalive.timeout | 50 | idle pooled-connection lifetime; set unless you set it |
CadetCoder honours the provider's Retry-After-Ms header ahead of
Retry-After, and accepts Retry-After in both RFC 7231 forms, delay-seconds
and HTTP-date. The millisecond form matters at the short end. A provider that
asks for 200 ms must express it as Retry-After: 1, which rounds up to five
times the wait it wanted. A Retry-After longer than
cadet.llm.retry.maxDelayMs ends the retries, because the provider asked for a
pause longer than the CLI waits.
The agent harness
chat answers a request. Use agent for work that you want evidence for. It
runs under the agent harness, which records that evidence.
cadet agent "make the action parser reject an empty ARGS block, with a test"
cadet agent "fix the failing build" -c "bash mvn -o -q test"
The loop has four stages: observe, deliberate, commit, observe. Each turn the harness shows the agent where the world is. The agent then thinks, and it has exactly one way to change anything.
- The ledger records every step. The harness appends what the agent observed, what it did and what happened next to a hash-chained ledger. The ledger is the run's ground truth, and nothing rewrites it.
- The agent writes its beliefs as an executable model. It states how it
thinks this project behaves as a small program, and
certifyreplays the whole ledger through that program. A certificate reports two things: the model reproduced every transition, and the ledger exercised these particular rules. A rule that the ledger never touched is untested, however green the run reads. - Every change reaches the world through the commit gate. The gate admits a plan when a green certificate covers the current ledger head. It cuts the plan off at the first step that turns on a rule the ledger has never exercised, so the agent acts on an untested belief once, under observation, and never builds on it. With no model at all, an agent gets a blind probe of three actions and no more. An irreversible action needs a certified model behind it. The policy belongs to whoever started the run, because an agent that could widen its own gate would not have one.
- The agent's actions are the commands you type. It acts through the same
registry as the CLI and the shell, under the same confirmation and path
rules. CadetCoder marks what the agent runs as a model's doing, so a
quitends the agent's own run rather than your session. The agent cannot start a second agent or a chat inside itself.
Every run keeps its own record under .cadet/runs/<timestamp>-<unique>/. The
record holds what the run was asked to do, how it ended, the ledger, the models
the agent wrote, its beliefs and its notes. The last line of a run says what to
type to read that record back. No two runs share a directory, so eight workers
leave eight readable records. runs lists them newest first, runs show opens
one, and runs ledger prints the last things that really happened.
What "done" means. Without -c, a run ends when the agent declares the
work finished. With -c <command>, that command runs after every action and
its exit code decides: the task is done when the check exits 0, whatever the
agent believes. agent itself exits 0 only for a task that finished, either by
the check or by the agent's declaration. A run that spent its allowance or gave
up exits 1. A run that you called off exits 130. Its record is complete in
every case and worth a read.
Budgets are yours to impose, and none is set by default. -m <steps>
bounds how many times the agent may think. -t <seconds> bounds how long the
whole run may take. --classic asks for the classic loop, which keeps no
ledger and no record. You have to ask for it by name, because a run that
downgraded itself quietly would report the same work with none of the evidence
behind it.
When a run stops learning. Four rounds of thought that certify nothing new
and fix no mispredictions make a plateau. The harness measures that off the
record rather than asks the agent, because an agent inside a loop always has a
reason for the next step, which is why it cannot tell that the last four
produced nothing. A plateau hands the run to the model that ai.escalateTo
names, with the beliefs and the latest certificate in front of it and a note
that says what it has walked into. The run's record counts the hand-over.
cadet config ai.escalateTo gpt-5 # a model on the provider you are already connected to
Nothing is named by default, because which of two models is the stronger one is a fact about the account that pays for them. A run that stalls with nobody to hand to says so once and says what to set. That is not an error and does not stop the run, because an agent that explores a part of a project it has no model for legitimately certifies nothing for a while.
Workers
Some questions are wide rather than deep. Examples: review this change for correctness, for security, and for test coverage; or search four subsystems for the same defect. One agent answers those in sequence. It carries every earlier answer in its context and gets slower and less focused as it goes.
cadet workers "review error handling" "review test coverage" -b "the net package"

cadet workers start "<task>" "<task>"   # start them and carry on
cadet workers status                    # who has finished, who is still going
cadet workers wait [<seconds>]          # block until they finish
cadet workers stop                      # end them, and keep what finished
cadet workers list                      # summary of the last run
cadet workers show 2                    # one worker's output in full
Each worker may think 12 times by default. Pass -m <steps> to change that.
CadetCoder tells the model the whole lifecycle rather than how to start alone. A capability the model cannot discover how to read or stop is one it will either abandon mid-run or wait on forever, so the command catalog in every agentic system prompt carries every verb, and the limits the model would otherwise learn by refusal. Workers themselves get the catalog without this entry, because an offer of a capability that is refused on use costs a turn and teaches nothing.
A worker cannot ask you anything, because nobody watches its output while it
runs. With security.commandApproval at its default, manual, a worker's
shell commands that need approval are therefore refused. Set it to auto if
you want workers to run shell commands, and accept that the model then
approves them.
Only one run exists at a time. CadetCoder refuses a second start while one is going rather than queue it. A queue would double the agents pointed at one provider, and it would make every later question about "the workers" ambiguous.
Every first word that is not one of those verbs is a task, so CadetCoder
reports a misspelled verb such as workers staus rather than run it.
Otherwise a typo starts an agent whose task is the typo, at the provider's
price, and answers a question about the workers by doing something else.
CadetCoder tests a single bare word this way alone, because a task is a
sentence and workers "stop the memory leak" is a task. To insist on the one
word, name the verb: workers start "staus".
Each worker runs its own agent over the same briefing and its own task. The briefing is identical across workers and comes first in every prompt, so a provider can serve it from a cached prefix. The task differs per worker and goes last, which follows the same append-only discipline as the main loop.
Workers never see each other's output. Two reasons hold. Different context makes findings incomparable, because a disagreement might be a real conflict or two agents that looked at different things. Shared output makes workers converge on whatever the first one said, which is the failure this design avoids. It follows that workers suit steps that are independent. Use one agent for steps that depend on each other.
Three workers run at once by default, up to eight per run. Set
performance.threads to change it, or set performance.parallelProcessing to
false to run them one at a time. -Dcadet.workers.concurrency overrides both
for a single run. The provider sets the limit rather than the machine. Every
worker is a full agentic loop against one account and one shared retry budget,
so past a handful they stop queueing and start to fail each other. CadetCoder
reads the number in one place, reports it before a run starts, and tells the
model the same figure. A worker cannot start more workers.
workers start keeps the workers running across the model's later steps, so
the model can start a set of reviews, read something else, and come back for
the results. A one-shot CLI invocation waits for them before it exits rather
than kill them microseconds after launch.
In the shell, Tab steps through the workers. It shows each worker's output as
it arrives, whether or not that worker has finished. The header bar counts them
off, as in 2/5 workers done. CadetCoder collects a worker's output per worker
rather than streams it, so without that counter the bar would sit unchanged for
minutes, which reads exactly like a hang. F2 stops the run and its workers.
What had finished is still there to inspect, and /resume runs again only the
tasks that did not finish.
Timers
An agent has no clock. It sees a prompt, answers it, and does not exist again until the next one. "Check back on this in two minutes" is therefore something it can intend and cannot arrange. Without timers the only ways to wait are to sit inside one command with the run blind for the duration, or to spend a model call on the question of whether it is time yet.
A timer is a note the model leaves itself.
timer create --every 2m check whether the workers have finished
Every loop in CadetCoder appends the timers that are due to the prompt it is
about to send. That covers chat, the classic agent loop and the harness.
[timer] t1 fired at 2026-09-13T18:22:04+01:00 -- firing number 3, unlimited left, every 2m.
You set it to: check whether the workers have finished
The count tells a third check on a build from a first. That is the difference between a build that still runs and a build that ran far too long. The timestamp makes "far too long" measurable. Neither is recoverable from the note itself, and a model asked to keep its own tally across a compacted transcript will not have one.
| Command | What it does |
|---|---|
timer create --every <interval> <what to check> [--limit <n>] | Set one. Intervals are 30s, 5m, 2h, 1d or 1h30m, from 5 s to 24 h; a bare number means seconds. --limit retires the timer after that many firings. |
timer list | Report what is set, and when each is next due. |
timer cancel <id>, timer cancel all | Stop one timer, or all of them. |
timer wait [<seconds>] | Block until the next one is due, instead of a step spent on nothing. Capped at ten minutes. |
Four points are worth knowing.
- CadetCoder drops missed firings. A run that spends twenty minutes inside one command is owed one reminder when it comes back, rather than ten identical ones with the wrong count on each.
- CadetCoder delivers a firing once. It takes the firing from the register at the moment it reports it, so the same firing never reaches two prompts and the count always means how many times the thing happened.
- Each agent has its own timers, and loses them when it ends. A
workersrun puts up to eight agents on their own threads. A note one of them left itself never arrives in another's prompt, and CadetCoder discards it when that worker finishes. Workers are numbered from one in every run, so the next run'sWorker 1is a different agent on different work and must not inherit the last one's timers. - CadetCoder does not record firings in the transcript. A firing is true of one moment, so CadetCoder appends it to the prompt and nowhere else. That also keeps every turn's prompt an extension of the last one, and therefore cacheable.
Timers live for the session rather than for one request, so one set during an
investigation of a build is still running when you ask the next question. The
shell's header bar counts them, as in 2 timers, so a timer left behind is
visible rather than merely surprising. Each agent may have at most eight
timers at a time.
Background jobs
bash waits for what it starts. That is right for almost everything: a command
that answers in a second is best answered by its output. It is wrong for work
that takes longer than a step. A full build, a test suite, a server that has to
be up while something is tried against it -- waiting for those spends the step,
then the timeout, and the command is killed before it finishes.
A job is the same command, started and let go.
job start mvn -o test -d "the full suite"
The call returns at once with an id. The command keeps running while the conversation goes on, its output accumulates, and when it ends the model is told in its next prompt.
[job] j1 finished successfully after 4m12s.
It ran: mvn -o test
You started it to: the full suite
It printed 812 lines you have not read; read them with `job output j1`.
A job that failed carries its last twenty lines into that notice without being asked. A run told only that the build failed will either spend its next step asking why, or act on the failure without reading it.
| Command | What it does |
|---|---|
job start <command> [-d <description>] | Run it without waiting. Returns an id. |
job list | Every job, how long it has run, and how many lines are unread. |
job output <id> [--all] [-n <lines>] | What it printed since you last looked, at most 200 lines unless -n says otherwise. --all starts again from the beginning. |
job stop <id>, job stop all | End one, or all of them. |
job wait [<id>...] [--all] [-t <seconds>] | Block until one ends, or with --all until every one has, instead of asking again and again. Waits 600 s by default and at most 3,600 s. |
Six points are worth knowing.
- Starting a job is screened exactly as
bashis. Same denylist, same network and path rules, same confirmation. A command nobody waits for is if anything the one worth screening most carefully. - CadetCoder announces an ending once. It takes the ending from the register at the moment it reports it, so the same job never reaches two prompts, and an announcement whose prompt was never sent is owed again rather than lost.
- Reading is incremental.
job outputgives what is new since the last read. A build watched over ten steps would otherwise spend the context window ten times on the same lines. - Output is bounded, and says when it was cut. CadetCoder keeps the last 200,000 characters per job and drops the oldest first, because what a job printed just before it failed is the part anybody reads. A read that starts after a drop says how many lines went.
- Jobs are stopped when the session ends. A job is a process, not a thread,
so leaving does not end it.
quitlists what it is about to stop. - At most eight run at once. The shell's header bar counts them, as in
2 jobs, so a job left behind is visible rather than merely surprising.
Jobs and timers are complementary. A job says when it has ended; a timer is for checking on something that gives no sign of its own.
Uber mode
Every agentic loop ends the same way. The model says it has finished, and the loop believes it. That is the only signal available, and the one participant who cannot check it produces it: the model declares completion from inside the same context that decided what completion meant. So a run ends with the tests unrun, with the second call site never updated, or with the last third of the request answered in prose. From outside, that is indistinguishable from a run that finished, because the closing summary describes the part that was done.
/ubermode on
Two things change.
CadetCoder tells the model up front what finishing means here. It means every
separate thing the request asked for, verified with whatever the project can
actually be checked with rather than reasoned about, with the surrounding code
still in agreement. A stop to report progress does not count as finishing. That
text is a prompt like any other, so prompt edit ubermode changes it.
A claim of completion also stops being the end of the run. CadetCoder answers the claim with two questions in a row.
- The first sends the model back to the request that started the run. It asks whether every separate part of that request is done, and it asks the model to run the project's checks rather than reason about them. It does not check against the summary, because the summary was written from the same understanding that decided the work was done and therefore always agrees with itself.
- The second asks what else depends on the files that the run actually changed, which is where abandoned work usually lives. It differs from the first on purpose, because a model asked the same question twice gives the same answer twice.
The run ends when the model answers both questions in a row without any further work. Any work in between starts the questions again from the first. A model that keeps finding work therefore keeps being asked, and a model with nothing left to do ends the run in two turns.
| Command | What it does |
|---|---|
ubermode | Turn it on if it is off, and off if it is on. |
ubermode on, ubermode off | Set it explicitly. |
ubermode status | Report what it does without a change to it. |
Uber mode is off by default. It costs turns, against your tokens, on work you
may consider already done. CadetCoder keeps the setting in config.json, so it
survives the session. The shell's header bar says uber while it is on,
because a mode nobody can see is a run that will not stop when you expect it
to. CadetCoder deliberately does not offer uber mode to the model as a command
it can run.
Resume an interrupted run
F2 stops a run. /resume carries it on from where it stopped.
/resume
A new request such as continue starts a new run, and a new run knows nothing
of the one before it. An interrupted run holds more than its request: the
actions it took, the pass of a loop it was on, and how many of uber mode's
questions its work had passed. When you interrupt a chat, agent, loop,
loopfresh or workers run in the interactive shell, CadetCoder saves that
state as the session's resume point. /resume starts the same command again
from it. CadetCoder also saves the point when the provider stops answering
after the run did some work.
Outside the shell, Ctrl+C ends the CadetCoder process at once, so a one-shot
command such as cadet chat "..." saves no resume point.
| Run | What /resume does |
|---|---|
chat | Shows the model the request and the conversation of the interrupted run, and keeps the count of uber mode's questions that the work had passed. |
agent | Starts the agent with the same options. The task carries the notes and the last ledger entries from the record of the interrupted run. |
loop, loopfresh | Carries on the pass that was interrupted, with what that pass had done, and then runs the passes left. |
workers | Keeps the results of the workers that finished, and runs again only the tasks that did not finish. |
An interrupt also stops the workers that the run started, including workers that a chat started in the background. The resumed run learns which of them finished. Jobs keep going after an interrupt, because a server or a watch build is often what the work needs. The resumed run learns which jobs ran.
CadetCoder keeps the resume point in the session file, so it survives an exit,
--continue and /session resume. CadetCoder stops every job when it exits,
and timers live only in memory. A run resumed after a restart therefore learns
that its jobs stopped, and CadetCoder sets its timers again. Before it saves
the point, CadetCoder replaces any API key or token it finds in the saved text
with ***redacted***.
| Command | What it does |
|---|---|
resume | Carry on the run you last interrupted. |
resume show | Say what resume would carry on, and start nothing. |
resume discard | Forget the resume point. |
There is one resume point per session. A second interrupted run replaces it.
A resumed run that ends by itself clears it, whether its work succeeded or
failed. A resumed run that cannot reach the model saves a new point with its
new work. A resume that cannot start keeps the point: for example, when other
workers still run. CadetCoder resumes a run only in the project it worked in.
The model cannot run resume.
Read the output
A line the console prints carries a one-column marker when the line says something about how the run is going. An ordinary notice carries none: "this is information" was true of most of what the program printed, so the glyph in front of it marked nothing out.
| Marker | Meaning |
|---|---|
✓ | something completed |
⚠ | something to be aware of; the run continues |
✗ | something failed; this goes to stderr |
▎ | a heading |
▸ | a sub-heading; in the interactive shell it opens a nested, separately scrollable section |
• | the start of a new iteration of an agent run |
ℹ | a message that contains a Markdown code fence; see below |
CadetCoder indents a marked message that runs to several lines, so its continuation lines sit under the first line's text rather than in column 0. A notice has no marker to sit under, so every line of it starts in the same column.
A message that contains a Markdown code fence is the exception on both counts:
every line of it carries the ℹ marker, notice or not, so a fence inside a
message cannot be mistaken for one that opens a code block and swallow
everything printed after it.
Some terminals cannot render those glyphs. CadetCoder inspects the encoding and
the LANG and LC_* variables at startup. On such a terminal the markers fall
back to the bracketed words [OK], [WARN], [ERR], [i], [*],
=== heading === and -- sub-heading --. The shell's line classifier
understands both vocabularies, so output captured on one machine still colours
correctly when rendered on another.
In the interactive shell a line's colour comes from its marker, because the shell strips the escape codes and colours what it classifies. An unmarked notice is therefore drawn in the ordinary text colour there. On a plain console it keeps the theme's colour, which travels in the escape codes.
Colour comes from the active theme, which cadet theme list reports.
--no-color disables it.
Command output
By default the console shows what the AI ran and in what order, rather than the raw output of every command.
▸ bash echo one
  sanity check before the build
✓ [1] ok  (3 lines)
The first line is what is about to run. The second is the model's own stated reason to run it. The third is the record of what happened, which carries the position in the sequence, whether it worked, and how much output there was.
An agentic turn runs many commands, and one read of a large file or one
grep with many hits buries the reasoning and the result.
In the interactive shell the output is kept rather than cut. Click the result,
or focus it with Tab, to read all of it. Press Esc to go back to the run.
Four things go behind that click: the command's output, the Iteration <n>
line, the request's own cost-and-speed line, and the record of a step that
worked. What stays is what the run is doing, one or two lines per command. A
step that FAILED keeps its record on screen, because that is the column to scan
down to find where a run went wrong.
On a plain command line there is nothing to click, so the head of the output stays on screen with a note that says how many lines follow it. A step's own diagnostics lead its output, and a failure explained by a number is no explanation.
The shell renders the model's answers as Markdown. It shows what a program
printed exactly as printed, so a git diff keeps its - and + lines and a
shell comment does not become a heading.
This is a console setting. A hidden output never changes what the model receives. CadetCoder still feeds the captured text into the next prompt, and still writes it to the debug and session logs.
Show everything with either form:
cadet config ui.showCommandOutput true    # persistent
cadet -Dcadet.showCommandOutput=true …    # one run
What the model receives
A separate backstop bounds how much of a command's output goes into a prompt:
100,000 characters, roughly 25,000 tokens. It sits deliberately above every
limit the commands enforce for themselves, so those remain the limits that
normally apply, expressed in terms the command understands. Those are read's
line limit, multiread's 20,000-line total, and bash's 30,000-character cap.
The backstop exists for output that is pathological rather than merely large.
When the backstop fires, the note says how many characters it dropped and that a re-run of the same command will not return more. A bare "output truncated" leaves a model no option but to try the same thing again.
cadet -Dcadet.maxCommandOutputChars=250000 …   # raise it
cadet -Dcadet.maxCommandOutputChars=0 …        # remove it
How commands are dispatched
Commands start with /; everything else is a message for the AI
About twenty command names are also ordinary English words, among them read,
write, edit, explain, commit, push, undo, help, find and run.
A decision between command and conversation made from the first word alone
therefore executes plain sentences as tool calls. write a test for Foo would
create a file named a, and commit the changes would make a real git commit.
A leading / means "this is a command", and nothing else does.
/read pom.xml            run the read command
read pom.xml and explain what it does    a message for the AI
//starts with a slash    '//' escapes, for a message that begins with a slash
- In the interactive shell that is the whole rule. Plain text always goes to
the AI. The first time you type a message whose first word is also a command
name, the shell says so and points at the
/form. It says so once for each command name in a session. - On the command line,
cadet read pom.xmlstill dispatchesread. Your shell already tokenized argv and you typed the command name deliberately, so the documented CLI contract does not change.cadet /read pom.xmlworks too, and is the unambiguous spelling. - An explicit
/namenever falls back to chat. A mistyped/raedreportsUnknown command: raed, suggests/read, and exits 1, rather than spend an LLM request silently.
One dispatch path
Every command goes the same way, from the command line, from the shell and from a script.
argv -> picocli (global options only) -> CommandRegistry -> Command.execute(String[])
                                                         -> no match -> chat
- picocli parses the global options and nothing else. No command is
registered as a subcommand of
Main, so CadetCoder never matches a command name out of the middle of a sentence.cadet please lsreaches the model, andcadet help undoreaches the help command. CommandRegistrydiscovers everyCommandRegistry.Commandimplementation incom.eonmux.cadetcoder.commandsby reflection, and callsexecute(String[])directly. Each command parses its own options, socadet /grep -i Xreachesgrepwith its flag intact.- The interactive shell (
cadet -i) and script mode (cadet -s file) dispatch through the same registry. A command behaves the same wherever it runs. In a script every line is a command, with or without the leading/. A line that starts with#is a comment. - The registry answers
--helpor-has the first argument, with the same text thatcadet help <command>prints, and does not run the command. One place answers it, sochat --helpdoes not send two words to the model and bill the call,websearch --helpdoes not search the web for them, andbash --helpdoes not offer to run--helpas a shell command. Only the first argument counts.runs show --helpstill asks for a run by that name, and CadetCoder answers that there is none.
Quoting matters on the command line, where your shell tokenizes for you.
cadet ls .        # LSCommand
cadet /ls .       # the same, spelled unambiguously
cadet "/ls ."     # the same again: the line is tokenized as the shell prompt does
cadet "ls ."      # a message for the AI, because it has no leading slash
Without the slash, nothing separates a command from a sentence that opens with a command word. A guess would turn "read the design doc and summarise it" into a read of a file called "the".
CadetCoder tokenizes the line itself inside the interactive shell and in script files. Quoted arguments survive as one argument.
/write notes.txt "hello world"   -> two arguments; the file contains: hello world
/grep "class Foo" --path=src     -> the pattern is one argument
Write every option as --flag=value or as --flag value.
Exit codes
| Code | Meaning |
|---|---|
0 | the command did what it was asked |
1 | the command could not do what it was asked |
69 | the command needed the model and could not reach it |
130 | somebody stopped the command before it could finish |
130 is what a shell reports for a process killed by SIGINT, which is 128 + 2.
It is the answer for every way a run stops part-way: F2 in the interactive
shell, Ctrl-C, a refused confirmation, a harness run called off, and
workers stop. It is deliberately neither 0 nor 1. A run that
somebody stopped neither finished the task nor found it impossible, and a
script that cannot tell those apart will build on work that was never done.
69 means that no request reached the model, so nothing was attempted. The
fix is to wait or to repair the credentials. loop uses it to stop instead of
running its remaining passes against a provider it cannot reach. It is
EX_UNAVAILABLE from sysexits.
cadet agent -y "refactor the parser"
case $? in
  0)   echo "done" ;;
  130) echo "you stopped it; nothing downstream should run" ;;
  *)   echo "it failed" ;;
esac
Command reference
This reference follows each command's usage text in the source. The CLI
column says what cadet <command> does. OK means the command works from the
CLI. AI means it works but needs a configured provider. Every command
dispatches the same way from the command line, the interactive shell and a
script. A few, such as clear and quit, only have an effect inside the
interactive shell.
Files
| Command | CLI | Notes |
|---|---|---|
read <file> [-o <line>] [-l <n>] | OK | Prints with line numbers. The -o offset is 1-based. Resolves partial paths. Takes one file; it names multiread if you pass more. |
multiread <file...> [-l <n>] [-o <line>] [--max-files <n>] [--max-total-lines <n>] | OK | Reads several files in one call. Paths may be globs. Each file goes through read, so the same security rules apply. A file that cannot be read is reported in place and the rest are still read. Exits 0 if at least one file was read. |
write <file> [content...] [-f] [-i] | OK | Confirms before an overwrite unless -f. -i reads the content interactively. |
edit <request...> | AI | AI-assisted edit. The request names the file. Returns SEARCH/REPLACE blocks. |
multiedit <file> <edits...> [-r] | AI | Several edits to one file, applied atomically. |
ls [path] [-a] [-l] [-R] [-r] [-S] [-t] [-d] [-i <glob>] [--max-depth <n>] | OK | cadet ls alone lists the working directory. |
stat <path...> | OK | Kind, size, line count, permissions and last modification, without reading the file out. Every path is reported; the exit code is non-zero if any was missing. |
diff <fileA> <fileB> [-U <n>] [--stat] | OK | Unified diff, the same format git diff prints and patch reads. -U sets the surrounding context, default 3. --stat reports only how many lines changed. A difference exits 0; a file that cannot be read exits 1. |
patch <diff> [-n] [-f|--file <path>] | OK | Applies a unified diff to the files it names. The diff is one argument, or -f reads it from a path. Adds, edits and removes files: a /dev/null on either side of the header, which is what git diff writes for a new or deleted file, is read as a creation or a deletion. Every file is worked out before any is changed, so a patch that does not fit changes nothing. A patch that adds a file will not replace one that is already there. -n reports what it would do. |
notebookread <notebook> [-c <cellId>] | OK | Reads .ipynb cells and outputs. |
notebookedit <notebook> <cellId> [source...] [-m <replace|insert|delete>] [-t <code|markdown>] [-i] | OK | Edits one notebook cell. |
Search
| Command | CLI | Notes |
|---|---|---|
grep <pattern> [-p <path>] [--include <glob>] [-e <glob>] [-i] [--no-line-number] [-w] [-x] [-v] [-c] [-l] [-A <n>] [-B <n>] [-C <n>] [--column] [--max-depth <n>] | OK | Regex search, recursive by default; there is no --recursive. --include and -e match relative to -p; use **/ for nested files. Line numbers are on by default: --no-line-number omits them, and -n changes nothing. -A, -B and -C add surrounding lines, numbered with a dash rather than a colon, with -- between groups. --column adds where in the line the first match starts. |
glob <pattern> [-p <path>] [-l <n>] [-d] [-f] [-r] [-s name|time|size] [--max-depth <n>] | OK | The default sort is time, oldest first. --max-depth 0 means the start directory alone. |
search <query> | OK | Lucene-backed code search. Takes plain words, not query syntax: punctuation is searched for, not obeyed. Prints the lines that matched, with their numbers. Brings the index up to date first, once per run. |
index [path] | OK | Builds or refreshes the search index and reports how many files it wrote. Discards and rebuilds an index written by an incompatible Lucene rather than fail. |
AI
| Command | CLI | Notes |
|---|---|---|
chat <request...> | AI | Agentic loop. The default when the first word is not a known command. |
agent <task...> [-m <steps>] [-t <seconds>] [-c <check>] [-v] [-y] [--classic] | AI | Runs under the agent harness and leaves a record under .cadet/runs/. -c names the command that decides when the task is done. Exits 0 only for a run that finished. |
workers <task...> [-b <briefing>] [-m <steps>], workers start|status|wait|stop|list|show <n> | AI | Runs several agents at once over one shared briefing, three concurrently by default and eight at most. Only one run exists at a time. See Workers. |
runs [show|ledger] [<name>] [<n>] | OK | Reads what past runs recorded. Read-only: a record is written once and never revised. |
loop [--times=<n>] <goal> | AI | Runs the goal as a full run, 100 times by default and at most 1,000. Each pass sees the tail of what the last pass said. Every pass runs, whatever the model says about the goal. Ctrl-C ends it. A provider that cannot be reached stops it with exit code 69. |
loopfresh [--times=<n>] <goal> | AI | The same as loop, except that each pass is told nothing about what the last one said. |
resume [show|discard] | AI | Carries on the chat, agent, loop or workers run you last interrupted. See Resume an interrupted run. |
plan [description...] [-e] | OK | Enters plan mode. done, exit or a blank line finishes it, as does -e. CadetCoder records the plan into the session and asks whether to run it. |
refactor <file> [instructions...] | AI | AI-assisted refactor of one file. |
analyze <file> | AI | Reports what the file does and where its problems are. |
explain <file> | AI | Explains the file in prose. |
suggest <type> [file] | AI | <type> is improvements, tests, refactoring, documentation or performance. |
Git
| Command | CLI | Notes |
|---|---|---|
commit <message...> [-a] [-n] | OK | -a stages all changes. -n skips the pre-commit lint. |
push [-b <branch>] [-f] [-u] | OK | -b pushes that branch instead of the current one. -u records it as the upstream, after a successful push. -f overwrites the remote's history. It says what that discards and asks you to confirm, every time and whoever asked for it. With nobody to ask, as in a script or a worker, it is refused. |
undo [-c] [-e] [-f] | OK | -c resets the last commit. -e discards uncommitted changes, and is the default when neither flag is given. -f skips confirmation, and is required without a terminal. |
Tasks, web and shell
| Command | CLI | Notes |
|---|---|---|
todoread | OK | Prints the current todo list. |
todowrite <add|update|remove|clear> [text...] [-i <id>] [-p high|medium|low] [-s pending|in_progress|completed] | OK | todowrite "<text>" with no verb adds that item. |
timer <create --every <interval> <what to check> [--limit <n>] | list | cancel <id>|all | wait [<seconds>]> | OK | A repeating check-in that fires into a later step of the same run. See Timers. |
bash <command...> [-f] [-t <ms>] [-d <desc>] | OK | One command only. Rejects pipes, redirects, ;, &, $(...) and backticks. Confirms unless -f. The timeout caps at 600000 ms. |
job <start <command> [-d <desc>] | list | output <id> [--all] [-n <lines>] | stop <id>|all | wait [<id>...] [--all] [-t <seconds>]> | OK | Runs a command without waiting for it. Screened exactly as bash is. At most eight run at once. See Background jobs. |
webfetch <url> [prompt...] [-f] [-t <seconds>] | AI | Fetches a URL and answers the prompt about it. |
websearch <query...> [-n <num>] [-a <domain>] [-b <domain>] | AI | -a allows a domain, -b blocks one. |
execute <scriptFile> | OK | Runs one command per line. Skips # comments and blank lines. |
shell | OK | Starts the interactive shell. Needs a real terminal, and says so when it has none. cadet -i does the same. |
clear | OK | Clears the interactive shell's console, as Ctrl+L does. The session log keeps what was cleared. A model may not run it. |
quit | OK | Meaningful inside the interactive shell alone. A model that emits it ends its own run rather than the session. |
Configuration and providers
| Command | CLI | Notes |
|---|---|---|
models [providers | <providerId> | find <text> | current | use <provider> [model] [--context=<tokens>] | select | context [<tokens>|clear]] | OK | context shows, sets or clears the input window of the active model. See Set up a provider. |
login [<provider> | status | logout <provider>] | OK | Key entry needs a real TTY. See Set up a provider. |
copilot [login | status | logout] | OK | OAuth device flow for GitHub Copilot. logout removes the stored token from this machine, which is the same act as login logout github-copilot. |
context [show|create|reload|clear] [-v] | OK | Manages CADET.md, the project-context file. |
compact [status | on | off | trigger <0-1> | target <0-1> | keep-head <n> | keep-tail <n>] | OK | Controls when a long run folds its own history to keep fitting the context window. |
theme <list|set|preview|current|validate|reset> [name] [-s] [-v] | OK | -s persists the choice. reset returns to the default theme. |
session [status | list [count] | new | resume <id>] | OK | CadetCoder keeps the session being left, so resume can reopen it. A model cannot start or switch sessions. |
config [<name> [<value>]] | OK | No arguments prints the config with secrets redacted. One argument prints that setting. Two arguments change it and save it. Names are <section>.<property>. |
ubermode [on | off | status] | OK | Keeps a run going until the task is actually finished. No argument flips it. See Uber mode. |
prompt [list|show|edit|reset|reload] [name] [-c <content> | -f <file>] | OK | No argument lists the prompt templates. |
help [command] | OK | help <name> prints one command's options. |
Global options
This is cadet --help on the built jar.
Usage: cadet [-chiV] [--debug] [--no-color] [--no-git] [--read-only]
             [--verbose] [--ai-endpoint=<aiEndpoint>]
             [--ai-temp=<aiTemperature>] [--base-dir=<baseDir>]
             [--chat-template=<chatTemplate>] [--config=<configPath>]
             [--context-tokens=<contextTokens>] [--model=<aiModel>]
             [--provider=<provider>] [--provider-key=<providerKey>]
             [-r=<resumeSessionId>] [-s=<scriptFile>] [<commandArgs>...]
AI-assisted coding tool
      [<commandArgs>...]     Command and arguments to execute
      --ai-endpoint=<aiEndpoint>
                             AI API endpoint URL
      --ai-temp=<aiTemperature>
                             Temperature for sampling
      --base-dir=<baseDir>   Base directory for storing global files
  -c, --continue             Continue the most recent session
      --chat-template=<chatTemplate>
                             Chat template to use (e.g., plain, chatml, alpaca,
                               llama2, llama3, openchat, deepseek)
      --config=<configPath>  Configuration file to read and write (default ~/.
                               cadet/config.json)
      --context-tokens=<contextTokens>
                             Input context window in tokens (default: the
                               model's published limit)
      --debug                Enable debug logging to file
  -h, --help                 Show this help message and exit.
  -i, --interactive          Start in interactive shell mode
      --model, --ai-model=<aiModel>
                             Model name to use
      --no-color             Disable colored output
      --no-git               Disable Git integration
      --provider=<provider>  AI provider/connector id (e.g. anthropic, openai,
                               openrouter, google, xai, amazon-bedrock, azure,
                               github-copilot, groq, deepseek)
      --provider-key=<providerKey>
                             API key for the selected --provider. Visible to
                               anyone who can list processes and kept in shell
                               history; prefer the provider's environment
                               variable, or 'login', which reads the key
                               without echoing it
  -r, --resume=<resumeSessionId>
                             Resume a specific session by ID (see '/session
                               list')
      --read-only            Enable read-only mode
  -s, --script=<scriptFile>  Run commands from script file
  -V, --version              Print version information and exit.
      --verbose              Enable verbose output
Select every provider the same way, OpenRouter included.
cadet --provider openrouter --provider-key <key> --model anthropic/claude-3-opus
Point a connector at a different host with its baseURL provider option.
--base-dir expands a leading ~.
Configuration
Everything lives under ~/.cadet/, rather than under ~/.config/cadet/.
~/.cadet/
├── config.json           # main configuration
├── session.json          # current session
├── sessions/             # saved sessions and per-session logs
├── logs/                 # cadet.log, history.log, debug/
├── indexes/              # Lucene index
├── models/               # local model storage
├── cache/models.json     # cached models.dev catalog
├── prompts/              # user prompt template overrides (*.json)
└── copilot-auth.json     # GitHub Copilot token, if you logged in
Override the location with --base-dir <path>. That moves everything in the
tree except config.json itself. CadetCoder has to find config.json before
it can read any setting inside it, so name that one file with
--config <path>. The baseDir in it then decides where the rest goes. A
second profile is therefore one file plus the directory it points at.
cadet --config ~/work/cadet.json config baseDir ~/work/cadet   # once
cadet --config ~/work/cadet.json agent "..."                   # thereafter
logs/history.log holds the interactive shell's command history, which is the
list that Up, Down and F3 walk back through. CadetCoder appends a line
the moment you enter it, so a session that ends in a crash or a closed terminal
still leaves its commands behind. Two shells open at once both add to the file,
and neither replaces the other's work. The file keeps the most recent 1000
lines.
This is config.json as written on first run. The sections appear in this
order. baseDir is written as an absolute path.
{
  "ai": {
    "localEndpoint": "http://localhost:8012",
    "localModel": "llama3-8b-q4",
    "temperature": 0.7,
    "maxTokens": 0,
    "contextTokens": 0,
    "modelContextTokens": {},
    "apiKey": "",
    "apiEndpoint": "https://api.openai.com/v1",
    "model": "o1-mini",
    "escalateTo": "",
    "completionTimeoutSeconds": 300,
    "chatTemplate": "chatml",
    "provider": "",
    "providerApiKeys": {},
    "providerOptions": {},
    "zeroDataRetention": true,
    "uberMode": false
  },
  "context":   { "maxFiles": 10, "maxLinesPerFile": 500, "priorityFiles": [] },
  "indexing":  { "enabled": true, "indexLocation": ".cadet/index",
                 "excludePatterns": ["bin", "build", "dist", "node_modules", "obj", "out", "target"],
                 "refreshIntervalMinutes": 60 },
  "git":       { "enabled": true,
                 "includeBranches": false, "includeCommitHistory": false, "maxCommitHistory": 10,
                 "autoCommitEnabled": false,
                 "commitMessageTemplate": "Auto-commit on {date}", "commitTrigger": "onChange",
                 "autoCommitIntervalMinutes": 60 },
  "ui":        { "colorEnabled": true, "colorTheme": "modern", "verbosityLevel": 1,
                 "interactivePrompts": true, "showCommandOutput": false },
  "performance": { "threads": 3, "parallelProcessing": true },
  "security":  { "allowRemoteExecution": false, "allowedCommands": [], "allowedActions": [],
                 "sandboxMode": false, "readOnlyMode": false, "requireConfirmation": true,
                 "allowOutsideProject": false, "commandApproval": "manual",
                 "maxFileContentSize": 10 },
  "logging":   { "level": "INFO", "logFile": "logs/cadet.log", "consoleLoggingEnabled": true,
                 "maxLogFiles": 5, "maxLogSize": 10, "debugEnabled": false,
                 "sessionLoggingEnabled": true, "structuredLogging": true,
                 "maxSessionLogSize": 50, "maxSessionLogs": 20 },
  "compaction": { "enabled": true, "trigger": 0.8, "target": 0.45,
                  "keepHeadEntries": 6, "keepTailEntries": 9 },
  "baseDir": "/home/you/.cadet"
}
ai.modelContextTokens holds the input windows that models context sets,
one per provider and model.
Note three shipped defaults. ui.colorTheme is modern.
security.allowOutsideProject is false, so file commands work only inside
the directory you start CadetCoder in. security.commandApproval is manual,
so you approve each shell command yourself.
config works from the command line and from the shell, and you can edit
~/.cadet/config.json directly. A path setting that begins with ~ means your
home directory whichever of those three routes it arrives by. Your shell
expands it for you on a command line, and nothing expands it inside cadet -i
or in a file you edit yourself.
Context
context.maxFilesbounds how many whole project files one prompt may carry.context.maxLinesPerFilebounds how much of any one of them. CadetCoder cuts a longer file at a line boundary, with a note that says how many more lines there were.context.priorityFilesnames project files that go in front of the model every time, ahead of whatever the index search returned. An index search matches on what is inside a file, so no search over the sentence the user typed returns a document that the project has decided always matters, such as its coding conventions or its architecture notes. Paths are relative to the project and count againstmaxFiles.
Indexing
indexing.enabledsays whether CadetCoder indexes the project at all. With it off,searchand the context the model is given fall back to whatever is already in the index.indexing.indexLocationsays where the index lives. Two CadetCoder processes cannot share one. CadetCoder tells the second process so and stops, rather than delete the first one's index.indexing.excludePatternsnames directories to skip. CadetCoder matches each entry as a regular expression against a directory name, and as a literal if it is not valid regex. Despite the section it lives in, this governs every walk over the project: the index,grep,ls,glob, and the file search thatread,write,editand the agent do. CadetCoder also skips hidden directories, by the leading dot rather than by a listed name.indexing.refreshIntervalMinutessays how long the index stays fresh inside one run. A one-shot command indexes once and exits, so this setting matters tocadet -i. A shell left open all day would otherwise index the project when it opened and never again, and nothing written afterwards would be searchable for the rest of the session. That covers writes by your editor and by this tool's ownwriteandedit. Set0to keep the old behaviour deliberately: index once, then leave the project alone.
Repository context
Both settings are off by default, because every line of repository context is prompt that the code you asked about does not get.
git.includeBranchestells the model which branch the work is on, and what other branches exist. A branch name is often the clearest statement of what a task is for.git.includeCommitHistorytells the model the recent commits on that branch, newest first, so it does not propose work that was done three commits ago.git.maxCommitHistorybounds how many of them.
Worker settings
performance.threadssets how many workersworkersruns at once, between 1 and 8. The provider's rate limit sets the ceiling rather than the machine. Every worker is a full agent loop against one account, one rate limit and one shared retry budget, so past a point they do not queue and instead fail each other.performance.parallelProcessingruns workers one at a time when set tofalse.
Security controls
These are the settings the code actually consults.
security.readOnlyMode, also--read-only, blocks writes.security.sandboxModerestrictsbashto a command whitelist and file access to safe extensions.security.allowOutsideProjectdecides whether file commands may reach paths outside the project root. It isfalseby default. Set it totrueto let them read there. Writes still stay inside the project or the system temporary directory when it istrue.security.allowedCommandsnames the programsbashmay start in sandbox mode. Empty means the shipped list:echo pwd cd ls dir cat type grep find git mvn npm yarn python java javac node. A value replaces that list rather than adds to it. The setting has no effect when sandbox mode is off.security.allowedActionsnames the actions a model may ask for, such asread,writeandbash. These are the tool's own names rather than shell programs. Empty means all of them, which is the default. The list covers bothchatandagent. A refused action costs the agent a step and reports why; it does not end the run.security.requireConfirmationprompts beforebashand before destructive file operations. It decides whether the question is asked at all, andsecurity.commandApprovaldecides who answers it. Neither decides whether an action is allowed.security.commandApprovalnames who answers when a command needs approval.manual, the default, asks the person at the terminal, including during an agent run: the question is drawn on the screen rather than filed into the step's transcript, and the answer comes from the shell's input line.autoasks the model instead, in a separate request that is shown one command and told to allow ordinary development work. When the command is a plain run of a script withpython,node,ruby,perlor a shell, such aspython3 tool.py,bash build.shor./deploy.sh, optionally aftercd /path &&, the request also shows the script, so the model judges what the script does. A script outside the project, a credential file, a file that is not text, and any line of another shape are judged from the line alone. A script over 20,000 characters is cut there. The model answersALLOW: <why>orDENY: <why>, and anything else — a refusal to answer, an error, an unreachable provider — is read as a refusal. Chooseautoonly if you accept that a model approves commands without you. It suits a long run whose commands are routine, and workers need it, because nobody can answer a worker's question. Where nobody can be reached the command is blocked, and the message names this setting. Neither mode can approve what the screens below refuse outright. Set it for one run with-Dcadet.commandApproval=auto.
A model cannot change your saved setup. When a model asks for them, CadetCoder refuses these commands:
loginandcopilot, exceptstatus.config <name> <value>.- The
modelssubcommands that switch the active model or set its window. prompt editandprompt reset, because a saved prompt template is the system prompt of every later session.ubermodeandcompact, exceptstatus.theme set,theme applyandtheme reset.
A model also may not clear the console with clear, start or switch sessions,
or start a nested chat, agent, loop, loopfresh or resume inside its
own run.
A model may still read settings, for example with config <name>,
login status, ubermode status or models context.
These refusals cover CadetCoder's own commands. A model can still ask bash to
run a command that changes the same files, such as cadet config ... or a
copy into ~/.cadet/prompts. With the shipped settings,
security.requireConfirmation is true and security.commandApproval is
manual, so you approve every such command yourself. With auto, the model
approves it.
CadetCoder also ignores a --force from a model. bash then asks for approval
as security.commandApproval says. undo from a model is refused, because
only you can confirm a hard reset.
push --force asks you every time, whether you or a model asked for it. The
model never answers this question, even with auto. With nobody to ask, as in
a script or a worker, the force push is refused. The same applies to a
git push run through bash that can discard commits on the remote: one with
--force, --force-with-lease, --mirror, --delete, --prune, or a
refspec that starts with + or :. bash -f does not skip that question.
Whatever the settings say, bash reads a command line before it runs it. It
takes the line apart the way a shell would, through quotes, pipes, &&, ;,
$(...) and backticks, and screens every program the line would start and
every file it would write. A quoted metacharacter is text, so awk '{print $1}'
and grep -r todo src | wc -l run. A program on the dangerous list, a
protected system path and a named credential file are refused, and the refusal
says which of those it was.
Two things cannot be read from the line: a program named by a variable, such as
$TOOL --version, and the commands inside bash -c "..." that is itself built
by expansion. Those are the cases security.commandApproval settles. login
and config redact secrets from logs and console output.
Context compaction
A long run's prompt is its transcript, rendered in order, so it grows every turn. At 80% of the usable input budget the run folds its own history into three parts: a verbatim head, a marker that says how many steps were omitted, and the most recent steps verbatim.
CadetCoder keeps the head deliberately. A cache matches a leading prefix, so the kept head is what stops a fold from discarding the whole cache. A fold rewrites the prompt's start, which is expensive, so it is threshold-driven and rare rather than eager. The alternative is worse, because an over-length prompt is a terminal 400 that loses the task outright.
CadetCoder drops steps rather than summarises them. A summary costs a request exactly when the run is most valuable, it can fail, and it can succeed while it quietly loses the one fact that mattered. A drop is safe here because the loop guard's memory of what has already been tried lives outside the transcript.
cadet compact status              # thresholds, and the budget they are measured against
cadet compact off                 # or: on
cadet compact trigger 0.9         # fold at 90% of the usable budget
cadet compact target 0.5          # fold back down to 50%
cadet compact keep-head 8         # entries kept verbatim at each end
cadet compact keep-tail 12
There is no compact now. The transcript belongs to a single run and does not
outlive it, so between commands there would be nothing to fold.
Token budgets
maxTokens and contextTokens are two different numbers. maxTokens is how
many tokens the model may generate, and CadetCoder sends it to the provider as
max_tokens. contextTokens is how many tokens the model can accept, and
CadetCoder budgets the prompt against it.
maxTokens is 0 by default, which asks for no ceiling at all. Nobody knows
how long an answer needs to be before it is written, and a number chosen in
advance is only ever wrong in the direction that truncates. The risk grew with
reasoning models, which charge their thinking to the same budget as their
answer, so a model can spend the whole allowance before it writes a word. Set a
number to cap a reply. One API cannot be told "no limit": Anthropic's Messages
API requires max_tokens, so CadetCoder sends that model's published output
limit.
contextTokens set to 0 means CadetCoder takes the active model's published
context length from the models.dev catalog, which is the right number and
differs by orders of magnitude between models. It falls back to a conservative
default for a local or uncatalogued endpoint.
Interactive shell
cadet -i
The shell is a full-screen interface built on TamboUI and JLine. It has four parts:
- A top line. It carries whatever modes are switched on, such as
uberand2 timers, the activeprovider/model, the git branch, and, while a request is in flight, what runs, its elapsed time and what it cost so far. - A scrollback console. It renders Markdown and keeps per-command result sections.
- A status bar, under a divider of its own. It lists the keys available. Where you are in the view -- following, scrolled, focused or selecting -- is drawn in the console's own top-right corner, beside the text it describes.
- A prompt line, under a rule and its own heading, which names the working directory.
Live request state appears in one place only, the top line. Any sub-heading a
command prints with ▸ opens a nested section inside its result, so an AI
run's individual steps are separately scrollable and titled. Tab steps
through workers. CadetCoder collects a worker's output per worker rather than
streams it, so while workers run the transcript says nothing about them, and
Tab is the only way to watch one without an interrupt to the run you wanted
to watch.
Nothing in the transcript is boxed or padded to the terminal width. Each region has a one-row heading and no border. Each result opens with a heading of its own. Code blocks have no gutter down their left edge. A selection therefore copies the text and no frame around it. Only the modal help overlay keeps a full border, and nobody copies that out.
Type / to start a command. The shell predicts the rest of the name as you
type: /com shows mit in dim text, and Right at the end of the line
accepts it. While several commands still match the prefix, the completion adds
only the characters they all share and reports how many remain, so it never
guesses which one you meant. Tab is not used for this, because it moves
between workers. The shell also supports command history, mouse wheel
scrolling, click-drag selection with OSC-52 clipboard copy, and bracketed
paste. Non-UTF-8 terminals get ASCII glyph substitutes.
| Key | Action |
|---|---|
Enter | Send the line. It runs the command, or asks the AI. |
Tab / Shift+Tab | Step through each worker's output, live (focus mode) |
Right | Accept the predicted command name, at end of line |
Up / Down | Command history, or scroll the focused result |
Ctrl+Left / Ctrl+Right | Move the cursor a word at a time. Some terminals send Alt instead of Ctrl; both work, as do Alt+B and Alt+F. |
Ctrl+W | Delete the word behind the cursor |
F1 | Help overlay, holding the same reference /help prints. Arrows, PgUp and PgDn scroll it; any other key closes it. |
F2 / Ctrl+C | Interrupt the running command. /resume carries on an interrupted chat, agent, loop or workers run. |
F3 | Print recent history |
F4 | Select mode: the mouse selects, and a click does not open the result under it |
Ctrl+U | Clear the line being typed |
Ctrl+L | Clear the console |
Page Up / Page Down | Scroll |
Ctrl+Home / Ctrl+End | Jump to top, or follow the bottom |
| Click a result | Focus it. Esc returns to the live view. |
Esc | Back out of whatever is innermost: a prompt, select mode, a selection, a focused result, then the line being typed |
Ctrl+Q or /quit | Exit |
Ctrl+C when idle | Asks. A second press exits. Anything else takes the question back. |
A paste of more than one line, or of more than 200 characters, does not go into
the line as text. It goes in as a short marker naming what it stands for, such
as [#1: 42 lines], and the text itself is sent when you press Enter. The
marker is ordinary text: type before and after it, cross it a word at a time,
delete it like any other word. The console, the history and the saved
transcript keep the line as it was typed, marker and all, because what the
marker stands for is no more readable as a result heading than it was at the
prompt.
A file dropped on the terminal arrives as a paste of its path. It goes in as
its name, [#2: Foo.java], and is sent as the full path, so a command can open
it.
A dropped PNG, JPEG, GIF or WebP is read as well as named. Its marker says so,
[#3: image shot.png], it still stands for the path, and the picture itself is
sent to the model with your question. Delete the marker before you press
Enter and nothing is sent. The picture goes with the first request of the
turn and not with the iterations after it, so a long run pays for it once. A
model that does not read images is sent the question and the path, and a line
on screen says what was left out. Images are limited to 5 MB, which is the
lowest of the providers' limits.
Drag over the console to select text, and release to copy it. A selection is
not limited to the rows on screen: drag to the top or bottom edge and hold
there, and the transcript scrolls under the pointer so the selection keeps
growing. The further past the edge the pointer sits, the faster it moves, up to
a third of the console per tick. The wheel and the paging keys also work
mid-drag, which is the quick way to cover a long stretch: scroll to where the
selection should end, then move the pointer there. F4 is worth pressing
first for a long selection, because it stops a mis-click from opening the
result underneath.
With text selected and nothing running, Ctrl+C copies the selection rather
than does either of those. That follows the terminal convention, and it also
covers terminals that report Ctrl+Shift+C as a bare Ctrl+C.
The banner carries one more line when the run is restricted. It names read-only mode or sandbox mode, each as it applies. With neither on, the line is absent. Files confined to the project directory is the default, so the banner does not name it.
In the shell, plain text is a message for the AI and commands start with /.
See How commands are dispatched. /help prints
the reference the F1 overlay shows: how a typed line is routed, the keys, the
mouse, then every command grouped by what it is for. Both render
HelpContent, so neither can drift from the other. Outside the shell,
cadet help prints the commands alone, since the keys and the mouse belong to
a window that is not open. /help <name> prints one command's full option
list.
The shell dispatches through CommandRegistry, the same single path the
command line uses, so every command behaves the same on both surfaces. It needs
a real terminal. With stdin redirected it emits its terminal setup sequences
and then blocks forever instead of exiting, so never launch it from a script or
a pipe.
Themes and templates
CadetCoder ships 10 themes, all 24-bit truecolor: modern, which is the
default, matrix, default, solarized-dark, solarized-light, monokai,
dracula, nord, gruvbox-dark and one-dark.
cadet theme list
cadet theme preview dracula
cadet theme set nord -s      # -s persists to config.json
cadet theme current
CadetCoder ships 11 chat templates, for local and non-connector models that
need a specific prompt format: plain, chatml, which is the default,
chatml-advanced, alpaca, alpaca-system, llama2, llama3, openchat,
deepseek, tekken and intel-neural.
Select one for a single run with the global flag, or save it in the config.
cadet --chat-template alpaca "explain this code"
cadet config ai.chatTemplate alpaca
Prompt templates customise the system prompt per command. Defaults ship in the
jar for chat, edit, analyze, explain, suggest, refactor, agent,
webfetch, websearch and ubermode. CadetCoder writes example overrides to
~/.cadet/prompts/*.json.example on first run. Drop a <command>.json next to
them to override one, or use the prompt command.
The default system prompt is a further template, named system, and the only
one that applies to every command. It holds the operating principles the agent
works by, and it leads the system prompt of every request. The command's own
prompt follows it, with its command catalog and required action format.
Commands that send no system prompt of their own get the principles alone.
CadetCoder composes that prompt once, where every completion funnels through, so a command cannot omit it and a new command inherits it without any work. The block is constant, so it forms a stable prefix, which is what a provider caches. It costs roughly 900 input tokens on the first request of a conversation and comes from cache afterwards.
Override it like any other template, with ~/.cadet/prompts/system.json.
{ "name": "system", "version": "1.0", "content": "Your principles here." }
Set "content" to an empty string to remove the block. Each command's prompt
then stands alone.
The uber-mode directive is the third kind, named ubermode. CadetCoder appends
it to an agentic command's own prompt, and only while
uber mode is on, so it qualifies the completion contract above it
rather than the reverse. It says what finishing means: every part of the
request, verified with what the project can be checked with, with the
surrounding code still in agreement. Edit ~/.cadet/prompts/ubermode.json to
change how hard a run is pushed.
Limitations
Both items below were reproduced against
target/CadetCoder-1.0-SNAPSHOT.jar.
login cannot accept a key without a TTY
This is by design rather than a defect, but it means login is unusable in CI,
over a pipe, and on the interactive shell's prompt line. Use the provider's
environment variable instead. See
Set up a provider.
Console output wraps to a width it is told
CadetCoder does not measure the terminal width for its own messages. Set
COLUMNS=100, export COLUMNS, or pass -Dcadet.terminalWidth=100. Any of
those breaks the tool's own messages on spaces and indents the continuations
under the text. -Dcadet.terminalWidth=0 turns that off again.
With nobody to say, CadetCoder re-wraps nothing. Output that is piped, redirected or captured has no width, and a break inserted there lands in the middle of what another program reads. A question to the terminal costs about 60 ms of a 315 ms startup on every invocation, which is not worth it for a handful of lines.
CadetCoder never wraps aligned listings, whatever the width. That covers
help <command>, config and models. Their columns carry more meaning than
the overflow costs. The interactive shell measures its own width and always
has.
Build and test
mvn clean package -DskipTests    # jar only
mvn test                         # full suite: 4,838 tests
mvn clean package                # both
Run the suite from a git checkout. GitIntegrationTest resolves a repository
from the working directory, and 9 of its tests error with
RepositoryNotFound in a plain copied directory.
Build with JDK 17, because maven-compiler-plugin targets 17. The jar it
produces runs on 17 or newer. See
A native access warning on JDK 22 and newer.
mvn verify additionally enforces a JaCoCo floor over the whole project: 80%
of lines and 67% of branches. The measured figures are 81.7% of lines and 70.6%
of branches. Raise the floor as coverage improves. Never lower it to make a
build pass.
What remains uncovered concentrates in one class.
commands/InteractiveShell accounts for 649 of the project's roughly 6,400
uncovered lines. What is left in it is the TamboUI event loop and the threads
around a running command. Neither is reachable without a terminal. Everything
that could be lifted out of it was lifted out, and is tested. See the TUI note
in CADET.md.
Project layout
src/main/java/com/eonmux/cadetcoder/
├── Main.java                 # picocli entry point, global flags, session/script/interactive modes
├── CommandRegistry.java      # reflection-based command discovery and dispatch
├── OutputFormatter.java
├── commands/                 # every command implementation, plus InteractiveShell
├── harness/                  # the agent harness `agent` runs under
│   ├── loop/                 # the run loop: transcript, reasoners, escalation, stop
│   ├── tools/                # what the agent may do, and the session that gates it
│   ├── ledger/               # the hash chain of what really happened
│   ├── env/                  # the environment the agent observes and acts on
│   ├── model/                # the theory it holds about the project, and the language it is in
│   ├── belief/, spec/, fit/  # what it thinks, what it predicts, and what fits the evidence
│   ├── plan/, commit/        # search before acting, and the gate on acting
│   ├── budget/, certify/     # what a run may spend, and whether its record stands up
│   └── cadet/                # the bindings to this tool: commands, models, records, the terminal
├── agents/                   # worker pool, registry and results for `workers`
├── ai/
│   ├── AIManager.java, AIClient.java, APIClient.java, LocalAIClient.java, ConnectorAIClient.java
│   ├── providers/            # the 23 connectors and their auth schemes
│   ├── catalog/              # models.dev catalog loading and caching
│   ├── metrics/              # token counts and speeds for each request
│   ├── templates/            # the 11 chat templates
│   └── parsing/              # response and action parsing
├── auth/                     # GitHub Copilot device flow
├── config/                   # Configuration, ConfigManager
├── context/                  # CADET.md project context, and the Lucene search engine
├── git/                      # JGit integration, auto-commit scheduler
├── logging/                  # debug and session logging
├── jobs/                     # background jobs that `job` starts
├── timers/                   # repeating check-ins the model sets itself
├── net/, patch/, security/, session/, shell/, ui/, util/, error/, prompts/
CadetCoder is built on picocli for the CLI, JGit for git, Apache Lucene for the index, Jackson for JSON, JLine and TamboUI for the interactive shell, and Reflections for command discovery.
Three further items sit at the repository root beside the source: LICENSE,
which is Apache 2.0; NOTICE, which records what the shaded jar bundles and
under what terms; and licenses/, which holds the full text of every bundled
licence that is not Apache 2.0. All three are packaged into the jar under
META-INF.
assets/ holds the tour at the top of this page. It is not packaged into the
jar.
Further documentation
CADET.md is the project-context file that CadetCoder reads when
it works on this repository. It also describes the architecture and the
conventions for contributors. Manage it with context show and
context create.
Licence
CadetCoder is licensed under the Apache License, Version 2.0. See
LICENSE.
Copyright 2026 Amir Farhad Eslampanah

Licensed under the Apache License, Version 2.0 (the "License");
you may not use this file except in compliance with the License.
You may obtain a copy of the License at

    http://www.apache.org/licenses/LICENSE-2.0
mvn package produces a shaded jar that bundles its dependencies, so their
licences travel with it. NOTICE names each one. The texts that are
not Apache 2.0 live in licenses/, and inside the jar at
META-INF/licenses. Those are JGit's Eclipse Distribution License, JLine's BSD
3-Clause, and the MIT licences of SLF4J, TamboUI and the bundled models.dev
catalog snapshot. JNA, Reflections and Javassist each offer a choice of
licences. This project takes the Apache License, Version 2.0 for all three, and
NOTICE records that choice, because it belongs to whoever distributes the
jar.
Similar repos


Languages
Java
100.0%
An LLM coding terminal interface written entirely in Java
Java
0
7 commits
updated Sep 30, 2026
See what people are saying
README
CadetCoder
CadetCoder is a Java 17+ command-line coding assistant. Point it at a model provider. It then reads, searches, edits and commits files in your project, either from a direct command or from a request in plain English. It ships connectors for 23 providers, among them Anthropic, OpenAI, OpenRouter, Google, Amazon Bedrock, GitHub Copilot, Groq and a local OpenAI-compatible endpoint.
The agent loops (chat, agent and workers) search the codebase, propose
edits and run checks. Uber mode makes the model confirm that the work is
finished before a run ends. CadetCoder also ships a full-screen interactive
shell, timers, background jobs, sessions, themes and prompt templates. Requests
ask providers for zero data retention by default.
Build it with mvn clean package -DskipTests. The jar lands at
target/CadetCoder-1.0-SNAPSHOT.jar.
The tour runs a local model. The waits for the model play at up to three times normal speed.
Contents
- Requirements
- Install
- Set up a provider
- Your first task
- The agent harness
- Workers
- Timers
- Background jobs
- Uber mode
- Resume an interrupted run
- Read the output
- Command output
- How commands are dispatched
- Command reference
- Global options
- Configuration
- Interactive shell
- Themes and templates
- Limitations
- Build and test
- Project layout
- Further documentation
- Licence
Requirements
| Requirement | Detail |
|---|---|
| Java | 17 or newer. Built and tested on 17 and 21. |
| Maven | Needed to build. Needs network access to Maven Central and the Central snapshot repository. See Install. |
| Git | Optional. Needed for commit, push and undo, and for auto-commit. |
| A model provider | An API key for one connector, or a local OpenAI-compatible server. The default local endpoint is http://localhost:8012. |
A native access warning on JDK 22 and newer
The jar bundles JLine's terminal provider for java.lang.foreign, the API that
became final in JDK 22. On JDK 17 and JDK 21 the shell starts without any
warning; both were tested. On JDK 22 and newer the JVM may print a notice like
this before the program starts. JDK 22 was not available to test, so this is
not confirmed.
WARNING: A restricted method in java.lang.foreign.Linker has been called
WARNING: java.lang.foreign.Linker::downcallHandle has been called by the unnamed module
WARNING: Use --enable-native-access=ALL-UNNAMED to avoid a warning for this module
The JVM prints that text, and no code inside the program can suppress it. Pass
--enable-native-access=ALL-UNNAMED before -jar to silence it.
Install
git clone <repository-url> cadetcoder
cd cadetcoder
mvn clean package -DskipTests
The executable jar lands at target/CadetCoder-1.0-SNAPSHOT.jar. Define an
alias for the examples below.
alias cadet='java -jar /absolute/path/to/target/CadetCoder-1.0-SNAPSHOT.jar'
On a machine with several JDKs, pin 17 in the alias.
alias cadet='/usr/lib/jvm/java-17-openjdk/bin/java -jar /absolute/path/to/target/CadetCoder-1.0-SNAPSHOT.jar'
CadetCoder writes its state to ~/.cadet/ on first run. That covers the
config, sessions, logs, index and model cache.
If the build cannot resolve TamboUI
The interactive shell depends on dev.tamboui:*:0.5.0-SNAPSHOT. That artifact
is published only to the Central snapshot repository, which pom.xml declares
as central-snapshots. A catch-all mirror in your ~/.m2/settings.xml
intercepts that repository too, and the build then fails to resolve TamboUI.
<mirror><id>nexus</id><mirrorOf>*</mirrorOf><url>https://nexus.example.com/...</url></mirror>
Fix it in one of two ways. Either make the mirror proxy the Central snapshot repository, or exclude the snapshot repository from the mirror.
<mirrorOf>*,!central-snapshots</mirrorOf>
Set up a provider
CadetCoder needs a model before it can do anything AI-driven. Three commands
cover the setup. Run models to see what exists, login to authenticate, and
models use to select. All three work from the command line.
1. See what is available
cadet models              # catalog summary, then the 23 connectors
cadet models providers    # connector table: protocol, auth scheme, env vars
cadet models anthropic    # the models one provider offers
cadet models find claude  # search model ids and names across every provider
A wire protocol is the request and response shape a provider accepts.
CadetCoder implements four: OpenAI Chat Completions, Anthropic Messages, Google
Generative AI (generateContent), and Amazon Bedrock Converse with SigV4
signatures.
cadet models providers names the exact environment variable each connector
reads, along with its protocol, auth scheme and retention control.
anthropic              Anthropic                  ANTHROPIC_MESSAGES              X_API_KEY       provider default  ANTHROPIC_API_KEY
google                 Google                     GOOGLE_GENERATIVE_AI            X_GOOG_API_KEY  provider default  GEMINI_API_KEY,GOOGLE_GENERATIVE_AI_API_KEY
amazon-bedrock         Amazon Bedrock             BEDROCK_CONVERSE                AWS_SIGV4       provider default  AWS_BEARER_TOKEN_BEDROCK,AWS_ACCESS_KEY_ID,AWS_SECRET_ACCESS_KEY
openai                 OpenAI                     OPENAI_CHAT                     BEARER          no storage        OPENAI_API_KEY
openrouter             OpenRouter                 OPENAI_CHAT                     BEARER          zero retention    OPENROUTER_API_KEY
commandcode            Command Code               OPENAI_CHAT/ANTHROPIC_MESSAGES  BEARER          zero retention    COMMAND_CODE_API_KEY,CMD_API_KEY
local                  Local (OpenAI-compatible)  OPENAI_CHAT                     NONE            provider default  -
The full list of 23 also covers xAI, Azure OpenAI, Cloudflare AI Gateway, Cloudflare Workers AI, GitHub Copilot, OpenCode Zen, OpenCode Go, Groq, DeepSeek, Cerebras, Fireworks AI, Together AI, Baseten, DeepInfra, Mistral and Perplexity.
A connector normally speaks one protocol for every model it offers. A gateway
that resells several vendors need not. Command Code serves its Claude models
only from the Anthropic Messages endpoint and everything else only from Chat
Completions, and each endpoint refuses the other's models. CadetCoder therefore
chooses the protocol per model rather than per provider. Run
cadet models commandcode to list what that gateway currently offers.
CadetCoder asks the gateway directly, because models.dev carries no entry for
it.
2. Provide a credential
Option A is an environment variable. It works everywhere and stores nothing.
Export the variable that models providers listed, and the connector picks it
up.
export ANTHROPIC_API_KEY=sk-ant-...
cadet models use anthropic claude-sonnet-4-5
Option B is login, which saves the key into ~/.cadet/config.json.
cadet login              # pick a provider from a numbered list, then authenticate
cadet login anthropic    # authenticate one provider directly
cadet login status       # per-connector credential status; keys are never printed
cadet login logout openai
login reads the key with System.console().readPassword(...), so the
terminal does not echo it and your shell history does not record it. This needs
a real terminal. System.console() returns null when output is piped, under
CI, and on the interactive shell's prompt line. In those cases login refuses
to read the key rather than echo it, and it names the environment variable
instead.
⚠ Cannot read the API key here without showing it on screen, so it will not be
  requested on this prompt for security.
Export ANTHROPIC_API_KEY before starting, then run 'login anthropic' again.
Alternatively, run the 'login anthropic' command from a real terminal (outside the TUI) where the key can be typed without being echoed.
That refusal is intended. Use Option A in any context without a terminal.
GitHub Copilot takes no API key. Run cadet login github-copilot or
cadet copilot login to start the OAuth device flow. The command prints a user
code and then waits for you to authorise it in a browser. CadetCoder caches the
token in ~/.cadet/copilot-auth.json.
Disclaimer. CadetCoder is not affiliated with or endorsed by GitHub. The Copilot login uses the OAuth client ID of GitHub's own Copilot editor integrations, because GitHub does not issue one to other tools. GitHub's terms may not permit that use. GitHub could revoke access or restrict your account. Use the Copilot connector at your own risk. The login shows this notice before it contacts GitHub.
After a successful login, CadetCoder offers to make that provider active and to
pick a model. Set it later with models use if you decline.
3. Select the active model
cadet models use openai gpt-4o    # set provider and model directly
cadet models use anthropic        # set provider, then prompt for a model (needs a TTY)
cadet models select               # interactive: pick provider, then model (needs a TTY)
cadet models current              # show what is active, and whether it has a credential
models use <provider> <model> is the non-interactive form. Use it in scripts.
4. Verify
cadet models current
▎ Active model
  Provider: anthropic (Anthropic)
  Model:    claude-sonnet-4-5
  Window:   200,000 input tokens (published for anthropic/claude-sonnet-4-5)
  Auth:     configured (saved key)
Window: gives the model's input window and where that figure came from. Run
models context <tokens> to set the window for the active model. Run
models context clear to remove that setting.
Auth: reports one of six states.
configured (saved key)configured (env <VAR>)authenticated (device flow)for GitHub Copilot after a loginnot logged infor GitHub Copilot before a loginno key requiredfor thelocalconnectorno credential
With no connector selected, models current prints
No connector provider is configured (falling back to the legacy local/API client). CadetCoder then sends requests to ai.localEndpoint, which defaults
to http://localhost:8012. Every AI command fails with
java.net.ConnectException when nothing listens there.
Per-invocation override
You need not persist anything.
cadet --provider groq --model llama-3.3-70b-versatile --provider-key "$GROQ_API_KEY" "..."
cadet --provider anthropic --model claude-sonnet-4-5 "summarize Main.java"
Amazon Bedrock takes its credentials from the standard AWS chain.
export AWS_ACCESS_KEY_ID=... AWS_SECRET_ACCESS_KEY=... AWS_REGION=us-east-1
cadet --provider amazon-bedrock --model anthropic.claude-3-5-sonnet-20240620-v1:0 "..."
Zero data retention
Every request carries the files, diffs and prompts of whatever you work on, so
ai.zeroDataRetention is on by default. CadetCoder asks each provider not to
retain the request wherever the provider accepts such a request. Where no
control exists, nothing changes, so the setting costs nothing on those
providers.
Three connectors implement a control, and they do not all promise the same
thing. The Retention column of cadet models providers reports which is which.
| Connector | How CadetCoder asks | What you get |
|---|---|---|
| Command Code | x-cmd-zdr: 1 header, on both of its protocols | zero retention: the gateway refuses the request rather than route it to an upstream that would keep it |
| OpenRouter | provider.zdr in the request body | zero retention: routed only to upstreams that agreed not to keep it |
| OpenAI | store: false in the request body | no storage, which is weaker. See below. |
OpenAI offers no per-request zero retention. store: false keeps the exchange
out of the stored history that the account can read back. OpenAI still retains
abuse-monitoring logs for up to thirty days, and no request parameter turns
that off. OpenAI arranges true zero retention for an organisation or project
rather than per request. CadetCoder therefore reports "no storage" for OpenAI
and "zero retention" for the other two.
CadetCoder sends OpenRouter provider.zdr rather than
provider.data_collection: deny. The second field is a promise about training
rather than about retention, and sending it would report a guarantee that
nobody gave.
A provider can refuse the request. A gateway that resells a model whose upstream
will not agree to zero retention answers with an error rather than retain the
request quietly. Command Code answers 422, and the message names both ways
out.
Provider 'commandcode' has no zero-retention upstream for model 'Qwen/Qwen3.8-Flash' (HTTP 422),
so it refused the request rather than retain it. Either choose a model whose upstream does promise
it, or allow retention deliberately with `cadet config ai.zeroDataRetention false`.
Most models have a zero-retention upstream. Prefer a switch of model over a change to the setting, because the setting is global and the gap is usually specific to one model.
Your first task
Non-AI commands work with no provider configured. Start there to confirm the install.
$ cd ~/my-project
$ cadet ls -l
-rw-rw-rw-      86B   2 min ago  Foo.java
-rw-rw-rw-      12B   2 min ago  README.md

 2 files, 0 directories, total size: 98B

$ cadet grep -n class
▎ Foo.java
    1: public class Foo { ... }

✓ Found 1 match in 1 file

$ cadet read Foo.java
Substituted path: 'Foo.java' -> './Foo.java'
▎ File: /home/you/my-project/Foo.java
     1	public class Foo { ... }
Then try a real AI task, once a provider is set up.
$ cadet "add a null check to the constructor in Foo.java and explain what you changed"
The first word is no recognised command, so CadetCoder routes the whole string
to chat. chat runs an agentic loop. It may call glob and grep to locate
files, read them, propose edits as SEARCH/REPLACE blocks, and ask before it
writes. bash and write ask for confirmation unless you pass -f.
There is no iteration limit. A task runs until it completes, fails, or stops making progress. A fixed ceiling is the wrong stop condition in both directions. It cuts off long tasks that work steadily, and it does nothing about a run stuck on step three.
The loop guard ends a stuck run. It refuses only repetition that cannot produce new information. It refuses an action in three cases:
- The same command with the same arguments already produced the same result twice.
- A multi-step sequence repeats with identical results.
- Ten consecutive commands return nothing that was not already seen.
Normal work is never blocked. That covers reads of many different files, several different searches, and a re-read of a file after an edit. On a refusal, CadetCoder tells the model which invocation repeated and what to do instead. The run stops once the guard refuses several proposed actions in a row.
Ten commands propose no actions: explain, analyze, refactor, suggest,
search, commit, edit, multiedit, webfetch and websearch. The same
principle applies to what the model returns for those. When a
reply repeats the one before it, the next request carries a short note that
says so, plus a unique id, so a provider that answers deterministically cannot
return the same bytes again. The run stops when the reply still repeats after a
few turns.
You can still impose your own budget. Use cadet agent -m <steps> or
-t <seconds>, or set -Dcadet.iterative.maxIterations=<n>, where 0 means
unlimited. None of them is set by default.
CadetCoder batches reads. multiread returns several files in a single call,
so five files cost one model round trip instead of five.
Request metrics
Every request prints one line when it completes.
~5,460 in (5,348 cached · 112 new) · ~340 out · 4.2s · 1,300 in/s · 81 out/s (47 over 5s)
in (cached · new)splits the input. cached is the provider's own count of cached input tokens when the provider reports one. Otherwise it is the leading part of this request that is byte-identical to the previous one, which is the part a provider can serve from a cached prefix. new is the rest. See prompt reuse.outcounts the tokens the model produced. CadetCoder reports input and output separately, because providers price them differently and the two move independently. A run can shed input through compaction while its output stays flat, and the two numbers say which one is the problem.4.2sis the wall-clock time for the request.1,300 in/sis the input processed per second for that request.81 out/sis the generation speed for that request alone. The figure in brackets is the trailing five-second session rate.
The shell shows the same figures as they accumulate while a request is in flight.
4.2s · ~5.6k in (96% cached) · total ~3.1k out
The elapsed time ticks, so you can tell a slow provider from a hung one. The cached share is a percentage rather than a count, because the count is not yet final. The output figure is the session total, because the current request's own output is unknown until it arrives.
A leading ~ marks an estimated figure. CadetCoder uses the provider's own
token counts where the provider reports them, and then omits the ~. Where the
provider reports none, CadetCoder estimates at roughly four characters per
token, because it talks to four wire protocols and ships none of their
tokenizers. Treat a marked figure as a relative measure rather than a billing
one. The in-flight line above always carries the mark, because a provider sends
its counts with the response. Suppress the line with
-Dcadet.metrics.show=false.
CadetCoder prints a cumulative summary at exit when the run made at least one request.
Prompt reuse
CadetCoder builds every turn's prompt append-only. Turn N+1 is turn N plus the new exchange. Prompt caching needs that property, because a provider can then serve the shared leading prefix from cache and process only the tail.
Measured over an eight-turn conversation, the reusable region beyond the system prompt grows by roughly one exchange per turn. The system prompt is stable for the whole run.
Keep this invariant if you change how CadetCoder assembles prompts. Nothing
volatile may go anywhere except the very end. That covers a timestamp, an
iteration counter and a re-computed snippet. The transcript may only ever be
appended to. PromptCachePrefixTest fails if that stops holding.
Cache breakpoints
A stable prefix is necessary but not sufficient. Some providers cache automatically. Others cache only what the request explicitly marks.
| Provider or protocol | What CadetCoder sends | Why |
|---|---|---|
| Anthropic Messages | cache_control: {"type":"ephemeral"} on the system block and the user block | Anthropic caches nothing without a breakpoint |
| Bedrock Converse | a {"cachePoint":{"type":"default"}} block after the system and user content | the same, in Converse's spelling |
| OpenRouter | cache_control inside the content parts | OpenRouter forwards it to the Anthropic and Gemini models it proxies |
| OpenAI and OpenAI-compatible providers | nothing | these match a shared prefix automatically, and an unrecognised field would risk a rejection |
| Google Generative AI | nothing | implicit caching is automatic, and the explicit mode is a separate stateful cachedContents resource rather than a per-request marker |
CadetCoder uses two breakpoints where they apply: the system prompt, which is stable for the whole run, and the end of the conversation so far. The second breakpoint writes the whole prompt into the cache. The next turn appends to it, reads everything from cache, and pays only for what it added.
Breakpoint support depends on the model rather than on the provider alone.
Bedrock rejects cachePoint outright for models that do not implement it.
CadetCoder therefore treats caching as an optimisation that may fail. A
rejection that names a cache field disables breakpoints for that provider and
model for the rest of the process, retries once without them, and warns. A
rejection for any other reason passes through untouched. Disable breakpoints
up front with -Dcadet.cache.breakpoints=false. CadetCoder sends no breakpoint
on a prompt shorter than 4,096 characters, because providers ignore a cache
marker on a prefix that short.
When a request fails
CadetCoder retries only failures that can plausibly change outcome on a second try: 408, 429, 5xx, and transport errors. It does not retry a 400 or a 401, because a repeat of a malformed or unauthorised request produces the same answer more slowly.
A 200 is not automatically a success. Status codes describe the HTTP exchange rather than the provider behind it. Two things arrive under a 200 and mean "try again": a gateway in front of the model answers with its own error payload, and a body is cut off in flight. Both look like "the model replied with nothing" under a check of the status alone, which is terminal, so a run that had already made twenty good requests would die on a blip.
The check is structural rather than a search of the body text. A completion's
text is arbitrary. Ask this tool why a provider rate-limits you, and the
correct answer contains every word that a naive scan looks for. CadetCoder
therefore reads failure wording only inside a top-level error node, which a
successful response does not have. It tells an unparseable body apart the same
way. A body that starts as JSON and stops was truncated in flight, so
CadetCoder retries it. A body that was never JSON means the endpoint does not
speak the protocol, which is a misconfiguration that no retry can fix.
CadetCoder bounds every request rather than completions alone. The health probes, the models.dev catalog fetch and the OAuth device flow all go through one helper that cannot block forever. A probe that hangs at startup stops the CLI as dead as a completion that hangs mid-run.
Two timeouts apply, because they bound different things. HttpRequest.timeout
in the JDK covers the wait for response headers only. That was measured rather
than assumed: a two-second timeout let a six-second body through untouched.
The split suits a completion, because time-to-first-byte is predictable while
generation time scales with the answer. On its own it leaves a hole. Once
headers arrive, a body that stops mid-flight without a closed connection blocks
forever, and the run freezes with no timeout and no retry.
cadet.llm.responseDeadlineSeconds is the backstop for that case. Set it far
above any real generation time rather than as a latency budget.
CadetCoder drops pooled connections before the far end drops them. The JDK keeps an idle connection for 1200 seconds by default. Almost nothing in front of a model API holds one that long: an AWS load balancer closes at 60 seconds and nginx at 75. The pool then hands back sockets that the far end closed minutes ago, and the next request fails as an unreachable provider. An agentic run makes that routine, because its gaps are exactly this long. CadetCoder sets 50 seconds instead, below the tightest of them. A lost reuse costs one TLS handshake. A dead connection costs a request.
The retried set is exactly the set that rewards persistence, so the budget is generous. CadetCoder makes 10 attempts by default, with exponential backoff from 500 ms, capped at 20 s per wait and jittered so that concurrent runs do not resynchronise. The worst case is roughly a minute and a half of waiting before a run gives up, and about half that in practice.
The shell offers one more attempt once the automatic attempts are spent. It does so only when a terminal exists to ask, and only for a failure that a retry can fix. A rejected key gets no offer.
✗ AI request failed: 503 Service Unavailable
Enter to retry, or 'stop' to end the run >>>
Enter, retry, or y tries again. Anything else ends the run. The alternative
discards a run that already made twenty successful requests, because the
twenty-first hit a provider that was briefly down. A script, a pipe and CI have
nobody to ask, so the failure propagates as before and the exit code does not
change. End-of-input counts as "stop" for the same reason, because a loop on an
EOF that will never change would hang. Suppress the prompt on a terminal with
-Dcadet.manualRetry=false.
| Property | Default | Effect |
|---|---|---|
cadet.llm.maxAttempts | 10 | total attempts including the first; clamped to 20 |
cadet.llm.retry.baseDelayMs | 500 | first backoff, doubled from there |
cadet.llm.retry.maxDelayMs | 20000 | ceiling on a single wait |
cadet.manualRetry | true | offer Enter-to-retry once the budget is spent |
cadet.llm.connectTimeoutSeconds | 10 | establish the TCP and TLS connection |
ai.completionTimeoutSeconds (config) | 300 | wait for response headers, which is the whole generation because nothing streams |
cadet.llm.responseDeadlineSeconds | 600 | whole exchange including the body; a stall backstop |
jdk.httpclient.keepalive.timeout | 50 | idle pooled-connection lifetime; set unless you set it |
CadetCoder honours the provider's Retry-After-Ms header ahead of
Retry-After, and accepts Retry-After in both RFC 7231 forms, delay-seconds
and HTTP-date. The millisecond form matters at the short end. A provider that
asks for 200 ms must express it as Retry-After: 1, which rounds up to five
times the wait it wanted. A Retry-After longer than
cadet.llm.retry.maxDelayMs ends the retries, because the provider asked for a
pause longer than the CLI waits.
The agent harness
chat answers a request. Use agent for work that you want evidence for. It
runs under the agent harness, which records that evidence.
cadet agent "make the action parser reject an empty ARGS block, with a test"
cadet agent "fix the failing build" -c "bash mvn -o -q test"
The loop has four stages: observe, deliberate, commit, observe. Each turn the harness shows the agent where the world is. The agent then thinks, and it has exactly one way to change anything.
- The ledger records every step. The harness appends what the agent observed, what it did and what happened next to a hash-chained ledger. The ledger is the run's ground truth, and nothing rewrites it.
- The agent writes its beliefs as an executable model. It states how it
thinks this project behaves as a small program, and
certifyreplays the whole ledger through that program. A certificate reports two things: the model reproduced every transition, and the ledger exercised these particular rules. A rule that the ledger never touched is untested, however green the run reads. - Every change reaches the world through the commit gate. The gate admits a plan when a green certificate covers the current ledger head. It cuts the plan off at the first step that turns on a rule the ledger has never exercised, so the agent acts on an untested belief once, under observation, and never builds on it. With no model at all, an agent gets a blind probe of three actions and no more. An irreversible action needs a certified model behind it. The policy belongs to whoever started the run, because an agent that could widen its own gate would not have one.
- The agent's actions are the commands you type. It acts through the same
registry as the CLI and the shell, under the same confirmation and path
rules. CadetCoder marks what the agent runs as a model's doing, so a
quitends the agent's own run rather than your session. The agent cannot start a second agent or a chat inside itself.
Every run keeps its own record under .cadet/runs/<timestamp>-<unique>/. The
record holds what the run was asked to do, how it ended, the ledger, the models
the agent wrote, its beliefs and its notes. The last line of a run says what to
type to read that record back. No two runs share a directory, so eight workers
leave eight readable records. runs lists them newest first, runs show opens
one, and runs ledger prints the last things that really happened.
What "done" means. Without -c, a run ends when the agent declares the
work finished. With -c <command>, that command runs after every action and
its exit code decides: the task is done when the check exits 0, whatever the
agent believes. agent itself exits 0 only for a task that finished, either by
the check or by the agent's declaration. A run that spent its allowance or gave
up exits 1. A run that you called off exits 130. Its record is complete in
every case and worth a read.
Budgets are yours to impose, and none is set by default. -m <steps>
bounds how many times the agent may think. -t <seconds> bounds how long the
whole run may take. --classic asks for the classic loop, which keeps no
ledger and no record. You have to ask for it by name, because a run that
downgraded itself quietly would report the same work with none of the evidence
behind it.
When a run stops learning. Four rounds of thought that certify nothing new
and fix no mispredictions make a plateau. The harness measures that off the
record rather than asks the agent, because an agent inside a loop always has a
reason for the next step, which is why it cannot tell that the last four
produced nothing. A plateau hands the run to the model that ai.escalateTo
names, with the beliefs and the latest certificate in front of it and a note
that says what it has walked into. The run's record counts the hand-over.
cadet config ai.escalateTo gpt-5 # a model on the provider you are already connected to
Nothing is named by default, because which of two models is the stronger one is a fact about the account that pays for them. A run that stalls with nobody to hand to says so once and says what to set. That is not an error and does not stop the run, because an agent that explores a part of a project it has no model for legitimately certifies nothing for a while.
Workers
Some questions are wide rather than deep. Examples: review this change for correctness, for security, and for test coverage; or search four subsystems for the same defect. One agent answers those in sequence. It carries every earlier answer in its context and gets slower and less focused as it goes.
cadet workers "review error handling" "review test coverage" -b "the net package"

cadet workers start "<task>" "<task>"   # start them and carry on
cadet workers status                    # who has finished, who is still going
cadet workers wait [<seconds>]          # block until they finish
cadet workers stop                      # end them, and keep what finished
cadet workers list                      # summary of the last run
cadet workers show 2                    # one worker's output in full
Each worker may think 12 times by default. Pass -m <steps> to change that.
CadetCoder tells the model the whole lifecycle rather than how to start alone. A capability the model cannot discover how to read or stop is one it will either abandon mid-run or wait on forever, so the command catalog in every agentic system prompt carries every verb, and the limits the model would otherwise learn by refusal. Workers themselves get the catalog without this entry, because an offer of a capability that is refused on use costs a turn and teaches nothing.
A worker cannot ask you anything, because nobody watches its output while it
runs. With security.commandApproval at its default, manual, a worker's
shell commands that need approval are therefore refused. Set it to auto if
you want workers to run shell commands, and accept that the model then
approves them.
Only one run exists at a time. CadetCoder refuses a second start while one is going rather than queue it. A queue would double the agents pointed at one provider, and it would make every later question about "the workers" ambiguous.
Every first word that is not one of those verbs is a task, so CadetCoder
reports a misspelled verb such as workers staus rather than run it.
Otherwise a typo starts an agent whose task is the typo, at the provider's
price, and answers a question about the workers by doing something else.
CadetCoder tests a single bare word this way alone, because a task is a
sentence and workers "stop the memory leak" is a task. To insist on the one
word, name the verb: workers start "staus".
Each worker runs its own agent over the same briefing and its own task. The briefing is identical across workers and comes first in every prompt, so a provider can serve it from a cached prefix. The task differs per worker and goes last, which follows the same append-only discipline as the main loop.
Workers never see each other's output. Two reasons hold. Different context makes findings incomparable, because a disagreement might be a real conflict or two agents that looked at different things. Shared output makes workers converge on whatever the first one said, which is the failure this design avoids. It follows that workers suit steps that are independent. Use one agent for steps that depend on each other.
Three workers run at once by default, up to eight per run. Set
performance.threads to change it, or set performance.parallelProcessing to
false to run them one at a time. -Dcadet.workers.concurrency overrides both
for a single run. The provider sets the limit rather than the machine. Every
worker is a full agentic loop against one account and one shared retry budget,
so past a handful they stop queueing and start to fail each other. CadetCoder
reads the number in one place, reports it before a run starts, and tells the
model the same figure. A worker cannot start more workers.
workers start keeps the workers running across the model's later steps, so
the model can start a set of reviews, read something else, and come back for
the results. A one-shot CLI invocation waits for them before it exits rather
than kill them microseconds after launch.
In the shell, Tab steps through the workers. It shows each worker's output as
it arrives, whether or not that worker has finished. The header bar counts them
off, as in 2/5 workers done. CadetCoder collects a worker's output per worker
rather than streams it, so without that counter the bar would sit unchanged for
minutes, which reads exactly like a hang. F2 stops the run and its workers.
What had finished is still there to inspect, and /resume runs again only the
tasks that did not finish.
Timers
An agent has no clock. It sees a prompt, answers it, and does not exist again until the next one. "Check back on this in two minutes" is therefore something it can intend and cannot arrange. Without timers the only ways to wait are to sit inside one command with the run blind for the duration, or to spend a model call on the question of whether it is time yet.
A timer is a note the model leaves itself.
timer create --every 2m check whether the workers have finished
Every loop in CadetCoder appends the timers that are due to the prompt it is
about to send. That covers chat, the classic agent loop and the harness.
[timer] t1 fired at 2026-09-13T18:22:04+01:00 -- firing number 3, unlimited left, every 2m.
You set it to: check whether the workers have finished
The count tells a third check on a build from a first. That is the difference between a build that still runs and a build that ran far too long. The timestamp makes "far too long" measurable. Neither is recoverable from the note itself, and a model asked to keep its own tally across a compacted transcript will not have one.
| Command | What it does |
|---|---|
timer create --every <interval> <what to check> [--limit <n>] | Set one. Intervals are 30s, 5m, 2h, 1d or 1h30m, from 5 s to 24 h; a bare number means seconds. --limit retires the timer after that many firings. |
timer list | Report what is set, and when each is next due. |
timer cancel <id>, timer cancel all | Stop one timer, or all of them. |
timer wait [<seconds>] | Block until the next one is due, instead of a step spent on nothing. Capped at ten minutes. |
Four points are worth knowing.
- CadetCoder drops missed firings. A run that spends twenty minutes inside one command is owed one reminder when it comes back, rather than ten identical ones with the wrong count on each.
- CadetCoder delivers a firing once. It takes the firing from the register at the moment it reports it, so the same firing never reaches two prompts and the count always means how many times the thing happened.
- Each agent has its own timers, and loses them when it ends. A
workersrun puts up to eight agents on their own threads. A note one of them left itself never arrives in another's prompt, and CadetCoder discards it when that worker finishes. Workers are numbered from one in every run, so the next run'sWorker 1is a different agent on different work and must not inherit the last one's timers. - CadetCoder does not record firings in the transcript. A firing is true of one moment, so CadetCoder appends it to the prompt and nowhere else. That also keeps every turn's prompt an extension of the last one, and therefore cacheable.
Timers live for the session rather than for one request, so one set during an
investigation of a build is still running when you ask the next question. The
shell's header bar counts them, as in 2 timers, so a timer left behind is
visible rather than merely surprising. Each agent may have at most eight
timers at a time.
Background jobs
bash waits for what it starts. That is right for almost everything: a command
that answers in a second is best answered by its output. It is wrong for work
that takes longer than a step. A full build, a test suite, a server that has to
be up while something is tried against it -- waiting for those spends the step,
then the timeout, and the command is killed before it finishes.
A job is the same command, started and let go.
job start mvn -o test -d "the full suite"
The call returns at once with an id. The command keeps running while the conversation goes on, its output accumulates, and when it ends the model is told in its next prompt.
[job] j1 finished successfully after 4m12s.
It ran: mvn -o test
You started it to: the full suite
It printed 812 lines you have not read; read them with `job output j1`.
A job that failed carries its last twenty lines into that notice without being asked. A run told only that the build failed will either spend its next step asking why, or act on the failure without reading it.
| Command | What it does |
|---|---|
job start <command> [-d <description>] | Run it without waiting. Returns an id. |
job list | Every job, how long it has run, and how many lines are unread. |
job output <id> [--all] [-n <lines>] | What it printed since you last looked, at most 200 lines unless -n says otherwise. --all starts again from the beginning. |
job stop <id>, job stop all | End one, or all of them. |
job wait [<id>...] [--all] [-t <seconds>] | Block until one ends, or with --all until every one has, instead of asking again and again. Waits 600 s by default and at most 3,600 s. |
Six points are worth knowing.
- Starting a job is screened exactly as
bashis. Same denylist, same network and path rules, same confirmation. A command nobody waits for is if anything the one worth screening most carefully. - CadetCoder announces an ending once. It takes the ending from the register at the moment it reports it, so the same job never reaches two prompts, and an announcement whose prompt was never sent is owed again rather than lost.
- Reading is incremental.
job outputgives what is new since the last read. A build watched over ten steps would otherwise spend the context window ten times on the same lines. - Output is bounded, and says when it was cut. CadetCoder keeps the last 200,000 characters per job and drops the oldest first, because what a job printed just before it failed is the part anybody reads. A read that starts after a drop says how many lines went.
- Jobs are stopped when the session ends. A job is a process, not a thread,
so leaving does not end it.
quitlists what it is about to stop. - At most eight run at once. The shell's header bar counts them, as in
2 jobs, so a job left behind is visible rather than merely surprising.
Jobs and timers are complementary. A job says when it has ended; a timer is for checking on something that gives no sign of its own.
Uber mode
Every agentic loop ends the same way. The model says it has finished, and the loop believes it. That is the only signal available, and the one participant who cannot check it produces it: the model declares completion from inside the same context that decided what completion meant. So a run ends with the tests unrun, with the second call site never updated, or with the last third of the request answered in prose. From outside, that is indistinguishable from a run that finished, because the closing summary describes the part that was done.
/ubermode on
Two things change.
CadetCoder tells the model up front what finishing means here. It means every
separate thing the request asked for, verified with whatever the project can
actually be checked with rather than reasoned about, with the surrounding code
still in agreement. A stop to report progress does not count as finishing. That
text is a prompt like any other, so prompt edit ubermode changes it.
A claim of completion also stops being the end of the run. CadetCoder answers the claim with two questions in a row.
- The first sends the model back to the request that started the run. It asks whether every separate part of that request is done, and it asks the model to run the project's checks rather than reason about them. It does not check against the summary, because the summary was written from the same understanding that decided the work was done and therefore always agrees with itself.
- The second asks what else depends on the files that the run actually changed, which is where abandoned work usually lives. It differs from the first on purpose, because a model asked the same question twice gives the same answer twice.
The run ends when the model answers both questions in a row without any further work. Any work in between starts the questions again from the first. A model that keeps finding work therefore keeps being asked, and a model with nothing left to do ends the run in two turns.
| Command | What it does |
|---|---|
ubermode | Turn it on if it is off, and off if it is on. |
ubermode on, ubermode off | Set it explicitly. |
ubermode status | Report what it does without a change to it. |
Uber mode is off by default. It costs turns, against your tokens, on work you
may consider already done. CadetCoder keeps the setting in config.json, so it
survives the session. The shell's header bar says uber while it is on,
because a mode nobody can see is a run that will not stop when you expect it
to. CadetCoder deliberately does not offer uber mode to the model as a command
it can run.
Resume an interrupted run
F2 stops a run. /resume carries it on from where it stopped.
/resume
A new request such as continue starts a new run, and a new run knows nothing
of the one before it. An interrupted run holds more than its request: the
actions it took, the pass of a loop it was on, and how many of uber mode's
questions its work had passed. When you interrupt a chat, agent, loop,
loopfresh or workers run in the interactive shell, CadetCoder saves that
state as the session's resume point. /resume starts the same command again
from it. CadetCoder also saves the point when the provider stops answering
after the run did some work.
Outside the shell, Ctrl+C ends the CadetCoder process at once, so a one-shot
command such as cadet chat "..." saves no resume point.
| Run | What /resume does |
|---|---|
chat | Shows the model the request and the conversation of the interrupted run, and keeps the count of uber mode's questions that the work had passed. |
agent | Starts the agent with the same options. The task carries the notes and the last ledger entries from the record of the interrupted run. |
loop, loopfresh | Carries on the pass that was interrupted, with what that pass had done, and then runs the passes left. |
workers | Keeps the results of the workers that finished, and runs again only the tasks that did not finish. |
An interrupt also stops the workers that the run started, including workers that a chat started in the background. The resumed run learns which of them finished. Jobs keep going after an interrupt, because a server or a watch build is often what the work needs. The resumed run learns which jobs ran.
CadetCoder keeps the resume point in the session file, so it survives an exit,
--continue and /session resume. CadetCoder stops every job when it exits,
and timers live only in memory. A run resumed after a restart therefore learns
that its jobs stopped, and CadetCoder sets its timers again. Before it saves
the point, CadetCoder replaces any API key or token it finds in the saved text
with ***redacted***.
| Command | What it does |
|---|---|
resume | Carry on the run you last interrupted. |
resume show | Say what resume would carry on, and start nothing. |
resume discard | Forget the resume point. |
There is one resume point per session. A second interrupted run replaces it.
A resumed run that ends by itself clears it, whether its work succeeded or
failed. A resumed run that cannot reach the model saves a new point with its
new work. A resume that cannot start keeps the point: for example, when other
workers still run. CadetCoder resumes a run only in the project it worked in.
The model cannot run resume.
Read the output
A line the console prints carries a one-column marker when the line says something about how the run is going. An ordinary notice carries none: "this is information" was true of most of what the program printed, so the glyph in front of it marked nothing out.
| Marker | Meaning |
|---|---|
✓ | something completed |
⚠ | something to be aware of; the run continues |
✗ | something failed; this goes to stderr |
▎ | a heading |
▸ | a sub-heading; in the interactive shell it opens a nested, separately scrollable section |
• | the start of a new iteration of an agent run |
ℹ | a message that contains a Markdown code fence; see below |
CadetCoder indents a marked message that runs to several lines, so its continuation lines sit under the first line's text rather than in column 0. A notice has no marker to sit under, so every line of it starts in the same column.
A message that contains a Markdown code fence is the exception on both counts:
every line of it carries the ℹ marker, notice or not, so a fence inside a
message cannot be mistaken for one that opens a code block and swallow
everything printed after it.
Some terminals cannot render those glyphs. CadetCoder inspects the encoding and
the LANG and LC_* variables at startup. On such a terminal the markers fall
back to the bracketed words [OK], [WARN], [ERR], [i], [*],
=== heading === and -- sub-heading --. The shell's line classifier
understands both vocabularies, so output captured on one machine still colours
correctly when rendered on another.
In the interactive shell a line's colour comes from its marker, because the shell strips the escape codes and colours what it classifies. An unmarked notice is therefore drawn in the ordinary text colour there. On a plain console it keeps the theme's colour, which travels in the escape codes.
Colour comes from the active theme, which cadet theme list reports.
--no-color disables it.
Command output
By default the console shows what the AI ran and in what order, rather than the raw output of every command.
▸ bash echo one
  sanity check before the build
✓ [1] ok  (3 lines)
The first line is what is about to run. The second is the model's own stated reason to run it. The third is the record of what happened, which carries the position in the sequence, whether it worked, and how much output there was.
An agentic turn runs many commands, and one read of a large file or one
grep with many hits buries the reasoning and the result.
In the interactive shell the output is kept rather than cut. Click the result,
or focus it with Tab, to read all of it. Press Esc to go back to the run.
Four things go behind that click: the command's output, the Iteration <n>
line, the request's own cost-and-speed line, and the record of a step that
worked. What stays is what the run is doing, one or two lines per command. A
step that FAILED keeps its record on screen, because that is the column to scan
down to find where a run went wrong.
On a plain command line there is nothing to click, so the head of the output stays on screen with a note that says how many lines follow it. A step's own diagnostics lead its output, and a failure explained by a number is no explanation.
The shell renders the model's answers as Markdown. It shows what a program
printed exactly as printed, so a git diff keeps its - and + lines and a
shell comment does not become a heading.
This is a console setting. A hidden output never changes what the model receives. CadetCoder still feeds the captured text into the next prompt, and still writes it to the debug and session logs.
Show everything with either form:
cadet config ui.showCommandOutput true    # persistent
cadet -Dcadet.showCommandOutput=true …    # one run
What the model receives
A separate backstop bounds how much of a command's output goes into a prompt:
100,000 characters, roughly 25,000 tokens. It sits deliberately above every
limit the commands enforce for themselves, so those remain the limits that
normally apply, expressed in terms the command understands. Those are read's
line limit, multiread's 20,000-line total, and bash's 30,000-character cap.
The backstop exists for output that is pathological rather than merely large.
When the backstop fires, the note says how many characters it dropped and that a re-run of the same command will not return more. A bare "output truncated" leaves a model no option but to try the same thing again.
cadet -Dcadet.maxCommandOutputChars=250000 …   # raise it
cadet -Dcadet.maxCommandOutputChars=0 …        # remove it
How commands are dispatched
Commands start with /; everything else is a message for the AI
About twenty command names are also ordinary English words, among them read,
write, edit, explain, commit, push, undo, help, find and run.
A decision between command and conversation made from the first word alone
therefore executes plain sentences as tool calls. write a test for Foo would
create a file named a, and commit the changes would make a real git commit.
A leading / means "this is a command", and nothing else does.
/read pom.xml            run the read command
read pom.xml and explain what it does    a message for the AI
//starts with a slash    '//' escapes, for a message that begins with a slash
- In the interactive shell that is the whole rule. Plain text always goes to
the AI. The first time you type a message whose first word is also a command
name, the shell says so and points at the
/form. It says so once for each command name in a session. - On the command line,
cadet read pom.xmlstill dispatchesread. Your shell already tokenized argv and you typed the command name deliberately, so the documented CLI contract does not change.cadet /read pom.xmlworks too, and is the unambiguous spelling. - An explicit
/namenever falls back to chat. A mistyped/raedreportsUnknown command: raed, suggests/read, and exits 1, rather than spend an LLM request silently.
One dispatch path
Every command goes the same way, from the command line, from the shell and from a script.
argv -> picocli (global options only) -> CommandRegistry -> Command.execute(String[])
                                                         -> no match -> chat
- picocli parses the global options and nothing else. No command is
registered as a subcommand of
Main, so CadetCoder never matches a command name out of the middle of a sentence.cadet please lsreaches the model, andcadet help undoreaches the help command. CommandRegistrydiscovers everyCommandRegistry.Commandimplementation incom.eonmux.cadetcoder.commandsby reflection, and callsexecute(String[])directly. Each command parses its own options, socadet /grep -i Xreachesgrepwith its flag intact.- The interactive shell (
cadet -i) and script mode (cadet -s file) dispatch through the same registry. A command behaves the same wherever it runs. In a script every line is a command, with or without the leading/. A line that starts with#is a comment. - The registry answers
--helpor-has the first argument, with the same text thatcadet help <command>prints, and does not run the command. One place answers it, sochat --helpdoes not send two words to the model and bill the call,websearch --helpdoes not search the web for them, andbash --helpdoes not offer to run--helpas a shell command. Only the first argument counts.runs show --helpstill asks for a run by that name, and CadetCoder answers that there is none.
Quoting matters on the command line, where your shell tokenizes for you.
cadet ls .        # LSCommand
cadet /ls .       # the same, spelled unambiguously
cadet "/ls ."     # the same again: the line is tokenized as the shell prompt does
cadet "ls ."      # a message for the AI, because it has no leading slash
Without the slash, nothing separates a command from a sentence that opens with a command word. A guess would turn "read the design doc and summarise it" into a read of a file called "the".
CadetCoder tokenizes the line itself inside the interactive shell and in script files. Quoted arguments survive as one argument.
/write notes.txt "hello world"   -> two arguments; the file contains: hello world
/grep "class Foo" --path=src     -> the pattern is one argument
Write every option as --flag=value or as --flag value.
Exit codes
| Code | Meaning |
|---|---|
0 | the command did what it was asked |
1 | the command could not do what it was asked |
69 | the command needed the model and could not reach it |
130 | somebody stopped the command before it could finish |
130 is what a shell reports for a process killed by SIGINT, which is 128 + 2.
It is the answer for every way a run stops part-way: F2 in the interactive
shell, Ctrl-C, a refused confirmation, a harness run called off, and
workers stop. It is deliberately neither 0 nor 1. A run that
somebody stopped neither finished the task nor found it impossible, and a
script that cannot tell those apart will build on work that was never done.
69 means that no request reached the model, so nothing was attempted. The
fix is to wait or to repair the credentials. loop uses it to stop instead of
running its remaining passes against a provider it cannot reach. It is
EX_UNAVAILABLE from sysexits.
cadet agent -y "refactor the parser"
case $? in
  0)   echo "done" ;;
  130) echo "you stopped it; nothing downstream should run" ;;
  *)   echo "it failed" ;;
esac
Command reference
This reference follows each command's usage text in the source. The CLI
column says what cadet <command> does. OK means the command works from the
CLI. AI means it works but needs a configured provider. Every command
dispatches the same way from the command line, the interactive shell and a
script. A few, such as clear and quit, only have an effect inside the
interactive shell.
Files
| Command | CLI | Notes |
|---|---|---|
read <file> [-o <line>] [-l <n>] | OK | Prints with line numbers. The -o offset is 1-based. Resolves partial paths. Takes one file; it names multiread if you pass more. |
multiread <file...> [-l <n>] [-o <line>] [--max-files <n>] [--max-total-lines <n>] | OK | Reads several files in one call. Paths may be globs. Each file goes through read, so the same security rules apply. A file that cannot be read is reported in place and the rest are still read. Exits 0 if at least one file was read. |
write <file> [content...] [-f] [-i] | OK | Confirms before an overwrite unless -f. -i reads the content interactively. |
edit <request...> | AI | AI-assisted edit. The request names the file. Returns SEARCH/REPLACE blocks. |
multiedit <file> <edits...> [-r] | AI | Several edits to one file, applied atomically. |
ls [path] [-a] [-l] [-R] [-r] [-S] [-t] [-d] [-i <glob>] [--max-depth <n>] | OK | cadet ls alone lists the working directory. |
stat <path...> | OK | Kind, size, line count, permissions and last modification, without reading the file out. Every path is reported; the exit code is non-zero if any was missing. |
diff <fileA> <fileB> [-U <n>] [--stat] | OK | Unified diff, the same format git diff prints and patch reads. -U sets the surrounding context, default 3. --stat reports only how many lines changed. A difference exits 0; a file that cannot be read exits 1. |
patch <diff> [-n] [-f|--file <path>] | OK | Applies a unified diff to the files it names. The diff is one argument, or -f reads it from a path. Adds, edits and removes files: a /dev/null on either side of the header, which is what git diff writes for a new or deleted file, is read as a creation or a deletion. Every file is worked out before any is changed, so a patch that does not fit changes nothing. A patch that adds a file will not replace one that is already there. -n reports what it would do. |
notebookread <notebook> [-c <cellId>] | OK | Reads .ipynb cells and outputs. |
notebookedit <notebook> <cellId> [source...] [-m <replace|insert|delete>] [-t <code|markdown>] [-i] | OK | Edits one notebook cell. |
Search
| Command | CLI | Notes |
|---|---|---|
grep <pattern> [-p <path>] [--include <glob>] [-e <glob>] [-i] [--no-line-number] [-w] [-x] [-v] [-c] [-l] [-A <n>] [-B <n>] [-C <n>] [--column] [--max-depth <n>] | OK | Regex search, recursive by default; there is no --recursive. --include and -e match relative to -p; use **/ for nested files. Line numbers are on by default: --no-line-number omits them, and -n changes nothing. -A, -B and -C add surrounding lines, numbered with a dash rather than a colon, with -- between groups. --column adds where in the line the first match starts. |
glob <pattern> [-p <path>] [-l <n>] [-d] [-f] [-r] [-s name|time|size] [--max-depth <n>] | OK | The default sort is time, oldest first. --max-depth 0 means the start directory alone. |
search <query> | OK | Lucene-backed code search. Takes plain words, not query syntax: punctuation is searched for, not obeyed. Prints the lines that matched, with their numbers. Brings the index up to date first, once per run. |
index [path] | OK | Builds or refreshes the search index and reports how many files it wrote. Discards and rebuilds an index written by an incompatible Lucene rather than fail. |
AI
| Command | CLI | Notes |
|---|---|---|
chat <request...> | AI | Agentic loop. The default when the first word is not a known command. |
agent <task...> [-m <steps>] [-t <seconds>] [-c <check>] [-v] [-y] [--classic] | AI | Runs under the agent harness and leaves a record under .cadet/runs/. -c names the command that decides when the task is done. Exits 0 only for a run that finished. |
workers <task...> [-b <briefing>] [-m <steps>], workers start|status|wait|stop|list|show <n> | AI | Runs several agents at once over one shared briefing, three concurrently by default and eight at most. Only one run exists at a time. See Workers. |
runs [show|ledger] [<name>] [<n>] | OK | Reads what past runs recorded. Read-only: a record is written once and never revised. |
loop [--times=<n>] <goal> | AI | Runs the goal as a full run, 100 times by default and at most 1,000. Each pass sees the tail of what the last pass said. Every pass runs, whatever the model says about the goal. Ctrl-C ends it. A provider that cannot be reached stops it with exit code 69. |
loopfresh [--times=<n>] <goal> | AI | The same as loop, except that each pass is told nothing about what the last one said. |
resume [show|discard] | AI | Carries on the chat, agent, loop or workers run you last interrupted. See Resume an interrupted run. |
plan [description...] [-e] | OK | Enters plan mode. done, exit or a blank line finishes it, as does -e. CadetCoder records the plan into the session and asks whether to run it. |
refactor <file> [instructions...] | AI | AI-assisted refactor of one file. |
analyze <file> | AI | Reports what the file does and where its problems are. |
explain <file> | AI | Explains the file in prose. |
suggest <type> [file] | AI | <type> is improvements, tests, refactoring, documentation or performance. |
Git
| Command | CLI | Notes |
|---|---|---|
commit <message...> [-a] [-n] | OK | -a stages all changes. -n skips the pre-commit lint. |
push [-b <branch>] [-f] [-u] | OK | -b pushes that branch instead of the current one. -u records it as the upstream, after a successful push. -f overwrites the remote's history. It says what that discards and asks you to confirm, every time and whoever asked for it. With nobody to ask, as in a script or a worker, it is refused. |
undo [-c] [-e] [-f] | OK | -c resets the last commit. -e discards uncommitted changes, and is the default when neither flag is given. -f skips confirmation, and is required without a terminal. |
Tasks, web and shell
| Command | CLI | Notes |
|---|---|---|
todoread | OK | Prints the current todo list. |
todowrite <add|update|remove|clear> [text...] [-i <id>] [-p high|medium|low] [-s pending|in_progress|completed] | OK | todowrite "<text>" with no verb adds that item. |
timer <create --every <interval> <what to check> [--limit <n>] | list | cancel <id>|all | wait [<seconds>]> | OK | A repeating check-in that fires into a later step of the same run. See Timers. |
bash <command...> [-f] [-t <ms>] [-d <desc>] | OK | One command only. Rejects pipes, redirects, ;, &, $(...) and backticks. Confirms unless -f. The timeout caps at 600000 ms. |
job <start <command> [-d <desc>] | list | output <id> [--all] [-n <lines>] | stop <id>|all | wait [<id>...] [--all] [-t <seconds>]> | OK | Runs a command without waiting for it. Screened exactly as bash is. At most eight run at once. See Background jobs. |
webfetch <url> [prompt...] [-f] [-t <seconds>] | AI | Fetches a URL and answers the prompt about it. |
websearch <query...> [-n <num>] [-a <domain>] [-b <domain>] | AI | -a allows a domain, -b blocks one. |
execute <scriptFile> | OK | Runs one command per line. Skips # comments and blank lines. |
shell | OK | Starts the interactive shell. Needs a real terminal, and says so when it has none. cadet -i does the same. |
clear | OK | Clears the interactive shell's console, as Ctrl+L does. The session log keeps what was cleared. A model may not run it. |
quit | OK | Meaningful inside the interactive shell alone. A model that emits it ends its own run rather than the session. |
Configuration and providers
| Command | CLI | Notes |
|---|---|---|
models [providers | <providerId> | find <text> | current | use <provider> [model] [--context=<tokens>] | select | context [<tokens>|clear]] | OK | context shows, sets or clears the input window of the active model. See Set up a provider. |
login [<provider> | status | logout <provider>] | OK | Key entry needs a real TTY. See Set up a provider. |
copilot [login | status | logout] | OK | OAuth device flow for GitHub Copilot. logout removes the stored token from this machine, which is the same act as login logout github-copilot. |
context [show|create|reload|clear] [-v] | OK | Manages CADET.md, the project-context file. |
compact [status | on | off | trigger <0-1> | target <0-1> | keep-head <n> | keep-tail <n>] | OK | Controls when a long run folds its own history to keep fitting the context window. |
theme <list|set|preview|current|validate|reset> [name] [-s] [-v] | OK | -s persists the choice. reset returns to the default theme. |
session [status | list [count] | new | resume <id>] | OK | CadetCoder keeps the session being left, so resume can reopen it. A model cannot start or switch sessions. |
config [<name> [<value>]] | OK | No arguments prints the config with secrets redacted. One argument prints that setting. Two arguments change it and save it. Names are <section>.<property>. |
ubermode [on | off | status] | OK | Keeps a run going until the task is actually finished. No argument flips it. See Uber mode. |
prompt [list|show|edit|reset|reload] [name] [-c <content> | -f <file>] | OK | No argument lists the prompt templates. |
help [command] | OK | help <name> prints one command's options. |
Global options
This is cadet --help on the built jar.
Usage: cadet [-chiV] [--debug] [--no-color] [--no-git] [--read-only]
             [--verbose] [--ai-endpoint=<aiEndpoint>]
             [--ai-temp=<aiTemperature>] [--base-dir=<baseDir>]
             [--chat-template=<chatTemplate>] [--config=<configPath>]
             [--context-tokens=<contextTokens>] [--model=<aiModel>]
             [--provider=<provider>] [--provider-key=<providerKey>]
             [-r=<resumeSessionId>] [-s=<scriptFile>] [<commandArgs>...]
AI-assisted coding tool
      [<commandArgs>...]     Command and arguments to execute
      --ai-endpoint=<aiEndpoint>
                             AI API endpoint URL
      --ai-temp=<aiTemperature>
                             Temperature for sampling
      --base-dir=<baseDir>   Base directory for storing global files
  -c, --continue             Continue the most recent session
      --chat-template=<chatTemplate>
                             Chat template to use (e.g., plain, chatml, alpaca,
                               llama2, llama3, openchat, deepseek)
      --config=<configPath>  Configuration file to read and write (default ~/.
                               cadet/config.json)
      --context-tokens=<contextTokens>
                             Input context window in tokens (default: the
                               model's published limit)
      --debug                Enable debug logging to file
  -h, --help                 Show this help message and exit.
  -i, --interactive          Start in interactive shell mode
      --model, --ai-model=<aiModel>
                             Model name to use
      --no-color             Disable colored output
      --no-git               Disable Git integration
      --provider=<provider>  AI provider/connector id (e.g. anthropic, openai,
                               openrouter, google, xai, amazon-bedrock, azure,
                               github-copilot, groq, deepseek)
      --provider-key=<providerKey>
                             API key for the selected --provider. Visible to
                               anyone who can list processes and kept in shell
                               history; prefer the provider's environment
                               variable, or 'login', which reads the key
                               without echoing it
  -r, --resume=<resumeSessionId>
                             Resume a specific session by ID (see '/session
                               list')
      --read-only            Enable read-only mode
  -s, --script=<scriptFile>  Run commands from script file
  -V, --version              Print version information and exit.
      --verbose              Enable verbose output
Select every provider the same way, OpenRouter included.
cadet --provider openrouter --provider-key <key> --model anthropic/claude-3-opus
Point a connector at a different host with its baseURL provider option.
--base-dir expands a leading ~.
Configuration
Everything lives under ~/.cadet/, rather than under ~/.config/cadet/.
~/.cadet/
├── config.json           # main configuration
├── session.json          # current session
├── sessions/             # saved sessions and per-session logs
├── logs/                 # cadet.log, history.log, debug/
├── indexes/              # Lucene index
├── models/               # local model storage
├── cache/models.json     # cached models.dev catalog
├── prompts/              # user prompt template overrides (*.json)
└── copilot-auth.json     # GitHub Copilot token, if you logged in
Override the location with --base-dir <path>. That moves everything in the
tree except config.json itself. CadetCoder has to find config.json before
it can read any setting inside it, so name that one file with
--config <path>. The baseDir in it then decides where the rest goes. A
second profile is therefore one file plus the directory it points at.
cadet --config ~/work/cadet.json config baseDir ~/work/cadet   # once
cadet --config ~/work/cadet.json agent "..."                   # thereafter
logs/history.log holds the interactive shell's command history, which is the
list that Up, Down and F3 walk back through. CadetCoder appends a line
the moment you enter it, so a session that ends in a crash or a closed terminal
still leaves its commands behind. Two shells open at once both add to the file,
and neither replaces the other's work. The file keeps the most recent 1000
lines.
This is config.json as written on first run. The sections appear in this
order. baseDir is written as an absolute path.
{
  "ai": {
    "localEndpoint": "http://localhost:8012",
    "localModel": "llama3-8b-q4",
    "temperature": 0.7,
    "maxTokens": 0,
    "contextTokens": 0,
    "modelContextTokens": {},
    "apiKey": "",
    "apiEndpoint": "https://api.openai.com/v1",
    "model": "o1-mini",
    "escalateTo": "",
    "completionTimeoutSeconds": 300,
    "chatTemplate": "chatml",
    "provider": "",
    "providerApiKeys": {},
    "providerOptions": {},
    "zeroDataRetention": true,
    "uberMode": false
  },
  "context":   { "maxFiles": 10, "maxLinesPerFile": 500, "priorityFiles": [] },
  "indexing":  { "enabled": true, "indexLocation": ".cadet/index",
                 "excludePatterns": ["bin", "build", "dist", "node_modules", "obj", "out", "target"],
                 "refreshIntervalMinutes": 60 },
  "git":       { "enabled": true,
                 "includeBranches": false, "includeCommitHistory": false, "maxCommitHistory": 10,
                 "autoCommitEnabled": false,
                 "commitMessageTemplate": "Auto-commit on {date}", "commitTrigger": "onChange",
                 "autoCommitIntervalMinutes": 60 },
  "ui":        { "colorEnabled": true, "colorTheme": "modern", "verbosityLevel": 1,
                 "interactivePrompts": true, "showCommandOutput": false },
  "performance": { "threads": 3, "parallelProcessing": true },
  "security":  { "allowRemoteExecution": false, "allowedCommands": [], "allowedActions": [],
                 "sandboxMode": false, "readOnlyMode": false, "requireConfirmation": true,
                 "allowOutsideProject": false, "commandApproval": "manual",
                 "maxFileContentSize": 10 },
  "logging":   { "level": "INFO", "logFile": "logs/cadet.log", "consoleLoggingEnabled": true,
                 "maxLogFiles": 5, "maxLogSize": 10, "debugEnabled": false,
                 "sessionLoggingEnabled": true, "structuredLogging": true,
                 "maxSessionLogSize": 50, "maxSessionLogs": 20 },
  "compaction": { "enabled": true, "trigger": 0.8, "target": 0.45,
                  "keepHeadEntries": 6, "keepTailEntries": 9 },
  "baseDir": "/home/you/.cadet"
}
ai.modelContextTokens holds the input windows that models context sets,
one per provider and model.
Note three shipped defaults. ui.colorTheme is modern.
security.allowOutsideProject is false, so file commands work only inside
the directory you start CadetCoder in. security.commandApproval is manual,
so you approve each shell command yourself.
config works from the command line and from the shell, and you can edit
~/.cadet/config.json directly. A path setting that begins with ~ means your
home directory whichever of those three routes it arrives by. Your shell
expands it for you on a command line, and nothing expands it inside cadet -i
or in a file you edit yourself.
Context
context.maxFilesbounds how many whole project files one prompt may carry.context.maxLinesPerFilebounds how much of any one of them. CadetCoder cuts a longer file at a line boundary, with a note that says how many more lines there were.context.priorityFilesnames project files that go in front of the model every time, ahead of whatever the index search returned. An index search matches on what is inside a file, so no search over the sentence the user typed returns a document that the project has decided always matters, such as its coding conventions or its architecture notes. Paths are relative to the project and count againstmaxFiles.
Indexing
indexing.enabledsays whether CadetCoder indexes the project at all. With it off,searchand the context the model is given fall back to whatever is already in the index.indexing.indexLocationsays where the index lives. Two CadetCoder processes cannot share one. CadetCoder tells the second process so and stops, rather than delete the first one's index.indexing.excludePatternsnames directories to skip. CadetCoder matches each entry as a regular expression against a directory name, and as a literal if it is not valid regex. Despite the section it lives in, this governs every walk over the project: the index,grep,ls,glob, and the file search thatread,write,editand the agent do. CadetCoder also skips hidden directories, by the leading dot rather than by a listed name.indexing.refreshIntervalMinutessays how long the index stays fresh inside one run. A one-shot command indexes once and exits, so this setting matters tocadet -i. A shell left open all day would otherwise index the project when it opened and never again, and nothing written afterwards would be searchable for the rest of the session. That covers writes by your editor and by this tool's ownwriteandedit. Set0to keep the old behaviour deliberately: index once, then leave the project alone.
Repository context
Both settings are off by default, because every line of repository context is prompt that the code you asked about does not get.
git.includeBranchestells the model which branch the work is on, and what other branches exist. A branch name is often the clearest statement of what a task is for.git.includeCommitHistorytells the model the recent commits on that branch, newest first, so it does not propose work that was done three commits ago.git.maxCommitHistorybounds how many of them.
Worker settings
performance.threadssets how many workersworkersruns at once, between 1 and 8. The provider's rate limit sets the ceiling rather than the machine. Every worker is a full agent loop against one account, one rate limit and one shared retry budget, so past a point they do not queue and instead fail each other.performance.parallelProcessingruns workers one at a time when set tofalse.
Security controls
These are the settings the code actually consults.
security.readOnlyMode, also--read-only, blocks writes.security.sandboxModerestrictsbashto a command whitelist and file access to safe extensions.security.allowOutsideProjectdecides whether file commands may reach paths outside the project root. It isfalseby default. Set it totrueto let them read there. Writes still stay inside the project or the system temporary directory when it istrue.security.allowedCommandsnames the programsbashmay start in sandbox mode. Empty means the shipped list:echo pwd cd ls dir cat type grep find git mvn npm yarn python java javac node. A value replaces that list rather than adds to it. The setting has no effect when sandbox mode is off.security.allowedActionsnames the actions a model may ask for, such asread,writeandbash. These are the tool's own names rather than shell programs. Empty means all of them, which is the default. The list covers bothchatandagent. A refused action costs the agent a step and reports why; it does not end the run.security.requireConfirmationprompts beforebashand before destructive file operations. It decides whether the question is asked at all, andsecurity.commandApprovaldecides who answers it. Neither decides whether an action is allowed.security.commandApprovalnames who answers when a command needs approval.manual, the default, asks the person at the terminal, including during an agent run: the question is drawn on the screen rather than filed into the step's transcript, and the answer comes from the shell's input line.autoasks the model instead, in a separate request that is shown one command and told to allow ordinary development work. When the command is a plain run of a script withpython,node,ruby,perlor a shell, such aspython3 tool.py,bash build.shor./deploy.sh, optionally aftercd /path &&, the request also shows the script, so the model judges what the script does. A script outside the project, a credential file, a file that is not text, and any line of another shape are judged from the line alone. A script over 20,000 characters is cut there. The model answersALLOW: <why>orDENY: <why>, and anything else — a refusal to answer, an error, an unreachable provider — is read as a refusal. Chooseautoonly if you accept that a model approves commands without you. It suits a long run whose commands are routine, and workers need it, because nobody can answer a worker's question. Where nobody can be reached the command is blocked, and the message names this setting. Neither mode can approve what the screens below refuse outright. Set it for one run with-Dcadet.commandApproval=auto.
A model cannot change your saved setup. When a model asks for them, CadetCoder refuses these commands:
loginandcopilot, exceptstatus.config <name> <value>.- The
modelssubcommands that switch the active model or set its window. prompt editandprompt reset, because a saved prompt template is the system prompt of every later session.ubermodeandcompact, exceptstatus.theme set,theme applyandtheme reset.
A model also may not clear the console with clear, start or switch sessions,
or start a nested chat, agent, loop, loopfresh or resume inside its
own run.
A model may still read settings, for example with config <name>,
login status, ubermode status or models context.
These refusals cover CadetCoder's own commands. A model can still ask bash to
run a command that changes the same files, such as cadet config ... or a
copy into ~/.cadet/prompts. With the shipped settings,
security.requireConfirmation is true and security.commandApproval is
manual, so you approve every such command yourself. With auto, the model
approves it.
CadetCoder also ignores a --force from a model. bash then asks for approval
as security.commandApproval says. undo from a model is refused, because
only you can confirm a hard reset.
push --force asks you every time, whether you or a model asked for it. The
model never answers this question, even with auto. With nobody to ask, as in
a script or a worker, the force push is refused. The same applies to a
git push run through bash that can discard commits on the remote: one with
--force, --force-with-lease, --mirror, --delete, --prune, or a
refspec that starts with + or :. bash -f does not skip that question.
Whatever the settings say, bash reads a command line before it runs it. It
takes the line apart the way a shell would, through quotes, pipes, &&, ;,
$(...) and backticks, and screens every program the line would start and
every file it would write. A quoted metacharacter is text, so awk '{print $1}'
and grep -r todo src | wc -l run. A program on the dangerous list, a
protected system path and a named credential file are refused, and the refusal
says which of those it was.
Two things cannot be read from the line: a program named by a variable, such as
$TOOL --version, and the commands inside bash -c "..." that is itself built
by expansion. Those are the cases security.commandApproval settles. login
and config redact secrets from logs and console output.
Context compaction
A long run's prompt is its transcript, rendered in order, so it grows every turn. At 80% of the usable input budget the run folds its own history into three parts: a verbatim head, a marker that says how many steps were omitted, and the most recent steps verbatim.
CadetCoder keeps the head deliberately. A cache matches a leading prefix, so the kept head is what stops a fold from discarding the whole cache. A fold rewrites the prompt's start, which is expensive, so it is threshold-driven and rare rather than eager. The alternative is worse, because an over-length prompt is a terminal 400 that loses the task outright.
CadetCoder drops steps rather than summarises them. A summary costs a request exactly when the run is most valuable, it can fail, and it can succeed while it quietly loses the one fact that mattered. A drop is safe here because the loop guard's memory of what has already been tried lives outside the transcript.
cadet compact status              # thresholds, and the budget they are measured against
cadet compact off                 # or: on
cadet compact trigger 0.9         # fold at 90% of the usable budget
cadet compact target 0.5          # fold back down to 50%
cadet compact keep-head 8         # entries kept verbatim at each end
cadet compact keep-tail 12
There is no compact now. The transcript belongs to a single run and does not
outlive it, so between commands there would be nothing to fold.
Token budgets
maxTokens and contextTokens are two different numbers. maxTokens is how
many tokens the model may generate, and CadetCoder sends it to the provider as
max_tokens. contextTokens is how many tokens the model can accept, and
CadetCoder budgets the prompt against it.
maxTokens is 0 by default, which asks for no ceiling at all. Nobody knows
how long an answer needs to be before it is written, and a number chosen in
advance is only ever wrong in the direction that truncates. The risk grew with
reasoning models, which charge their thinking to the same budget as their
answer, so a model can spend the whole allowance before it writes a word. Set a
number to cap a reply. One API cannot be told "no limit": Anthropic's Messages
API requires max_tokens, so CadetCoder sends that model's published output
limit.
contextTokens set to 0 means CadetCoder takes the active model's published
context length from the models.dev catalog, which is the right number and
differs by orders of magnitude between models. It falls back to a conservative
default for a local or uncatalogued endpoint.
Interactive shell
cadet -i
The shell is a full-screen interface built on TamboUI and JLine. It has four parts:
- A top line. It carries whatever modes are switched on, such as
uberand2 timers, the activeprovider/model, the git branch, and, while a request is in flight, what runs, its elapsed time and what it cost so far. - A scrollback console. It renders Markdown and keeps per-command result sections.
- A status bar, under a divider of its own. It lists the keys available. Where you are in the view -- following, scrolled, focused or selecting -- is drawn in the console's own top-right corner, beside the text it describes.
- A prompt line, under a rule and its own heading, which names the working directory.
Live request state appears in one place only, the top line. Any sub-heading a
command prints with ▸ opens a nested section inside its result, so an AI
run's individual steps are separately scrollable and titled. Tab steps
through workers. CadetCoder collects a worker's output per worker rather than
streams it, so while workers run the transcript says nothing about them, and
Tab is the only way to watch one without an interrupt to the run you wanted
to watch.
Nothing in the transcript is boxed or padded to the terminal width. Each region has a one-row heading and no border. Each result opens with a heading of its own. Code blocks have no gutter down their left edge. A selection therefore copies the text and no frame around it. Only the modal help overlay keeps a full border, and nobody copies that out.
Type / to start a command. The shell predicts the rest of the name as you
type: /com shows mit in dim text, and Right at the end of the line
accepts it. While several commands still match the prefix, the completion adds
only the characters they all share and reports how many remain, so it never
guesses which one you meant. Tab is not used for this, because it moves
between workers. The shell also supports command history, mouse wheel
scrolling, click-drag selection with OSC-52 clipboard copy, and bracketed
paste. Non-UTF-8 terminals get ASCII glyph substitutes.
| Key | Action |
|---|---|
Enter | Send the line. It runs the command, or asks the AI. |
Tab / Shift+Tab | Step through each worker's output, live (focus mode) |
Right | Accept the predicted command name, at end of line |
Up / Down | Command history, or scroll the focused result |
Ctrl+Left / Ctrl+Right | Move the cursor a word at a time. Some terminals send Alt instead of Ctrl; both work, as do Alt+B and Alt+F. |
Ctrl+W | Delete the word behind the cursor |
F1 | Help overlay, holding the same reference /help prints. Arrows, PgUp and PgDn scroll it; any other key closes it. |
F2 / Ctrl+C | Interrupt the running command. /resume carries on an interrupted chat, agent, loop or workers run. |
F3 | Print recent history |
F4 | Select mode: the mouse selects, and a click does not open the result under it |
Ctrl+U | Clear the line being typed |
Ctrl+L | Clear the console |
Page Up / Page Down | Scroll |
Ctrl+Home / Ctrl+End | Jump to top, or follow the bottom |
| Click a result | Focus it. Esc returns to the live view. |
Esc | Back out of whatever is innermost: a prompt, select mode, a selection, a focused result, then the line being typed |
Ctrl+Q or /quit | Exit |
Ctrl+C when idle | Asks. A second press exits. Anything else takes the question back. |
A paste of more than one line, or of more than 200 characters, does not go into
the line as text. It goes in as a short marker naming what it stands for, such
as [#1: 42 lines], and the text itself is sent when you press Enter. The
marker is ordinary text: type before and after it, cross it a word at a time,
delete it like any other word. The console, the history and the saved
transcript keep the line as it was typed, marker and all, because what the
marker stands for is no more readable as a result heading than it was at the
prompt.
A file dropped on the terminal arrives as a paste of its path. It goes in as
its name, [#2: Foo.java], and is sent as the full path, so a command can open
it.
A dropped PNG, JPEG, GIF or WebP is read as well as named. Its marker says so,
[#3: image shot.png], it still stands for the path, and the picture itself is
sent to the model with your question. Delete the marker before you press
Enter and nothing is sent. The picture goes with the first request of the
turn and not with the iterations after it, so a long run pays for it once. A
model that does not read images is sent the question and the path, and a line
on screen says what was left out. Images are limited to 5 MB, which is the
lowest of the providers' limits.
Drag over the console to select text, and release to copy it. A selection is
not limited to the rows on screen: drag to the top or bottom edge and hold
there, and the transcript scrolls under the pointer so the selection keeps
growing. The further past the edge the pointer sits, the faster it moves, up to
a third of the console per tick. The wheel and the paging keys also work
mid-drag, which is the quick way to cover a long stretch: scroll to where the
selection should end, then move the pointer there. F4 is worth pressing
first for a long selection, because it stops a mis-click from opening the
result underneath.
With text selected and nothing running, Ctrl+C copies the selection rather
than does either of those. That follows the terminal convention, and it also
covers terminals that report Ctrl+Shift+C as a bare Ctrl+C.
The banner carries one more line when the run is restricted. It names read-only mode or sandbox mode, each as it applies. With neither on, the line is absent. Files confined to the project directory is the default, so the banner does not name it.
In the shell, plain text is a message for the AI and commands start with /.
See How commands are dispatched. /help prints
the reference the F1 overlay shows: how a typed line is routed, the keys, the
mouse, then every command grouped by what it is for. Both render
HelpContent, so neither can drift from the other. Outside the shell,
cadet help prints the commands alone, since the keys and the mouse belong to
a window that is not open. /help <name> prints one command's full option
list.
The shell dispatches through CommandRegistry, the same single path the
command line uses, so every command behaves the same on both surfaces. It needs
a real terminal. With stdin redirected it emits its terminal setup sequences
and then blocks forever instead of exiting, so never launch it from a script or
a pipe.
Themes and templates
CadetCoder ships 10 themes, all 24-bit truecolor: modern, which is the
default, matrix, default, solarized-dark, solarized-light, monokai,
dracula, nord, gruvbox-dark and one-dark.
cadet theme list
cadet theme preview dracula
cadet theme set nord -s      # -s persists to config.json
cadet theme current
CadetCoder ships 11 chat templates, for local and non-connector models that
need a specific prompt format: plain, chatml, which is the default,
chatml-advanced, alpaca, alpaca-system, llama2, llama3, openchat,
deepseek, tekken and intel-neural.
Select one for a single run with the global flag, or save it in the config.
cadet --chat-template alpaca "explain this code"
cadet config ai.chatTemplate alpaca
Prompt templates customise the system prompt per command. Defaults ship in the
jar for chat, edit, analyze, explain, suggest, refactor, agent,
webfetch, websearch and ubermode. CadetCoder writes example overrides to
~/.cadet/prompts/*.json.example on first run. Drop a <command>.json next to
them to override one, or use the prompt command.
The default system prompt is a further template, named system, and the only
one that applies to every command. It holds the operating principles the agent
works by, and it leads the system prompt of every request. The command's own
prompt follows it, with its command catalog and required action format.
Commands that send no system prompt of their own get the principles alone.
CadetCoder composes that prompt once, where every completion funnels through, so a command cannot omit it and a new command inherits it without any work. The block is constant, so it forms a stable prefix, which is what a provider caches. It costs roughly 900 input tokens on the first request of a conversation and comes from cache afterwards.
Override it like any other template, with ~/.cadet/prompts/system.json.
{ "name": "system", "version": "1.0", "content": "Your principles here." }
Set "content" to an empty string to remove the block. Each command's prompt
then stands alone.
The uber-mode directive is the third kind, named ubermode. CadetCoder appends
it to an agentic command's own prompt, and only while
uber mode is on, so it qualifies the completion contract above it
rather than the reverse. It says what finishing means: every part of the
request, verified with what the project can be checked with, with the
surrounding code still in agreement. Edit ~/.cadet/prompts/ubermode.json to
change how hard a run is pushed.
Limitations
Both items below were reproduced against
target/CadetCoder-1.0-SNAPSHOT.jar.
login cannot accept a key without a TTY
This is by design rather than a defect, but it means login is unusable in CI,
over a pipe, and on the interactive shell's prompt line. Use the provider's
environment variable instead. See
Set up a provider.
Console output wraps to a width it is told
CadetCoder does not measure the terminal width for its own messages. Set
COLUMNS=100, export COLUMNS, or pass -Dcadet.terminalWidth=100. Any of
those breaks the tool's own messages on spaces and indents the continuations
under the text. -Dcadet.terminalWidth=0 turns that off again.
With nobody to say, CadetCoder re-wraps nothing. Output that is piped, redirected or captured has no width, and a break inserted there lands in the middle of what another program reads. A question to the terminal costs about 60 ms of a 315 ms startup on every invocation, which is not worth it for a handful of lines.
CadetCoder never wraps aligned listings, whatever the width. That covers
help <command>, config and models. Their columns carry more meaning than
the overflow costs. The interactive shell measures its own width and always
has.
Build and test
mvn clean package -DskipTests    # jar only
mvn test                         # full suite: 4,838 tests
mvn clean package                # both
Run the suite from a git checkout. GitIntegrationTest resolves a repository
from the working directory, and 9 of its tests error with
RepositoryNotFound in a plain copied directory.
Build with JDK 17, because maven-compiler-plugin targets 17. The jar it
produces runs on 17 or newer. See
A native access warning on JDK 22 and newer.
mvn verify additionally enforces a JaCoCo floor over the whole project: 80%
of lines and 67% of branches. The measured figures are 81.7% of lines and 70.6%
of branches. Raise the floor as coverage improves. Never lower it to make a
build pass.
What remains uncovered concentrates in one class.
commands/InteractiveShell accounts for 649 of the project's roughly 6,400
uncovered lines. What is left in it is the TamboUI event loop and the threads
around a running command. Neither is reachable without a terminal. Everything
that could be lifted out of it was lifted out, and is tested. See the TUI note
in CADET.md.
Project layout
src/main/java/com/eonmux/cadetcoder/
├── Main.java                 # picocli entry point, global flags, session/script/interactive modes
├── CommandRegistry.java      # reflection-based command discovery and dispatch
├── OutputFormatter.java
├── commands/                 # every command implementation, plus InteractiveShell
├── harness/                  # the agent harness `agent` runs under
│   ├── loop/                 # the run loop: transcript, reasoners, escalation, stop
│   ├── tools/                # what the agent may do, and the session that gates it
│   ├── ledger/               # the hash chain of what really happened
│   ├── env/                  # the environment the agent observes and acts on
│   ├── model/                # the theory it holds about the project, and the language it is in
│   ├── belief/, spec/, fit/  # what it thinks, what it predicts, and what fits the evidence
│   ├── plan/, commit/        # search before acting, and the gate on acting
│   ├── budget/, certify/     # what a run may spend, and whether its record stands up
│   └── cadet/                # the bindings to this tool: commands, models, records, the terminal
├── agents/                   # worker pool, registry and results for `workers`
├── ai/
│   ├── AIManager.java, AIClient.java, APIClient.java, LocalAIClient.java, ConnectorAIClient.java
│   ├── providers/            # the 23 connectors and their auth schemes
│   ├── catalog/              # models.dev catalog loading and caching
│   ├── metrics/              # token counts and speeds for each request
│   ├── templates/            # the 11 chat templates
│   └── parsing/              # response and action parsing
├── auth/                     # GitHub Copilot device flow
├── config/                   # Configuration, ConfigManager
├── context/                  # CADET.md project context, and the Lucene search engine
├── git/                      # JGit integration, auto-commit scheduler
├── logging/                  # debug and session logging
├── jobs/                     # background jobs that `job` starts
├── timers/                   # repeating check-ins the model sets itself
├── net/, patch/, security/, session/, shell/, ui/, util/, error/, prompts/
CadetCoder is built on picocli for the CLI, JGit for git, Apache Lucene for the index, Jackson for JSON, JLine and TamboUI for the interactive shell, and Reflections for command discovery.
Three further items sit at the repository root beside the source: LICENSE,
which is Apache 2.0; NOTICE, which records what the shaded jar bundles and
under what terms; and licenses/, which holds the full text of every bundled
licence that is not Apache 2.0. All three are packaged into the jar under
META-INF.
assets/ holds the tour at the top of this page. It is not packaged into the
jar.
Further documentation
CADET.md is the project-context file that CadetCoder reads when
it works on this repository. It also describes the architecture and the
conventions for contributors. Manage it with context show and
context create.
Licence
CadetCoder is licensed under the Apache License, Version 2.0. See
LICENSE.
Copyright 2026 Amir Farhad Eslampanah

Licensed under the Apache License, Version 2.0 (the "License");
you may not use this file except in compliance with the License.
You may obtain a copy of the License at

    http://www.apache.org/licenses/LICENSE-2.0
mvn package produces a shaded jar that bundles its dependencies, so their
licences travel with it. NOTICE names each one. The texts that are
not Apache 2.0 live in licenses/, and inside the jar at
META-INF/licenses. Those are JGit's Eclipse Distribution License, JLine's BSD
3-Clause, and the MIT licences of SLF4J, TamboUI and the bundled models.dev
catalog snapshot. JNA, Reflections and Javassist each offer a choice of
licences. This project takes the Apache License, Version 2.0 for all three, and
NOTICE records that choice, because it belongs to whoever distributes the
jar.
Similar repos
Languages
Java
100.0%