
README
🎙️ VibeVoice: A Frontier Long Conversational Text-to-Speech Model




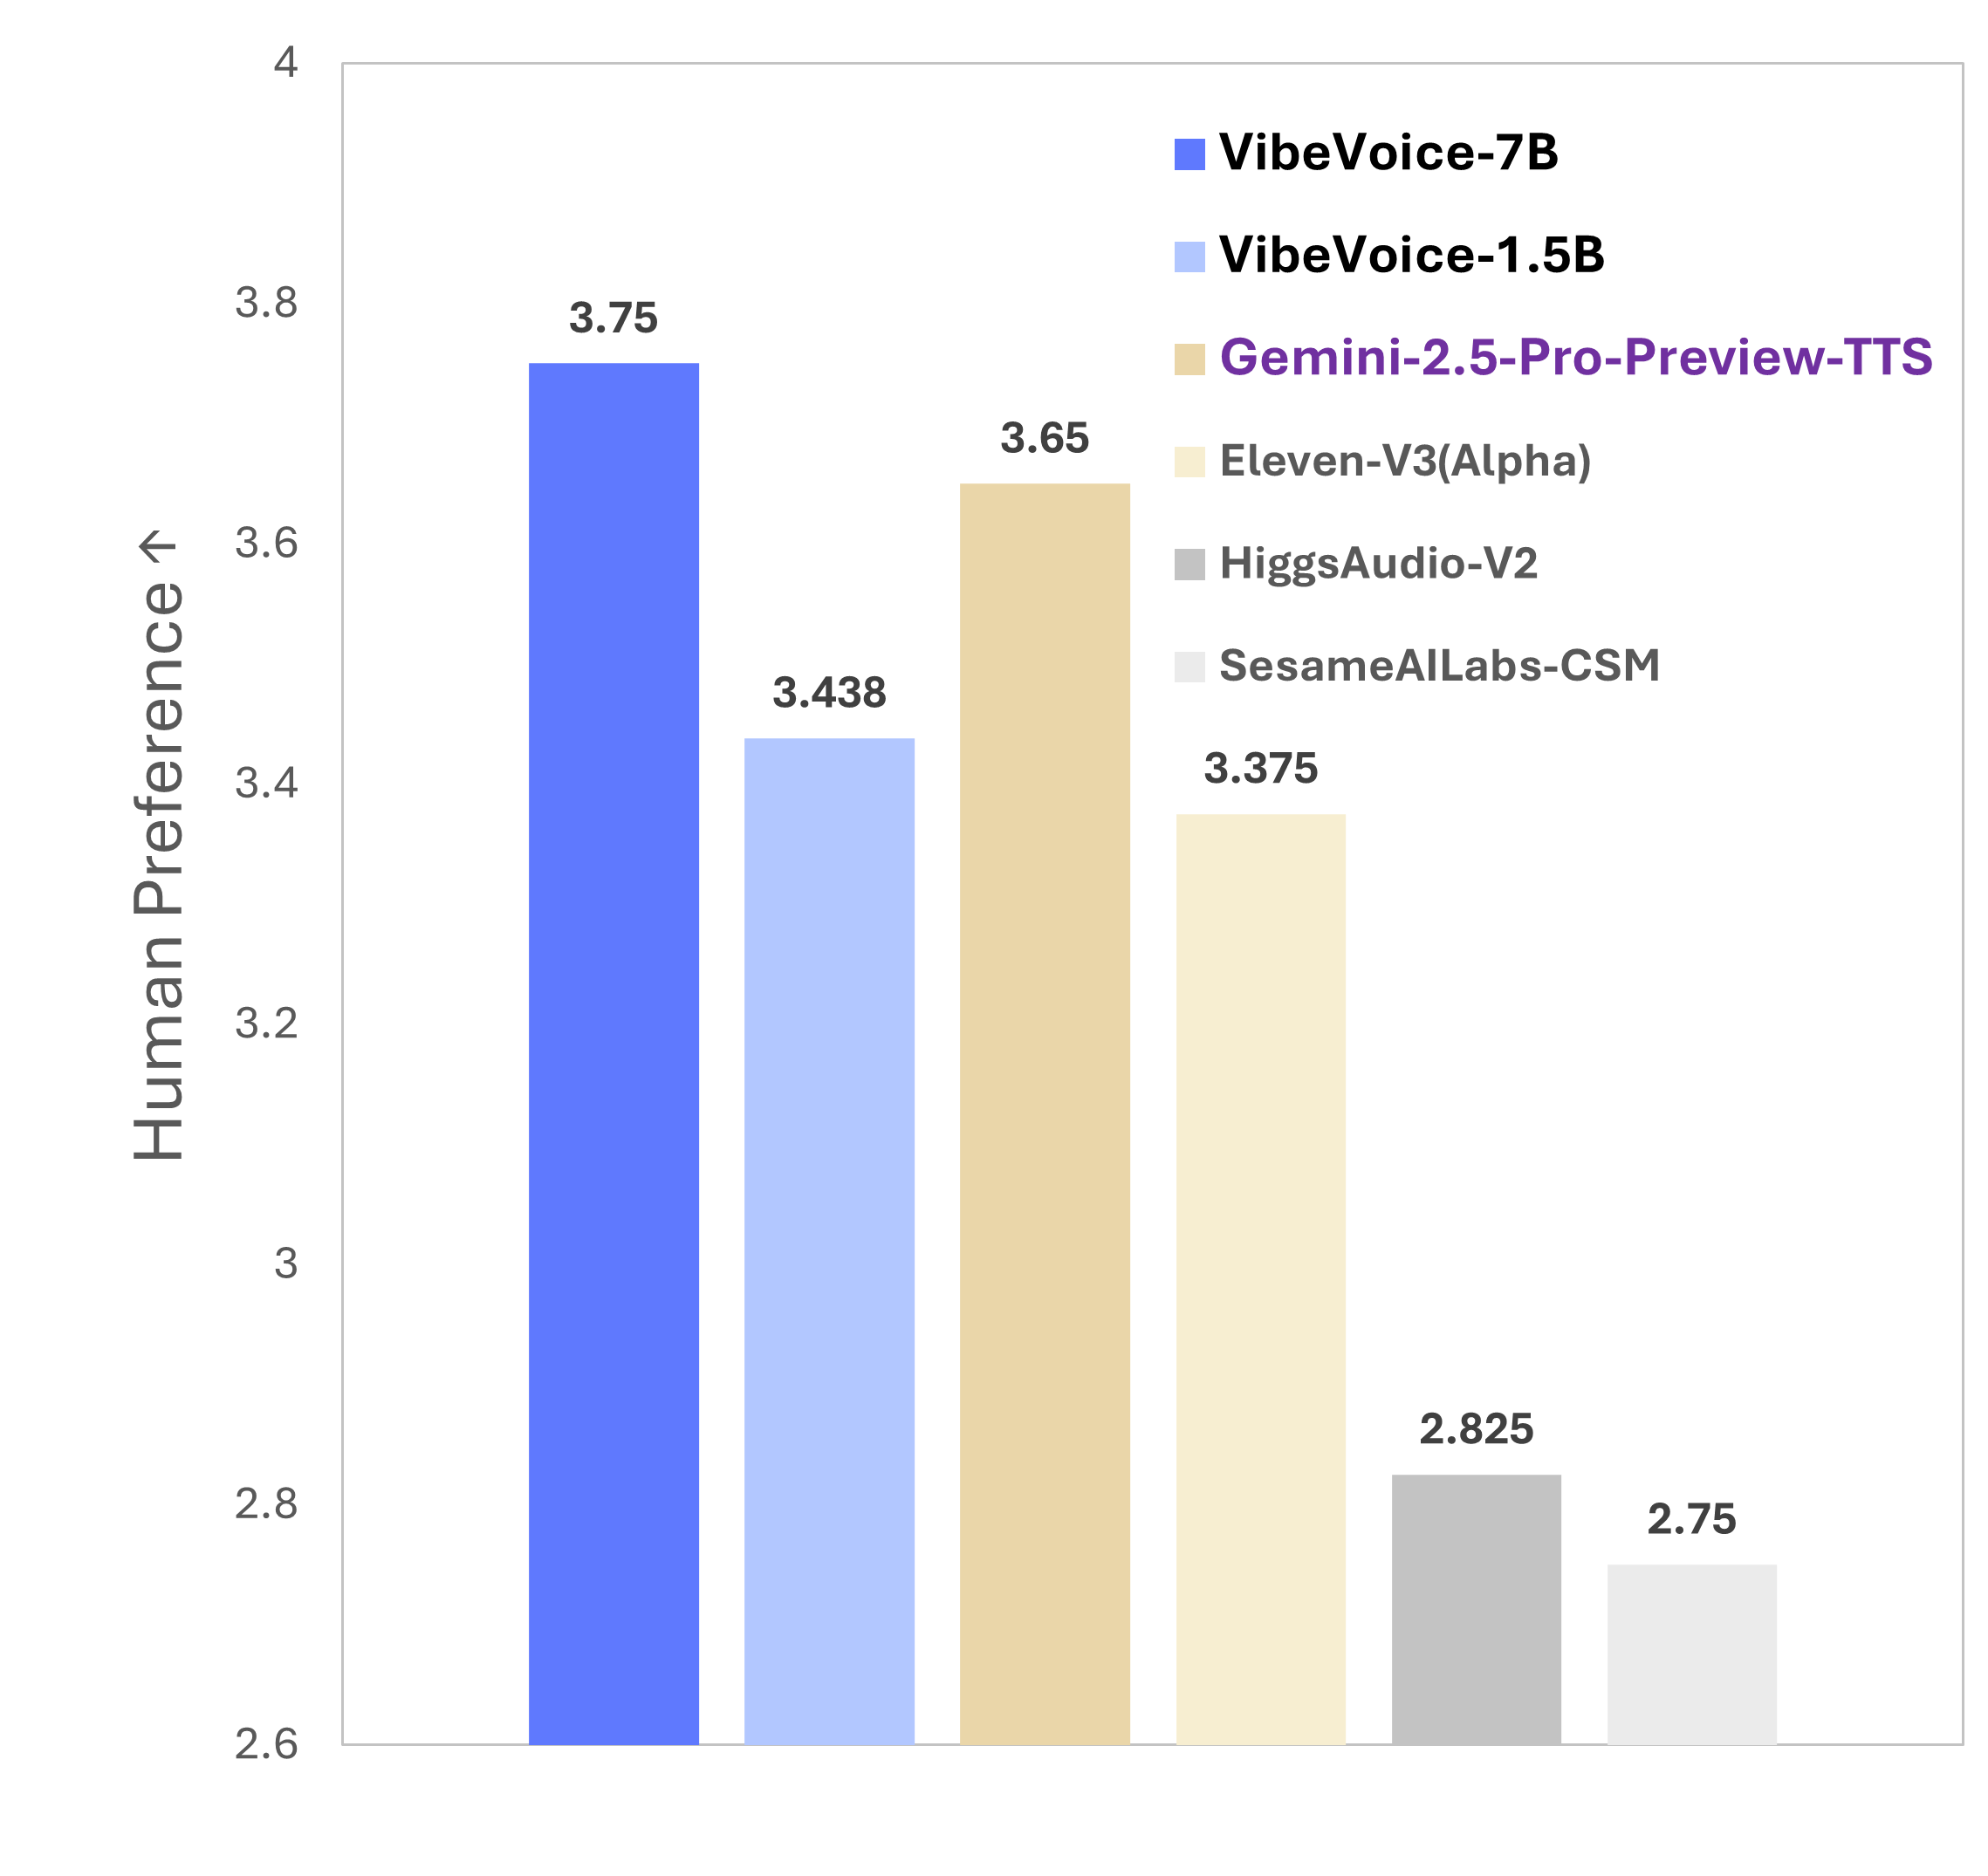
VibeVoice is a novel framework designed for generating expressive, long-form, multi-speaker conversational audio, such as podcasts, from text. It addresses significant challenges in traditional Text-to-Speech (TTS) systems, particularly in scalability, speaker consistency, and natural turn-taking.
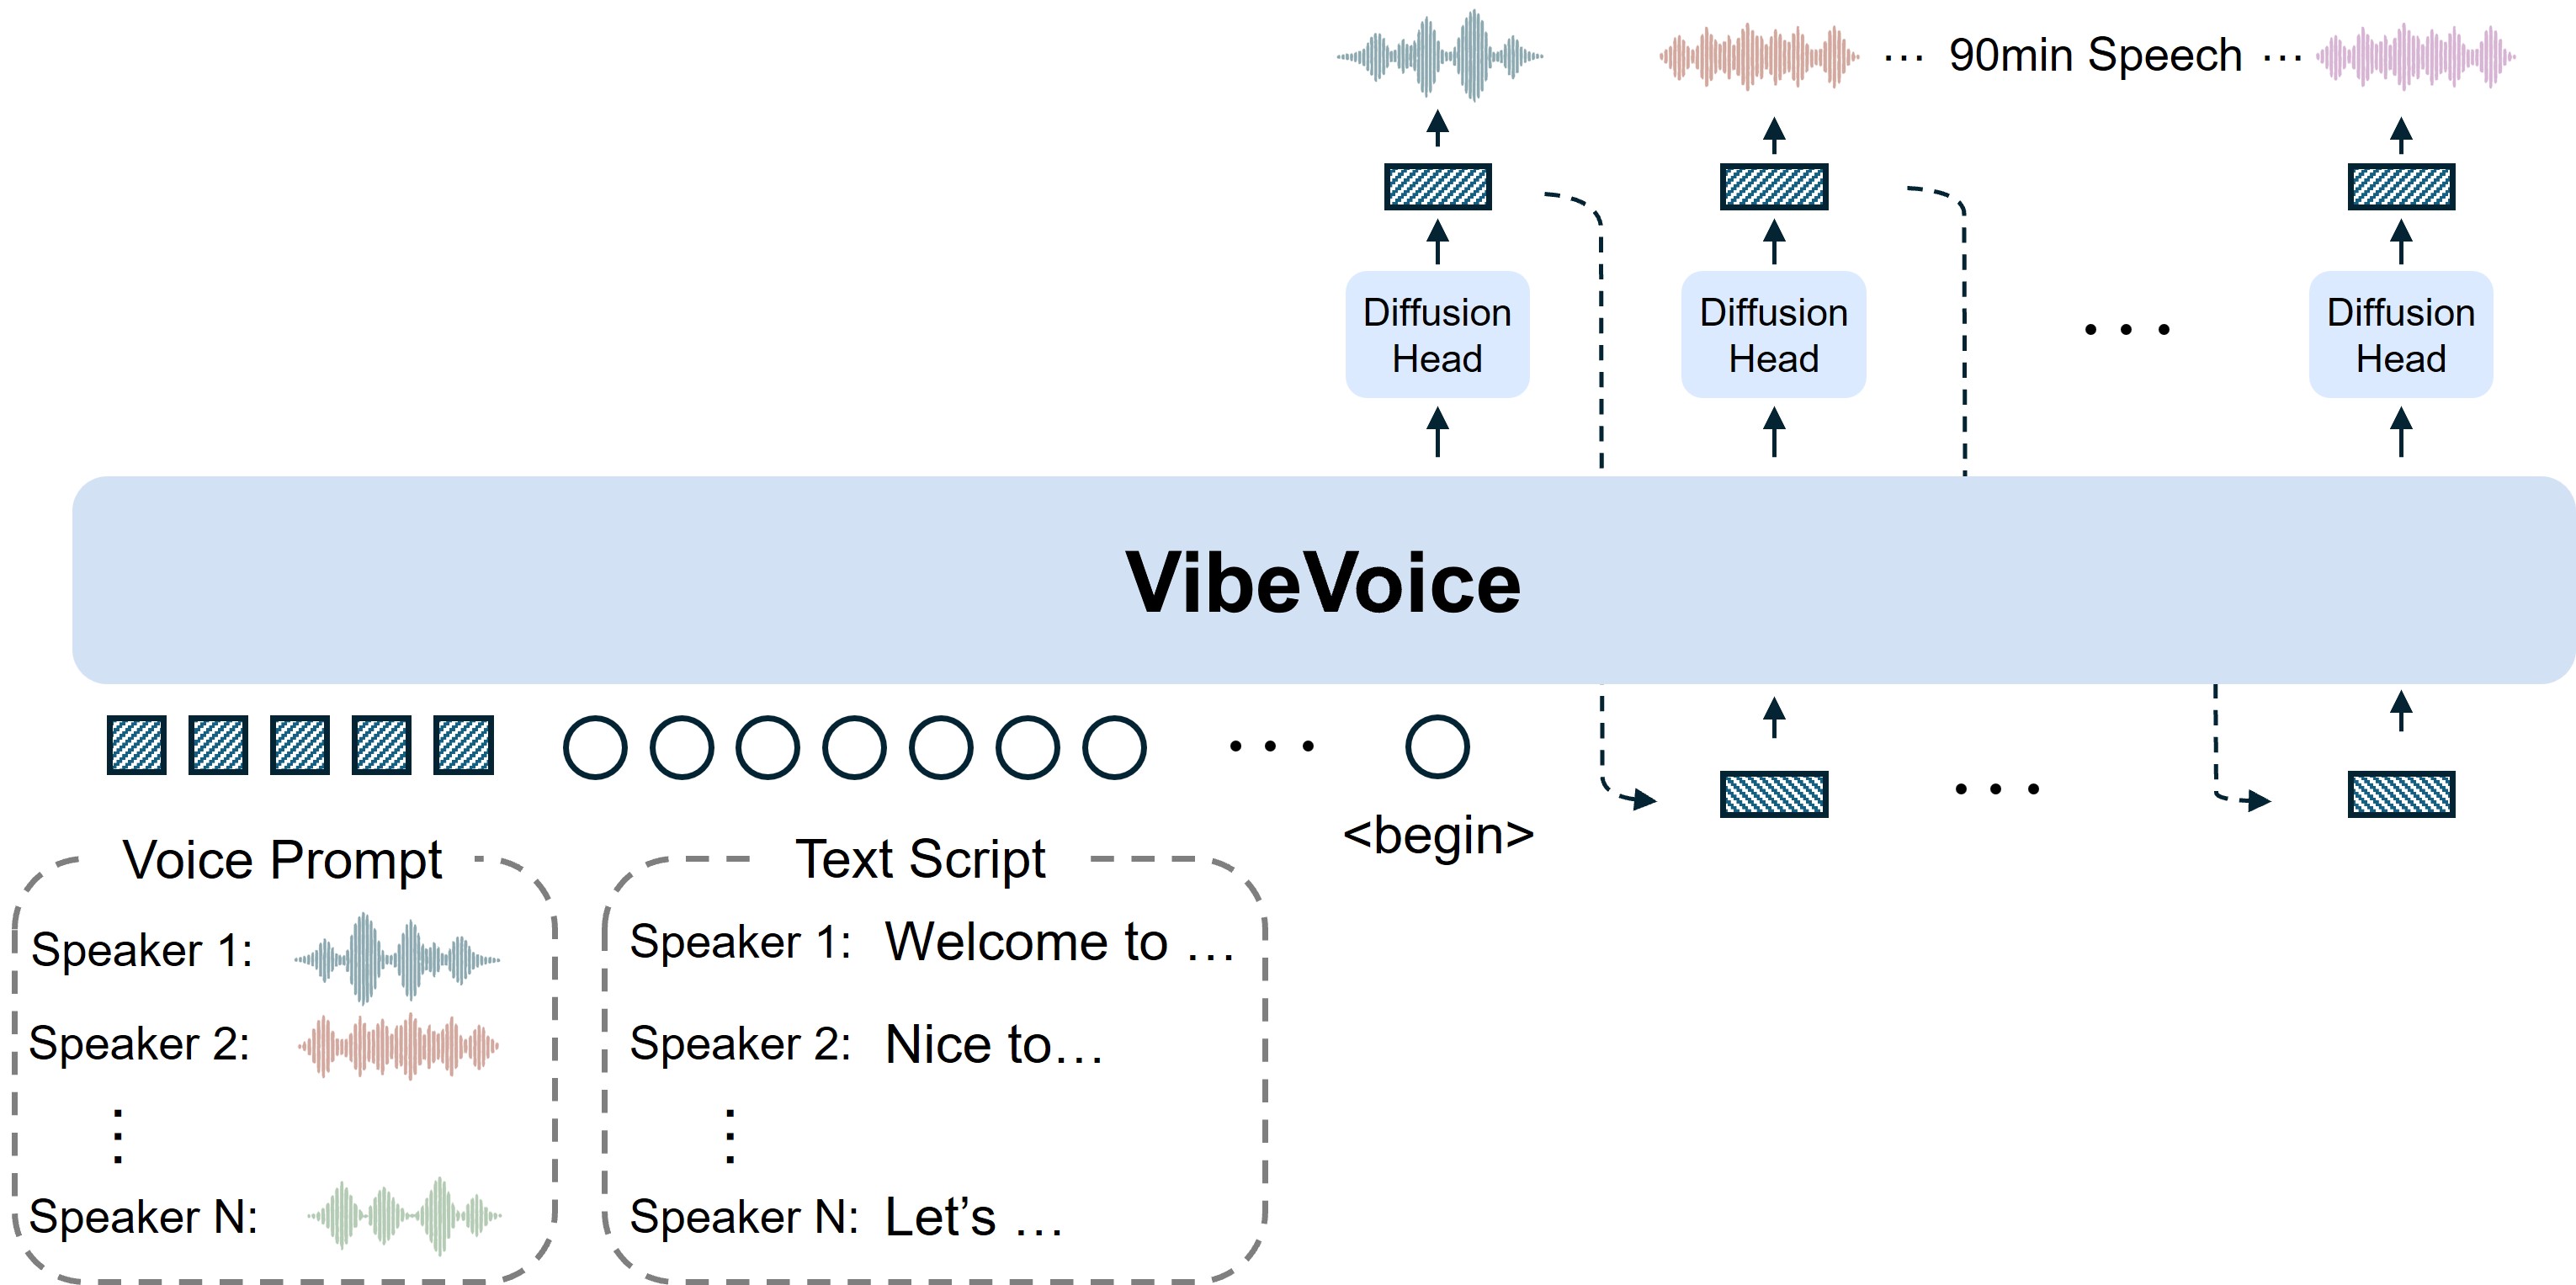
A core innovation of VibeVoice is its use of continuous speech tokenizers (Acoustic and Semantic) operating at an ultra-low frame rate of 7.5 Hz. These tokenizers efficiently preserve audio fidelity while significantly boosting computational efficiency for processing long sequences. VibeVoice employs a next-token diffusion framework, leveraging a Large Language Model (LLM) to understand textual context and dialogue flow, and a diffusion head to generate high-fidelity acoustic details.
The model can synthesize speech up to 90 minutes long with up to 4 distinct speakers, surpassing the typical 1-2 speaker limits of many prior models.
🔥 News
- [2025-08-26] 🎉 We Open Source the VibeVoice-Large model weights!
- [2025-08-28] 🎉 We provide a Colab script for easy access to our model. Due to GPU memory limitations, only VibeVoice-1.5B is supported.
📋 TODO
- Merge models into official Hugging Face repository (PR)
- Release example training code and documentation
- VibePod: End-to-end solution that creates podcasts from documents, webpages, or even a simple topic.
🎵 Demo Examples
Video Demo
We produced this video with Wan2.2. We sincerely appreciate the Wan-Video team for their great work.
English
Chinese
Cross-Lingual
Spontaneous Singing
Long Conversation with 4 people
For more examples, see the Project Page.
Models
| Model | Context Length | Generation Length | Weight |
|---|---|---|---|
| VibeVoice-0.5B-Streaming | - | - | On the way |
| VibeVoice-1.5B | 64K | ~90 min | HF link |
| VibeVoice-Large | 32K | ~45 min | HF link |
Installation
We recommend to use NVIDIA Deep Learning Container to manage the CUDA environment.
- Launch docker
# NVIDIA PyTorch Container 24.07 / 24.10 / 24.12 verified.
# Later versions are also compatible.
sudo docker run --privileged --net=host --ipc=host --ulimit memlock=-1:-1 --ulimit stack=-1:-1 --gpus all --rm -it  nvcr.io/nvidia/pytorch:24.07-py3

## If flash attention is not included in your docker environment, you need to install it manually
## Refer to https://github.com/Dao-AILab/flash-attention for installation instructions
# pip install flash-attn --no-build-isolation
- Install from github
git clone https://github.com/microsoft/VibeVoice.git
cd VibeVoice/

pip install -e .
Usages
🚨 Tips
We observed users may encounter occasional instability when synthesizing Chinese speech. We recommend:
- Using English punctuation even for Chinese text, preferably only commas and periods.
- Using the Large model variant, which is considerably more stable.
- If you found the generated voice speak too fast. Please try to chunk your text with multiple speaker turns with same speaker label.
We'd like to thank PsiPi for sharing an interesting way for emotion control. Detials can be found via discussion12.
Usage 1: Launch Gradio demo
apt update && apt install ffmpeg -y # for demo

# For 1.5B model
python demo/gradio_demo.py --model_path microsoft/VibeVoice-1.5B --share

# For Large model
python demo/gradio_demo.py --model_path aoi-ot/VibeVoice-Large --share
Usage 2: Inference from files directly
# We provide some LLM generated example scripts under demo/text_examples/ for demo
# 1 speaker
python demo/inference_from_file.py --model_path aoi-ot/VibeVoice-Large --txt_path demo/text_examples/1p_abs.txt --speaker_names Alice

# or more speakers
python demo/inference_from_file.py --model_path aoi-ot/VibeVoice-Large --txt_path demo/text_examples/2p_music.txt --speaker_names Alice Frank
FAQ
Q1: Is this a pretrained model?
A: Yes, it's a pretrained model without any post-training or benchmark-specific optimizations. In a way, this makes VibeVoice very versatile and fun to use.
Q2: Randomly trigger Sounds / Music / BGM.
A: As you can see from our demo page, the background music or sounds are spontaneous. This means we can't directly control whether they are generated or not. The model is content-aware, and these sounds are triggered based on the input text and the chosen voice prompt.
Here are a few things we've noticed:
- If the voice prompt you use contains background music, the generated speech is more likely to have it as well. (The Large model is quite stable and effective at this—give it a try on the demo!)
- If the voice prompt is clean (no BGM), but the input text includes introductory words or phrases like "Welcome to," "Hello," or "However," background music might still appear.
- Speaker voice related, using "Alice" results in random BGM than others (fixed).
- In other scenarios, the Large model is more stable and has a lower probability of generating unexpected background music.
In fact, we intentionally decided not to denoise our training data because we think it's an interesting feature for BGM to show up at just the right moment. You can think of it as a little easter egg we left for you.
Q3: Text normalization?
A: We don't perform any text normalization during training or inference. Our philosophy is that a large language model should be able to handle complex user inputs on its own. However, due to the nature of the training data, you might still run into some corner cases.
Q4: Singing Capability.
A: Our training data doesn't contain any music data. The ability to sing is an emergent capability of the model (which is why it might sound off-key, even on a famous song like 'See You Again'). (The Large model is more likely to exhibit this than the 1.5B).
Q5: Some Chinese pronunciation errors.
A: The volume of Chinese data in our training set is significantly smaller than the English data. Additionally, certain special characters (e.g., Chinese quotation marks) may occasionally cause pronunciation issues.
Q6: Instability of cross-lingual transfer.
A: The model does exhibit strong cross-lingual transfer capabilities, including the preservation of accents, but its performance can be unstable. This is an emergent ability of the model that we have not specifically optimized. It's possible that a satisfactory result can be achieved through repeated sampling.
Risks and limitations
While efforts have been made to optimize it through various techniques, it may still produce outputs that are unexpected, biased, or inaccurate. VibeVoice inherits any biases, errors, or omissions produced by its base model (specifically, Qwen2.5 1.5b in this release). Potential for Deepfakes and Disinformation: High-quality synthetic speech can be misused to create convincing fake audio content for impersonation, fraud, or spreading disinformation. Users must ensure transcripts are reliable, check content accuracy, and avoid using generated content in misleading ways. Users are expected to use the generated content and to deploy the models in a lawful manner, in full compliance with all applicable laws and regulations in the relevant jurisdictions. It is best practice to disclose the use of AI when sharing AI-generated content.
English and Chinese only: Transcripts in languages other than English or Chinese may result in unexpected audio outputs.
Non-Speech Audio: The model focuses solely on speech synthesis and does not handle background noise, music, or other sound effects.
Overlapping Speech: The current model does not explicitly model or generate overlapping speech segments in conversations.
We do not recommend using VibeVoice in commercial or real-world applications without further testing and development. This model is intended for research and development purposes only. Please use responsibly.
Contributors


Similar repos



Languages
Python
100.0%
README
🎙️ VibeVoice: A Frontier Long Conversational Text-to-Speech Model
VibeVoice is a novel framework designed for generating expressive, long-form, multi-speaker conversational audio, such as podcasts, from text. It addresses significant challenges in traditional Text-to-Speech (TTS) systems, particularly in scalability, speaker consistency, and natural turn-taking.
A core innovation of VibeVoice is its use of continuous speech tokenizers (Acoustic and Semantic) operating at an ultra-low frame rate of 7.5 Hz. These tokenizers efficiently preserve audio fidelity while significantly boosting computational efficiency for processing long sequences. VibeVoice employs a next-token diffusion framework, leveraging a Large Language Model (LLM) to understand textual context and dialogue flow, and a diffusion head to generate high-fidelity acoustic details.
The model can synthesize speech up to 90 minutes long with up to 4 distinct speakers, surpassing the typical 1-2 speaker limits of many prior models.
🔥 News
- [2025-08-26] 🎉 We Open Source the VibeVoice-Large model weights!
- [2025-08-28] 🎉 We provide a Colab script for easy access to our model. Due to GPU memory limitations, only VibeVoice-1.5B is supported.
📋 TODO
- Merge models into official Hugging Face repository (PR)
- Release example training code and documentation
- VibePod: End-to-end solution that creates podcasts from documents, webpages, or even a simple topic.
🎵 Demo Examples
Video Demo
We produced this video with Wan2.2. We sincerely appreciate the Wan-Video team for their great work.
English
Chinese
Cross-Lingual
Spontaneous Singing
Long Conversation with 4 people
For more examples, see the Project Page.
Models
| Model | Context Length | Generation Length | Weight |
|---|---|---|---|
| VibeVoice-0.5B-Streaming | - | - | On the way |
| VibeVoice-1.5B | 64K | ~90 min | HF link |
| VibeVoice-Large | 32K | ~45 min | HF link |
Installation
We recommend to use NVIDIA Deep Learning Container to manage the CUDA environment.
- Launch docker
# NVIDIA PyTorch Container 24.07 / 24.10 / 24.12 verified.
# Later versions are also compatible.
sudo docker run --privileged --net=host --ipc=host --ulimit memlock=-1:-1 --ulimit stack=-1:-1 --gpus all --rm -it  nvcr.io/nvidia/pytorch:24.07-py3

## If flash attention is not included in your docker environment, you need to install it manually
## Refer to https://github.com/Dao-AILab/flash-attention for installation instructions
# pip install flash-attn --no-build-isolation
- Install from github
git clone https://github.com/microsoft/VibeVoice.git
cd VibeVoice/

pip install -e .
Usages
🚨 Tips
We observed users may encounter occasional instability when synthesizing Chinese speech. We recommend:
- Using English punctuation even for Chinese text, preferably only commas and periods.
- Using the Large model variant, which is considerably more stable.
- If you found the generated voice speak too fast. Please try to chunk your text with multiple speaker turns with same speaker label.
We'd like to thank PsiPi for sharing an interesting way for emotion control. Detials can be found via discussion12.
Usage 1: Launch Gradio demo
apt update && apt install ffmpeg -y # for demo

# For 1.5B model
python demo/gradio_demo.py --model_path microsoft/VibeVoice-1.5B --share

# For Large model
python demo/gradio_demo.py --model_path aoi-ot/VibeVoice-Large --share
Usage 2: Inference from files directly
# We provide some LLM generated example scripts under demo/text_examples/ for demo
# 1 speaker
python demo/inference_from_file.py --model_path aoi-ot/VibeVoice-Large --txt_path demo/text_examples/1p_abs.txt --speaker_names Alice

# or more speakers
python demo/inference_from_file.py --model_path aoi-ot/VibeVoice-Large --txt_path demo/text_examples/2p_music.txt --speaker_names Alice Frank
FAQ
Q1: Is this a pretrained model?
A: Yes, it's a pretrained model without any post-training or benchmark-specific optimizations. In a way, this makes VibeVoice very versatile and fun to use.
Q2: Randomly trigger Sounds / Music / BGM.
A: As you can see from our demo page, the background music or sounds are spontaneous. This means we can't directly control whether they are generated or not. The model is content-aware, and these sounds are triggered based on the input text and the chosen voice prompt.
Here are a few things we've noticed:
- If the voice prompt you use contains background music, the generated speech is more likely to have it as well. (The Large model is quite stable and effective at this—give it a try on the demo!)
- If the voice prompt is clean (no BGM), but the input text includes introductory words or phrases like "Welcome to," "Hello," or "However," background music might still appear.
- Speaker voice related, using "Alice" results in random BGM than others (fixed).
- In other scenarios, the Large model is more stable and has a lower probability of generating unexpected background music.
In fact, we intentionally decided not to denoise our training data because we think it's an interesting feature for BGM to show up at just the right moment. You can think of it as a little easter egg we left for you.
Q3: Text normalization?
A: We don't perform any text normalization during training or inference. Our philosophy is that a large language model should be able to handle complex user inputs on its own. However, due to the nature of the training data, you might still run into some corner cases.
Q4: Singing Capability.
A: Our training data doesn't contain any music data. The ability to sing is an emergent capability of the model (which is why it might sound off-key, even on a famous song like 'See You Again'). (The Large model is more likely to exhibit this than the 1.5B).
Q5: Some Chinese pronunciation errors.
A: The volume of Chinese data in our training set is significantly smaller than the English data. Additionally, certain special characters (e.g., Chinese quotation marks) may occasionally cause pronunciation issues.
Q6: Instability of cross-lingual transfer.
A: The model does exhibit strong cross-lingual transfer capabilities, including the preservation of accents, but its performance can be unstable. This is an emergent ability of the model that we have not specifically optimized. It's possible that a satisfactory result can be achieved through repeated sampling.
Risks and limitations
While efforts have been made to optimize it through various techniques, it may still produce outputs that are unexpected, biased, or inaccurate. VibeVoice inherits any biases, errors, or omissions produced by its base model (specifically, Qwen2.5 1.5b in this release). Potential for Deepfakes and Disinformation: High-quality synthetic speech can be misused to create convincing fake audio content for impersonation, fraud, or spreading disinformation. Users must ensure transcripts are reliable, check content accuracy, and avoid using generated content in misleading ways. Users are expected to use the generated content and to deploy the models in a lawful manner, in full compliance with all applicable laws and regulations in the relevant jurisdictions. It is best practice to disclose the use of AI when sharing AI-generated content.
English and Chinese only: Transcripts in languages other than English or Chinese may result in unexpected audio outputs.
Non-Speech Audio: The model focuses solely on speech synthesis and does not handle background noise, music, or other sound effects.
Overlapping Speech: The current model does not explicitly model or generate overlapping speech segments in conversations.
We do not recommend using VibeVoice in commercial or real-world applications without further testing and development. This model is intended for research and development purposes only. Please use responsibly.
Similar repos
Contributors
Languages
Python
100.0%