Text and image to video generation: Kandinsky 4.0 (2024)
See the code
In this repository, we provide a family of diffusion models to generate a video given a textual prompt or an image (Coming Soon), a distilled model for a faster generation and a video to audio generation model.
2024/12/13: We have open-sourced Kandinsky 4.0 T2V Flash a distilled version of Kandinsky 4.0 T2V text-to-video generation model.2024/12/13: We have open-sourced Kandinsky 4.0 V2A a video-to-audio generation model.Coming Soon 🤗
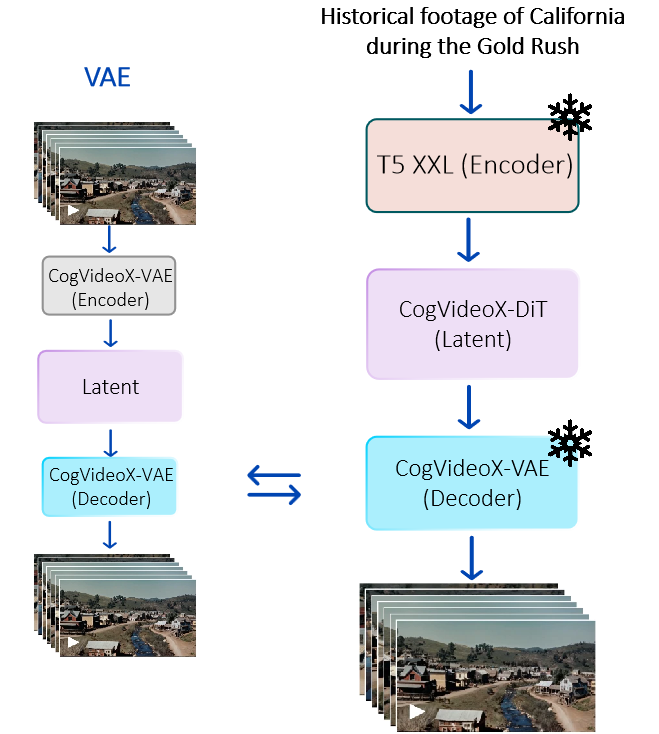
Kandinsky 4.0 is a text-to-video generation model leveraging latent diffusion to produce videos in both 480p and HD resolutions. We also introduce Kandinsky 4 Flash, a distilled version of the model capable of generating 12-second 480p videos in just 11 seconds using a single NVIDIA H100 GPU. The pipeline integrates a 3D causal CogVideoX VAE, the T5-V1.1-XXL text embedder, and our custom-trained MMDiT-like transformer model. Kandinsky 4.0 Flash was trained using the Latent Adversarial Diffusion Distillation (LADD) approach, proposed for distilling image generation models and first described in the article from Stability AI.
The following scheme describes the overall generation pipeline:
import torch
from IPython.display import Video
from kandinsky import get_T2V_pipeline

device_map = {
    "dit": torch.device('cuda:0'),
    "vae": torch.device('cuda:0'),
    "text_embedder": torch.device('cuda:0')
}

pipe = get_T2V_pipeline(device_map)

images = pipe(
    seed=42,
    time_length=12,
    width = 672,
    height = 384,
    save_path="./test.mp4",
    text="Several giant wooly mammoths approach treading through a snowy meadow, their long wooly fur lightly blows in the wind as they walk, snow covered trees and dramatic snow capped mountains in the distance",
)

Video("./test.mp4")
Please, refer to examples.ipynb notebook for more usage details.
For a faster inference, we also provide the capability to perform inference in a distributed way:
NUMBER_OF_NODES=1
NUMBER_OF_DEVICES_PER_NODE=8
python -m torch.distributed.launch --nnodes $NUMBER_OF_NODES --nproc-per-node $NUMBER_OF_DEVICES_PER_NODE run_inference_distil.py
Coming Soon 🤗
|
|
|
Video to Audio pipeline consists of a visual encoder, a text encoder, UNet diffusion model to generate spectrogram and Griffin-lim algorithm to convert spectrogram into audio. Visual and text encoders share the same multimodal visual language decoder (cogvlm2-video-llama3-chat).
Our UNet diffusion model is a finetune of the music generation model riffusion. We made modifications in the architecture to condition on video frames and improve the synchronization between video and audio. Also, we replace the text encoder with the decoder of cogvlm2-video-llama3-chat.
import torch
import torchvision

from kandinsky4_video2audio.video2audio_pipe import Video2AudioPipeline
from kandinsky4_video2audio.utils import load_video, create_video

device='cuda:0'

pipe = Video2AudioPipeline(
    "ai-forever/kandinsky-4-v2a",
    torch_dtype=torch.float16,
    device = device
)

video_path = 'assets/inputs/1.mp4'
video, _, fps = torchvision.io.read_video(video_path)

prompt="clean. clear. good quality."
negative_prompt = "hissing noise. drumming rythm. saying. poor quality."
video_input, video_complete, duration_sec = load_video(video, fps['video_fps'], num_frames=96, max_duration_sec=12)

out = pipe(
    video_input,
    prompt,
    negative_prompt=negative_prompt,
    duration_sec=duration_sec,
)[0]

save_path = f'assets/outputs/1.mp4'
create_video(
    out,
    video_complete,
    display_video=True,
    save_path=save_path,
    device=device
)
Project Leader: Denis Dimitrov.
Scientific Advisors: Andrey Kuznetsov, Sergey Markov.
Training Pipeline & Model Pretrain & Model Distillation: Vladimir Arkhipkin, Lev Novitskiy, Maria Kovaleva.
Model Architecture: Vladimir Arkhipkin, Maria Kovaleva, Zein Shaheen, Arsen Kuzhamuratov, Nikolay Gerasimenko, Mikhail Zhirnov, Alexander Gambashidze, Konstantin Sobolev.
Data Pipeline: Ivan Kirillov, Andrei Shutkin, Kirill Chernishev, Julia Agafonova, Elizaveta Dakhova, Denis Parkhomenko.
Video-to-audio model: Zein Shaheen, Arseniy Shakhmatov, Denis Parkhomenko.
Quality Assessment: Nikolay Gerasimenko, Anna Averchenkova, Victor Panshin, Vladislav Veselov, Pavel Perminov, Vladislav Rodionov, Sergey Skachkov, Stepan Ponomarev.
Other Contributors: Viacheslav Vasilev, Andrei Filatov, Gregory Leleytner.
228 followers · starred Dec 2024
467 followers · starred Dec 2024
64 followers · starred Dec 2024
Text and image to video generation: Kandinsky 4.0 (2024)
See the code
In this repository, we provide a family of diffusion models to generate a video given a textual prompt or an image (Coming Soon), a distilled model for a faster generation and a video to audio generation model.
2024/12/13: We have open-sourced Kandinsky 4.0 T2V Flash a distilled version of Kandinsky 4.0 T2V text-to-video generation model.2024/12/13: We have open-sourced Kandinsky 4.0 V2A a video-to-audio generation model.Coming Soon 🤗
Kandinsky 4.0 is a text-to-video generation model leveraging latent diffusion to produce videos in both 480p and HD resolutions. We also introduce Kandinsky 4 Flash, a distilled version of the model capable of generating 12-second 480p videos in just 11 seconds using a single NVIDIA H100 GPU. The pipeline integrates a 3D causal CogVideoX VAE, the T5-V1.1-XXL text embedder, and our custom-trained MMDiT-like transformer model. Kandinsky 4.0 Flash was trained using the Latent Adversarial Diffusion Distillation (LADD) approach, proposed for distilling image generation models and first described in the article from Stability AI.
The following scheme describes the overall generation pipeline:
import torch
from IPython.display import Video
from kandinsky import get_T2V_pipeline

device_map = {
    "dit": torch.device('cuda:0'),
    "vae": torch.device('cuda:0'),
    "text_embedder": torch.device('cuda:0')
}

pipe = get_T2V_pipeline(device_map)

images = pipe(
    seed=42,
    time_length=12,
    width = 672,
    height = 384,
    save_path="./test.mp4",
    text="Several giant wooly mammoths approach treading through a snowy meadow, their long wooly fur lightly blows in the wind as they walk, snow covered trees and dramatic snow capped mountains in the distance",
)

Video("./test.mp4")
Please, refer to examples.ipynb notebook for more usage details.
For a faster inference, we also provide the capability to perform inference in a distributed way:
NUMBER_OF_NODES=1
NUMBER_OF_DEVICES_PER_NODE=8
python -m torch.distributed.launch --nnodes $NUMBER_OF_NODES --nproc-per-node $NUMBER_OF_DEVICES_PER_NODE run_inference_distil.py
Coming Soon 🤗
|
|
|
|
|
|
Video to Audio pipeline consists of a visual encoder, a text encoder, UNet diffusion model to generate spectrogram and Griffin-lim algorithm to convert spectrogram into audio. Visual and text encoders share the same multimodal visual language decoder (cogvlm2-video-llama3-chat).
Our UNet diffusion model is a finetune of the music generation model riffusion. We made modifications in the architecture to condition on video frames and improve the synchronization between video and audio. Also, we replace the text encoder with the decoder of cogvlm2-video-llama3-chat.
import torch
import torchvision

from kandinsky4_video2audio.video2audio_pipe import Video2AudioPipeline
from kandinsky4_video2audio.utils import load_video, create_video

device='cuda:0'

pipe = Video2AudioPipeline(
    "ai-forever/kandinsky-4-v2a",
    torch_dtype=torch.float16,
    device = device
)

video_path = 'assets/inputs/1.mp4'
video, _, fps = torchvision.io.read_video(video_path)

prompt="clean. clear. good quality."
negative_prompt = "hissing noise. drumming rythm. saying. poor quality."
video_input, video_complete, duration_sec = load_video(video, fps['video_fps'], num_frames=96, max_duration_sec=12)

out = pipe(
    video_input,
    prompt,
    negative_prompt=negative_prompt,
    duration_sec=duration_sec,
)[0]

save_path = f'assets/outputs/1.mp4'
create_video(
    out,
    video_complete,
    display_video=True,
    save_path=save_path,
    device=device
)
Project Leader: Denis Dimitrov.
Scientific Advisors: Andrey Kuznetsov, Sergey Markov.
Training Pipeline & Model Pretrain & Model Distillation: Vladimir Arkhipkin, Lev Novitskiy, Maria Kovaleva.
Model Architecture: Vladimir Arkhipkin, Maria Kovaleva, Zein Shaheen, Arsen Kuzhamuratov, Nikolay Gerasimenko, Mikhail Zhirnov, Alexander Gambashidze, Konstantin Sobolev.
Data Pipeline: Ivan Kirillov, Andrei Shutkin, Kirill Chernishev, Julia Agafonova, Elizaveta Dakhova, Denis Parkhomenko.
Video-to-audio model: Zein Shaheen, Arseniy Shakhmatov, Denis Parkhomenko.
Quality Assessment: Nikolay Gerasimenko, Anna Averchenkova, Victor Panshin, Vladislav Veselov, Pavel Perminov, Vladislav Rodionov, Sergey Skachkov, Stepan Ponomarev.
Other Contributors: Viacheslav Vasilev, Andrei Filatov, Gregory Leleytner.
228 followers · starred Dec 2024
467 followers · starred Dec 2024
64 followers · starred Dec 2024



