
A ComfyUI node implementation for ByteDance's Sa2VA
Python
95
9 commits
updated Dec 22, 2025
README
ComfyUI Sa2VA
Overview
A ComfyUI node implementation for ByteDance's Sa2VA (Segment Anything 2 Video Assistant) models, enabling advanced multimodal image and video understanding with precise segmentation capabilities. This repo only implements the image portion of the model.
What is Sa2VA?
Sa2VA is a state-of-the-art multimodal large language model (MLLM) that combines SAM2 (Segment Anything Model 2) with VLLMs for grounded understanding of images and videos. It achieves comparable performance to SOTA MLLMs like Qwen2.5-VL and InternVL3 on question-answering benchmarks while adding advanced visual prompt understanding and dense object segmentation capabilities.
Comparisons and Uses
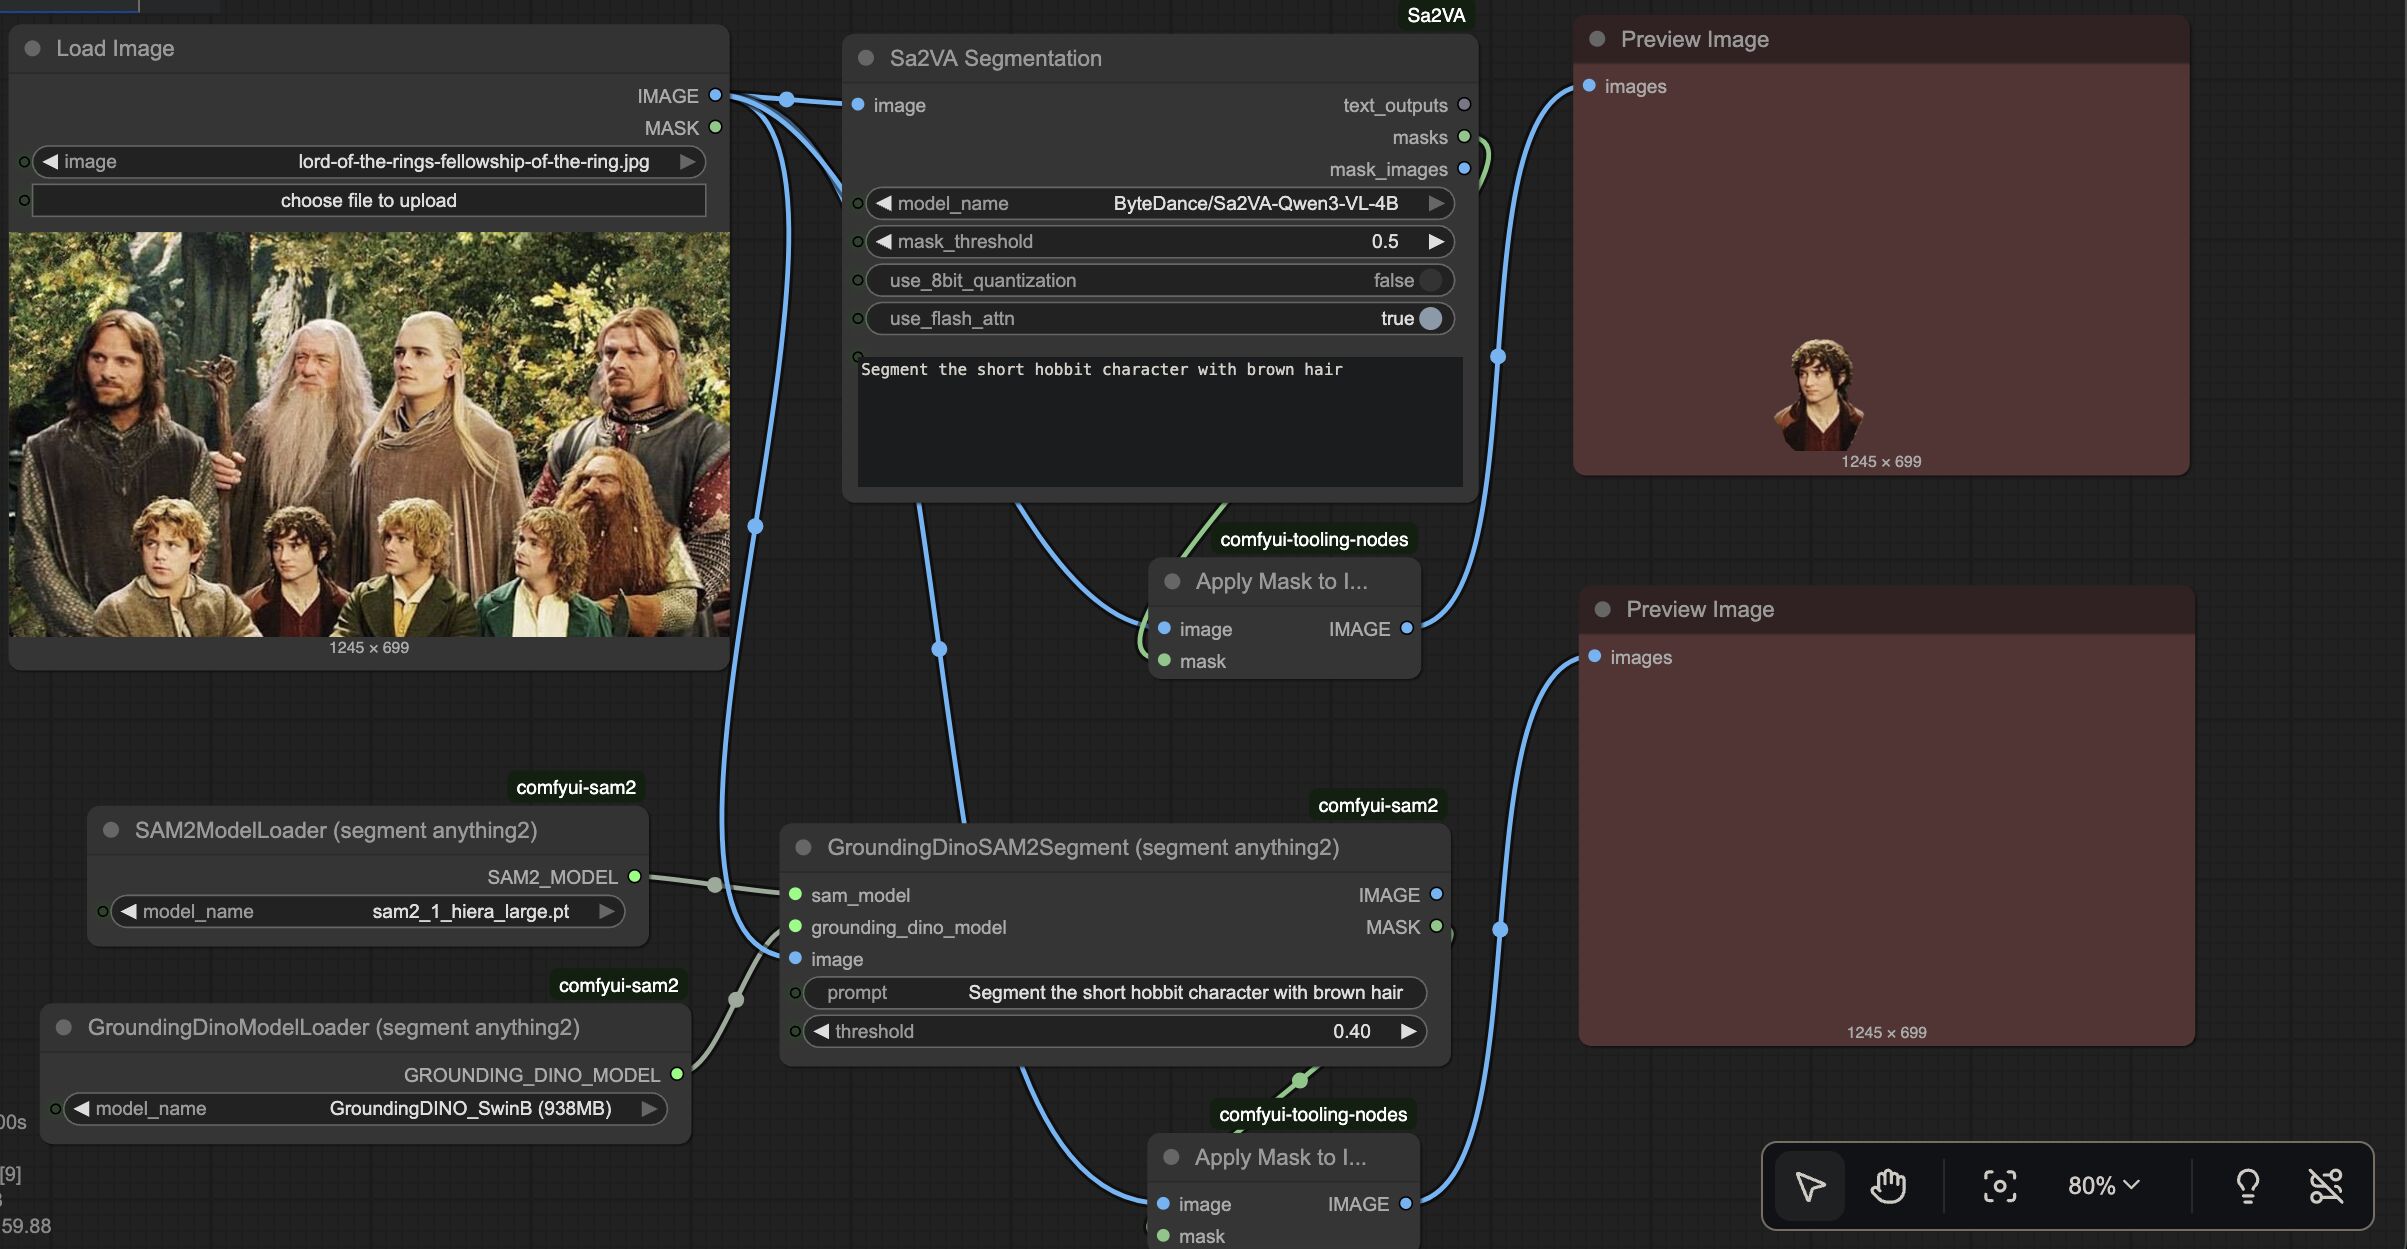
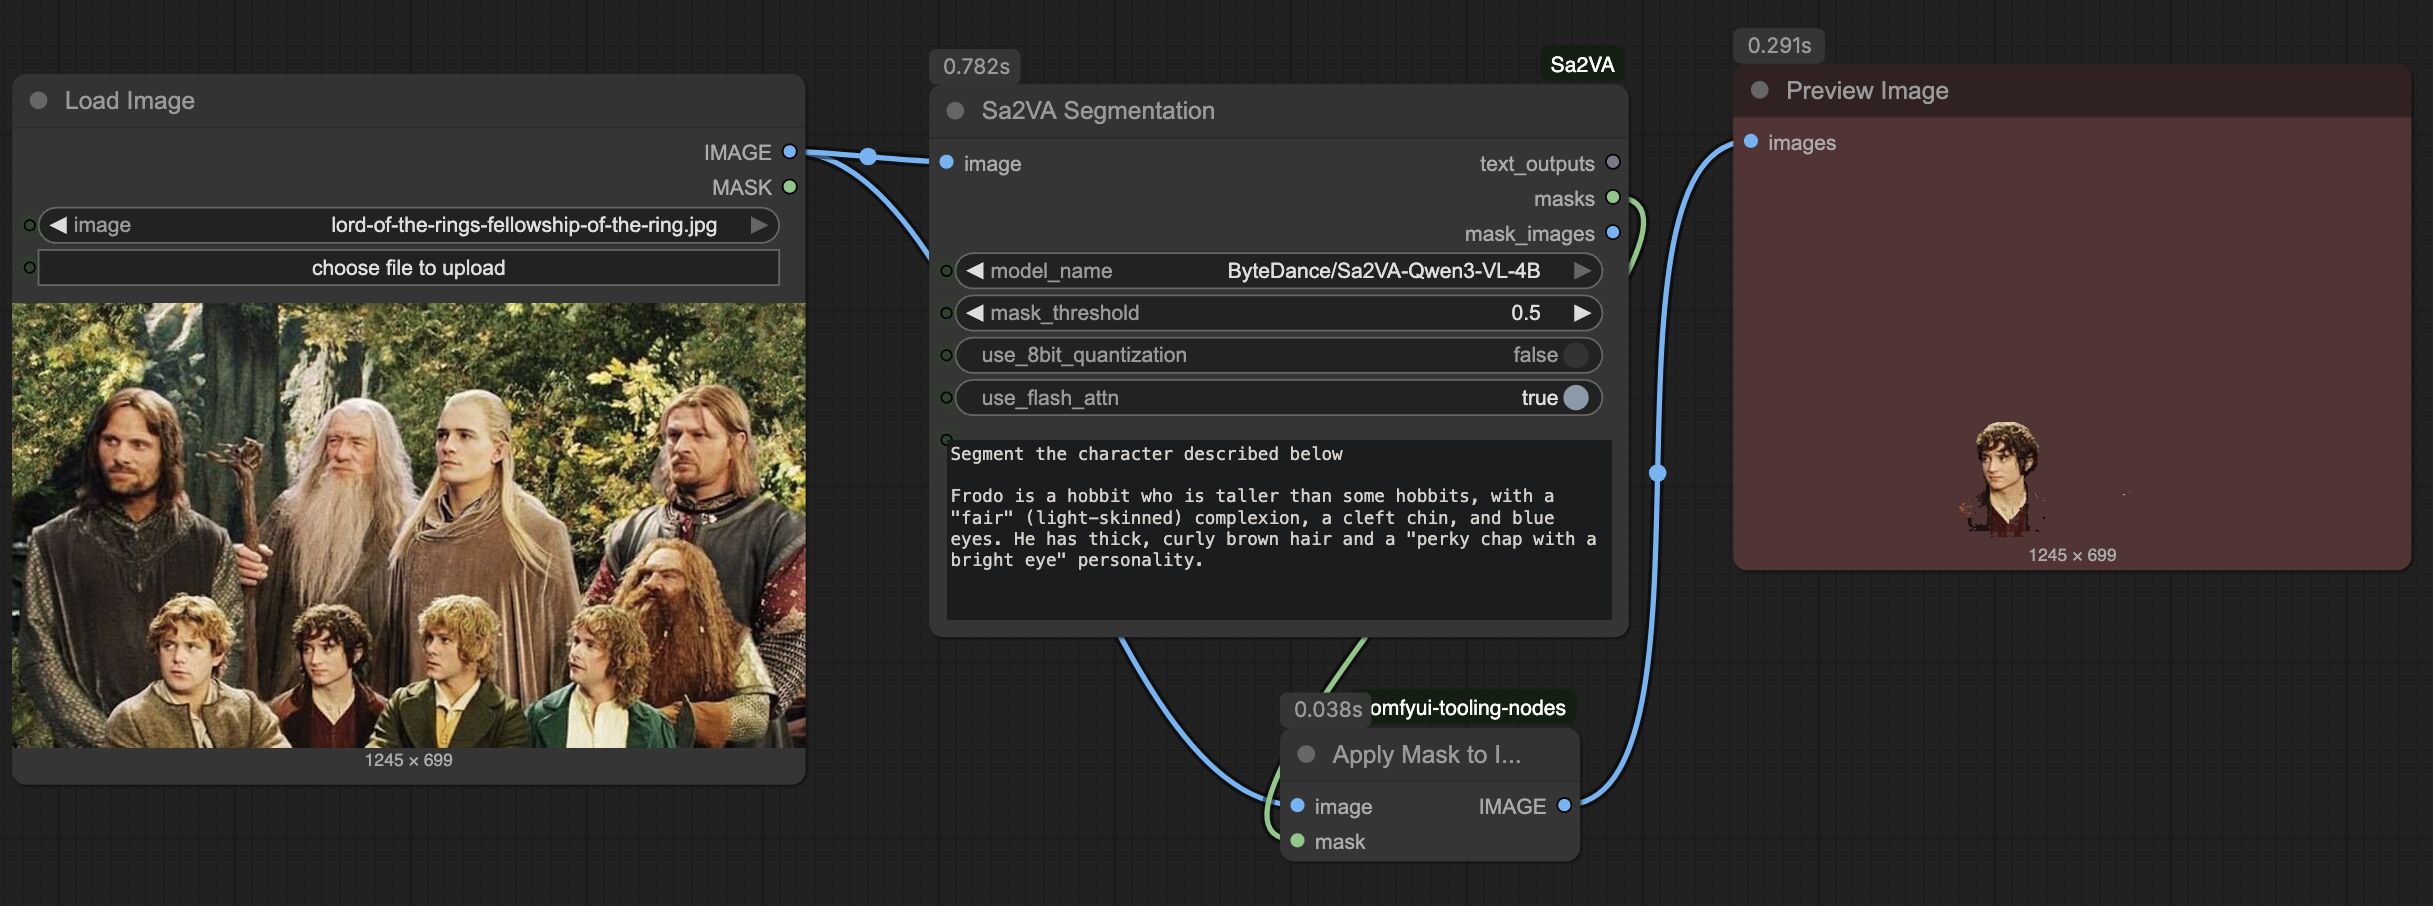
This Sa2VA node can be thought of as a more advanced version of neverbiasu's ComfyUI-SAM2 node that allows for segmentation of objects in an image using natural langauge. Unlike that node which is based on Grounded SAM/Grounding DINO, Sa2VA uses a full VLLM trained to output SAM2 segmentation masks, which means it can handle significantly longer and more descriptive text. This allows Sa2VA to be better for uses cases where simple phrases like "woman on right" isn't sufficient to completely disambiguate between objects.
It outperforms Grounding DINO on short prompts:
And can follow longer instructions quite well, such as describing a character in general, rather than their position or traits in the image itself. This lends itself well to auto-generated or agentic segmentation prompts:
It can also segment more than one mask at a time, but the prompt needs to be precise:

Installation
Installation
cd ComfyUI/custom_nodes
git clone https://github.com/adambarbato/ComfyUI-Sa2VA.git
cd ComfyUI-Sa2VA
pip install -r requirements.txt
Requirements
- Python 3.8+
- PyTorch 2.0+
- transformers >= 4.57.0 (Critical!)
- CUDA 11.8+ (for GPU acceleration)
- 8GB+ VRAM recommended for 4B models
- 20GB+ VRAM for full precision
Important: Sa2VA models require:
- transformers >= 4.57.0 (for Qwen3-VL support)
- qwen_vl_utils (for model utilities)
Older transformers versions will fail with "No module named 'transformers.models.qwen3_vl'" error.
Features
Core Capabilities
- Multimodal Understanding: Combines text generation with visual understanding
- Dense Segmentation: Pixel-perfect object segmentation masks
- Video Processing: Temporal understanding across video sequences
- Visual Prompts: Understanding of spatial relationships and object references
- Integrated Mask Conversion: Built-in conversion to ComfyUI mask and image formats
- Cancellable, Real-time Downloads: Large model downloads show progress and respect ComfyUI's cancel button
Supported Models
ByteDance/Sa2VA-Qwen3-VL-4B(recommended - 4B parameters)ByteDance/Sa2VA-Qwen2_5-VL-7B(7B parameters)ByteDance/Sa2VA-InternVL3-8B(8B parameters)ByteDance/Sa2VA-InternVL3-14B(14B parameters)ByteDance/Sa2VA-Qwen2_5-VL-3B(3B parameters)ByteDance/Sa2VA-InternVL3-2B(2B parameters)
Node
Sa2VA Segmentation
A single, comprehensive node that provides:
- Text Generation: Detailed image descriptions and analysis
- Object Segmentation: Precise pixel-level object masks
- Integrated Mask Conversion: Automatic conversion to ComfyUI MASK and IMAGE formats
- Memory Management: Built-in VRAM optimization and model lifecycle management
- Multiple Output Formats: Text, ComfyUI masks, and visualizable mask images
Quick Start
Basic Image Description
- Add Load Image node and load your image
- Add Sa2VA Segmentation node
- Connect Load Image → Sa2VA node
- Adjust
model_nameandmask_thresholdas needed - Set
segmentation_prompt: "Please describe the image in detail." - Execute to get text descriptions
Image Segmentation
- Load image using Load Image node
- Add Sa2VA Segmentation node
- Connect Load Image → Sa2VA node
- Adjust
model_nameandmask_thresholdas needed - Set
segmentation_prompt: "Please provide segmentation masks for all objects." - Connect the
masksoutput to mask-compatible nodes ormask_imagesto Preview Image - The node automatically provides both MASK tensors and visualizable IMAGE tensors
Model Precision
Sa2VA models use bfloat16 precision by default with the option to quantize to 8 bits using bits-and-bytes.
Troubleshooting
Common Issues
"No module named 'transformers.models.qwen3_vl'"
pip install transformers>=4.57.0 --upgrade
This is the most common issue - your transformers version is too old.
"No module named 'qwen_vl_utils'"
pip install qwen_vl_utils
This dependency is required for Sa2VA model utilities.
"'NoneType' object is not subscriptable"
- Model loading failed (check console for errors)
- Usually caused by outdated transformers version
- Verify internet connection for model download
CUDA Out of Memory
- Use 8 bit quantization
- Use smaller model variant (2B or 3B parameters)
- Reduce batch size
Model Loading Errors
- Check internet connection for initial download
- Ensure sufficient disk space (20GB+ per model)
- Verify CUDA compatibility
- Try:
torch.cuda.empty_cache()to clear VRAM
Poor Segmentation Quality
- Use more specific prompts: "Please segment the person"
- Try different model variants
- Adjust threshold in Mask Converter
- Use higher resolution images
For detailed troubleshooting, see TROUBLESHOOTING.md.
Advanced Configuration
Custom Prompts
# Object-specific segmentation
"Please segment the person in the image"
"Identify and segment all vehicles"

# Multi-object segmentation
"Create separate masks for all distinct objects"
"Segment foreground and background separately"
Contributing
Contributions welcome! Areas for improvement:
- Performance optimizations
- Video processing
- Better mask post-processing
License
MIT
Links
Similar repos





Languages
Python
100.0%
A ComfyUI node implementation for ByteDance's Sa2VA
Python
95
9 commits
updated Dec 22, 2025
README
ComfyUI Sa2VA
Overview
A ComfyUI node implementation for ByteDance's Sa2VA (Segment Anything 2 Video Assistant) models, enabling advanced multimodal image and video understanding with precise segmentation capabilities. This repo only implements the image portion of the model.
What is Sa2VA?
Sa2VA is a state-of-the-art multimodal large language model (MLLM) that combines SAM2 (Segment Anything Model 2) with VLLMs for grounded understanding of images and videos. It achieves comparable performance to SOTA MLLMs like Qwen2.5-VL and InternVL3 on question-answering benchmarks while adding advanced visual prompt understanding and dense object segmentation capabilities.
Comparisons and Uses
This Sa2VA node can be thought of as a more advanced version of neverbiasu's ComfyUI-SAM2 node that allows for segmentation of objects in an image using natural langauge. Unlike that node which is based on Grounded SAM/Grounding DINO, Sa2VA uses a full VLLM trained to output SAM2 segmentation masks, which means it can handle significantly longer and more descriptive text. This allows Sa2VA to be better for uses cases where simple phrases like "woman on right" isn't sufficient to completely disambiguate between objects.
It outperforms Grounding DINO on short prompts:
And can follow longer instructions quite well, such as describing a character in general, rather than their position or traits in the image itself. This lends itself well to auto-generated or agentic segmentation prompts:
It can also segment more than one mask at a time, but the prompt needs to be precise:
Installation
Installation
cd ComfyUI/custom_nodes
git clone https://github.com/adambarbato/ComfyUI-Sa2VA.git
cd ComfyUI-Sa2VA
pip install -r requirements.txt
Requirements
- Python 3.8+
- PyTorch 2.0+
- transformers >= 4.57.0 (Critical!)
- CUDA 11.8+ (for GPU acceleration)
- 8GB+ VRAM recommended for 4B models
- 20GB+ VRAM for full precision
Important: Sa2VA models require:
- transformers >= 4.57.0 (for Qwen3-VL support)
- qwen_vl_utils (for model utilities)
Older transformers versions will fail with "No module named 'transformers.models.qwen3_vl'" error.
Features
Core Capabilities
- Multimodal Understanding: Combines text generation with visual understanding
- Dense Segmentation: Pixel-perfect object segmentation masks
- Video Processing: Temporal understanding across video sequences
- Visual Prompts: Understanding of spatial relationships and object references
- Integrated Mask Conversion: Built-in conversion to ComfyUI mask and image formats
- Cancellable, Real-time Downloads: Large model downloads show progress and respect ComfyUI's cancel button
Supported Models
ByteDance/Sa2VA-Qwen3-VL-4B(recommended - 4B parameters)ByteDance/Sa2VA-Qwen2_5-VL-7B(7B parameters)ByteDance/Sa2VA-InternVL3-8B(8B parameters)ByteDance/Sa2VA-InternVL3-14B(14B parameters)ByteDance/Sa2VA-Qwen2_5-VL-3B(3B parameters)ByteDance/Sa2VA-InternVL3-2B(2B parameters)
Node
Sa2VA Segmentation
A single, comprehensive node that provides:
- Text Generation: Detailed image descriptions and analysis
- Object Segmentation: Precise pixel-level object masks
- Integrated Mask Conversion: Automatic conversion to ComfyUI MASK and IMAGE formats
- Memory Management: Built-in VRAM optimization and model lifecycle management
- Multiple Output Formats: Text, ComfyUI masks, and visualizable mask images
Quick Start
Basic Image Description
- Add Load Image node and load your image
- Add Sa2VA Segmentation node
- Connect Load Image → Sa2VA node
- Adjust
model_nameandmask_thresholdas needed - Set
segmentation_prompt: "Please describe the image in detail." - Execute to get text descriptions
Image Segmentation
- Load image using Load Image node
- Add Sa2VA Segmentation node
- Connect Load Image → Sa2VA node
- Adjust
model_nameandmask_thresholdas needed - Set
segmentation_prompt: "Please provide segmentation masks for all objects." - Connect the
masksoutput to mask-compatible nodes ormask_imagesto Preview Image - The node automatically provides both MASK tensors and visualizable IMAGE tensors
Model Precision
Sa2VA models use bfloat16 precision by default with the option to quantize to 8 bits using bits-and-bytes.
Troubleshooting
Common Issues
"No module named 'transformers.models.qwen3_vl'"
pip install transformers>=4.57.0 --upgrade
This is the most common issue - your transformers version is too old.
"No module named 'qwen_vl_utils'"
pip install qwen_vl_utils
This dependency is required for Sa2VA model utilities.
"'NoneType' object is not subscriptable"
- Model loading failed (check console for errors)
- Usually caused by outdated transformers version
- Verify internet connection for model download
CUDA Out of Memory
- Use 8 bit quantization
- Use smaller model variant (2B or 3B parameters)
- Reduce batch size
Model Loading Errors
- Check internet connection for initial download
- Ensure sufficient disk space (20GB+ per model)
- Verify CUDA compatibility
- Try:
torch.cuda.empty_cache()to clear VRAM
Poor Segmentation Quality
- Use more specific prompts: "Please segment the person"
- Try different model variants
- Adjust threshold in Mask Converter
- Use higher resolution images
For detailed troubleshooting, see TROUBLESHOOTING.md.
Advanced Configuration
Custom Prompts
# Object-specific segmentation
"Please segment the person in the image"
"Identify and segment all vehicles"

# Multi-object segmentation
"Create separate masks for all distinct objects"
"Segment foreground and background separately"
Contributing
Contributions welcome! Areas for improvement:
- Performance optimizations
- Video processing
- Better mask post-processing
License
MIT
Links
Similar repos
Languages
Python
100.0%