Official code for paper:"Speaking Clearly: A Simplified Whisper-Based Codec for Low-Bitrate Speech Coding"
Python
39
22 commits
updated Jan 28, 2026
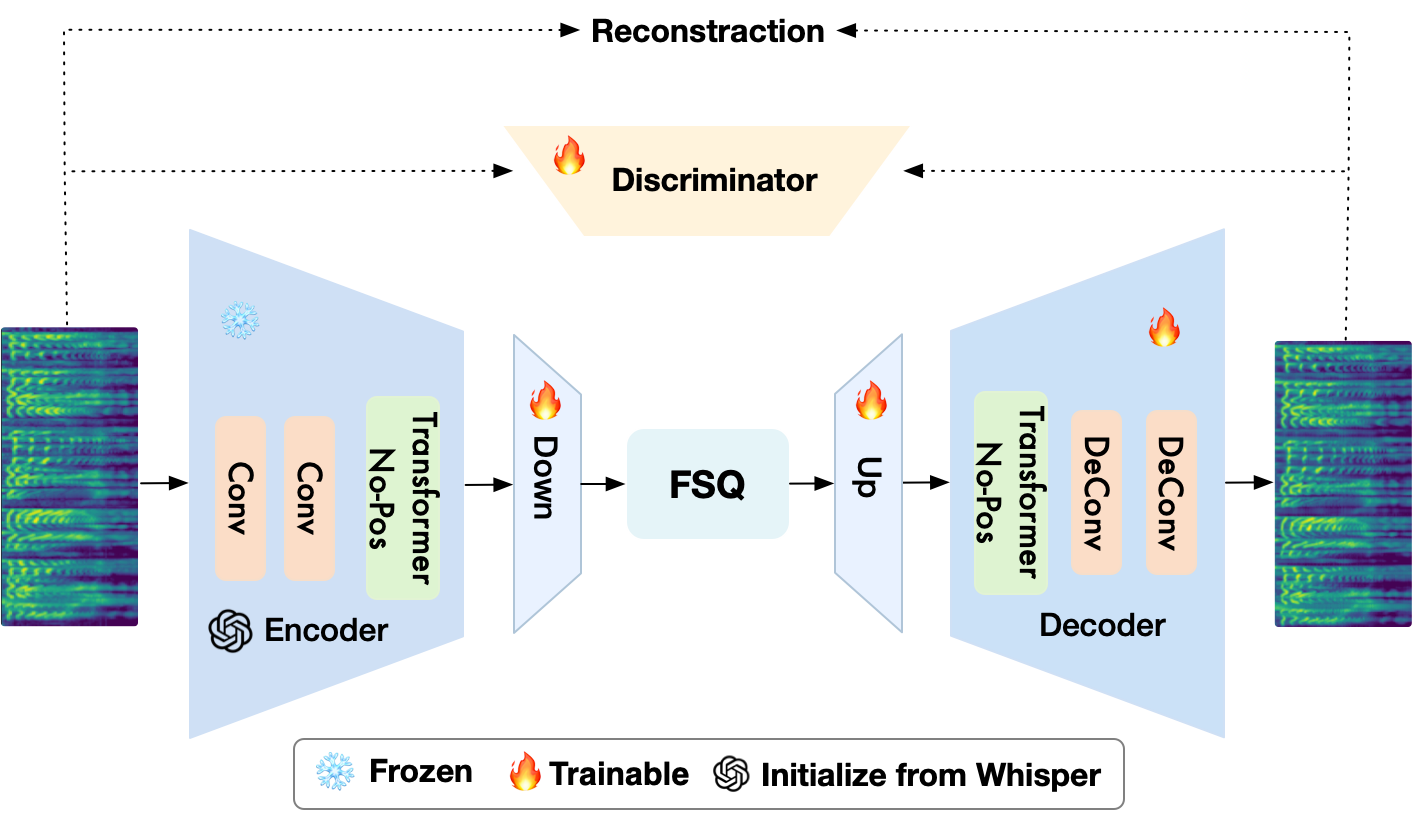

A semantic-first speech codec that achieves superior performance through architectural simplification rather than complex supervision.
| Model | Bitrate | WER ↓ | PESQ-NB ↑ | PESQ-WB ↑ | STOI ↑ | SIM ↑ | UTMOS ↑ |
|---|---|---|---|---|---|---|---|
| XCodec2.0 | 0.8 kbps | 2.61 | 3.04 | 2.43 | 0.92 | 0.82 | 4.13 |
| XY-Tokenizer | 1.0 kbps | 2.46 | 3.10 | 2.50 | 0.92 | 0.85 | 4.03 |
| BigCodec | 1.04 kbps | 2.92 | 3.27 | 2.68 | 0.93 | 0.84 | 4.11 |
| SimWhisper-Codec | 1.1 kbps | 2.75 | 3.29 | 2.72 | 0.93 | 0.83 | 4.00 |
Evaluation on Seed-TTS-Eval Dataset
| Model | Bitrate | SEED-ZH | SEED-EN | ||||||
|---|---|---|---|---|---|---|---|---|---|
| PESQ-NB ↑ | PESQ-WB ↑ | SIM ↑ | STOI ↑ | PESQ-NB ↑ | PESQ-WB ↑ | SIM ↑ | STOI ↑ | ||
| XCodec2.0 | 0.8 kbps | 2.69 | 2.10 | 0.81 | 0.89 | 2.57 | 2.01 | 0.78 | 0.89 |
| XY-Tokenizer | 1.0 kbps | 2.97 | 2.32 | 0.88 | 0.90 | 2.75 | 2.18 | 0.82 | 0.90 |
| BigCodec | 1.04 kbps | 2.88 | 2.26 | 0.80 | 0.91 | 2.80 | 2.22 | 0.80 | 0.91 |
| SimWhisper-Codec | 1.1 kbps | 3.30 | 2.38 | 0.82 | 0.91 | 2.88 | 2.29 | 0.80 | 0.91 |
| Dataset | Language | Samples | PESQ-WB ↑ | PESQ-NB ↑ | STOI ↑ |
|---|---|---|---|---|---|
| LJSpeech | English | 2,620 | 2.79 | 3.30 | 0.94 |
| THCHS-30 | Chinese | test set | 2.63 | 3.21 | 0.91 |
SimWhisper-Codec is trained exclusively on LibriSpeech, demonstrating strong cross-lingual generalization.
# Clone repository
git clone https://github.com/ZhangXinWhut/SimWhisper-Codec.git && cd SimWhisper-Codec

# Create and activate conda environment
conda create -n swcodec python=3.10 -y && conda activate swcodec

# Install dependencies
pip install -r requirements.txt
| Model Name | Hugging Face | Training Data |
|---|---|---|
| SimWhisper-Codec | 🤗 | LibriSpeech |
You need to download the SimWhisper-Codec model weights. You can find the weights in the SimWhisper-Codec Hugging Face repository.
mkdir -p ./weights && huggingface-cli download xxx123456/SimWhisper_Codec SimWhisperCodec.pt --local-dir ./weights/
python inference.py --input_dir /path/to/LibriSpeech/test-clean
The reconstructed audio files will be available in the output_wavs/ directory.
Our codebase builds upon the XY-Tokenizer. We thank the authors for their excellent work.
If you find this work useful in your research, please cite our paper:
@misc{zhang2025speakingclearlysimplifiedwhisperbased,
      title={Speaking Clearly: A Simplified Whisper-Based Codec for Low-Bitrate Speech Coding},
      author={Xin Zhang and Lin Li and Xiangni Lu and Jianquan Liu and Kong Aik Lee},
      year={2025},
      eprint={2510.20504},
      archivePrefix={arXiv},
      primaryClass={cs.SD},
      url={https://arxiv.org/abs/2510.20504},
}
This project is licensed under the Apache 2.0 License.
971 followers · starred Oct 2025
Official code for paper:"Speaking Clearly: A Simplified Whisper-Based Codec for Low-Bitrate Speech Coding"
Python
39
22 commits
updated Jan 28, 2026
A semantic-first speech codec that achieves superior performance through architectural simplification rather than complex supervision.
| Model | Bitrate | WER ↓ | PESQ-NB ↑ | PESQ-WB ↑ | STOI ↑ | SIM ↑ | UTMOS ↑ |
|---|---|---|---|---|---|---|---|
| XCodec2.0 | 0.8 kbps | 2.61 | 3.04 | 2.43 | 0.92 | 0.82 | 4.13 |
| XY-Tokenizer | 1.0 kbps | 2.46 | 3.10 | 2.50 | 0.92 | 0.85 | 4.03 |
| BigCodec | 1.04 kbps | 2.92 | 3.27 | 2.68 | 0.93 | 0.84 | 4.11 |
| SimWhisper-Codec | 1.1 kbps | 2.75 | 3.29 | 2.72 | 0.93 | 0.83 | 4.00 |
Evaluation on Seed-TTS-Eval Dataset
| Model | Bitrate | SEED-ZH | SEED-EN | ||||||
|---|---|---|---|---|---|---|---|---|---|
| PESQ-NB ↑ | PESQ-WB ↑ | SIM ↑ | STOI ↑ | PESQ-NB ↑ | PESQ-WB ↑ | SIM ↑ | STOI ↑ | ||
| XCodec2.0 | 0.8 kbps | 2.69 | 2.10 | 0.81 | 0.89 | 2.57 | 2.01 | 0.78 | 0.89 |
| XY-Tokenizer | 1.0 kbps | 2.97 | 2.32 | 0.88 | 0.90 | 2.75 | 2.18 | 0.82 | 0.90 |
| BigCodec | 1.04 kbps | 2.88 | 2.26 | 0.80 | 0.91 | 2.80 | 2.22 | 0.80 | 0.91 |
| SimWhisper-Codec | 1.1 kbps | 3.30 | 2.38 | 0.82 | 0.91 | 2.88 | 2.29 | 0.80 | 0.91 |
| Dataset | Language | Samples | PESQ-WB ↑ | PESQ-NB ↑ | STOI ↑ |
|---|---|---|---|---|---|
| LJSpeech | English | 2,620 | 2.79 | 3.30 | 0.94 |
| THCHS-30 | Chinese | test set | 2.63 | 3.21 | 0.91 |
SimWhisper-Codec is trained exclusively on LibriSpeech, demonstrating strong cross-lingual generalization.
# Clone repository
git clone https://github.com/ZhangXinWhut/SimWhisper-Codec.git && cd SimWhisper-Codec

# Create and activate conda environment
conda create -n swcodec python=3.10 -y && conda activate swcodec

# Install dependencies
pip install -r requirements.txt
| Model Name | Hugging Face | Training Data |
|---|---|---|
| SimWhisper-Codec | 🤗 | LibriSpeech |
You need to download the SimWhisper-Codec model weights. You can find the weights in the SimWhisper-Codec Hugging Face repository.
mkdir -p ./weights && huggingface-cli download xxx123456/SimWhisper_Codec SimWhisperCodec.pt --local-dir ./weights/
python inference.py --input_dir /path/to/LibriSpeech/test-clean
The reconstructed audio files will be available in the output_wavs/ directory.
Our codebase builds upon the XY-Tokenizer. We thank the authors for their excellent work.
If you find this work useful in your research, please cite our paper:
@misc{zhang2025speakingclearlysimplifiedwhisperbased,
      title={Speaking Clearly: A Simplified Whisper-Based Codec for Low-Bitrate Speech Coding},
      author={Xin Zhang and Lin Li and Xiangni Lu and Jianquan Liu and Kong Aik Lee},
      year={2025},
      eprint={2510.20504},
      archivePrefix={arXiv},
      primaryClass={cs.SD},
      url={https://arxiv.org/abs/2510.20504},
}
This project is licensed under the Apache 2.0 License.
971 followers · starred Oct 2025



