
The official repository for the paper: Evaluation of Retrieval-Augmented Generation: A Survey.
TeX
200
5 commits
updated Apr 25, 2025
README
Awesome RAG Evaluation
English | 简体中文
The official repository for the paper: Evaluation of Retrieval-Augmented Generation: A Survey Arxiv. This paper has been accepted by the 2024 CCF Big Data.
Abstract
Retrieval-Augmented Generation (RAG) has recently gained traction in natural language processing. Numerous studies and real-world applications are leveraging its ability to enhance generative models through external information retrieval. Evaluating these RAG systems, however, poses unique challenges due to their hybrid structure and reliance on dynamic knowledge sources. To better understand these challenges, we conduct A Unified Evaluation Process of RAG (Auepora) and aim to provide a comprehensive overview of the evaluation and benchmarks of RAG systems. Specifically, we examine and compare several quantifiable metrics of the Retrieval and Generation components, such as relevance, accuracy, and faithfulness, within the current RAG benchmarks, encompassing the possible output and ground truth pairs. We then analyze the various datasets and metrics, discuss the limitations of current benchmarks, and suggest potential directions to advance the field of RAG benchmarks.
Analysis Framework for Evaluating RAG Systems
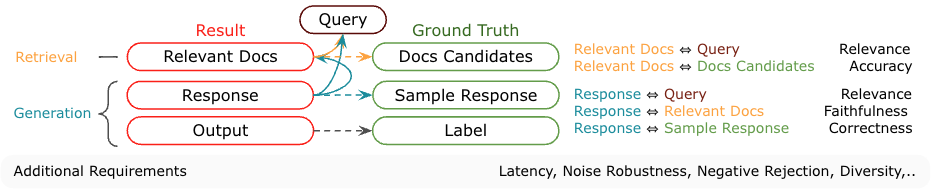
- The Target modular of Auepora. The retrieval and generation components are highlighted in red and green, respectively.
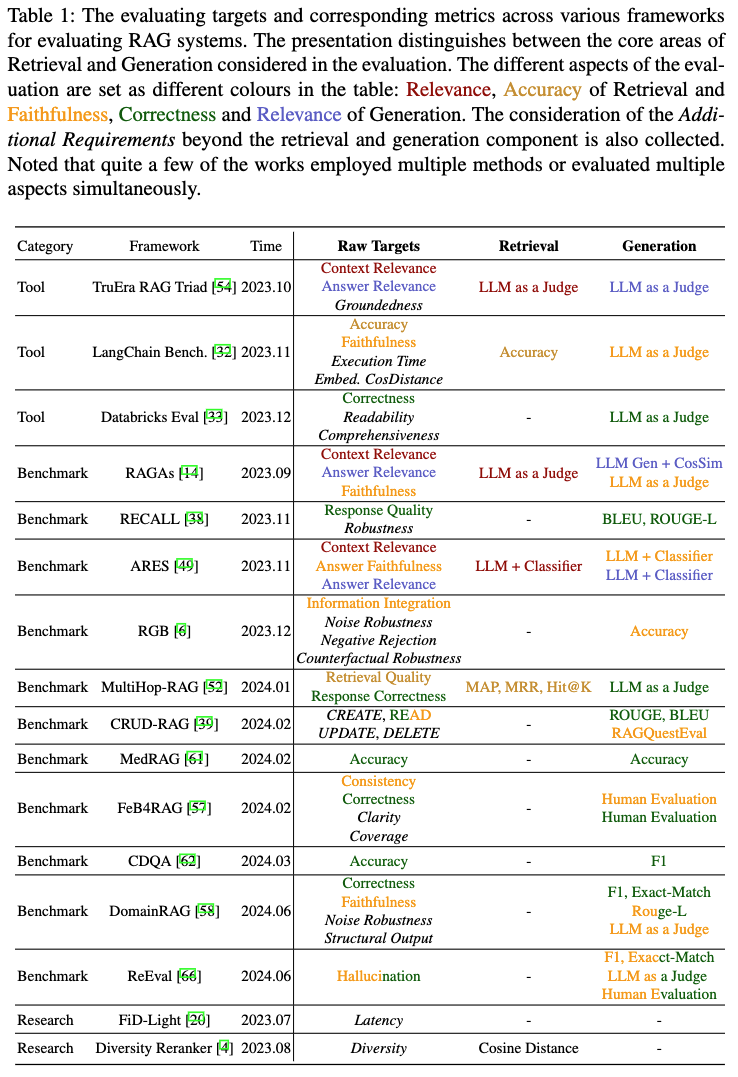
Reference Framework
Citation
If you find this paper or repository helpful, please consider citing our work:
@InProceedings{Yu2025,
    author    = {Yu, Hao and Gan, Aoran and Zhang, Kai and Tong, Shiwei and Liu, Qi and Liu, Zhaofeng},
    booktitle = {Big Data},
    title     = {Evaluation of Retrieval-Augmented Generation: A Survey},
    year      = {2025},
    address   = {Singapore},
    editor    = {Zhu, Wenwu and Xiong, Hui and Cheng, Xiuzhen and Cui, Lizhen and Dou, Zhicheng and Dong, Junyu and Pang, Shanchen and Wang, Li and Kong, Lanju and Chen, Zhenxiang},
    pages     = {102--120},
    publisher = {Springer Nature Singapore},
    isbn      = {978-981-96-1024-2},
}
@misc{gan2025retrievalaugmentedgenerationevaluation,
    title={Retrieval Augmented Generation Evaluation in the Era of Large Language Models: A Comprehensive Survey},
    author={Aoran Gan and Hao Yu and Kai Zhang and Qi Liu and Wenyu Yan and Zhenya Huang and Shiwei Tong and Guoping Hu},
    year={2025},
    eprint={2504.14891},
    archivePrefix={arXiv},
    primaryClass={cs.CL},
    url={https://arxiv.org/abs/2504.14891},
}
Citation for benchmarks: benchmarks.bib
Call for Contributions
We welcome contributions to this repository, including new benchmarks, datasets, and evaluation metrics. If you have any suggestions or would like to collaborate, please open an issue or pull request.
Changelog
- 2024-05-11: Initial release of the paper and repository.
- 2024-06-25: Acceptance of the paper by the 2024 CCF Big Data.
- 2024-06-30: Add two benchmarks: DomainRAG and ReEval.
- 2024-07-03: Update Arxiv version to v2.
- 2024-07-16: Add multiple new benchmarks and research papers to the reference table. Update existing paper links.
- 2025-04-21: Add new benchmarks for RAG system.
Contributors

5 commits
Similar repos


Languages
TeX
100.0%
The official repository for the paper: Evaluation of Retrieval-Augmented Generation: A Survey.
TeX
200
5 commits
updated Apr 25, 2025
README
Awesome RAG Evaluation
English | 简体中文
The official repository for the paper: Evaluation of Retrieval-Augmented Generation: A Survey Arxiv. This paper has been accepted by the 2024 CCF Big Data.
Abstract
Retrieval-Augmented Generation (RAG) has recently gained traction in natural language processing. Numerous studies and real-world applications are leveraging its ability to enhance generative models through external information retrieval. Evaluating these RAG systems, however, poses unique challenges due to their hybrid structure and reliance on dynamic knowledge sources. To better understand these challenges, we conduct A Unified Evaluation Process of RAG (Auepora) and aim to provide a comprehensive overview of the evaluation and benchmarks of RAG systems. Specifically, we examine and compare several quantifiable metrics of the Retrieval and Generation components, such as relevance, accuracy, and faithfulness, within the current RAG benchmarks, encompassing the possible output and ground truth pairs. We then analyze the various datasets and metrics, discuss the limitations of current benchmarks, and suggest potential directions to advance the field of RAG benchmarks.
Analysis Framework for Evaluating RAG Systems
- The Target modular of Auepora. The retrieval and generation components are highlighted in red and green, respectively.
Reference Framework
Citation
If you find this paper or repository helpful, please consider citing our work:
@InProceedings{Yu2025,
    author    = {Yu, Hao and Gan, Aoran and Zhang, Kai and Tong, Shiwei and Liu, Qi and Liu, Zhaofeng},
    booktitle = {Big Data},
    title     = {Evaluation of Retrieval-Augmented Generation: A Survey},
    year      = {2025},
    address   = {Singapore},
    editor    = {Zhu, Wenwu and Xiong, Hui and Cheng, Xiuzhen and Cui, Lizhen and Dou, Zhicheng and Dong, Junyu and Pang, Shanchen and Wang, Li and Kong, Lanju and Chen, Zhenxiang},
    pages     = {102--120},
    publisher = {Springer Nature Singapore},
    isbn      = {978-981-96-1024-2},
}
@misc{gan2025retrievalaugmentedgenerationevaluation,
    title={Retrieval Augmented Generation Evaluation in the Era of Large Language Models: A Comprehensive Survey},
    author={Aoran Gan and Hao Yu and Kai Zhang and Qi Liu and Wenyu Yan and Zhenya Huang and Shiwei Tong and Guoping Hu},
    year={2025},
    eprint={2504.14891},
    archivePrefix={arXiv},
    primaryClass={cs.CL},
    url={https://arxiv.org/abs/2504.14891},
}
Citation for benchmarks: benchmarks.bib
Call for Contributions
We welcome contributions to this repository, including new benchmarks, datasets, and evaluation metrics. If you have any suggestions or would like to collaborate, please open an issue or pull request.
Changelog
- 2024-05-11: Initial release of the paper and repository.
- 2024-06-25: Acceptance of the paper by the 2024 CCF Big Data.
- 2024-06-30: Add two benchmarks: DomainRAG and ReEval.
- 2024-07-03: Update Arxiv version to v2.
- 2024-07-16: Add multiple new benchmarks and research papers to the reference table. Update existing paper links.
- 2025-04-21: Add new benchmarks for RAG system.
Similar repos
Contributors
5 commits
Languages
TeX
100.0%