Chat Your Doc is an experimental project aimed at exploring various applications based on LLM. Although it is nominally a chatbot project, its purpose is broader. The project explores various applications using tools such as LangChain, LlamaIndex. In the "Lab Apps" section, you can find many examples, including simple and complex ones. The project focuses on researching and exploring various LLM applications, while also incorporating other fields such as UX and computer vision. The "Lab App" section includes a table with links to various apps, descriptions, launch commands, and demos.
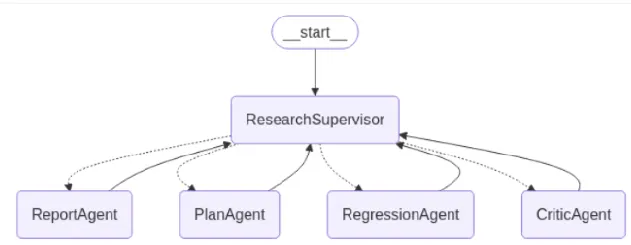

Also, take a look at a use-case known as Knowledge Center that leverages different RAG or Chunking techniques in this repository.
streamlit run simple/multimodal_chat.py --server.port 8000 --server.enableCORS falseFor OpenAI, set API-KEY to your environment variables.
export OPENAI_API_KEY="sk-$TJHGFHJDSFDGAFDFRTHT§$%$%&§%&"
conda env create -n chat-ur-doc -f environment.yml
conda activate chat-ur-doc
pip install -r requirements.txt
ref: https://python.langchain.com/docs/modules/data_connection/vectorstores/
Chroma, FAISS
pip install chromadb
pip install faiss-cpu
LLM fine-tuning step: Tokenizing
Chat with your PDF (Streamlit Demo)
LLM, LangChain Agent, Computer Vision
How to Use OpenAI Assistants (API)
Experience with the LangChain App Template
wine price app, prompt and query wine price. The application has been created, just need to create data, install Poetry and run it.
Full instructions for creating a LangChain App Template can be found here: LangChain App Template
Llama-Index: RAG with Vector and Summary
Multi-Retrievers with Vector and Summary pattern implementation.
Llama-Index: RAG with Vector and Summary by using Agent
Agent for Vector and Summary pattern implementation.
Intuitively create an agent from scratch with LangChain.
Intuitively create an agent from scratch with LlamaIndex.
Multi-Query Retrieval with RAG
Enhance query context with intermediate queries during RAG to improve information retrieval for the original query.
Explain how prio-reasoning works in LangChain(qa-chain with refine) and LlamaIndex (MultiStepQueryEngine).
Introduce the Multi-Query pattern in bundle and step-down solutions.
Introduce the hello,world version use-case with LangGraph, just simple example to kick off the topic.
Quick Tour: Ollama+Gemma+LangChain
Use ollama to deploy and use Gemma with langchain on local machine.
RAG with Hypothetical Document Embeddings(HyDE)
Hypothetical Document Embeddings, two-steps process of RAG. Implementation of HyDE retrieval by LlamaIndex, hybrid, local or remote LLMs.
LangChain: Use LLM Agent for World GPU Demand Prediction Report
Reflecting the analytical methods of the AI era, based on the Agent mechanism and generative AI, intelligently generates necessary information and code.
LangChain: Multi-User Conversation Support
By using some methods, make the conversation able to happen among multiple users, achieving the basic of a simple “group conversation”.
LangChain: History-Driven RAG Enhanced By LLM-Chain Routing LangChain
Using LLM to predict the routing of the chain and achieve Retrieval Augmented Generation with help of conversation history applying HyDE or refined standalone query.
LangChain: Multi-User Conversation Support(Follow-up)
A follow-up read: Use Cohere’s documents and a special field in additional_kwargsfeature to enhance the organization of information in multi-user conversation.
(Llama-Index Workflow)Translation Agent via Reflection Workflow
Implemention of Translation Agent: Agentic translation using reflection workflow with Llama-Index workflow framework.
Ollama Workaround: DeepSeek R1 Tool Support
Tool support of Ollama served DeepSeek R1 is still not very well, in this text there is a solution to workaround it and some how we can call tool according to the model response.
| App | Description | Launch | Demo |
|---|---|---|---|
| i-ask.sh | Simply ask & answer via OpenAI API | i-ask.sh "Who is Joe Biden?" | 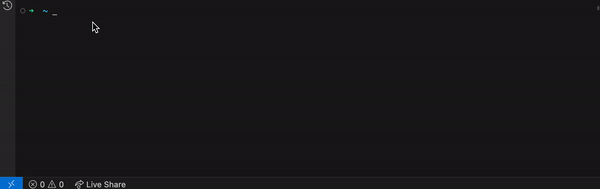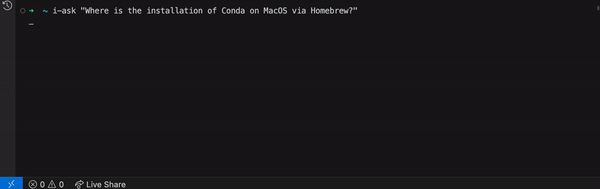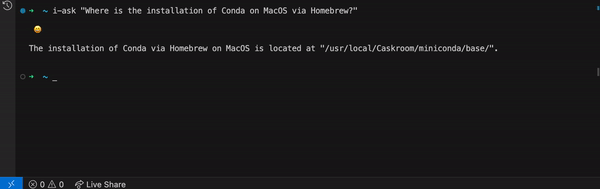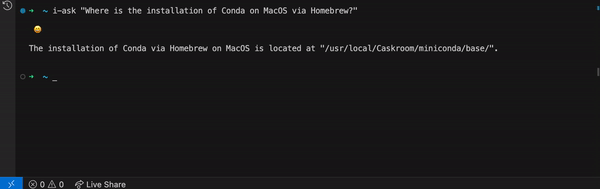 |
| chat_openai.py | Just one chat session | streamlit run simple/chat_openai.py --server.port 8000 --server.enableCORS false | 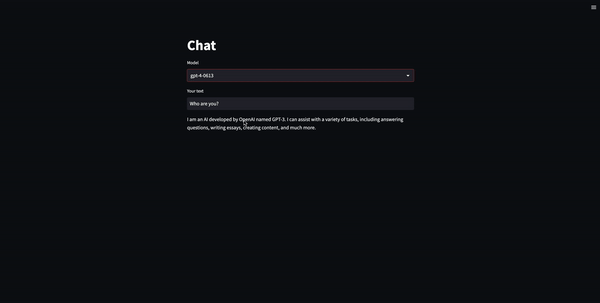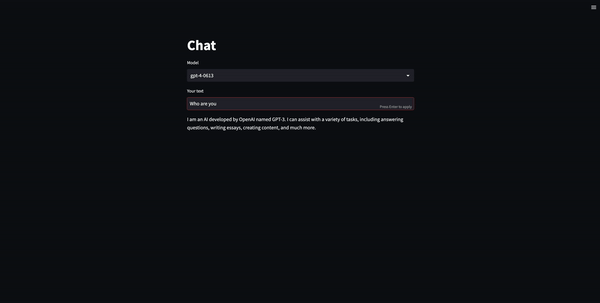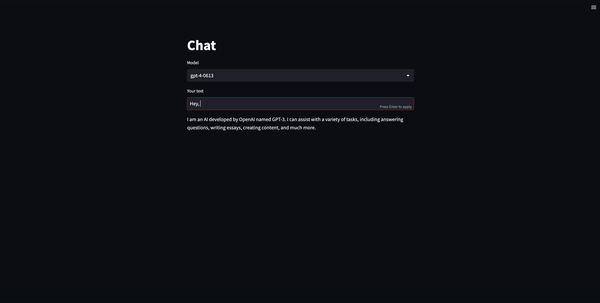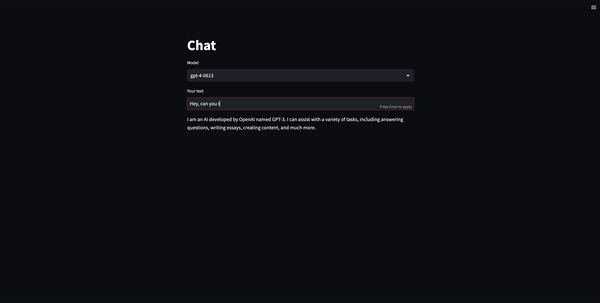 |
| open_api_llm_app.py | Use OpenAI LLM to answer simple question | streamlit run simple/open_api_llm_app.py --server.port 8001 --server.enableCORS false | 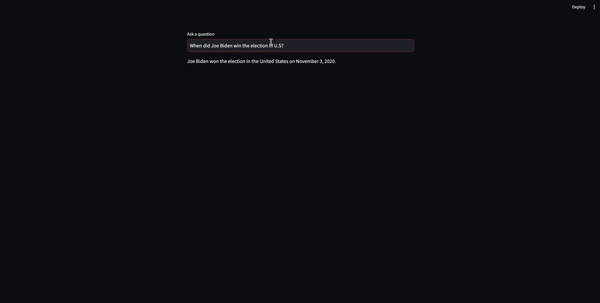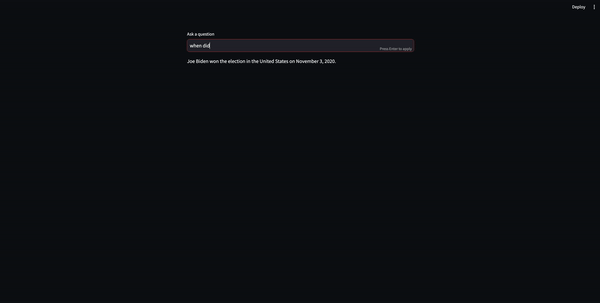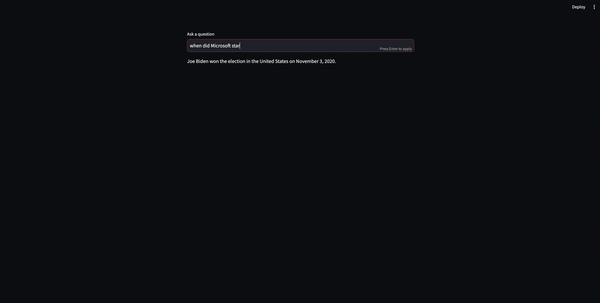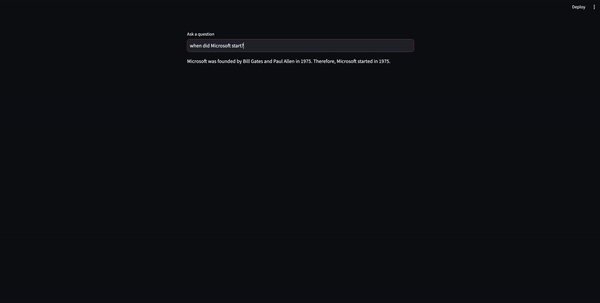 |
| read_html_app.py | Get html content and chunk | streamlit run simple/read_html_app.py --server.port 8002 --server.enableCORS false | 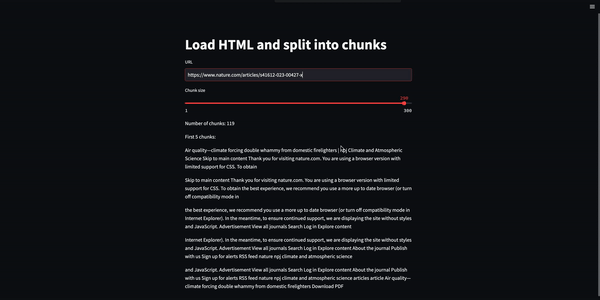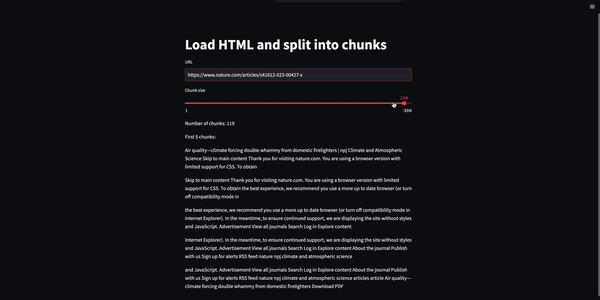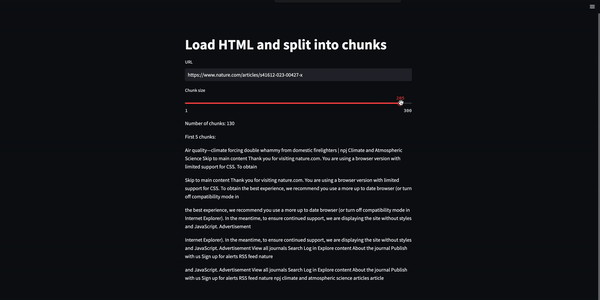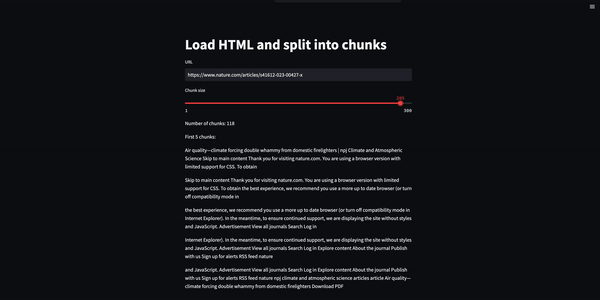 |
| chatbot.py | Basic chatbot | streamlit run simple/chatbot.py --server.port 8003 --server.enableCORS false | 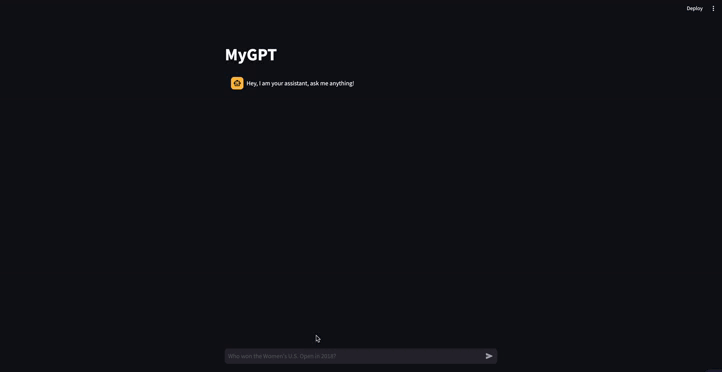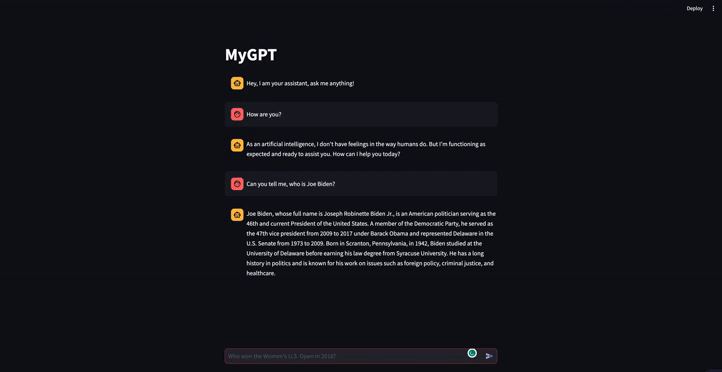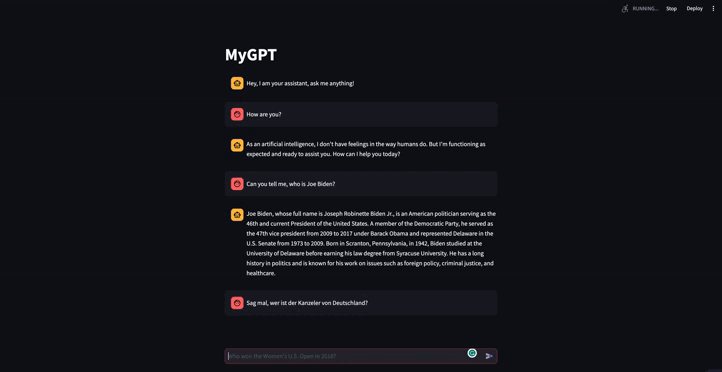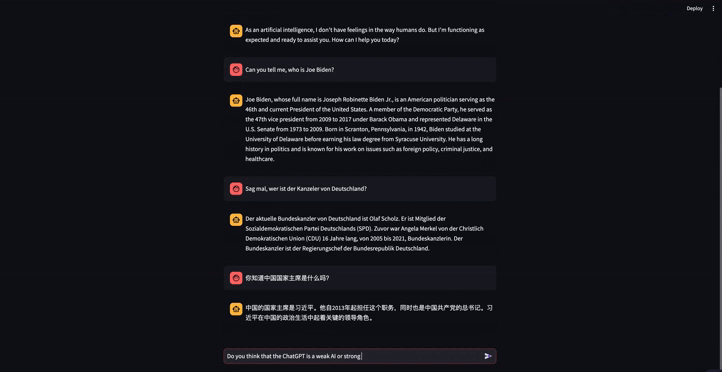 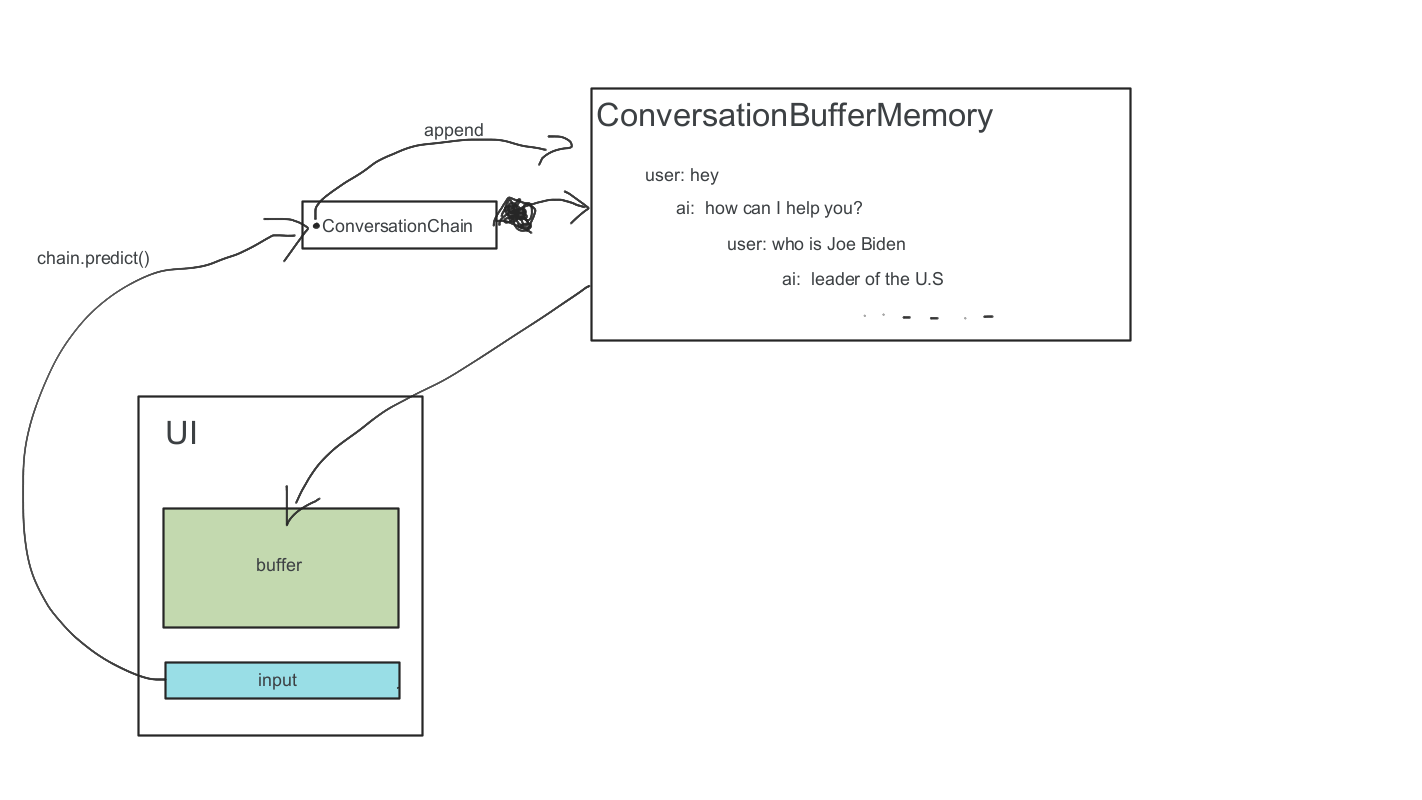 |
| retriever.py | Use concept of retriever and LangChain Expression Language (LCEL) | streamlit run simple/retriever.py --server.port 8004 --server.enableCORS false | 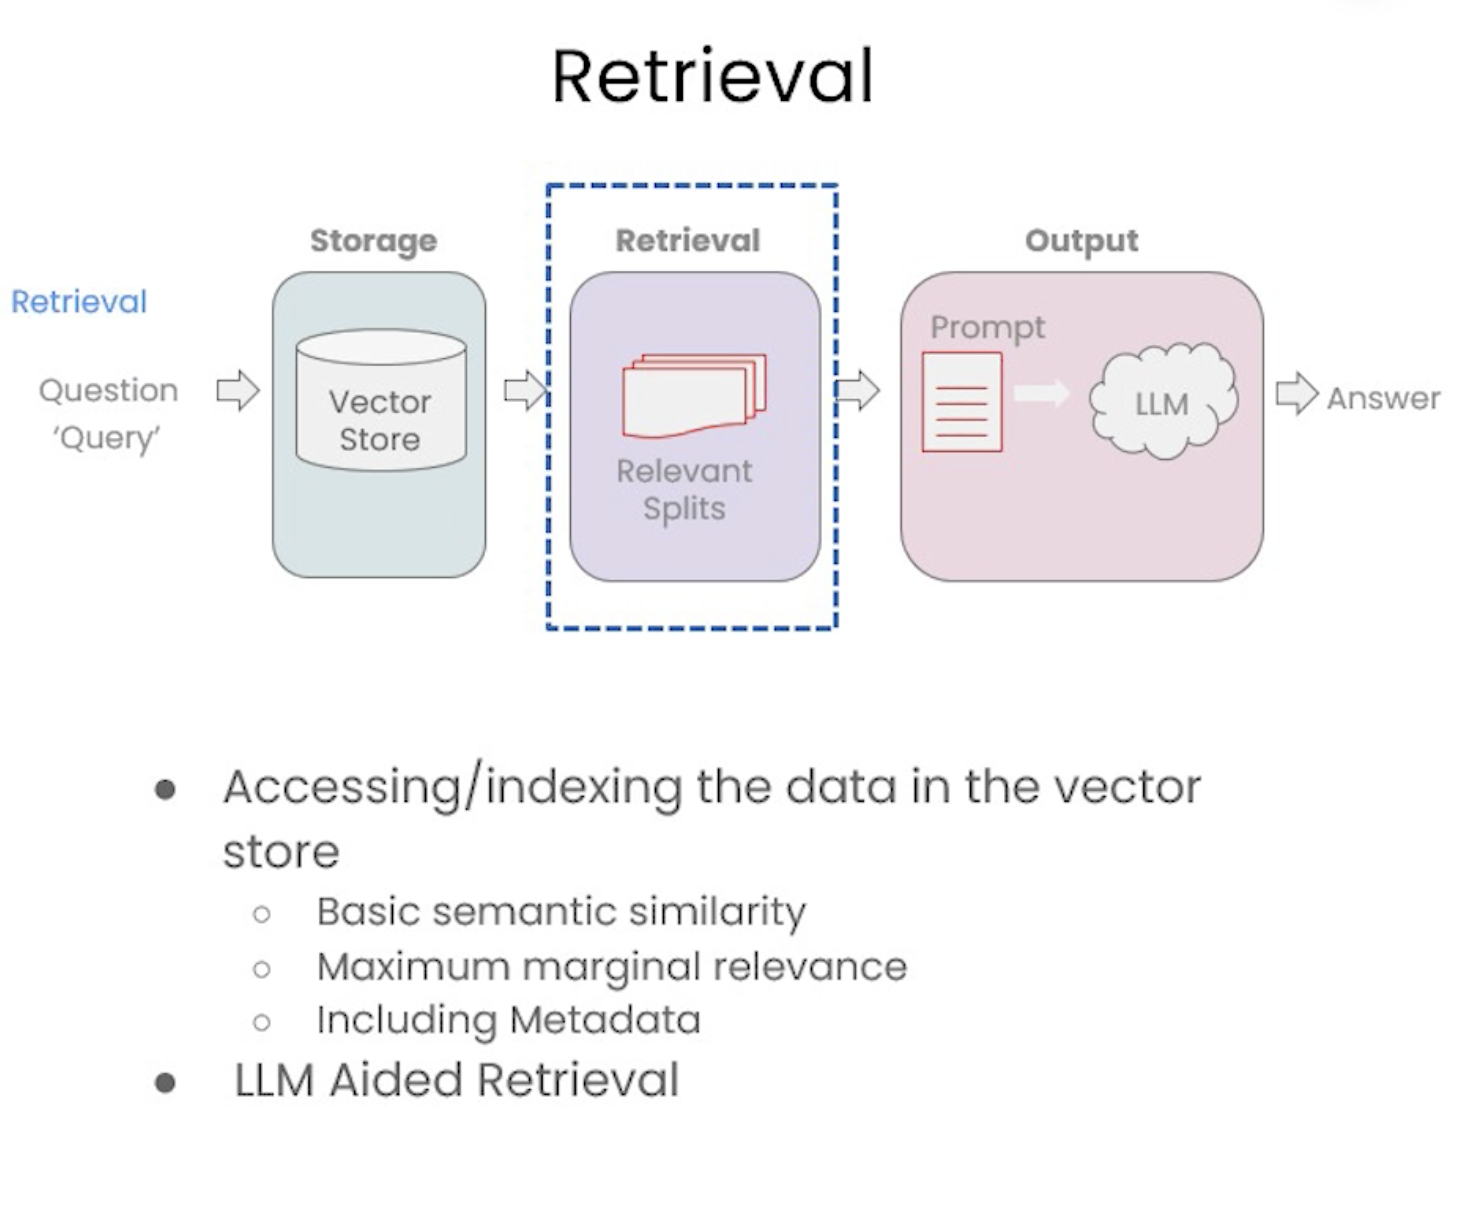 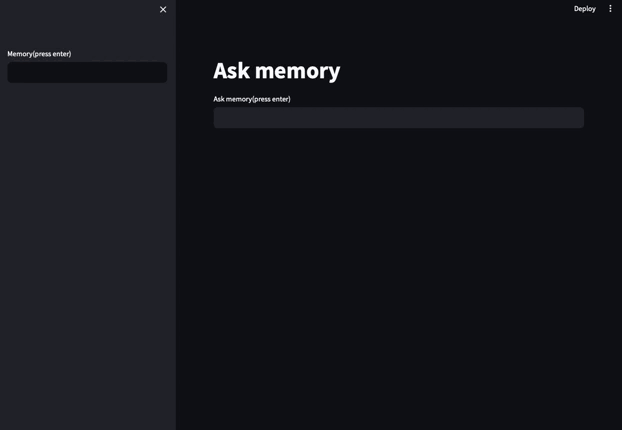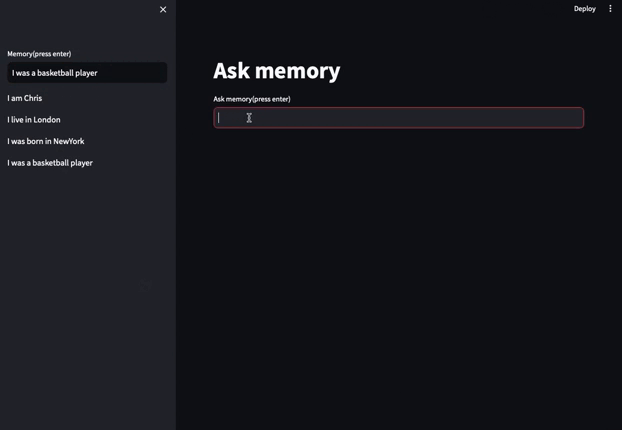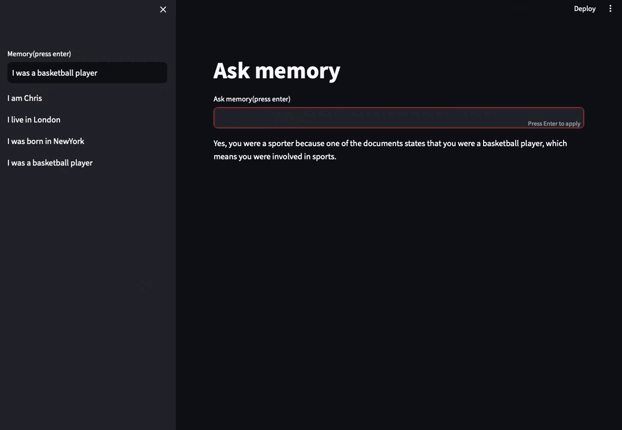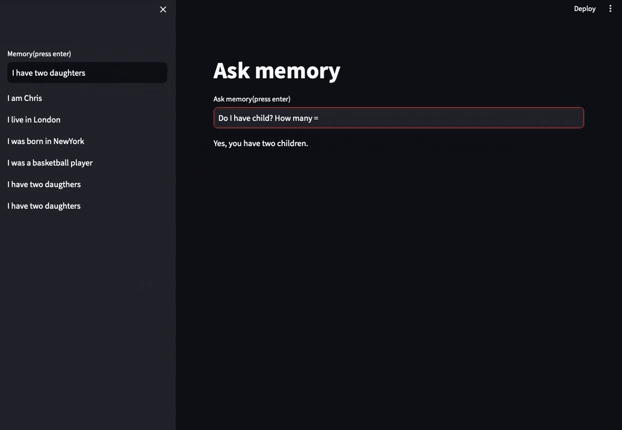 |
| hello_llamaindex.py | A very simple LlamaIndex to break ice of the story. | streamlit run simple/hello_llamaindex.py --server.port 8005 --server.enableCORS false | |
| llamaindex_context.py | A simple app of LlamaIndex, introduce of context for configuration, StorageContext, ServiceContext. | streamlit run simple/llamaindex_context.py --server.port 8006 --server.enableCORS false | |
| llamaindex_hub_simple.py | A simple app of LlamaIndex, introduce of load stuff from https://llamahub.ai/. | streamlit run simple/llamaindex_hub_simple.py --server.port 8007 --server.enableCORS false | |
| prio_reasoning_context.py | A simple app that based on RAG with Prio-Reasoning pattern in LlamaIndex or LangChain. | streamlit run simple/prio_reasoning_context.py --server.port 8008 --server.enableCORS false | read 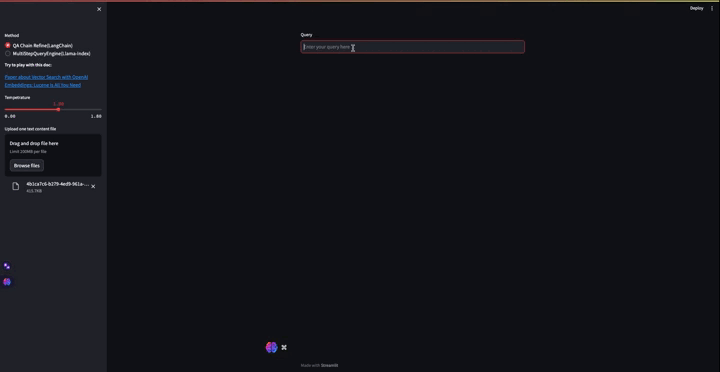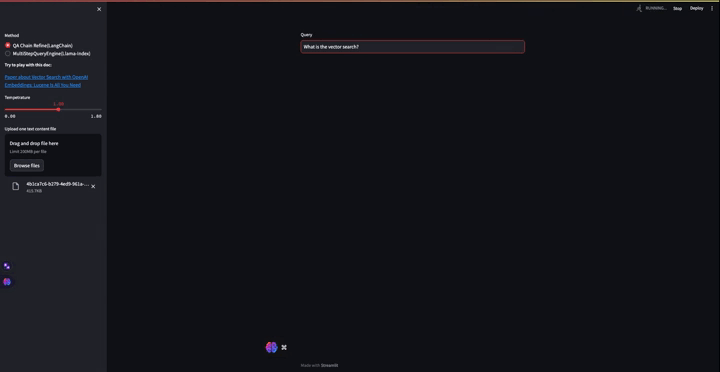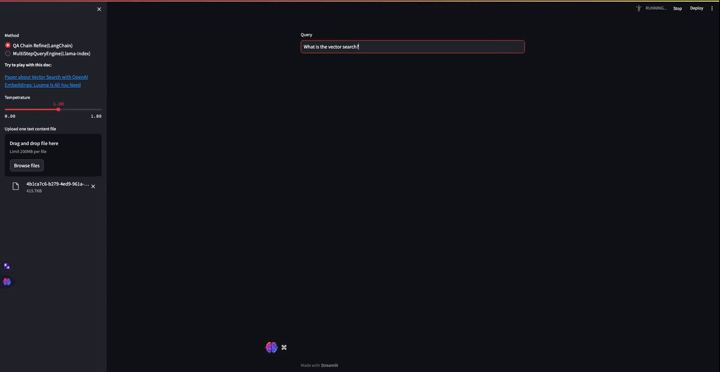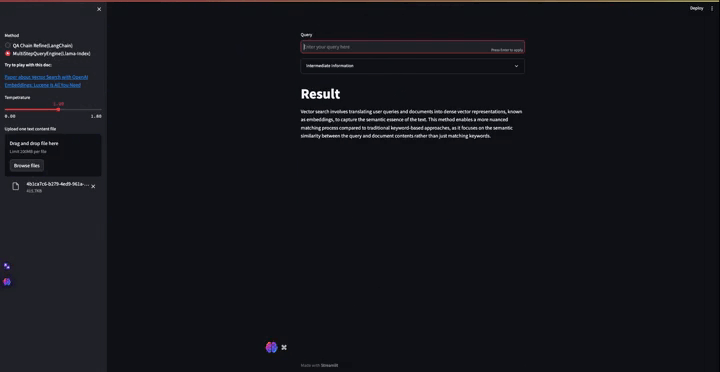 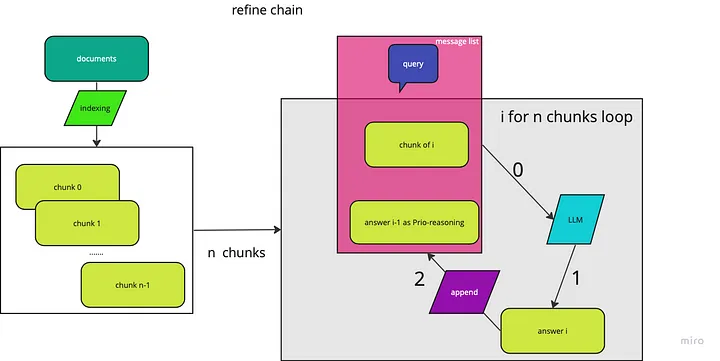 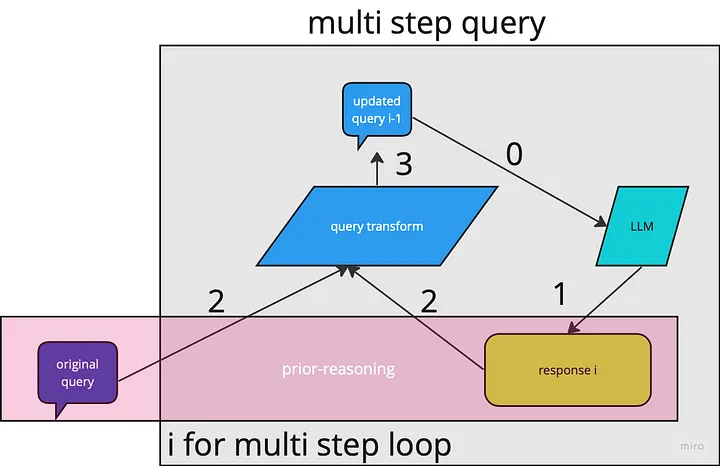 |
| ollama_gemma.py | A Ollama for Gemma integration with the langchain. | read 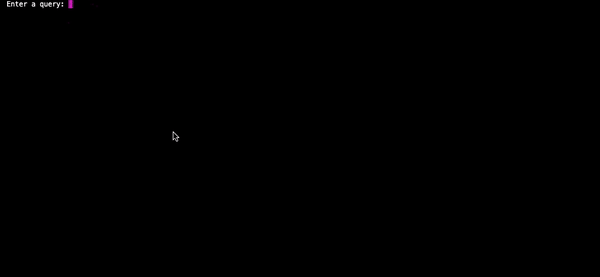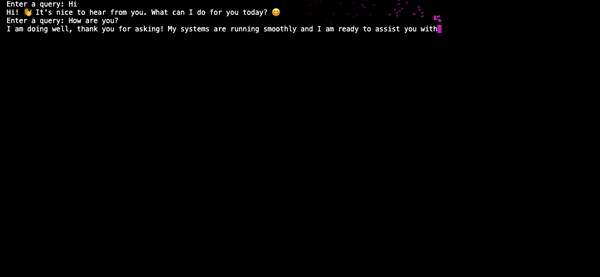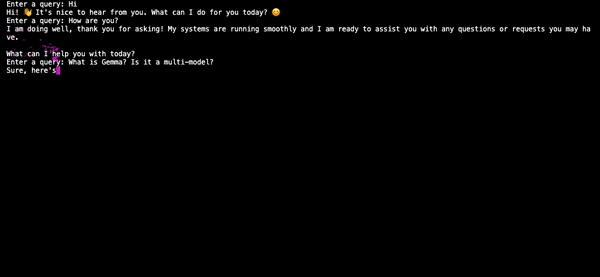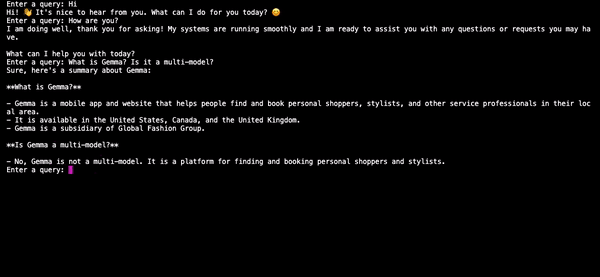 | |
| nvidia_vs_groq.py | Compare Nvidia API and Groq, by using llama2 and mixtral_8x7b | streamlit run simple/nvidia_vs_groq.py --server.port 8009 --server.enableCORS false | read 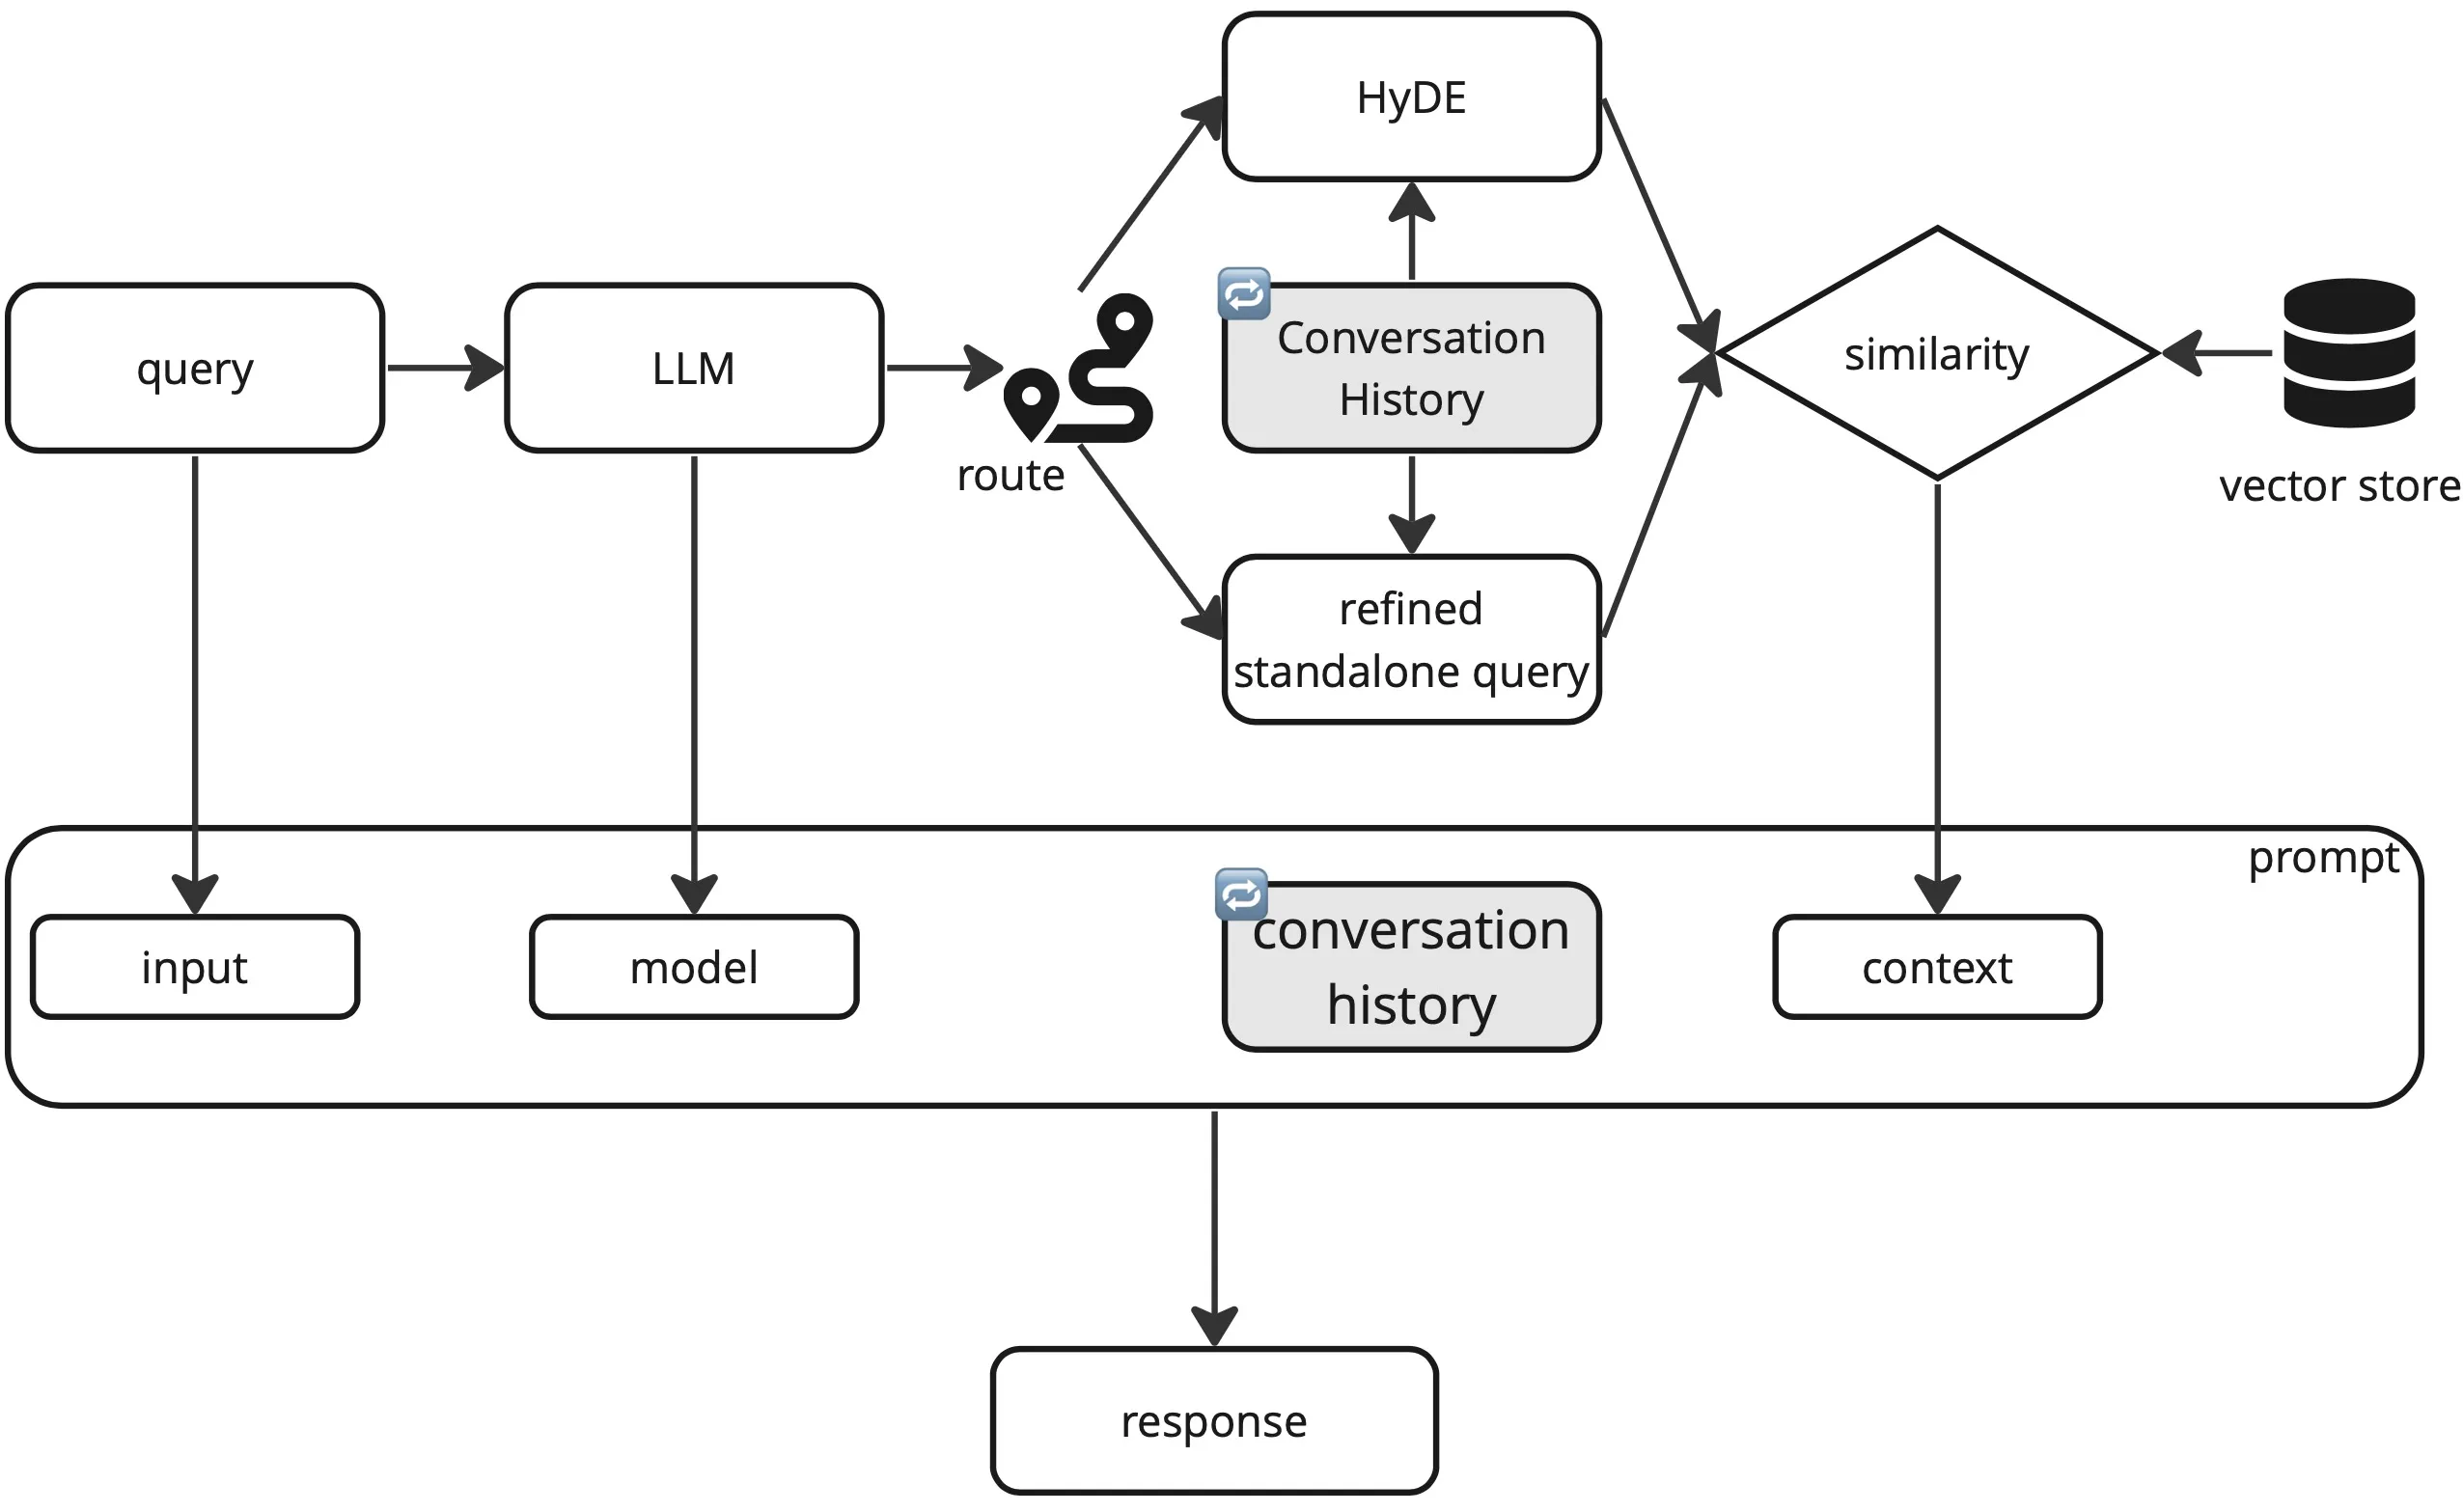 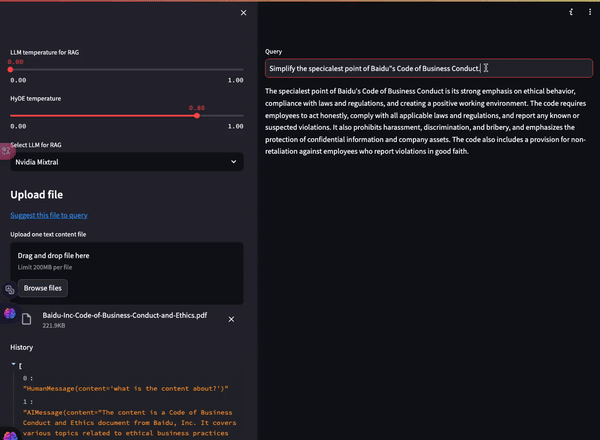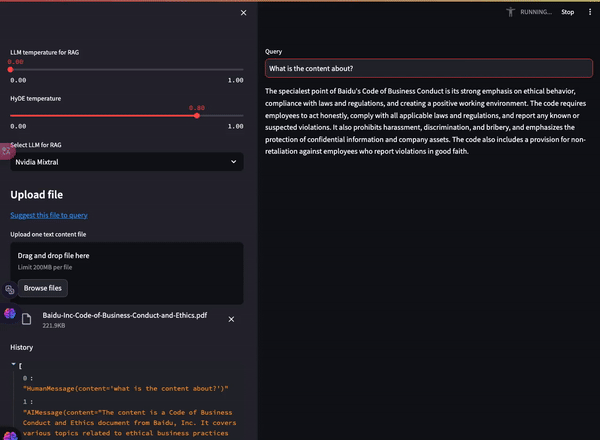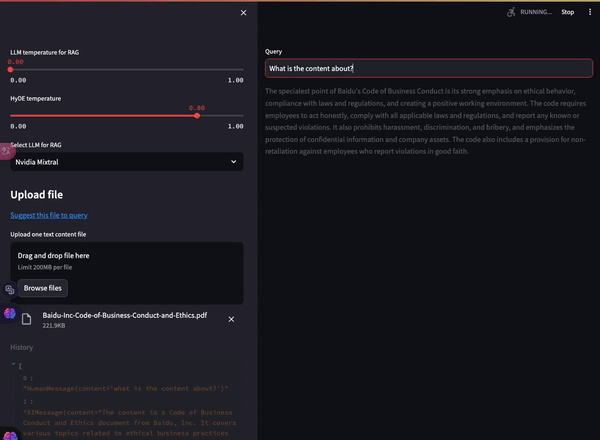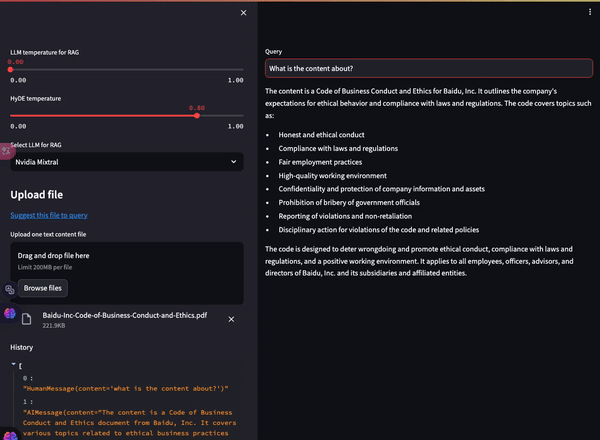 |
| llamaindex_workflow_reflection_flow.py | Implemention of Translation Agent: Agentic translation using reflection workflow with Llama-Index workflow framework | streamlit run simple/llamaindex_workflow_reflection_flow.py --server.port 8009 --server.enableCORS false | read 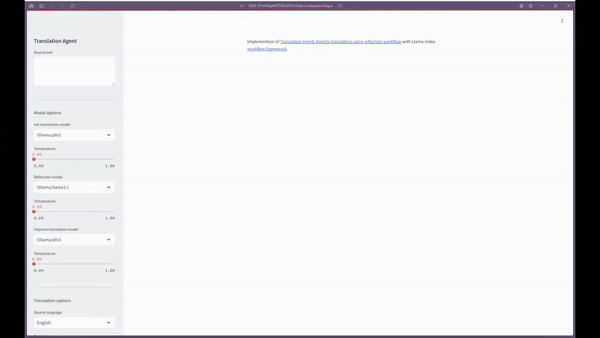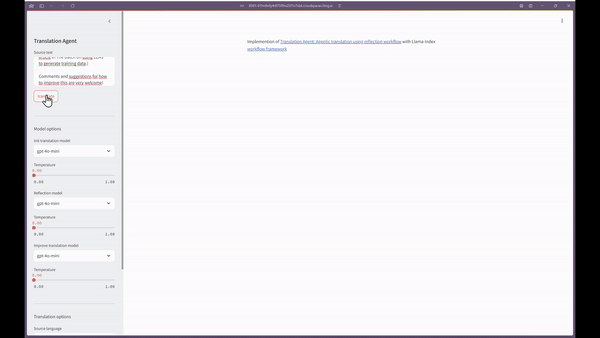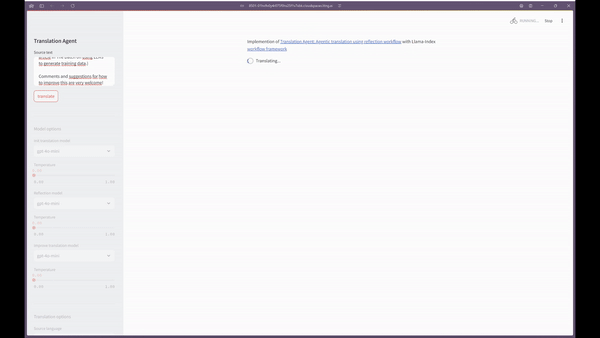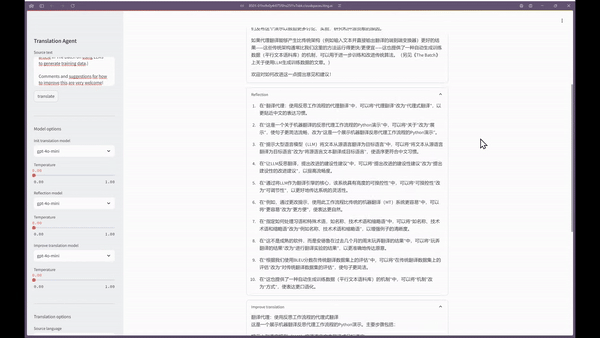 |
| langchain_citation_chain.py | (LangChain) Retrieval Augmented Generation with Citations, inspired by Llama-index version | Llama-index version | |
| lc_deepseek_tool_call.py | Use some workarounds to apply tool calling on Ollama served DeepSeek R1 | python simple/lc_deepseek_tool_call.py | Ollama Workaround: DeepSeek R1 Tool Support |
| li_deepseek_agent.py | LlamaIndex to apply ReAct with Ollama served DeepSeek R1 | python simple/li_deepseek_agent.py |
| App | Description | Launch | Demo |
|---|---|---|---|
| sim_app.py | Use the vector database to save file in chunks and retrieve similar content from the database | streamlit run intermediate/sim_app.py --server.port 8002 --server.enableCORS false | 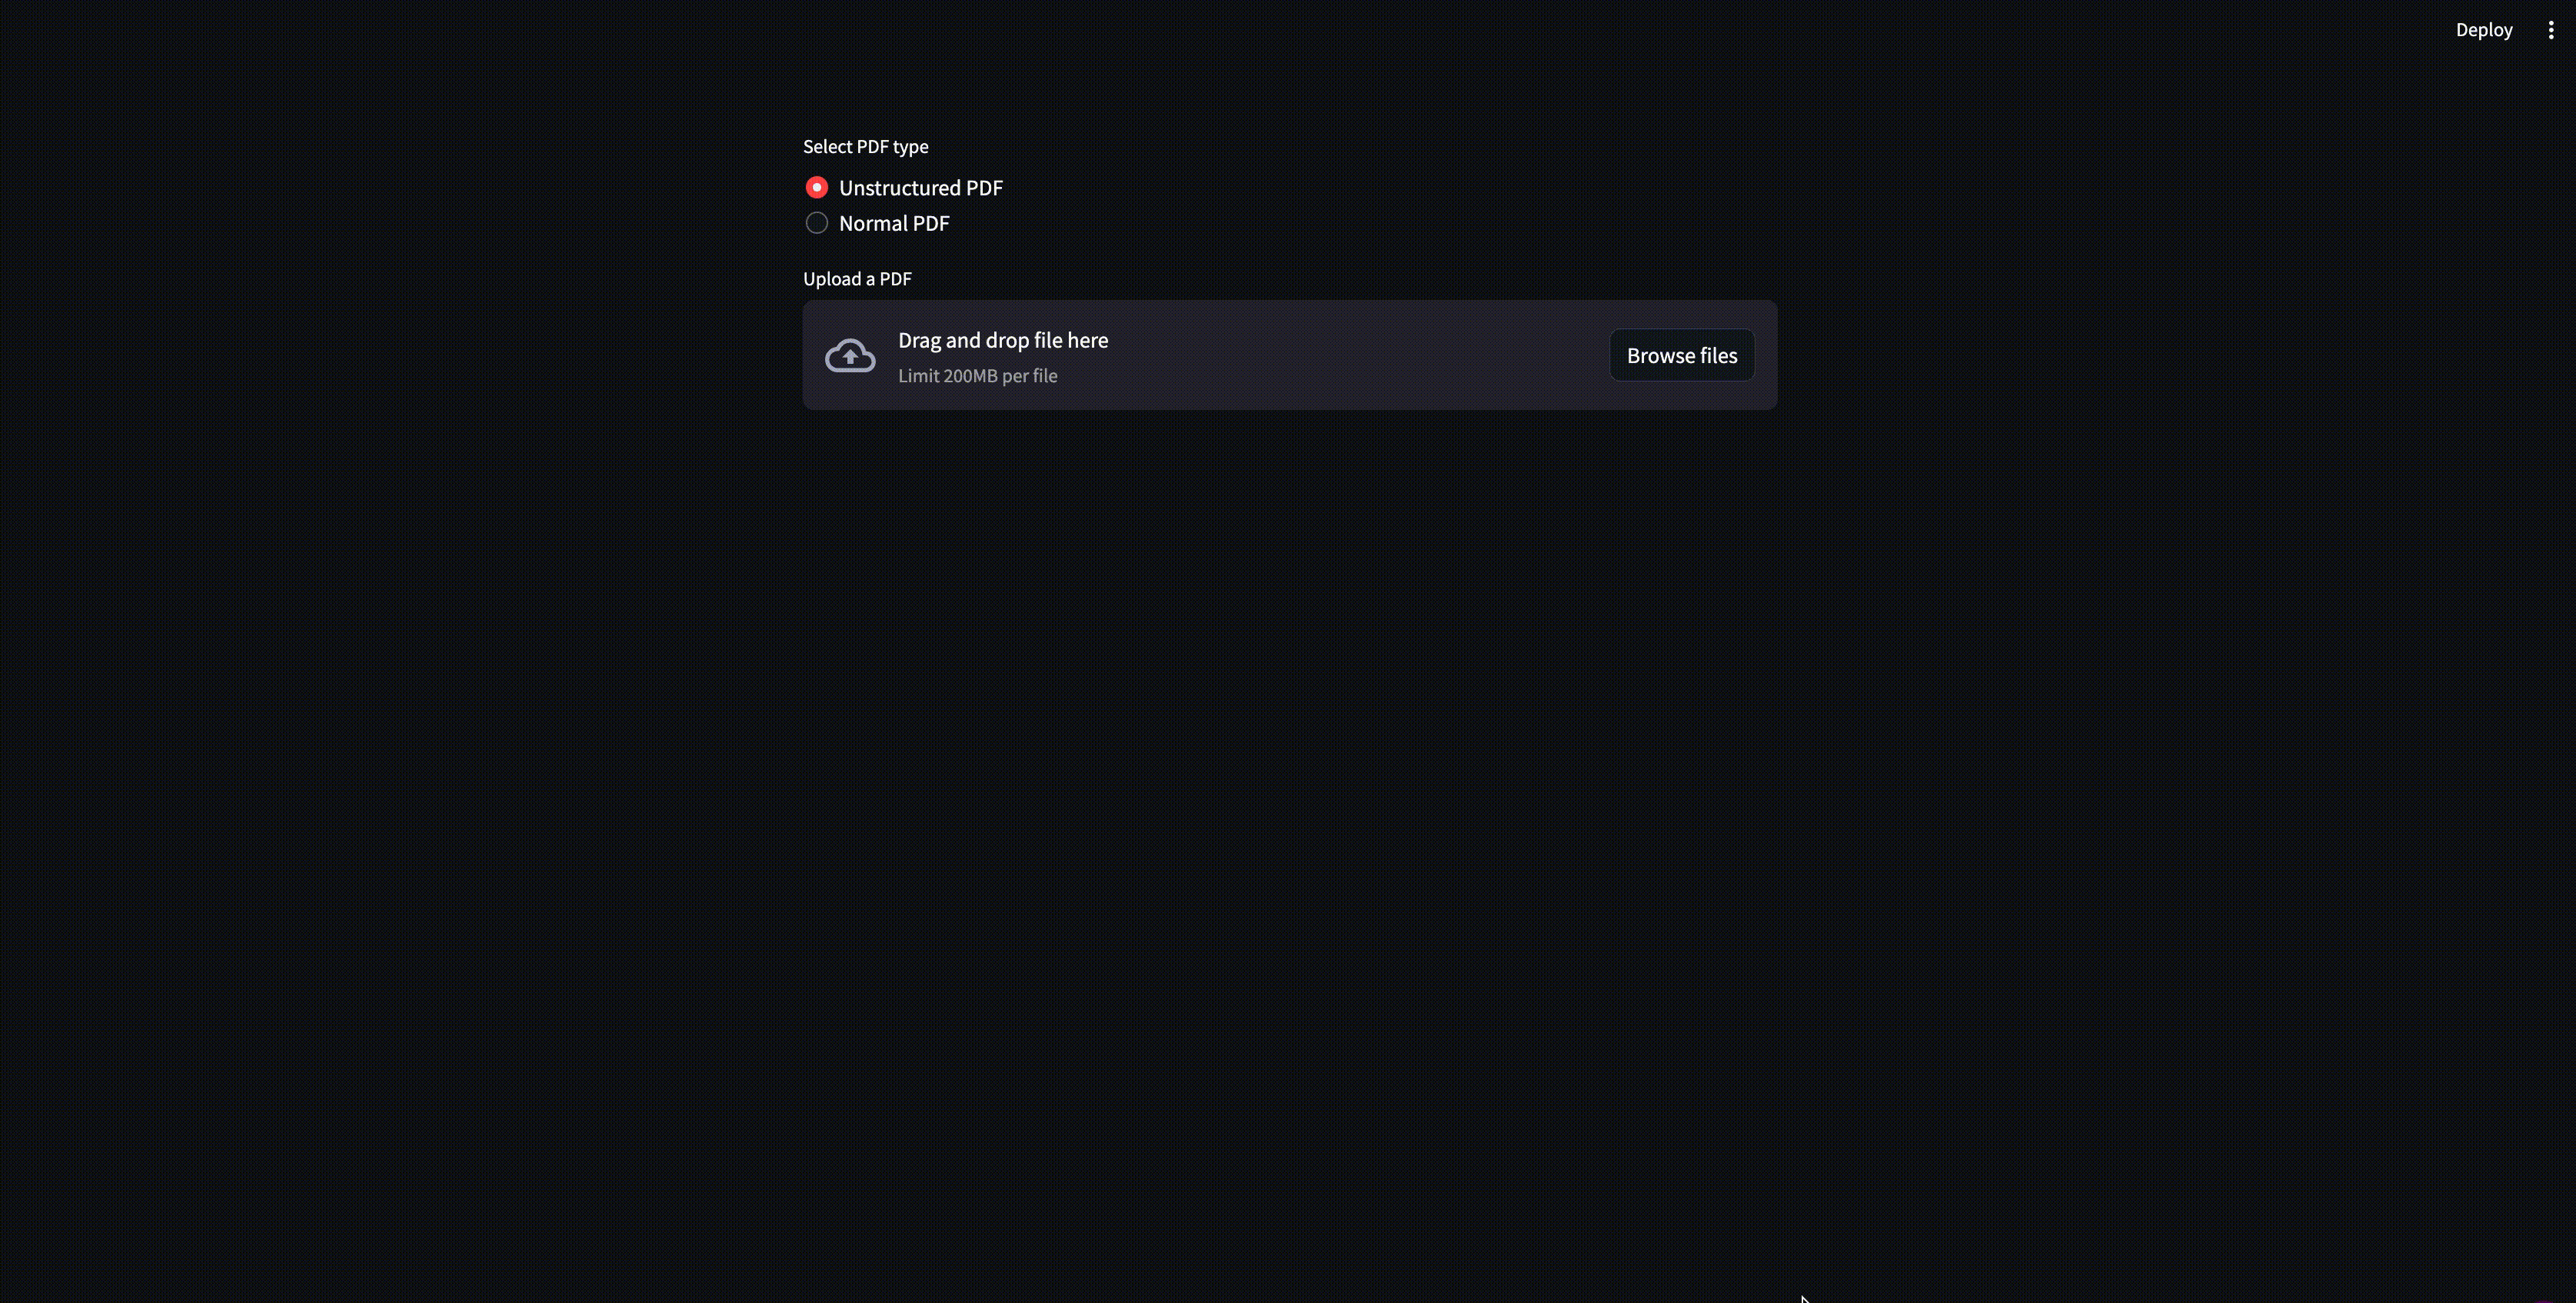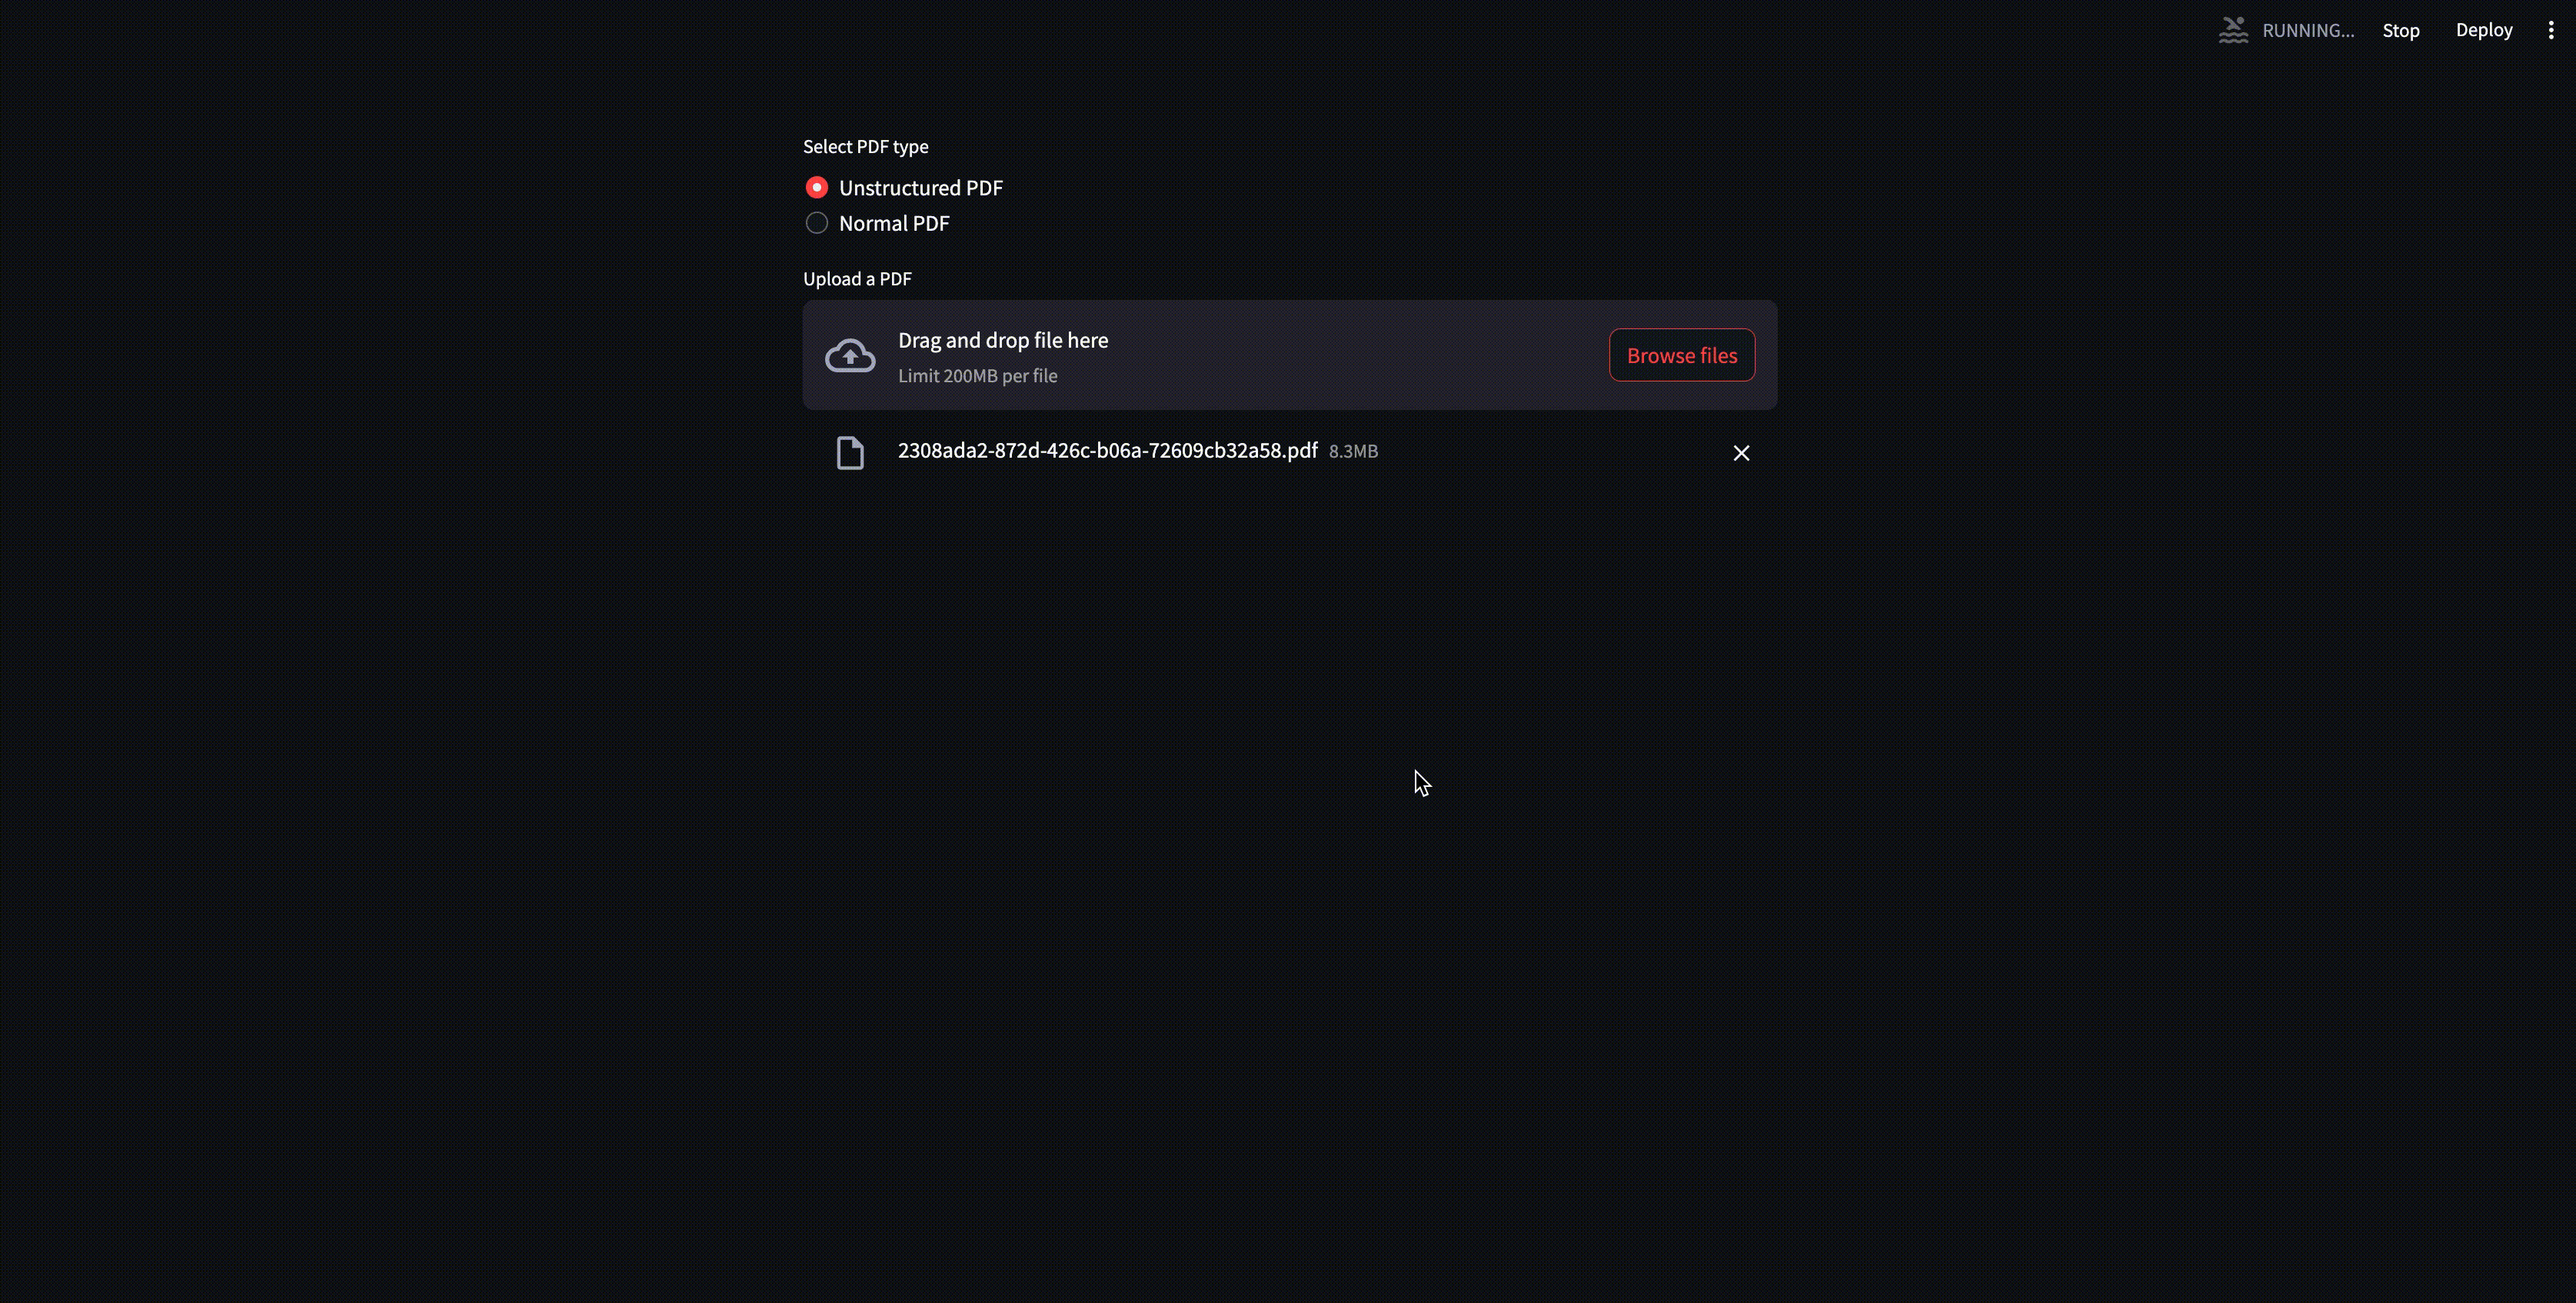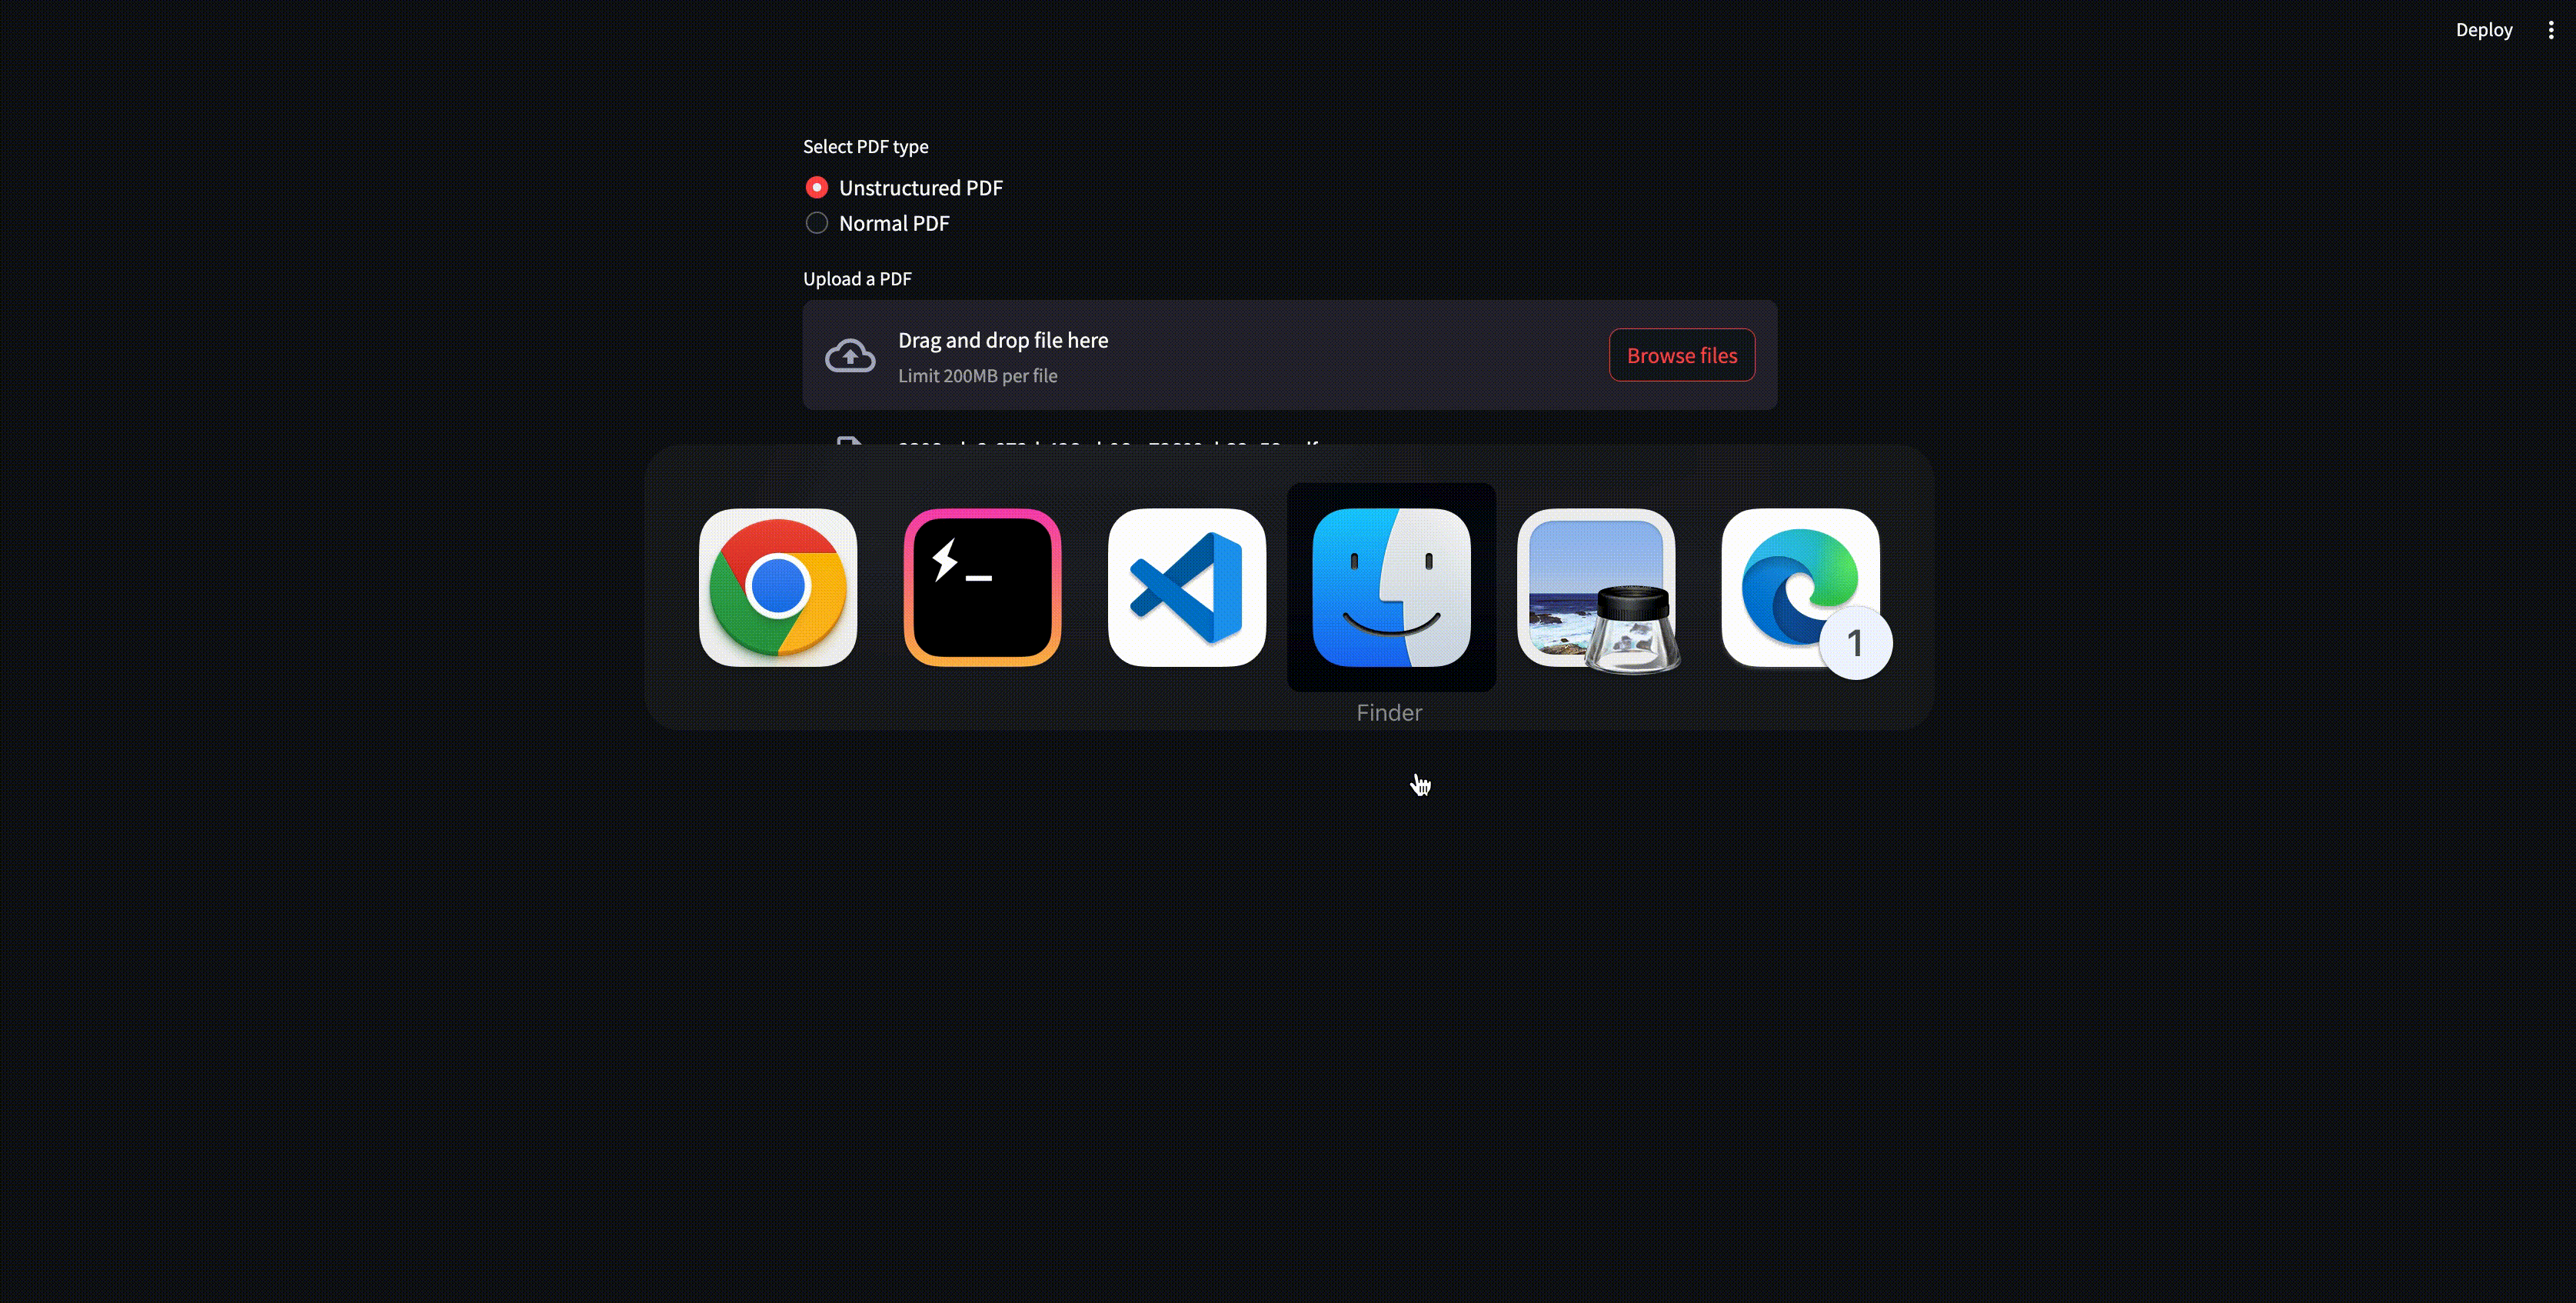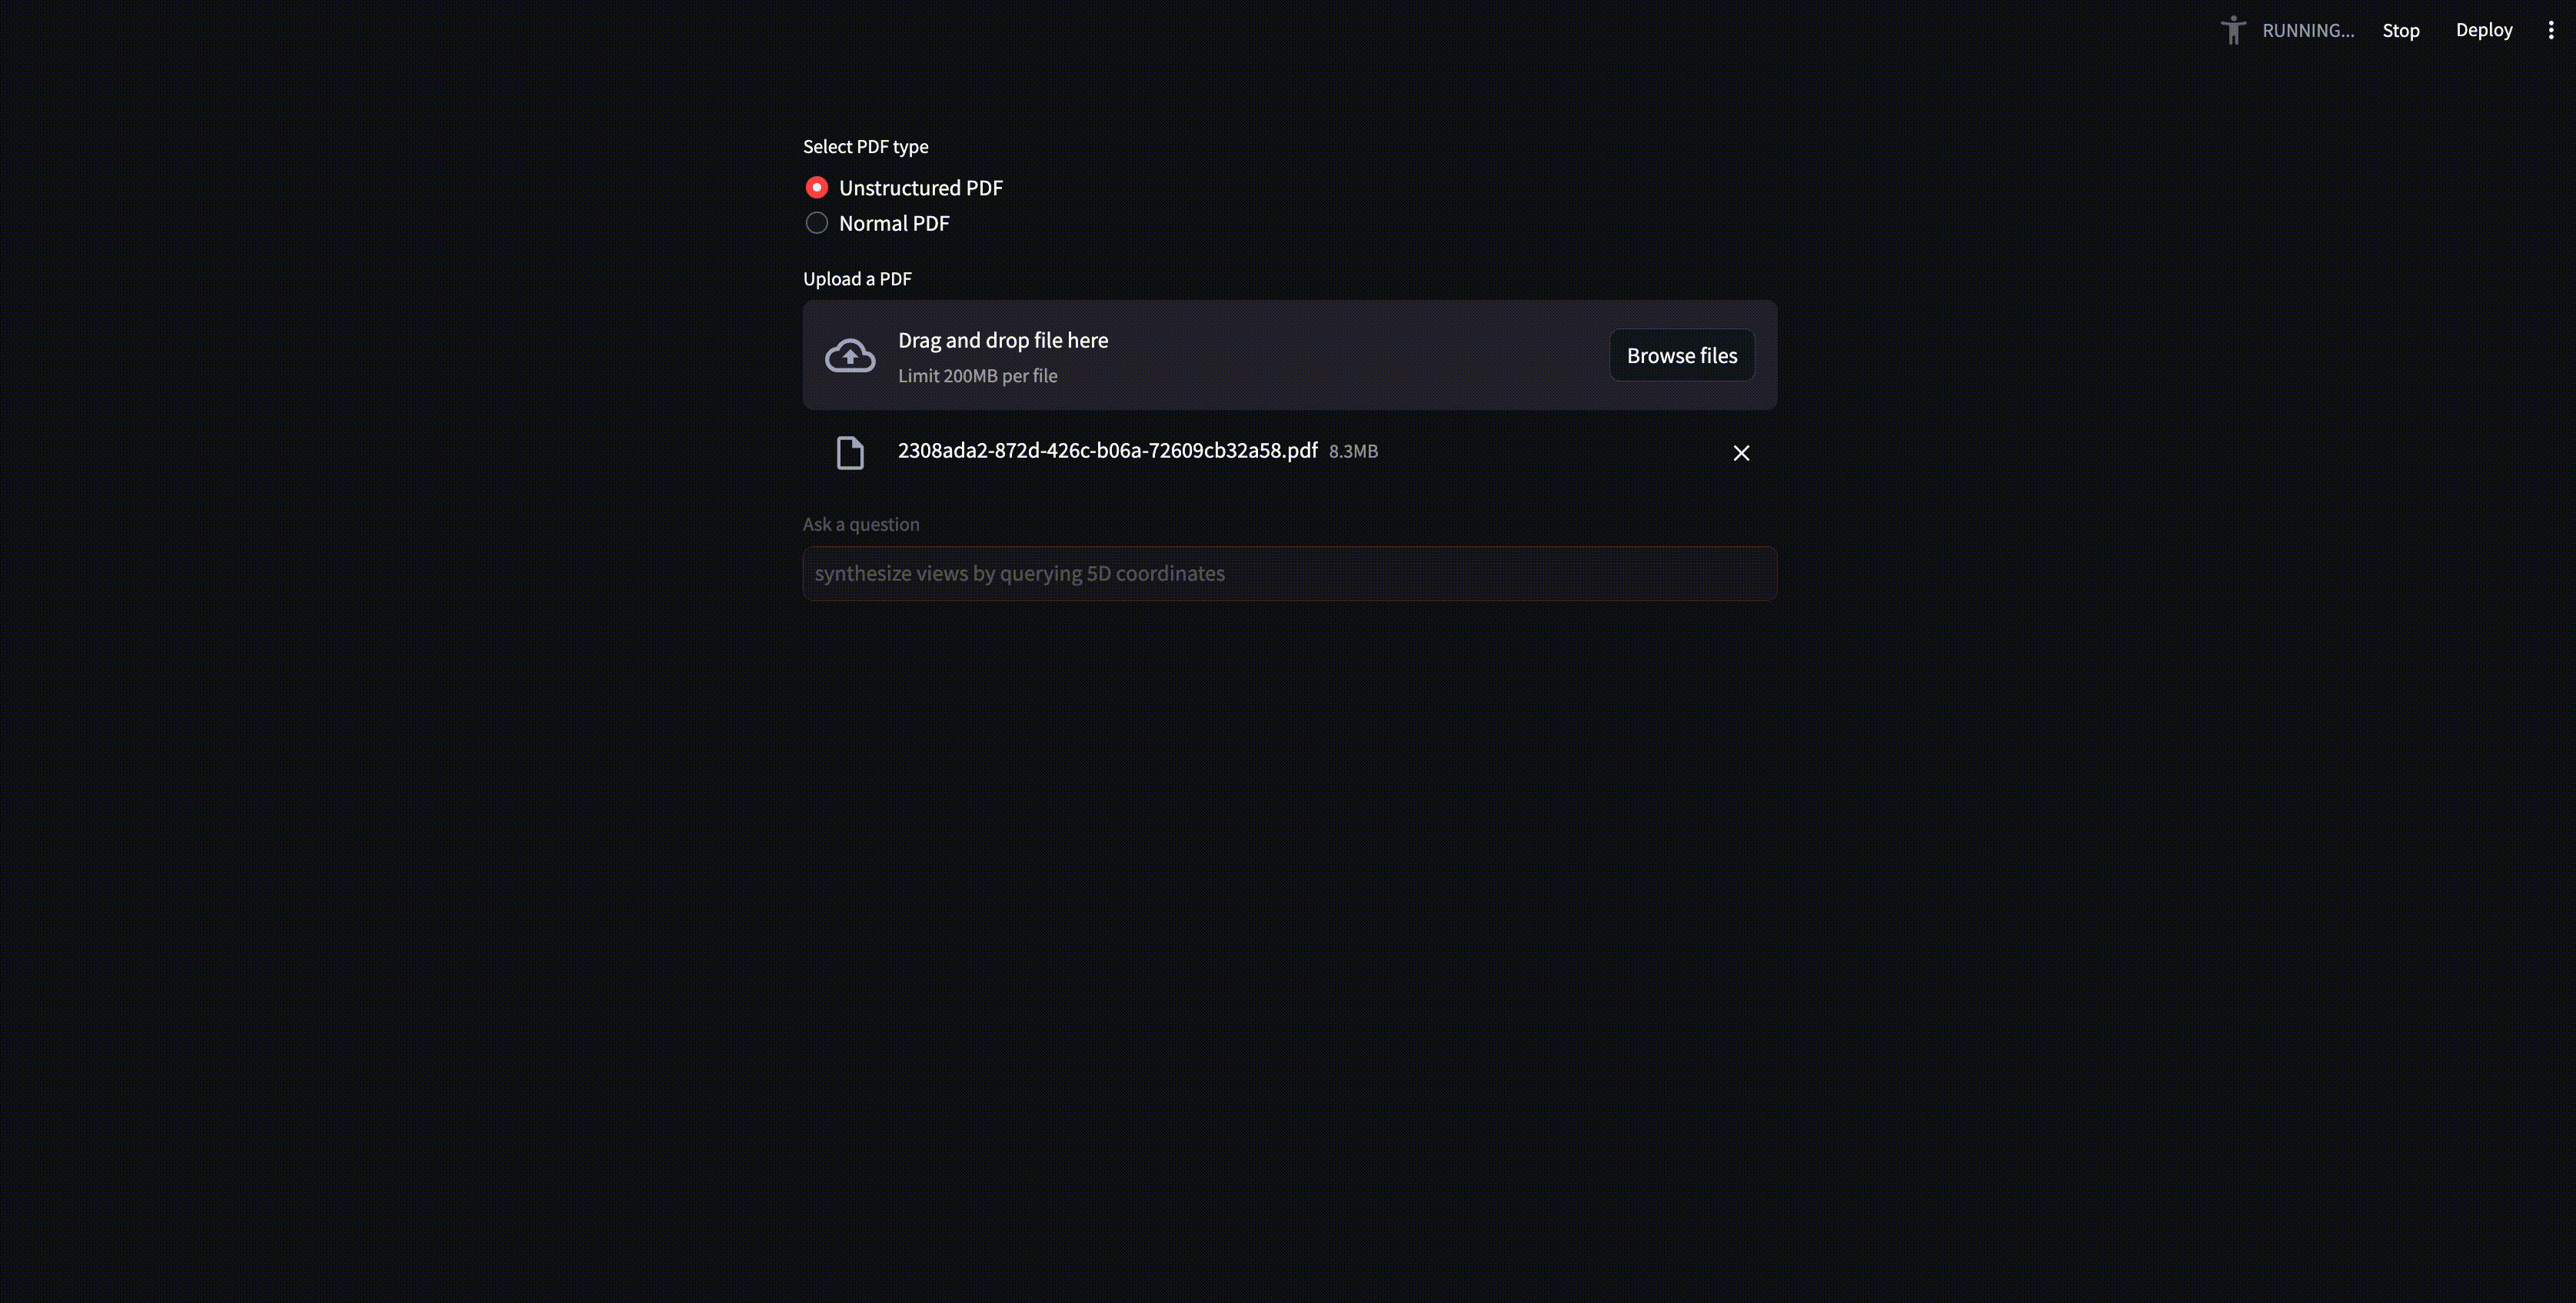 |
| llm_chain_translator_app.py | Use LLMChain to do language translation | streamlit run intermediate/llm_chain_translator_app.py --server.port 8003 --server.enableCORS false | 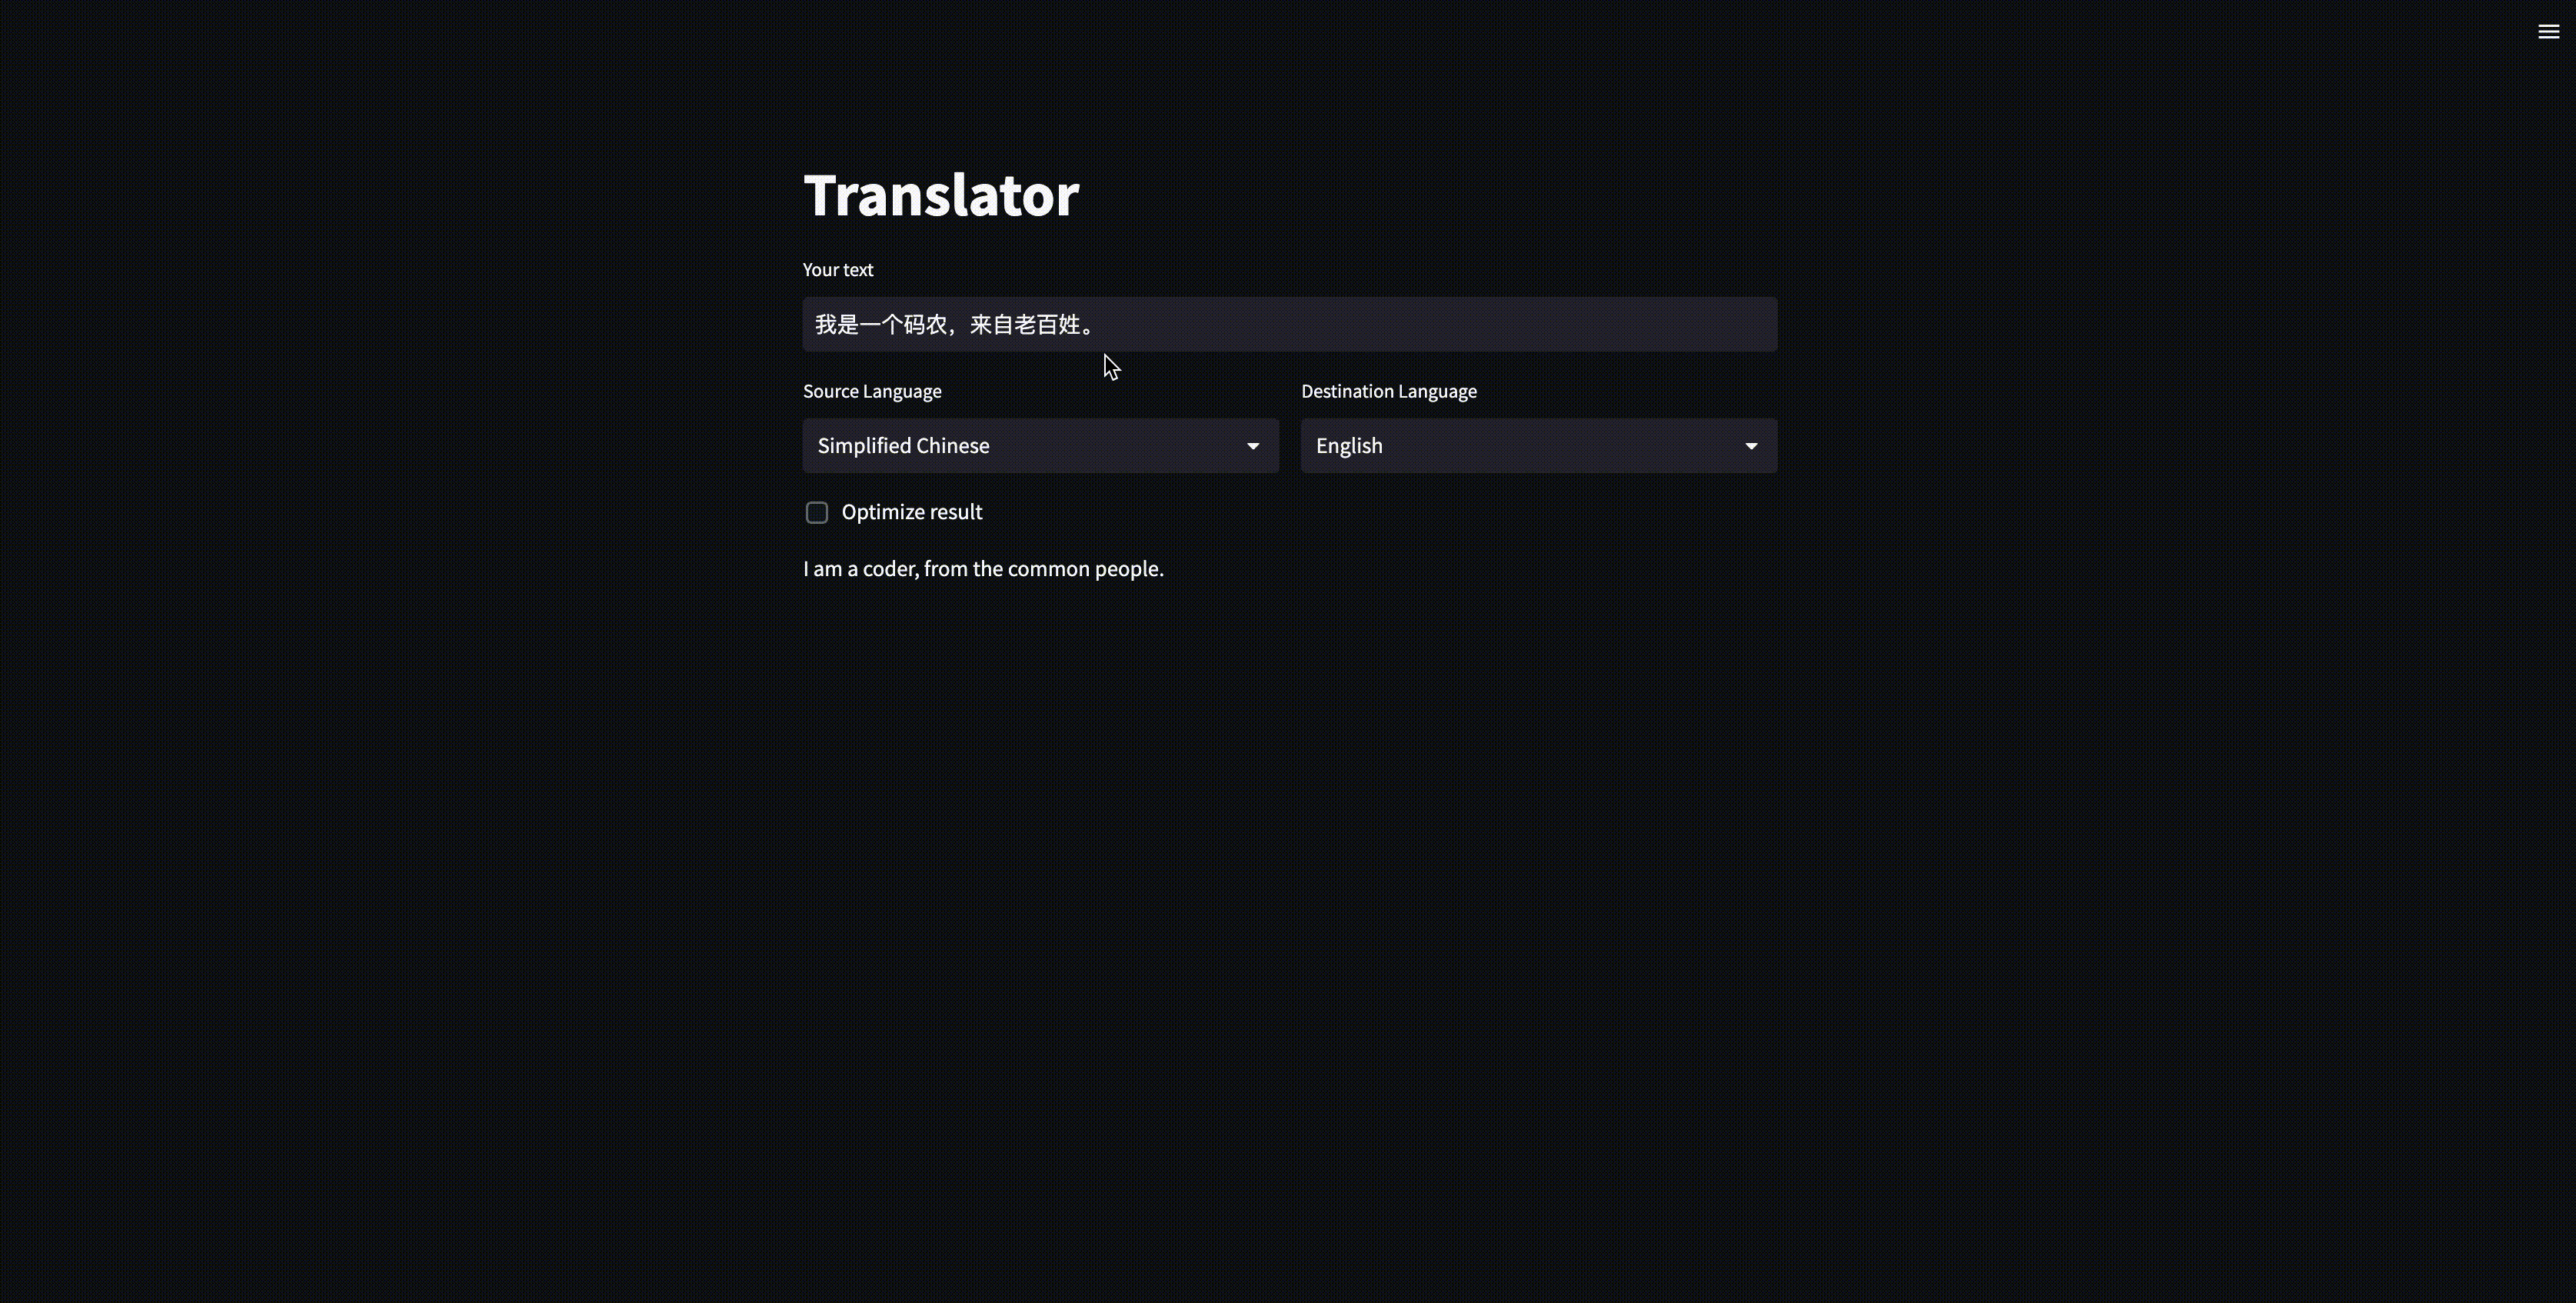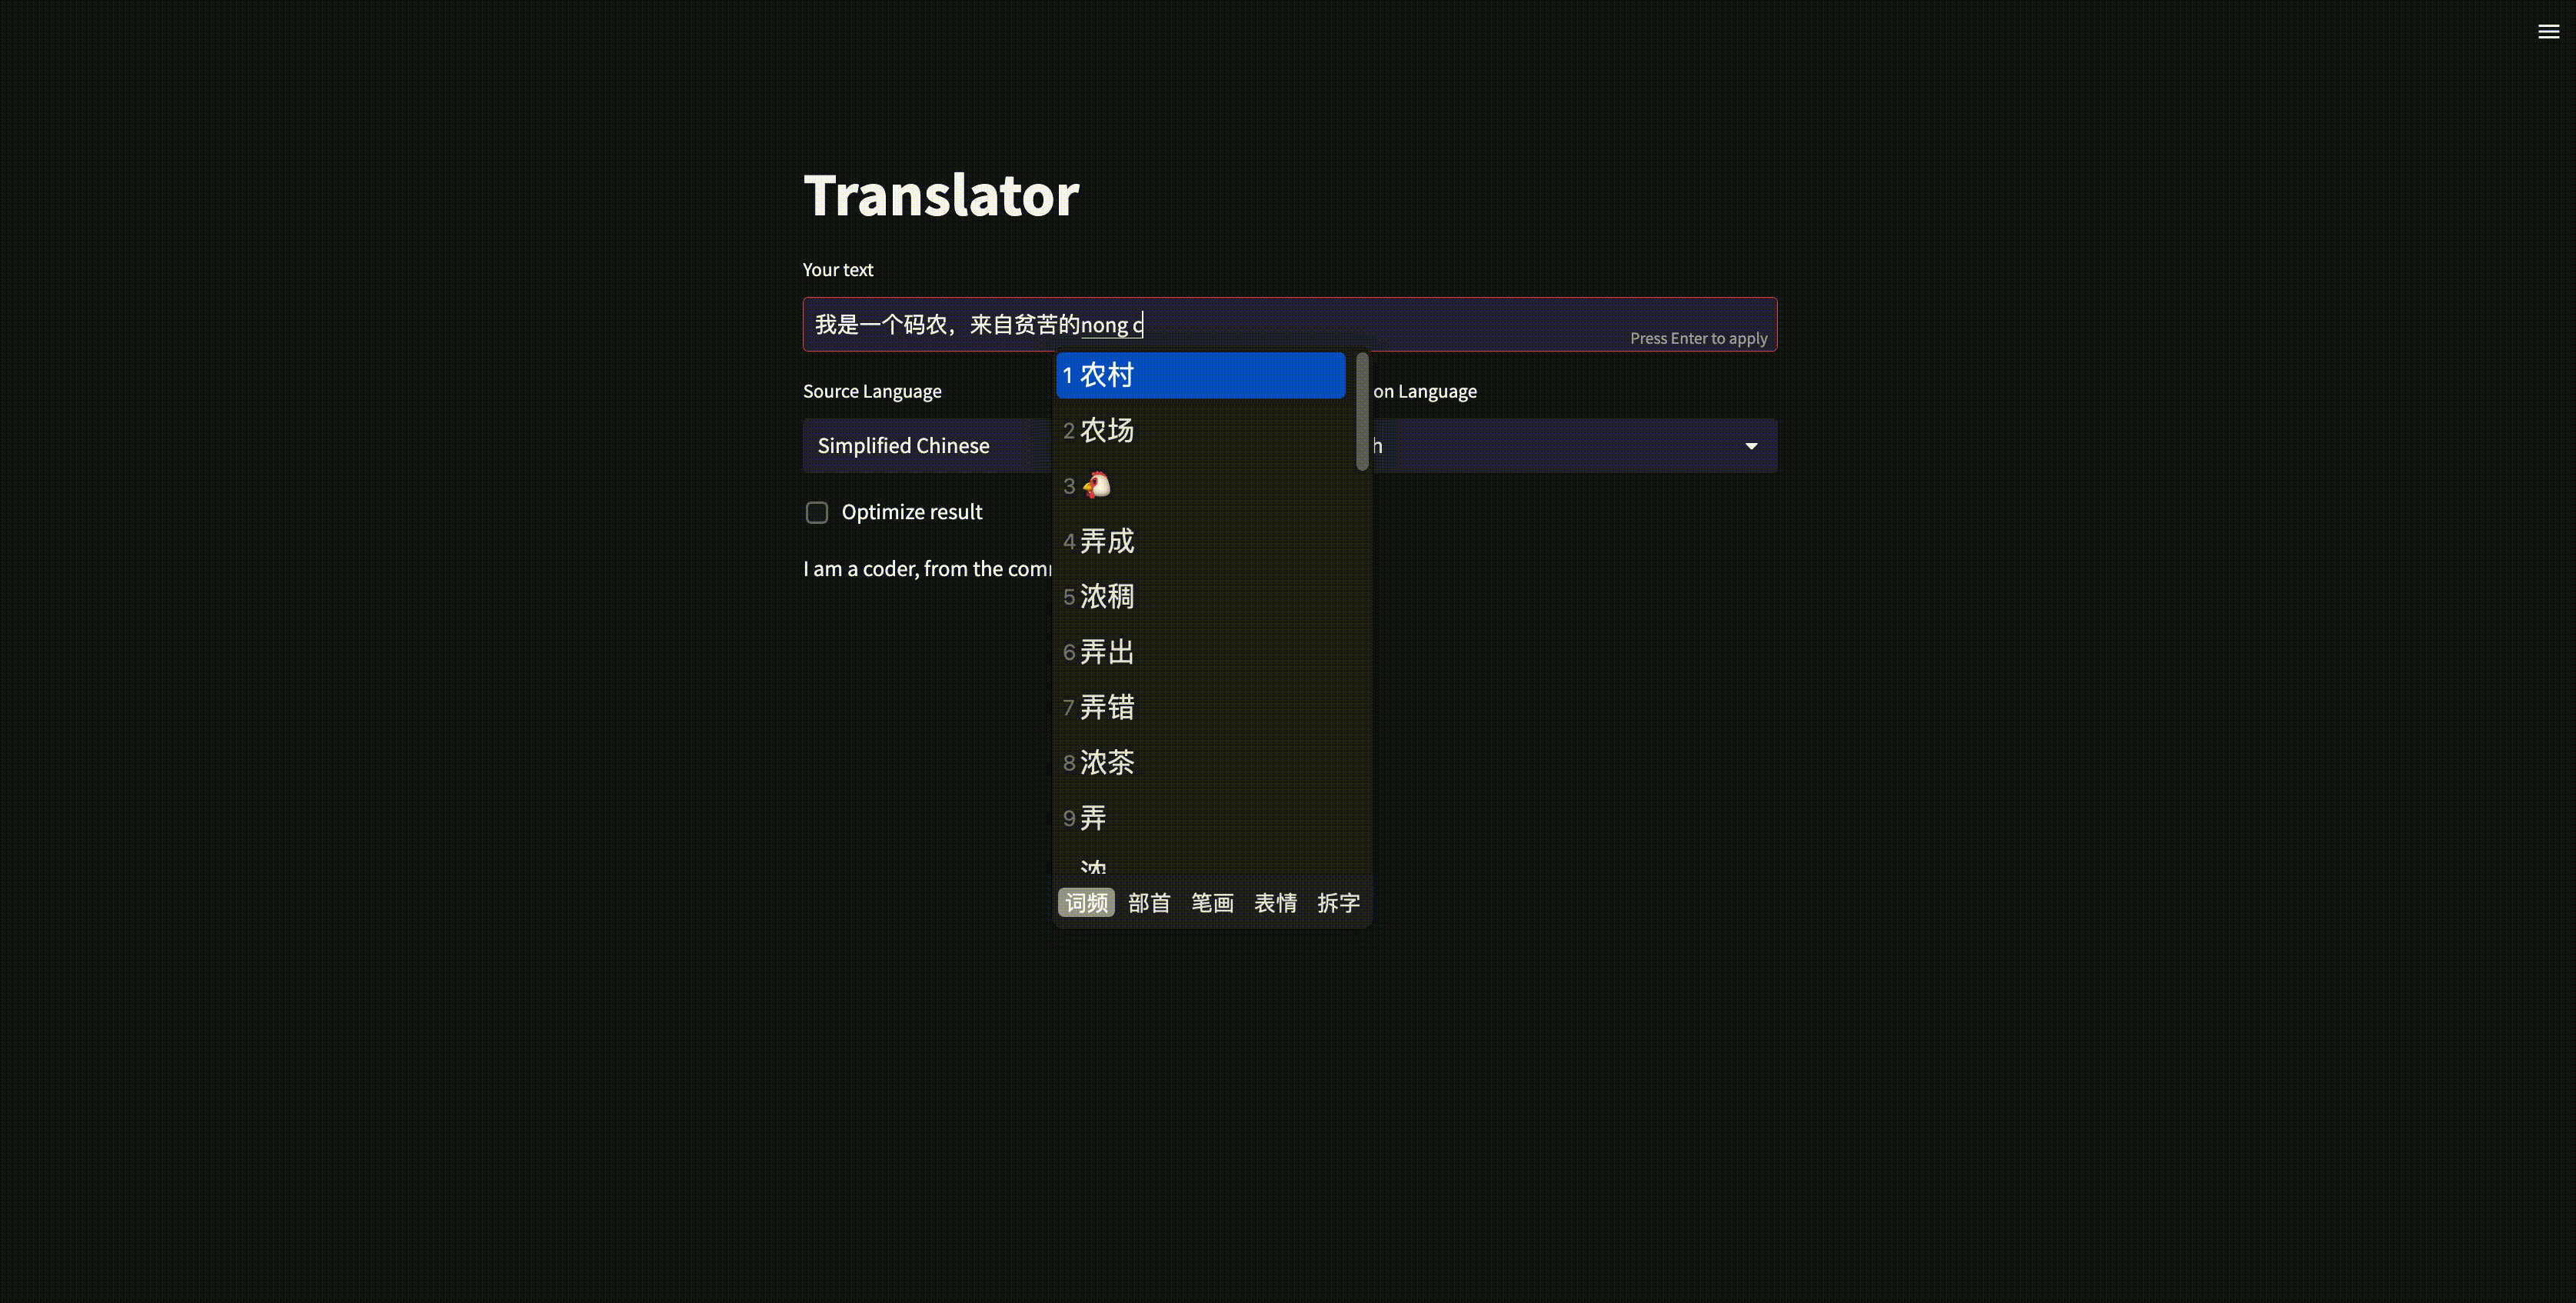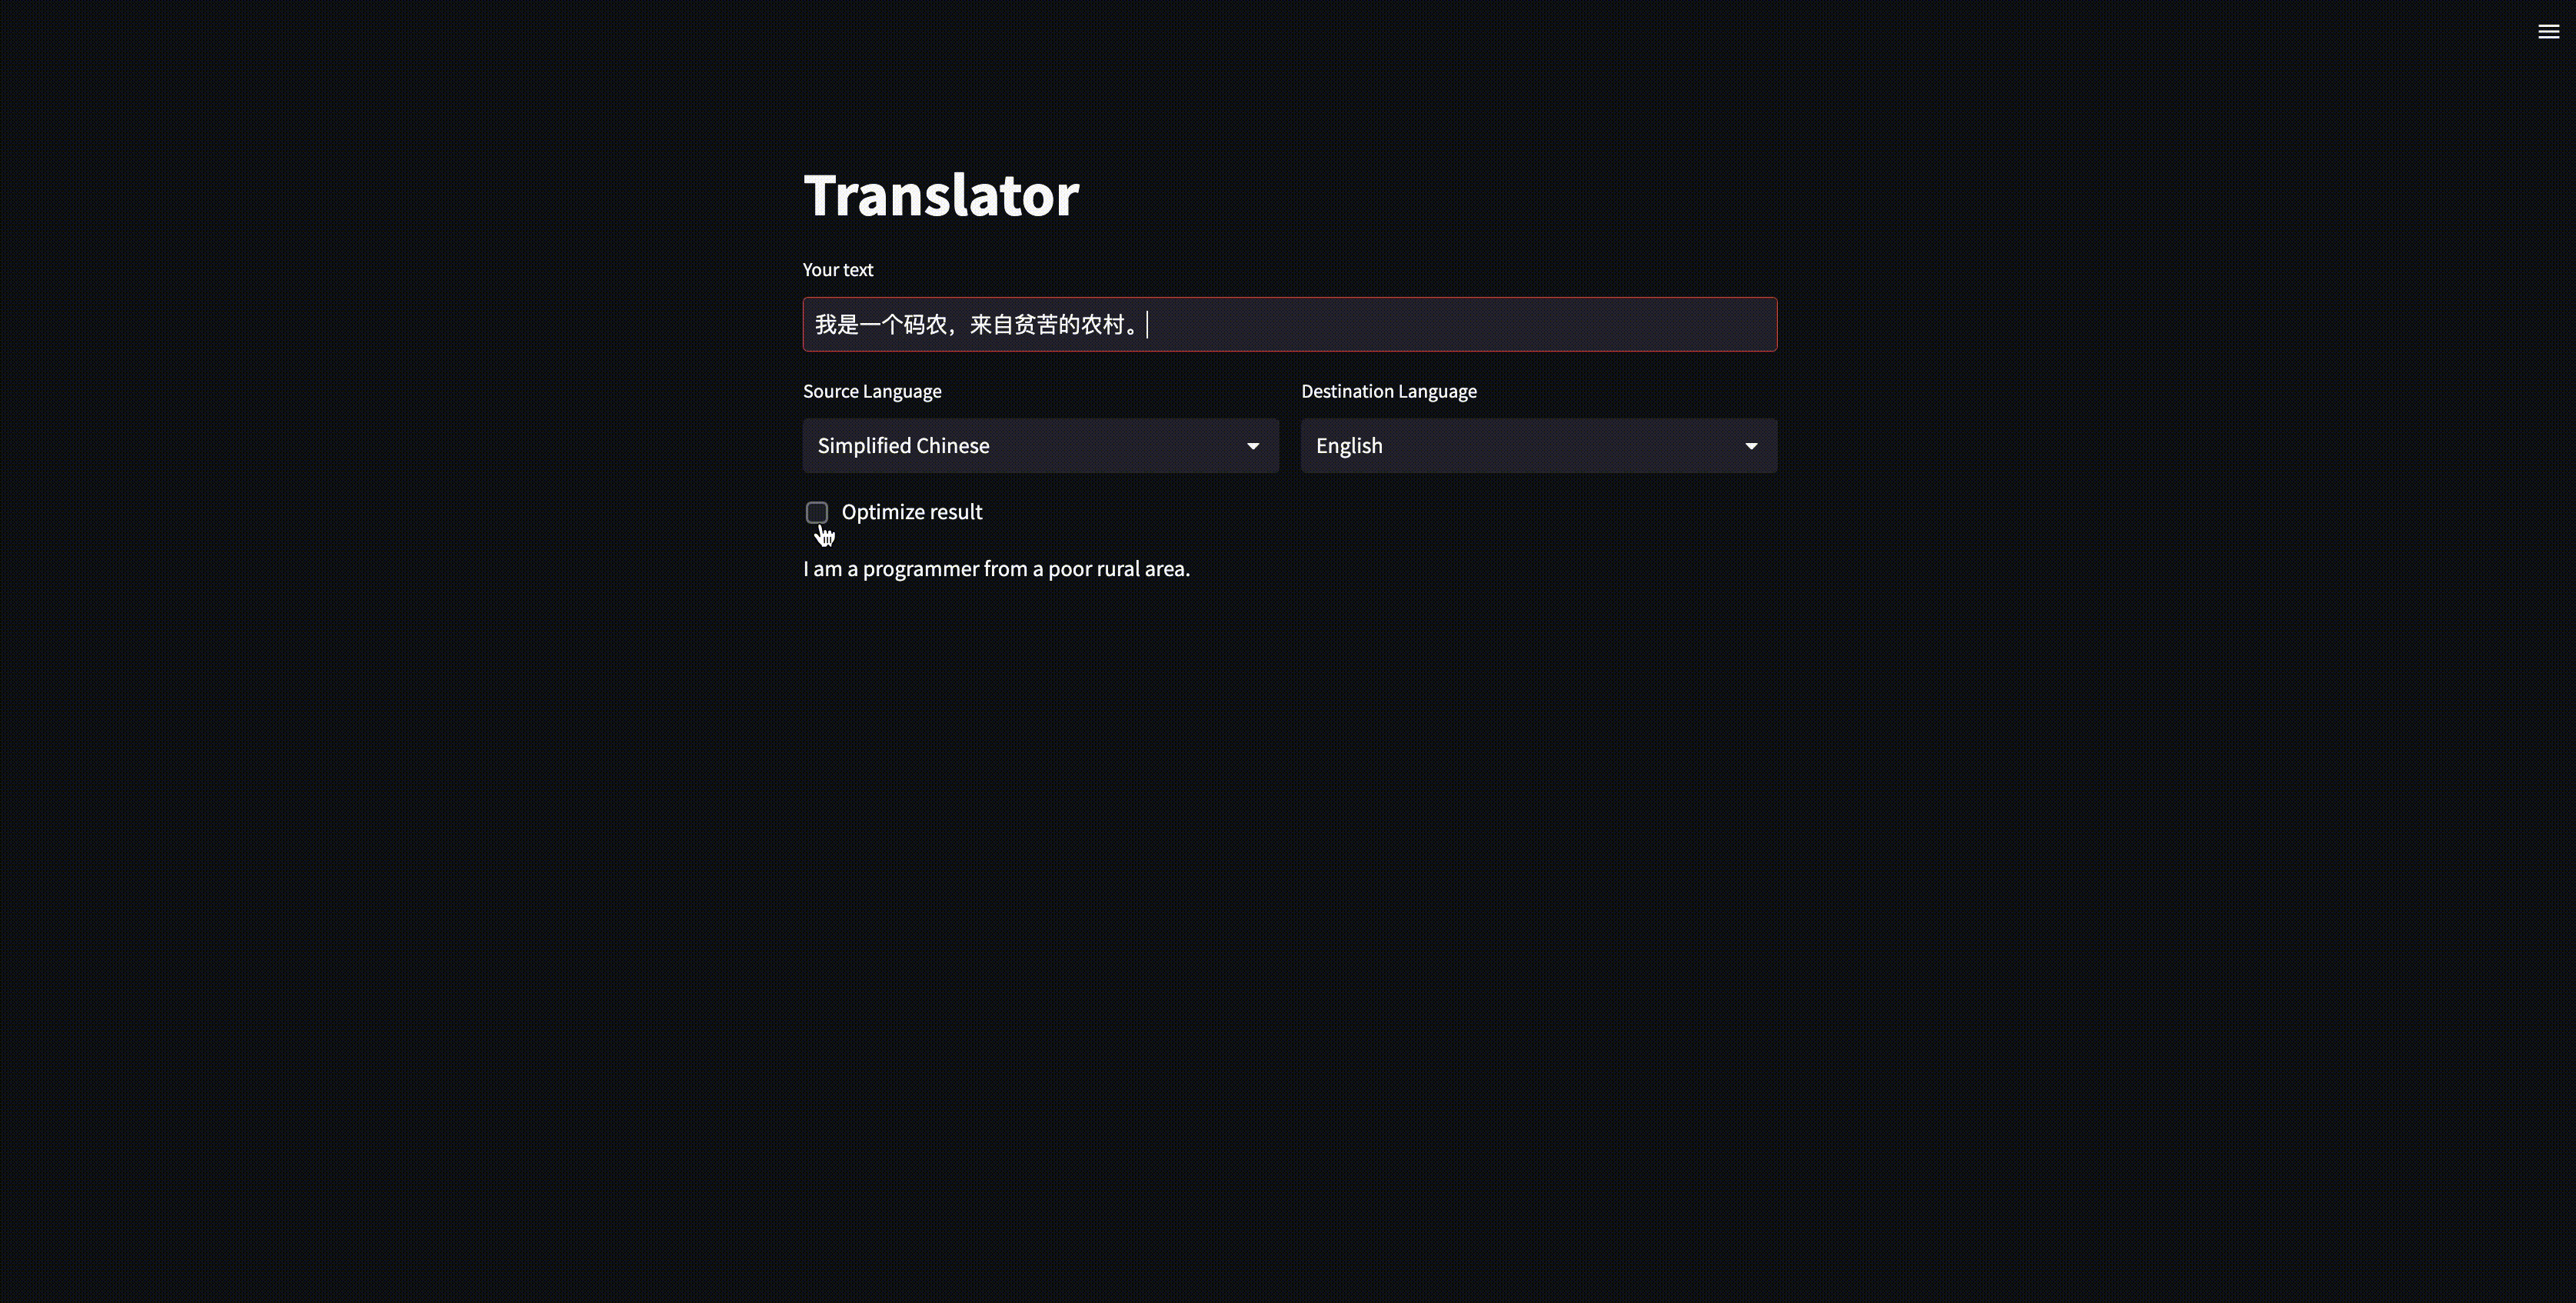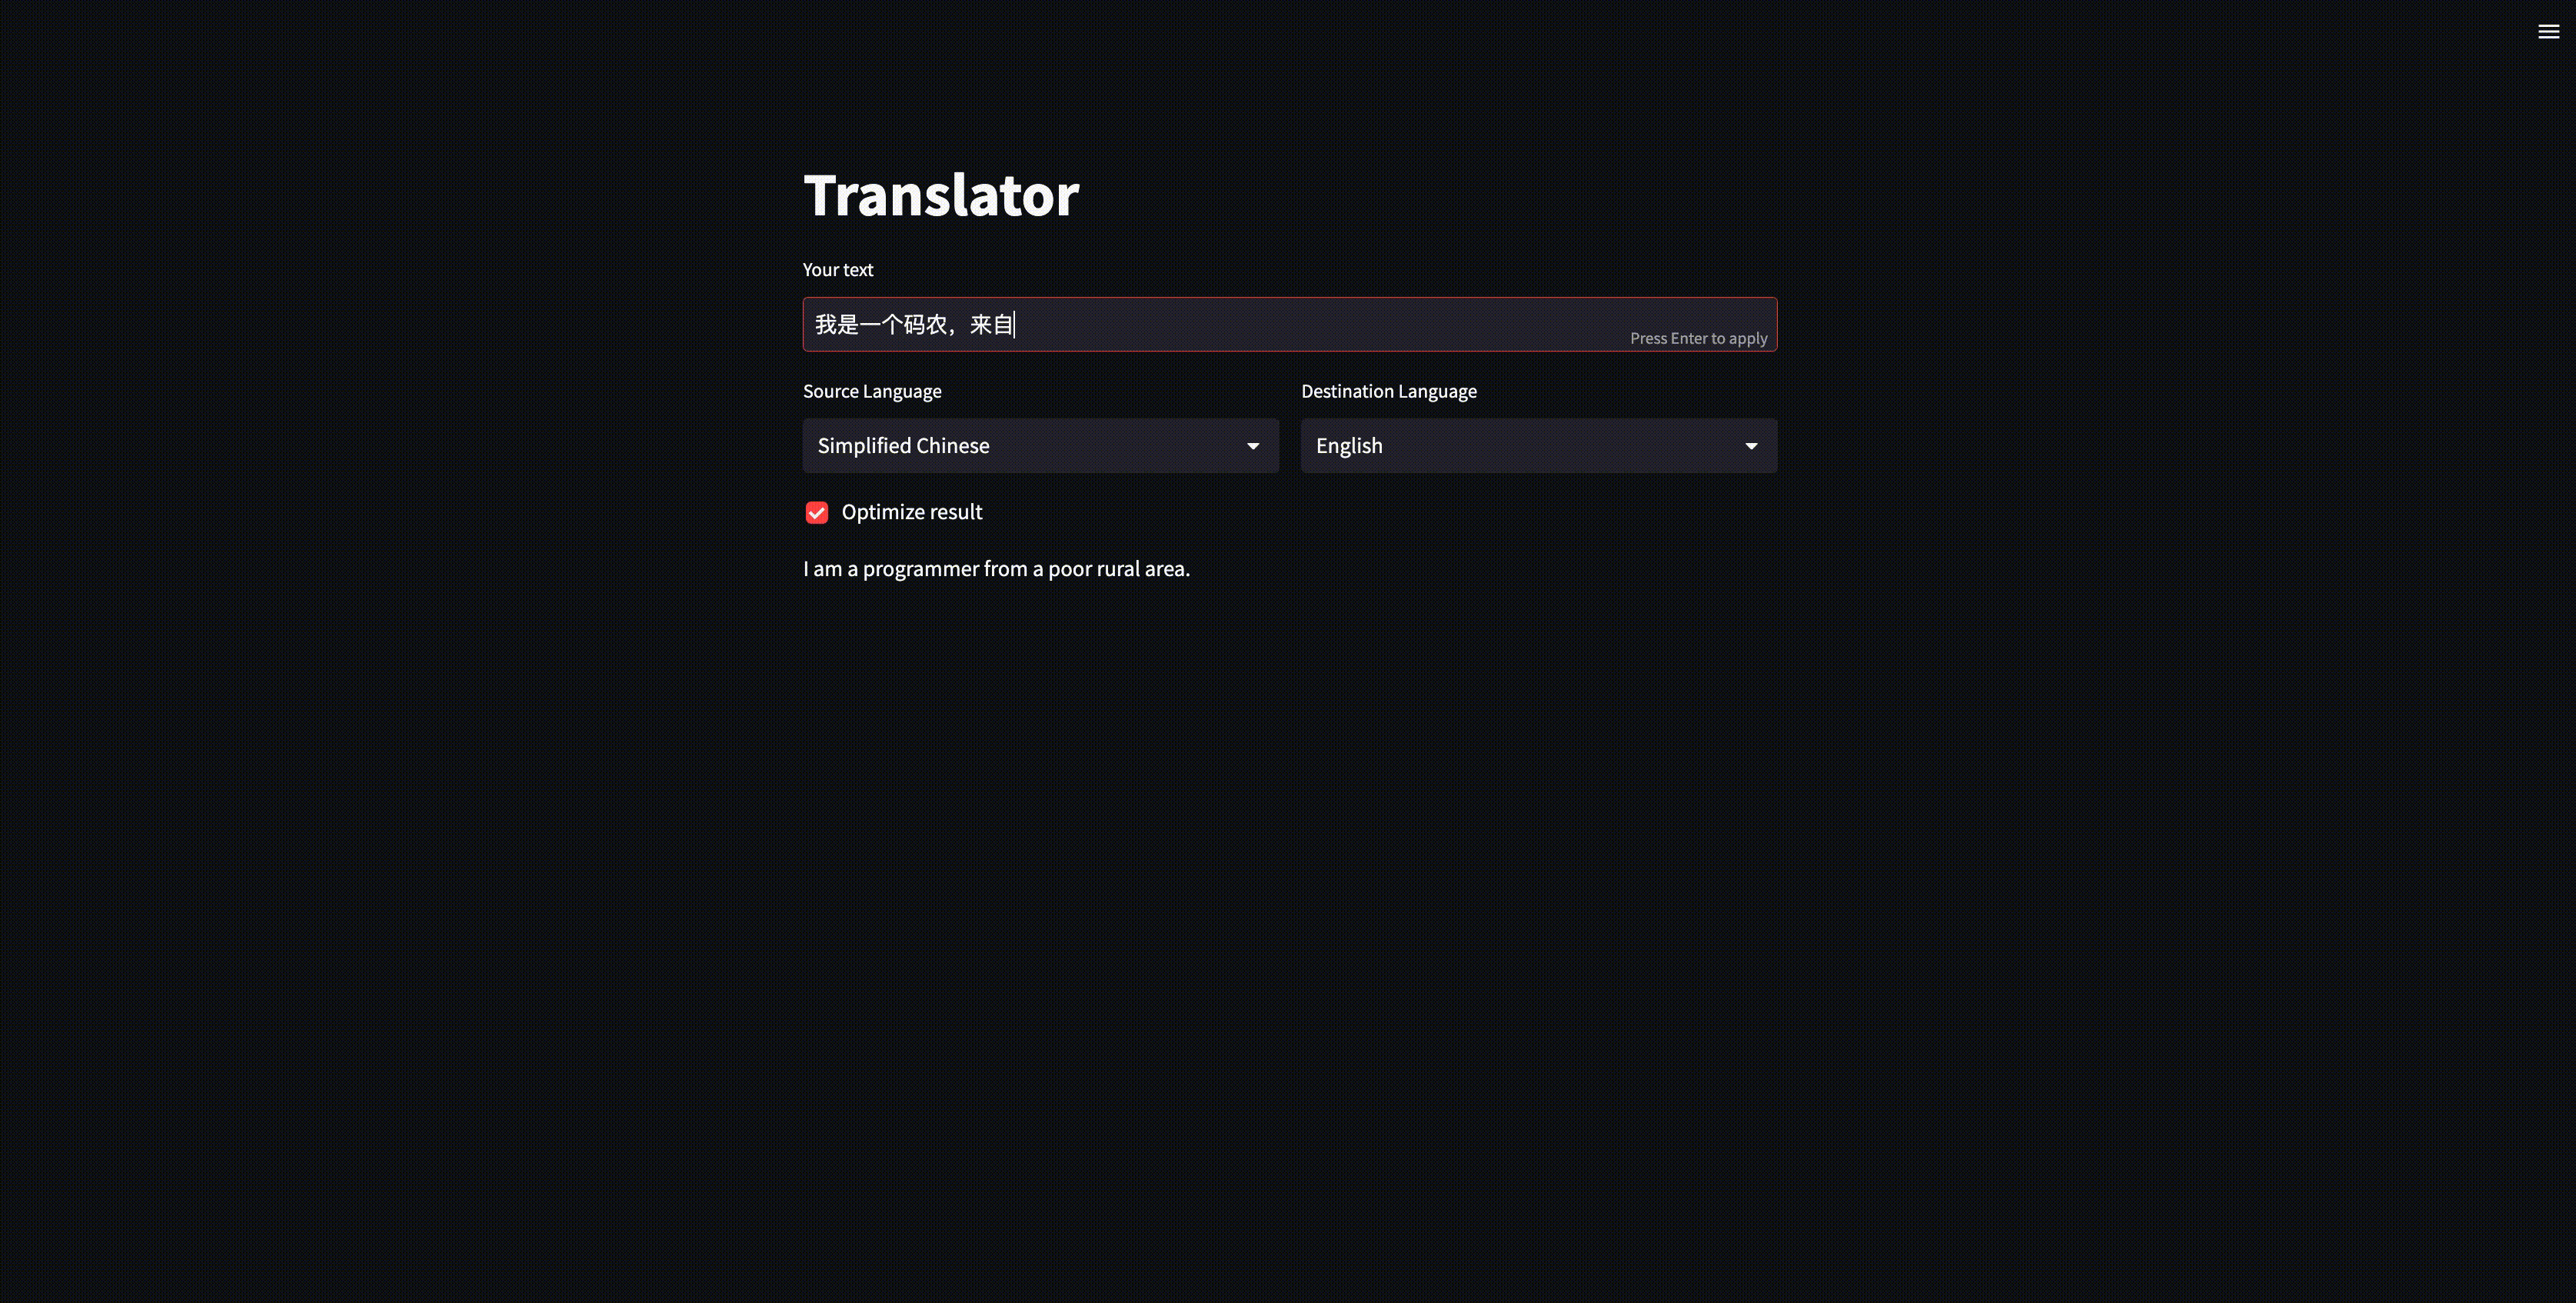 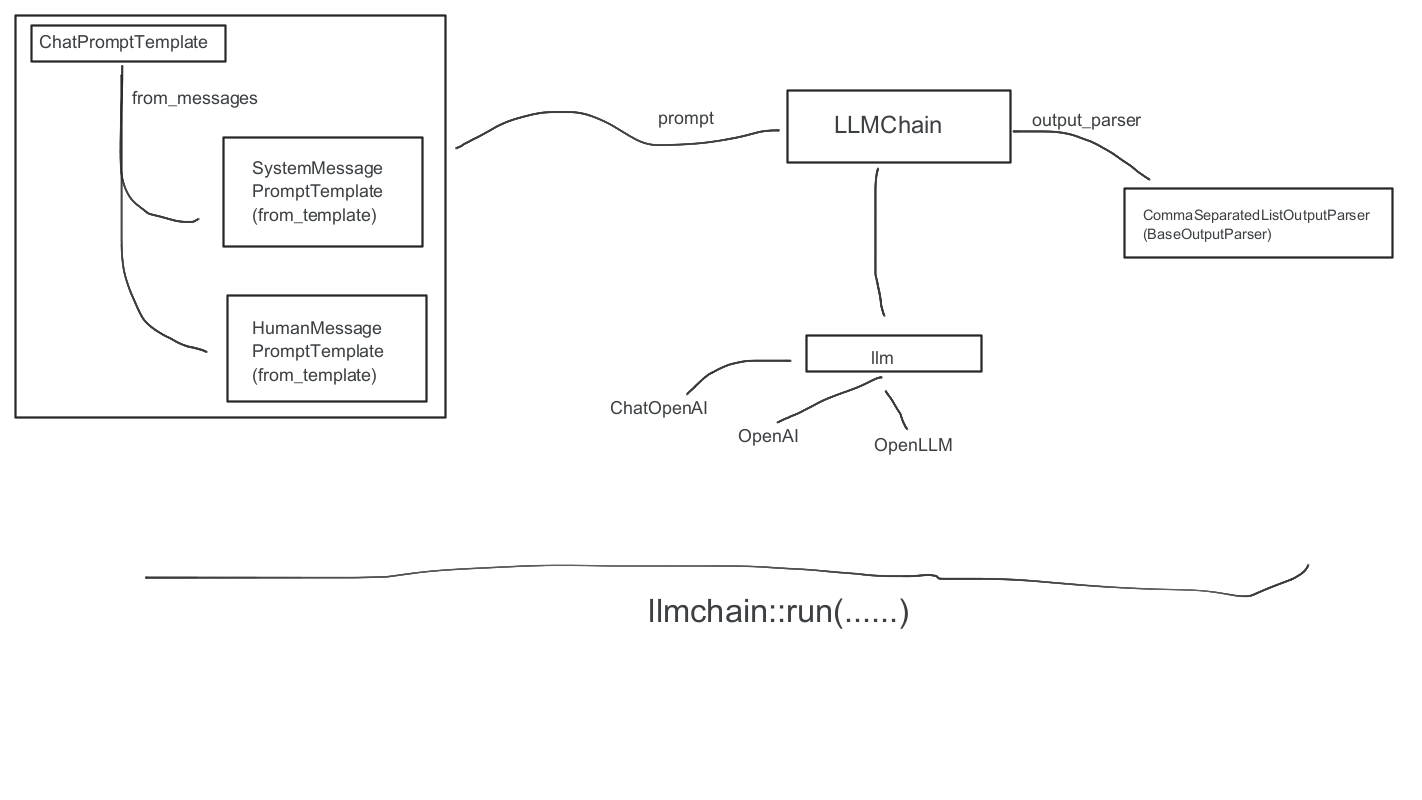 |
| html_summary_chat_app.py | Summary html content | streamlit run intermediate/html_summary_chat_app.py --server.port 8004 --server.enableCORS false | 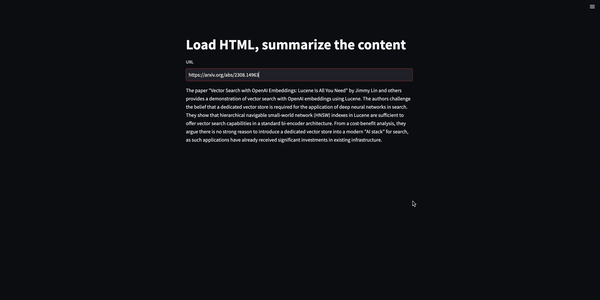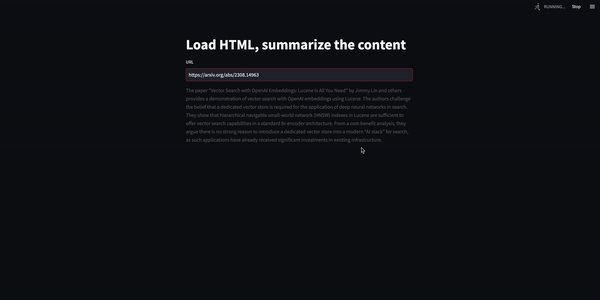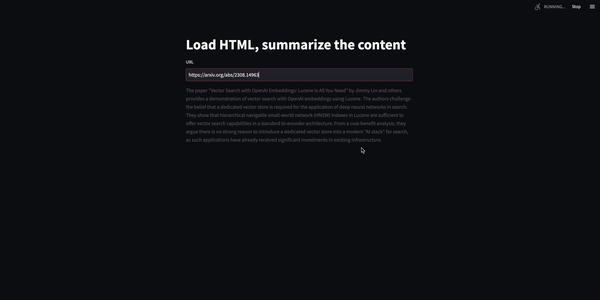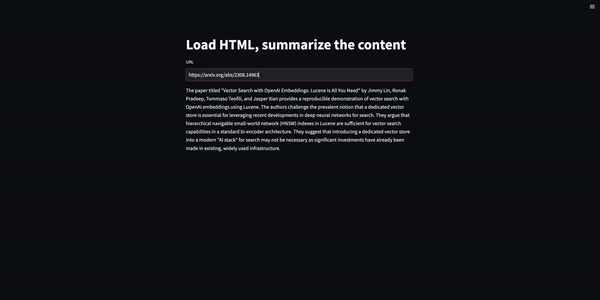 |
| html_2_json_app.py | Summary html keypoints into keypoint json | streamlit run intermediate/html_2_json_app.py --server.port 8005 --server.enableCORS false | 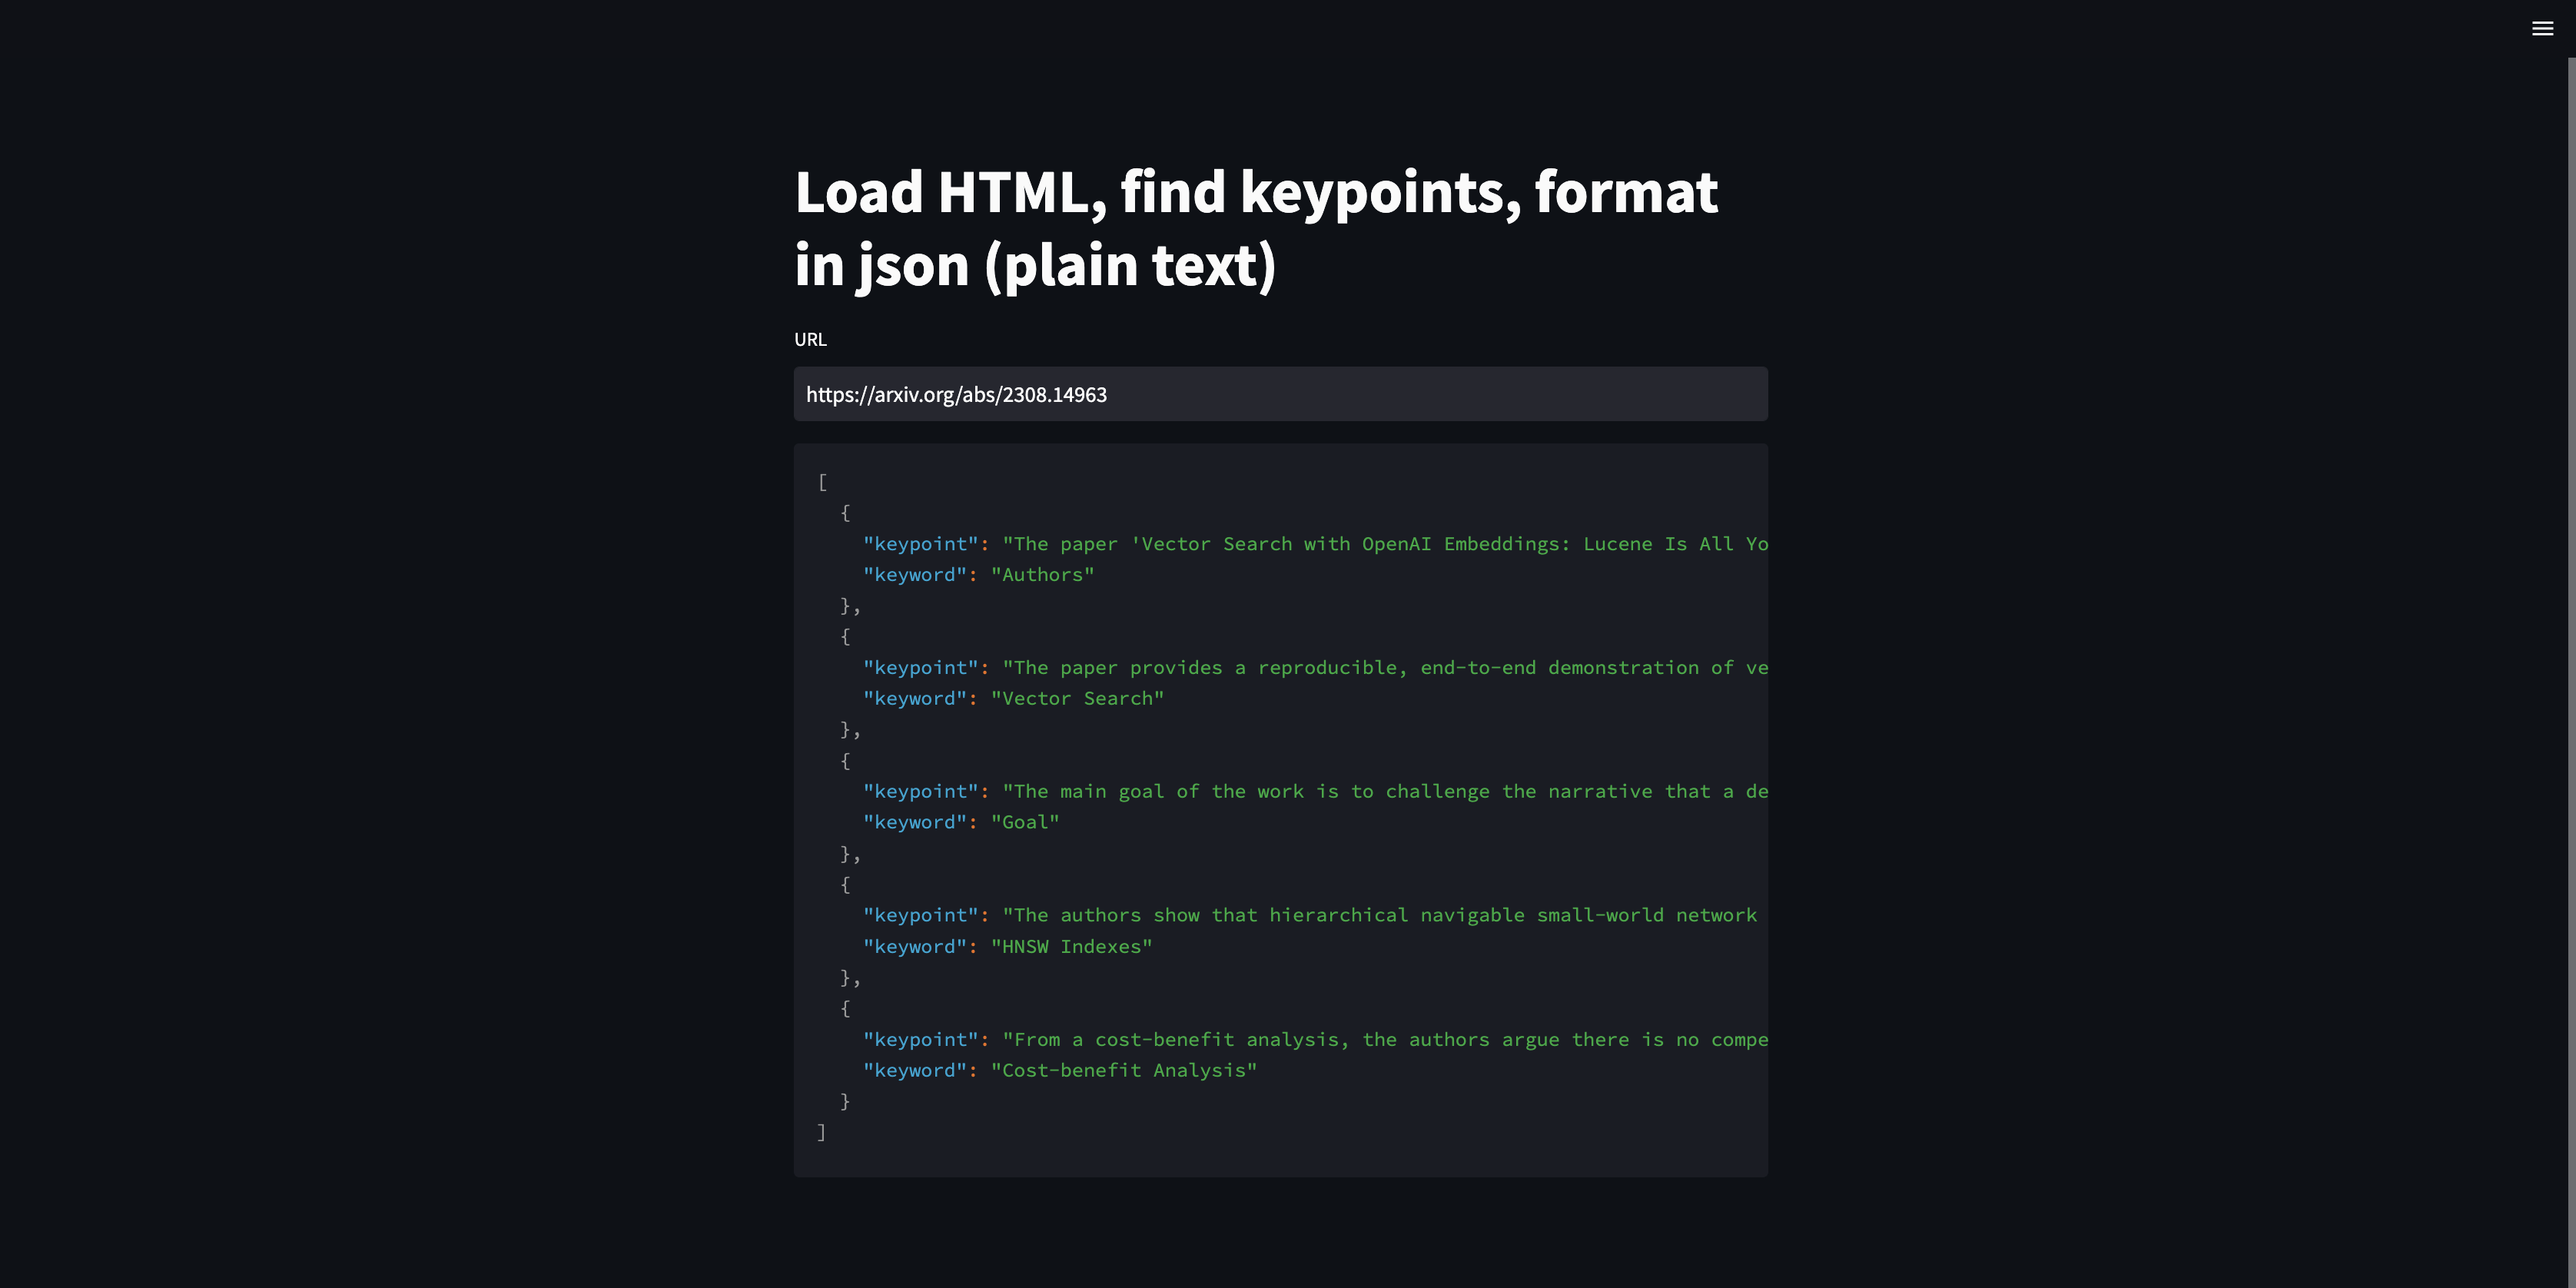 |
| assistants.py | Use OpenAI Assistants API in different ways | streamlit run intermediate/assistants.py --server.port 8006 --server.enableCORS false | read 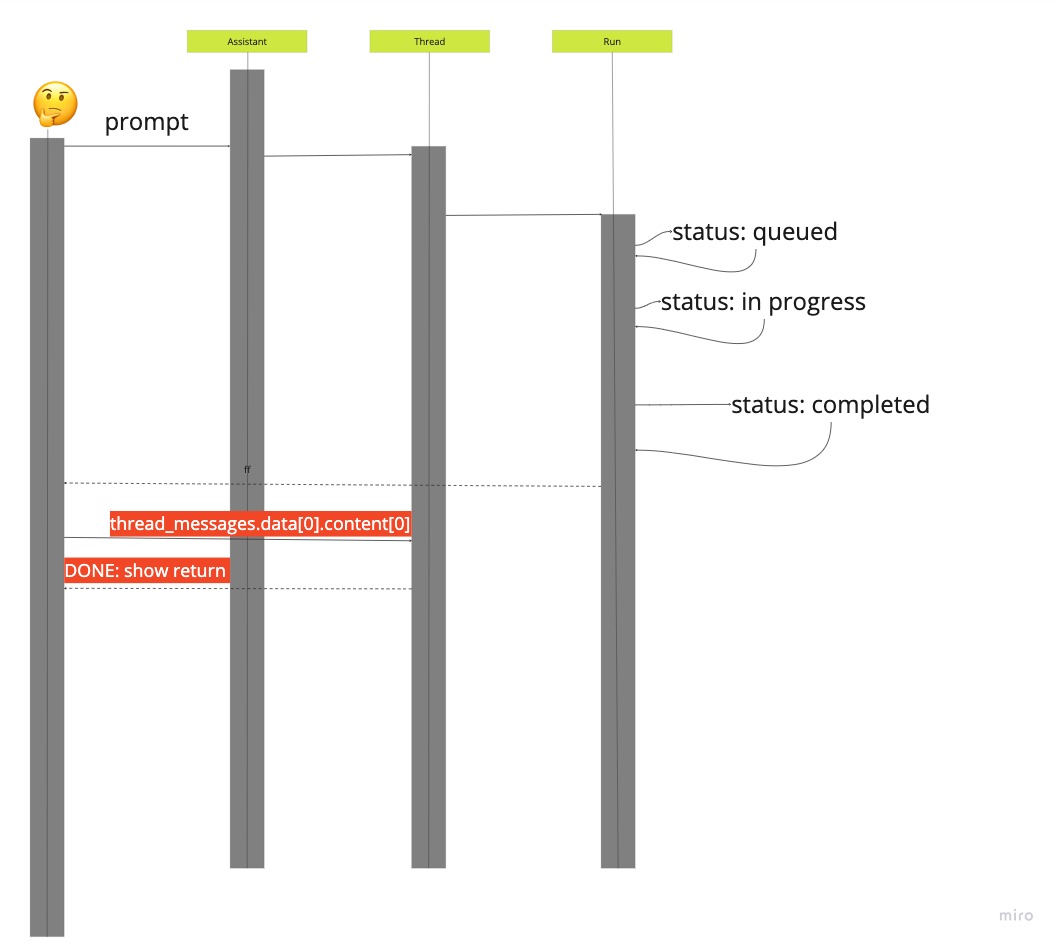 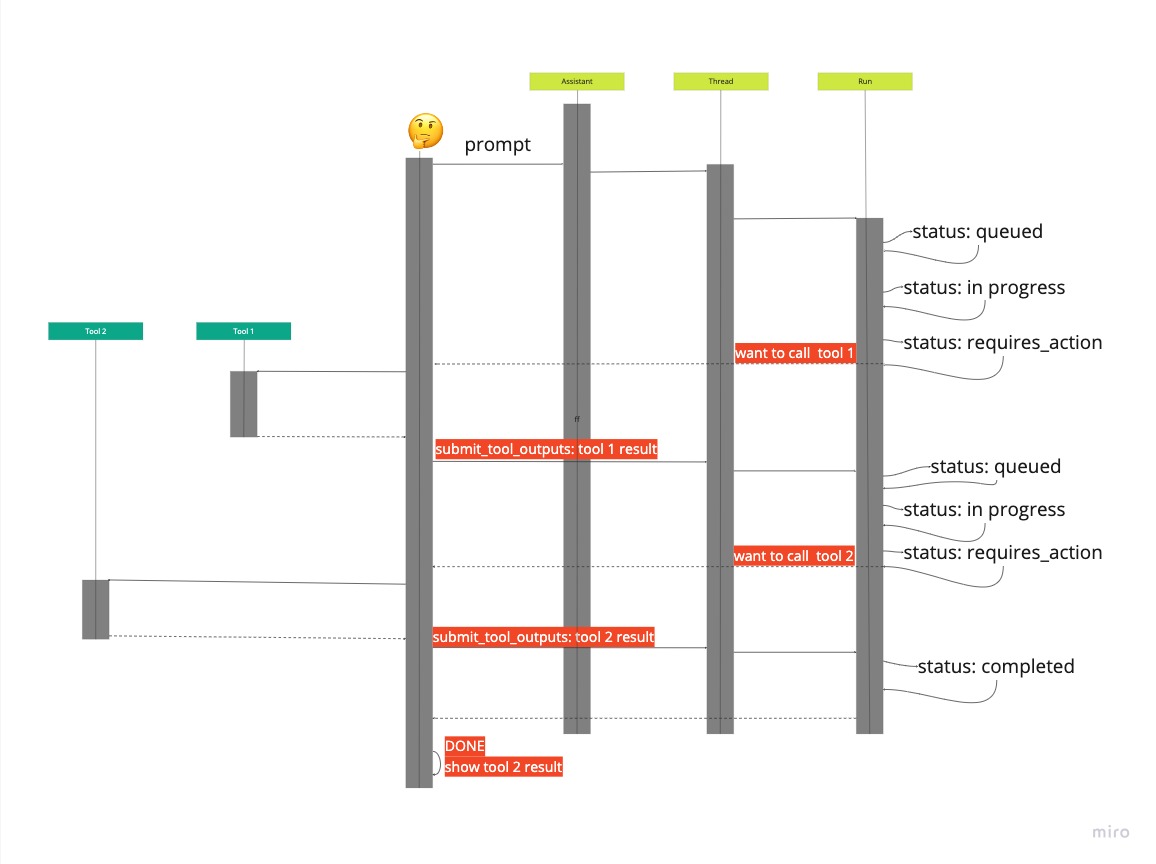 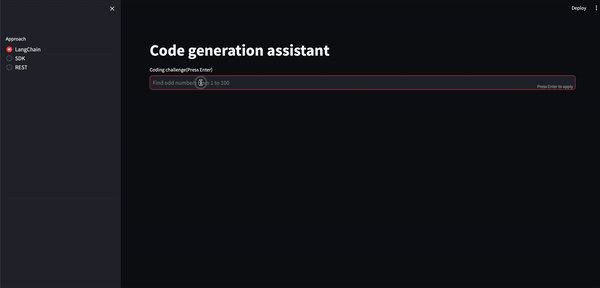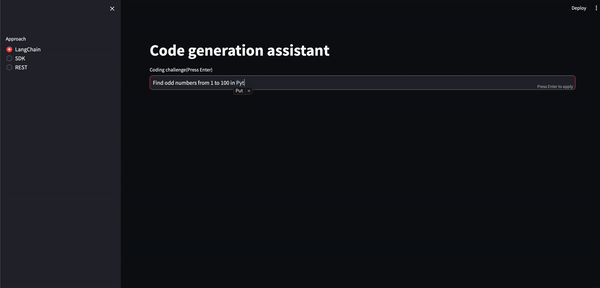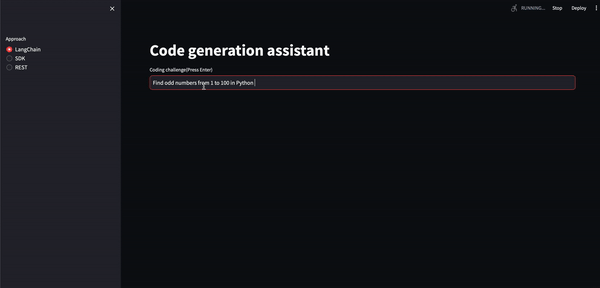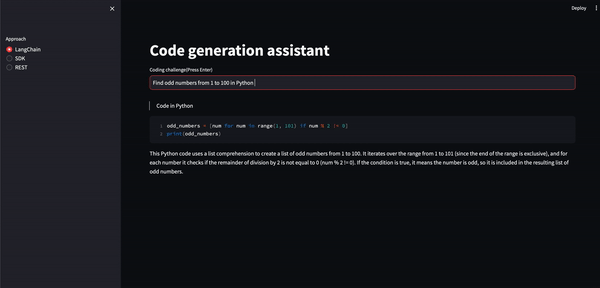 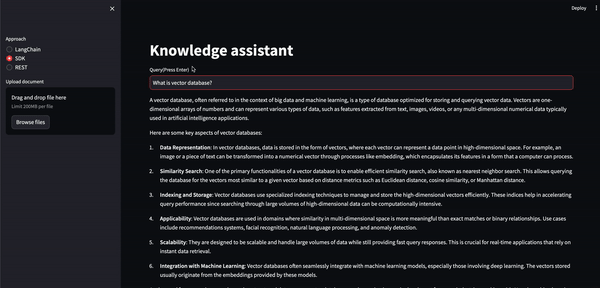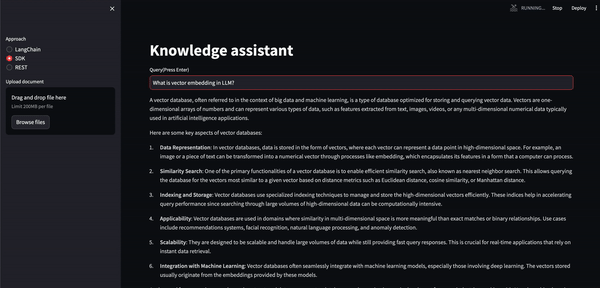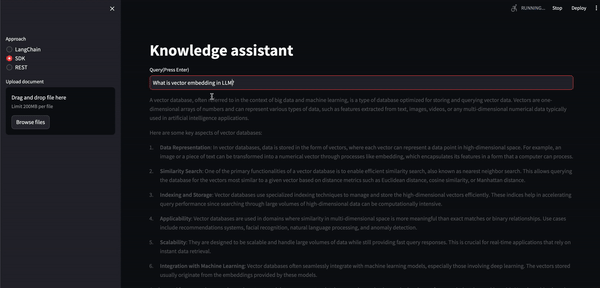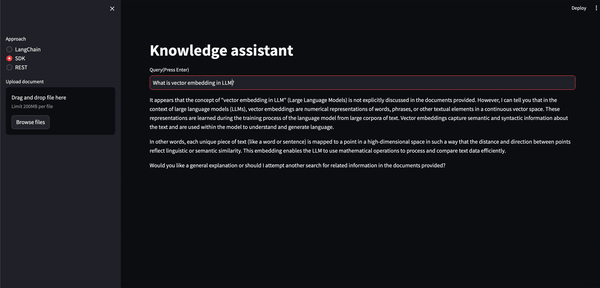 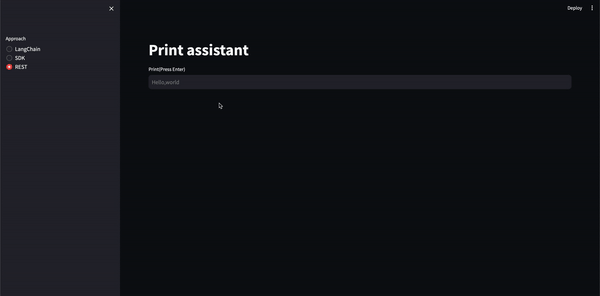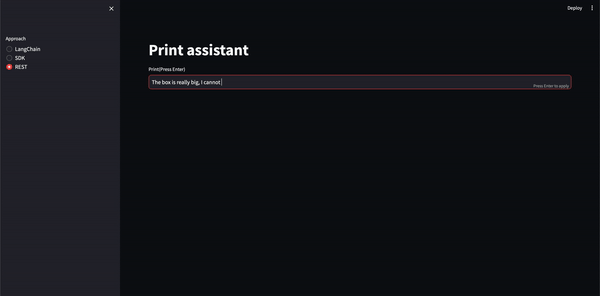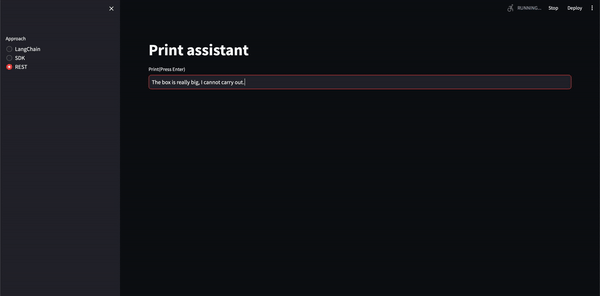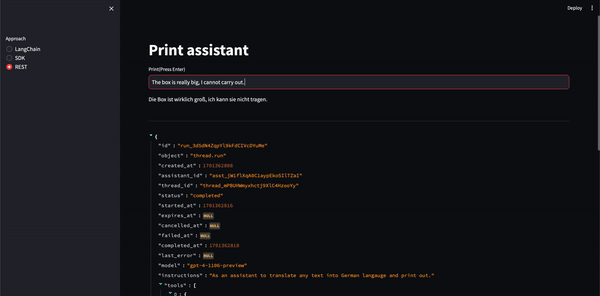 |
| hyde_retrieval.py | Implementation of HyDE retrieval by LlamaIndex, hybrid, local or remote LLMs. | streamlit run intermediate/hyde_retrieval.py --server.port 8007 --server.enableCORS false | read 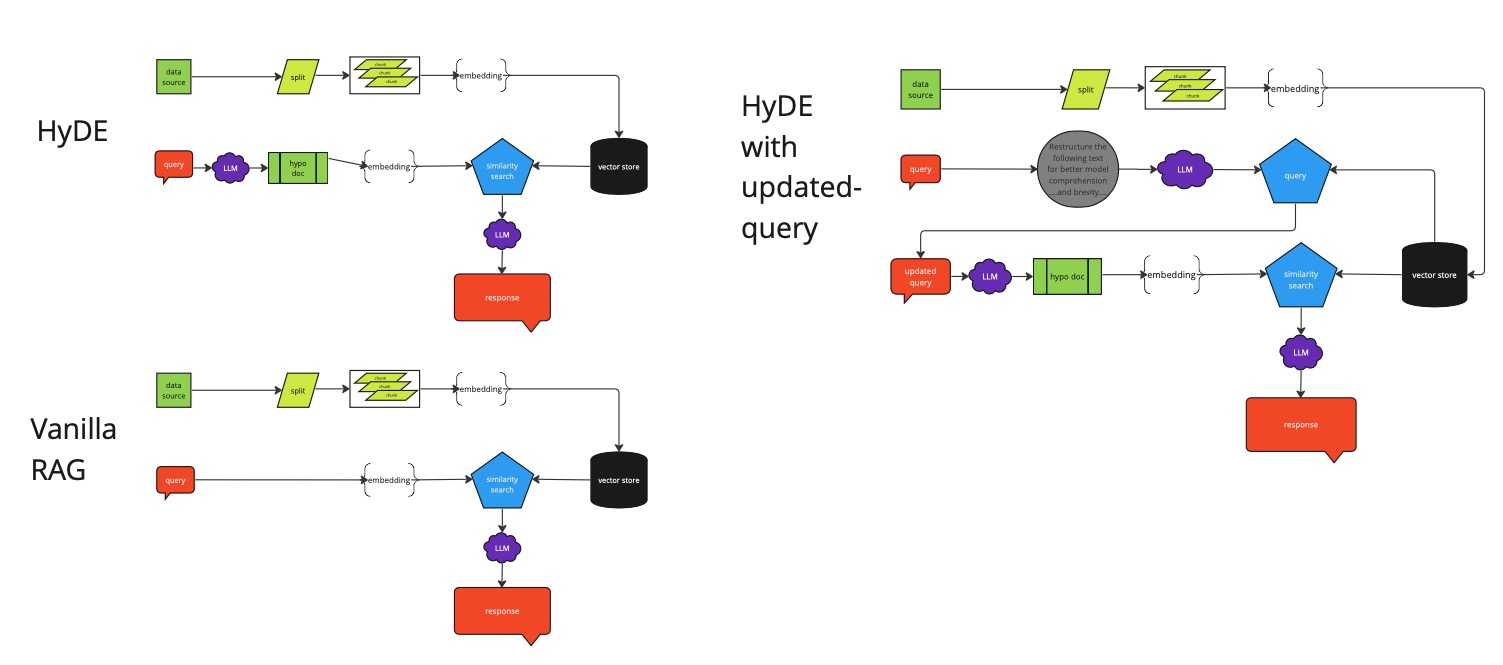 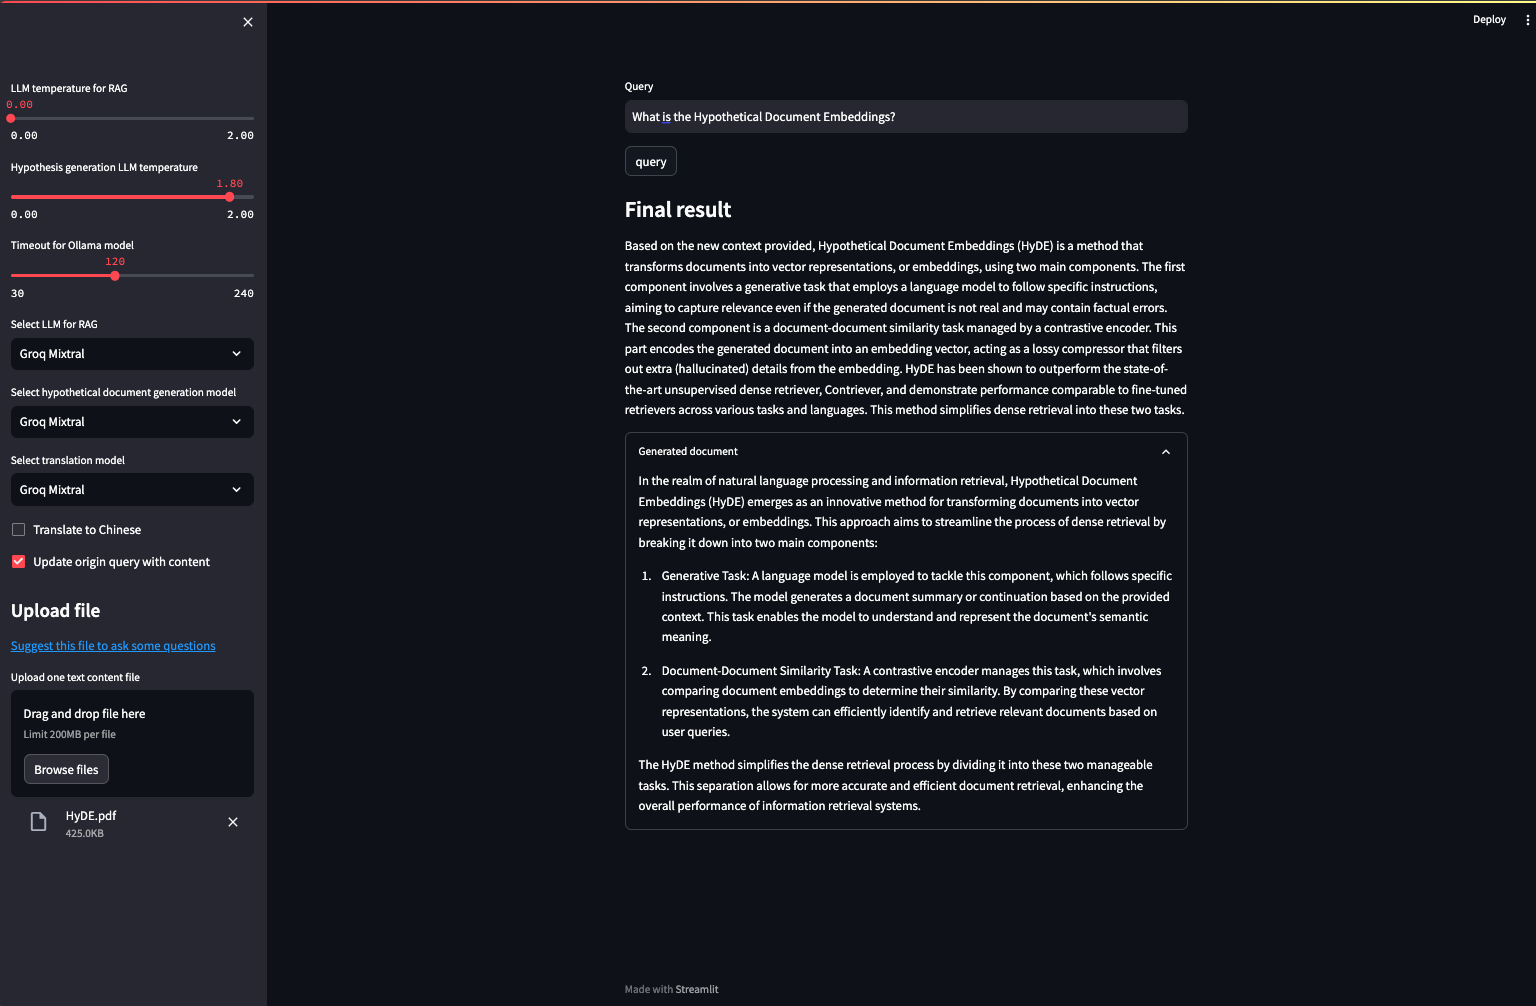 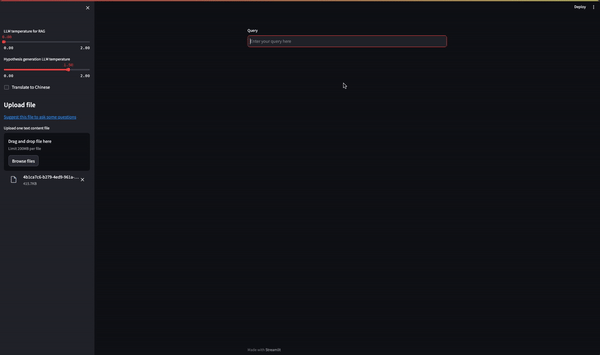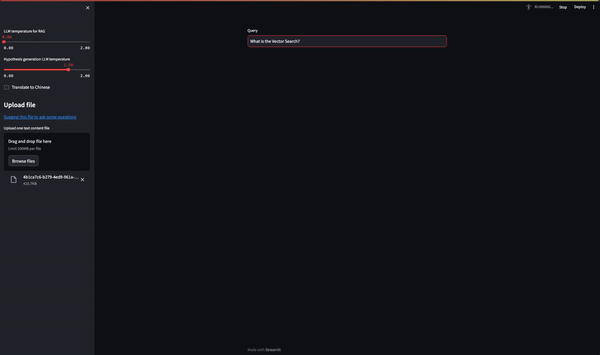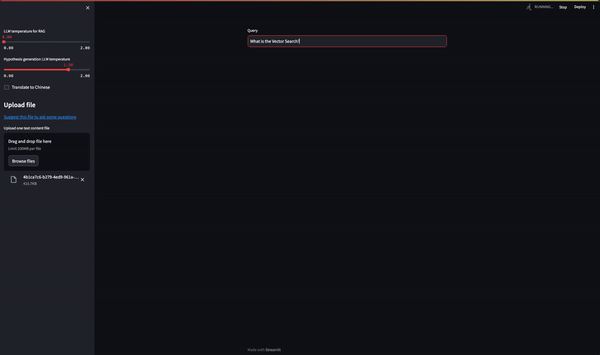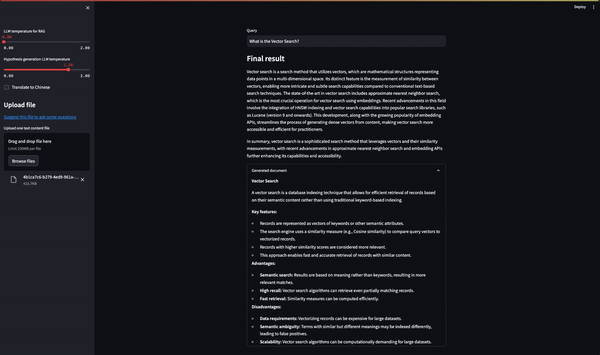 |
| App | Description | Launch | Demo |
|---|---|---|---|
| qa_chain_pdf_app.py | Ask info from PDF file, chat with it | streamlit run advanced/qa_chain_pdf_app.py --server.port 8004 --server.enableCORS false | 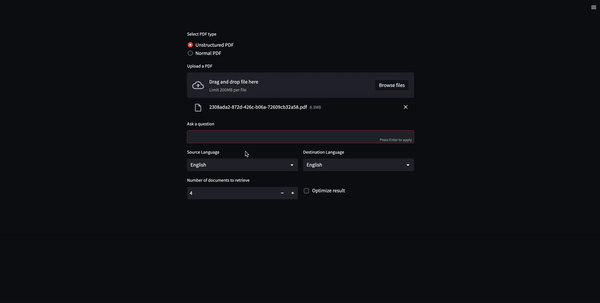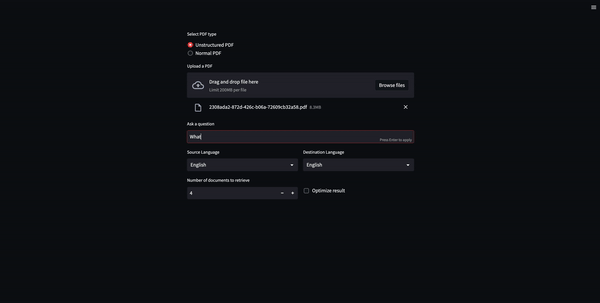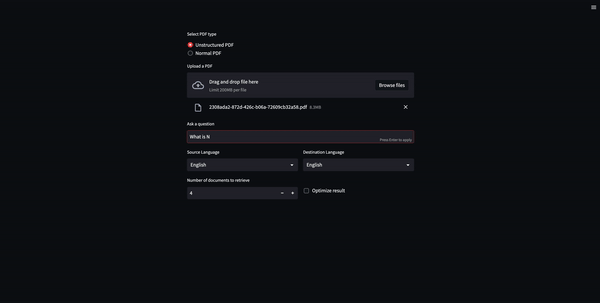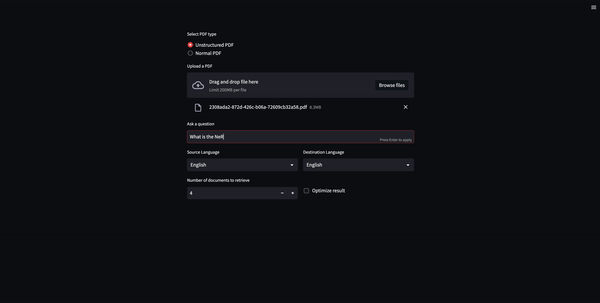 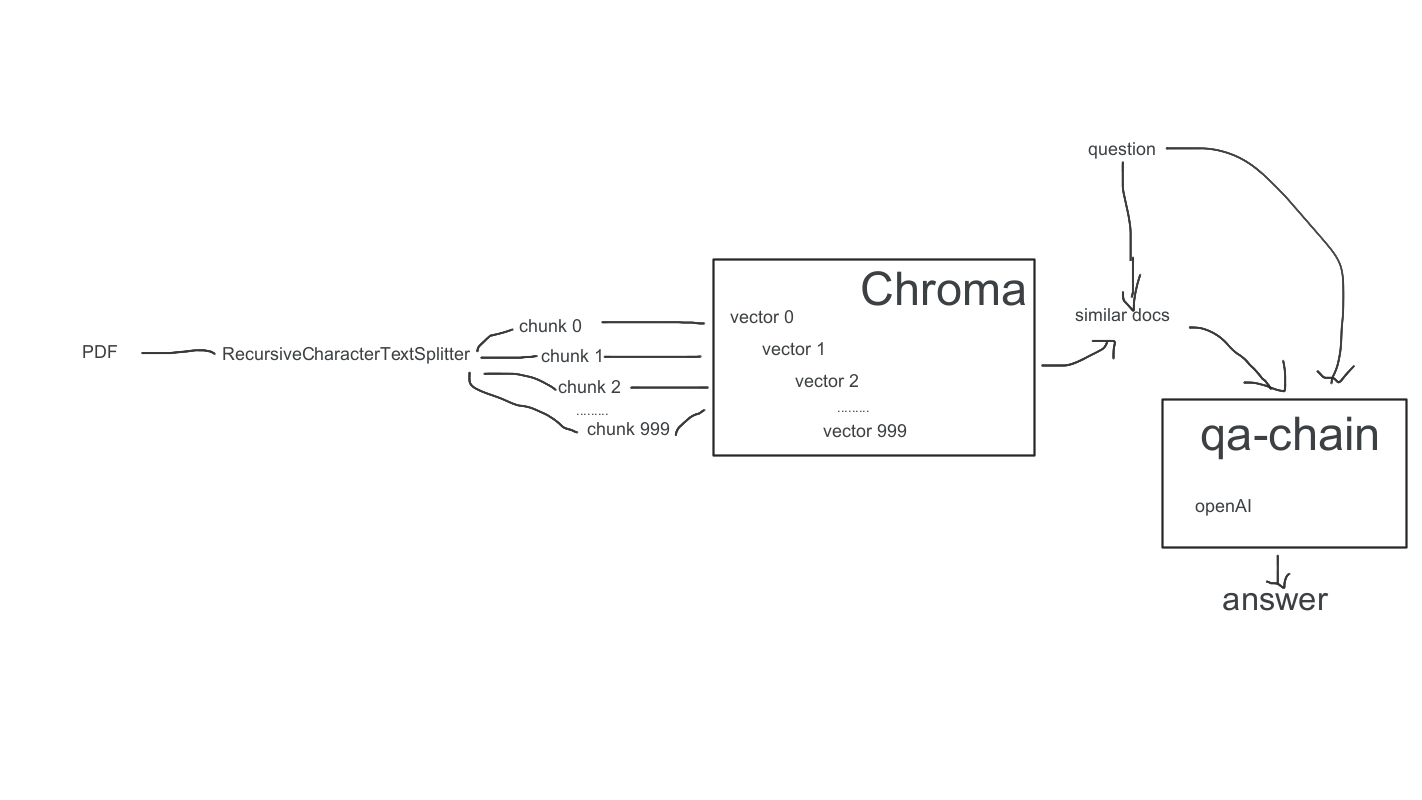 |
| faiss_app.py | Ask info from a internet file, find similar docs and answer with VectorDBQAWithSourcesChain | streamlit run advanced/faiss_app.py --server.port 8005 --server.enableCORS false | 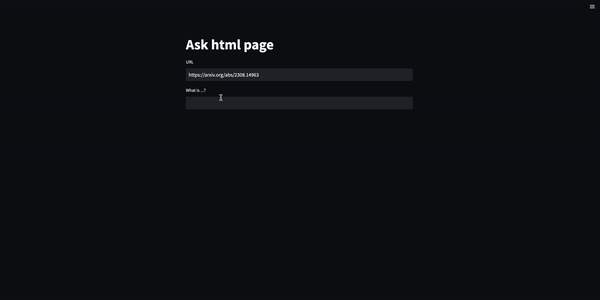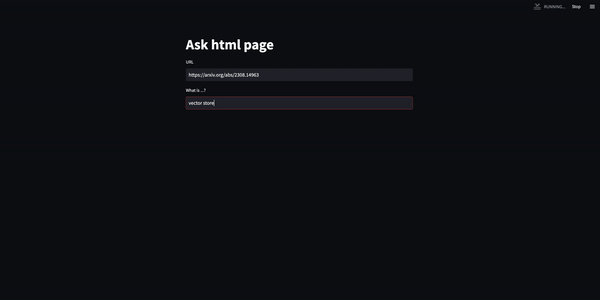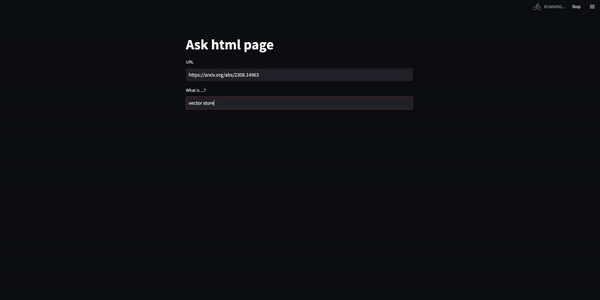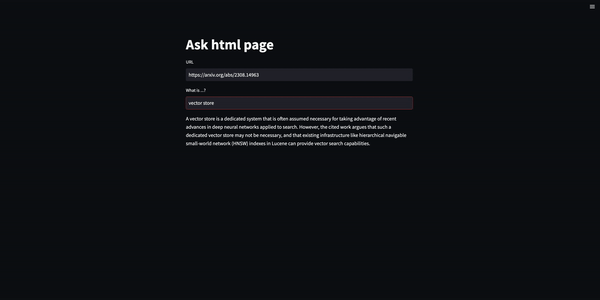 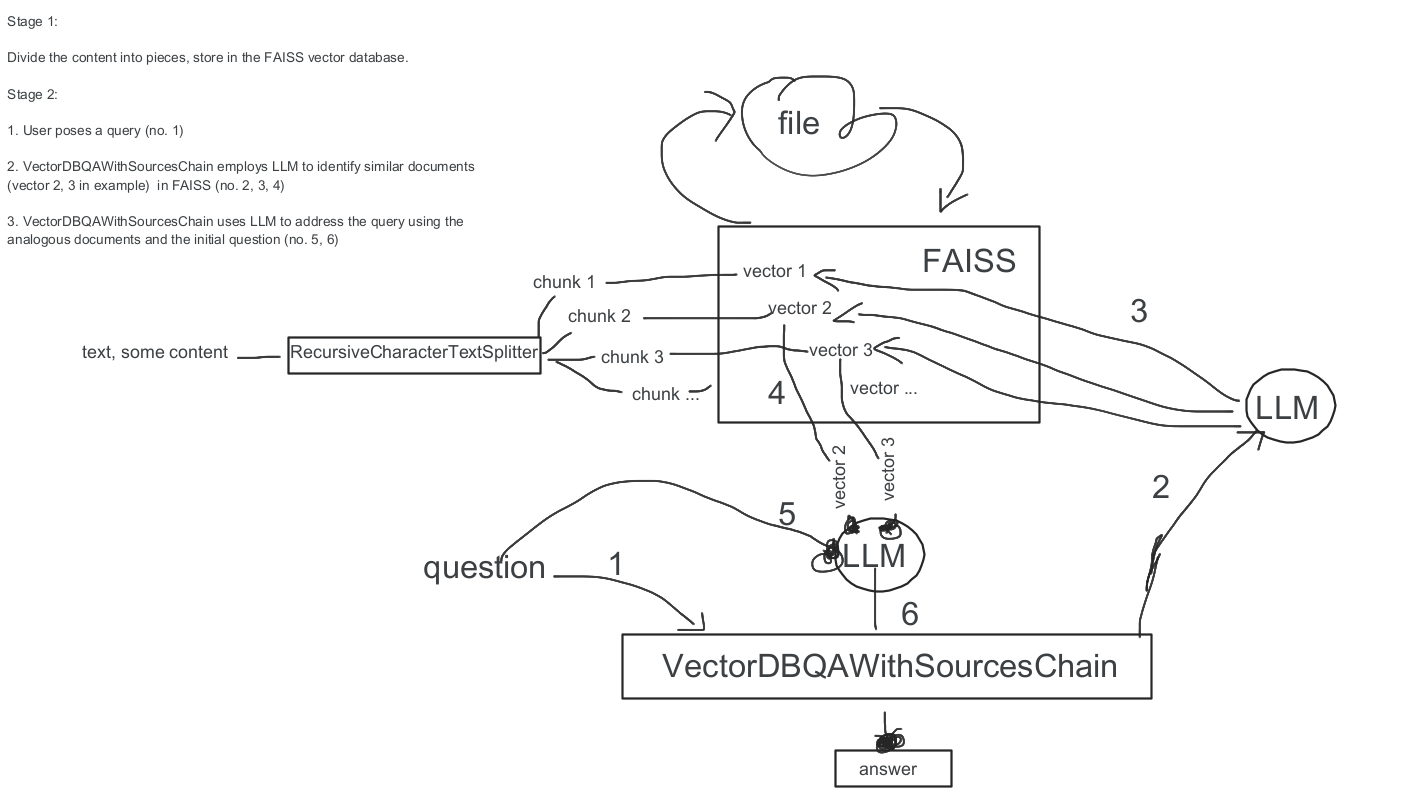 |
| html_2_json_output_app.py | Load html content and summary into json objects | streamlit run advanced/html_2_json_output_app.py --server.port 8006 --server.enableCORS false | 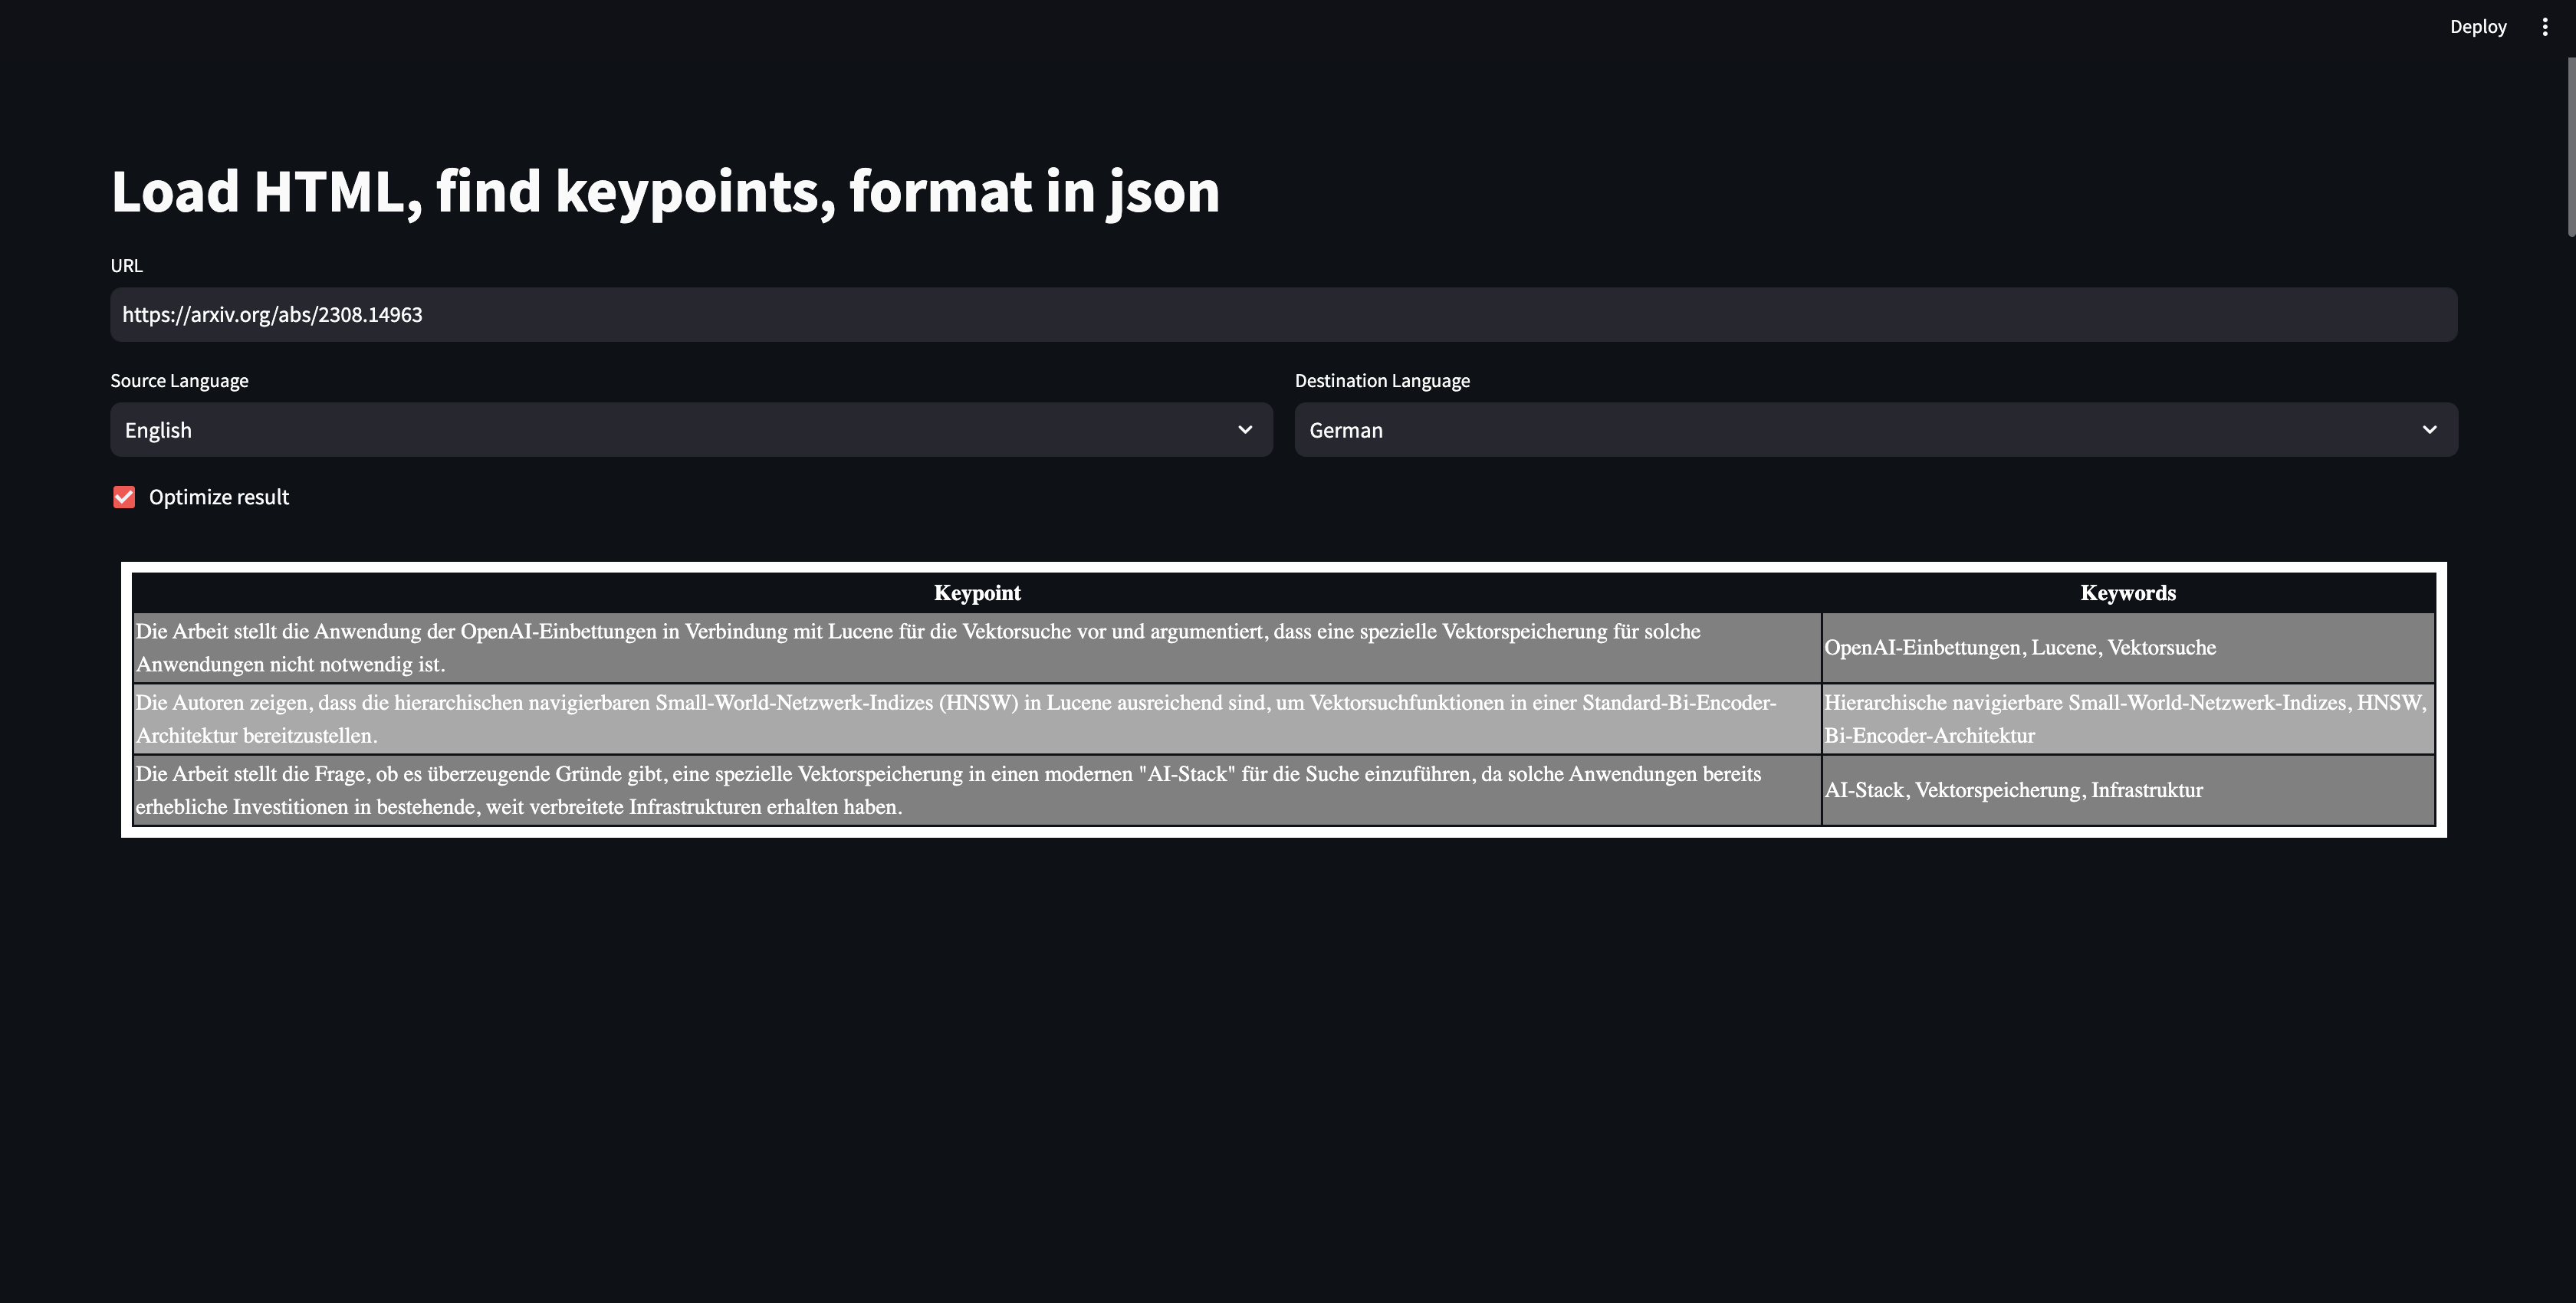 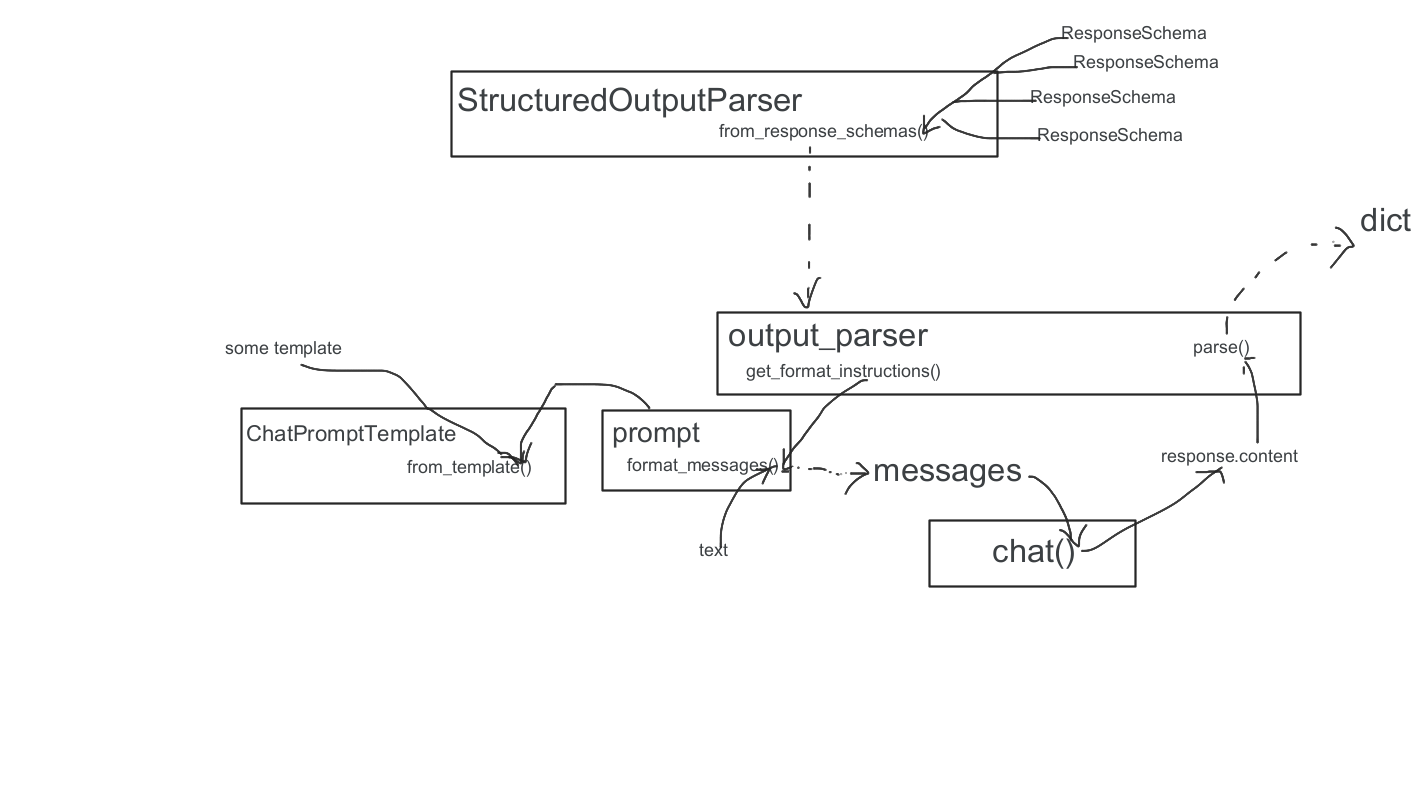 |
| joke_bot.py | Prompt engineering to get one random joke or rate one joke | python advanced/joke_bot.py --rate "Why couldn't the bicycle stand up by itself? It was two tired." or python advanced/joke_bot.py --tell --num 4 | 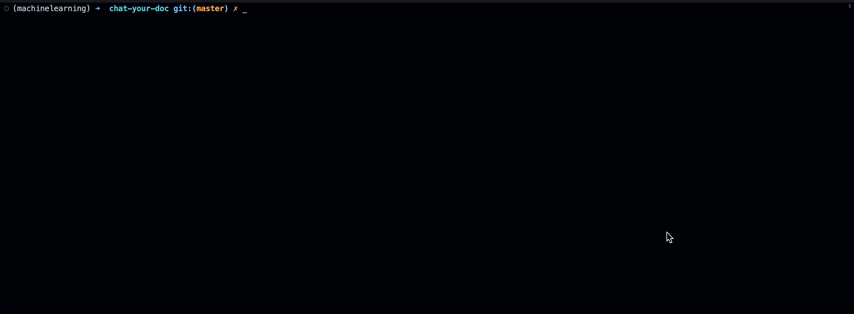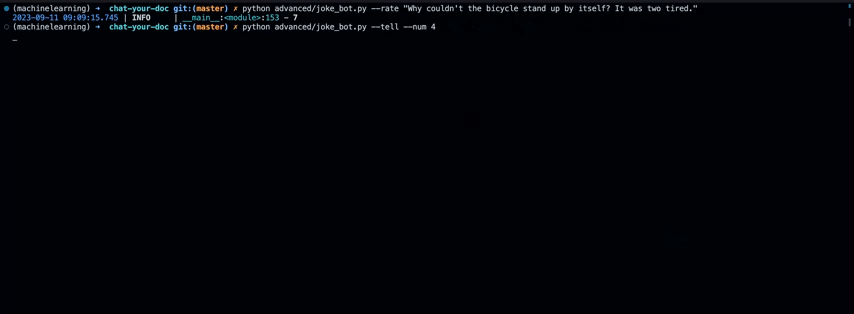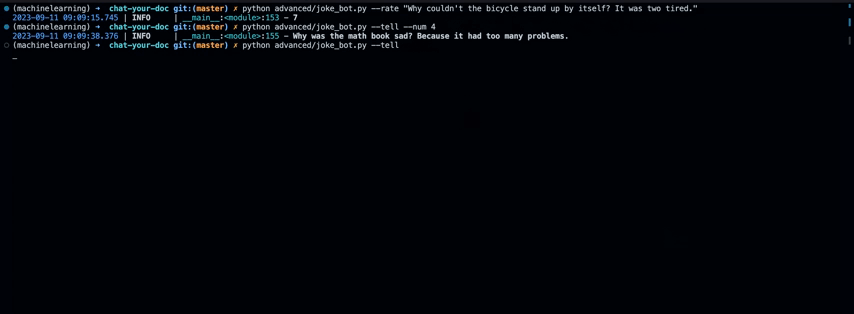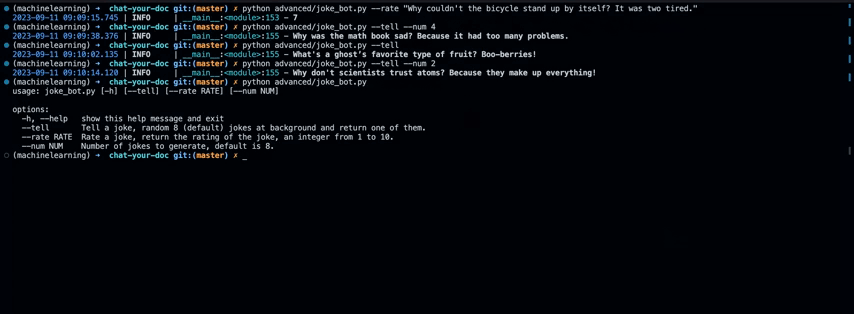 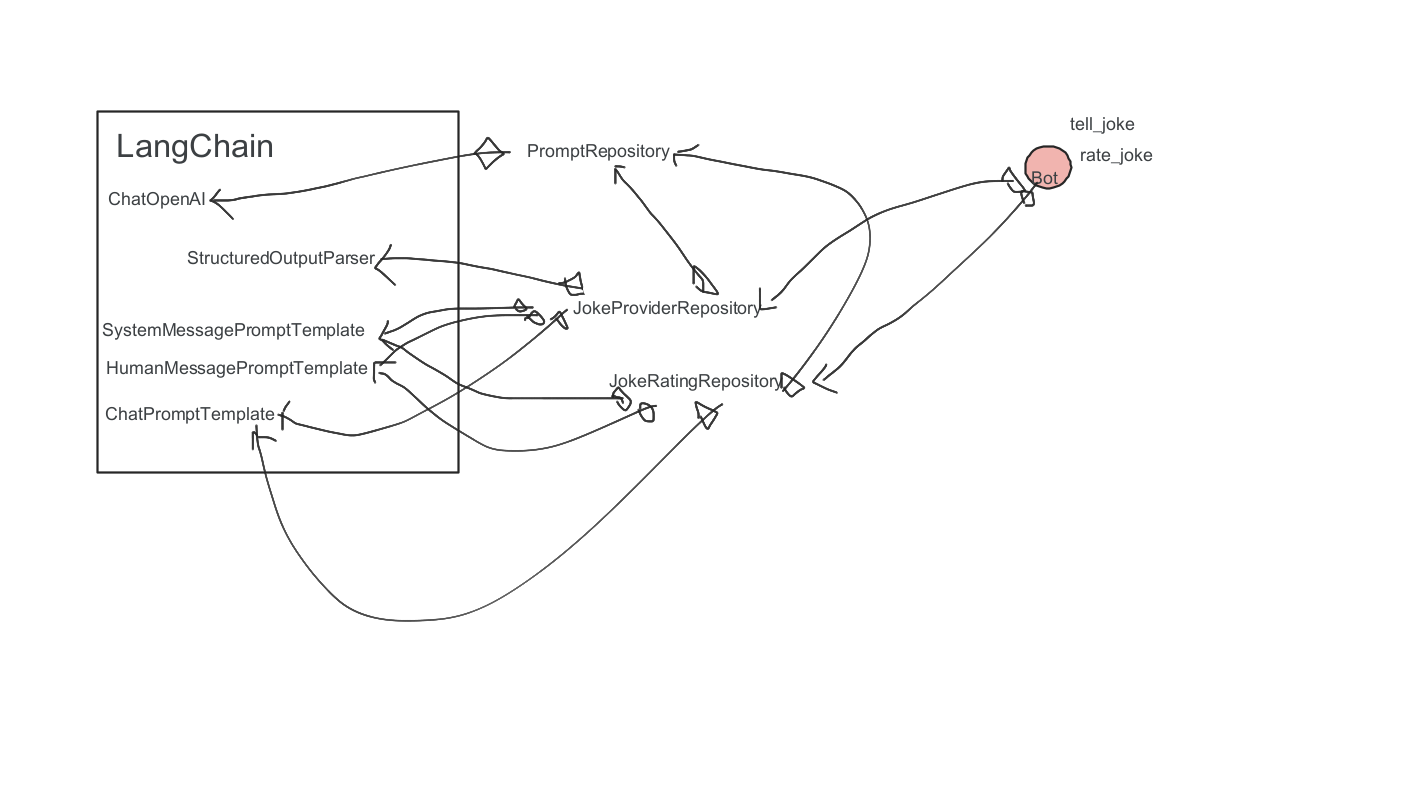 |
| chat_ur_docs.py | Chat with documents freely | streamlit run advanced/chat_ur_docs.py --server.port 8004 --server.enableCORS false | read 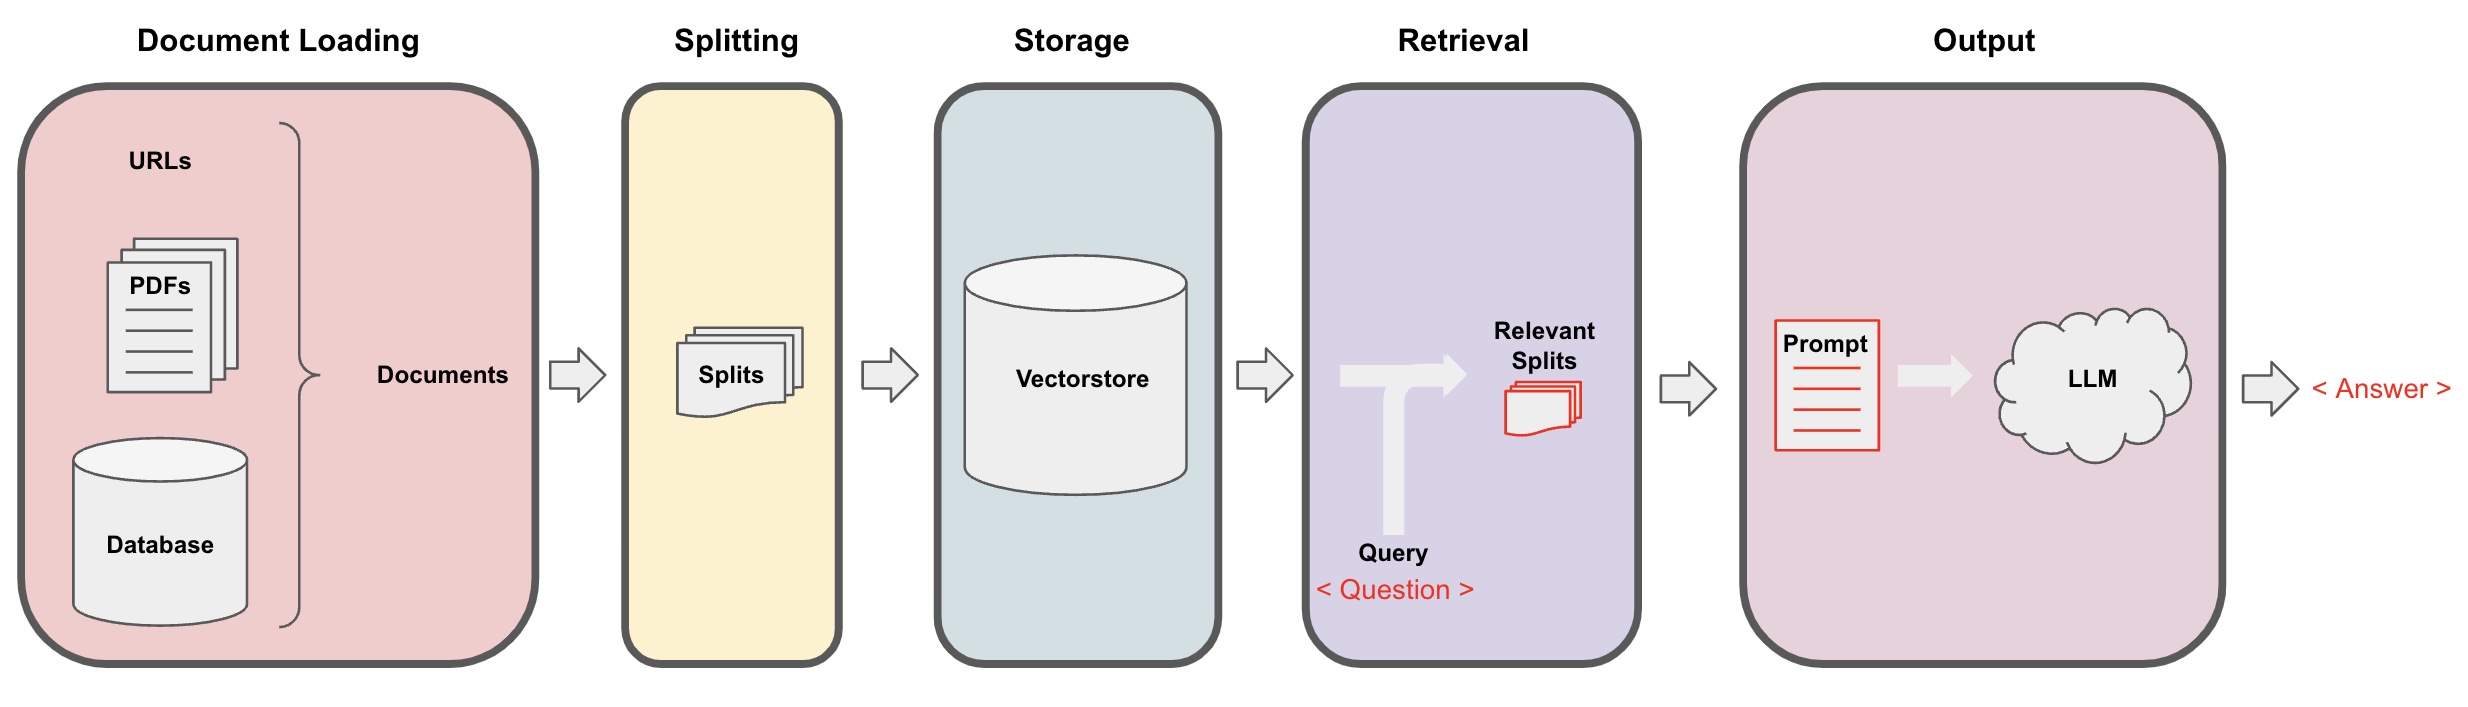 |
| image_auto_annotation.py | Use LLM, LangChain Agent and GroundingDINO to detect objects on images freely (auto-annotation) | streamlit run advanced/image_auto_annotation.py --server.port 8006 --server.enableCORS false | read 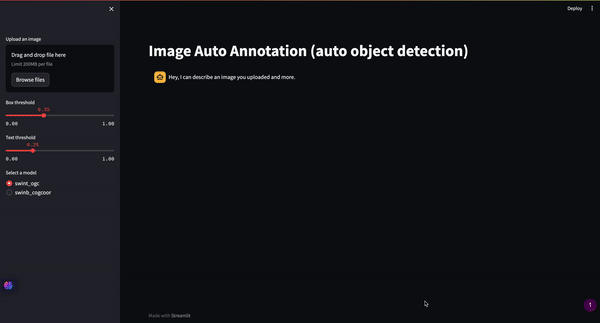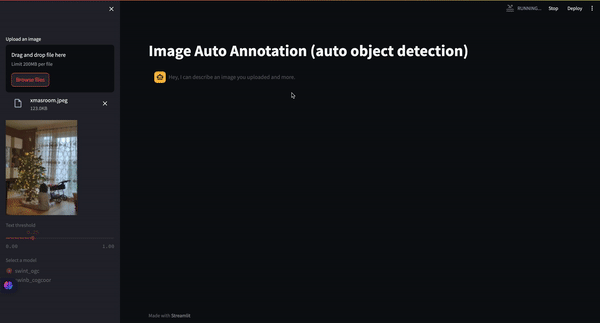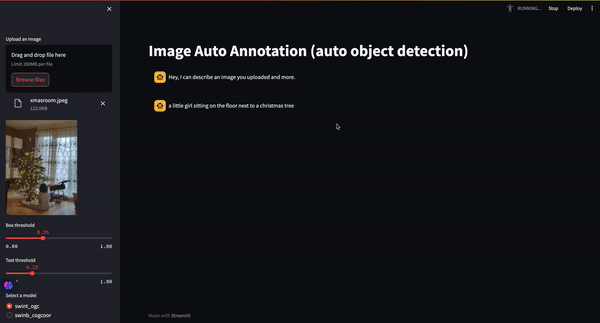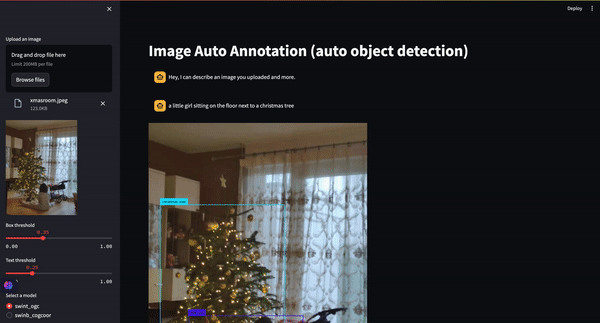 |
| langgraph_auto_annotation.py | LangGraph, YOLOv8 World, Gemma, BlipProcessor or OpenAI-Vision to detect on image freely (auto-annotation) | streamlit run advanced/langgraph_auto_annotation.py --server.port 8006 --server.enableCORS false | 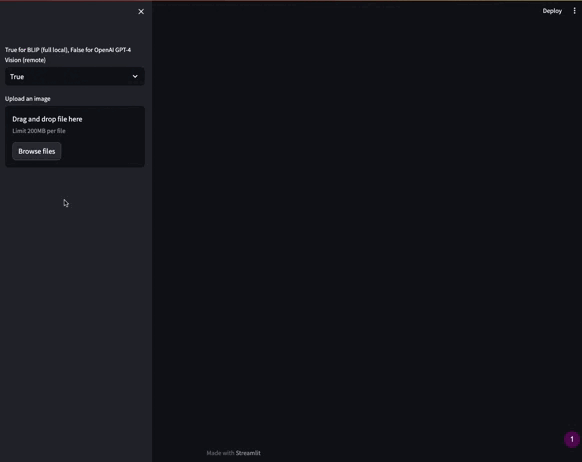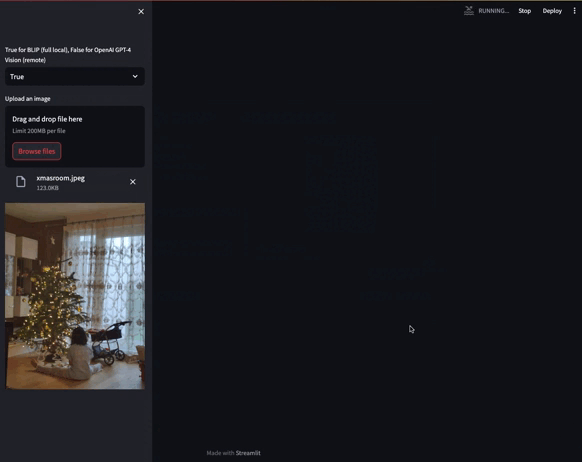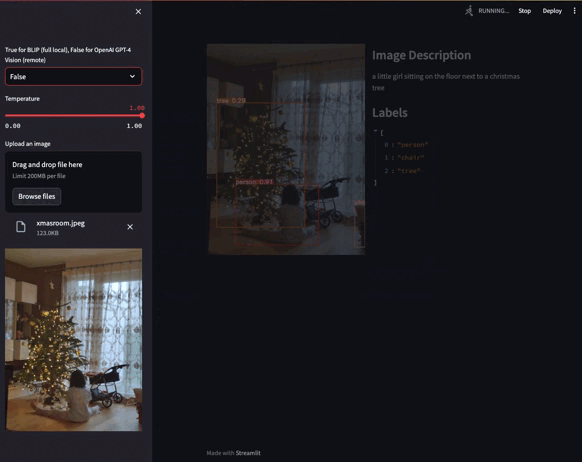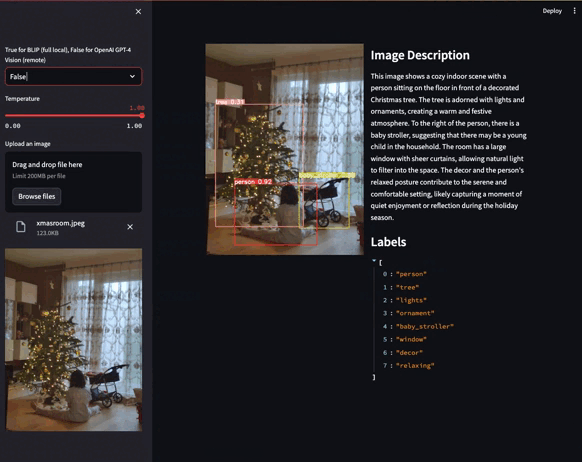 |
| adv_rag.py | Advanced RAG approaches, use partition_pdf to extract texts and tables and analyze them | streamlit run advanced/adv_rag.py --server.port 8007 --server.enableCORS false | read |
| llamaindex_vector_summary_retriever.py | Use LlamaIndex to apply vectory/summary pattern by using multi retrievers | streamlit run advanced/llamaindex_multi_vector_summary.py --server.port 8008 --server.enableCORS false | read 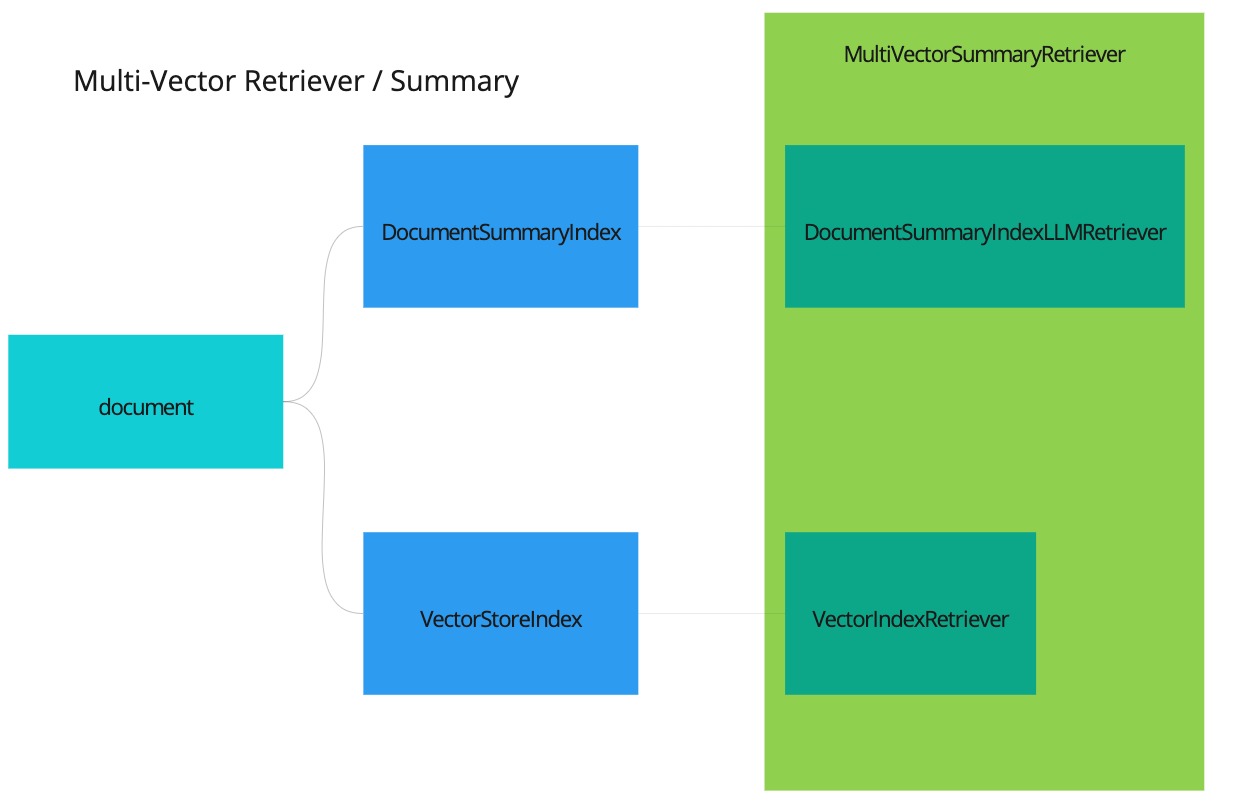 |
| llamaindex_vector_summary_agent.py | Use LlamaIndex to apply vectory/summary pattern by using agent | streamlit run advanced/llamaindex_multi_vector_summary_agent.py --server.port 8009 --server.enableCORS false | read 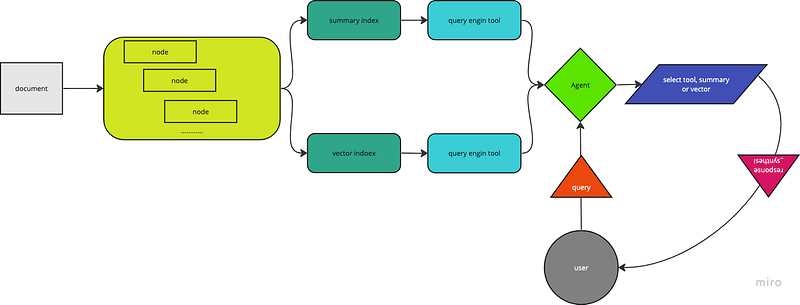 |
| multi_queries.py | Use LlamaIndex and LangChain to apply the multi-queries pattern, including build method of the LangChain, and custom retriever based solution in Llama-Index, also the other sub-query based solutions | streamlit run advanced/multi_queries.py --server.port 8010 --server.enableCORS false | read 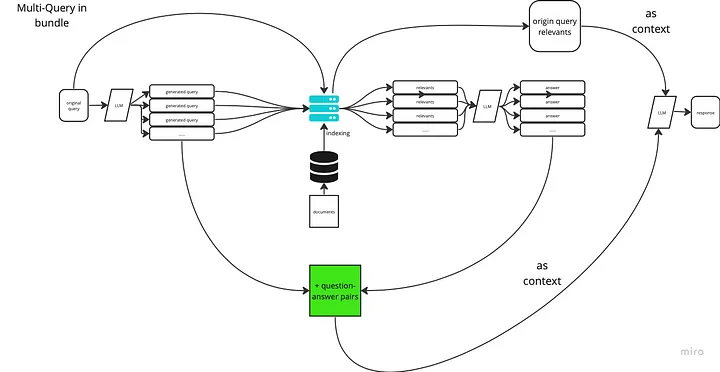 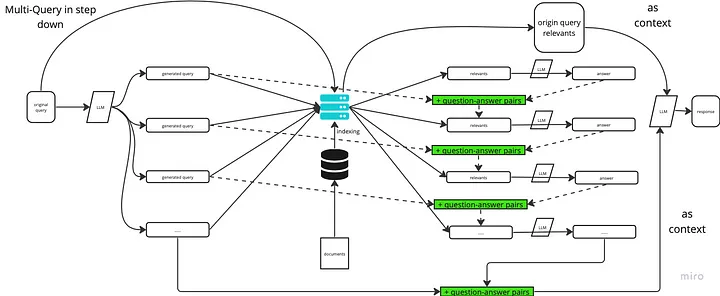 |
| langgraph_agent_mailtool.py | Use LangGraph (Groq is used for agent) to driven a Email deliever of the custom receipts. | streamlit run advanced/langgraph_agent_mailtool.py --server.port 8011 --server.enableCORS false | 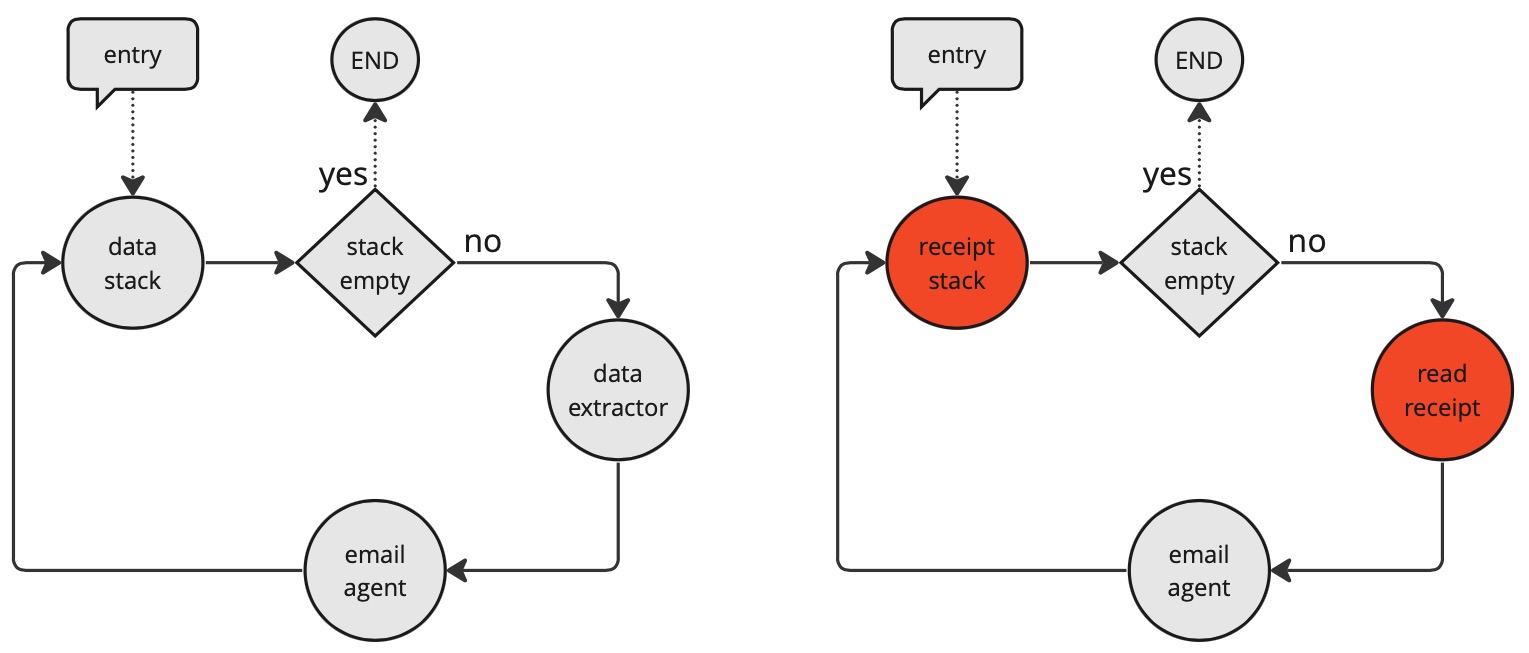 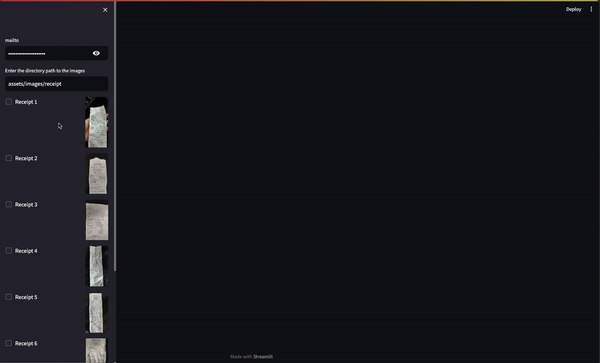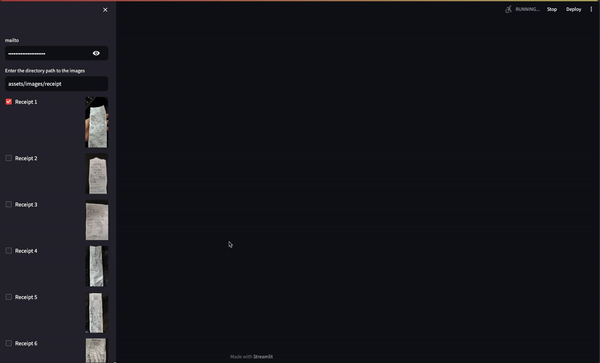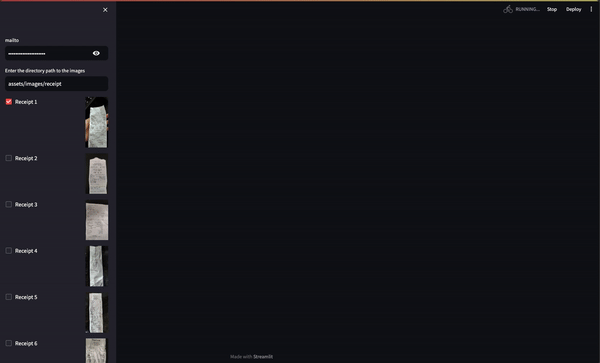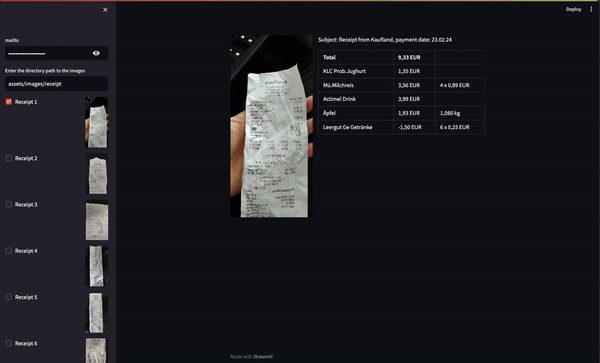 |
| llamaindex_adaptive_rag.py | App that implements the adaptive RAG pattern | streamlit run advanced/llamaindex_adaptive_rag.py --server.port 8012 --server.enableCORS false | 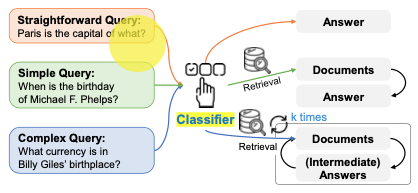 |
| Notebook | Description | Demo |
|---|---|---|
| audio2text2LLM.ipynb | Basic audio to text and summary | 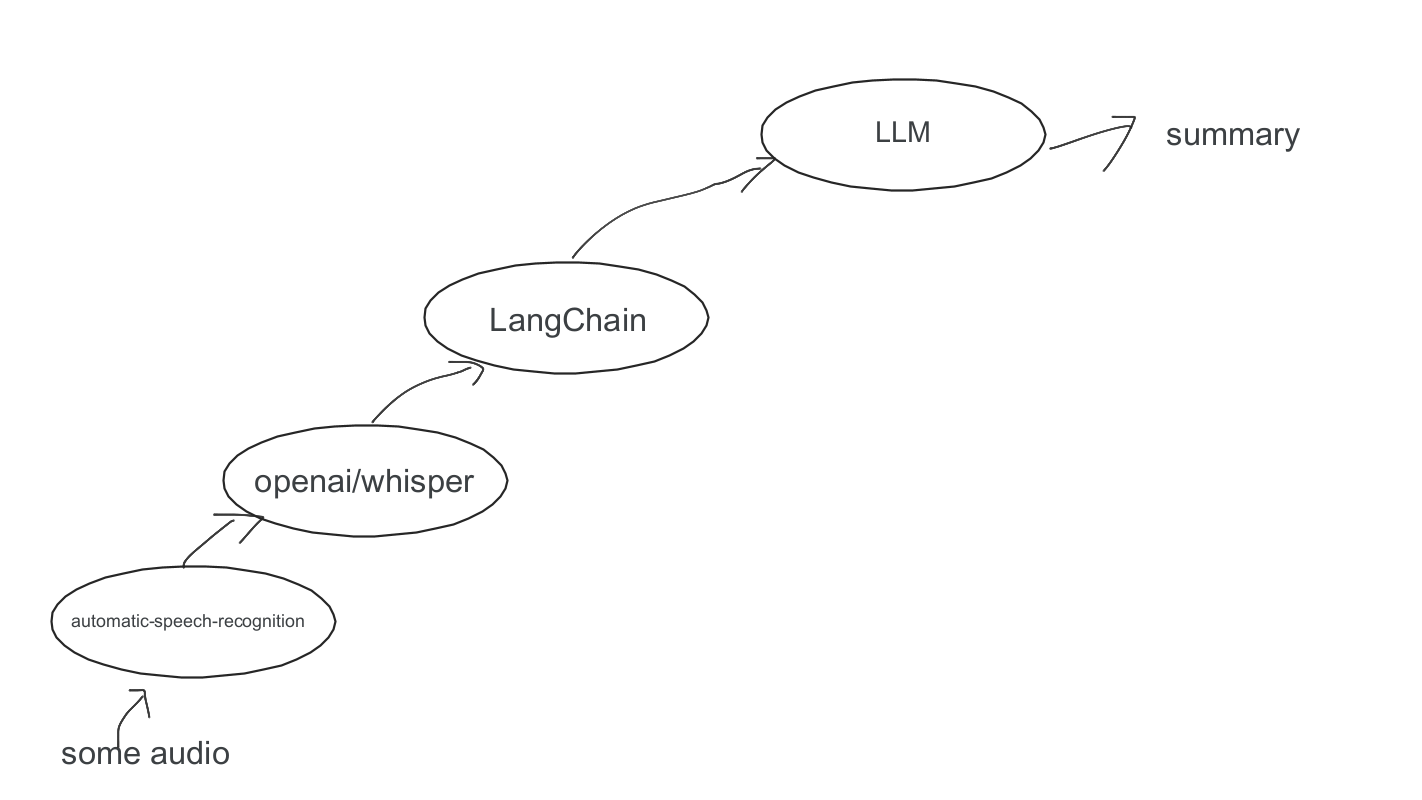 |
| audio2text2music.ipynb | audiocraft, Whisper, automatic-speech-recognition, speech to text, generate music by the text, synthesis speech+BGM | 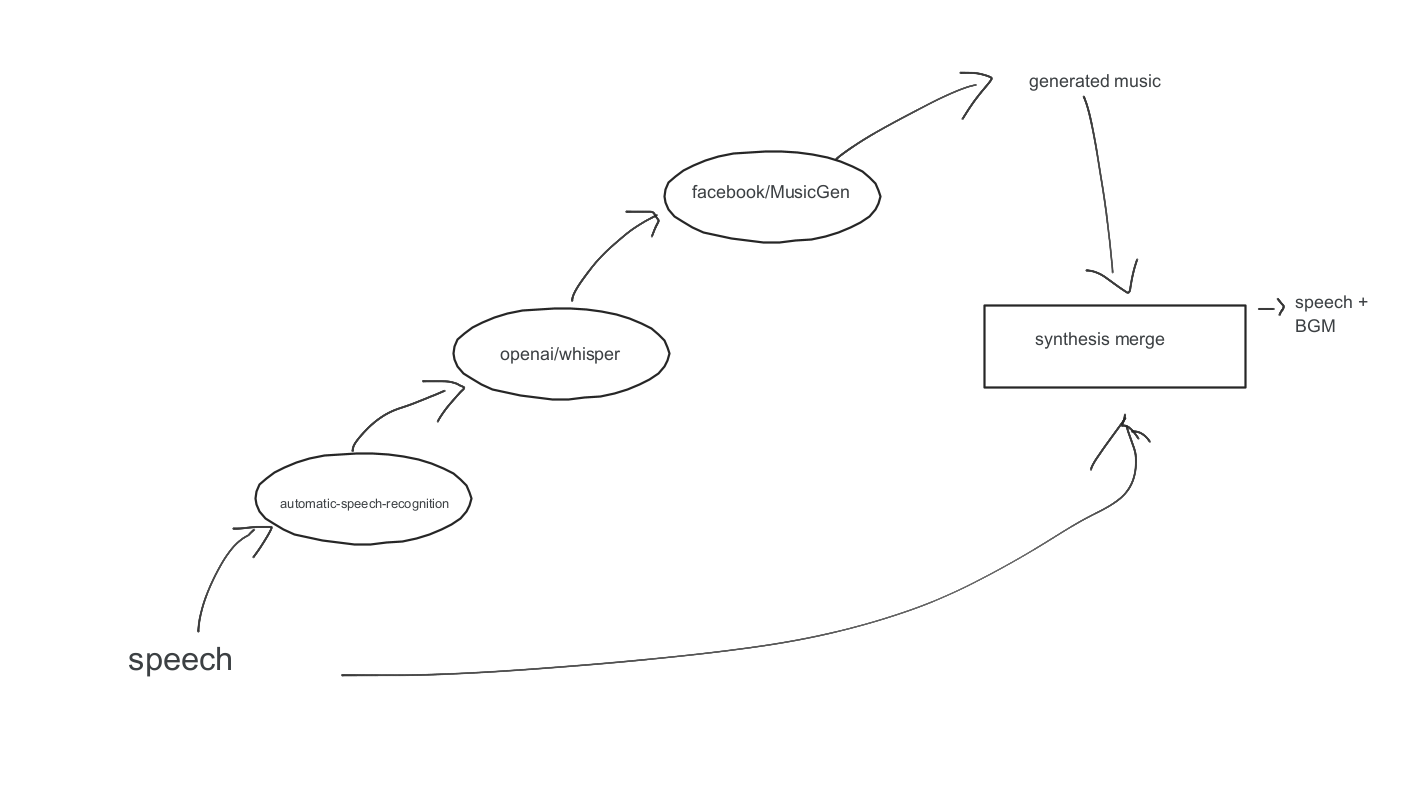 |
| image_description.ipynb | Use OpenAI Vision or blip-image-captioning-base, blip-image-captioning-large, a use-case to get the image description. | |
| image_desc2music.ipynb | audiocraft blip-image-captioning-base, blip-image-captioning-large, a use-case to get the image description and generate music based on the image | |
| langchain_agent_scratch.ipynb | Create the agent from scratch in langchain | read 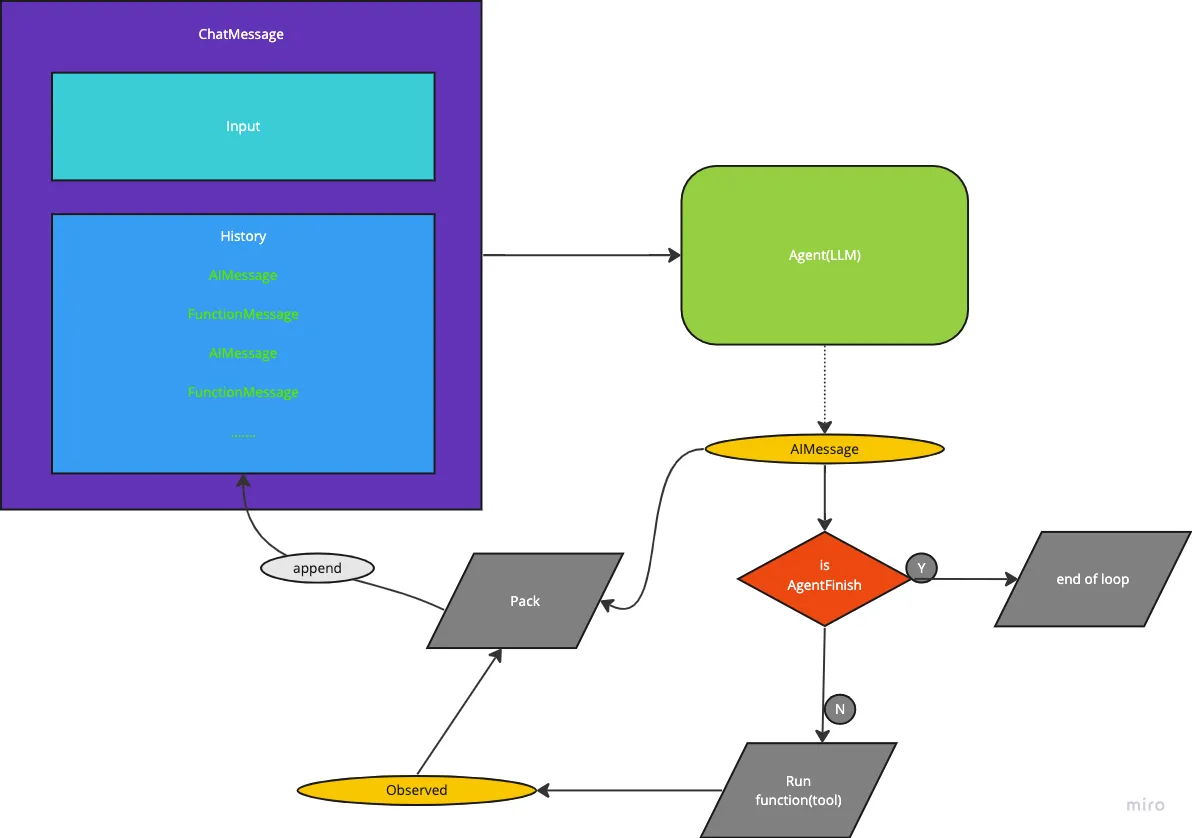 |
| llamaindex_agent_from_scratch.ipynb | Create the agent from scratch with LlamaIndex | read 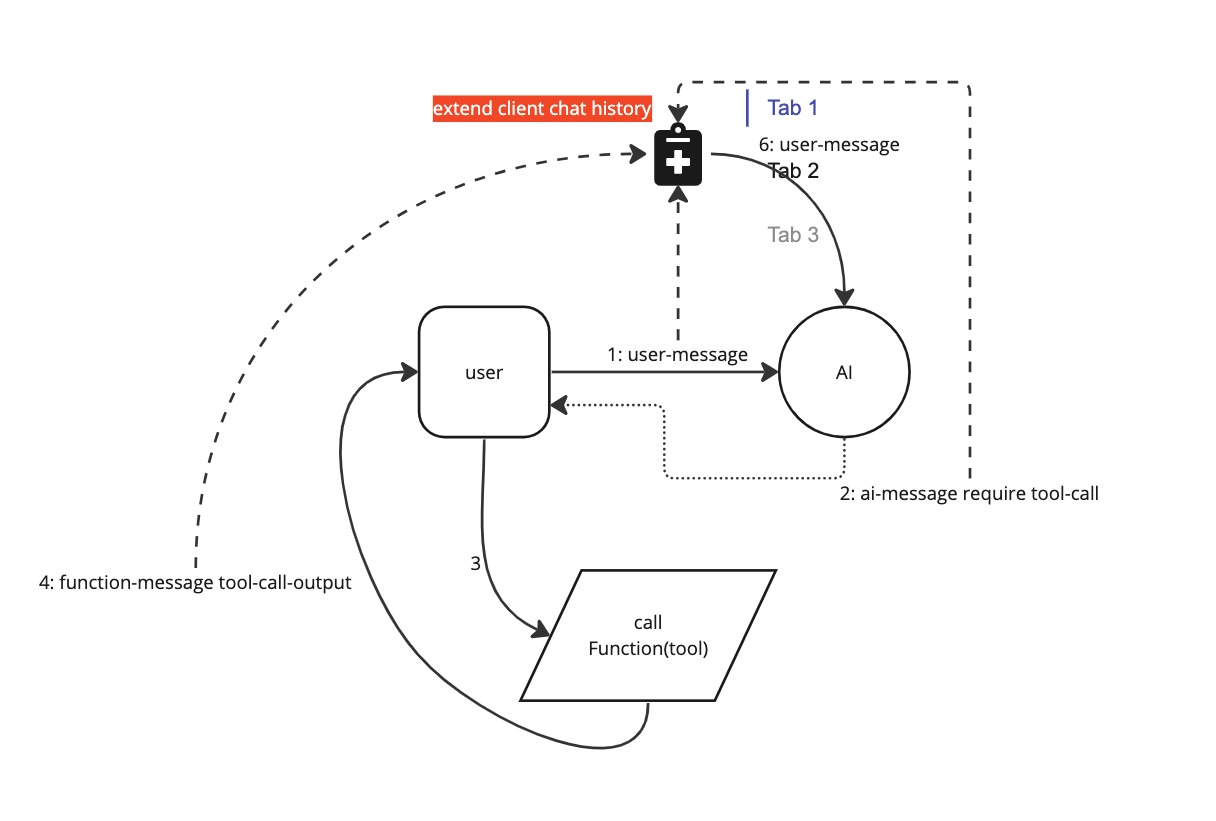 |
| llamaindex_vector_summary_retriever.ipynb | Use LlamaIndex to apply vectory/summary pattern by using multi retrievers | read |
| llamaindex_vector_summary_agent.ipynb | Use LlamaIndex to apply vectory/summary pattern by using agent | read |
| multi_queries_retrieval.ipynb | Use LlamaIndex and LangChain to apply mutli-query pattern for RAG | read 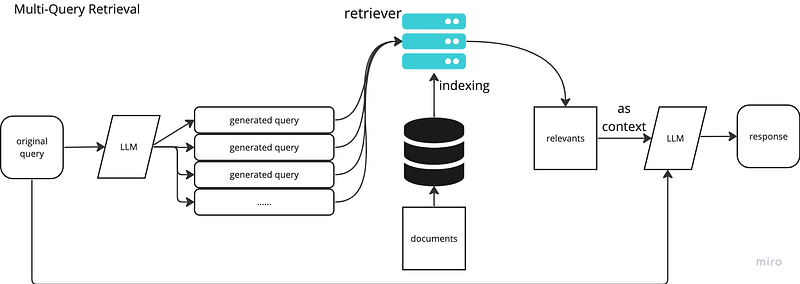 |
| yolo8_world_and_openai_vision.py | Use YoLoV8 World and OpenAI Vision together to enchance image auto-annotation | 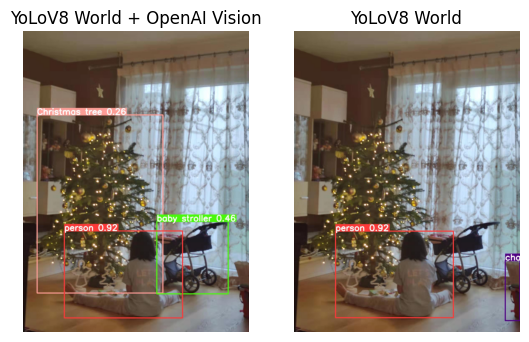 |
| yolo8_world_and_gemma.py | Use YoLoV8 World, OpenAI Vision, Ollama Gemma integration to enchance image auto-annotation | |
| langgraph_helloworld.ipynb | hello,world version of langgraph | read 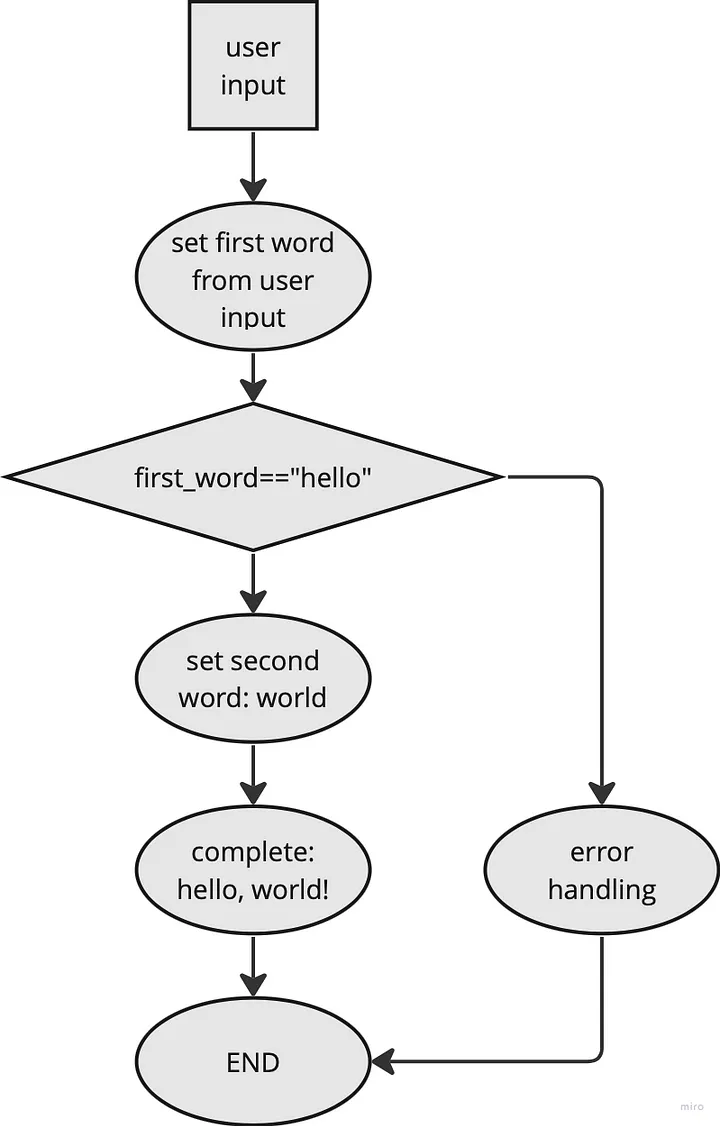 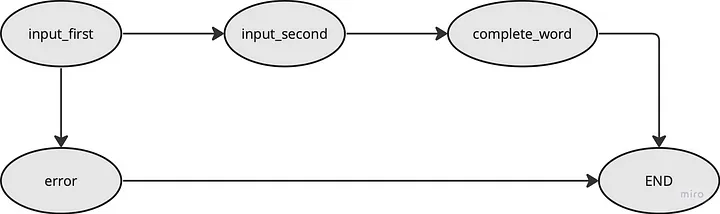 |
| langchain_agent_gmail.ipynb | Use LangGraph to driven a Email deliever of the custom receipts. | |
| hyde_retrieval.ipynb | Implementation of HyDE retrieval by LlamaIndex, hybrid, local or remote LLMs. | read  |
| agent_gpu_demand_prediction.ipynb | Use pure Agent (LangChain) to generate a report paper of global GPU demand prediction. | read,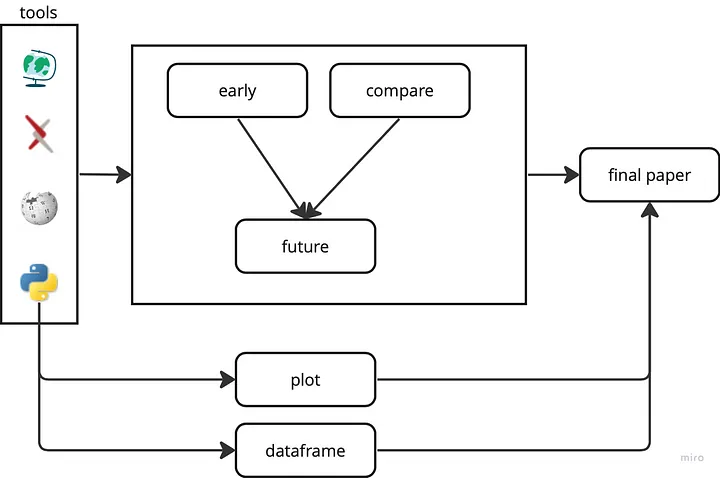 , 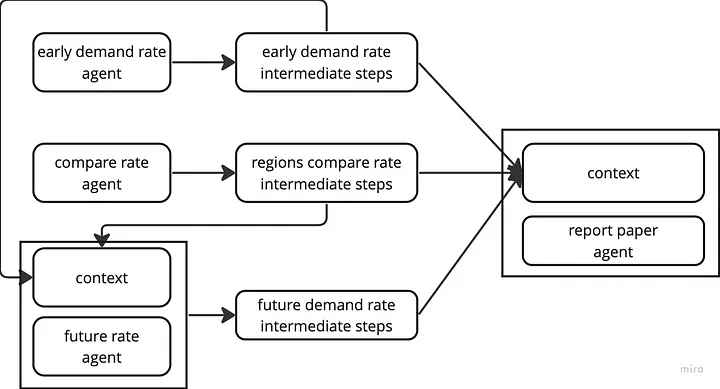 |
| multi_user_conversation.ipynb | Try to do multi-user chat with LangChain, ConversationBufferMemory, ConversationChain, RunnableWithMessageHistory, ChatMessageHistory, convert_openai_messages and LCEL | read read (Follow-up) |
| DenseXRetrieval.ipynb | Dense X Retrieval: What Retrieval Granularity Should We Use? by using Llama Packs | |
| llamaindex_query_router.ipynb | LLM application through query routing and long-context, a type of reflection flow based on the user query. Inspired by Retrieval Augmented Generation or Long-Context LLMs? A Comprehensive Study and Hybrid Approach |
94 followers · starred Sep 2024
Chat Your Doc is an experimental project aimed at exploring various applications based on LLM. Although it is nominally a chatbot project, its purpose is broader. The project explores various applications using tools such as LangChain, LlamaIndex. In the "Lab Apps" section, you can find many examples, including simple and complex ones. The project focuses on researching and exploring various LLM applications, while also incorporating other fields such as UX and computer vision. The "Lab App" section includes a table with links to various apps, descriptions, launch commands, and demos.
Also, take a look at a use-case known as Knowledge Center that leverages different RAG or Chunking techniques in this repository.
streamlit run simple/multimodal_chat.py --server.port 8000 --server.enableCORS falseFor OpenAI, set API-KEY to your environment variables.
export OPENAI_API_KEY="sk-$TJHGFHJDSFDGAFDFRTHT§$%$%&§%&"
conda env create -n chat-ur-doc -f environment.yml
conda activate chat-ur-doc
pip install -r requirements.txt
ref: https://python.langchain.com/docs/modules/data_connection/vectorstores/
Chroma, FAISS
pip install chromadb
pip install faiss-cpu
LLM fine-tuning step: Tokenizing
Chat with your PDF (Streamlit Demo)
LLM, LangChain Agent, Computer Vision
How to Use OpenAI Assistants (API)
Experience with the LangChain App Template
wine price app, prompt and query wine price. The application has been created, just need to create data, install Poetry and run it.
Full instructions for creating a LangChain App Template can be found here: LangChain App Template
Llama-Index: RAG with Vector and Summary
Multi-Retrievers with Vector and Summary pattern implementation.
Llama-Index: RAG with Vector and Summary by using Agent
Agent for Vector and Summary pattern implementation.
Intuitively create an agent from scratch with LangChain.
Intuitively create an agent from scratch with LlamaIndex.
Multi-Query Retrieval with RAG
Enhance query context with intermediate queries during RAG to improve information retrieval for the original query.
Explain how prio-reasoning works in LangChain(qa-chain with refine) and LlamaIndex (MultiStepQueryEngine).
Introduce the Multi-Query pattern in bundle and step-down solutions.
Introduce the hello,world version use-case with LangGraph, just simple example to kick off the topic.
Quick Tour: Ollama+Gemma+LangChain
Use ollama to deploy and use Gemma with langchain on local machine.
RAG with Hypothetical Document Embeddings(HyDE)
Hypothetical Document Embeddings, two-steps process of RAG. Implementation of HyDE retrieval by LlamaIndex, hybrid, local or remote LLMs.
LangChain: Use LLM Agent for World GPU Demand Prediction Report
Reflecting the analytical methods of the AI era, based on the Agent mechanism and generative AI, intelligently generates necessary information and code.
LangChain: Multi-User Conversation Support
By using some methods, make the conversation able to happen among multiple users, achieving the basic of a simple “group conversation”.
LangChain: History-Driven RAG Enhanced By LLM-Chain Routing LangChain
Using LLM to predict the routing of the chain and achieve Retrieval Augmented Generation with help of conversation history applying HyDE or refined standalone query.
LangChain: Multi-User Conversation Support(Follow-up)
A follow-up read: Use Cohere’s documents and a special field in additional_kwargsfeature to enhance the organization of information in multi-user conversation.
(Llama-Index Workflow)Translation Agent via Reflection Workflow
Implemention of Translation Agent: Agentic translation using reflection workflow with Llama-Index workflow framework.
Ollama Workaround: DeepSeek R1 Tool Support
Tool support of Ollama served DeepSeek R1 is still not very well, in this text there is a solution to workaround it and some how we can call tool according to the model response.
| App | Description | Launch | Demo |
|---|---|---|---|
| i-ask.sh | Simply ask & answer via OpenAI API | i-ask.sh "Who is Joe Biden?" | |
| chat_openai.py | Just one chat session | streamlit run simple/chat_openai.py --server.port 8000 --server.enableCORS false | |
| open_api_llm_app.py | Use OpenAI LLM to answer simple question | streamlit run simple/open_api_llm_app.py --server.port 8001 --server.enableCORS false | |
| read_html_app.py | Get html content and chunk | streamlit run simple/read_html_app.py --server.port 8002 --server.enableCORS false | |
| chatbot.py | Basic chatbot | streamlit run simple/chatbot.py --server.port 8003 --server.enableCORS false | |
| retriever.py | Use concept of retriever and LangChain Expression Language (LCEL) | streamlit run simple/retriever.py --server.port 8004 --server.enableCORS false | |
| hello_llamaindex.py | A very simple LlamaIndex to break ice of the story. | streamlit run simple/hello_llamaindex.py --server.port 8005 --server.enableCORS false | |
| llamaindex_context.py | A simple app of LlamaIndex, introduce of context for configuration, StorageContext, ServiceContext. | streamlit run simple/llamaindex_context.py --server.port 8006 --server.enableCORS false | |
| llamaindex_hub_simple.py | A simple app of LlamaIndex, introduce of load stuff from https://llamahub.ai/. | streamlit run simple/llamaindex_hub_simple.py --server.port 8007 --server.enableCORS false | |
| prio_reasoning_context.py | A simple app that based on RAG with Prio-Reasoning pattern in LlamaIndex or LangChain. | streamlit run simple/prio_reasoning_context.py --server.port 8008 --server.enableCORS false | read |
| ollama_gemma.py | A Ollama for Gemma integration with the langchain. | read | |
| nvidia_vs_groq.py | Compare Nvidia API and Groq, by using llama2 and mixtral_8x7b | streamlit run simple/nvidia_vs_groq.py --server.port 8009 --server.enableCORS false | read |
| llamaindex_workflow_reflection_flow.py | Implemention of Translation Agent: Agentic translation using reflection workflow with Llama-Index workflow framework | streamlit run simple/llamaindex_workflow_reflection_flow.py --server.port 8009 --server.enableCORS false | read |
| langchain_citation_chain.py | (LangChain) Retrieval Augmented Generation with Citations, inspired by Llama-index version | Llama-index version | |
| lc_deepseek_tool_call.py | Use some workarounds to apply tool calling on Ollama served DeepSeek R1 | python simple/lc_deepseek_tool_call.py | Ollama Workaround: DeepSeek R1 Tool Support |
| li_deepseek_agent.py | LlamaIndex to apply ReAct with Ollama served DeepSeek R1 | python simple/li_deepseek_agent.py |
| App | Description | Launch | Demo |
|---|---|---|---|
| sim_app.py | Use the vector database to save file in chunks and retrieve similar content from the database | streamlit run intermediate/sim_app.py --server.port 8002 --server.enableCORS false | |
| llm_chain_translator_app.py | Use LLMChain to do language translation | streamlit run intermediate/llm_chain_translator_app.py --server.port 8003 --server.enableCORS false | |
| html_summary_chat_app.py | Summary html content | streamlit run intermediate/html_summary_chat_app.py --server.port 8004 --server.enableCORS false | |
| html_2_json_app.py | Summary html keypoints into keypoint json | streamlit run intermediate/html_2_json_app.py --server.port 8005 --server.enableCORS false | |
| assistants.py | Use OpenAI Assistants API in different ways | streamlit run intermediate/assistants.py --server.port 8006 --server.enableCORS false | read |
| hyde_retrieval.py | Implementation of HyDE retrieval by LlamaIndex, hybrid, local or remote LLMs. | streamlit run intermediate/hyde_retrieval.py --server.port 8007 --server.enableCORS false | read |
| App | Description | Launch | Demo |
|---|---|---|---|
| qa_chain_pdf_app.py | Ask info from PDF file, chat with it | streamlit run advanced/qa_chain_pdf_app.py --server.port 8004 --server.enableCORS false | |
| faiss_app.py | Ask info from a internet file, find similar docs and answer with VectorDBQAWithSourcesChain | streamlit run advanced/faiss_app.py --server.port 8005 --server.enableCORS false | |
| html_2_json_output_app.py | Load html content and summary into json objects | streamlit run advanced/html_2_json_output_app.py --server.port 8006 --server.enableCORS false | |
| joke_bot.py | Prompt engineering to get one random joke or rate one joke | python advanced/joke_bot.py --rate "Why couldn't the bicycle stand up by itself? It was two tired." or python advanced/joke_bot.py --tell --num 4 | |
| chat_ur_docs.py | Chat with documents freely | streamlit run advanced/chat_ur_docs.py --server.port 8004 --server.enableCORS false | read |
| image_auto_annotation.py | Use LLM, LangChain Agent and GroundingDINO to detect objects on images freely (auto-annotation) | streamlit run advanced/image_auto_annotation.py --server.port 8006 --server.enableCORS false | read |
| langgraph_auto_annotation.py | LangGraph, YOLOv8 World, Gemma, BlipProcessor or OpenAI-Vision to detect on image freely (auto-annotation) | streamlit run advanced/langgraph_auto_annotation.py --server.port 8006 --server.enableCORS false | |
| adv_rag.py | Advanced RAG approaches, use partition_pdf to extract texts and tables and analyze them | streamlit run advanced/adv_rag.py --server.port 8007 --server.enableCORS false | read |
| llamaindex_vector_summary_retriever.py | Use LlamaIndex to apply vectory/summary pattern by using multi retrievers | streamlit run advanced/llamaindex_multi_vector_summary.py --server.port 8008 --server.enableCORS false | read |
| llamaindex_vector_summary_agent.py | Use LlamaIndex to apply vectory/summary pattern by using agent | streamlit run advanced/llamaindex_multi_vector_summary_agent.py --server.port 8009 --server.enableCORS false | read |
| multi_queries.py | Use LlamaIndex and LangChain to apply the multi-queries pattern, including build method of the LangChain, and custom retriever based solution in Llama-Index, also the other sub-query based solutions | streamlit run advanced/multi_queries.py --server.port 8010 --server.enableCORS false | read |
| langgraph_agent_mailtool.py | Use LangGraph (Groq is used for agent) to driven a Email deliever of the custom receipts. | streamlit run advanced/langgraph_agent_mailtool.py --server.port 8011 --server.enableCORS false | |
| llamaindex_adaptive_rag.py | App that implements the adaptive RAG pattern | streamlit run advanced/llamaindex_adaptive_rag.py --server.port 8012 --server.enableCORS false | |
| Notebook | Description | Demo |
|---|---|---|
| audio2text2LLM.ipynb | Basic audio to text and summary | |
| audio2text2music.ipynb | audiocraft, Whisper, automatic-speech-recognition, speech to text, generate music by the text, synthesis speech+BGM | |
| image_description.ipynb | Use OpenAI Vision or blip-image-captioning-base, blip-image-captioning-large, a use-case to get the image description. | |
| image_desc2music.ipynb | audiocraft blip-image-captioning-base, blip-image-captioning-large, a use-case to get the image description and generate music based on the image | |
| langchain_agent_scratch.ipynb | Create the agent from scratch in langchain | read |
| llamaindex_agent_from_scratch.ipynb | Create the agent from scratch with LlamaIndex | read |
| llamaindex_vector_summary_retriever.ipynb | Use LlamaIndex to apply vectory/summary pattern by using multi retrievers | read |
| llamaindex_vector_summary_agent.ipynb | Use LlamaIndex to apply vectory/summary pattern by using agent | read |
| multi_queries_retrieval.ipynb | Use LlamaIndex and LangChain to apply mutli-query pattern for RAG | read |
| yolo8_world_and_openai_vision.py | Use YoLoV8 World and OpenAI Vision together to enchance image auto-annotation | |
| yolo8_world_and_gemma.py | Use YoLoV8 World, OpenAI Vision, Ollama Gemma integration to enchance image auto-annotation | |
| langgraph_helloworld.ipynb | hello,world version of langgraph | read |
| langchain_agent_gmail.ipynb | Use LangGraph to driven a Email deliever of the custom receipts. | |
| hyde_retrieval.ipynb | Implementation of HyDE retrieval by LlamaIndex, hybrid, local or remote LLMs. | read |
| agent_gpu_demand_prediction.ipynb | Use pure Agent (LangChain) to generate a report paper of global GPU demand prediction. | read,, |
| multi_user_conversation.ipynb | Try to do multi-user chat with LangChain, ConversationBufferMemory, ConversationChain, RunnableWithMessageHistory, ChatMessageHistory, convert_openai_messages and LCEL | read read (Follow-up) |
| DenseXRetrieval.ipynb | Dense X Retrieval: What Retrieval Granularity Should We Use? by using Llama Packs | |
| llamaindex_query_router.ipynb | LLM application through query routing and long-context, a type of reflection flow based on the user query. Inspired by Retrieval Augmented Generation or Long-Context LLMs? A Comprehensive Study and Hybrid Approach |
94 followers · starred Sep 2024



