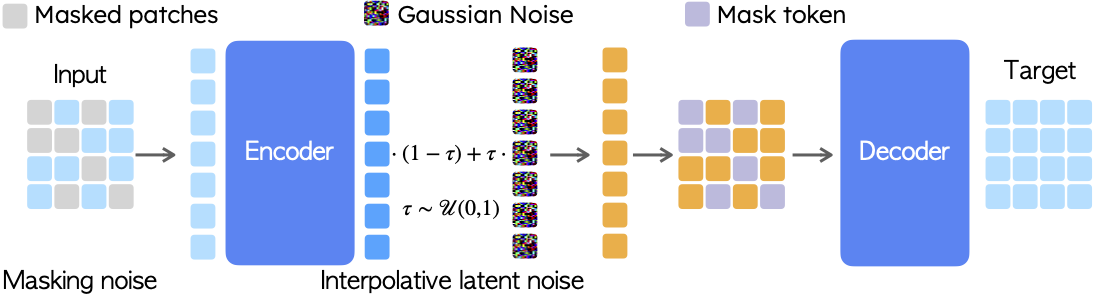
This is a PyTorch/GPU implementation of the paper Latent Denoising Makes Good Visual Tokenizers:
@article{yang2025detok,
  title={Latent Denoising Makes Good Visual Tokenizers},
  author={Jiawei Yang and Tianhong Li and Lijie Fan and Yonglong Tian and Yue Wang},
  journal={arXiv preprint arXiv:2507.15856},
  year={2025}
}
This repo contains:
Download the code:
git clone https://github.com/Jiawei-Yang/detok.git
cd detok
Create and activate conda environment:
conda create -n detok python=3.10 -y && conda activate detok
pip install -r requirements.txt
Create data/ folder by mkdir data/ then download ImageNet dataset. You can either:
data/imagenet/ln -s /path/to/your/imagenet data/imagenetCreate data directory and download required files:
mkdir data/
# Download everything from huggingface
huggingface-cli download jjiaweiyang/l-DeTok --local-dir released_model
mv released_model/train.txt data/
mv released_model/val.txt data/
mv released_model/fid_stats data/
mv released_model/imagenet-val-prc.zip ./data/

# Unzip: imagenet-val-prc.zip for precision & recall evaluation
python -m zipfile -e ./data/imagenet-val-prc.zip ./data/
Your data directory should be organized as follows:
data/
├── fid_stats/          # FID statistics
│   ├── adm_in256_stats.npz
│   └── val_fid_statistics_file.npz
├── imagenet/           # ImageNet dataset (or symlink)
│   ├── train/
│   └── val/
├── imagenet-val-prc/   # Precision-recall data
├── train.txt           # Training file list
└── val.txt             # Validation file list
For convenience, our pre-trained models will be available on Hugging Face:
| Model | Type | Params | Hugging Face |
|---|---|---|---|
| DeTok-BB | Tokenizer | 172M | 🤗 detok-bb |
| DeTok-BB-decoder_ft | Tokenizer | 172M | 🤗 detok-bb-decoder_ft |
| MAR-Base | Generator | 208M | 🤗 mar-base |
| MAR-Large | Generator | 479M | 🤗 mar-large |
FID-50k with CFG:
| cfg | MAR Model | FID-50K | Inception Score |
|---|---|---|---|
| 3.9 | MAR-Base + DeTok-BB | 1.61 | 289.7 |
| 3.9 | MAR-Base + DeTok-BB-decoder_ft | 1.55 | 291.0 |
| 3.4 | MAR-Large + DeTok-BB | 1.43 | 303.5 |
| 3.4 | MAR-Large + DeTok-BB-decoder_ft | 1.32 | 304.1 |
Run our demo using notebook at demo.ipynb
Train DeTok tokenizer with denoising:
project=tokenizer_training
exp_name=detokBB-g3.0-m0.7-200ep
batch_size=32  # global batch size = batch_size x num_nodes x 8 = 1024
num_nodes=4    # adjust for your multi-node setup
YOUR_WANDB_ENTITY=""  # change to your wandb entity

torchrun --nproc_per_node=8 --nnodes=$num_nodes --node_rank=${NODE_RANK} --master_addr=${MASTER_ADDR} --master_port=${MASTER_PORT} \
    main_reconstruction.py \
    --project $project --exp_name $exp_name --auto_resume \
    --batch_size $batch_size --model detok_BB \
    --gamma 3.0 --mask_ratio 0.7 \
    --online_eval \
    --epochs 200 --discriminator_start_epoch 100 \
    --data_path ./data/imagenet/train \
    --entity $YOUR_WANDB_ENTITY --enable_wandb
Decoder fine-tuning:
project=tokenizer_training
exp_name=detokBB-g3.0-m0.7-200ep-decoder_ft-100ep
batch_size=32
num_nodes=4
pretrained_tok=work_dirs/tokenizer_training/detokBB-g3.0-m0.7-200ep/checkpoints/latest.pth
YOUR_WANDB_ENTITY=""

torchrun --nproc_per_node=8 --nnodes=$num_nodes --node_rank=${NODE_RANK} --master_addr=${MASTER_ADDR} --master_port=${MASTER_PORT} \
    main_reconstruction.py \
    --project $project --exp_name $exp_name --auto_resume \
    --batch_size $batch_size --model detok_BB \
    --load_from $pretrained_tok \
    --online_eval --train_decoder_only \
    --perceptual_weight 0.1 \
    --gamma 0.0 --mask_ratio 0.0 \
    --blr 5e-5 --warmup_rate 0.05 \
    --epochs 100 --discriminator_start_epoch 0 \
    --data_path ./data/imagenet/train \
    --entity $YOUR_WANDB_ENTITY --enable_wandb
nohup torchrun --nproc_per_node=8 main_flowtok.py --project flowtok --exp_name flowtok_debug --use_znorm --batch_size 128 --model FlowTok_SS --token_channels 64 --mask_ratio 0.6 --noise_ratio 0.3 --epochs 100 --discriminator_start_epoch 50 --perceptual_weight 1. --reconstruction_weight 16 --diff_weight 1. --diff_leak 0.0001 --warmup_rate 0.02 --data_path /data/imagenet/train --auto_resume --vis_freq 1 > flowtok.debug.out &
nohup torchrun --nproc_per_node=8 main_contrast.py --project contrast --exp_name simcov1.0 --use_znorm --batch_size 256 --model detok_BB --gamma 1.0 --mask_ratio 0.0 --epochs 50 --discriminator_start_epoch 10 --perceptual_weight 1. --vis_freq 1 --warmup_rate 0.02 --data_path /data/imagenet/train --cons_type simcov1.0 --contrast_weight 0.01 --auto_resume --load_from released_model/detok-BB-gamm3.0-m0.7.pth >> contrast.simcov1.0.out &
nohup torchrun --nproc_per_node=8 main_contrast.py --project contrast --exp_name simcov0.3 --use_znorm --batch_size 224 --model detok_BB --gamma 1.0 --mask_ratio 0.0 --epochs 50 --discriminator_start_epoch 0 --perceptual_weight 1. --vis_freq 1 --warmup_rate 0.02 --data_path /data/imagenet/train --cons_type simcov0.3 --contrast_weight 0.1 --auto_resume --load_from released_model/detok-BB-gamm3.0-m0.7.pth --discriminator_weight 0.5 --d_loss_weight 1.0 > contrast.simcov0.3.out &
nohup torchrun --nproc_per_node=8 main_contrast.py --project contrast --exp_name mococov0.3 --use_znorm --batch_size 192 --model detok_BB --gamma 1.0 --mask_ratio 0.0 --epochs 50 --discriminator_start_epoch 0 --perceptual_weight 1. --vis_freq 1 --warmup_rate 0.02 --data_path /data/imagenet/train --cons_type mococov0.3 --contrast_weight 0.1 --auto_resume --load_from released_model/detok-BB-gamm3.0-m0.7.pth > contrast.mococov0.3.out &
nohup torchrun --nproc_per_node=8 main_contrast.py --project contrast --exp_name emamococov0.3 --use_znorm --batch_size 192 --model detok_BB --gamma 1.0 --mask_ratio 0.0 --epochs 50 --discriminator_start_epoch 0 --perceptual_weight 1. --vis_freq 1 --warmup_rate 0.02 --data_path /data/imagenet/train --cons_type emamococov0.3 --contrast_weight 0.1 --auto_resume --load_from released_model/detok-BB-gamm3.0-m0.7.pth > contrast.emamococov0.3.out &
nohup torchrun --nproc_per_node=8 main_contrast.py --project contrast --exp_name lmoco0.05 --use_znorm --batch_size 224 --model detok_BB --gamma 1.0 --mask_ratio 0.0 --epochs 50 --discriminator_start_epoch 0 --perceptual_weight 1. --vis_freq 1 --warmup_rate 0.02 --data_path /data/imagenet/train --cons_type lmoco0.05 --contrast_weight 0.01 --auto_resume --load_from released_model/detok-BB-gamm3.0-m0.7.pth > contrast.lmoco0.05.out &
nohup torchrun --nproc_per_node=8 main_contrast.py --project contrast --exp_name lmoco0.03 --use_znorm --batch_size 224 --model detok_BB --gamma 1.0 --mask_ratio 0.0 --epochs 50 --discriminator_start_epoch 0 --perceptual_weight 1. --vis_freq 1 --warmup_rate 0.02 --data_path /data/imagenet/train --cons_type lmoco0.03 --contrast_weight 0.01 --auto_resume --load_from released_model/detok-BB-gamm3.0-m0.7.pth > contrast.lmoco0.03.out &
nohup torchrun --nproc_per_node=8 main_contrast.py --project contrast --exp_name ldisp0.05 --use_znorm --batch_size 224 --model detok_BB --gamma 1.0 --mask_ratio 0.0 --epochs 50 --discriminator_start_epoch 0 --perceptual_weight 1. --vis_freq 1 --warmup_rate 0.02 --data_path /data/imagenet/train --cons_type ldisp0.05 --contrast_weight 0.001 --auto_resume --load_from released_model/detok-BB-gamm3.0-m0.7.pth > contrast.ldisp0.05.out &
nohup torchrun --nproc_per_node=8 main_contrast.py --project contrast --exp_name acccov --use_znorm --batch_size 224 --model detok_BB --gamma 1.0 --mask_ratio 0.0 --epochs 50 --discriminator_start_epoch 0 --perceptual_weight 1. --vis_freq 1 --warmup_rate 0.02 --data_path /data/imagenet/train --cons_type acccov --contrast_weight 0.1 --auto_resume --load_from released_model/detok-BB-gamm3.0-m0.7.pth --max_alpha 0.3 --contrast_buffer 30 > contrast.acccov.out &
nohup torchrun --nproc_per_node=8 main_contrast.py --project contrast --exp_name acccov0.6 --use_znorm --batch_size 224 --model detok_BB --gamma 1.0 --mask_ratio 0.0 --epochs 50 --discriminator_start_epoch 0 --perceptual_weight 1. --vis_freq 1 --warmup_rate 0.02 --data_path /data/imagenet/train --cons_type acccov --contrast_weight 0.1 --auto_resume --load_from released_model/detok-BB-gamm3.0-m0.7.pth --max_alpha 0.6 --contrast_buffer 30 > contrast.acccov0.6.out &
CUDA_VISIBLE_DEVICES=2,3,4,5,6,7 nohup torchrun --nproc_per_node=6 main_contrast.py --project contrast --exp_name lacccov0.3 --use_znorm --batch_size 224 --model detok_BB --gamma 1.0 --mask_ratio 0.0 --epochs 50 --discriminator_start_epoch 0 --perceptual_weight 1. --vis_freq 1 --warmup_rate 0.02 --data_path /data/imagenet/train --cons_type lacccov --contrast_weight 0.1 --auto_resume --load_from released_model/detok-BB-gamm3.0-m0.7.pth --max_alpha 0.3 --contrast_buffer 30 > contrast.lacccov.out &
CUDA_VISIBLE_DEVICES=0 nohup python precompute.py --batch_size 2048 --model detok_BB --use_znorm --load_from work_dirs/contrast/acccov/checkpoints/epoch_0032.pth --exp_name acccov --gamma 0.0 --mask_ratio 0.0 --blr 5e-5 --data_path /data/imagenet/train/ > precompute.acccov.out &
CUDA_VISIBLE_DEVICES=3 nohup python precompute.py --batch_size 2048 --model detok_BB --use_znorm --load_from work_dirs/contrast/acccov0.6/checkpoints/epoch_0010.pth --exp_name acccov0.6 --gamma 0.0 --mask_ratio 0.0 --blr 5e-5 --data_path /data/imagenet/train/ > precompute.acccov0.6.out &
CUDA_VISIBLE_DEVICES=1 nohup python precompute.py --batch_size 2048 --model detok_BB --use_znorm --load_from work_dirs/contrast/emamococov0.3/checkpoints/epoch_0017.pth --exp_name emamococov --gamma 0.0 --mask_ratio 0.0 --blr 5e-5 --data_path /data/imagenet/train/ > precompute.emamococov.out &
CUDA_VISIBLE_DEVICES=2 nohup python precompute.py --batch_size 2048 --model detok_BB --use_znorm --load_from work_dirs/contrast/simcov0.3/checkpoints/epoch_0032.pth --exp_name simcov --gamma 0.0 --mask_ratio 0.0 --blr 5e-5 --data_path /data/imagenet/train/ > precompute.simcov.out &
CUDA_VISIBLE_DEVICES=0 nohup python precompute.py --batch_size 2048 --model detok_BB --use_znorm --load_from work_dirs/contrast/lmoco0.05/checkpoints/epoch_0008.pth --exp_name lmoco0.05 --gamma 0.0 --mask_ratio 0.0 --blr 5e-5 --data_path /data/imagenet/train/ > precompute.lmoco0.05.out &
CUDA_VISIBLE_DEVICES=0,1 nohup torchrun --master_port=15901 --nproc_per_node=2 main_diffusion.py --project SiTS --exp_name acccov --batch_size 512 --epochs 100 --use_aligned_schedule --noise_schedule linear --tokenizer detok_BB --use_znorm --no_prenorm --use_ema_tokenizer --load_tokenizer_from work_dirs/contrast/acccov/checkpoints/epoch_0032.pth --model SiT_small --num_sampling_steps 250 --vis_freq 10 --online_eval --eval_freq 10 --num_images 1000 --eval_bsz 256 --data_path precompute_latent/detok_BB.acccov.precompute.safetensors > SiTS.acccov.out &
CUDA_VISIBLE_DEVICES=2,3 nohup torchrun --master_port=15902 --nproc_per_node=2 main_diffusion.py --project SiTS --exp_name acccov0.6 --batch_size 512 --epochs 100 --use_aligned_schedule --noise_schedule linear --tokenizer detok_BB --use_znorm --no_prenorm --use_ema_tokenizer --load_tokenizer_from work_dirs/contrast/acccov0.6/checkpoints/epoch_0010.pth --model SiT_small --num_sampling_steps 250 --vis_freq 10 --online_eval --eval_freq 10 --num_images 1000 --eval_bsz 256 --data_path precompute_latent/detok_BB.acccov0.6.precompute.safetensors > SiTS.acccov0.6.out &
CUDA_VISIBLE_DEVICES=4,5 nohup torchrun --master_port=15903 --nproc_per_node=2 main_diffusion.py --project SiTS --exp_name emamococov --batch_size 512 --epochs 100 --use_aligned_schedule --noise_schedule linear --tokenizer detok_BB --use_znorm --no_prenorm --use_ema_tokenizer --load_tokenizer_from work_dirs/contrast/emamococov0.3/checkpoints/epoch_0017.pth --model SiT_small --num_sampling_steps 250 --vis_freq 10 --online_eval --eval_freq 10 --num_images 1000 --eval_bsz 256 --data_path precompute_latent/detok_BB.emamococov.precompute.safetensors > SiTS.emamococov.out &
CUDA_VISIBLE_DEVICES=6,7 nohup torchrun --master_port=15904 --nproc_per_node=2 main_diffusion.py --project SiTS --exp_name simcov --batch_size 512 --epochs 100 --use_aligned_schedule --noise_schedule linear --tokenizer detok_BB --use_znorm --no_prenorm --use_ema_tokenizer --load_tokenizer_from work_dirs/contrast/simcov0.3/checkpoints/epoch_0032.pth --model SiT_small --num_sampling_steps 250 --vis_freq 10 --online_eval --eval_freq 10 --num_images 1000 --eval_bsz 256 --data_path precompute_latent/detok_BB.simcov.precompute.safetensors > SiTS.simcov.out &
CUDA_VISIBLE_DEVICES=0,1 nohup torchrun --master_port=15904 --nproc_per_node=2 main_diffusion.py --project SiTS --exp_name lmoco0.05 --batch_size 512 --epochs 100 --use_aligned_schedule --noise_schedule linear --tokenizer detok_BB --use_znorm --no_prenorm --use_ema_tokenizer --load_tokenizer_from work_dirs/contrast/lmoco0.05/checkpoints/epoch_0008.pth --model SiT_small --num_sampling_steps 250 --vis_freq 10 --online_eval --eval_freq 10 --num_images 1000 --eval_bsz 256 --data_path precompute_latent/detok_BB.lmoco0.05.precompute.safetensors > SiTS.lmoco0.05.out &
CUDA_VISIBLE_DEVICES=0 nohup python precompute.py --batch_size 256 --model vavae --gamma 0.0 --mask_ratio 0.0 --blr 5e-5 --data_path /data1/prune/imagenet/train > vavae.out & CUDA_VISIBLE_DEVICES=1 nohup python precompute.py --batch_size 256 --model sdvae --gamma 0.0 --mask_ratio 0.0 --blr 5e-5 --data_path /data1/prune/imagenet/train > sdvae.out &
CUDA_VISIBLE_DEVICES=1 nohup python precompute.py --batch_size 256 --model marvae --gamma 0.0 --mask_ratio 0.0 --blr 5e-5 --data_path /data1/prune/imagenet/train > marvae.out & CUDA_VISIBLE_DEVICES=0 nohup python precompute.py --batch_size 256 --model eqvae --gamma 0.0 --mask_ratio 0.0 --blr 5e-5 --data_path /data1/prune/imagenet/train > eqvae.out &
Train MAR-base (100 epochs):
tokenizer_project=tokenizer_training
tokenizer_exp_name=detokBB-g3.0-m0.7-200ep-decoder_ft-100ep
project=gen_model_training
exp_name=mar_base-${tokenizer_exp_name}
batch_size=32  # global batch size = batch_size x num_nodes x 8 = 1024
num_nodes=4
epochs=100

torchrun --nproc_per_node=8 --nnodes=$num_nodes --node_rank=${NODE_RANK} --master_addr=${MASTER_ADDR} --master_port=${MASTER_PORT} \
    main_diffusion.py \
    --project $project --exp_name $exp_name --auto_resume \
    --batch_size $batch_size --epochs $epochs --use_aligned_schedule \
    --tokenizer detok_BB --use_ema_tokenizer --collect_tokenizer_stats \
    --stats_key $tokenizer_exp_name --stats_cache_path work_dirs/stats.pkl \
    --load_tokenizer_from work_dirs/$tokenizer_project/$tokenizer_exp_name/checkpoints/latest.pth \
    --model MAR_base --no_dropout_in_mlp \
    --diffloss_d 6 --diffloss_w 1024 \
    --num_sampling_steps 100 --cfg 4.0 \
    --cfg_list 3.0 3.5 3.7 3.8 3.9 4.0 4.1 4.3 4.5 \
    --vis_freq 50 --eval_bsz 256 \
    --data_path ./data/imagenet/train \
    --entity $YOUR_WANDB_ENTITY --enable_wandb
Train SiT-base (100 epochs):
tokenizer_project=tokenizer_training
tokenizer_exp_name=detokBB-g3.0-m0.7-200ep-decoder_ft-100ep
project=gen_model_training
exp_name=sit_base-${tokenizer_exp_name}
batch_size=32
num_nodes=4
epochs=100

torchrun --nproc_per_node=8 --nnodes=$num_nodes --node_rank=${NODE_RANK} --master_addr=${MASTER_ADDR} --master_port=${MASTER_PORT} \
    main_diffusion.py \
    --project $project --exp_name $exp_name --auto_resume \
    --batch_size $batch_size --epochs $epochs --use_aligned_schedule \
    --tokenizer detok_BB --use_ema_tokenizer --collect_tokenizer_stats \
    --stats_key $tokenizer_exp_name --stats_cache_path work_dirs/stats.pkl \
    --load_tokenizer_from work_dirs/$tokenizer_project/$tokenizer_exp_name/checkpoints/latest.pth \
    --model SiT_base \
    --num_sampling_steps 250 --cfg 1.6 \
    --cfg_list 1.3 1.4 1.5 1.6 1.7 1.8 1.9 2.0 \
    --vis_freq 50 --eval_bsz 256 \
    --data_path ./data/imagenet/train \
    --entity $YOUR_WANDB_ENTITY --enable_wandb
CUDA_VISIBLE_DEVICES=7 nohup torchrun --master_port=15904 --nproc_per_node=1 main_diffusion.py --project SiTS --exp_name covbyol --batch_size 1024 --epochs 100 --use_aligned_schedule --tokenizer detok_BB --use_znorm --no_prenorm --use_ema_tokenizer --load_tokenizer_from work_dirs/contrast/covbyol/checkpoints/epoch_0024.pth --model SiT_small --num_sampling_steps 250 --vis_freq 10 --online_eval --eval_freq 10 --num_images 1000 --eval_bsz 256 --data_path precompute_latent/detok_BB.covbyol.precompute.safetensors > SiTS.covbyol.out &
CUDA_VISIBLE_DEVICES=0 nohup torchrun --master_port=15904 --nproc_per_node=1 main_diffusion.py --project SiTS --exp_name jac_znorm_bn_ep4 --auto_resume --batch_size 1024 --epochs 100 --use_aligned_schedule --tokenizer detok_BB --use_znorm --no_prenorm --use_ema_tokenizer --load_tokenizer_from work_dirs/contrast/jac_pretrain_bn/checkpoints/epoch_0004.pth --model SiT_small --num_sampling_steps 250 --vis_freq 10 --online_eval --eval_freq 10 --num_images 1000 --eval_bsz 256 --data_path precompute_latent/detok_BB.jac_znorm_bn_ep4.precompute.safetensors > SiTS.jac_znorm_bn_ep4.out &
CUDA_VISIBLE_DEVICES=0 nohup torchrun --master_port=15904 --nproc_per_node=1 main_diffusion.py --project SiTS --exp_name jac_znorm_ep4 --auto_resume --batch_size 1024 --epochs 100 --use_aligned_schedule --tokenizer detok_BB --use_znorm --no_prenorm --use_ema_tokenizer --load_tokenizer_from work_dirs/contrast/jac_pretrain/checkpoints/epoch_0004.pth --model SiT_small --num_sampling_steps 250 --vis_freq 10 --online_eval --eval_freq 10 --num_images 1000 --eval_bsz 256 --data_path precompute_latent/detok_BB.jac_znorm_ep4.precompute.safetensors > SiTS.jac_znorm_ep4.out &
CUDA_VISIBLE_DEVICES=3 nohup torchrun --master_port=15904 --nproc_per_node=1 main_diffusion.py --project SiTS --exp_name x0x1_pretrain_15 --auto_resume --batch_size 1024 --epochs 100 --use_aligned_schedule --tokenizer detok_BB --use_ema_tokenizer --load_tokenizer_from work_dirs/contrast/x0x1_pretrain_noln_finetune15/checkpoints/epoch_0007.pth --model SiT_small --num_sampling_steps 250 --vis_freq 10 --online_eval --eval_freq 10 --num_images 1000 --eval_bsz 256 --data_path precompute_latent/detok_BB.x0x1_pretrain_15.precompute.safetensors > SiTS.x0x1_pretrain_15.out &
CUDA_VISIBLE_DEVICES=7 nohup torchrun --master_port=15904 --nproc_per_node=1 main_diffusion.py --project SiTS --exp_name x0x1_ep1 --auto_resume --batch_size 1024 --epochs 100 --use_aligned_schedule --tokenizer detok_BB --use_ema_tokenizer --load_tokenizer_from work_dirs/contrast/x0x1/checkpoints/epoch_0001.pth --model SiT_small --num_sampling_steps 250 --vis_freq 10 --online_eval --eval_freq 10 --num_images 1000 --eval_bsz 256 --data_path precompute_latent/detok_BB.x0x1_ep1.precompute.safetensors > SiTS.x0x1_ep1.out &
CUDA_VISIBLE_DEVICES=5 nohup torchrun --master_port=15906 --nproc_per_node=1 main_diffusion.py --project SiTS --exp_name x0x1_ep0 --auto_resume --batch_size 1024 --epochs 100 --use_aligned_schedule --tokenizer detok_BB --use_ema_tokenizer --load_tokenizer_from work_dirs/contrast/x0x1/checkpoints/epoch_0000.pth --model SiT_small --num_sampling_steps 250 --vis_freq 10 --online_eval --eval_freq 10 --num_images 1000 --eval_bsz 256 --data_path precompute_latent/detok_BB.x0x1_ep0.precompute.safetensors > SiTS.x0x1_ep0.out &
CUDA_VISIBLE_DEVICES=5 nohup torchrun --master_port=15907 --nproc_per_node=1 main_diffusion.py --project SiTS --exp_name x0x1_ep3 --auto_resume --batch_size 1024 --epochs 100 --use_aligned_schedule --tokenizer detok_BB --use_ema_tokenizer --load_tokenizer_from work_dirs/contrast/x0x1/checkpoints/epoch_0003.pth --model SiT_small --num_sampling_steps 250 --vis_freq 10 --online_eval --eval_freq 10 --num_images 1000 --eval_bsz 256 --data_path precompute_latent/detok_BB.x0x1_ep3.precompute.safetensors > SiTS.x0x1_ep3.out &
CUDA_VISIBLE_DEVICES=3 nohup torchrun --master_port=15905 --nproc_per_node=1 main_diffusion.py --project SiTS --exp_name baseline --auto_resume --batch_size 1024 --epochs 100 --use_aligned_schedule --tokenizer detok_BB --use_ema_tokenizer --load_tokenizer_from released_model/detok-BB-gamm3.0-m0.7.pth --model SiT_small --num_sampling_steps 250 --vis_freq 10 --online_eval --eval_freq 10 --num_images 1000 --eval_bsz 256 --data_path precompute_latent/detok_BB.precompute.safetensors > SiTS.baseline.out &
CUDA_VISIBLE_DEVICES=1,3,5,7 nohup torchrun --master_port=15901 --nproc_per_node=4 main_diffusion.py --project SiTB --exp_name contrast --auto_resume --batch_size 512 --epochs 100 --use_aligned_schedule --tokenizer detok_BB --use_ema_tokenizer --load_tokenizer_from work_dirs/contrast/contrast_debug/checkpoints/epoch_0003.pth --model SiT_base --num_sampling_steps 250 --vis_freq 10 --online_eval --eval_freq 10 --num_images 1000 --eval_bsz 256 --data_path precompute_latent/detok_BB.contrast.precompute.safetensors > SiTB.contrast.out &
CUDA_VISIBLE_DEVICES=0,2,4,6 nohup torchrun --nproc_per_node=4 main_diffusion.py --project SiTB --exp_name baseline --auto_resume --batch_size 512 --epochs 100 --use_aligned_schedule --tokenizer detok_BB --use_ema_tokenizer --load_tokenizer_from released_model/detok-BB-gamm3.0-m0.7.pth --model SiT_base --num_sampling_steps 250 --vis_freq 10 --online_eval --eval_freq 10 --num_images 1000 --eval_bsz 256 --data_path precompute_latent/detok_BB.precompute.safetensors > SiTB.baseline.out &
Train MAR-base for 800 epochs using released tokenizer:
project=gen_model_training
exp_name=mar_base_800ep-detok-BB-gamm3.0-m0.7-decoder_tuned
batch_size=16  # global batch size = batch_size x num_nodes x 8 = 1024
num_nodes=8
epochs=800

torchrun --nproc_per_node=8 --nnodes=$num_nodes --node_rank=${NODE_RANK} --master_addr=${MASTER_ADDR} --master_port=${MASTER_PORT} \
    main_diffusion.py \
    --project $project --exp_name $exp_name --auto_resume \
    --batch_size $batch_size --epochs $epochs --use_aligned_schedule \
    --tokenizer detok_BB --use_ema_tokenizer --collect_tokenizer_stats \
    --stats_key detok-BB-gamm3.0-m0.7 --stats_cache_path released_model/stats.pkl \
    --load_tokenizer_from released_model/detok-BB-gamm3.0-m0.7-decoder_tuned.pth \
    --model MAR_base --no_dropout_in_mlp \
    --diffloss_d 6 --diffloss_w 1024 \
    --num_sampling_steps 100 --cfg 3.9 \
    --cfg_list 3.0 3.5 3.7 3.8 3.9 4.0 4.1 4.3 4.5 \
    --online_eval --vis_freq 80 --eval_bsz 256 \
    --data_path ./data/imagenet/train \
    --entity $YOUR_WANDB_ENTITY --enable_wandb
Train MAR-large for 800 epochs:
project=gen_model_training
exp_name=mar_large_800ep-detok-BB-gamm3.0-m0.7-decoder_tuned
batch_size=16
num_nodes=8
epochs=800

torchrun --nproc_per_node=8 --nnodes=$num_nodes --node_rank=${NODE_RANK} --master_addr=${MASTER_ADDR} --master_port=${MASTER_PORT} \
    main_diffusion.py \
    --project $project --exp_name $exp_name --auto_resume \
    --batch_size $batch_size --epochs $epochs --use_aligned_schedule \
    --tokenizer detok_BB --use_ema_tokenizer --collect_tokenizer_stats \
    --stats_key detok-BB-gamm3.0-m0.7 --stats_cache_path released_model/stats.pkl \
    --load_tokenizer_from released_model/detok-BB-gamm3.0-m0.7-decoder_tuned.pth \
    --model MAR_large --no_dropout_in_mlp \
    --diffloss_d 8 --diffloss_w 1280 \
    --num_sampling_steps 100 --cfg 3.4 \
    --cfg_list 3.0 3.2 3.3 3.4 3.5 3.6 3.7 3.8 3.9 \
    --online_eval --vis_freq 80 --eval_bsz 256 \
    --data_path ./data/imagenet/train \
    --entity $YOUR_WANDB_ENTITY --enable_wandb
torchrun --nproc_per_node=8 --nnodes=1 --node_rank=0 \
    main_diffusion.py \
    --project mar_eval --exp_name mar_base_ep800 --auto_resume \
    --batch_size 64 --epochs 800 --use_aligned_schedule \
    --tokenizer detok_BB --use_ema_tokenizer --collect_tokenizer_stats \
    --stats_key detok-BB-gamm3.0-m0.7 --stats_cache_path released_model/stats.pkl \
    --load_tokenizer_from released_model/detok-BB-gamm3.0-m0.7-decoder_tuned.pth \
    --model MAR_base --no_dropout_in_mlp \
    --diffloss_d 6 --diffloss_w 1024 \
    --load_from released_model/mar_base.pth \
    --num_sampling_steps 100 --eval_bsz 256 --num_images 50000 --num_iter 256 --evaluate \
    --cfg 3.9 \
    --data_path ./data/imagenet/train
torchrun --nproc_per_node=8 --nnodes=1 --node_rank=0 \
    main_diffusion.py \
    --project mar_eval --exp_name mar_large_ep800 --auto_resume \
    --batch_size 64 --epochs 800 --use_aligned_schedule \
    --tokenizer detok_BB --use_ema_tokenizer --collect_tokenizer_stats \
    --stats_key detok-BB-gamm3.0-m0.7 --stats_cache_path released_model/stats.pkl \
    --load_tokenizer_from released_model/detok-BB-gamm3.0-m0.7-decoder_tuned.pth \
    --model MAR_large --no_dropout_in_mlp \
    --diffloss_d 8 --diffloss_w 1280 \
    --load_from released_model/mar_large.pth \
    --num_sampling_steps 100 --eval_bsz 256 --num_images 50000 --num_iter 256 --evaluate \
    --cfg 3.4 \
    --data_path ./data/imagenet/train
FID-50k with CFG:
| cfg | MAR Model | FID-50K | Inception Score | #params |
|---|---|---|---|---|
| 3.9 | MAR-B + l-DeTok | 1.61 | 289.7 | 208M |
| 3.9 | MAR-B + l-DeTok (decoder_ft) | 1.55 | 291.0 | 208M |
| 3.4 | MAR-L + l-DeTok | 1.43 | 303.5 | 479M |
| 3.4 | MAR-L + l-DeTok (decoder_ft) | 1.32 | 304.1 | 479M |
Note:
--cfg 1.0 --temperature 0.95 to evaluate without CFG for MAR-base and --cfg 1.0 --temperature 0.97 for MAR-large--num_iter 64)We thank the authors of MAE, MAGE, DiT, LightningDiT, MAETok and MAR for their foundational work.
Our codebase builds upon several excellent open-source projects, including MAR and 1d-tokenizer. We are grateful to the communities behind them.
This codebase has been cleaned up but has not undergone extensive testing. If you encounter any issues or have questions, please open a GitHub issue. We appreciate your feedback!



