[ACL 2026 Oral] From Word to World: Can Large Language Models be Implicit Text-based World Models?
See the code

Code and data for "From Word to World: Can Large Language Models be Implicit Text-based World Models?".
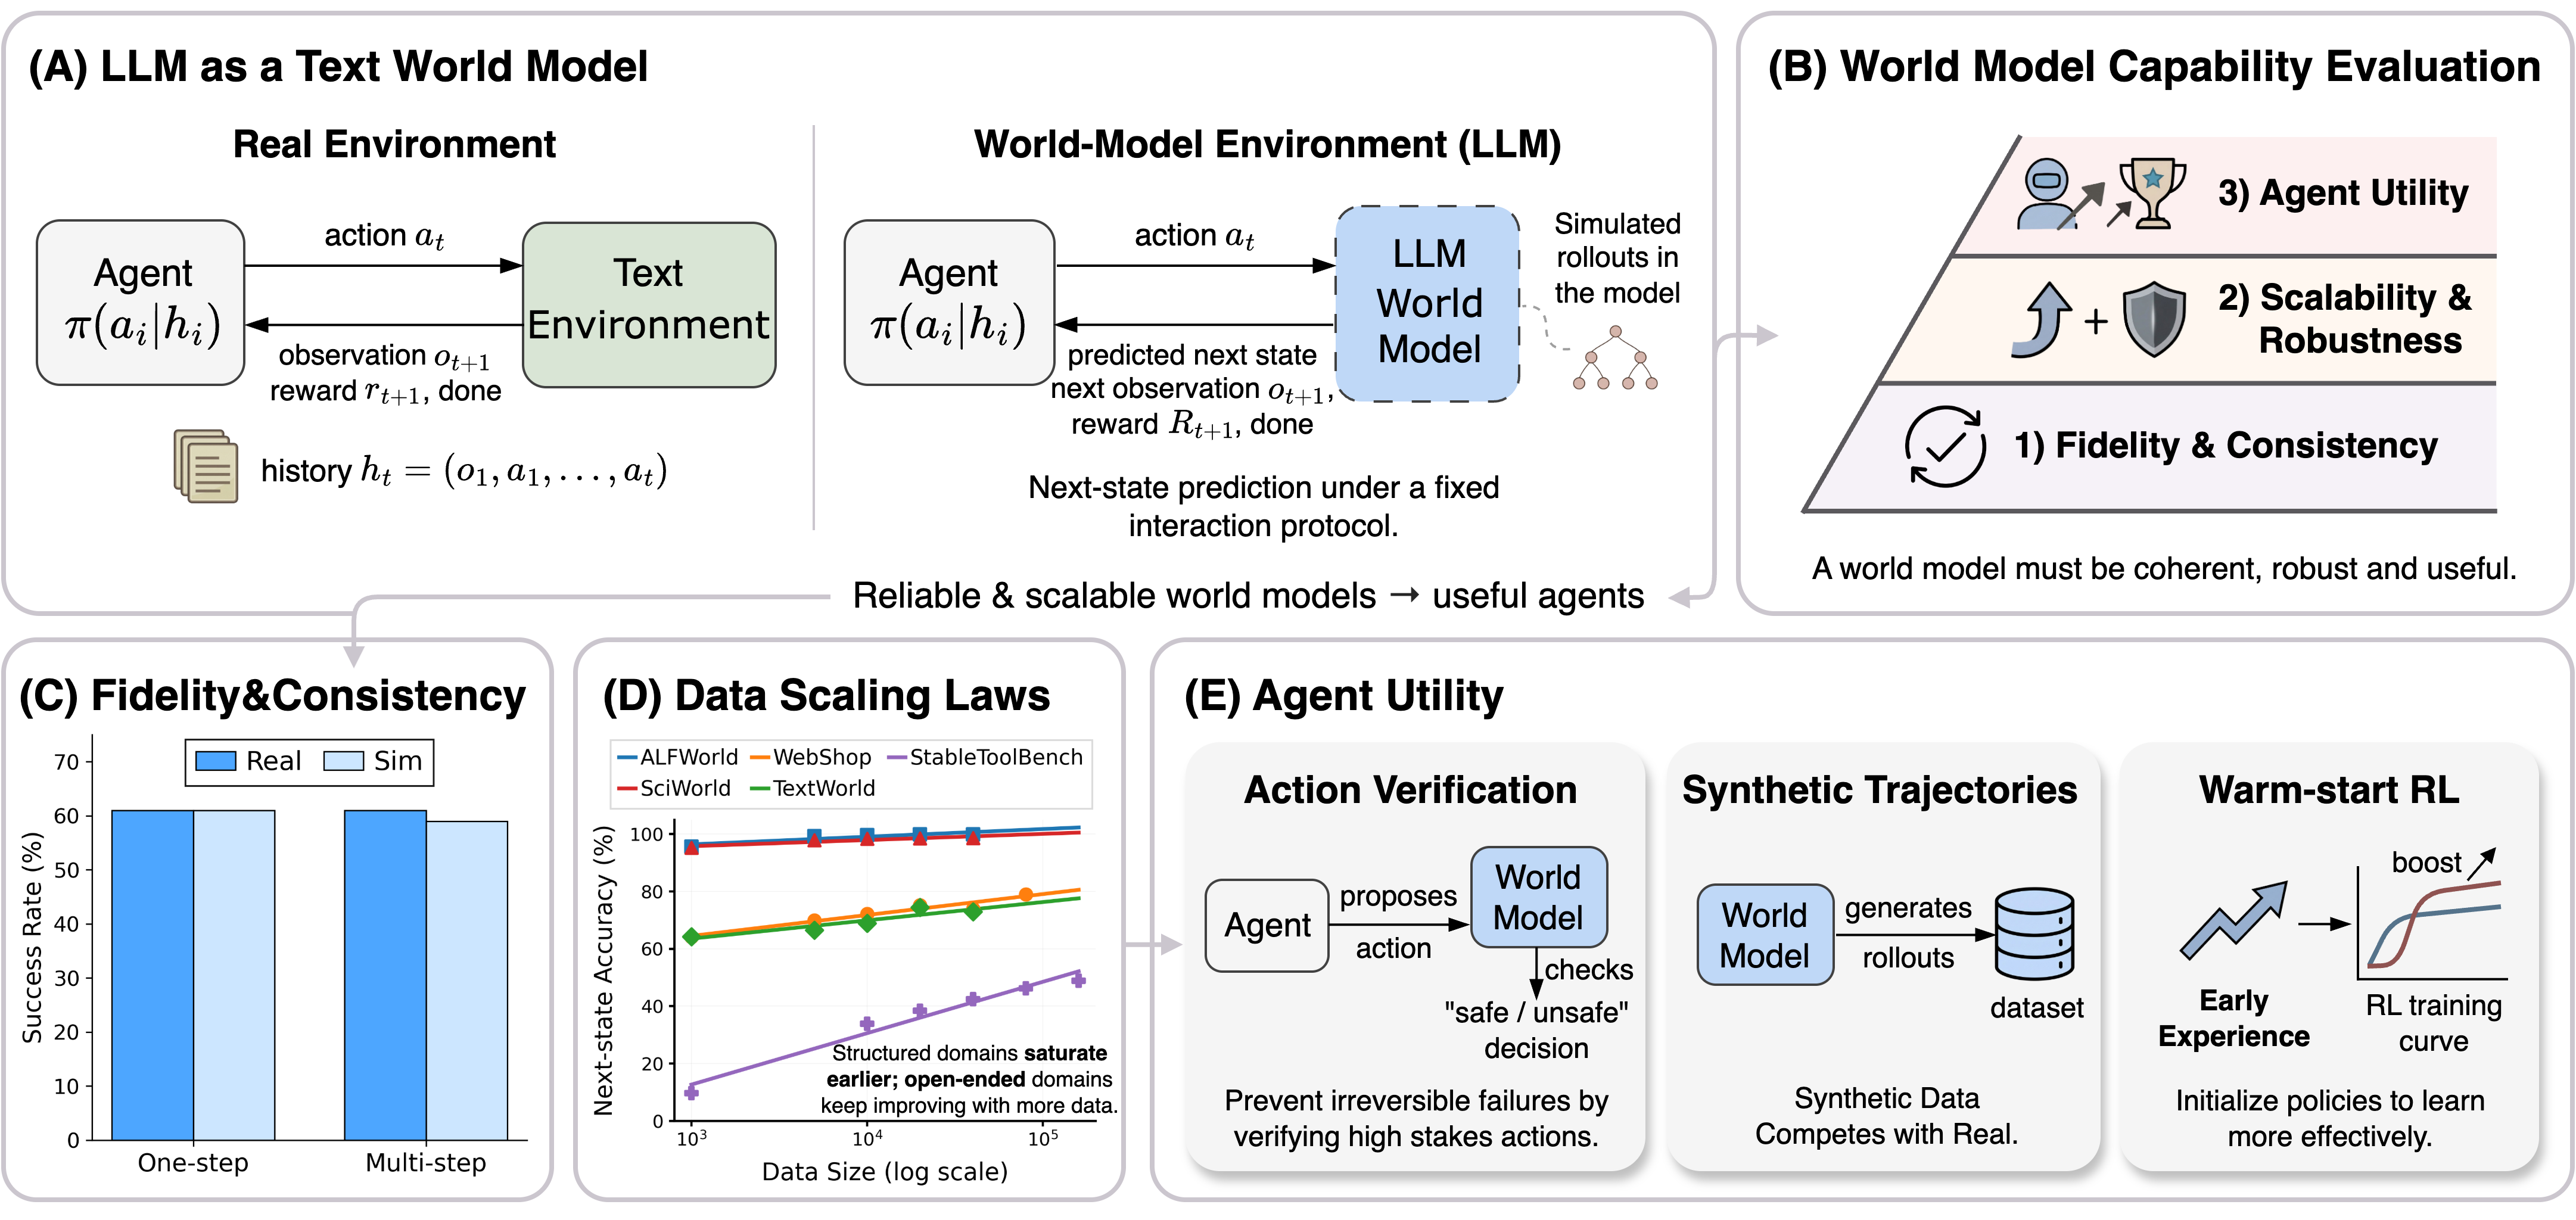
LLMs as text-based world models for agent learning.
| Environment | Qwen2.5-7B | Llama3.1-8B |
|---|---|---|
| ALFWorld | X1AOX1A/WorldModel-Alfworld-Qwen2.5-7B | X1AOX1A/WorldModel-Alfworld-Llama3.1-8B |
| SciWorld | X1AOX1A/WorldModel-Sciworld-Qwen2.5-7B | X1AOX1A/WorldModel-Sciworld-Llama3.1-8B |
| TextWorld | X1AOX1A/WorldModel-Textworld-Qwen2.5-7B | X1AOX1A/WorldModel-Textworld-Llama3.1-8B |
| Webshop | X1AOX1A/WorldModel-Webshop-Qwen2.5-7B | X1AOX1A/WorldModel-Webshop-Llama3.1-8B |
| StableToolBench | X1AOX1A/WorldModel-Stabletoolbench-Qwen2.5-7B | X1AOX1A/WorldModel-Stabletoolbench-Llama3.1-8B |
# install AgentGym-RL
bash scripts/env_setup/uv_agentgym_rl.sh

# install AgentGym environments
bash scripts/env_setup/uv_alfworld.sh
bash scripts/env_setup/uv_sciworld.sh
bash scripts/env_setup/uv_textworld.sh
bash scripts/env_setup/uv_webshop.sh
You can verify each environment by launching its server:
bash scripts/env_server/start_alfworld.sh
bash scripts/env_server/start_sciworld.sh
bash scripts/env_server/start_textworld.sh
bash scripts/env_server/start_webshop.sh
Note (ALFWorld): to align with AgentGym, we renamed action
put→moveand added ahelpaction (see the updated.twl2underscripts/download_data). Therefore the originalalfworld-downloadworkflow is not compatible. If you downloaded ALFWorld data before, please remove the old data and re-download using the command below; otherwise evaluation may be lower than expected.
source uv_agentgym_rl/bin/activate
python scripts/download_data/download_data.py
This repo reports three complementary metrics:
To compute Single Step Accuracy, run:
TASK=alfworld         # alfworld, alfworld_valid_seen, alfworld_valid_unseen, sciworld, textworld, webshop, stabletoolbench
MODEL=X1AOX1A/WorldModel-Alfworld-Qwen2.5-7B                  # world model checkpoint
OUTPUT_ROOT=outputs/single_step_accuracy/${TASK}/${MODEL}     # output root directory
bash scripts/single_step_accuracy/run.sh $TASK $MODEL $OUTPUT_ROOT
Example output:
{
    "average_accuracy": 0.9987087517934002
}
To collect trajectories on the training set with real environments, set
SPLIT=train.
To compute Real Task Success Rate, run:
TASK=alfworld         # alfworld, sciworld, textworld, webshop
RUN=0                 # run id for multiple runs, just for separating output dirs
API_KEY=your_api_key  # your OpenAI API key
API_BASE_URL=your_api_base_url # your OpenAI API base URL
MODEL=gpt-4o          # agent model name
MAX_CONCURRENCY=150   # max concurrency
MAX_ROUND=50          # max round
NUM_EXAMPLES=-1       # num examples
SPLIT=test            # train, test (and valid_seen, valid_unseen for ALFWorld only)
OUTPUT_ROOT=outputs   # output root directory
# this will auto-launch the environment server
bash scripts/interact_with_real_env/run_openai.sh $TASK $RUN $API_KEY $API_BASE_URL $MODEL $MAX_CONCURRENCY $MAX_ROUND $NUM_EXAMPLES $SPLIT $OUTPUT_ROOT
# metrics will be saved to outputs/interaction/real_env/$SPLIT/${TASK}/$MODEL/${TASK}_maxround${MAX_ROUND}_run${RUN}/_metrics.json
Example output:
{
    "accuracy": 50.50,  # task success rate
    "success": 101.0,   # total successful interactions
    "api_errors": 0,    # API errors
    "total": 200,       # total interactions
    "time_seconds": 1075.621458530426  # time taken in seconds
}
TASK=alfworld         # alfworld, sciworld, textworld, webshop
RUN=0                 # run id for multiple runs, just for separating output dirs
MODEL=Qwen/Qwen2.5-7B-Instruct       # agent model name
MAX_CONCURRENCY=150   # max concurrency
MAX_ROUND=20          # max round, reduce to 20 to prevent exceeding the context length
NUM_EXAMPLES=-1       # num examples
SPLIT=test            # train, test (and valid_seen, valid_unseen for ALFWorld only)
OUTPUT_ROOT=outputs   # output root directory
# this will auto-launch the vLLM server and the environment server
bash scripts/interact_with_real_env/run_vllm.sh $TASK $RUN $MODEL $MAX_CONCURRENCY $MAX_ROUND $NUM_EXAMPLES $SPLIT $OUTPUT_ROOT
# metrics will be saved to outputs/interaction/real_env/$SPLIT/vllm/${TASK}/$MODEL/${TASK}_maxround${MAX_ROUND}_run${RUN}/_metrics.json
To compute WM Task Success Rate, run:
TASK=alfworld         # alfworld, sciworld, textworld, webshop
MODEL=gpt-4o          # agent model name
API_KEY=your_api_key  # your OpenAI API key
API_BASE_URL=your_api_base_url # your OpenAI API base URL
WORLD_MODEL=X1AOX1A/WorldModel-Alfworld-Qwen2.5-7B # world model checkpoint
MAX_CONCURRENCY=150   # max concurrency
MAX_ROUND=50          # max round
NUM_EXAMPLES=-1       # num examples
SPLIT=test            # train, test (and valid_seen, valid_unseen for ALFWorld only)
OUTPUT_ROOT=outputs   # output root directory
# this will auto-launch the vLLM server for the world model
bash scripts/interact_with_world_model/run.sh $TASK $MODEL $API_KEY $API_BASE_URL $WORLD_MODEL $MAX_CONCURRENCY $MAX_ROUND $NUM_EXAMPLES $SPLIT $OUTPUT_ROOT
# metrics will be saved to outputs/interaction/world_model/$SPLIT/$TASK/$MODEL/$WORLD_MODEL/$MODEL/_metrics.json
Example output:
{
    "task": "alfworld",                    # task name
    "agent_model": "gpt-4o",               # agent model name
    "total_items": 200,                    # total items
    "total_success": 109.0,                # total successful interactions
    "processed_items": 200,                # processed items
    "accuracy": 54.50000000000001,         # task success rate
    "api_errors": 0                        # API errors
}
To compute WM2Real Success Rate, run:
TASK=alfworld                 # alfworld, alfworld_valid_seen, alfworld_valid_unseen, sciworld, textworld, webshop
TEST_FILE_ROOT=test_file_root # e.g. outputs/interaction/world_model/${SPLIT}/${TASK}/${MODEL}/${WORLD_MODEL}/${MODEL}
MAX_WORKERS=50                # max workers, set to 1 for textworld
# this will auto-launch the environment server
bash scripts/interact_with_world_model/cal_wm2real.sh $TASK $TEST_FILE_ROOT $MAX_WORKERS
# metrics will be saved to $TEST_FILE_ROOT/valid_on_real_env/_metrics.json
Example output:
{
    "total": 200,                # total items
    "processed": 200,            # processed items
    "success": 111,              # total successful interactions
    "errors": 0,                 # API errors
    "accuracy": 0.555            # task success rate
}
To train the world models, update the dataset field in the LLaMA-Factory config to the corresponding JSON file.
| Environment | Dataset JSON | Data Size Used |
|---|---|---|
| ALFWorld | data/llama_factory/alfworld_train_with_env_54006.json | 40K |
| SciWorld | data/llama_factory/sciworld_train_with_env_40630.json | 40K |
| TextWorld | data/llama_factory/textworld_train_58805.json | 40K |
| Webshop | data/llama_factory/webshop_train_70790.json | 70K |
| StableToolBench | data/llama_factory/stabletoolbench_train_175183.json | 160K |
X1AOX1A/WorldModel-Alfworld-Qwen2.5-7B on 4xH100-80G### model
model_name_or_path: Qwen/Qwen2.5-7B
trust_remote_code: true
### method
stage: sft
do_train: true
finetuning_type: full
deepspeed: src/LLaMA-Factory/examples/deepspeed/ds_z2_config.json # choices: [ds_z0_config.json, ds_z2_config.json, ds_z3_config.json]
### dataset
dataset_dir: data/llama_factory
dataset: alfworld_train_with_env_54006
template: qwen
cutoff_len: 12288
max_samples: 40000 # 40K for ALFWorld, SciWorld, TextWorld; 70K for Webshop; 160K for StableToolBench
overwrite_cache: true
preprocessing_num_workers: 16
dataloader_num_workers: 4
### output
output_dir: outputs/ckpt/alfworld/qwen2.5_7b/alfworld_train_with_env_40k
logging_steps: 1
save_steps: 160
plot_loss: true
overwrite_output_dir: true
save_only_model: false
report_to: wandb # choices: [none, wandb, tensorboard, swanlab, mlflow]
### train
per_device_train_batch_size: 2
gradient_accumulation_steps: 16
learning_rate: 1.0e-5
num_train_epochs: 5.0
lr_scheduler_type: constant_with_warmup
warmup_steps: 10
bf16: true
ddp_timeout: 180000000
resume_from_checkpoint: null
max_grad_norm: 100
For any questions, please contact:
If you use our work in your research, please cite:
@misc{li2025wordworldlargelanguage,
      title={From Word to World: Can Large Language Models be Implicit Text-based World Models?},
      author={Yixia Li and Hongru Wang and Jiahao Qiu and Zhenfei Yin and Dongdong Zhang and Cheng Qian and Zeping Li and Pony Ma and Guanhua Chen and Heng Ji and Mengdi Wang},
      year={2025},
      eprint={2512.18832},
      archivePrefix={arXiv},
      primaryClass={cs.CL},
      url={https://arxiv.org/abs/2512.18832},
}
[ACL 2026 Oral] From Word to World: Can Large Language Models be Implicit Text-based World Models?
See the code
Code and data for "From Word to World: Can Large Language Models be Implicit Text-based World Models?".
LLMs as text-based world models for agent learning.
| Environment | Qwen2.5-7B | Llama3.1-8B |
|---|---|---|
| ALFWorld | X1AOX1A/WorldModel-Alfworld-Qwen2.5-7B | X1AOX1A/WorldModel-Alfworld-Llama3.1-8B |
| SciWorld | X1AOX1A/WorldModel-Sciworld-Qwen2.5-7B | X1AOX1A/WorldModel-Sciworld-Llama3.1-8B |
| TextWorld | X1AOX1A/WorldModel-Textworld-Qwen2.5-7B | X1AOX1A/WorldModel-Textworld-Llama3.1-8B |
| Webshop | X1AOX1A/WorldModel-Webshop-Qwen2.5-7B | X1AOX1A/WorldModel-Webshop-Llama3.1-8B |
| StableToolBench | X1AOX1A/WorldModel-Stabletoolbench-Qwen2.5-7B | X1AOX1A/WorldModel-Stabletoolbench-Llama3.1-8B |
# install AgentGym-RL
bash scripts/env_setup/uv_agentgym_rl.sh

# install AgentGym environments
bash scripts/env_setup/uv_alfworld.sh
bash scripts/env_setup/uv_sciworld.sh
bash scripts/env_setup/uv_textworld.sh
bash scripts/env_setup/uv_webshop.sh
You can verify each environment by launching its server:
bash scripts/env_server/start_alfworld.sh
bash scripts/env_server/start_sciworld.sh
bash scripts/env_server/start_textworld.sh
bash scripts/env_server/start_webshop.sh
Note (ALFWorld): to align with AgentGym, we renamed action
put→moveand added ahelpaction (see the updated.twl2underscripts/download_data). Therefore the originalalfworld-downloadworkflow is not compatible. If you downloaded ALFWorld data before, please remove the old data and re-download using the command below; otherwise evaluation may be lower than expected.
source uv_agentgym_rl/bin/activate
python scripts/download_data/download_data.py
This repo reports three complementary metrics:
To compute Single Step Accuracy, run:
TASK=alfworld         # alfworld, alfworld_valid_seen, alfworld_valid_unseen, sciworld, textworld, webshop, stabletoolbench
MODEL=X1AOX1A/WorldModel-Alfworld-Qwen2.5-7B                  # world model checkpoint
OUTPUT_ROOT=outputs/single_step_accuracy/${TASK}/${MODEL}     # output root directory
bash scripts/single_step_accuracy/run.sh $TASK $MODEL $OUTPUT_ROOT
Example output:
{
    "average_accuracy": 0.9987087517934002
}
To collect trajectories on the training set with real environments, set
SPLIT=train.
To compute Real Task Success Rate, run:
TASK=alfworld         # alfworld, sciworld, textworld, webshop
RUN=0                 # run id for multiple runs, just for separating output dirs
API_KEY=your_api_key  # your OpenAI API key
API_BASE_URL=your_api_base_url # your OpenAI API base URL
MODEL=gpt-4o          # agent model name
MAX_CONCURRENCY=150   # max concurrency
MAX_ROUND=50          # max round
NUM_EXAMPLES=-1       # num examples
SPLIT=test            # train, test (and valid_seen, valid_unseen for ALFWorld only)
OUTPUT_ROOT=outputs   # output root directory
# this will auto-launch the environment server
bash scripts/interact_with_real_env/run_openai.sh $TASK $RUN $API_KEY $API_BASE_URL $MODEL $MAX_CONCURRENCY $MAX_ROUND $NUM_EXAMPLES $SPLIT $OUTPUT_ROOT
# metrics will be saved to outputs/interaction/real_env/$SPLIT/${TASK}/$MODEL/${TASK}_maxround${MAX_ROUND}_run${RUN}/_metrics.json
Example output:
{
    "accuracy": 50.50,  # task success rate
    "success": 101.0,   # total successful interactions
    "api_errors": 0,    # API errors
    "total": 200,       # total interactions
    "time_seconds": 1075.621458530426  # time taken in seconds
}
TASK=alfworld         # alfworld, sciworld, textworld, webshop
RUN=0                 # run id for multiple runs, just for separating output dirs
MODEL=Qwen/Qwen2.5-7B-Instruct       # agent model name
MAX_CONCURRENCY=150   # max concurrency
MAX_ROUND=20          # max round, reduce to 20 to prevent exceeding the context length
NUM_EXAMPLES=-1       # num examples
SPLIT=test            # train, test (and valid_seen, valid_unseen for ALFWorld only)
OUTPUT_ROOT=outputs   # output root directory
# this will auto-launch the vLLM server and the environment server
bash scripts/interact_with_real_env/run_vllm.sh $TASK $RUN $MODEL $MAX_CONCURRENCY $MAX_ROUND $NUM_EXAMPLES $SPLIT $OUTPUT_ROOT
# metrics will be saved to outputs/interaction/real_env/$SPLIT/vllm/${TASK}/$MODEL/${TASK}_maxround${MAX_ROUND}_run${RUN}/_metrics.json
To compute WM Task Success Rate, run:
TASK=alfworld         # alfworld, sciworld, textworld, webshop
MODEL=gpt-4o          # agent model name
API_KEY=your_api_key  # your OpenAI API key
API_BASE_URL=your_api_base_url # your OpenAI API base URL
WORLD_MODEL=X1AOX1A/WorldModel-Alfworld-Qwen2.5-7B # world model checkpoint
MAX_CONCURRENCY=150   # max concurrency
MAX_ROUND=50          # max round
NUM_EXAMPLES=-1       # num examples
SPLIT=test            # train, test (and valid_seen, valid_unseen for ALFWorld only)
OUTPUT_ROOT=outputs   # output root directory
# this will auto-launch the vLLM server for the world model
bash scripts/interact_with_world_model/run.sh $TASK $MODEL $API_KEY $API_BASE_URL $WORLD_MODEL $MAX_CONCURRENCY $MAX_ROUND $NUM_EXAMPLES $SPLIT $OUTPUT_ROOT
# metrics will be saved to outputs/interaction/world_model/$SPLIT/$TASK/$MODEL/$WORLD_MODEL/$MODEL/_metrics.json
Example output:
{
    "task": "alfworld",                    # task name
    "agent_model": "gpt-4o",               # agent model name
    "total_items": 200,                    # total items
    "total_success": 109.0,                # total successful interactions
    "processed_items": 200,                # processed items
    "accuracy": 54.50000000000001,         # task success rate
    "api_errors": 0                        # API errors
}
To compute WM2Real Success Rate, run:
TASK=alfworld                 # alfworld, alfworld_valid_seen, alfworld_valid_unseen, sciworld, textworld, webshop
TEST_FILE_ROOT=test_file_root # e.g. outputs/interaction/world_model/${SPLIT}/${TASK}/${MODEL}/${WORLD_MODEL}/${MODEL}
MAX_WORKERS=50                # max workers, set to 1 for textworld
# this will auto-launch the environment server
bash scripts/interact_with_world_model/cal_wm2real.sh $TASK $TEST_FILE_ROOT $MAX_WORKERS
# metrics will be saved to $TEST_FILE_ROOT/valid_on_real_env/_metrics.json
Example output:
{
    "total": 200,                # total items
    "processed": 200,            # processed items
    "success": 111,              # total successful interactions
    "errors": 0,                 # API errors
    "accuracy": 0.555            # task success rate
}
To train the world models, update the dataset field in the LLaMA-Factory config to the corresponding JSON file.
| Environment | Dataset JSON | Data Size Used |
|---|---|---|
| ALFWorld | data/llama_factory/alfworld_train_with_env_54006.json | 40K |
| SciWorld | data/llama_factory/sciworld_train_with_env_40630.json | 40K |
| TextWorld | data/llama_factory/textworld_train_58805.json | 40K |
| Webshop | data/llama_factory/webshop_train_70790.json | 70K |
| StableToolBench | data/llama_factory/stabletoolbench_train_175183.json | 160K |
X1AOX1A/WorldModel-Alfworld-Qwen2.5-7B on 4xH100-80G### model
model_name_or_path: Qwen/Qwen2.5-7B
trust_remote_code: true
### method
stage: sft
do_train: true
finetuning_type: full
deepspeed: src/LLaMA-Factory/examples/deepspeed/ds_z2_config.json # choices: [ds_z0_config.json, ds_z2_config.json, ds_z3_config.json]
### dataset
dataset_dir: data/llama_factory
dataset: alfworld_train_with_env_54006
template: qwen
cutoff_len: 12288
max_samples: 40000 # 40K for ALFWorld, SciWorld, TextWorld; 70K for Webshop; 160K for StableToolBench
overwrite_cache: true
preprocessing_num_workers: 16
dataloader_num_workers: 4
### output
output_dir: outputs/ckpt/alfworld/qwen2.5_7b/alfworld_train_with_env_40k
logging_steps: 1
save_steps: 160
plot_loss: true
overwrite_output_dir: true
save_only_model: false
report_to: wandb # choices: [none, wandb, tensorboard, swanlab, mlflow]
### train
per_device_train_batch_size: 2
gradient_accumulation_steps: 16
learning_rate: 1.0e-5
num_train_epochs: 5.0
lr_scheduler_type: constant_with_warmup
warmup_steps: 10
bf16: true
ddp_timeout: 180000000
resume_from_checkpoint: null
max_grad_norm: 100
For any questions, please contact:
If you use our work in your research, please cite:
@misc{li2025wordworldlargelanguage,
      title={From Word to World: Can Large Language Models be Implicit Text-based World Models?},
      author={Yixia Li and Hongru Wang and Jiahao Qiu and Zhenfei Yin and Dongdong Zhang and Cheng Qian and Zeping Li and Pony Ma and Guanhua Chen and Heng Ji and Mengdi Wang},
      year={2025},
      eprint={2512.18832},
      archivePrefix={arXiv},
      primaryClass={cs.CL},
      url={https://arxiv.org/abs/2512.18832},
}