
Open-source evaluation toolkit of large vision-language models (LVLMs), support ~100 VLMs, 40+ benchmarks
See the codeREADME
🌍 Welcome to the Evaluation Suite for worldMedQA-V! 🚀
The fastest way to get started is:
👉 Follow the [QuickStart | 快速开始] guide to jump right in and get rolling! Make sure your Huggingface setup is good to go! 😊
Recommended Transformers Version 🤖
💡 Important Note: Some Vision-Language Models (VLMs) may not work well with certain versions of transformers. We recommend the following settings to evaluate each VLM:
-
Please use
transformers==4.33.0for:Qwen seriesMonkey seriesInternLM-XComposer SeriesmPLUG-Owl2OpenFlamingo v2IDEFICS seriesVisualGLMMMAlayaShareCaptionerMiniGPT-4 seriesInstructBLIP seriesPandaGPTVXVERSE
-
Please use
transformers==4.36.2for:Moondream1
-
Please use
transformers==4.37.0for:LLaVA seriesShareGPT4V seriesTransCore-MLLaVA (XTuner)CogVLM SeriesEMU2 SeriesYi-VL SeriesMiniCPM-[V1/V2]OmniLMM-12BDeepSeek-VL seriesInternVL seriesCambrian SeriesVILA SeriesLlama-3-MixSenseV1_1Parrot-7BPLLaVA Series
-
Please use
transformers==4.40.0for:IDEFICS2Bunny-Llama3MiniCPM-Llama3-V2.5360VL-70BPhi-3-VisionWeMM
-
Please use
transformers==latestfor:LLaVA-Next seriesPaliGemma-3BChameleon seriesVideo-LLaVA-7B-HFOvis seriesMantis seriesMiniCPM-V2.6OmChat-v2.0-13B-sinlge-betaIdefics-3GLM-4v-9BVideoChat2-HDRBDash_72bLlama-3.2 series
-
Please use
transformers==4.44.0for:Moondream2
Recommended Torchvision Version 🖼️
- Please use
torchvision>=0.16for theMoondream series
💻 Don’t forget to update the Python path in the run.sh file!
Have fun evaluating! 🎉
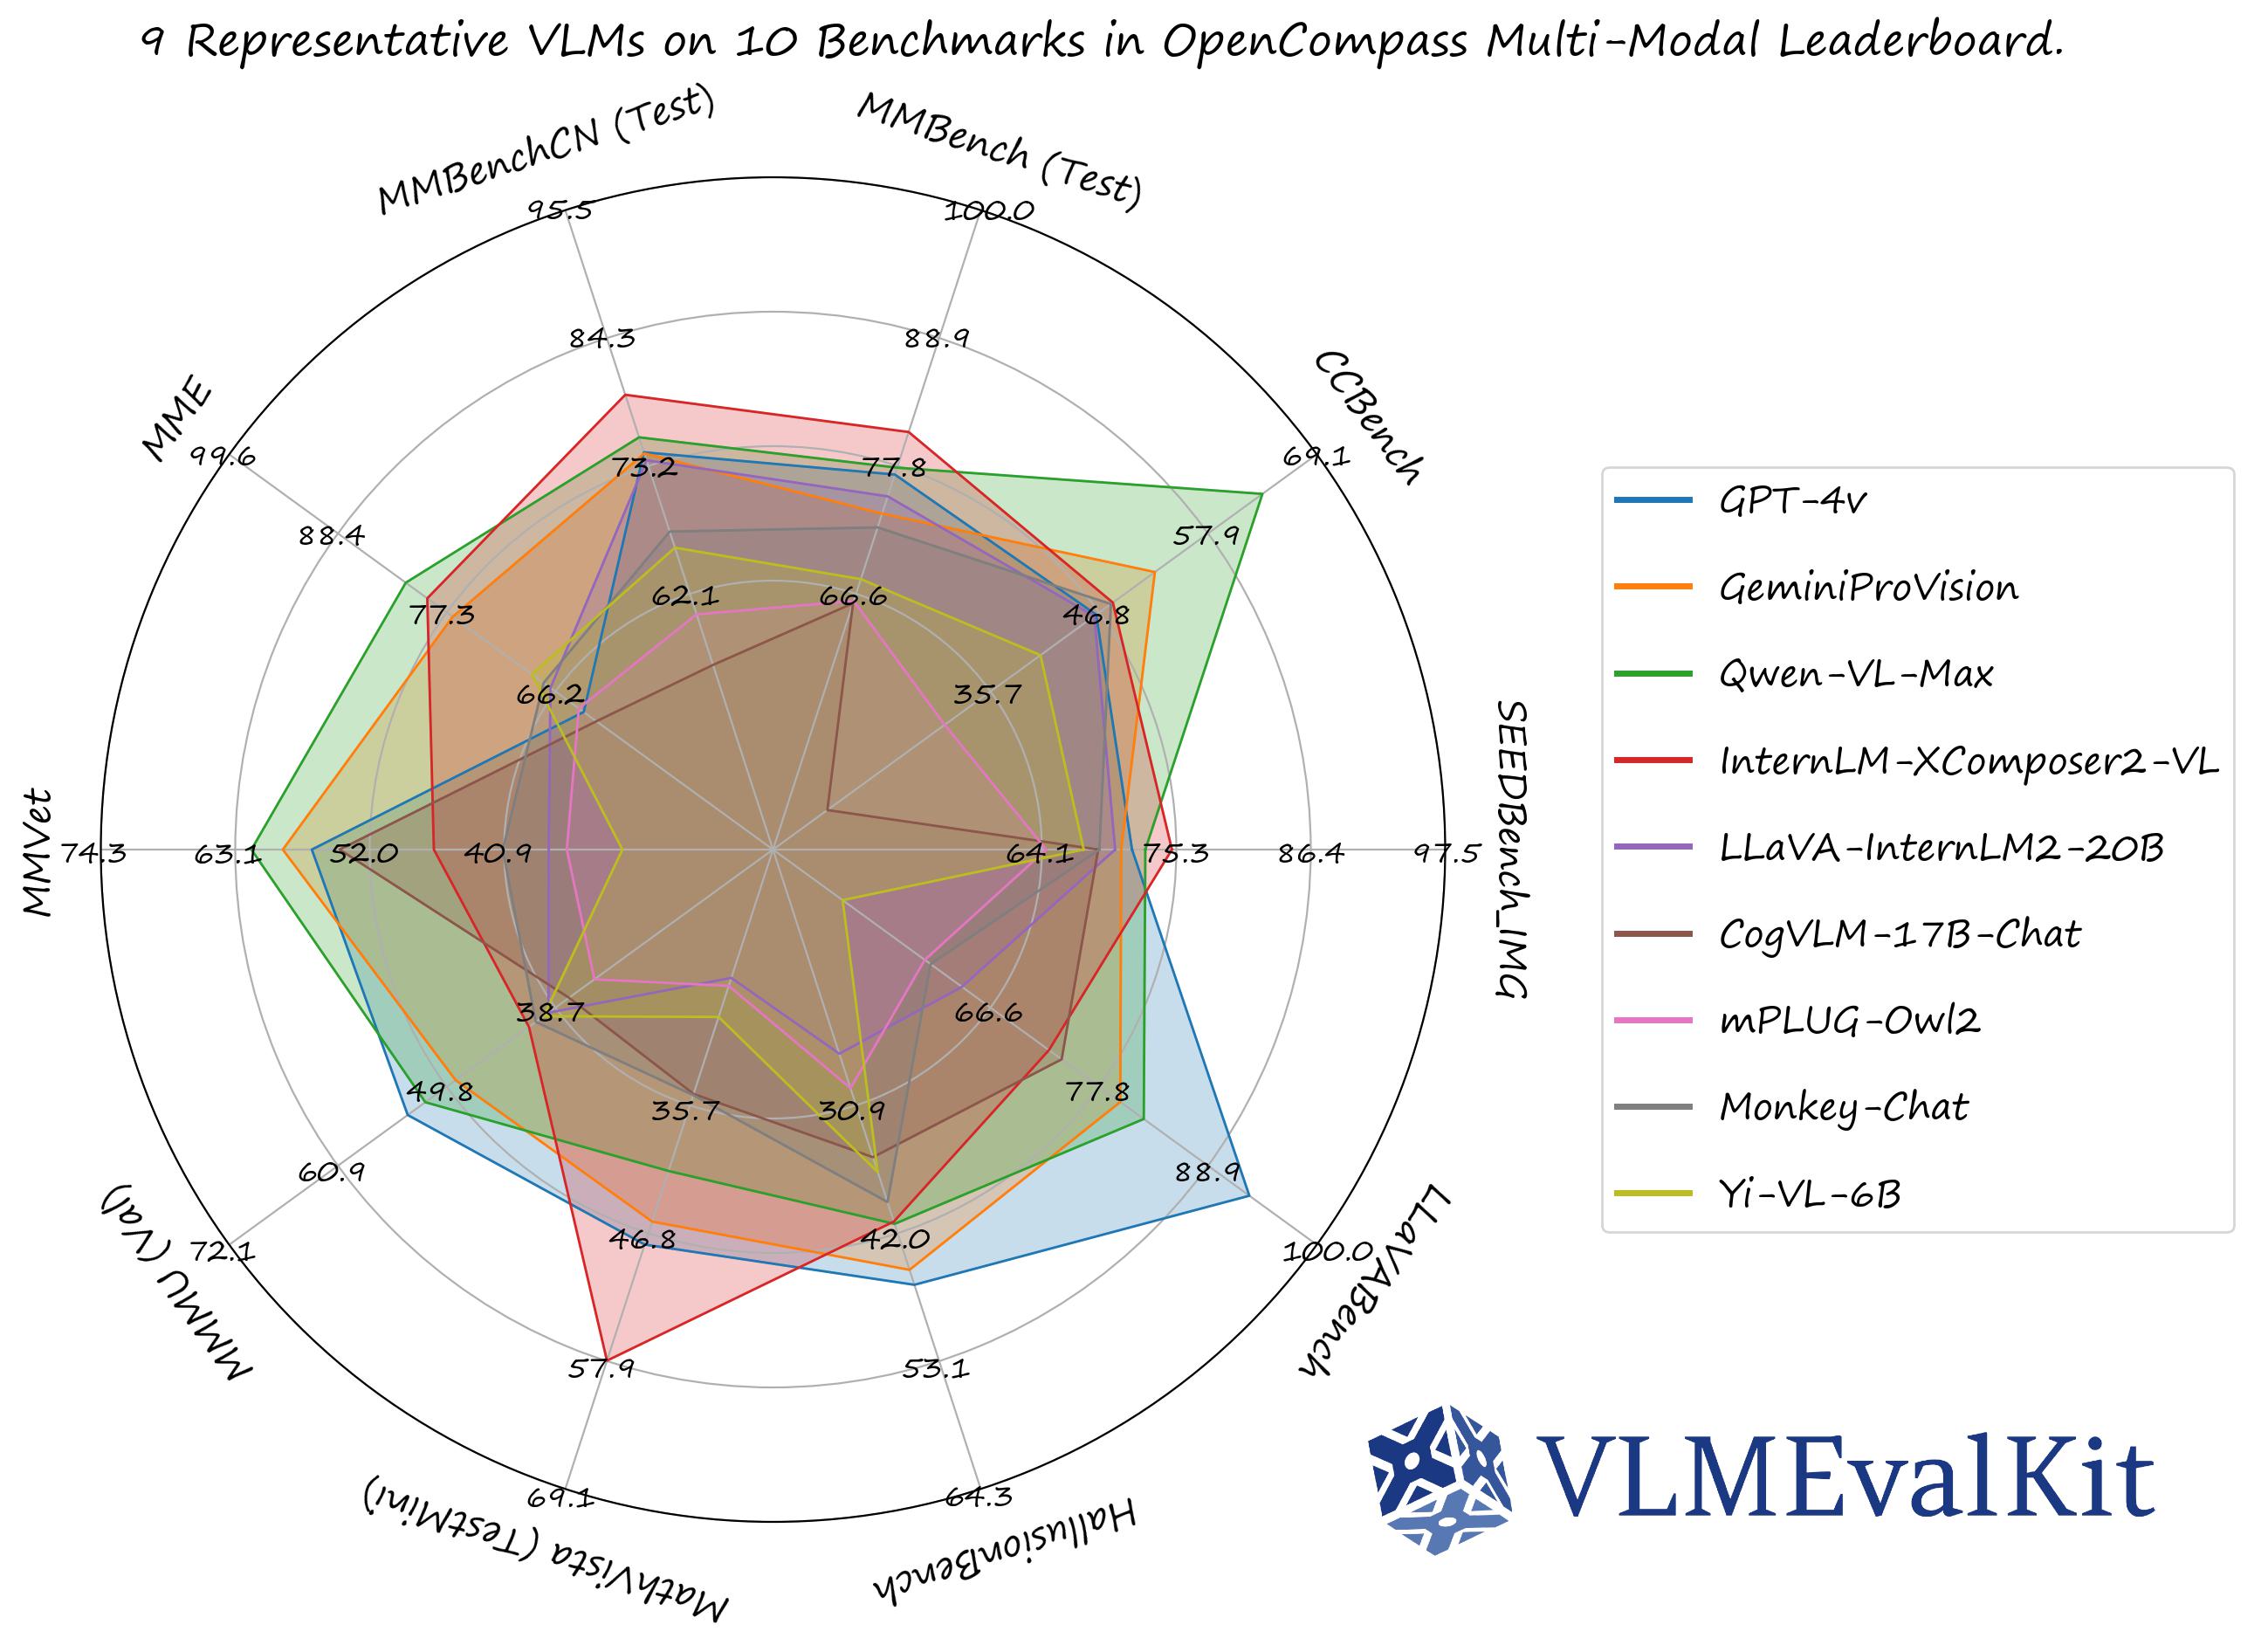
A Toolkit for Evaluating Large Vision-Language Models.


🏆 OC Learderboard • 📊Datasets & Models • 🏗️Quickstart • 🛠️Development • 🎯Goal • 🖊️Citation
🤗 HF Leaderboard • 🤗 Evaluation Records • 🔊 Discord • 📝 Report
VLMEvalKit (the python package name is vlmeval) is an open-source evaluation toolkit of large vision-language models (LVLMs). It enables one-command evaluation of LVLMs on various benchmarks, without the heavy workload of data preparation under multiple repositories. In VLMEvalKit, we adopt generation-based evaluation for all LVLMs, and provide the evaluation results obtained with both exact matching and LLM-based answer extraction.
🆕 News
- [2024-10-04] We have supported LLama3.2-Vision-Instruct, evaluations of two different sized models are in progress! 🔥🔥🔥
- [2024-09-30] We have supported BlueLM-V, thanks to rkshuai, the evaluation results are shown on the Leaderboard 🔥🔥🔥
- [2024-09-27] We have supported Xinyuan-VL-2B, thanks to thomas-yanxin, the evaluation results are shown on the Leaderboard 🔥🔥🔥
- [2024-09-26] We have supported MMSearch, thanks to CaraJ7 🔥🔥🔥
- [2024-09-23] We have supported Moondream Series, thanks to tackhwa 🔥🔥🔥
- [2024-09-23] We have supported MathVerse, thanks to CaraJ7 🔥🔥🔥
- [2024-09-20] We have supported AMBER, thanks to Yifan zhang 🔥🔥🔥
- [2024-09-20] We have supported Eagle, thanks to tackhwa 🔥🔥🔥
- [2024-09-19] We have supported Ovis1.6-Gemma2-9B, thanks to runninglsy 🔥🔥🔥
- [2024-09-13] We have supported CRPE, thanks to ttguoguo3 🔥🔥🔥
- [2024-09-09] We have supported HRBench, thanks to DreamMr 🔥🔥🔥
- [2024-09-09] We have supported SliME, thanks to Yifan zhang 🔥🔥🔥
- [2024-09-07] We have supported mPLUG-Owl3, thanks to SYuan03 🔥🔥🔥
- [2024-09-07] We have supported Qwen2-VL, thanks to kq-chen 🔥🔥🔥
- [2024-09-03] We have supported RBDash, thanks to anzhao920 🔥🔥🔥
- [2024-09-03] We have supported xGen-MM, thanks to amitbcp 🔥🔥🔥
- [2024-09-03] In the previous 2 months, 7 new contributors have made 3+ major contributions to the project: amitbcp, czczup, DseidLi, mayubo233, sun-hailong, PhoenixZ810, Cuiunbo. We will update the report accordingly in the coming weeks. Check contributor list for their detailed contributions 🔥🔥🔥
📊 Datasets, Models, and Evaluation Results
The performance numbers on our official multi-modal leaderboards can be downloaded from here!
OpenVLM Leaderboard: Download All DETAILED Results.
Supported Image Understanding Dataset
- By default, all evaluation results are presented in OpenVLM Leaderboard.
- Abbrs:
MCQ: Multi-choice question;Y/N: Yes-or-No Questions;MTT: Benchmark with Multi-turn Conversations;MTI: Benchmark with Multi-Image as Inputs.
| Dataset | Dataset Names (for run.py) | Task | Dataset | Dataset Names (for run.py) | Task |
|---|---|---|---|---|---|
| MMBench Series: MMBench, MMBench-CN, CCBench | MMBench_DEV_[EN/CN] MMBench_TEST_[EN/CN] MMBench_DEV_[EN/CN]_V11 MMBench_TEST_[EN/CN]_V11 CCBench | MCQ | MMStar | MMStar | MCQ |
| MME | MME | Y/N | SEEDBench Series | SEEDBench_IMG SEEDBench2 SEEDBench2_Plus | MCQ |
| MM-Vet | MMVet | VQA | MMMU | MMMU_[DEV_VAL/TEST] | MCQ |
| MathVista | MathVista_MINI | VQA | ScienceQA_IMG | ScienceQA_[VAL/TEST] | MCQ |
| COCO Caption | COCO_VAL | Caption | HallusionBench | HallusionBench | Y/N |
| OCRVQA* | OCRVQA_[TESTCORE/TEST] | VQA | TextVQA* | TextVQA_VAL | VQA |
| ChartQA* | ChartQA_TEST | VQA | AI2D | AI2D_[TEST/TEST_NO_MASK] | MCQ |
| LLaVABench | LLaVABench | VQA | DocVQA+ | DocVQA_[VAL/TEST] | VQA |
| InfoVQA+ | InfoVQA_[VAL/TEST] | VQA | OCRBench | OCRBench | VQA |
| RealWorldQA | RealWorldQA | MCQ | POPE | POPE | Y/N |
| Core-MM- | CORE_MM (MTI) | VQA | MMT-Bench | MMT-Bench_[VAL/ALL] MMT-Bench_[VAL/ALL]_MI | MCQ (MTI) |
| MLLMGuard - | MLLMGuard_DS | VQA | AesBench+ | AesBench_[VAL/TEST] | MCQ |
| VCR-wiki + | VCR_[EN/ZH]_[EASY/HARD]_[ALL/500/100] | VQA | MMLongBench-Doc+ | MMLongBench_DOC | VQA (MTI) |
| BLINK | BLINK | MCQ (MTI) | MathVision+ | MathVision MathVision_MINI | VQA |
| MT-VQA | MTVQA_TEST | VQA | MMDU+ | MMDU | VQA (MTT, MTI) |
| Q-Bench1 | Q-Bench1_[VAL/TEST] | MCQ | A-Bench | A-Bench_[VAL/TEST] | MCQ |
| DUDE+ | DUDE | VQA (MTI) | SlideVQA+ | SLIDEVQA SLIDEVQA_MINI | VQA (MTI) |
| TaskMeAnything ImageQA Random+ | TaskMeAnything_v1_imageqa_random | MCQ | MMMB and Multilingual MMBench+ | MMMB_[ar/cn/en/pt/ru/tr] MMBench_dev_[ar/cn/en/pt/ru/tr] MMMB MTL_MMBench_DEV PS: MMMB & MTL_MMBench_DEV are all-in-one names for 6 langs | MCQ |
| A-OKVQA+ | A-OKVQA | MCQ | MuirBench+ | MUIRBench | MCQ |
| GMAI-MMBench+ | GMAI-MMBench_VAL | MCQ | TableVQABench+ | TableVQABench | VQA |
| MME-RealWorld+ | MME-RealWorld[-CN] | MCQ | HRBench+ | HRBench[4K/8K] | MCQ |
| MathVerse+ | MathVerse_MINI MathVerse_MINI_Vision_Only MathVerse_MINI_Vision_Dominant MathVerse_MINI_Vision_Intensive MathVerse_MINI_Text_Lite MathVerse_MINI_Text_Dominant | VQA | AMBER+ | AMBER | Y/N |
| CRPE+ | CRPE_[EXIST/RELATION] | VQA | MMSearch* | - | - |
d reasonable results under the zero-shot setting
+ The evaluation results are not available yet
- Only inference is supported in VLMEvalKit
* VLMEvalKit is integrated in its official repository.
VLMEvalKit will use a judge LLM to extract answer from the output if you set the key, otherwise it uses the exact matching mode (find "Yes", "No", "A", "B", "C"... in the output strings). The exact matching can only be applied to the Yes-or-No tasks and the Multi-choice tasks.
Supported Video Understanding Dataset
| Dataset | Dataset Names (for run.py) | Task | Dataset | Dataset Names (for run.py) | Task |
|---|---|---|---|---|---|
| MMBench-Video | MMBench-Video | VQA | Video-MME | Video-MME | MCQ |
| MVBench | MVBench/MVBench_MP4 | MCQ |
Supported API Models
Supported PyTorch / HF Models
🎞️: Support multiple images as inputs.
🚅: Models can be used without any additional configuration/operation.
🎬: Support Video as inputs.
Transformers Version Recommendation:
Note that some VLMs may not be able to run under certain transformer versions, we recommend the following settings to evaluate each VLM:
- Please use
transformers==4.33.0for:Qwen series,Monkey series,InternLM-XComposer Series,mPLUG-Owl2,OpenFlamingo v2,IDEFICS series,VisualGLM,MMAlaya,ShareCaptioner,MiniGPT-4 series,InstructBLIP series,PandaGPT,VXVERSE. - Please use
transformers==4.36.2for:Moondream1. - Please use
transformers==4.37.0for:LLaVA series,ShareGPT4V series,TransCore-M,LLaVA (XTuner),CogVLM Series,EMU2 Series,Yi-VL Series,MiniCPM-[V1/V2],OmniLMM-12B,DeepSeek-VL series,InternVL series,Cambrian Series,VILA Series,Llama-3-MixSenseV1_1,Parrot-7B,PLLaVA Series. - Please use
transformers==4.40.0for:IDEFICS2,Bunny-Llama3,MiniCPM-Llama3-V2.5,360VL-70B,Phi-3-Vision,WeMM. - Please use
transformers==latestfor:LLaVA-Next series,PaliGemma-3B,Chameleon series,Video-LLaVA-7B-HF,Ovis series,Mantis series,MiniCPM-V2.6,OmChat-v2.0-13B-sinlge-beta,Idefics-3,GLM-4v-9B,VideoChat2-HD,RBDash_72b,Llama-3.2 series. - Please use
transformers==4.44.0for:Moondream2.
Note that some VLMs may not be able to run under certain torchvision versions, we recommend the following settings to evaluate each VLM:
- Please use
torchvision>=0.16for:Moondream series
# Demo
from vlmeval.config import supported_VLM
model = supported_VLM['idefics_9b_instruct']()
# Forward Single Image
ret = model.generate(['assets/apple.jpg', 'What is in this image?'])
print(ret)  # The image features a red apple with a leaf on it.
# Forward Multiple Images
ret = model.generate(['assets/apple.jpg', 'assets/apple.jpg', 'How many apples are there in the provided images? '])
print(ret)  # There are two apples in the provided images.
🏗️ QuickStart
See [QuickStart | 快速开始] for a quick start guide.
🛠️ Development Guide
To develop custom benchmarks, VLMs, or simply contribute other codes to VLMEvalKit, please refer to [Development_Guide | 开发指南].
Call for contributions
To promote the contribution from the community and share the corresponding credit (in the next report update):
- All Contributions will be acknowledged in the report.
- Contributors with 3 or more major contributions (implementing an MLLM, benchmark, or major feature) can join the author list of VLMEvalKit Technical Report on ArXiv. Eligible contributors can create an issue or dm kennyutc in VLMEvalKit Discord Channel.
Here is a contributor list we curated based on the records.
🎯 The Goal of VLMEvalKit
The codebase is designed to:
- Provide an easy-to-use, opensource evaluation toolkit to make it convenient for researchers & developers to evaluate existing LVLMs and make evaluation results easy to reproduce.
- Make it easy for VLM developers to evaluate their own models. To evaluate the VLM on multiple supported benchmarks, one just need to implement a single
generate_inner()function, all other workloads (data downloading, data preprocessing, prediction inference, metric calculation) are handled by the codebase.
The codebase is not designed to:
- Reproduce the exact accuracy number reported in the original papers of all 3rd party benchmarks. The reason can be two-fold:
- VLMEvalKit uses generation-based evaluation for all VLMs (and optionally with LLM-based answer extraction). Meanwhile, some benchmarks may use different approaches (SEEDBench uses PPL-based evaluation, eg.). For those benchmarks, we compare both scores in the corresponding result. We encourage developers to support other evaluation paradigms in the codebase.
- By default, we use the same prompt template for all VLMs to evaluate on a benchmark. Meanwhile, some VLMs may have their specific prompt templates (some may not covered by the codebase at this time). We encourage VLM developers to implement their own prompt template in VLMEvalKit, if that is not covered currently. That will help to improve the reproducibility.
🖊️ Citation
If you find this work helpful, please consider to star🌟 this repo. Thanks for your support!
If you use VLMEvalKit in your research or wish to refer to published OpenSource evaluation results, please use the following BibTeX entry and the BibTex entry corresponding to the specific VLM / benchmark you used.
@misc{duan2024vlmevalkit,
      title={VLMEvalKit: An Open-Source Toolkit for Evaluating Large Multi-Modality Models},
      author={Haodong Duan and Junming Yang and Yuxuan Qiao and Xinyu Fang and Lin Chen and Yuan Liu and Xiaoyi Dong and Yuhang Zang and Pan Zhang and Jiaqi Wang and Dahua Lin and Kai Chen},
      year={2024},
      eprint={2407.11691},
      archivePrefix={arXiv},
      primaryClass={cs.CV},
      url={https://arxiv.org/abs/2407.11691},
}
Similar repos


Languages
Python
97.6%
Jupyter Notebook
2.0%
Open-source evaluation toolkit of large vision-language models (LVLMs), support ~100 VLMs, 40+ benchmarks
See the codeREADME
🌍 Welcome to the Evaluation Suite for worldMedQA-V! 🚀
The fastest way to get started is:
👉 Follow the [QuickStart | 快速开始] guide to jump right in and get rolling! Make sure your Huggingface setup is good to go! 😊
Recommended Transformers Version 🤖
💡 Important Note: Some Vision-Language Models (VLMs) may not work well with certain versions of transformers. We recommend the following settings to evaluate each VLM:
-
Please use
transformers==4.33.0for:Qwen seriesMonkey seriesInternLM-XComposer SeriesmPLUG-Owl2OpenFlamingo v2IDEFICS seriesVisualGLMMMAlayaShareCaptionerMiniGPT-4 seriesInstructBLIP seriesPandaGPTVXVERSE
-
Please use
transformers==4.36.2for:Moondream1
-
Please use
transformers==4.37.0for:LLaVA seriesShareGPT4V seriesTransCore-MLLaVA (XTuner)CogVLM SeriesEMU2 SeriesYi-VL SeriesMiniCPM-[V1/V2]OmniLMM-12BDeepSeek-VL seriesInternVL seriesCambrian SeriesVILA SeriesLlama-3-MixSenseV1_1Parrot-7BPLLaVA Series
-
Please use
transformers==4.40.0for:IDEFICS2Bunny-Llama3MiniCPM-Llama3-V2.5360VL-70BPhi-3-VisionWeMM
-
Please use
transformers==latestfor:LLaVA-Next seriesPaliGemma-3BChameleon seriesVideo-LLaVA-7B-HFOvis seriesMantis seriesMiniCPM-V2.6OmChat-v2.0-13B-sinlge-betaIdefics-3GLM-4v-9BVideoChat2-HDRBDash_72bLlama-3.2 series
-
Please use
transformers==4.44.0for:Moondream2
Recommended Torchvision Version 🖼️
- Please use
torchvision>=0.16for theMoondream series
💻 Don’t forget to update the Python path in the run.sh file!
Have fun evaluating! 🎉
A Toolkit for Evaluating Large Vision-Language Models.
🏆 OC Learderboard • 📊Datasets & Models • 🏗️Quickstart • 🛠️Development • 🎯Goal • 🖊️Citation
🤗 HF Leaderboard • 🤗 Evaluation Records • 🔊 Discord • 📝 Report
VLMEvalKit (the python package name is vlmeval) is an open-source evaluation toolkit of large vision-language models (LVLMs). It enables one-command evaluation of LVLMs on various benchmarks, without the heavy workload of data preparation under multiple repositories. In VLMEvalKit, we adopt generation-based evaluation for all LVLMs, and provide the evaluation results obtained with both exact matching and LLM-based answer extraction.
🆕 News
- [2024-10-04] We have supported LLama3.2-Vision-Instruct, evaluations of two different sized models are in progress! 🔥🔥🔥
- [2024-09-30] We have supported BlueLM-V, thanks to rkshuai, the evaluation results are shown on the Leaderboard 🔥🔥🔥
- [2024-09-27] We have supported Xinyuan-VL-2B, thanks to thomas-yanxin, the evaluation results are shown on the Leaderboard 🔥🔥🔥
- [2024-09-26] We have supported MMSearch, thanks to CaraJ7 🔥🔥🔥
- [2024-09-23] We have supported Moondream Series, thanks to tackhwa 🔥🔥🔥
- [2024-09-23] We have supported MathVerse, thanks to CaraJ7 🔥🔥🔥
- [2024-09-20] We have supported AMBER, thanks to Yifan zhang 🔥🔥🔥
- [2024-09-20] We have supported Eagle, thanks to tackhwa 🔥🔥🔥
- [2024-09-19] We have supported Ovis1.6-Gemma2-9B, thanks to runninglsy 🔥🔥🔥
- [2024-09-13] We have supported CRPE, thanks to ttguoguo3 🔥🔥🔥
- [2024-09-09] We have supported HRBench, thanks to DreamMr 🔥🔥🔥
- [2024-09-09] We have supported SliME, thanks to Yifan zhang 🔥🔥🔥
- [2024-09-07] We have supported mPLUG-Owl3, thanks to SYuan03 🔥🔥🔥
- [2024-09-07] We have supported Qwen2-VL, thanks to kq-chen 🔥🔥🔥
- [2024-09-03] We have supported RBDash, thanks to anzhao920 🔥🔥🔥
- [2024-09-03] We have supported xGen-MM, thanks to amitbcp 🔥🔥🔥
- [2024-09-03] In the previous 2 months, 7 new contributors have made 3+ major contributions to the project: amitbcp, czczup, DseidLi, mayubo233, sun-hailong, PhoenixZ810, Cuiunbo. We will update the report accordingly in the coming weeks. Check contributor list for their detailed contributions 🔥🔥🔥
📊 Datasets, Models, and Evaluation Results
The performance numbers on our official multi-modal leaderboards can be downloaded from here!
OpenVLM Leaderboard: Download All DETAILED Results.
Supported Image Understanding Dataset
- By default, all evaluation results are presented in OpenVLM Leaderboard.
- Abbrs:
MCQ: Multi-choice question;Y/N: Yes-or-No Questions;MTT: Benchmark with Multi-turn Conversations;MTI: Benchmark with Multi-Image as Inputs.
| Dataset | Dataset Names (for run.py) | Task | Dataset | Dataset Names (for run.py) | Task |
|---|---|---|---|---|---|
| MMBench Series: MMBench, MMBench-CN, CCBench | MMBench_DEV_[EN/CN] MMBench_TEST_[EN/CN] MMBench_DEV_[EN/CN]_V11 MMBench_TEST_[EN/CN]_V11 CCBench | MCQ | MMStar | MMStar | MCQ |
| MME | MME | Y/N | SEEDBench Series | SEEDBench_IMG SEEDBench2 SEEDBench2_Plus | MCQ |
| MM-Vet | MMVet | VQA | MMMU | MMMU_[DEV_VAL/TEST] | MCQ |
| MathVista | MathVista_MINI | VQA | ScienceQA_IMG | ScienceQA_[VAL/TEST] | MCQ |
| COCO Caption | COCO_VAL | Caption | HallusionBench | HallusionBench | Y/N |
| OCRVQA* | OCRVQA_[TESTCORE/TEST] | VQA | TextVQA* | TextVQA_VAL | VQA |
| ChartQA* | ChartQA_TEST | VQA | AI2D | AI2D_[TEST/TEST_NO_MASK] | MCQ |
| LLaVABench | LLaVABench | VQA | DocVQA+ | DocVQA_[VAL/TEST] | VQA |
| InfoVQA+ | InfoVQA_[VAL/TEST] | VQA | OCRBench | OCRBench | VQA |
| RealWorldQA | RealWorldQA | MCQ | POPE | POPE | Y/N |
| Core-MM- | CORE_MM (MTI) | VQA | MMT-Bench | MMT-Bench_[VAL/ALL] MMT-Bench_[VAL/ALL]_MI | MCQ (MTI) |
| MLLMGuard - | MLLMGuard_DS | VQA | AesBench+ | AesBench_[VAL/TEST] | MCQ |
| VCR-wiki + | VCR_[EN/ZH]_[EASY/HARD]_[ALL/500/100] | VQA | MMLongBench-Doc+ | MMLongBench_DOC | VQA (MTI) |
| BLINK | BLINK | MCQ (MTI) | MathVision+ | MathVision MathVision_MINI | VQA |
| MT-VQA | MTVQA_TEST | VQA | MMDU+ | MMDU | VQA (MTT, MTI) |
| Q-Bench1 | Q-Bench1_[VAL/TEST] | MCQ | A-Bench | A-Bench_[VAL/TEST] | MCQ |
| DUDE+ | DUDE | VQA (MTI) | SlideVQA+ | SLIDEVQA SLIDEVQA_MINI | VQA (MTI) |
| TaskMeAnything ImageQA Random+ | TaskMeAnything_v1_imageqa_random | MCQ | MMMB and Multilingual MMBench+ | MMMB_[ar/cn/en/pt/ru/tr] MMBench_dev_[ar/cn/en/pt/ru/tr] MMMB MTL_MMBench_DEV PS: MMMB & MTL_MMBench_DEV are all-in-one names for 6 langs | MCQ |
| A-OKVQA+ | A-OKVQA | MCQ | MuirBench+ | MUIRBench | MCQ |
| GMAI-MMBench+ | GMAI-MMBench_VAL | MCQ | TableVQABench+ | TableVQABench | VQA |
| MME-RealWorld+ | MME-RealWorld[-CN] | MCQ | HRBench+ | HRBench[4K/8K] | MCQ |
| MathVerse+ | MathVerse_MINI MathVerse_MINI_Vision_Only MathVerse_MINI_Vision_Dominant MathVerse_MINI_Vision_Intensive MathVerse_MINI_Text_Lite MathVerse_MINI_Text_Dominant | VQA | AMBER+ | AMBER | Y/N |
| CRPE+ | CRPE_[EXIST/RELATION] | VQA | MMSearch* | - | - |
d reasonable results under the zero-shot setting
+ The evaluation results are not available yet
- Only inference is supported in VLMEvalKit
* VLMEvalKit is integrated in its official repository.
VLMEvalKit will use a judge LLM to extract answer from the output if you set the key, otherwise it uses the exact matching mode (find "Yes", "No", "A", "B", "C"... in the output strings). The exact matching can only be applied to the Yes-or-No tasks and the Multi-choice tasks.
Supported Video Understanding Dataset
| Dataset | Dataset Names (for run.py) | Task | Dataset | Dataset Names (for run.py) | Task |
|---|---|---|---|---|---|
| MMBench-Video | MMBench-Video | VQA | Video-MME | Video-MME | MCQ |
| MVBench | MVBench/MVBench_MP4 | MCQ |
Supported API Models
Supported PyTorch / HF Models
🎞️: Support multiple images as inputs.
🚅: Models can be used without any additional configuration/operation.
🎬: Support Video as inputs.
Transformers Version Recommendation:
Note that some VLMs may not be able to run under certain transformer versions, we recommend the following settings to evaluate each VLM:
- Please use
transformers==4.33.0for:Qwen series,Monkey series,InternLM-XComposer Series,mPLUG-Owl2,OpenFlamingo v2,IDEFICS series,VisualGLM,MMAlaya,ShareCaptioner,MiniGPT-4 series,InstructBLIP series,PandaGPT,VXVERSE. - Please use
transformers==4.36.2for:Moondream1. - Please use
transformers==4.37.0for:LLaVA series,ShareGPT4V series,TransCore-M,LLaVA (XTuner),CogVLM Series,EMU2 Series,Yi-VL Series,MiniCPM-[V1/V2],OmniLMM-12B,DeepSeek-VL series,InternVL series,Cambrian Series,VILA Series,Llama-3-MixSenseV1_1,Parrot-7B,PLLaVA Series. - Please use
transformers==4.40.0for:IDEFICS2,Bunny-Llama3,MiniCPM-Llama3-V2.5,360VL-70B,Phi-3-Vision,WeMM. - Please use
transformers==latestfor:LLaVA-Next series,PaliGemma-3B,Chameleon series,Video-LLaVA-7B-HF,Ovis series,Mantis series,MiniCPM-V2.6,OmChat-v2.0-13B-sinlge-beta,Idefics-3,GLM-4v-9B,VideoChat2-HD,RBDash_72b,Llama-3.2 series. - Please use
transformers==4.44.0for:Moondream2.
Note that some VLMs may not be able to run under certain torchvision versions, we recommend the following settings to evaluate each VLM:
- Please use
torchvision>=0.16for:Moondream series
# Demo
from vlmeval.config import supported_VLM
model = supported_VLM['idefics_9b_instruct']()
# Forward Single Image
ret = model.generate(['assets/apple.jpg', 'What is in this image?'])
print(ret)  # The image features a red apple with a leaf on it.
# Forward Multiple Images
ret = model.generate(['assets/apple.jpg', 'assets/apple.jpg', 'How many apples are there in the provided images? '])
print(ret)  # There are two apples in the provided images.
🏗️ QuickStart
See [QuickStart | 快速开始] for a quick start guide.
🛠️ Development Guide
To develop custom benchmarks, VLMs, or simply contribute other codes to VLMEvalKit, please refer to [Development_Guide | 开发指南].
Call for contributions
To promote the contribution from the community and share the corresponding credit (in the next report update):
- All Contributions will be acknowledged in the report.
- Contributors with 3 or more major contributions (implementing an MLLM, benchmark, or major feature) can join the author list of VLMEvalKit Technical Report on ArXiv. Eligible contributors can create an issue or dm kennyutc in VLMEvalKit Discord Channel.
Here is a contributor list we curated based on the records.
🎯 The Goal of VLMEvalKit
The codebase is designed to:
- Provide an easy-to-use, opensource evaluation toolkit to make it convenient for researchers & developers to evaluate existing LVLMs and make evaluation results easy to reproduce.
- Make it easy for VLM developers to evaluate their own models. To evaluate the VLM on multiple supported benchmarks, one just need to implement a single
generate_inner()function, all other workloads (data downloading, data preprocessing, prediction inference, metric calculation) are handled by the codebase.
The codebase is not designed to:
- Reproduce the exact accuracy number reported in the original papers of all 3rd party benchmarks. The reason can be two-fold:
- VLMEvalKit uses generation-based evaluation for all VLMs (and optionally with LLM-based answer extraction). Meanwhile, some benchmarks may use different approaches (SEEDBench uses PPL-based evaluation, eg.). For those benchmarks, we compare both scores in the corresponding result. We encourage developers to support other evaluation paradigms in the codebase.
- By default, we use the same prompt template for all VLMs to evaluate on a benchmark. Meanwhile, some VLMs may have their specific prompt templates (some may not covered by the codebase at this time). We encourage VLM developers to implement their own prompt template in VLMEvalKit, if that is not covered currently. That will help to improve the reproducibility.
🖊️ Citation
If you find this work helpful, please consider to star🌟 this repo. Thanks for your support!
If you use VLMEvalKit in your research or wish to refer to published OpenSource evaluation results, please use the following BibTeX entry and the BibTex entry corresponding to the specific VLM / benchmark you used.
@misc{duan2024vlmevalkit,
      title={VLMEvalKit: An Open-Source Toolkit for Evaluating Large Multi-Modality Models},
      author={Haodong Duan and Junming Yang and Yuxuan Qiao and Xinyu Fang and Lin Chen and Yuan Liu and Xiaoyi Dong and Yuhang Zang and Pan Zhang and Jiaqi Wang and Dahua Lin and Kai Chen},
      year={2024},
      eprint={2407.11691},
      archivePrefix={arXiv},
      primaryClass={cs.CV},
      url={https://arxiv.org/abs/2407.11691},
}
Similar repos
Languages
Python
97.6%
Jupyter Notebook
2.0%