
README
WildVision-Bench
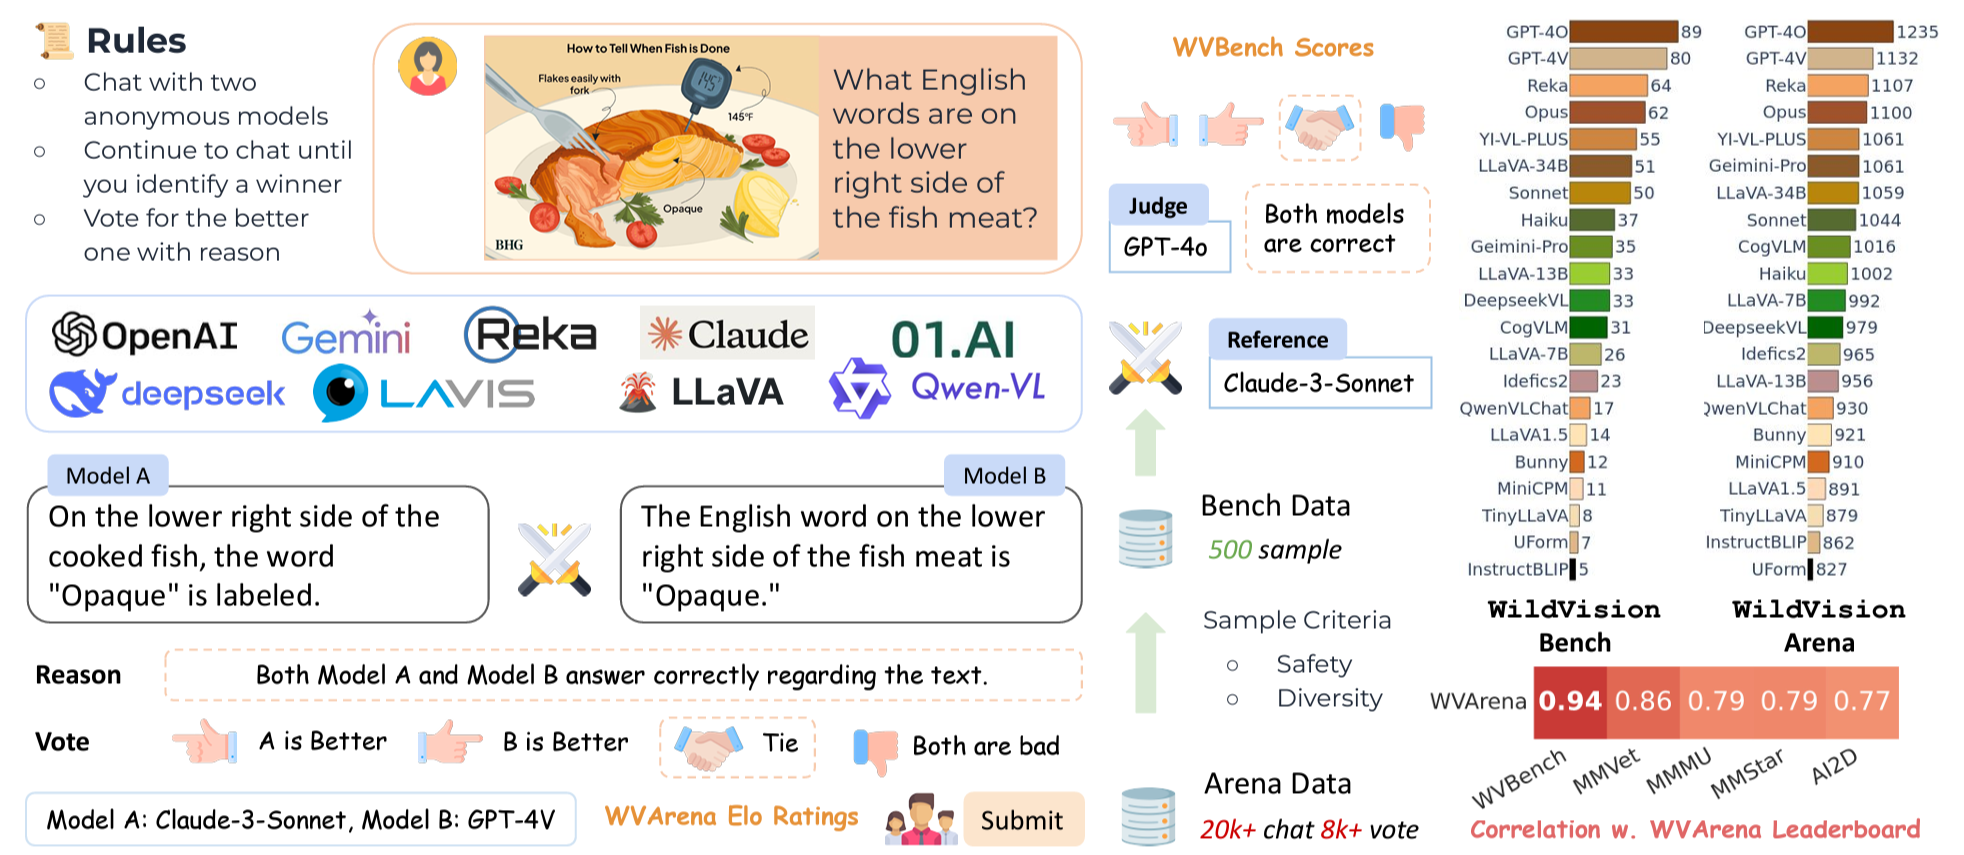
- Insipired by Alpaca-Eval, Arena-Hard, WildBench for the evaluation in the pure text setting, we propose WildVision-Bench to evaluate vision-language models in the wild with human preferences.
- Specifically, we collect real-world QA pairs from the 🤗 WildVision-Arena collections and curated 500 high quality examples for the evaluation.
- We use GPT-4o as the judgement model and Claude-3-Sonnet as our baseline model. The judge model is used to compare the model's response with the baseline model's response and decide which one is better.
- WildVision-Bench achives 0.94 correlation with the WildVision-Arena elo ranking, which is a good indicator for the model's performance in the wild.
installation
As part of the wildvision arena environment, please install the following dependencies:
conda create -n visionbench python==3.9
pip install -e .
WVBench Image-Instruct Pair
You can get image-instruct pair of WVBench-500 to generate your model answers by loading bench data below:
wildbench_data = load_dataset('WildVision/wildvision-bench', config_name='vision_bench_0617', split='test')
We have two versions of Wildvision-Bench data
vision_bench_0617: the selected 500 examples that best simulates the vision-arena elo ranking, same data in the paper.vision_bench_0701: the further filter and selected 500 examples by NSFW and manual selection. Leaderboard are still preparing.
Note: For now, if you want to evaluate your model, please use the vision_bench_0617 version to fairly compare the performance with other models in the following leaderboard.
We are preparing the leaderboard for vision_bench_0701 and will update it soon.
Evaluation
1. Generate model answers
Example model answers files is shown in data/vision_bench_0617/example_model_answers.jsonl. You need to fill the following fields:
output: the model's outputmodel: the model nametoken_len: the token length of the output (using tiktoken's gpt-3.5-turbo tokenizer) Then put the file indata/vision_bench_0617/model_answers/{model_name}.jsonl.
We provide example inference scripts in gen_answers.py and run_vllm.py to generate model answers. You can use the following command to generate model answers:
python run_vllm.py --tokenizer_mode "auto" --max_model_len 65536 --num_gpu 1 --model_name "meta-llama/Llama-3.2-11B-Vision-Instruct"
2. Get judgements
First, go to config/judge_config.yaml and add the models you want to evaluate in the model_list field. For example:
# Add your model below for evaluation
model_list:
  - liuhaotian/llava-v1.6-vicuna-7b
  - openbmb/MiniCPM-V
  - deepseek-ai/deepseek-vl-7b-chat
  - BAAI/Bunny-v1_0-3B
  - Salesforce/instructblip-vicuna-7b
Then, run the following command:
python get_judgement.py
Results will be saved in data/release_bench_0617/model_judgements/judge_gpt-4o_reference_claude-3-sonnet-20240229/{model_name}.jsonl
3. Show the results
python show_results.py
Then you will see the results as following leaderboard。
Using lmmseval to evaluate
LMMSEval is a Python package integrated with multiple MLLM's inference and evaluation tools. WildVision-Bench is one of the supported benchmarks. You can use the following command to evaluate your model on WildVision-Bench:
First, install lmmseval:
pip install lmmseval
Then, run the following command:
model_type=llava_hf
pretrained=llava-hf/llava-1.5-7b-hf
model_name=llava-1.5-7b-hf
python3 -m accelerate.commands.launch \
    --num_processes=8 \
    -m lmms_eval \
    --model $model_type \
    --model_args "pretrained=$pretrained" \
    --tasks wildvision_0617 \
    --batch_size 1 \
    --log_samples \
    --log_samples_suffix $model_name \
    --output_path ./logs/
Then find your lmmseval log dir for this evaluation, and run the following command to get the leaderboard:
python format_lmmseval_answers.py --lmmseval_log_dir {lmmseval_log_dir} --model_name {model_name}
python show_results.py
Leaderboard (vision_bench_0617)
| Model | Score | 95% CI | Win Rate | Reward | Much Better | Better | Tie | Worse | Much Worse | Avg Tokens |
|---|---|---|---|---|---|---|---|---|---|---|
| gpt-4o | 89.15 | (-1.9, 1.5) | 80.6% | 56.4 | 255.0 | 148.0 | 14.0 | 72.0 | 11.0 | 142 |
| gpt-4-vision-preview | 79.78 | (-2.9, 2.2) | 71.8% | 39.4 | 182.0 | 177.0 | 22.0 | 91.0 | 28.0 | 138 |
| aria | 74.1 | (-2.9, 3.2) | 68.0% | 28.8 | 88.0 | 252.0 | 47.0 | 86.0 | 27.0 | 185 |
| Reka-Flash | 64.65 | (-2.6, 2.7) | 58.8% | 18.9 | 135.0 | 159.0 | 28.0 | 116.0 | 62.0 | 168 |
| claude-3-opus-20240229 | 62.03 | (-3.7, 2.8) | 53.0% | 13.5 | 103.0 | 162.0 | 48.0 | 141.0 | 46.0 | 105 |
| yi-vl-plus | 55.05 | (-3.4, 2.3) | 52.8% | 7.2 | 98.0 | 166.0 | 29.0 | 124.0 | 83.0 | 140 |
| liuhaotian/llava-v1.6-34b | 51.89 | (-3.4, 3.8) | 49.2% | 2.5 | 90.0 | 156.0 | 26.0 | 145.0 | 83.0 | 153 |
| claude-3-sonnet-20240229 | 50.0 | (0.0, 0.0) | 0.2% | 0.1 | 0.0 | 1.0 | 499.0 | 0.0 | 0.0 | 114 |
| claude-3-haiku-20240307 | 37.83 | (-2.6, 2.8) | 30.6% | -16.5 | 54.0 | 99.0 | 47.0 | 228.0 | 72.0 | 89 |
| gemini-pro-vision | 35.57 | (-3.0, 3.2) | 32.6% | -21.0 | 80.0 | 83.0 | 27.0 | 167.0 | 143.0 | 68 |
| liuhaotian/llava-v1.6-vicuna-13b | 33.87 | (-2.9, 3.3) | 33.8% | -21.4 | 62.0 | 107.0 | 25.0 | 167.0 | 139.0 | 136 |
| deepseek-ai/deepseek-vl-7b-chat | 33.61 | (-3.3, 3.0) | 35.6% | -21.2 | 59.0 | 119.0 | 17.0 | 161.0 | 144.0 | 116 |
| THUDM/cogvlm-chat-hf | 32.01 | (-2.2, 3.0) | 30.6% | -26.4 | 75.0 | 78.0 | 15.0 | 172.0 | 160.0 | 61 |
| liuhaotian/llava-v1.6-vicuna-7b | 26.41 | (-3.3, 3.1) | 27.0% | -31.4 | 45.0 | 90.0 | 36.0 | 164.0 | 165.0 | 130 |
| idefics2-8b-chatty | 23.96 | (-2.2, 2.4) | 26.4% | -35.8 | 44.0 | 88.0 | 19.0 | 164.0 | 185.0 | 135 |
| Qwen/Qwen-VL-Chat | 18.08 | (-1.9, 2.2) | 19.6% | -47.9 | 42.0 | 56.0 | 15.0 | 155.0 | 232.0 | 69 |
| llava-1.5-7b-hf | 15.5 | (-2.4, 2.4) | 18.0% | -47.8 | 28.0 | 62.0 | 25.0 | 174.0 | 211.0 | 185 |
| liuhaotian/llava-v1.5-13b | 14.43 | (-1.7, 1.6) | 16.8% | -52.5 | 28.0 | 56.0 | 19.0 | 157.0 | 240.0 | 91 |
| BAAI/Bunny-v1_0-3B | 12.98 | (-2.0, 2.1) | 16.6% | -54.4 | 23.0 | 60.0 | 10.0 | 164.0 | 243.0 | 72 |
| openbmb/MiniCPM-V | 11.95 | (-2.4, 2.1) | 13.6% | -57.5 | 25.0 | 43.0 | 16.0 | 164.0 | 252.0 | 86 |
| bczhou/tiny-llava-v1-hf | 8.3 | (-1.6, 1.2) | 11.0% | -66.2 | 16.0 | 39.0 | 15.0 | 127.0 | 303.0 | 72 |
| unum-cloud/uform-gen2-qwen-500m | 7.81 | (-1.3, 1.7) | 10.8% | -68.5 | 16.0 | 38.0 | 11.0 | 115.0 | 320.0 | 92 |
Contributing to the leaderboard
If you want to contribute to the leaderboard, please follow the steps below:
- Fork this repository.
- Add your model's answers to the
data/vision_bench_0617/model_answers/directory. - Add your model's judgements to the
data/release_bench_0617/model_judgements/directory. - Run
python show_results.pyto generate the leaderboard. - Copy the
elo_leaderboard.mdfile and paste it into the above "Leaderboard" section. - Create a pull request.
Acknowledgment
We thank LMSYS for their great work on https://chat.lmsys.org/. Our code base is adapted from https://github.com/lm-sys/arena-hard-auto.
Thanks lmmseval for integrating WildVision-Bench into their evaluation platform.
Citation
If you found this repository useful, please consider cite our paper and resources:
@article{lu2024wildvision,
  title={WildVision: Evaluating Vision-Language Models in the Wild with Human Preferences},
  author={Lu, Yujie and Jiang, Dongfu and Chen, Wenhu and Wang, William Yang and Choi, Yejin and Lin, Bill Yuchen},
  publisher={NeurIPS},
  year={2024}
}
@misc{yujie2024wildvisionarena,
    title={WildVision Arena: Benchmarking Multimodal LLMs in the Wild},
    url={https://huggingface.co/spaces/WildVision/vision-arena/},
    author={Lu, Yujie and Jiang, Dongfu and Chen, Hui and Ma, Yingzi and Gu, Jing and Xiao, Chaowei and Chen, Wenhu and Wang, William and Choi, Yejin and Lin, Bill Yuchen},
    year={2024}
}
@misc{yujie2024wildvisionv2,
    title={WildVision Data and Model},
    url={https://huggingface.co/WildVision},
    author={Lu, Yujie* and Jiang, Dongfu* and Chen, Hui* and Fu, Xingyu and Ma, Yingzi and Gu, Jing and Saxon, Michael and Xiao, Chaowei and Chen, Wenhu and Choi, Yejin and Lin, Bill Yuchen and Eckstein, Miguel and Wang, William},
    year={2024}
}


Similar repos



Languages
Python
96.7%
Shell
3.3%
README
WildVision-Bench
- Insipired by Alpaca-Eval, Arena-Hard, WildBench for the evaluation in the pure text setting, we propose WildVision-Bench to evaluate vision-language models in the wild with human preferences.
- Specifically, we collect real-world QA pairs from the 🤗 WildVision-Arena collections and curated 500 high quality examples for the evaluation.
- We use GPT-4o as the judgement model and Claude-3-Sonnet as our baseline model. The judge model is used to compare the model's response with the baseline model's response and decide which one is better.
- WildVision-Bench achives 0.94 correlation with the WildVision-Arena elo ranking, which is a good indicator for the model's performance in the wild.
installation
As part of the wildvision arena environment, please install the following dependencies:
conda create -n visionbench python==3.9
pip install -e .
WVBench Image-Instruct Pair
You can get image-instruct pair of WVBench-500 to generate your model answers by loading bench data below:
wildbench_data = load_dataset('WildVision/wildvision-bench', config_name='vision_bench_0617', split='test')
We have two versions of Wildvision-Bench data
vision_bench_0617: the selected 500 examples that best simulates the vision-arena elo ranking, same data in the paper.vision_bench_0701: the further filter and selected 500 examples by NSFW and manual selection. Leaderboard are still preparing.
Note: For now, if you want to evaluate your model, please use the vision_bench_0617 version to fairly compare the performance with other models in the following leaderboard.
We are preparing the leaderboard for vision_bench_0701 and will update it soon.
Evaluation
1. Generate model answers
Example model answers files is shown in data/vision_bench_0617/example_model_answers.jsonl. You need to fill the following fields:
output: the model's outputmodel: the model nametoken_len: the token length of the output (using tiktoken's gpt-3.5-turbo tokenizer) Then put the file indata/vision_bench_0617/model_answers/{model_name}.jsonl.
We provide example inference scripts in gen_answers.py and run_vllm.py to generate model answers. You can use the following command to generate model answers:
python run_vllm.py --tokenizer_mode "auto" --max_model_len 65536 --num_gpu 1 --model_name "meta-llama/Llama-3.2-11B-Vision-Instruct"
2. Get judgements
First, go to config/judge_config.yaml and add the models you want to evaluate in the model_list field. For example:
# Add your model below for evaluation
model_list:
  - liuhaotian/llava-v1.6-vicuna-7b
  - openbmb/MiniCPM-V
  - deepseek-ai/deepseek-vl-7b-chat
  - BAAI/Bunny-v1_0-3B
  - Salesforce/instructblip-vicuna-7b
Then, run the following command:
python get_judgement.py
Results will be saved in data/release_bench_0617/model_judgements/judge_gpt-4o_reference_claude-3-sonnet-20240229/{model_name}.jsonl
3. Show the results
python show_results.py
Then you will see the results as following leaderboard。
Using lmmseval to evaluate
LMMSEval is a Python package integrated with multiple MLLM's inference and evaluation tools. WildVision-Bench is one of the supported benchmarks. You can use the following command to evaluate your model on WildVision-Bench:
First, install lmmseval:
pip install lmmseval
Then, run the following command:
model_type=llava_hf
pretrained=llava-hf/llava-1.5-7b-hf
model_name=llava-1.5-7b-hf
python3 -m accelerate.commands.launch \
    --num_processes=8 \
    -m lmms_eval \
    --model $model_type \
    --model_args "pretrained=$pretrained" \
    --tasks wildvision_0617 \
    --batch_size 1 \
    --log_samples \
    --log_samples_suffix $model_name \
    --output_path ./logs/
Then find your lmmseval log dir for this evaluation, and run the following command to get the leaderboard:
python format_lmmseval_answers.py --lmmseval_log_dir {lmmseval_log_dir} --model_name {model_name}
python show_results.py
Leaderboard (vision_bench_0617)
| Model | Score | 95% CI | Win Rate | Reward | Much Better | Better | Tie | Worse | Much Worse | Avg Tokens |
|---|---|---|---|---|---|---|---|---|---|---|
| gpt-4o | 89.15 | (-1.9, 1.5) | 80.6% | 56.4 | 255.0 | 148.0 | 14.0 | 72.0 | 11.0 | 142 |
| gpt-4-vision-preview | 79.78 | (-2.9, 2.2) | 71.8% | 39.4 | 182.0 | 177.0 | 22.0 | 91.0 | 28.0 | 138 |
| aria | 74.1 | (-2.9, 3.2) | 68.0% | 28.8 | 88.0 | 252.0 | 47.0 | 86.0 | 27.0 | 185 |
| Reka-Flash | 64.65 | (-2.6, 2.7) | 58.8% | 18.9 | 135.0 | 159.0 | 28.0 | 116.0 | 62.0 | 168 |
| claude-3-opus-20240229 | 62.03 | (-3.7, 2.8) | 53.0% | 13.5 | 103.0 | 162.0 | 48.0 | 141.0 | 46.0 | 105 |
| yi-vl-plus | 55.05 | (-3.4, 2.3) | 52.8% | 7.2 | 98.0 | 166.0 | 29.0 | 124.0 | 83.0 | 140 |
| liuhaotian/llava-v1.6-34b | 51.89 | (-3.4, 3.8) | 49.2% | 2.5 | 90.0 | 156.0 | 26.0 | 145.0 | 83.0 | 153 |
| claude-3-sonnet-20240229 | 50.0 | (0.0, 0.0) | 0.2% | 0.1 | 0.0 | 1.0 | 499.0 | 0.0 | 0.0 | 114 |
| claude-3-haiku-20240307 | 37.83 | (-2.6, 2.8) | 30.6% | -16.5 | 54.0 | 99.0 | 47.0 | 228.0 | 72.0 | 89 |
| gemini-pro-vision | 35.57 | (-3.0, 3.2) | 32.6% | -21.0 | 80.0 | 83.0 | 27.0 | 167.0 | 143.0 | 68 |
| liuhaotian/llava-v1.6-vicuna-13b | 33.87 | (-2.9, 3.3) | 33.8% | -21.4 | 62.0 | 107.0 | 25.0 | 167.0 | 139.0 | 136 |
| deepseek-ai/deepseek-vl-7b-chat | 33.61 | (-3.3, 3.0) | 35.6% | -21.2 | 59.0 | 119.0 | 17.0 | 161.0 | 144.0 | 116 |
| THUDM/cogvlm-chat-hf | 32.01 | (-2.2, 3.0) | 30.6% | -26.4 | 75.0 | 78.0 | 15.0 | 172.0 | 160.0 | 61 |
| liuhaotian/llava-v1.6-vicuna-7b | 26.41 | (-3.3, 3.1) | 27.0% | -31.4 | 45.0 | 90.0 | 36.0 | 164.0 | 165.0 | 130 |
| idefics2-8b-chatty | 23.96 | (-2.2, 2.4) | 26.4% | -35.8 | 44.0 | 88.0 | 19.0 | 164.0 | 185.0 | 135 |
| Qwen/Qwen-VL-Chat | 18.08 | (-1.9, 2.2) | 19.6% | -47.9 | 42.0 | 56.0 | 15.0 | 155.0 | 232.0 | 69 |
| llava-1.5-7b-hf | 15.5 | (-2.4, 2.4) | 18.0% | -47.8 | 28.0 | 62.0 | 25.0 | 174.0 | 211.0 | 185 |
| liuhaotian/llava-v1.5-13b | 14.43 | (-1.7, 1.6) | 16.8% | -52.5 | 28.0 | 56.0 | 19.0 | 157.0 | 240.0 | 91 |
| BAAI/Bunny-v1_0-3B | 12.98 | (-2.0, 2.1) | 16.6% | -54.4 | 23.0 | 60.0 | 10.0 | 164.0 | 243.0 | 72 |
| openbmb/MiniCPM-V | 11.95 | (-2.4, 2.1) | 13.6% | -57.5 | 25.0 | 43.0 | 16.0 | 164.0 | 252.0 | 86 |
| bczhou/tiny-llava-v1-hf | 8.3 | (-1.6, 1.2) | 11.0% | -66.2 | 16.0 | 39.0 | 15.0 | 127.0 | 303.0 | 72 |
| unum-cloud/uform-gen2-qwen-500m | 7.81 | (-1.3, 1.7) | 10.8% | -68.5 | 16.0 | 38.0 | 11.0 | 115.0 | 320.0 | 92 |
Contributing to the leaderboard
If you want to contribute to the leaderboard, please follow the steps below:
- Fork this repository.
- Add your model's answers to the
data/vision_bench_0617/model_answers/directory. - Add your model's judgements to the
data/release_bench_0617/model_judgements/directory. - Run
python show_results.pyto generate the leaderboard. - Copy the
elo_leaderboard.mdfile and paste it into the above "Leaderboard" section. - Create a pull request.
Acknowledgment
We thank LMSYS for their great work on https://chat.lmsys.org/. Our code base is adapted from https://github.com/lm-sys/arena-hard-auto.
Thanks lmmseval for integrating WildVision-Bench into their evaluation platform.
Citation
If you found this repository useful, please consider cite our paper and resources:
@article{lu2024wildvision,
  title={WildVision: Evaluating Vision-Language Models in the Wild with Human Preferences},
  author={Lu, Yujie and Jiang, Dongfu and Chen, Wenhu and Wang, William Yang and Choi, Yejin and Lin, Bill Yuchen},
  publisher={NeurIPS},
  year={2024}
}
@misc{yujie2024wildvisionarena,
    title={WildVision Arena: Benchmarking Multimodal LLMs in the Wild},
    url={https://huggingface.co/spaces/WildVision/vision-arena/},
    author={Lu, Yujie and Jiang, Dongfu and Chen, Hui and Ma, Yingzi and Gu, Jing and Xiao, Chaowei and Chen, Wenhu and Wang, William and Choi, Yejin and Lin, Bill Yuchen},
    year={2024}
}
@misc{yujie2024wildvisionv2,
    title={WildVision Data and Model},
    url={https://huggingface.co/WildVision},
    author={Lu, Yujie* and Jiang, Dongfu* and Chen, Hui* and Fu, Xingyu and Ma, Yingzi and Gu, Jing and Saxon, Michael and Xiao, Chaowei and Chen, Wenhu and Choi, Yejin and Lin, Bill Yuchen and Eckstein, Miguel and Wang, William},
    year={2024}
}
Similar repos
Languages
Python
96.7%
Shell
3.3%