UNetFormer: A UNet-like transformer for efficient semantic segmentation of remote sensing urban scene imagery, ISPRS. Also, including other vision transformers and CNNs for satellite, aerial image and UAV image segmentation.
Python
1,114
75 commits
updated Aug 19, 2024


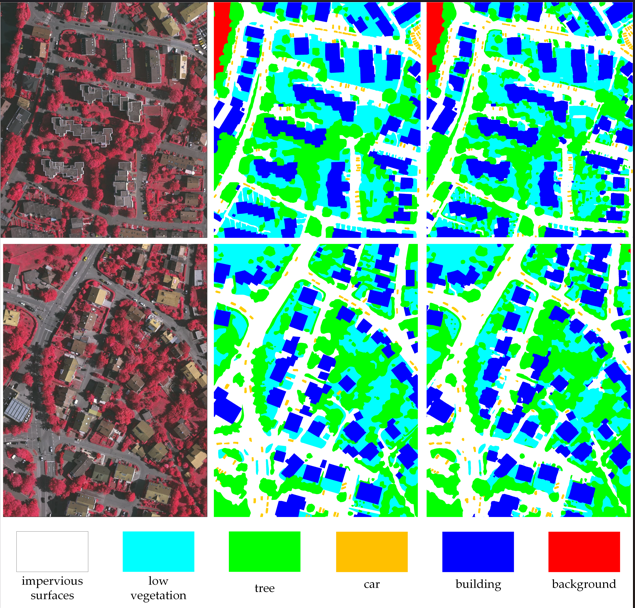
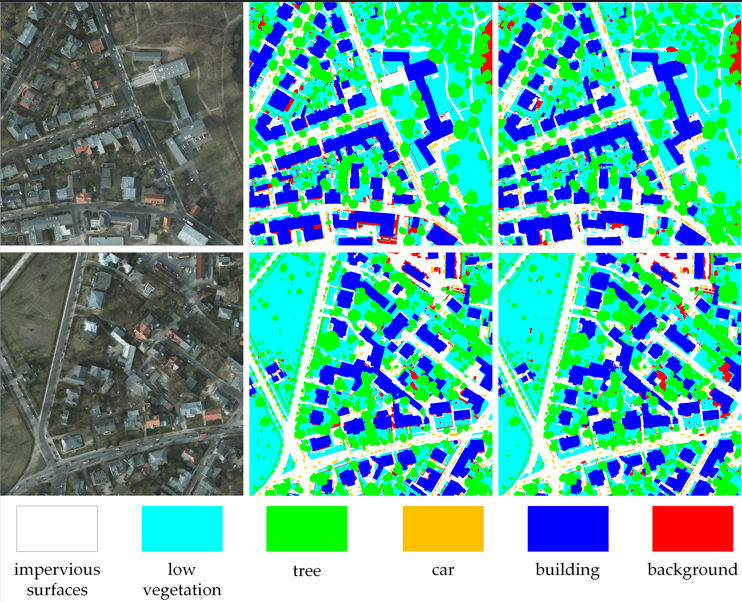
GeoSeg is an open-source semantic segmentation toolbox based on PyTorch, pytorch lightning and timm, which mainly focuses on developing advanced Vision Transformers for remote sensing image segmentation.
Unified Benchmark
we provide a unified training script for various segmentation methods.
Simple and Effective
Thanks to pytorch lightning and timm , the code is easy for further development.
Supported Remote Sensing Datasets
Multi-scale Training and Testing
Inference on Huge Remote Sensing Images
Mamba
Vision Transformer
CNN
Prepare the following folders to organize this repo:
airs
├── GeoSeg (code)
├── pretrain_weights (pretrained weights of backbones, such as vit, swin, etc)
├── model_weights (save the model weights trained on ISPRS vaihingen, LoveDA, etc)
├── fig_results (save the masks predicted by models)
├── lightning_logs (CSV format training logs)
├── data
│   ├── LoveDA
│   │   ├── Train
│   │   │   ├── Urban
│   │   │   │   ├── images_png (original images)
│   │   │   │   ├── masks_png (original masks)
│   │   │   │   ├── masks_png_convert (converted masks used for training)
│   │   │   │   ├── masks_png_convert_rgb (original rgb format masks)
│   │   │   ├── Rural
│   │   │   │   ├── images_png
│   │   │   │   ├── masks_png
│   │   │   │   ├── masks_png_convert
│   │   │   │   ├── masks_png_convert_rgb
│   │   ├── Val (the same with Train)
│   │   ├── Test
│   │   ├── train_val (Merge Train and Val)
│   ├── uavid
│   │   ├── uavid_train (original)
│   │   ├── uavid_val (original)
│   │   ├── uavid_test (original)
│   │   ├── uavid_train_val (Merge uavid_train and uavid_val)
│   │   ├── train (processed)
│   │   ├── val (processed)
│   │   ├── train_val (processed)
│   ├── vaihingen
│   │   ├── train_images (original)
│   │   ├── train_masks (original)
│   │   ├── test_images (original)
│   │   ├── test_masks (original)
│   │   ├── test_masks_eroded (original)
│   │   ├── train (processed)
│   │   ├── test (processed)
│   ├── potsdam (the same with vaihingen)
Open the folder airs using Linux Terminal and create python environment:
conda create -n airs python=3.8
conda activate airs
pip3 install torch torchvision torchaudio --index-url https://download.pytorch.org/whl/cu118
pip install -r GeoSeg/requirements.txt
Install Mamba
pip install causal-conv1d>=1.4.0
pip install mamba-ssm
Baidu Disk : 1234
Download the datasets from the official website and split them yourself.
Vaihingen
Generate the training set.
python GeoSeg/tools/vaihingen_patch_split.py \
--img-dir "data/vaihingen/train_images" \
--mask-dir "data/vaihingen/train_masks" \
--output-img-dir "data/vaihingen/train/images_1024" \
--output-mask-dir "data/vaihingen/train/masks_1024" \
--mode "train" --split-size 1024 --stride 512
Generate the testing set.
python GeoSeg/tools/vaihingen_patch_split.py \
--img-dir "data/vaihingen/test_images" \
--mask-dir "data/vaihingen/test_masks_eroded" \
--output-img-dir "data/vaihingen/test/images_1024" \
--output-mask-dir "data/vaihingen/test/masks_1024" \
--mode "val" --split-size 1024 --stride 1024 \
--eroded
Generate the masks_1024_rgb (RGB format ground truth labels) for visualization.
python GeoSeg/tools/vaihingen_patch_split.py \
--img-dir "data/vaihingen/test_images" \
--mask-dir "data/vaihingen/test_masks" \
--output-img-dir "data/vaihingen/test/images_1024" \
--output-mask-dir "data/vaihingen/test/masks_1024_rgb" \
--mode "val" --split-size 1024 --stride 1024 \
--gt
As for the validation set, you can select some images from the training set to build it.
Potsdam
python GeoSeg/tools/potsdam_patch_split.py \
--img-dir "data/potsdam/train_images" \
--mask-dir "data/potsdam/train_masks" \
--output-img-dir "data/potsdam/train/images_1024" \
--output-mask-dir "data/potsdam/train/masks_1024" \
--mode "train" --split-size 1024 --stride 1024 --rgb-image
python GeoSeg/tools/potsdam_patch_split.py \
--img-dir "data/potsdam/test_images" \
--mask-dir "data/potsdam/test_masks_eroded" \
--output-img-dir "data/potsdam/test/images_1024" \
--output-mask-dir "data/potsdam/test/masks_1024" \
--mode "val" --split-size 1024 --stride 1024 \
--eroded --rgb-image
python GeoSeg/tools/potsdam_patch_split.py \
--img-dir "data/potsdam/test_images" \
--mask-dir "data/potsdam/test_masks" \
--output-img-dir "data/potsdam/test/images_1024" \
--output-mask-dir "data/potsdam/test/masks_1024_rgb" \
--mode "val" --split-size 1024 --stride 1024 \
--gt --rgb-image
UAVid
python GeoSeg/tools/uavid_patch_split.py \
--input-dir "data/uavid/uavid_train_val" \
--output-img-dir "data/uavid/train_val/images" \
--output-mask-dir "data/uavid/train_val/masks" \
--mode 'train' --split-size-h 1024 --split-size-w 1024 \
--stride-h 1024 --stride-w 1024
python GeoSeg/tools/uavid_patch_split.py \
--input-dir "data/uavid/uavid_train" \
--output-img-dir "data/uavid/train/images" \
--output-mask-dir "data/uavid/train/masks" \
--mode 'train' --split-size-h 1024 --split-size-w 1024 \
--stride-h 1024 --stride-w 1024
python GeoSeg/tools/uavid_patch_split.py \
--input-dir "data/uavid/uavid_val" \
--output-img-dir "data/uavid/val/images" \
--output-mask-dir "data/uavid/val/masks" \
--mode 'val' --split-size-h 1024 --split-size-w 1024 \
--stride-h 1024 --stride-w 1024
LoveDA
python GeoSeg/tools/loveda_mask_convert.py --mask-dir data/LoveDA/Train/Rural/masks_png --output-mask-dir data/LoveDA/Train/Rural/masks_png_convert
python GeoSeg/tools/loveda_mask_convert.py --mask-dir data/LoveDA/Train/Urban/masks_png --output-mask-dir data/LoveDA/Train/Urban/masks_png_convert
python GeoSeg/tools/loveda_mask_convert.py --mask-dir data/LoveDA/Val/Rural/masks_png --output-mask-dir data/LoveDA/Val/Rural/masks_png_convert
python GeoSeg/tools/loveda_mask_convert.py --mask-dir data/LoveDA/Val/Urban/masks_png --output-mask-dir data/LoveDA/Val/Urban/masks_png_convert
"-c" means the path of the config, use different config to train different models.
python GeoSeg/train_supervision.py -c GeoSeg/config/uavid/unetformer.py
"-c" denotes the path of the config, Use different config to test different models.
"-o" denotes the output path
"-t" denotes the test time augmentation (TTA), can be [None, 'lr', 'd4'], default is None, 'lr' is flip TTA, 'd4' is multiscale TTA
"--rgb" denotes whether to output masks in RGB format
Vaihingen
python GeoSeg/vaihingen_test.py -c GeoSeg/config/vaihingen/dcswin.py -o fig_results/vaihingen/dcswin --rgb -t 'd4'
Potsdam
python GeoSeg/potsdam_test.py -c GeoSeg/config/potsdam/dcswin.py -o fig_results/potsdam/dcswin --rgb -t 'lr'
LoveDA (Online Testing)
python GeoSeg/loveda_test.py -c GeoSeg/config/loveda/dcswin.py -o fig_results/loveda/dcswin_test -t 'd4'
UAVid (Online Testing)
python GeoSeg/inference_uavid.py \
-i 'data/uavid/uavid_test' \
-c GeoSeg/config/uavid/unetformer.py \
-o fig_results/uavid/unetformer_r18 \
-t 'lr' -ph 1152 -pw 1024 -b 2 -d "uavid"
python GeoSeg/inference_huge_image.py \
-i data/vaihingen/test_images \
-c GeoSeg/config/vaihingen/dcswin.py \
-o fig_results/vaihingen/dcswin_huge \
-t 'lr' -ph 512 -pw 512 -b 2 -d "pv"
| Method | Dataset | F1 | OA | mIoU |
|---|---|---|---|---|
| UNetFormer | UAVid | - | - | 67.63 |
| UNetFormer | Vaihingen | 90.30 | 91.10 | 82.54 |
| UNetFormer | Potsdam | 92.64 | 91.19 | 86.52 |
| UNetFormer | LoveDA | - | - | 52.97 |
| FT-UNetFormer | Vaihingen | 91.17 | 91.74 | 83.98 |
| FT-UNetFormer | Potsdam | 93.22 | 91.87 | 87.50 |
Due to some random operations in the training stage, reproduced results (run once) are slightly different from the reported in paper.
If you find this project useful in your research, please consider citing:
We wish GeoSeg could serve the growing research of remote sensing by providing a unified benchmark and inspiring researchers to develop their own segmentation networks. Many thanks the following projects's contributions to GeoSeg.
8,328 followers · starred Nov 2024
6 followers · starred Mar 2024
UNetFormer: A UNet-like transformer for efficient semantic segmentation of remote sensing urban scene imagery, ISPRS. Also, including other vision transformers and CNNs for satellite, aerial image and UAV image segmentation.
Python
1,114
75 commits
updated Aug 19, 2024
GeoSeg is an open-source semantic segmentation toolbox based on PyTorch, pytorch lightning and timm, which mainly focuses on developing advanced Vision Transformers for remote sensing image segmentation.
Unified Benchmark
we provide a unified training script for various segmentation methods.
Simple and Effective
Thanks to pytorch lightning and timm , the code is easy for further development.
Supported Remote Sensing Datasets
Multi-scale Training and Testing
Inference on Huge Remote Sensing Images
Mamba
Vision Transformer
CNN
Prepare the following folders to organize this repo:
airs
├── GeoSeg (code)
├── pretrain_weights (pretrained weights of backbones, such as vit, swin, etc)
├── model_weights (save the model weights trained on ISPRS vaihingen, LoveDA, etc)
├── fig_results (save the masks predicted by models)
├── lightning_logs (CSV format training logs)
├── data
│   ├── LoveDA
│   │   ├── Train
│   │   │   ├── Urban
│   │   │   │   ├── images_png (original images)
│   │   │   │   ├── masks_png (original masks)
│   │   │   │   ├── masks_png_convert (converted masks used for training)
│   │   │   │   ├── masks_png_convert_rgb (original rgb format masks)
│   │   │   ├── Rural
│   │   │   │   ├── images_png
│   │   │   │   ├── masks_png
│   │   │   │   ├── masks_png_convert
│   │   │   │   ├── masks_png_convert_rgb
│   │   ├── Val (the same with Train)
│   │   ├── Test
│   │   ├── train_val (Merge Train and Val)
│   ├── uavid
│   │   ├── uavid_train (original)
│   │   ├── uavid_val (original)
│   │   ├── uavid_test (original)
│   │   ├── uavid_train_val (Merge uavid_train and uavid_val)
│   │   ├── train (processed)
│   │   ├── val (processed)
│   │   ├── train_val (processed)
│   ├── vaihingen
│   │   ├── train_images (original)
│   │   ├── train_masks (original)
│   │   ├── test_images (original)
│   │   ├── test_masks (original)
│   │   ├── test_masks_eroded (original)
│   │   ├── train (processed)
│   │   ├── test (processed)
│   ├── potsdam (the same with vaihingen)
Open the folder airs using Linux Terminal and create python environment:
conda create -n airs python=3.8
conda activate airs
pip3 install torch torchvision torchaudio --index-url https://download.pytorch.org/whl/cu118
pip install -r GeoSeg/requirements.txt
Install Mamba
pip install causal-conv1d>=1.4.0
pip install mamba-ssm
Baidu Disk : 1234
Download the datasets from the official website and split them yourself.
Vaihingen
Generate the training set.
python GeoSeg/tools/vaihingen_patch_split.py \
--img-dir "data/vaihingen/train_images" \
--mask-dir "data/vaihingen/train_masks" \
--output-img-dir "data/vaihingen/train/images_1024" \
--output-mask-dir "data/vaihingen/train/masks_1024" \
--mode "train" --split-size 1024 --stride 512
Generate the testing set.
python GeoSeg/tools/vaihingen_patch_split.py \
--img-dir "data/vaihingen/test_images" \
--mask-dir "data/vaihingen/test_masks_eroded" \
--output-img-dir "data/vaihingen/test/images_1024" \
--output-mask-dir "data/vaihingen/test/masks_1024" \
--mode "val" --split-size 1024 --stride 1024 \
--eroded
Generate the masks_1024_rgb (RGB format ground truth labels) for visualization.
python GeoSeg/tools/vaihingen_patch_split.py \
--img-dir "data/vaihingen/test_images" \
--mask-dir "data/vaihingen/test_masks" \
--output-img-dir "data/vaihingen/test/images_1024" \
--output-mask-dir "data/vaihingen/test/masks_1024_rgb" \
--mode "val" --split-size 1024 --stride 1024 \
--gt
As for the validation set, you can select some images from the training set to build it.
Potsdam
python GeoSeg/tools/potsdam_patch_split.py \
--img-dir "data/potsdam/train_images" \
--mask-dir "data/potsdam/train_masks" \
--output-img-dir "data/potsdam/train/images_1024" \
--output-mask-dir "data/potsdam/train/masks_1024" \
--mode "train" --split-size 1024 --stride 1024 --rgb-image
python GeoSeg/tools/potsdam_patch_split.py \
--img-dir "data/potsdam/test_images" \
--mask-dir "data/potsdam/test_masks_eroded" \
--output-img-dir "data/potsdam/test/images_1024" \
--output-mask-dir "data/potsdam/test/masks_1024" \
--mode "val" --split-size 1024 --stride 1024 \
--eroded --rgb-image
python GeoSeg/tools/potsdam_patch_split.py \
--img-dir "data/potsdam/test_images" \
--mask-dir "data/potsdam/test_masks" \
--output-img-dir "data/potsdam/test/images_1024" \
--output-mask-dir "data/potsdam/test/masks_1024_rgb" \
--mode "val" --split-size 1024 --stride 1024 \
--gt --rgb-image
UAVid
python GeoSeg/tools/uavid_patch_split.py \
--input-dir "data/uavid/uavid_train_val" \
--output-img-dir "data/uavid/train_val/images" \
--output-mask-dir "data/uavid/train_val/masks" \
--mode 'train' --split-size-h 1024 --split-size-w 1024 \
--stride-h 1024 --stride-w 1024
python GeoSeg/tools/uavid_patch_split.py \
--input-dir "data/uavid/uavid_train" \
--output-img-dir "data/uavid/train/images" \
--output-mask-dir "data/uavid/train/masks" \
--mode 'train' --split-size-h 1024 --split-size-w 1024 \
--stride-h 1024 --stride-w 1024
python GeoSeg/tools/uavid_patch_split.py \
--input-dir "data/uavid/uavid_val" \
--output-img-dir "data/uavid/val/images" \
--output-mask-dir "data/uavid/val/masks" \
--mode 'val' --split-size-h 1024 --split-size-w 1024 \
--stride-h 1024 --stride-w 1024
LoveDA
python GeoSeg/tools/loveda_mask_convert.py --mask-dir data/LoveDA/Train/Rural/masks_png --output-mask-dir data/LoveDA/Train/Rural/masks_png_convert
python GeoSeg/tools/loveda_mask_convert.py --mask-dir data/LoveDA/Train/Urban/masks_png --output-mask-dir data/LoveDA/Train/Urban/masks_png_convert
python GeoSeg/tools/loveda_mask_convert.py --mask-dir data/LoveDA/Val/Rural/masks_png --output-mask-dir data/LoveDA/Val/Rural/masks_png_convert
python GeoSeg/tools/loveda_mask_convert.py --mask-dir data/LoveDA/Val/Urban/masks_png --output-mask-dir data/LoveDA/Val/Urban/masks_png_convert
"-c" means the path of the config, use different config to train different models.
python GeoSeg/train_supervision.py -c GeoSeg/config/uavid/unetformer.py
"-c" denotes the path of the config, Use different config to test different models.
"-o" denotes the output path
"-t" denotes the test time augmentation (TTA), can be [None, 'lr', 'd4'], default is None, 'lr' is flip TTA, 'd4' is multiscale TTA
"--rgb" denotes whether to output masks in RGB format
Vaihingen
python GeoSeg/vaihingen_test.py -c GeoSeg/config/vaihingen/dcswin.py -o fig_results/vaihingen/dcswin --rgb -t 'd4'
Potsdam
python GeoSeg/potsdam_test.py -c GeoSeg/config/potsdam/dcswin.py -o fig_results/potsdam/dcswin --rgb -t 'lr'
LoveDA (Online Testing)
python GeoSeg/loveda_test.py -c GeoSeg/config/loveda/dcswin.py -o fig_results/loveda/dcswin_test -t 'd4'
UAVid (Online Testing)
python GeoSeg/inference_uavid.py \
-i 'data/uavid/uavid_test' \
-c GeoSeg/config/uavid/unetformer.py \
-o fig_results/uavid/unetformer_r18 \
-t 'lr' -ph 1152 -pw 1024 -b 2 -d "uavid"
python GeoSeg/inference_huge_image.py \
-i data/vaihingen/test_images \
-c GeoSeg/config/vaihingen/dcswin.py \
-o fig_results/vaihingen/dcswin_huge \
-t 'lr' -ph 512 -pw 512 -b 2 -d "pv"
| Method | Dataset | F1 | OA | mIoU |
|---|---|---|---|---|
| UNetFormer | UAVid | - | - | 67.63 |
| UNetFormer | Vaihingen | 90.30 | 91.10 | 82.54 |
| UNetFormer | Potsdam | 92.64 | 91.19 | 86.52 |
| UNetFormer | LoveDA | - | - | 52.97 |
| FT-UNetFormer | Vaihingen | 91.17 | 91.74 | 83.98 |
| FT-UNetFormer | Potsdam | 93.22 | 91.87 | 87.50 |
Due to some random operations in the training stage, reproduced results (run once) are slightly different from the reported in paper.
If you find this project useful in your research, please consider citing:
We wish GeoSeg could serve the growing research of remote sensing by providing a unified benchmark and inspiring researchers to develop their own segmentation networks. Many thanks the following projects's contributions to GeoSeg.
8,328 followers · starred Nov 2024
6 followers · starred Mar 2024



