
Prelude is a lightweight, high-performance LLM inference framework focused on accelerating prefill and optimizing end-to-end inference.
Rust
3
292 commits
updated Jun 21, 2026
README
Fast LLM inference engine in Rust.
Performance
GPU (H200, Qwen3-4B)
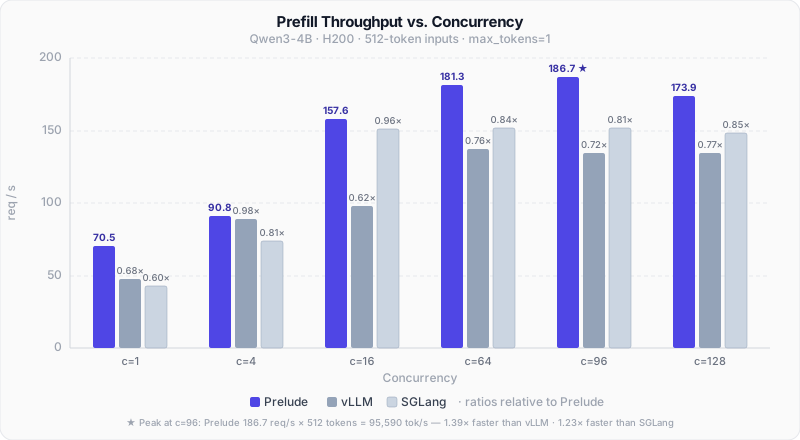
- Peak throughput: 186.7 req/s × 512 tokens = 95,590 tok/s — 1.39× vs vLLM, 1.23× vs SGLang (at c=96)
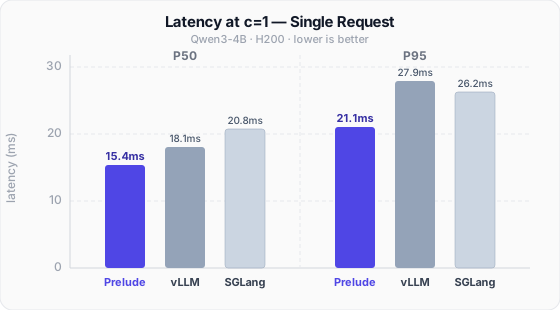
- Latency (c=1): P50 15.4ms · P95 21.1ms — vs vLLM 18.1ms/27.9ms, SGLang 20.8ms/26.2ms
512-token inputs, max_tokens=1, 200 requests per concurrency level, engines isolated on separate H200 GPUs.
Quick Start
Prerequisites
- Rust (stable, 1.85+)
- CUDA Toolkit (for GPU)
- CMake >= 3.18 (for oneDNN CPU backend)
Build
# GPU — full stack (FlashInfer + FA4 + DeepGEMM + CUTLASS + quant-gemm + cuLA)
cargo build -p prelude-server --release --features cuda

# CPU only (default — oneDNN BF16 GEMM + AVX-512 kernels)
cargo build -p prelude-server --release

# Both backends in one binary
cargo build -p prelude-server --release --features full
Run
# GPU
CUDA_VISIBLE_DEVICES=0 ./target/release/prelude-server \
  --model Qwen/Qwen3-4B --port 8000

# CPU
PRELUDE_DEVICE=cpu ./target/release/prelude-server \
  --model Qwen/Qwen3-0.6B --port 8000
Query
curl http://localhost:8000/v1/chat/completions \
  -H "Content-Type: application/json" \
  -d '{
    "model": "Qwen/Qwen3-4B",
    "messages": [{"role": "user", "content": "Hello!"}],
    "max_tokens": 64
  }'
Supported Models
| Name | Structure | Completion | Classify | Embed | GPU Backend |
|---|---|---|---|---|---|
| Qwen3 (0.6B–32B) | Dense | ✔ | ✔ | ✔ | FlashInfer / FA4 |
| Qwen3-MoE (30B-A3B) | MoE | ✔ | — | — | FlashInfer / FA4 |
| Qwen3-Next (80B-A3B) | Hybrid (DeltaNet + MoE) | ✔ | — | — | FlashInfer / FA4 |
| Qwen3.5 (0.8B–27B) | Hybrid (DeltaNet) | ✔ | — | — | FlashInfer / FA4 |
| Qwen3.5-MoE (35B-A3B) | Hybrid (DeltaNet + MoE) | ✔ | — | — | FlashInfer / FA4 |
| Gemma3 | Dense | ✔ | ✔ | ✔ | FlashInfer / FA4 |
| Gemma4 | Dense / MoE | ✔ | — | — | FlashInfer / FA4 |
| GGUF (Qwen3.5, Qwen3.5-MoE) | Quantized | ✔ | — | — | CUDA / CPU |
GGUF models are auto-detected from HuggingFace Hub or local .gguf files.
API
OpenAI-compatible endpoints:
| Endpoint | Description |
|---|---|
POST /v1/chat/completions | Chat completion |
POST /v1/completions | Text completion |
POST /v1/embeddings | Text embeddings |
POST /classify | Classification |
GET /v1/models | List models |
GET /health | Health check |
Supports logprobs, top_logprobs, prompt_logprobs, stop sequences, and stream mode. Compatible with OpenAI SDK, vLLM, and SGLang clients.
Architecture
Request -> Continuous Batching Scheduler -> GPU Queue -> GPU Worker -> Response
Attention: FA4 (prefill + decode) -> FlashInfer (fallback) -> CPU fallback. CUDA graph decode. One file per backend, zero #[cfg] in model code.
GEMM: DeepGEMM (SM90+ BF16) → CUTLASS (SM80+) → cuBLAS (universal fallback). oneDNN (CPU BF16).
Runtime: Paged KV cache, prefix caching, fused CUDA kernels (QKNorm+RoPE, SiLU*Mul, Add+RMSNorm), pure Rust AVX-512 CPU kernels.
License
Apache-2.0
Contributors


Similar repos


Languages
Rust
70.4%
Cuda
14.3%
Python
11.1%
C++
1.6%
Shell
1.6%
Prelude is a lightweight, high-performance LLM inference framework focused on accelerating prefill and optimizing end-to-end inference.
Rust
3
292 commits
updated Jun 21, 2026
README
Fast LLM inference engine in Rust.
Performance
GPU (H200, Qwen3-4B)
- Peak throughput: 186.7 req/s × 512 tokens = 95,590 tok/s — 1.39× vs vLLM, 1.23× vs SGLang (at c=96)
- Latency (c=1): P50 15.4ms · P95 21.1ms — vs vLLM 18.1ms/27.9ms, SGLang 20.8ms/26.2ms
512-token inputs, max_tokens=1, 200 requests per concurrency level, engines isolated on separate H200 GPUs.
Quick Start
Prerequisites
- Rust (stable, 1.85+)
- CUDA Toolkit (for GPU)
- CMake >= 3.18 (for oneDNN CPU backend)
Build
# GPU — full stack (FlashInfer + FA4 + DeepGEMM + CUTLASS + quant-gemm + cuLA)
cargo build -p prelude-server --release --features cuda

# CPU only (default — oneDNN BF16 GEMM + AVX-512 kernels)
cargo build -p prelude-server --release

# Both backends in one binary
cargo build -p prelude-server --release --features full
Run
# GPU
CUDA_VISIBLE_DEVICES=0 ./target/release/prelude-server \
  --model Qwen/Qwen3-4B --port 8000

# CPU
PRELUDE_DEVICE=cpu ./target/release/prelude-server \
  --model Qwen/Qwen3-0.6B --port 8000
Query
curl http://localhost:8000/v1/chat/completions \
  -H "Content-Type: application/json" \
  -d '{
    "model": "Qwen/Qwen3-4B",
    "messages": [{"role": "user", "content": "Hello!"}],
    "max_tokens": 64
  }'
Supported Models
| Name | Structure | Completion | Classify | Embed | GPU Backend |
|---|---|---|---|---|---|
| Qwen3 (0.6B–32B) | Dense | ✔ | ✔ | ✔ | FlashInfer / FA4 |
| Qwen3-MoE (30B-A3B) | MoE | ✔ | — | — | FlashInfer / FA4 |
| Qwen3-Next (80B-A3B) | Hybrid (DeltaNet + MoE) | ✔ | — | — | FlashInfer / FA4 |
| Qwen3.5 (0.8B–27B) | Hybrid (DeltaNet) | ✔ | — | — | FlashInfer / FA4 |
| Qwen3.5-MoE (35B-A3B) | Hybrid (DeltaNet + MoE) | ✔ | — | — | FlashInfer / FA4 |
| Gemma3 | Dense | ✔ | ✔ | ✔ | FlashInfer / FA4 |
| Gemma4 | Dense / MoE | ✔ | — | — | FlashInfer / FA4 |
| GGUF (Qwen3.5, Qwen3.5-MoE) | Quantized | ✔ | — | — | CUDA / CPU |
GGUF models are auto-detected from HuggingFace Hub or local .gguf files.
API
OpenAI-compatible endpoints:
| Endpoint | Description |
|---|---|
POST /v1/chat/completions | Chat completion |
POST /v1/completions | Text completion |
POST /v1/embeddings | Text embeddings |
POST /classify | Classification |
GET /v1/models | List models |
GET /health | Health check |
Supports logprobs, top_logprobs, prompt_logprobs, stop sequences, and stream mode. Compatible with OpenAI SDK, vLLM, and SGLang clients.
Architecture
Request -> Continuous Batching Scheduler -> GPU Queue -> GPU Worker -> Response
Attention: FA4 (prefill + decode) -> FlashInfer (fallback) -> CPU fallback. CUDA graph decode. One file per backend, zero #[cfg] in model code.
GEMM: DeepGEMM (SM90+ BF16) → CUTLASS (SM80+) → cuBLAS (universal fallback). oneDNN (CPU BF16).
Runtime: Paged KV cache, prefix caching, fused CUDA kernels (QKNorm+RoPE, SiLU*Mul, Add+RMSNorm), pure Rust AVX-512 CPU kernels.
License
Apache-2.0
Similar repos
Contributors
Languages
Rust
70.4%
Cuda
14.3%
Python
11.1%
C++
1.6%
Shell
1.6%