NeurIPS 2025 D&B | RAG-IGBench: benchmark for RAG-based interleaved image-text generation.
See the code
Official benchmark repository for "RAG-IGBench: Innovative Evaluation for RAG-based Interleaved Generation in Open-domain Question Answering".
RAG-IGBench evaluates RAG-based Interleaved Generation (RAG-IG), where multimodal models generate image-text interleaved answers for open-domain questions using retrieved documents and images. The repository releases the benchmark data, generation scripts, and evaluation code.
Rongyang Zhang, Yuqing Huang, Chengqiang Lu, Qimeng Wang, Yan Gao, Yi Wu, Yao Hu, Yin Xu, Wei Wang, Hao Wang, and Enhong Chen. RAG-IGBench: Innovative Evaluation for RAG-based Interleaved Generation in Open-domain Question Answering. NeurIPS 2025 Datasets and Benchmarks Track Poster, 2025.
Paper / PDF / Dataset / Project Page / Code / Citation
The paper introduces a benchmark for evaluating multimodal RAG systems that produce coherent image-text interleaved answers. It includes data from social platforms, generation scripts for common MLLMs, and metrics covering text quality, image quality, and image-text consistency.
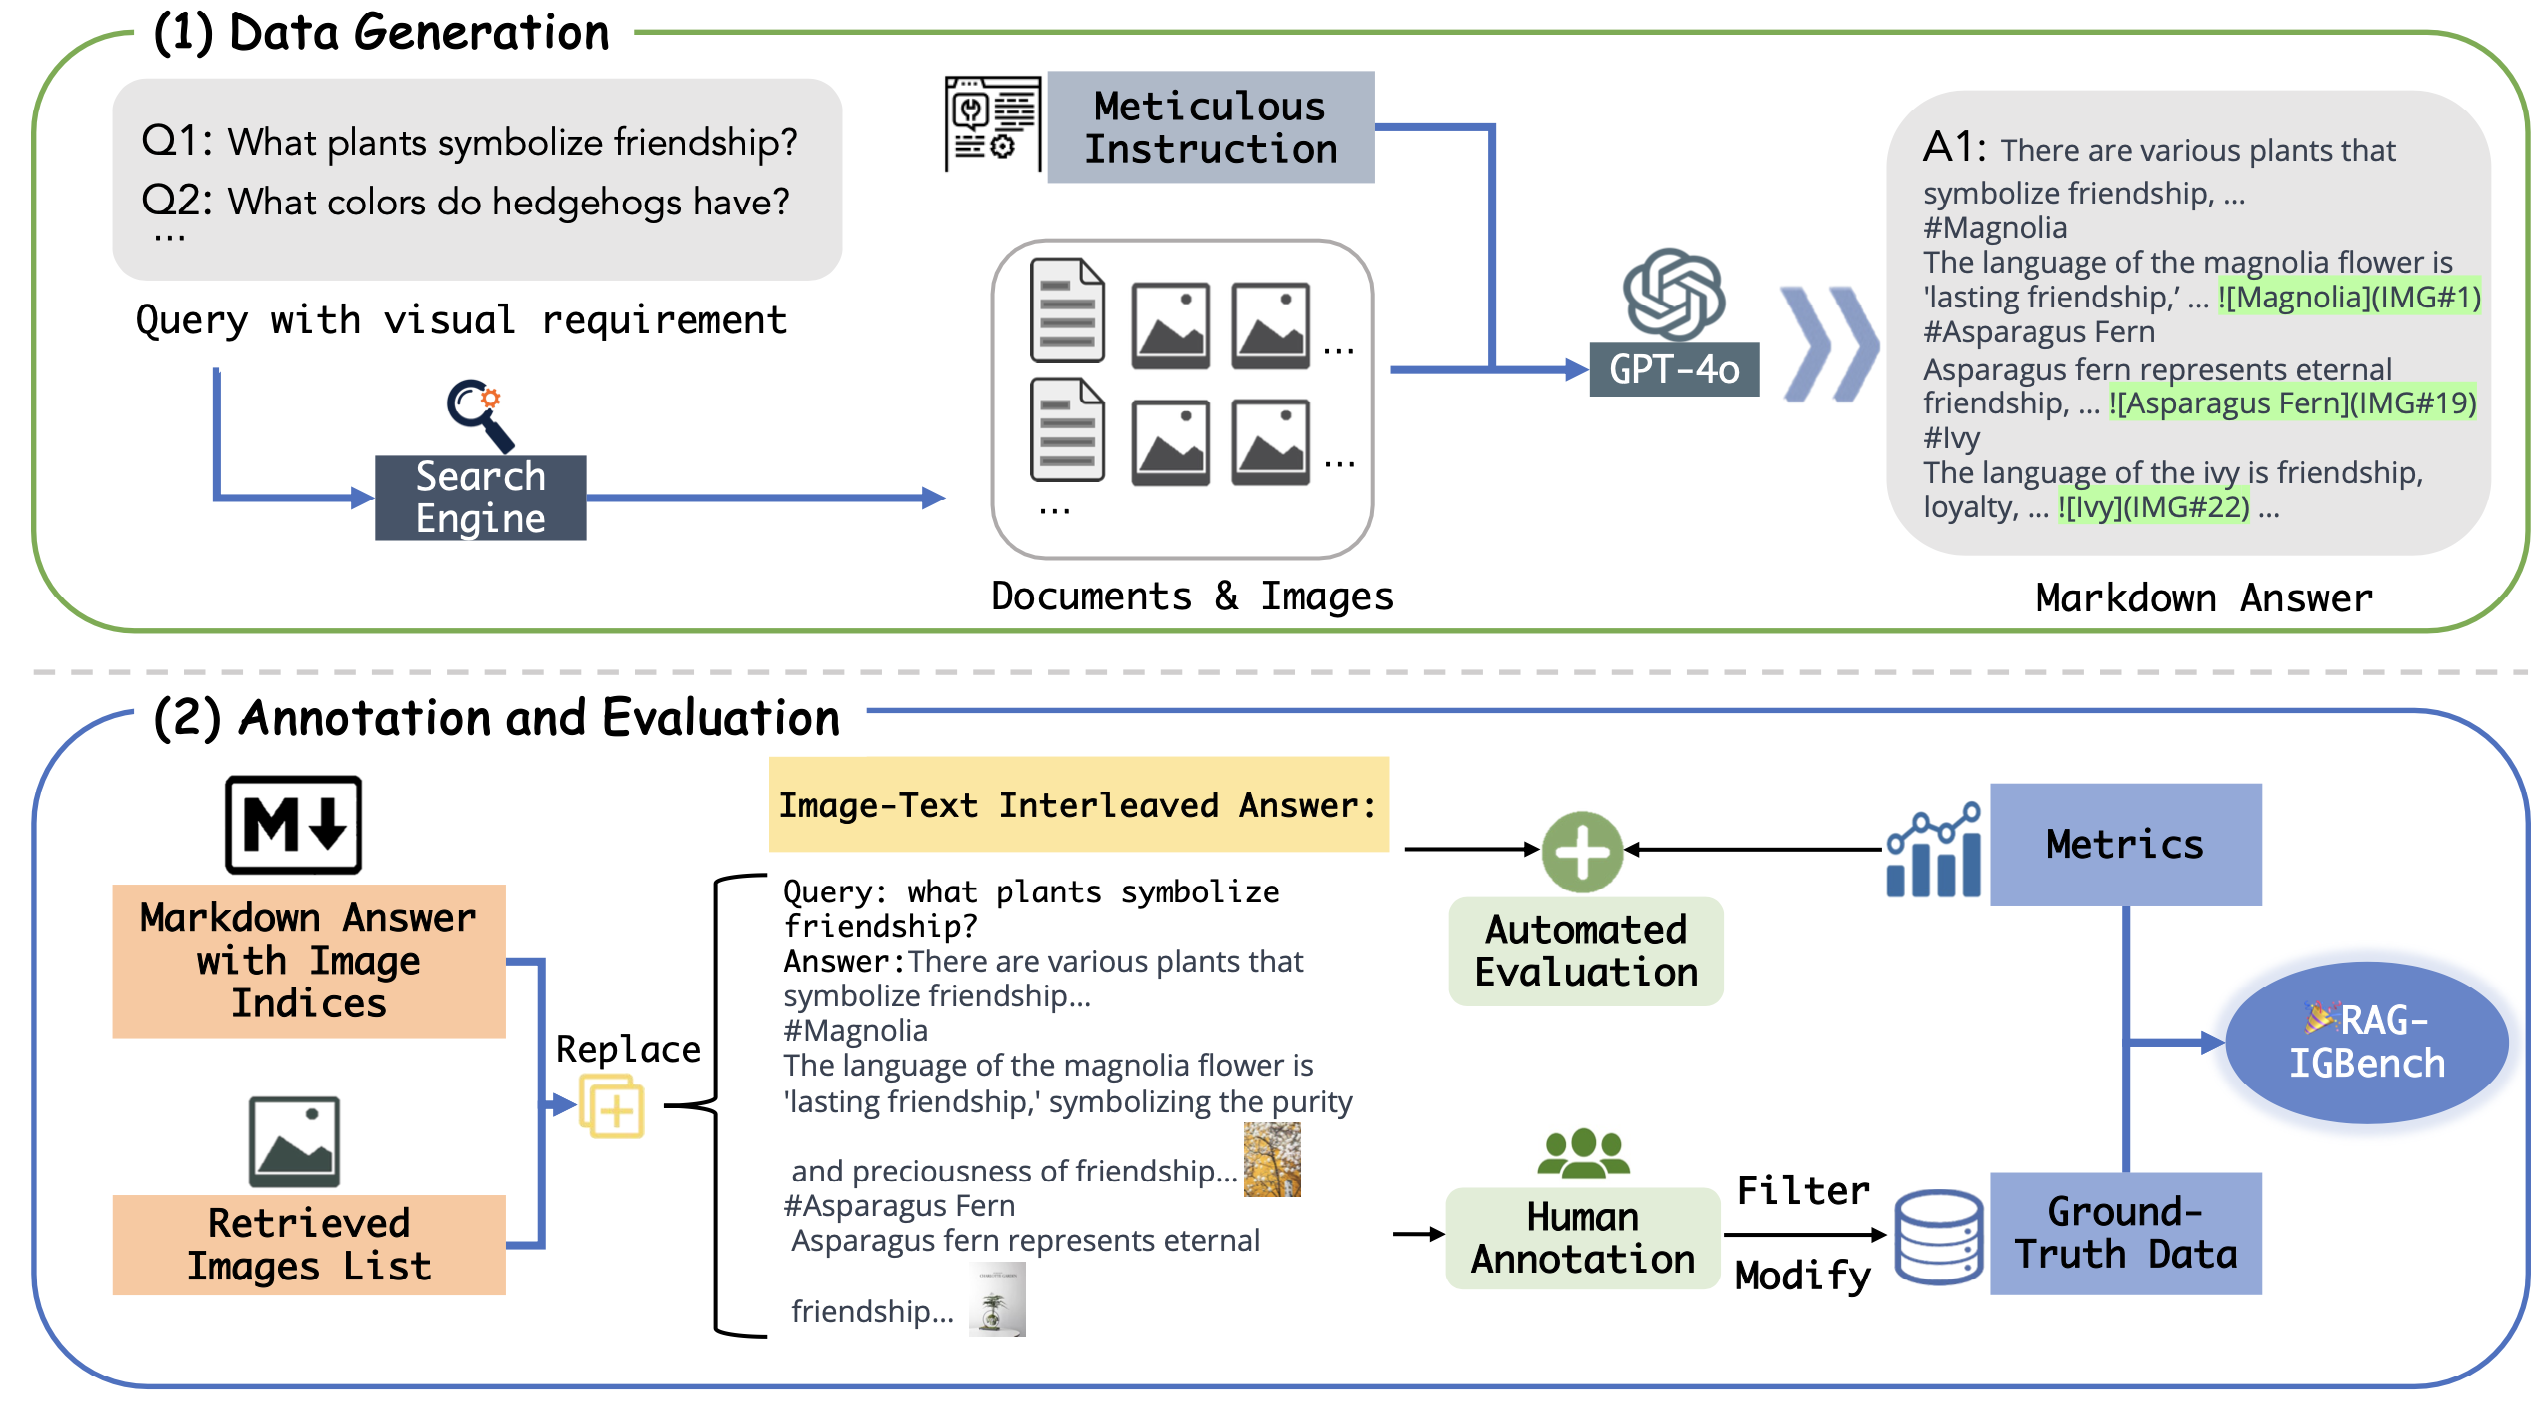
RAG-IG retrieves documents and images, feeds multimodal evidence to an MLLM, asks the model to generate markdown with image indices, and replaces those indices with retrieved images to form the final interleaved answer.
.
|-- assets/                 # Original README figures
|-- model_generation/       # Model-specific answer generation scripts
|-- score/                  # Evaluation metrics and aggregation
|-- RAG_IG_CH.jsonl         # Chinese benchmark split
|-- RAG_IG_EN.json          # English benchmark split
|-- download_images.py      # Optional image downloading/checking helper
|-- RAG_IGBench.pdf         # Paper PDF snapshot
`-- docs/                   # Project page and README assets
Install the dependencies required by the selected model generation scripts and scoring pipeline. Some generation scripts require API keys or local model checkpoints.
The benchmark is hosted on HuggingFace and provided in two versions:
RAG_IG_CH.jsonlRAG_IG_EN.jsonEach sample contains an id, query, retrieved documents, retrieved images, cleaned ground-truth interleaved answer, category labels, and split.
If you need local images, run:
python download_images.py
The expected image layout is:
INPUT_DIR/
|-- data.json
`-- images/
    |-- 1/
    |   |-- 1/
    |   `-- 2/
    `-- ...
Generate model answers with a script under model_generation/, after setting the model path, API key, and dataset path required by that model. The output JSONL should store each model response under the key model_answer.
Score generated answers:
python score/eval.py
Aggregate final scores:
python score/scores.py
The evaluation covers three dimensions:
The details and metric definitions are described in the paper.
For score/eval.py, configure:
output_dir = ''
input_file = ''
clip_model_path = ''
embedding_model_path = ''
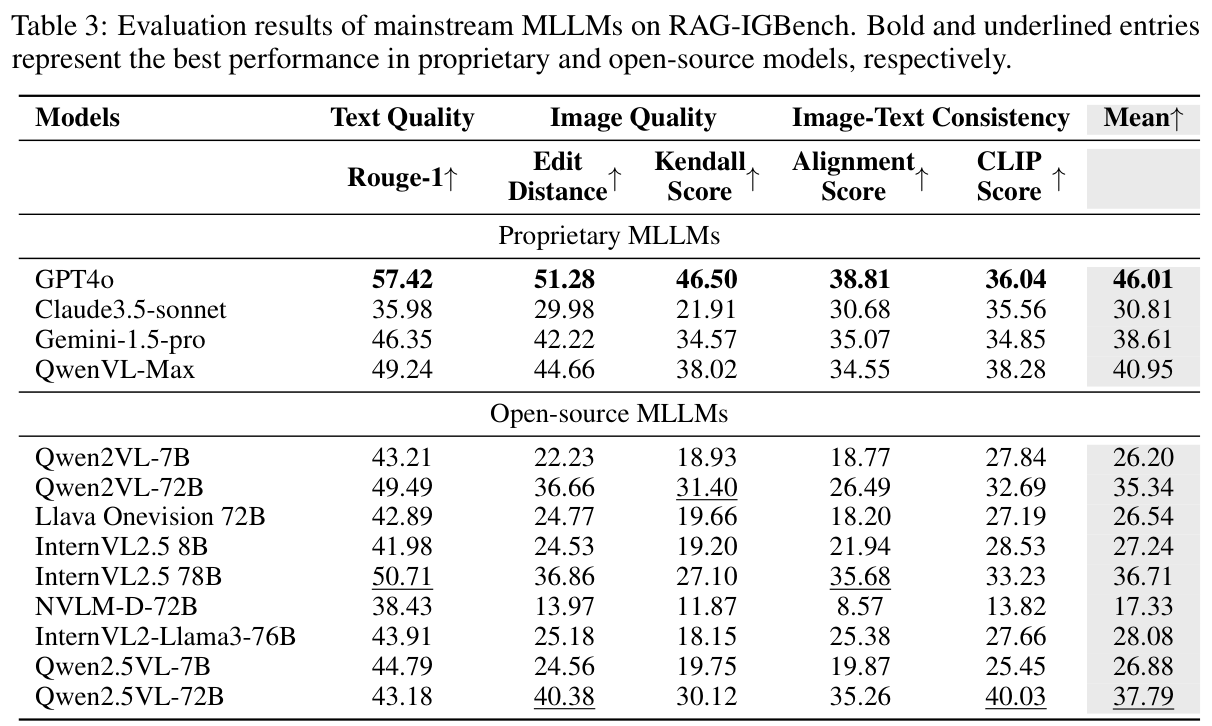
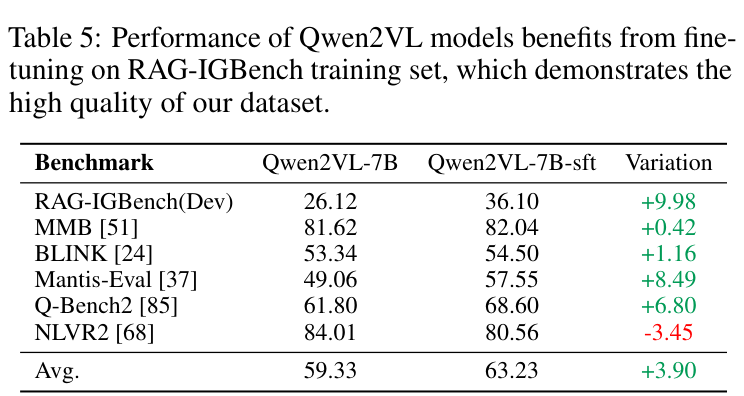
The first table reports benchmark scores for proprietary and open-source MLLMs; the second shows how fine-tuning on RAG-IGBench transfers to related multimodal benchmarks.
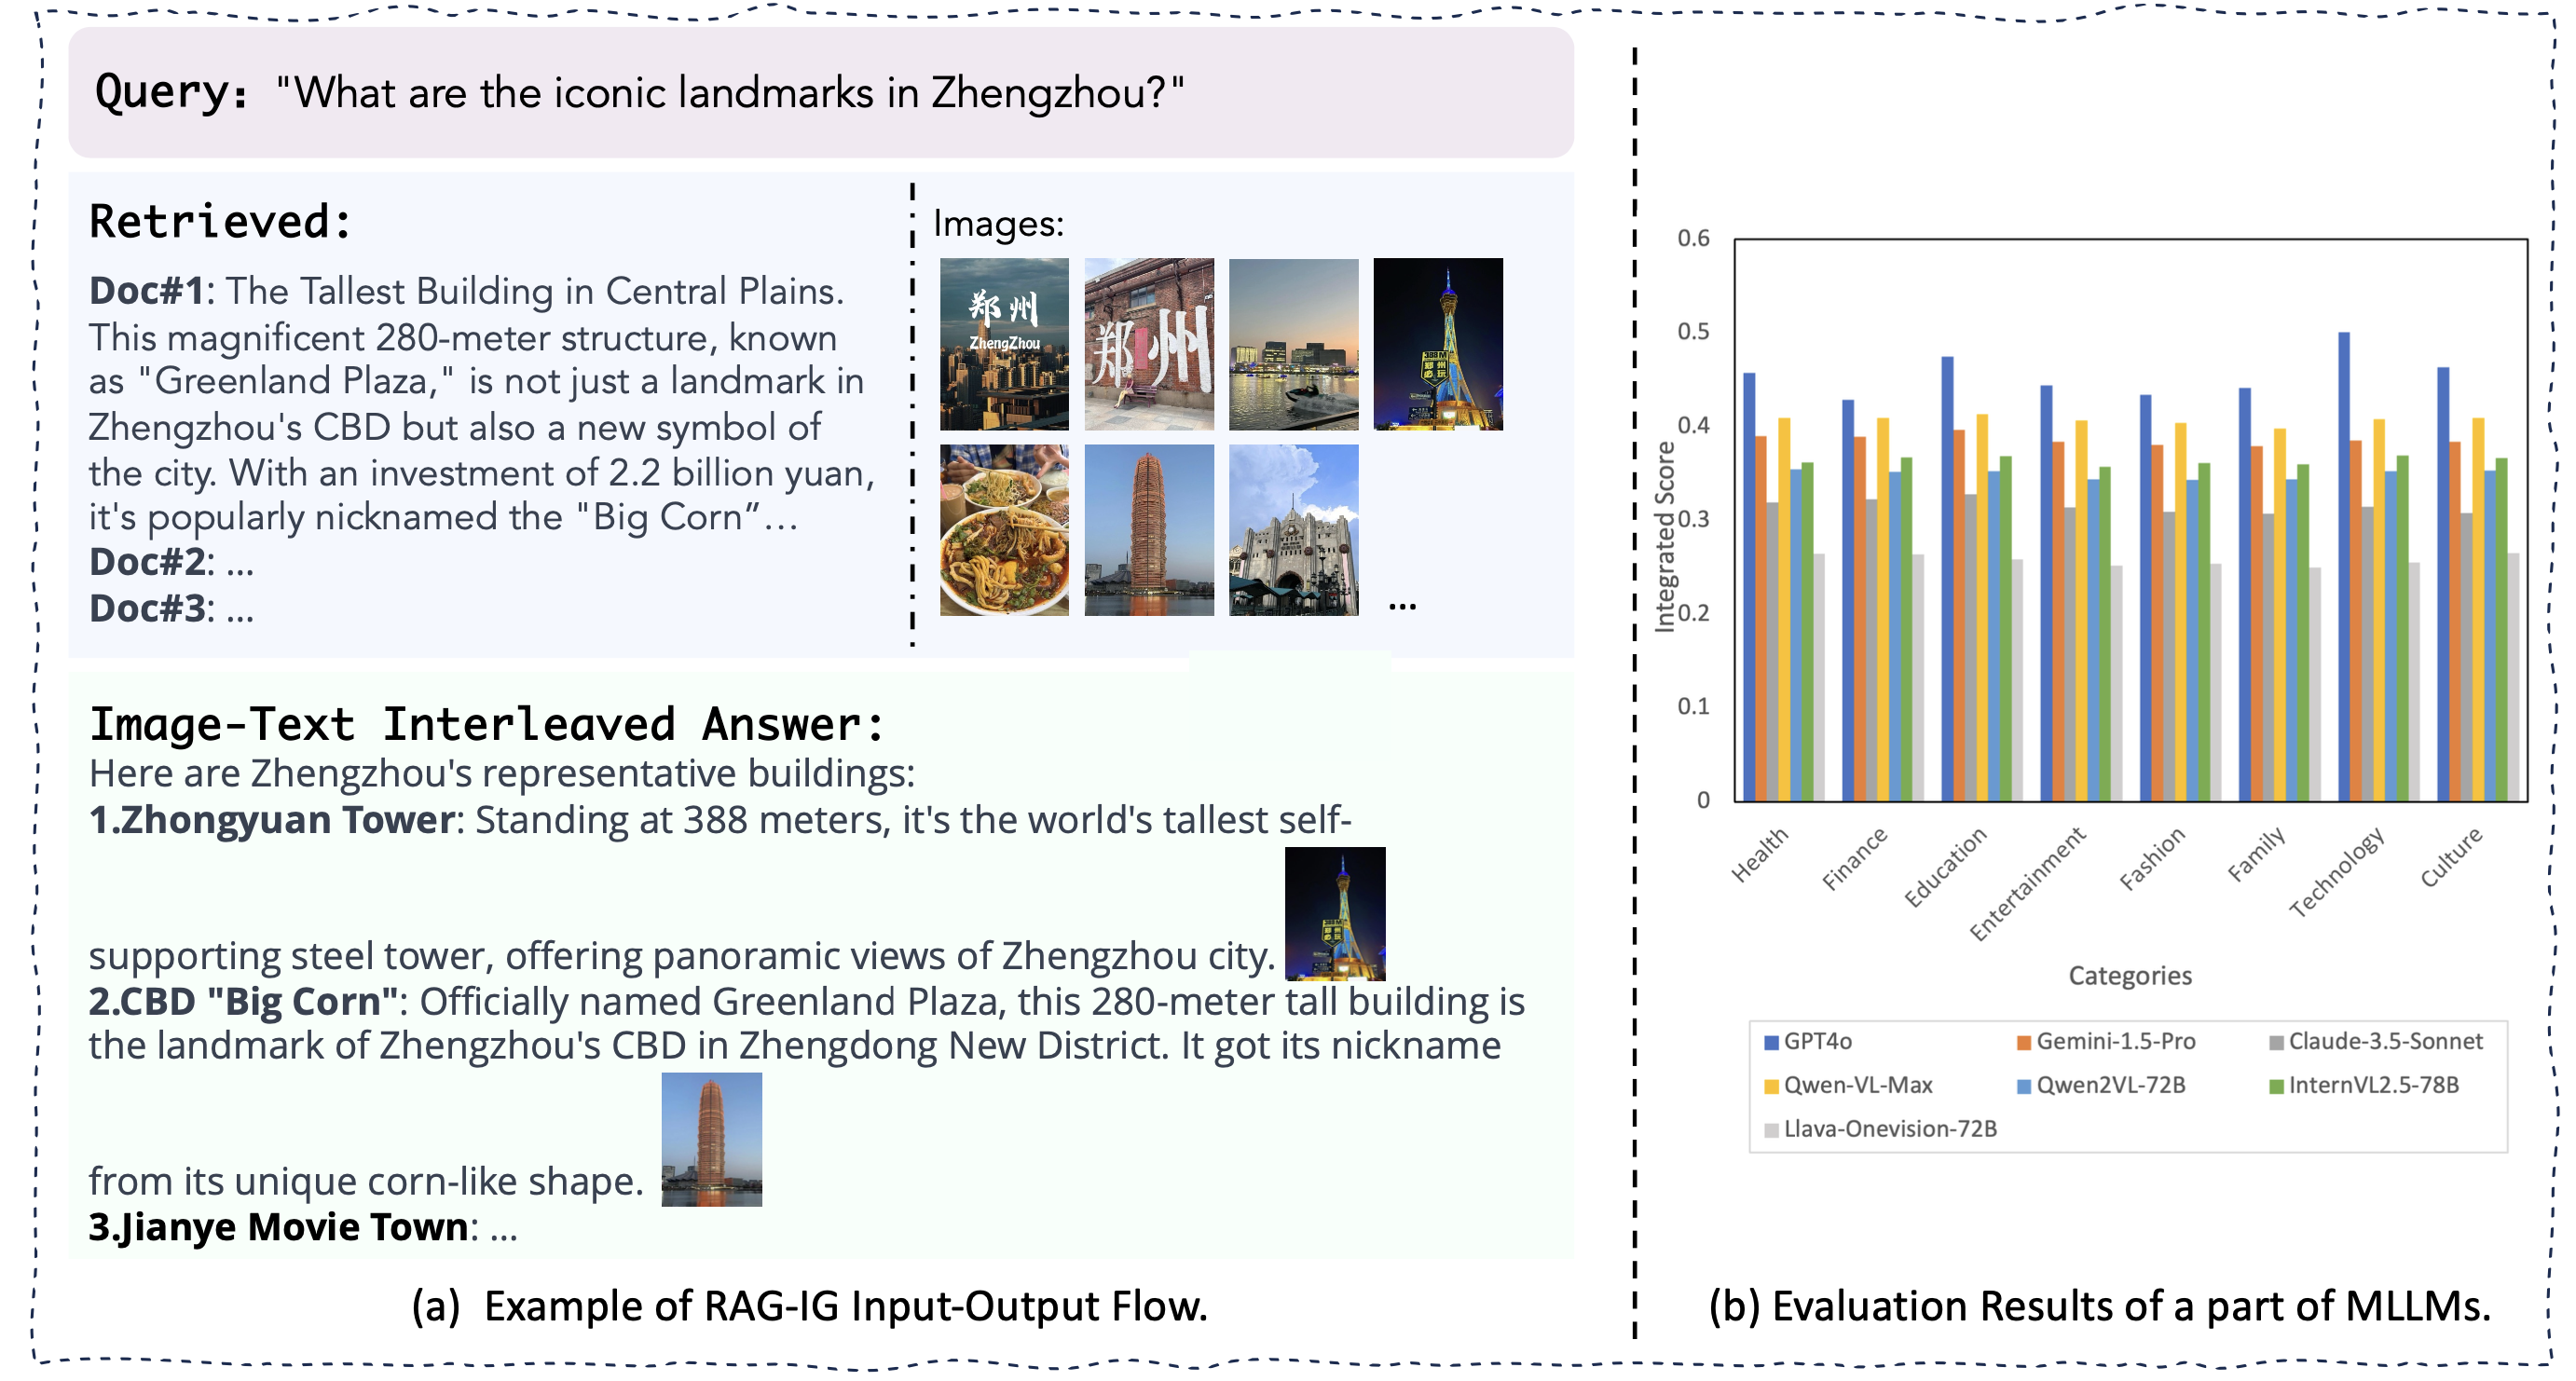
The benchmark exposes whether MLLMs can use retrieved multimodal evidence to generate answers that are textually useful, visually grounded, and coherent as image-text interleaved outputs.
| Model family | Mean score | Readout |
|---|---|---|
| GPT-4o | 46.01 | Best overall among the reported proprietary models. |
| QwenVL-Max | 40.95 | Strong proprietary baseline, behind GPT-4o. |
| Gemini-1.5-pro | 38.61 | Competitive but lower on the aggregate metric. |
| Qwen2.5VL-72B | 37.79 | Strongest reported open-source score in the table excerpt. |
| Qwen2VL-7B | 26.20 | Shows the large gap between small open models and frontier proprietary models. |
Fine-tuning Qwen2VL-7B on the RAG-IGBench training set improves the development score from 26.12 to 36.10 (+9.98), while also improving Mantis-Eval by +8.49 and Q-Bench2 by +6.80.
Conclusion: RAG-IGBench is not only an evaluation set; its training split can improve multimodal RAG behavior while revealing a persistent proprietary/open-source gap.
docs/assets/.@misc{zhang2025ragigbench,
title = {RAG-IGBench: Innovative Evaluation for RAG-based Interleaved Generation in Open-domain Question Answering},
author = {Zhang, Rongyang and Huang, Yuqing and Lu, Chengqiang and Wang, Qimeng and Gao, Yan and Wu, Yi and Hu, Yao and Xu, Yin and Wang, Wei and Wang, Hao and Chen, Enhong},
year = {2025},
eprint = {2512.05119},
archivePrefix = {arXiv},
primaryClass = {cs.IR},
url = {https://arxiv.org/abs/2512.05119}
}
Code is released under Apache 2.0. Data is released for research use under CC BY-NC 4.0.
For paper questions, please contact:
[email protected]) and Enhong Chen ([email protected])For repository issues, please open a GitHub issue in this repository.
NeurIPS 2025 D&B | RAG-IGBench: benchmark for RAG-based interleaved image-text generation.
See the code
Official benchmark repository for "RAG-IGBench: Innovative Evaluation for RAG-based Interleaved Generation in Open-domain Question Answering".
RAG-IGBench evaluates RAG-based Interleaved Generation (RAG-IG), where multimodal models generate image-text interleaved answers for open-domain questions using retrieved documents and images. The repository releases the benchmark data, generation scripts, and evaluation code.
Rongyang Zhang, Yuqing Huang, Chengqiang Lu, Qimeng Wang, Yan Gao, Yi Wu, Yao Hu, Yin Xu, Wei Wang, Hao Wang, and Enhong Chen. RAG-IGBench: Innovative Evaluation for RAG-based Interleaved Generation in Open-domain Question Answering. NeurIPS 2025 Datasets and Benchmarks Track Poster, 2025.
Paper / PDF / Dataset / Project Page / Code / Citation
The paper introduces a benchmark for evaluating multimodal RAG systems that produce coherent image-text interleaved answers. It includes data from social platforms, generation scripts for common MLLMs, and metrics covering text quality, image quality, and image-text consistency.
RAG-IG retrieves documents and images, feeds multimodal evidence to an MLLM, asks the model to generate markdown with image indices, and replaces those indices with retrieved images to form the final interleaved answer.
.
|-- assets/                 # Original README figures
|-- model_generation/       # Model-specific answer generation scripts
|-- score/                  # Evaluation metrics and aggregation
|-- RAG_IG_CH.jsonl         # Chinese benchmark split
|-- RAG_IG_EN.json          # English benchmark split
|-- download_images.py      # Optional image downloading/checking helper
|-- RAG_IGBench.pdf         # Paper PDF snapshot
`-- docs/                   # Project page and README assets
Install the dependencies required by the selected model generation scripts and scoring pipeline. Some generation scripts require API keys or local model checkpoints.
The benchmark is hosted on HuggingFace and provided in two versions:
RAG_IG_CH.jsonlRAG_IG_EN.jsonEach sample contains an id, query, retrieved documents, retrieved images, cleaned ground-truth interleaved answer, category labels, and split.
If you need local images, run:
python download_images.py
The expected image layout is:
INPUT_DIR/
|-- data.json
`-- images/
    |-- 1/
    |   |-- 1/
    |   `-- 2/
    `-- ...
Generate model answers with a script under model_generation/, after setting the model path, API key, and dataset path required by that model. The output JSONL should store each model response under the key model_answer.
Score generated answers:
python score/eval.py
Aggregate final scores:
python score/scores.py
The evaluation covers three dimensions:
The details and metric definitions are described in the paper.
For score/eval.py, configure:
output_dir = ''
input_file = ''
clip_model_path = ''
embedding_model_path = ''
The first table reports benchmark scores for proprietary and open-source MLLMs; the second shows how fine-tuning on RAG-IGBench transfers to related multimodal benchmarks.
The benchmark exposes whether MLLMs can use retrieved multimodal evidence to generate answers that are textually useful, visually grounded, and coherent as image-text interleaved outputs.
| Model family | Mean score | Readout |
|---|---|---|
| GPT-4o | 46.01 | Best overall among the reported proprietary models. |
| QwenVL-Max | 40.95 | Strong proprietary baseline, behind GPT-4o. |
| Gemini-1.5-pro | 38.61 | Competitive but lower on the aggregate metric. |
| Qwen2.5VL-72B | 37.79 | Strongest reported open-source score in the table excerpt. |
| Qwen2VL-7B | 26.20 | Shows the large gap between small open models and frontier proprietary models. |
Fine-tuning Qwen2VL-7B on the RAG-IGBench training set improves the development score from 26.12 to 36.10 (+9.98), while also improving Mantis-Eval by +8.49 and Q-Bench2 by +6.80.
Conclusion: RAG-IGBench is not only an evaluation set; its training split can improve multimodal RAG behavior while revealing a persistent proprietary/open-source gap.
docs/assets/.@misc{zhang2025ragigbench,
title = {RAG-IGBench: Innovative Evaluation for RAG-based Interleaved Generation in Open-domain Question Answering},
author = {Zhang, Rongyang and Huang, Yuqing and Lu, Chengqiang and Wang, Qimeng and Gao, Yan and Wu, Yi and Hu, Yao and Xu, Yin and Wang, Wei and Wang, Hao and Chen, Enhong},
year = {2025},
eprint = {2512.05119},
archivePrefix = {arXiv},
primaryClass = {cs.IR},
url = {https://arxiv.org/abs/2512.05119}
}
Code is released under Apache 2.0. Data is released for research use under CC BY-NC 4.0.
For paper questions, please contact:
[email protected]) and Enhong Chen ([email protected])For repository issues, please open a GitHub issue in this repository.