
An LLM Based Diagnosis System (https://arxiv.org/pdf/2312.01454.pdf)
See the codeREADME
 LLM As Database Administrator


Demo • QuickStart • Alerts And Anomalies • Knowledge And Tools • Dockers • FAQ • Community • Citation • Contributors • OpenAI, Azure aggregated API discounted access plan.
👫 Join Us on WeChat! 🏆 Top 100 Open Project! 🌟 VLDB 2024!
【English | 中文】
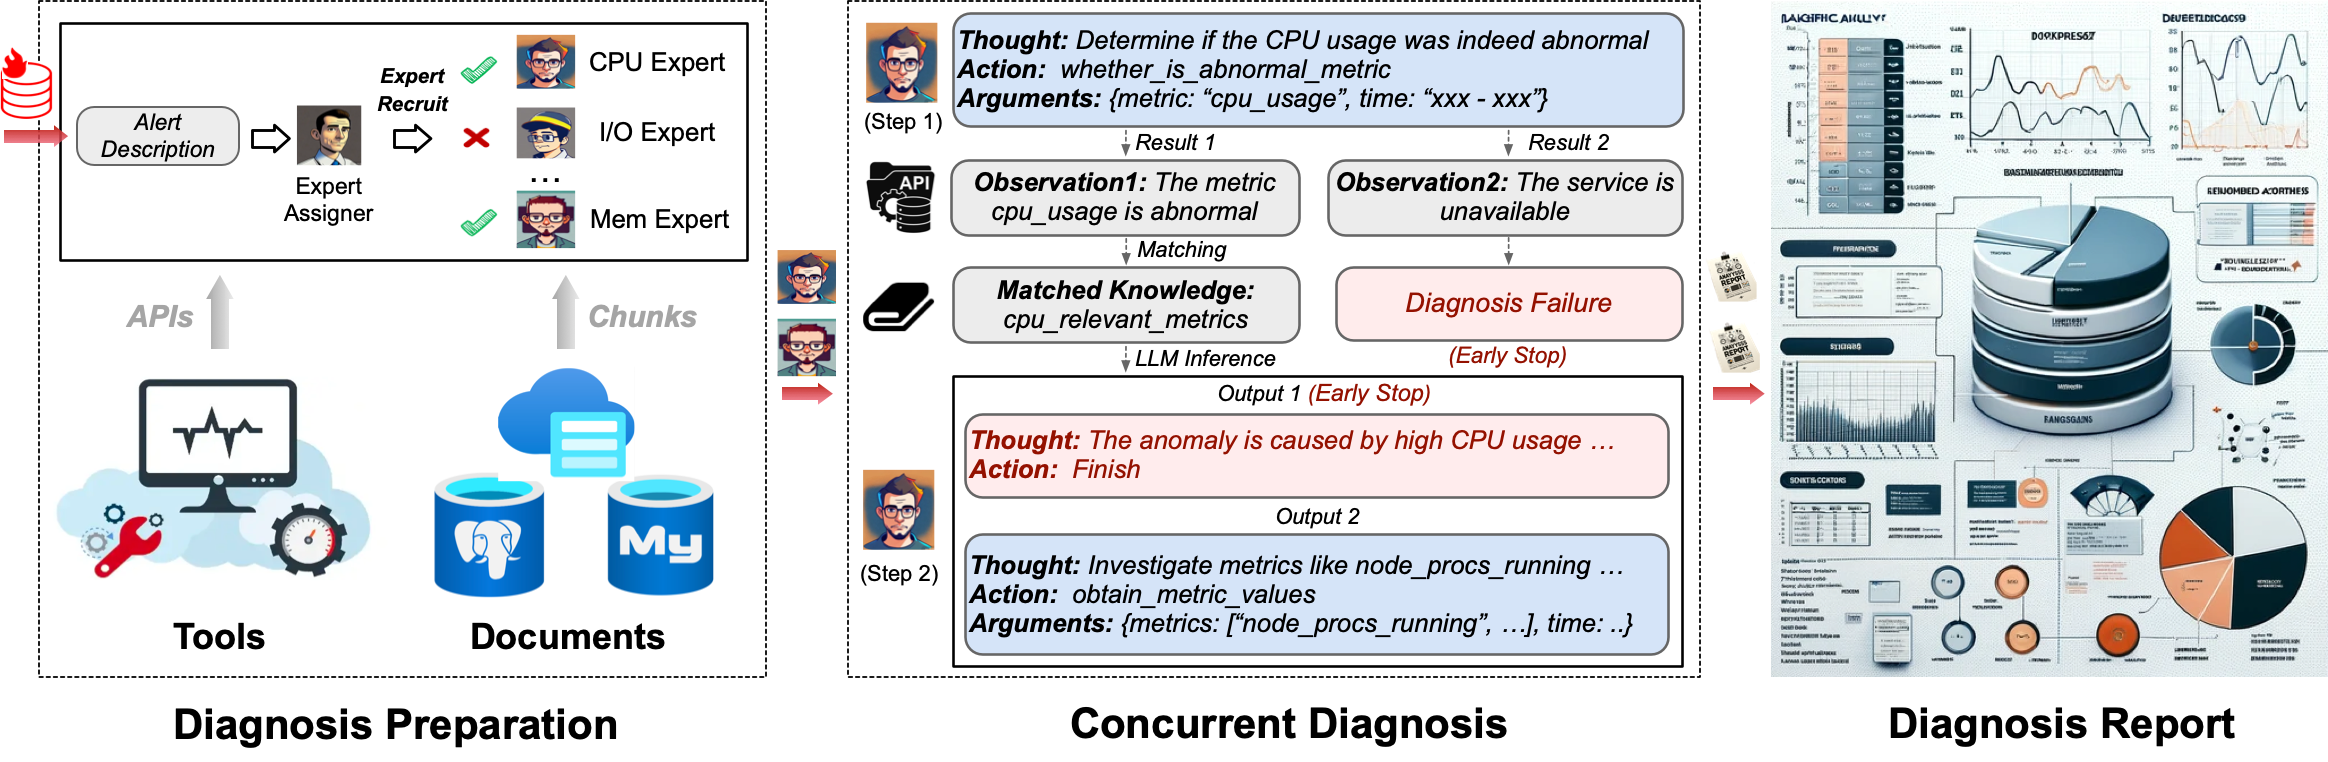
🦾 Build your personal database administrator (D-Bot)🧑💻, which is good at solving database problems by reading documents, using various tools, writing analysis reports! Undergoing An Upgrade!
🗺 Online Demo
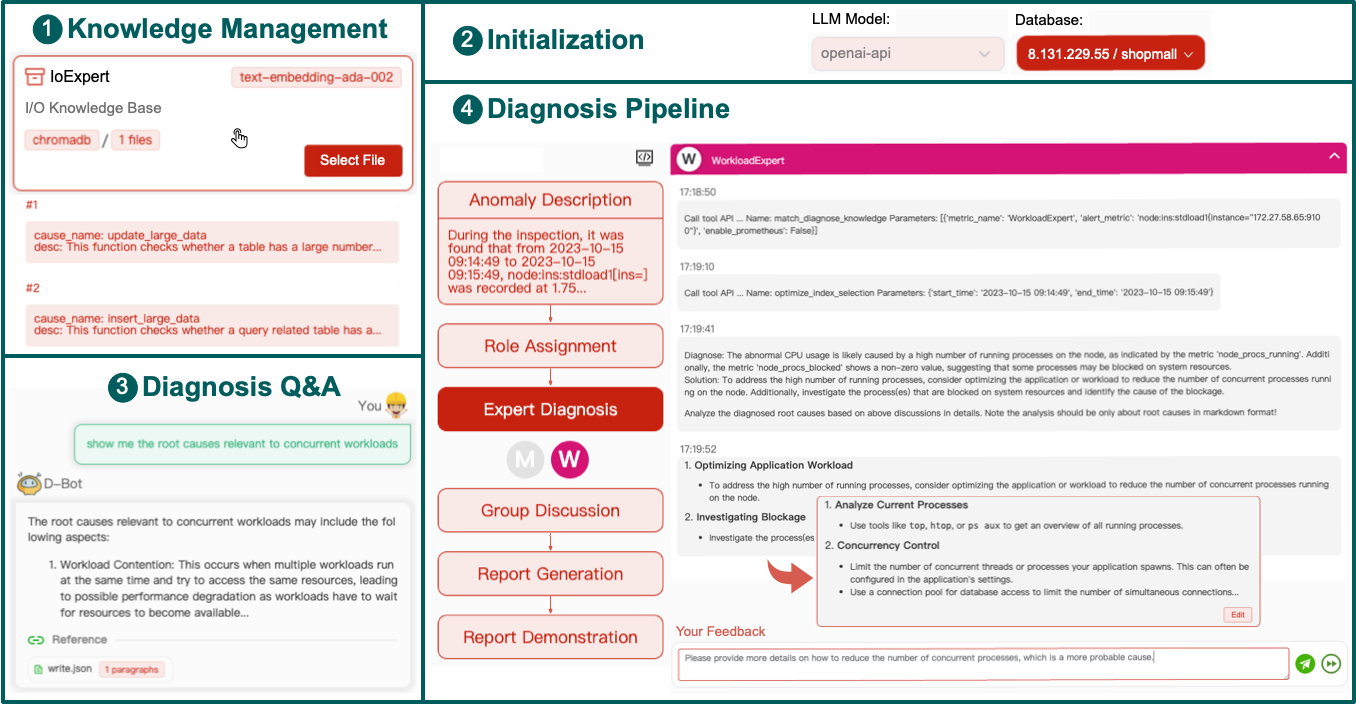
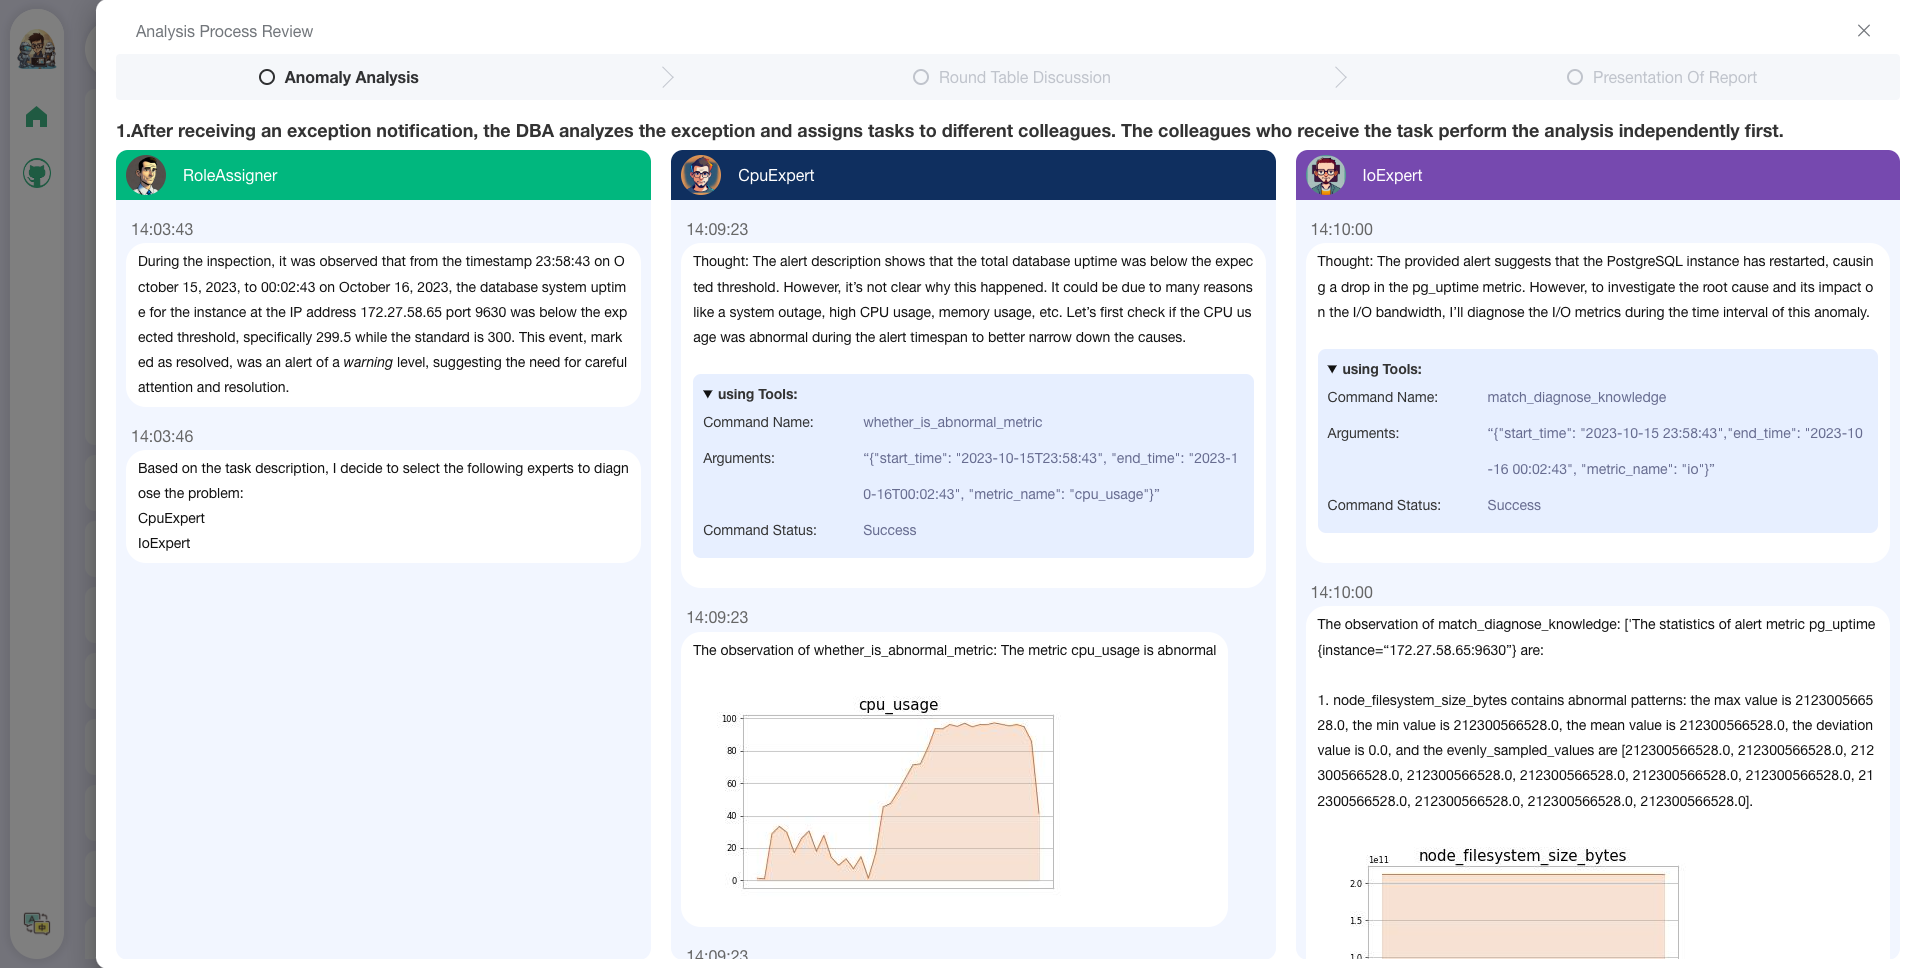
- After launching the local service (adopting frontend and configs from Chatchat), you can easily import documents into the knowledge base, utilize the knowledge base for well-founded Q&A and diagnosis analysis of abnormal alarms.
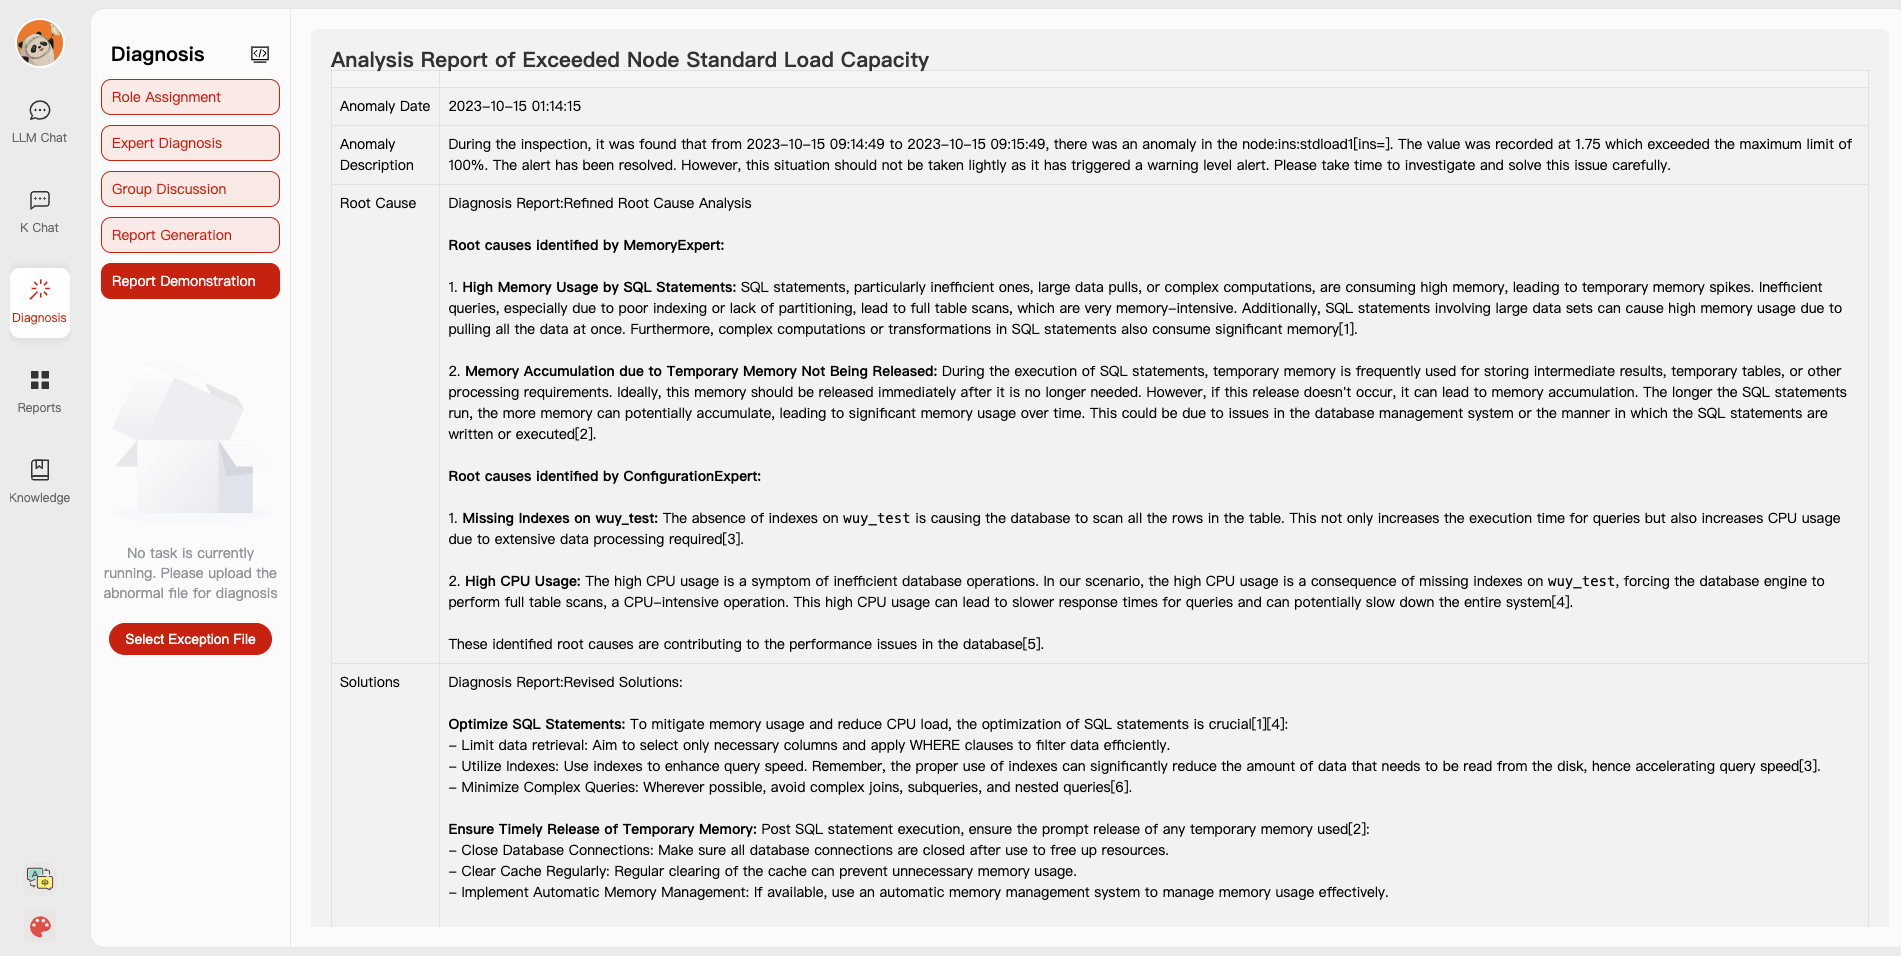
- With the user feedback function 🔗, you can (1) send feedbacks to make D-Bot follow and refine the intermediate diagnosis results, and (2) edit the diagnosis result by clicking the “Edit” button. D-Bot can accumulate refinement patterns from the user feedbacks (stored in vector database) and adaptively align to user's diagnosis preference.
- On the online website (http://dbgpt.dbmind.cn), you can browse all historical diagnosis results, used metrics, and detailed diagnosis processes.
Old Version 1: [Gradio for Diag Game] (no langchain)
Old Version 2: [Vue for Report Replay] (no langchain)
📰 Updates
-
Docker for a quick and safe use of D-Bot
-
Metric Monitoring (prometheus), Database (postgres_db), Alert (alertmanager) and Alert Recording (python_app).
-
D-bot (still too large, with over 12GB)
-
-
Human Feedback 🔥🔥🔥
-
Test-based Diagnosis Refinement with User Feedbacks
-
Refinement Patterns Extraction & Management
-
-
Language Support (english / chinese)
- english : default
- chinese : add "language: zh" in config.yaml
-
New Frontend
- Knowledgebase + Chat Q&A + Diagnosis + Report Replay
-
Result Report with reference
-
Extreme Speed Version for localized llms
-
4-bit quantized LLM (reducing inference time by 1/3)
-
vllm for fast inference (qwen)
-
Tiny LLM
-
-
Multi-path extraction of document knowledge
-
Vector database (ChromaDB)
-
RESTful Search Engine (Elasticsearch)
-
-
Expert prompt generation using document knowledge
-
Upgrade the LLM-based diagnosis mechanism:
-
Task Dispatching -> Concurrent Diagnosis -> Cross Review -> Report Generation
-
Synchronous Concurrency Mechanism during LLM inference
-
-
Support monitoring and optimization tools in multiple levels 🔗 link
- Monitoring metrics (Prometheus)
- Flame graph in code level
- Diagnosis knowledge retrieval (dbmind)
- Logical query transformations (Calcite)
- Index optimization algorithms (for PostgreSQL)
- Physical operator hints (for PostgreSQL)
- Backup and Point-in-time Recovery (Pigsty)
-
Papers and experimental reports are continuously updated
This project is evolving with new features 👫👫
Don't forget to star ⭐ and watch 👀 to stay up to date :)
🕹 QuickStart
1. Environment Setup
1.1 backend setup
- First, ensure that your machine has Python (>= 3.10) installed.
$ python --version
Python 3.10.12
- Next, create a virtual environment and install the dependencies for the project within it.
# Clone the repository
$ git clone https://github.com/TsinghuaDatabaseGroup/DB-GPT.git

# Enter the directory
$ cd DB-GPT

# Install all dependencies
$ pip3 install -r requirements.txt
$ pip3 install -r requirements_api.txt # If only running the API, you can just install the API dependencies, please use requirements_api.txt

# Default dependencies include the basic runtime environment (Chroma-DB vector library). If you want to use other vector libraries, please uncomment the respective dependencies in requirements.txt before installation.
If fail to install google-colab, try conda install -c conda-forge google-colab
-
PostgreSQL v12 (We have developed and tested based on PostgreSQL v12, we do not guarantee compatibility with other versions of PostgreSQL)
Ensure your database supports remote connections (link)
Moreover, install extensions like pg_stat_statements (track frequent queries), pg_hint_plan (optimize physical operators), and hypopg (create hypothetical indexes).
Note pg_stat_statements accumulates query statistics over time. Therefore, you need to regularly clear the statistics: 1) to discard all statistics, execute "SELECT pg_stat_statements_reset();"; 2) to discard statistics for a specific query, execute "SELECT pg_stat_statements_reset(userid, dbid, queryid);".
-
(optional) If you need to run this project locally or in an offline environment, you first need to download the required models to your local machine and then correctly adapt some configurations.
- Download the model parameters of Sentence Trasformer
Create a new directory ./multiagents/localized_llms/sentence_embedding/
Place the downloaded sentence-transformer.zip in the ./multiagents/localized_llms/sentence_embedding/ directory; unzip the archive.
- Download LLM and embedding models from HuggingFace.
To download models, first install Git LFS, then run
$ git lfs install
$ git clone https://huggingface.co/moka-ai/m3e-base
$ git clone https://huggingface.co/Qwen/Qwen-1_8B-Chat
- Adapt the model configuration to the download model paths, e.g.,
EMBEDDING_MODEL = "m3e-base"
LLM_MODELS = ["Qwen-1_8B-Chat"]
MODEL_PATH = {
    "embed_model": {
        "m3e-base": "m3e-base", # Download path of embedding model.
    },

    "llm_model": {
        "Qwen-1_8B-Chat": "Qwen-1_8B-Chat", # Download path of LLM.
    },
}
- Download and config localized LLMs.
1.2 frontend setup
- Ensure that your machine has Node (>= 18.15.0)
$ node -v
v18.15.0
Install pnpm and dependencies
cd webui
# pnpm address https://pnpm.io/zh/motivation
# install dependency(Recommend use pnpm)
# you can  use "npm -g i pnpm" to install pnpm
pnpm install
2. Initialize Knowledge Base and Configuration Files
Copy the configuration files
$ python copy_config_example.py
# The generated configuration files are in the configs/ directory
# basic_config.py is the basic configuration file, no modification needed
# diagnose_config.py is the diagnostic configuration file, needs to be modified according to your environment.
# kb_config.py is the knowledge base configuration file, you can modify DEFAULT_VS_TYPE to specify the storage vector library of the knowledge base, or modify related paths.
# model_config.py is the model configuration file, you can modify LLM_MODELS to specify the model used, the current model configuration is mainly for knowledge base search, diagnostic related models are still hardcoded in the code, they will be unified here later.
# prompt_config.py is the prompt configuration file, mainly for LLM dialogue and knowledge base prompts.
# server_config.py is the server configuration file, mainly for server port numbers, etc.
!!! Attention, please modify the following configurations before initializing the knowledge base, otherwise, it may cause the database initialization to fail.
- model_config.py
# EMBEDDING_MODEL   Vectorization model, if choosing a local model, it needs to be downloaded to the root directory as required.
# LLM_MODELS        LLM, if choosing a local model, it needs to be downloaded to the root directory as required.
# ONLINE_LLM_MODEL  If using an online model, you need to modify the configuration.
- server_config.py
# WEBUI_SERVER.api_base_url Pay attention to this parameter, if deploying the project on a server, then you need to modify the configuration.
- In diagnose_config.py, we set config.yaml as the default LLM expert configuration file.
DIAGNOSTIC_CONFIG_FILE = "config.yaml"
- To enable interactive diagnosis refinement with user feedbacks, you can set
DIAGNOSTIC_CONFIG_FILE = "config_feedback.yaml"
- To enable diagnosis in Chinese with Qwen, you can set
DIAGNOSTIC_CONFIG_FILE = "config_qwen.yaml"
- Initialize the knowledge base
$ python init_database.py --recreate-vs
3. One-click Start
Start the project with the following commands
$ python startup.py -a
4. Launch Interface Examples
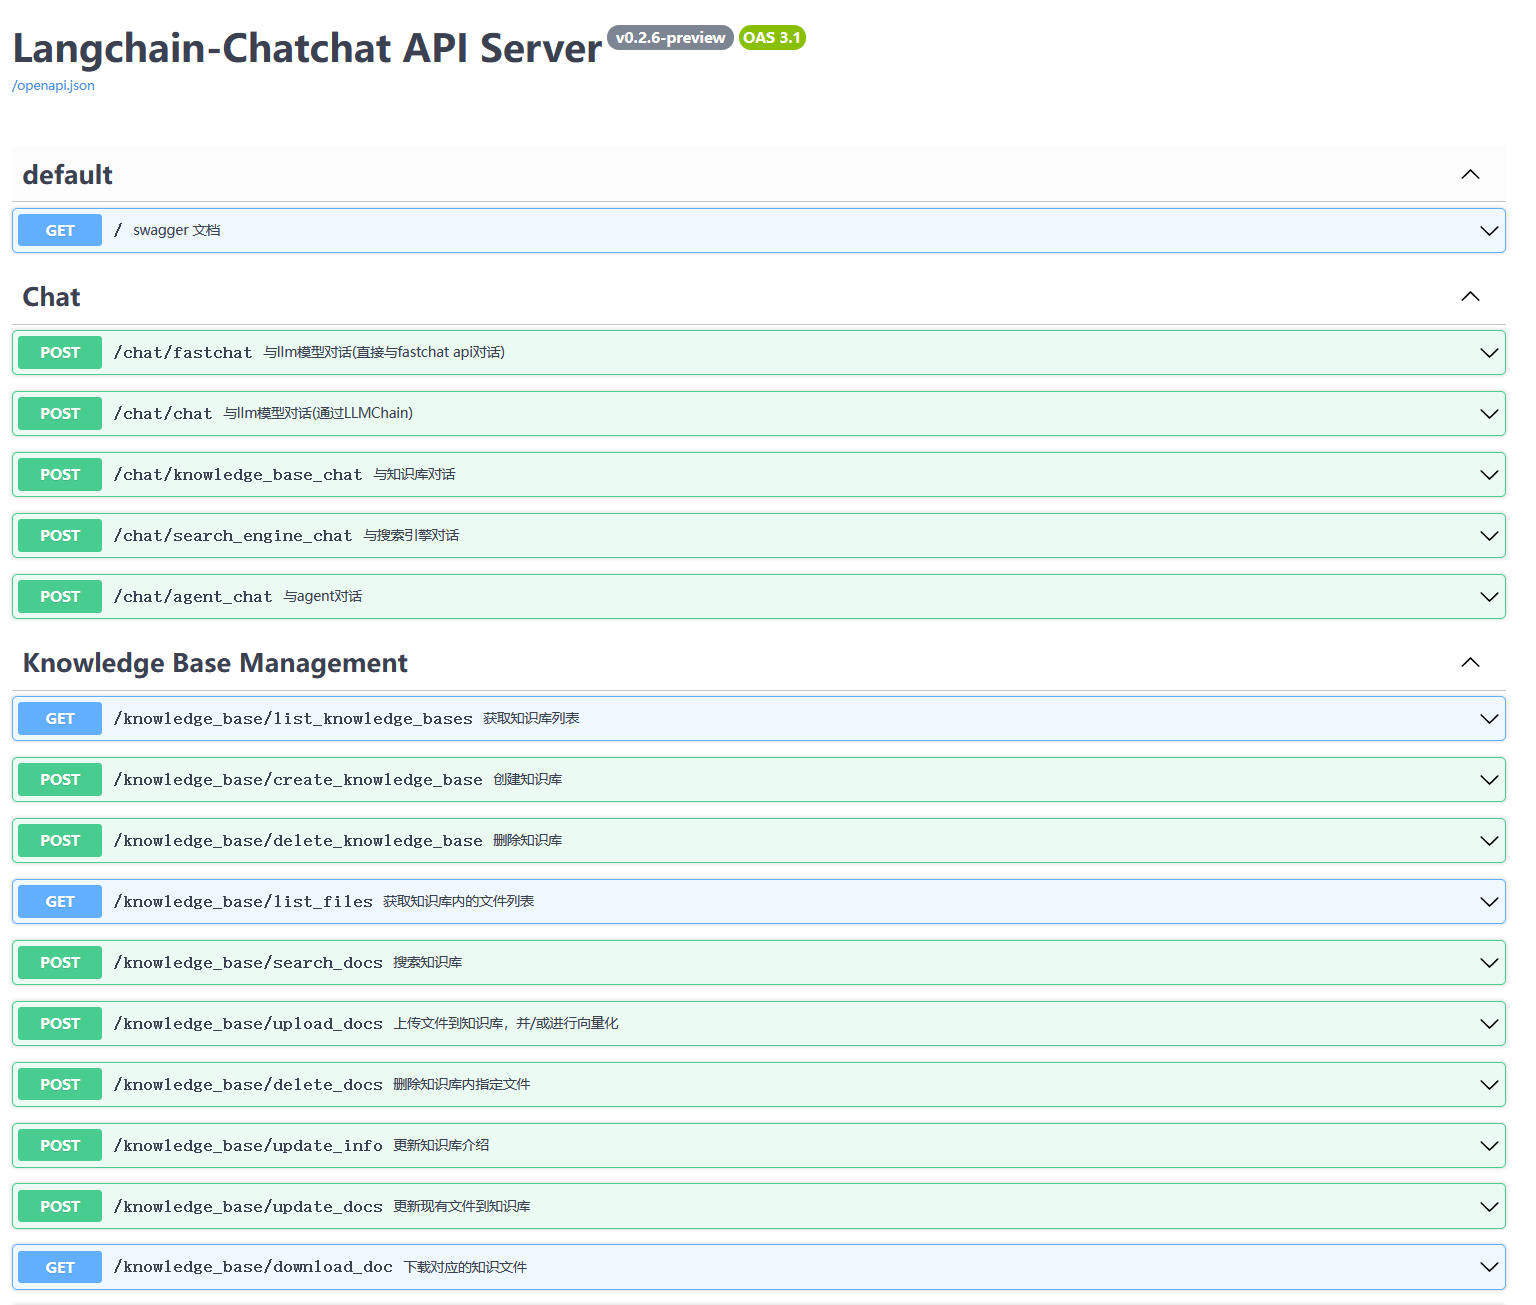
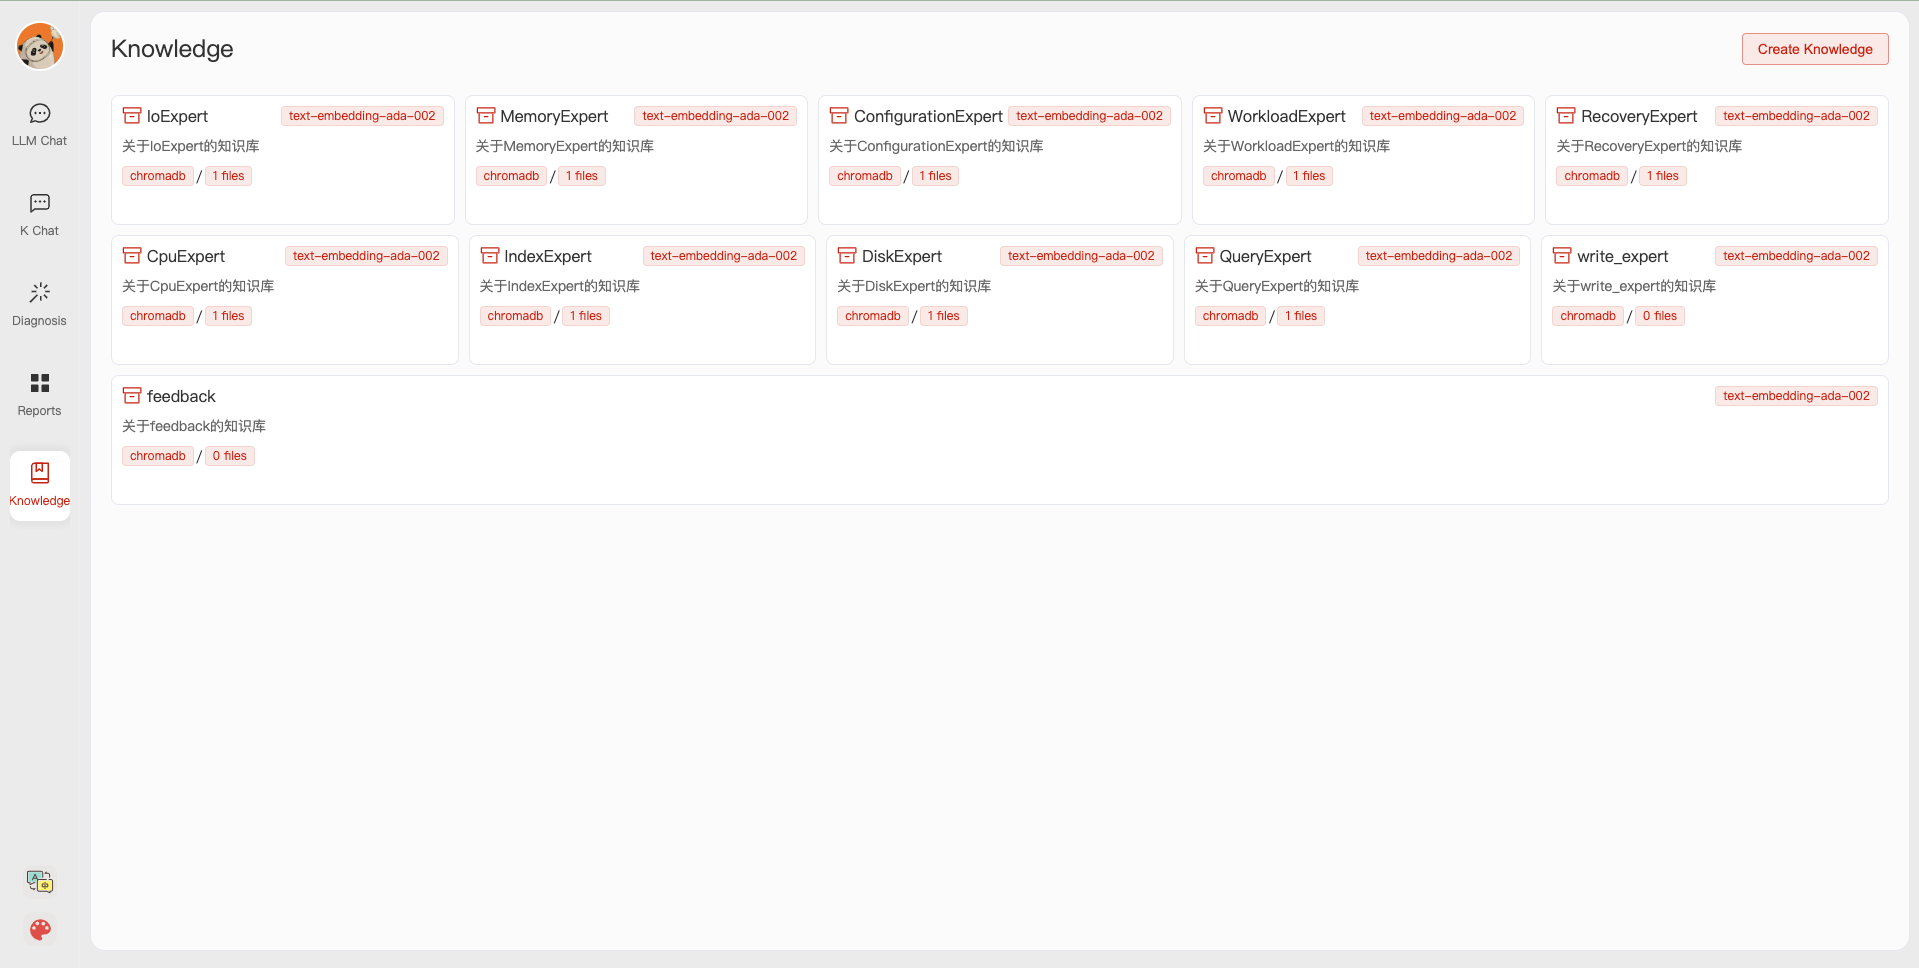
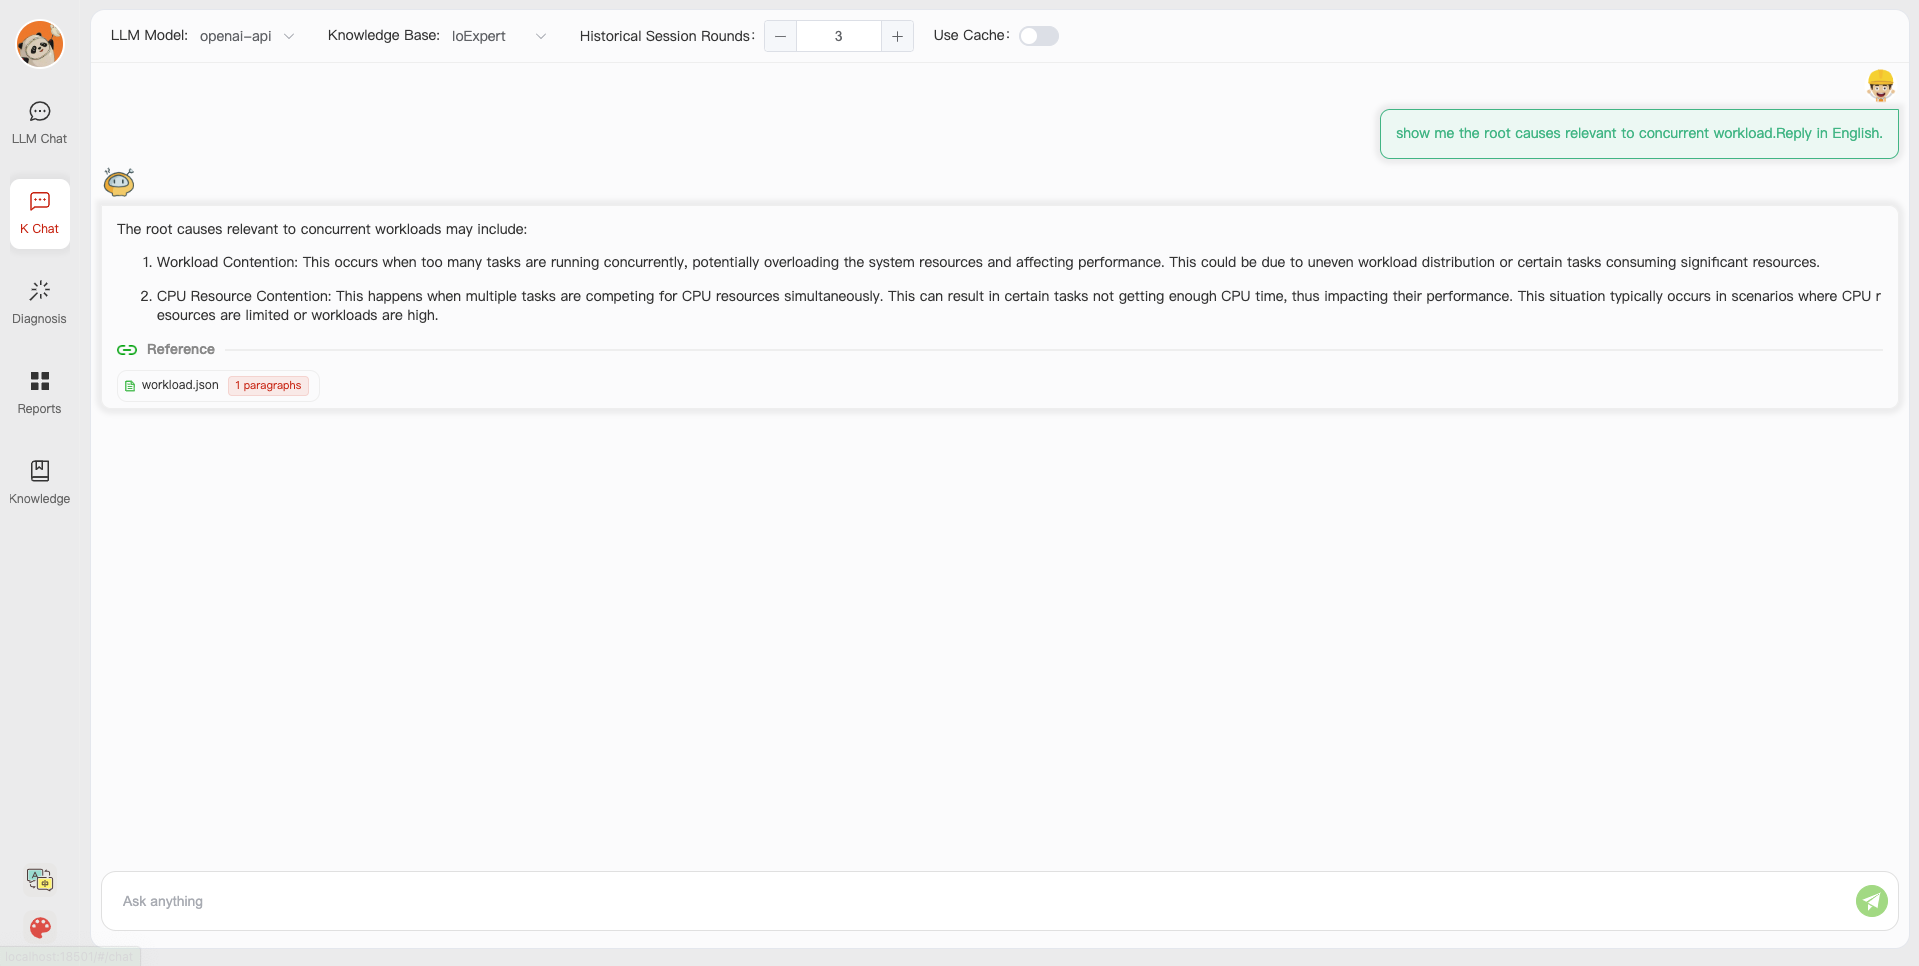
If started correctly, you will see the following interface
- FastAPI Docs Interface
- Web UI Launch Interface Examples:
- Web UI Knowledge Base Management Page:
- Web UI Conversation Interface:
- Web UI UI Diagnostic Page:
👩🏻⚕️ Anomaly Diagnosis
1. Prerequisites
Save time by trying out the docker deployment.
-
(optional) Enable slow query log in PostgreSQL (link)
(1) For "systemctl restart postgresql", the service name can be different (e.g., postgresql-12.service);
(2) Use absolute log path name like "log_directory = '/var/lib/pgsql/12/data/log'";
(3) Set "log_line_prefix = '%m [%p] [%d]'" in postgresql.conf (to record the database names of different queries).
-
(optional) Prometheus
Check prometheus.md for detailed installation guides.
2. Test typical cases
We put multiple test cases under the test_case folder. You can select a case file on the front-end page for diagnosis or use the command line.
python3 run_diagnose.py --anomaly_file ./test_cases/testing_cases_5.json --config_file config.yaml
🎩 Alerts And Anomalies
Alert Management
Check out how to deploy prometheus and alertmanager in prometheus_service_docker.
- You can also choose to quickly put your hands on by using our docker (docker deployment)
Anomaly Simulation
Script-Triggered Anomalies
We provide scripts that trigger typical anomalies (anomalies directory) using highly concurrent operations (e.g., inserts, deletes, updates) in combination with specific test benches.
Single Root Cause Anomalies:
Execute the following command to trigger a single type of anomaly with customized parameters:
python anomaly_trigger/main.py --anomaly MISSING_INDEXES --threads 100 --ncolumn 20 --colsize 100 --nrow 20000
Parameters:
--anomaly: Specifies the type of anomaly to trigger.--threads: Sets the number of concurrent clients.--ncolumn: Defines the number of columns.--colsize: Determines the size of each column (in bytes).--nrow: Indicates the number of rows.
Multiple Root Cause Anomalies:
To trigger anomalies caused by multiple factors, use the following command:
python anomaly_trigger/multi_anomalies.py
Modify the script as needed to simulate different types of anomalies.
| Root Cause | Description | Potential Alerts |
|---|---|---|
| INSERT_LARGE_DATA | Long execution time for large data insert |  |
| FETCH_LARGE_DATA | Long execution time for large data fetch |  |
| REDUNDANT_INDEX | Unnecessary and redundant indexes in tables | |
| VACUUM | Unused space caused by data modifications | |
| POOR_JOIN_PERFORMANCE | Poor performance of join operators | |
| CORRELATED_SUBQUERY | Non-promotable subqueries in SQL statements | , |
| LOCK_CONTENTION | Lock contention issues |   |
| CPU_CONTENTION | Severe CPU resource contention | |
| IO_CONTENTION | IO resource contention affecting SQL performance | |
| COMMIT_CONTENTION | Highly concurrent commits affecting SQL execution | |
| SMALL_MEMORY_ALLOC | Too small allocated memory space |
Check detailed use cases at http://dbgpt.dbmind.cn.
Manually Designed Anomalies
Click to check 29 typical anomalies together with expert analysis (supported by the DBMind team)
📎 Customize Knowledge And Tools
1. Knowledge Extraction
(Basic version by Zui Chen)
(1) If you only need simple document splitting, you can directly use the document import function in the "Knowledge Base Management Page".
(2) We require the document itself to have chapter format information, and currently only support the docx format.
Step 1. Configure the ROOT_DIR_NAME path in ./doc2knowledge/doc_to_section.py and store all docx format documents in ROOT_DIR_NAME.
Step 2. Configure OPENAI_KEY.
export OPENAI_API_KEY=XXXXX
Step 3. Split the document into separate chapter files by chapter index.
cd doc2knowledge/
python doc_to_section.py
Step 4. Modify parameters in the doc2knowledge.py script and run the script:
python doc2knowledge.py
Step 5. With the extracted knowledge, you can visualize their clustering results:
python knowledge_clustering.py
2. Tool Preparation
-
Tool APIs (for optimization)
Module Functions index_selection (equipped) heuristic algorithm query_rewrite (equipped) 45 rules physical_hint (equipped) 15 parameters For functions within [query_rewrite, physical_hint], you can use api_test.py script to verify the effectiveness.
If the function actually works, append it to the api.py of corresponding module.
Index Advisor Tool
We utilize db2advis heuristic algorithm to recommend indexes for given workloads. The function api is optimize_index_selection.
🐳 Docker Start
You can use docker for a quick and safe use of the monitoring platform and database.
1. Install Docker and Docker-Compose
Refer to tutorials (e.g., on CentOS) for installing Docker and Docoker-Compose.
2. Start service
We use docker-compose to build and manage multiple dockers for metric monitoring (prometheus), alert (alertmanager), database (postgres_db), and alert recording (python_app).
cd prometheus_service_docker
docker-compose  -p prometheus_service  -f docker-compose.yml up --build
Next time starting the prometheus_service, you can directly execute "docker-compose -p prometheus_service -f docker-compose.yml up" without building the dockers.
3. Run anomaly files and generate new alerts
Configure the settings in anomaly_trigger/utils/database.py (e.g., replace "host" with the IP address of the server) and execute an anomaly generation command, like:
cd anomaly_trigger
python3 main.py --anomaly MISSING_INDEXES --threads 100 --ncolumn 20 --colsize 100 --nrow 20000
You may need to modify the arugment values like "--threads 100" if no alert is recorded after execution.
After receiving a request sent to http://127.0.0.1:8023/alert from prometheus_service, the alert summary will be recorded in prometheus_and_db_docker/alert_history.txt, like:
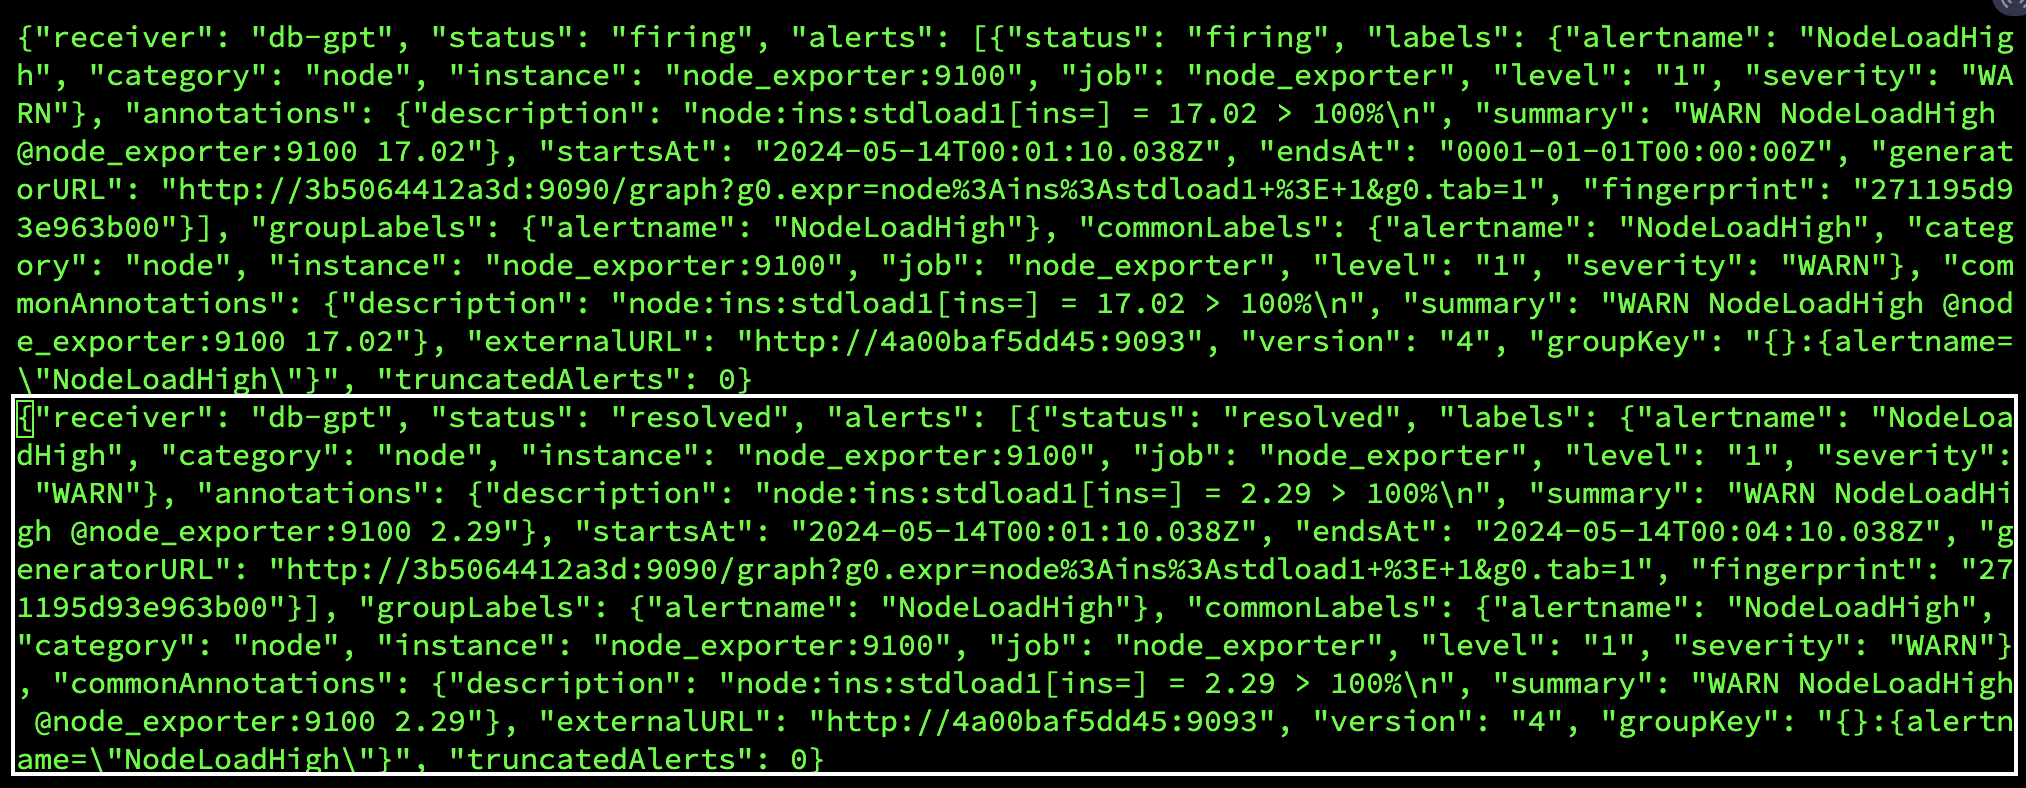
This way, you can use the alert marked as `resolved' as a new anomaly (under the ./diagnostic_files directory) for diagnosis by d-bot.
💁 FAQ
🤨 The '.sh' script command cannot be executed on windows system.
Switch the shell to *git bash* or use *git bash* to execute the '.sh' script.🤨 "No module named 'xxx'" on windows system.
This error is caused by issues with the Python runtime environment path. You need to perform the following steps:Step 1: Check Environment Variables.
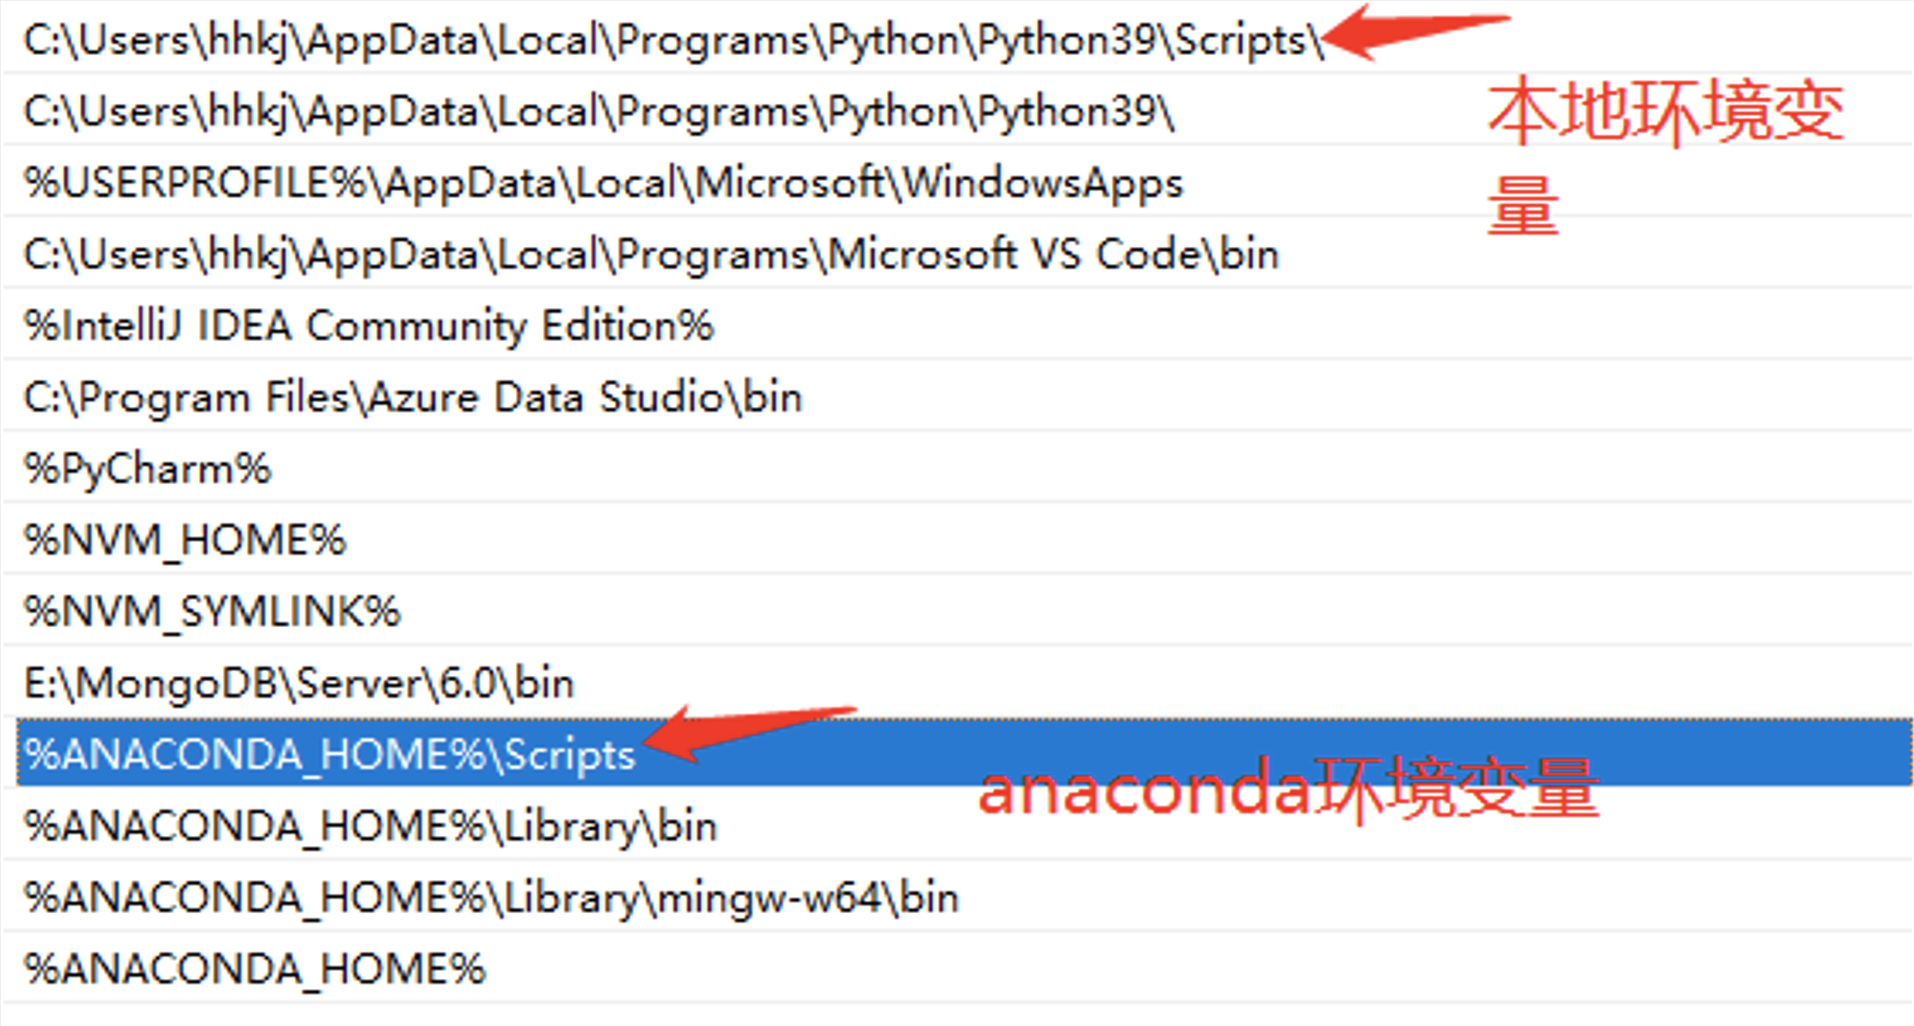
You must configure the "Scripts" in the environment variables.
Step 2: Check IDE Settings.
For VS Code, download the Python extension for code. For PyCharm, specify the Python version for the current project.
⏱ Todo
Project cleaningSupport more anomaliesSupport more knowledge sourcesQuery log option (potential to take up disk space and we need to consider it carefully)Add more communication mechanismsPrometheus-as-a-Service- Localized model that reaches D-bot(gpt4)'s capability
- Support other databases (e.g., mysql/redis)
👫 Community
🤗 Relevant Projects
https://github.com/OpenBMB/AgentVerse
https://github.com/Vonng/pigsty
https://github.com/UKPLab/sentence-transformers
https://github.com/chatchat-space/Langchain-Chatchat
https://github.com/shreyashankar/spade-experiments
📒 Citation
Feel free to cite us (paper link) if you like this project.
@misc{zhou2023llm4diag,
      title={D-Bot: Database Diagnosis System using Large Language Models},
      author={Xuanhe Zhou, Guoliang Li, Zhaoyan Sun, Zhiyuan Liu, Weize Chen, Jianming Wu, Jiesi Liu, Ruohang Feng, Guoyang Zeng},
      year={2023},
      eprint={2312.01454},
      archivePrefix={arXiv},
      primaryClass={cs.DB}
}
@misc{zhou2023dbgpt,
      title={DB-GPT: Large Language Model Meets Database},
      author={Xuanhe Zhou, Zhaoyan Sun, Guoliang Li},
      year={2023},
      archivePrefix={Data Science and Engineering},
}
📧 Contributors
Other Collaborators: Wei Zhou, Kunyi Li.
We thank all the contributors to this project. Do not hesitate if you would like to get involved or contribute!
Contact Information
👏🏻Welcome to our wechat group! If the QR code has expired, you can add the WeChat ID: ming621431. Please be sure to note [DB-GPT]!!!
Contributors


Similar repos


Languages
Python
79.3%
Vue
11.1%
JavaScript
6.0%
SCSS
3.0%
An LLM Based Diagnosis System (https://arxiv.org/pdf/2312.01454.pdf)
See the codeREADME
LLM As Database Administrator
Demo • QuickStart • Alerts And Anomalies • Knowledge And Tools • Dockers • FAQ • Community • Citation • Contributors • OpenAI, Azure aggregated API discounted access plan.
👫 Join Us on WeChat! 🏆 Top 100 Open Project! 🌟 VLDB 2024!
【English | 中文】
🦾 Build your personal database administrator (D-Bot)🧑💻, which is good at solving database problems by reading documents, using various tools, writing analysis reports! Undergoing An Upgrade!
🗺 Online Demo
- After launching the local service (adopting frontend and configs from Chatchat), you can easily import documents into the knowledge base, utilize the knowledge base for well-founded Q&A and diagnosis analysis of abnormal alarms.
- With the user feedback function 🔗, you can (1) send feedbacks to make D-Bot follow and refine the intermediate diagnosis results, and (2) edit the diagnosis result by clicking the “Edit” button. D-Bot can accumulate refinement patterns from the user feedbacks (stored in vector database) and adaptively align to user's diagnosis preference.
- On the online website (http://dbgpt.dbmind.cn), you can browse all historical diagnosis results, used metrics, and detailed diagnosis processes.
Old Version 1: [Gradio for Diag Game] (no langchain)
Old Version 2: [Vue for Report Replay] (no langchain)
📰 Updates
-
Docker for a quick and safe use of D-Bot
-
Metric Monitoring (prometheus), Database (postgres_db), Alert (alertmanager) and Alert Recording (python_app).
-
D-bot (still too large, with over 12GB)
-
-
Human Feedback 🔥🔥🔥
-
Test-based Diagnosis Refinement with User Feedbacks
-
Refinement Patterns Extraction & Management
-
-
Language Support (english / chinese)
- english : default
- chinese : add "language: zh" in config.yaml
-
New Frontend
- Knowledgebase + Chat Q&A + Diagnosis + Report Replay
-
Result Report with reference
-
Extreme Speed Version for localized llms
-
4-bit quantized LLM (reducing inference time by 1/3)
-
vllm for fast inference (qwen)
-
Tiny LLM
-
-
Multi-path extraction of document knowledge
-
Vector database (ChromaDB)
-
RESTful Search Engine (Elasticsearch)
-
-
Expert prompt generation using document knowledge
-
Upgrade the LLM-based diagnosis mechanism:
-
Task Dispatching -> Concurrent Diagnosis -> Cross Review -> Report Generation
-
Synchronous Concurrency Mechanism during LLM inference
-
-
Support monitoring and optimization tools in multiple levels 🔗 link
- Monitoring metrics (Prometheus)
- Flame graph in code level
- Diagnosis knowledge retrieval (dbmind)
- Logical query transformations (Calcite)
- Index optimization algorithms (for PostgreSQL)
- Physical operator hints (for PostgreSQL)
- Backup and Point-in-time Recovery (Pigsty)
-
Papers and experimental reports are continuously updated
This project is evolving with new features 👫👫
Don't forget to star ⭐ and watch 👀 to stay up to date :)
🕹 QuickStart
1. Environment Setup
1.1 backend setup
- First, ensure that your machine has Python (>= 3.10) installed.
$ python --version
Python 3.10.12
- Next, create a virtual environment and install the dependencies for the project within it.
# Clone the repository
$ git clone https://github.com/TsinghuaDatabaseGroup/DB-GPT.git

# Enter the directory
$ cd DB-GPT

# Install all dependencies
$ pip3 install -r requirements.txt
$ pip3 install -r requirements_api.txt # If only running the API, you can just install the API dependencies, please use requirements_api.txt

# Default dependencies include the basic runtime environment (Chroma-DB vector library). If you want to use other vector libraries, please uncomment the respective dependencies in requirements.txt before installation.
If fail to install google-colab, try conda install -c conda-forge google-colab
-
PostgreSQL v12 (We have developed and tested based on PostgreSQL v12, we do not guarantee compatibility with other versions of PostgreSQL)
Ensure your database supports remote connections (link)
Moreover, install extensions like pg_stat_statements (track frequent queries), pg_hint_plan (optimize physical operators), and hypopg (create hypothetical indexes).
Note pg_stat_statements accumulates query statistics over time. Therefore, you need to regularly clear the statistics: 1) to discard all statistics, execute "SELECT pg_stat_statements_reset();"; 2) to discard statistics for a specific query, execute "SELECT pg_stat_statements_reset(userid, dbid, queryid);".
-
(optional) If you need to run this project locally or in an offline environment, you first need to download the required models to your local machine and then correctly adapt some configurations.
- Download the model parameters of Sentence Trasformer
Create a new directory ./multiagents/localized_llms/sentence_embedding/
Place the downloaded sentence-transformer.zip in the ./multiagents/localized_llms/sentence_embedding/ directory; unzip the archive.
- Download LLM and embedding models from HuggingFace.
To download models, first install Git LFS, then run
$ git lfs install
$ git clone https://huggingface.co/moka-ai/m3e-base
$ git clone https://huggingface.co/Qwen/Qwen-1_8B-Chat
- Adapt the model configuration to the download model paths, e.g.,
EMBEDDING_MODEL = "m3e-base"
LLM_MODELS = ["Qwen-1_8B-Chat"]
MODEL_PATH = {
    "embed_model": {
        "m3e-base": "m3e-base", # Download path of embedding model.
    },

    "llm_model": {
        "Qwen-1_8B-Chat": "Qwen-1_8B-Chat", # Download path of LLM.
    },
}
- Download and config localized LLMs.
1.2 frontend setup
- Ensure that your machine has Node (>= 18.15.0)
$ node -v
v18.15.0
Install pnpm and dependencies
cd webui
# pnpm address https://pnpm.io/zh/motivation
# install dependency(Recommend use pnpm)
# you can  use "npm -g i pnpm" to install pnpm
pnpm install
2. Initialize Knowledge Base and Configuration Files
Copy the configuration files
$ python copy_config_example.py
# The generated configuration files are in the configs/ directory
# basic_config.py is the basic configuration file, no modification needed
# diagnose_config.py is the diagnostic configuration file, needs to be modified according to your environment.
# kb_config.py is the knowledge base configuration file, you can modify DEFAULT_VS_TYPE to specify the storage vector library of the knowledge base, or modify related paths.
# model_config.py is the model configuration file, you can modify LLM_MODELS to specify the model used, the current model configuration is mainly for knowledge base search, diagnostic related models are still hardcoded in the code, they will be unified here later.
# prompt_config.py is the prompt configuration file, mainly for LLM dialogue and knowledge base prompts.
# server_config.py is the server configuration file, mainly for server port numbers, etc.
!!! Attention, please modify the following configurations before initializing the knowledge base, otherwise, it may cause the database initialization to fail.
- model_config.py
# EMBEDDING_MODEL   Vectorization model, if choosing a local model, it needs to be downloaded to the root directory as required.
# LLM_MODELS        LLM, if choosing a local model, it needs to be downloaded to the root directory as required.
# ONLINE_LLM_MODEL  If using an online model, you need to modify the configuration.
- server_config.py
# WEBUI_SERVER.api_base_url Pay attention to this parameter, if deploying the project on a server, then you need to modify the configuration.
- In diagnose_config.py, we set config.yaml as the default LLM expert configuration file.
DIAGNOSTIC_CONFIG_FILE = "config.yaml"
- To enable interactive diagnosis refinement with user feedbacks, you can set
DIAGNOSTIC_CONFIG_FILE = "config_feedback.yaml"
- To enable diagnosis in Chinese with Qwen, you can set
DIAGNOSTIC_CONFIG_FILE = "config_qwen.yaml"
- Initialize the knowledge base
$ python init_database.py --recreate-vs
3. One-click Start
Start the project with the following commands
$ python startup.py -a
4. Launch Interface Examples
If started correctly, you will see the following interface
- FastAPI Docs Interface
- Web UI Launch Interface Examples:
- Web UI Knowledge Base Management Page:
- Web UI Conversation Interface:
- Web UI UI Diagnostic Page:
👩🏻⚕️ Anomaly Diagnosis
1. Prerequisites
Save time by trying out the docker deployment.
-
(optional) Enable slow query log in PostgreSQL (link)
(1) For "systemctl restart postgresql", the service name can be different (e.g., postgresql-12.service);
(2) Use absolute log path name like "log_directory = '/var/lib/pgsql/12/data/log'";
(3) Set "log_line_prefix = '%m [%p] [%d]'" in postgresql.conf (to record the database names of different queries).
-
(optional) Prometheus
Check prometheus.md for detailed installation guides.
2. Test typical cases
We put multiple test cases under the test_case folder. You can select a case file on the front-end page for diagnosis or use the command line.
python3 run_diagnose.py --anomaly_file ./test_cases/testing_cases_5.json --config_file config.yaml
🎩 Alerts And Anomalies
Alert Management
Check out how to deploy prometheus and alertmanager in prometheus_service_docker.
- You can also choose to quickly put your hands on by using our docker (docker deployment)
Anomaly Simulation
Script-Triggered Anomalies
We provide scripts that trigger typical anomalies (anomalies directory) using highly concurrent operations (e.g., inserts, deletes, updates) in combination with specific test benches.
Single Root Cause Anomalies:
Execute the following command to trigger a single type of anomaly with customized parameters:
python anomaly_trigger/main.py --anomaly MISSING_INDEXES --threads 100 --ncolumn 20 --colsize 100 --nrow 20000
Parameters:
--anomaly: Specifies the type of anomaly to trigger.--threads: Sets the number of concurrent clients.--ncolumn: Defines the number of columns.--colsize: Determines the size of each column (in bytes).--nrow: Indicates the number of rows.
Multiple Root Cause Anomalies:
To trigger anomalies caused by multiple factors, use the following command:
python anomaly_trigger/multi_anomalies.py
Modify the script as needed to simulate different types of anomalies.
| Root Cause | Description | Potential Alerts |
|---|---|---|
| INSERT_LARGE_DATA | Long execution time for large data insert | |
| FETCH_LARGE_DATA | Long execution time for large data fetch | |
| REDUNDANT_INDEX | Unnecessary and redundant indexes in tables | |
| VACUUM | Unused space caused by data modifications | |
| POOR_JOIN_PERFORMANCE | Poor performance of join operators | |
| CORRELATED_SUBQUERY | Non-promotable subqueries in SQL statements | , |
| LOCK_CONTENTION | Lock contention issues | |
| CPU_CONTENTION | Severe CPU resource contention | |
| IO_CONTENTION | IO resource contention affecting SQL performance | |
| COMMIT_CONTENTION | Highly concurrent commits affecting SQL execution | |
| SMALL_MEMORY_ALLOC | Too small allocated memory space |
Check detailed use cases at http://dbgpt.dbmind.cn.
Manually Designed Anomalies
Click to check 29 typical anomalies together with expert analysis (supported by the DBMind team)
📎 Customize Knowledge And Tools
1. Knowledge Extraction
(Basic version by Zui Chen)
(1) If you only need simple document splitting, you can directly use the document import function in the "Knowledge Base Management Page".
(2) We require the document itself to have chapter format information, and currently only support the docx format.
Step 1. Configure the ROOT_DIR_NAME path in ./doc2knowledge/doc_to_section.py and store all docx format documents in ROOT_DIR_NAME.
Step 2. Configure OPENAI_KEY.
export OPENAI_API_KEY=XXXXX
Step 3. Split the document into separate chapter files by chapter index.
cd doc2knowledge/
python doc_to_section.py
Step 4. Modify parameters in the doc2knowledge.py script and run the script:
python doc2knowledge.py
Step 5. With the extracted knowledge, you can visualize their clustering results:
python knowledge_clustering.py
2. Tool Preparation
-
Tool APIs (for optimization)
Module Functions index_selection (equipped) heuristic algorithm query_rewrite (equipped) 45 rules physical_hint (equipped) 15 parameters For functions within [query_rewrite, physical_hint], you can use api_test.py script to verify the effectiveness.
If the function actually works, append it to the api.py of corresponding module.
Index Advisor Tool
We utilize db2advis heuristic algorithm to recommend indexes for given workloads. The function api is optimize_index_selection.
🐳 Docker Start
You can use docker for a quick and safe use of the monitoring platform and database.
1. Install Docker and Docker-Compose
Refer to tutorials (e.g., on CentOS) for installing Docker and Docoker-Compose.
2. Start service
We use docker-compose to build and manage multiple dockers for metric monitoring (prometheus), alert (alertmanager), database (postgres_db), and alert recording (python_app).
cd prometheus_service_docker
docker-compose  -p prometheus_service  -f docker-compose.yml up --build
Next time starting the prometheus_service, you can directly execute "docker-compose -p prometheus_service -f docker-compose.yml up" without building the dockers.
3. Run anomaly files and generate new alerts
Configure the settings in anomaly_trigger/utils/database.py (e.g., replace "host" with the IP address of the server) and execute an anomaly generation command, like:
cd anomaly_trigger
python3 main.py --anomaly MISSING_INDEXES --threads 100 --ncolumn 20 --colsize 100 --nrow 20000
You may need to modify the arugment values like "--threads 100" if no alert is recorded after execution.
After receiving a request sent to http://127.0.0.1:8023/alert from prometheus_service, the alert summary will be recorded in prometheus_and_db_docker/alert_history.txt, like:
This way, you can use the alert marked as `resolved' as a new anomaly (under the ./diagnostic_files directory) for diagnosis by d-bot.
💁 FAQ
🤨 The '.sh' script command cannot be executed on windows system.
Switch the shell to *git bash* or use *git bash* to execute the '.sh' script.🤨 "No module named 'xxx'" on windows system.
This error is caused by issues with the Python runtime environment path. You need to perform the following steps:Step 1: Check Environment Variables.
You must configure the "Scripts" in the environment variables.
Step 2: Check IDE Settings.
For VS Code, download the Python extension for code. For PyCharm, specify the Python version for the current project.
⏱ Todo
Project cleaningSupport more anomaliesSupport more knowledge sourcesQuery log option (potential to take up disk space and we need to consider it carefully)Add more communication mechanismsPrometheus-as-a-Service- Localized model that reaches D-bot(gpt4)'s capability
- Support other databases (e.g., mysql/redis)
👫 Community
🤗 Relevant Projects
https://github.com/OpenBMB/AgentVerse
https://github.com/Vonng/pigsty
https://github.com/UKPLab/sentence-transformers
https://github.com/chatchat-space/Langchain-Chatchat
https://github.com/shreyashankar/spade-experiments
📒 Citation
Feel free to cite us (paper link) if you like this project.
@misc{zhou2023llm4diag,
      title={D-Bot: Database Diagnosis System using Large Language Models},
      author={Xuanhe Zhou, Guoliang Li, Zhaoyan Sun, Zhiyuan Liu, Weize Chen, Jianming Wu, Jiesi Liu, Ruohang Feng, Guoyang Zeng},
      year={2023},
      eprint={2312.01454},
      archivePrefix={arXiv},
      primaryClass={cs.DB}
}
@misc{zhou2023dbgpt,
      title={DB-GPT: Large Language Model Meets Database},
      author={Xuanhe Zhou, Zhaoyan Sun, Guoliang Li},
      year={2023},
      archivePrefix={Data Science and Engineering},
}
📧 Contributors
Other Collaborators: Wei Zhou, Kunyi Li.
We thank all the contributors to this project. Do not hesitate if you would like to get involved or contribute!
Contact Information
👏🏻Welcome to our wechat group! If the QR code has expired, you can add the WeChat ID: ming621431. Please be sure to note [DB-GPT]!!!
Similar repos
Contributors
Languages
Python
79.3%
Vue
11.1%
JavaScript
6.0%
SCSS
3.0%