
Gemma 4 abliteration research: biprojection + EGA for E2B, E4B, 12B, 26B MoE, 31B
Python
139
9 commits
updated Jun 13, 2026
README
Gemma 4 Abliteration
Abliterated (uncensored) versions of Google's Gemma 4 model family using norm-preserving biprojected abliteration and Expert-Granular Abliteration (EGA) for MoE models.
Models
| Model | Params | Refusals | KL Div | HF (bf16) | HF (GGUF) |
|---|---|---|---|---|---|
| E2B | 2.3B dense | 3/686 (0.4%) | 0.346 | TrevorJS/gemma-4-E2B-it-uncensored | GGUF |
| E4B | 4.5B dense | 5/686 (0.7%) | 0.068 | TrevorJS/gemma-4-E4B-it-uncensored | GGUF |
| 12B | 11.95B dense (Unified) | 14/686 (2.0%) | 0.056 | TrevorJS/gemma-4-12B-it-uncensored | GGUF |
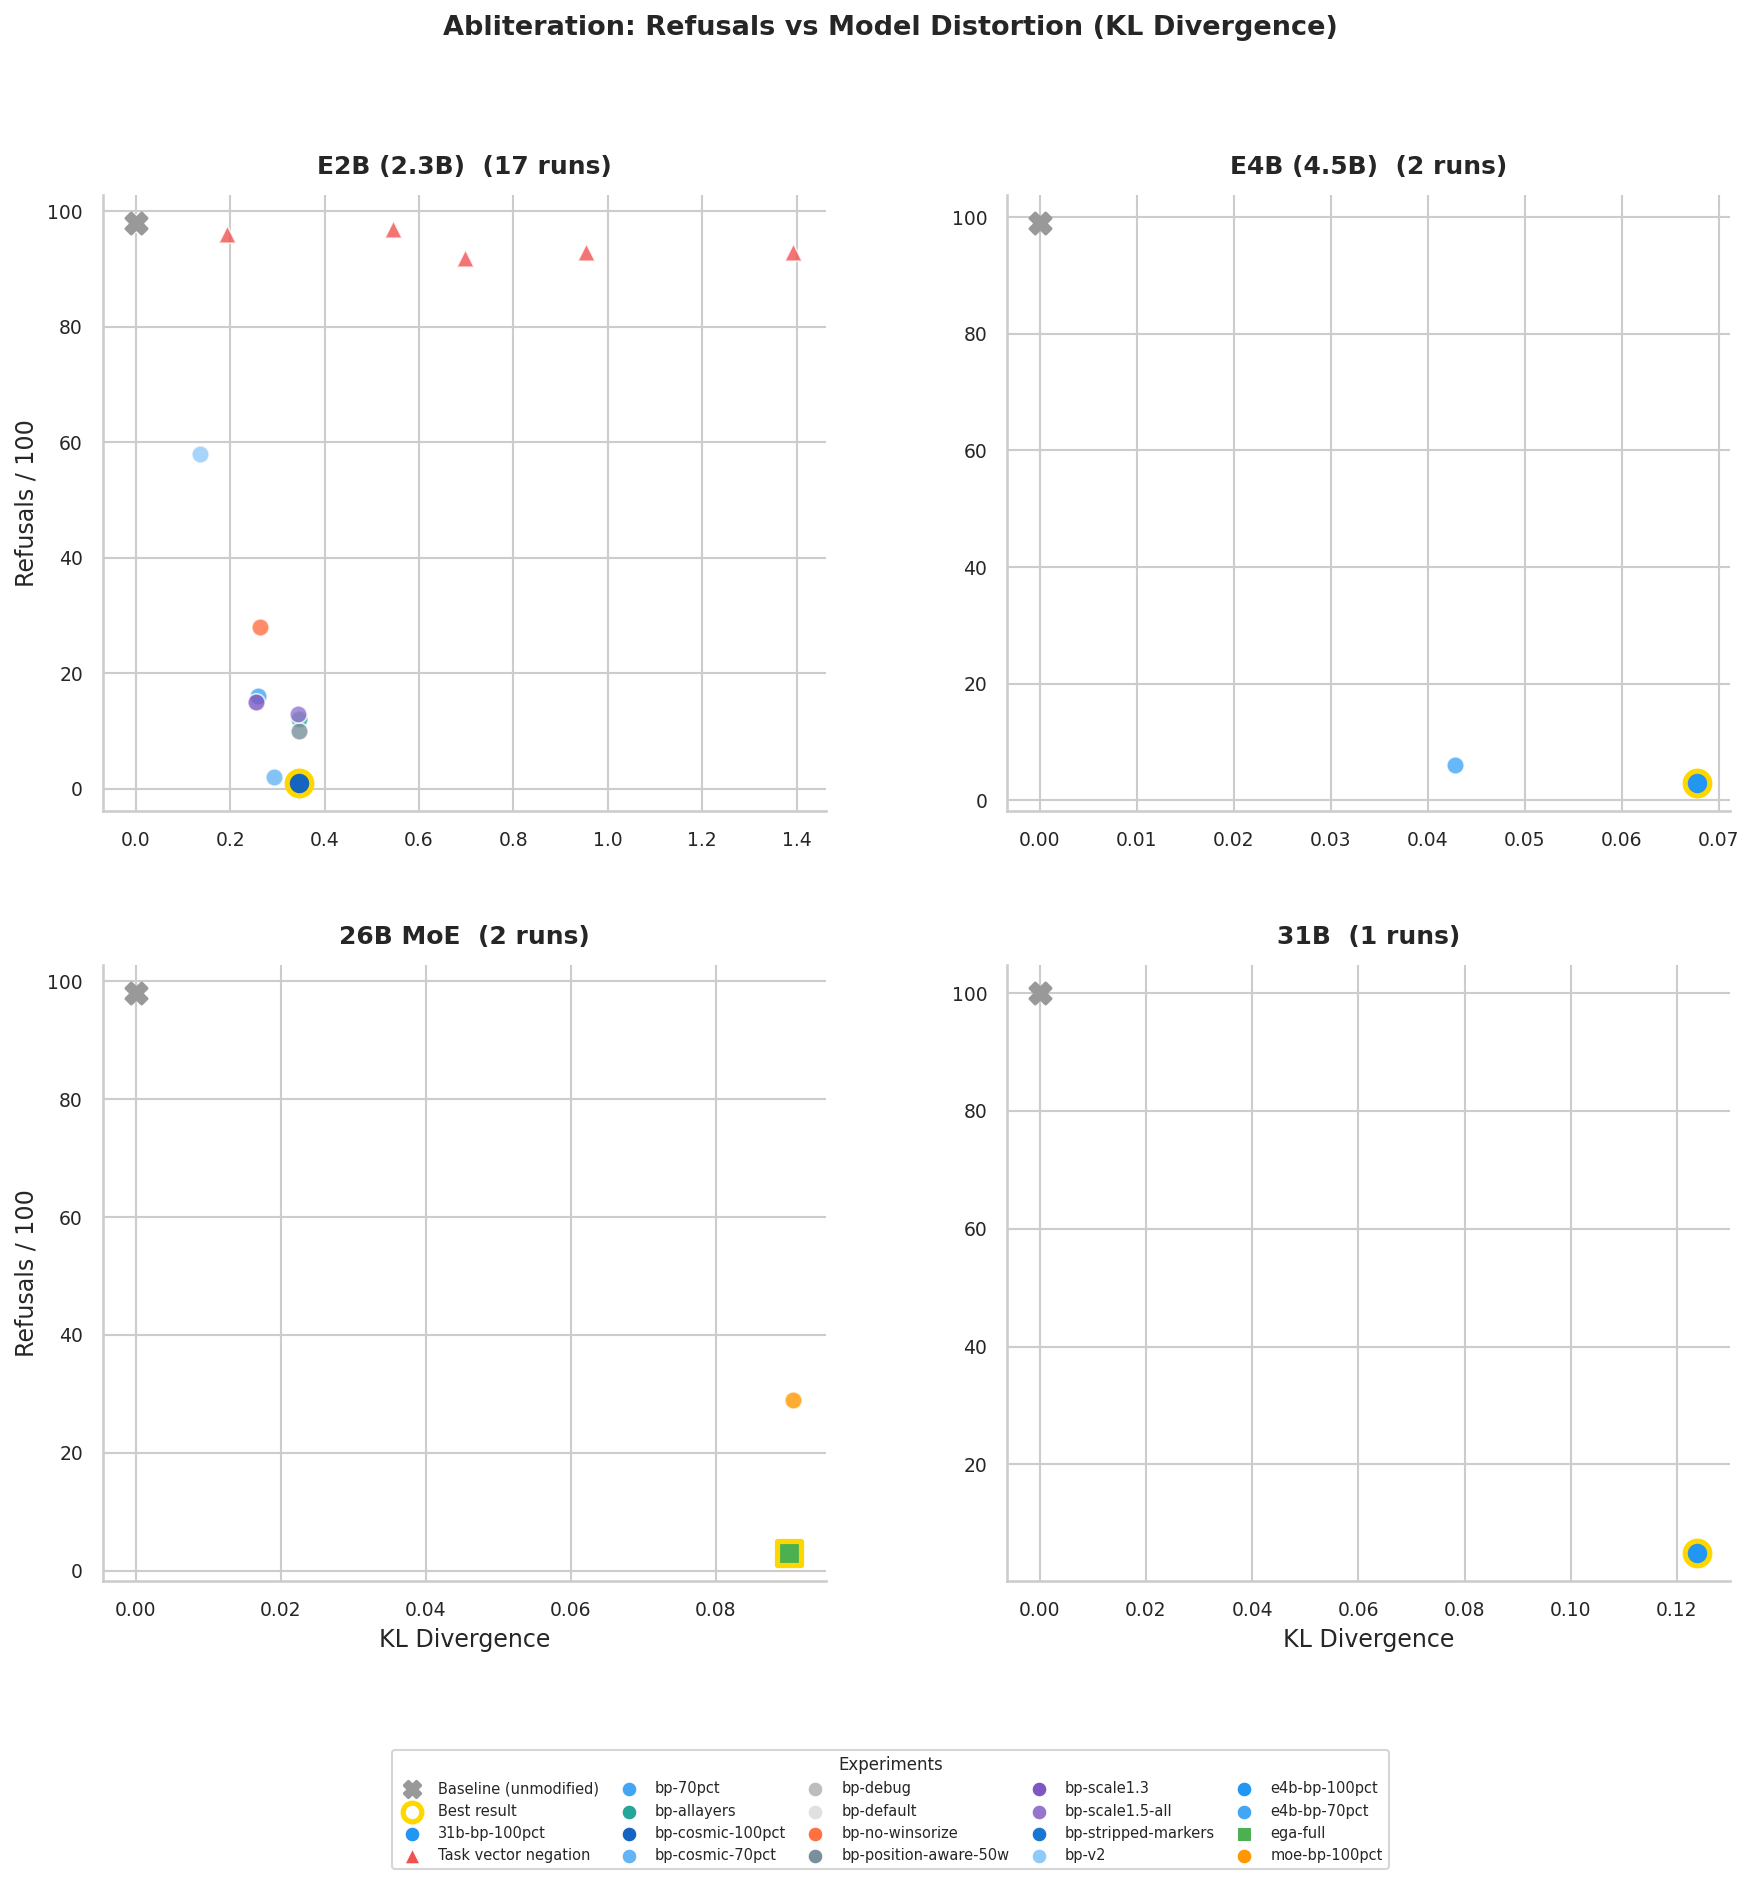
| 26B-A4B | 25.2B MoE (3.8B active) | 5/686 (0.7%) | 0.090 | TrevorJS/gemma-4-26B-A4B-it-uncensored | GGUF |
| 31B | 31B dense | 22/686 (3.2%) | 0.124 | TrevorJS/gemma-4-31B-it-uncensored | GGUF |
Refusal rates measured across 686 prompts from 4 independent datasets (JailbreakBench, tulu-harmbench, NousResearch, mlabonne). Every flagged refusal was manually audited — most are refusal-then-comply false positives.
Method
Dense models (E2B, E4B, 31B): Norm-preserving biprojected abliteration. Per-layer refusal directions are computed from 800 harmful/harmless prompt residuals, orthogonalized against harmless means, and projected out of o_proj + mlp.down_proj weights while preserving row norms.
Unified model (12B): Same dense biprojection on the text decoder. gemma-4-12B-it is the encoder-free Gemma4Unified arch (added 2026-06-03); its refusal signal sits in the upper layers (L15-47), so only the top 70% are abliterated. Two arch quirks: it needs transformers >= 5.10.1, and it emits -inf logits for reserved vocab tokens that NaN a naive KL — the eval masks those. See version requirements.
MoE model (26B-A4B): Same as above on the dense pathway, plus Expert-Granular Abliteration (EGA) — hooks MoE routers to compute per-expert routing weights, then applies the same projection to each of the 128 expert down_proj slices per layer. Dense-only abliteration leaves 29/100 refusals; adding EGA drops it to 3/100.
Built on heretic. EGA concept from OBLITERATUS. Biprojection from grimjim.
Quick Start
# Install heretic
uv tool install 'heretic-llm @ git+https://github.com/p-e-w/heretic' --with protobuf

# Abliterate a dense model
HF_DATASETS_CACHE=/tmp/hf_datasets_cache \
  heretic-python scripts/abliterate.py biprojection \
  --model google/gemma-4-E4B-it \
  --top-pct 100 --strip-topic-markers --skip-prefix --batch-size 4 \
  --auto-save models/output-dir

# Abliterate the 12B Unified model (needs transformers >= 5.10.1; 70% layers)
HF_DATASETS_CACHE=/tmp/hf_datasets_cache \
  heretic-python scripts/abliterate.py biprojection \
  --model google/gemma-4-12B-it \
  --top-pct 70 --strip-topic-markers --skip-prefix --batch-size 4 \
  --auto-save models/output-dir

# Abliterate the MoE model (EGA)
HF_DATASETS_CACHE=/tmp/hf_datasets_cache \
  heretic-python scripts/ega.py \
  --model google/gemma-4-26B-A4B-it \
  --strip-topic-markers --skip-prefix --no-eval --batch-size 4 \
  --save models/output-dir

# Memory-efficient 31B (4-bit directions + bf16 shard-by-shard save)
heretic-python scripts/export_31b.py
Requirements
| Component | Version | Notes |
|---|---|---|
transformers | >= 5.10.1 for 12B (5.5.0 ok for the other 4) | gemma4_unified arch was added in 5.10.1; tested on 5.12.0 |
torch | 2.11.0+cu130 (tested) | — |
heretic-llm | git HEAD (reports 1.2.0) | PyPI pin breaks on Gemma 4 tokenizer; install from git |
| llama.cpp (GGUF) | build >= 2026-06-04 | Gemma4Unified GGUF support added in PR #24118; converter refactored into a conversion/ package. Earlier builds fail with Gemma4UnifiedForConditionalGeneration is not supported. Tested at commit c34b922. |
The original four models (E2B/E4B/26B-A4B/31B) were produced on transformers 5.5.0 and the pre-refactor llama.cpp converter. Only the 12B Unified model needs the newer toolchain above.
Scripts
| Script | Purpose |
|---|---|
abliterate.py | Experiment driver — Optuna search and biprojection modes |
ega.py | Expert-Granular Abliteration for MoE models |
export.py | Save weights, convert GGUF, push to HF |
export_31b.py | Memory-efficient 31B export (4-bit directions + bf16 shards) |
multi_eval.py | Cross-dataset validation (686 prompts, 4 datasets) |
dashboard.py | Scatter plot + bar chart of all experiment results |
sanity_check.py | Baseline vs abliterated quality comparison |
task_vector.py | Task vector negation (tested, ruled out) |
Key Findings
- Biprojection + EGA covers dense, MoE, and Unified — sub-1% refusal rate across all models
- Larger models absorb abliteration better — E4B KL=0.07 vs E2B KL=0.35; 12B is cleanest at KL=0.056
- MoE experts carry most refusal signal — dense-only gets 29/100, EGA gets 3/100
- Default refusal markers are broken — "illegal", "harmful" etc. match disclaimers, not refusals
- Task vector negation doesn't work — sharp phase transition, no usable middle ground
- 4-bit directions ≈ bf16 directions — mean cosine similarity 0.935, fine for abliteration
- The Unified arch needs care — refusal signal in upper layers only (abliterate 70%, not 100%); reserved-token
-inflogits NaN a naive KL (mask them); needstransformers >= 5.10.1and a recent llama.cpp for GGUF
Repo Structure
├── ABLITERATION.md    # Full research doc with tables and references
├── STATE.md           # Current best results per model
├── IDEAS.md           # Prioritized technique backlog
├── REDTEAM.md         # Red team benchmark survey
├── scripts/           # All experiment and export scripts
├── experiments/       # JSON results from every experiment
├── prompts/           # Eval datasets (150 iteration + 686 full)
├── models/            # Saved weights (gitignored)
└── checkpoints/       # Heretic Optuna checkpoints (gitignored)
License
Apache 2.0 (same as base Gemma 4 models).
Significant stargazers

282 followers · starred Jun 2026
Similar repos

Languages
Python
100.0%
Gemma 4 abliteration research: biprojection + EGA for E2B, E4B, 12B, 26B MoE, 31B
Python
139
9 commits
updated Jun 13, 2026
README
Gemma 4 Abliteration
Abliterated (uncensored) versions of Google's Gemma 4 model family using norm-preserving biprojected abliteration and Expert-Granular Abliteration (EGA) for MoE models.
Models
| Model | Params | Refusals | KL Div | HF (bf16) | HF (GGUF) |
|---|---|---|---|---|---|
| E2B | 2.3B dense | 3/686 (0.4%) | 0.346 | TrevorJS/gemma-4-E2B-it-uncensored | GGUF |
| E4B | 4.5B dense | 5/686 (0.7%) | 0.068 | TrevorJS/gemma-4-E4B-it-uncensored | GGUF |
| 12B | 11.95B dense (Unified) | 14/686 (2.0%) | 0.056 | TrevorJS/gemma-4-12B-it-uncensored | GGUF |
| 26B-A4B | 25.2B MoE (3.8B active) | 5/686 (0.7%) | 0.090 | TrevorJS/gemma-4-26B-A4B-it-uncensored | GGUF |
| 31B | 31B dense | 22/686 (3.2%) | 0.124 | TrevorJS/gemma-4-31B-it-uncensored | GGUF |
Refusal rates measured across 686 prompts from 4 independent datasets (JailbreakBench, tulu-harmbench, NousResearch, mlabonne). Every flagged refusal was manually audited — most are refusal-then-comply false positives.
Method
Dense models (E2B, E4B, 31B): Norm-preserving biprojected abliteration. Per-layer refusal directions are computed from 800 harmful/harmless prompt residuals, orthogonalized against harmless means, and projected out of o_proj + mlp.down_proj weights while preserving row norms.
Unified model (12B): Same dense biprojection on the text decoder. gemma-4-12B-it is the encoder-free Gemma4Unified arch (added 2026-06-03); its refusal signal sits in the upper layers (L15-47), so only the top 70% are abliterated. Two arch quirks: it needs transformers >= 5.10.1, and it emits -inf logits for reserved vocab tokens that NaN a naive KL — the eval masks those. See version requirements.
MoE model (26B-A4B): Same as above on the dense pathway, plus Expert-Granular Abliteration (EGA) — hooks MoE routers to compute per-expert routing weights, then applies the same projection to each of the 128 expert down_proj slices per layer. Dense-only abliteration leaves 29/100 refusals; adding EGA drops it to 3/100.
Built on heretic. EGA concept from OBLITERATUS. Biprojection from grimjim.
Quick Start
# Install heretic
uv tool install 'heretic-llm @ git+https://github.com/p-e-w/heretic' --with protobuf

# Abliterate a dense model
HF_DATASETS_CACHE=/tmp/hf_datasets_cache \
  heretic-python scripts/abliterate.py biprojection \
  --model google/gemma-4-E4B-it \
  --top-pct 100 --strip-topic-markers --skip-prefix --batch-size 4 \
  --auto-save models/output-dir

# Abliterate the 12B Unified model (needs transformers >= 5.10.1; 70% layers)
HF_DATASETS_CACHE=/tmp/hf_datasets_cache \
  heretic-python scripts/abliterate.py biprojection \
  --model google/gemma-4-12B-it \
  --top-pct 70 --strip-topic-markers --skip-prefix --batch-size 4 \
  --auto-save models/output-dir

# Abliterate the MoE model (EGA)
HF_DATASETS_CACHE=/tmp/hf_datasets_cache \
  heretic-python scripts/ega.py \
  --model google/gemma-4-26B-A4B-it \
  --strip-topic-markers --skip-prefix --no-eval --batch-size 4 \
  --save models/output-dir

# Memory-efficient 31B (4-bit directions + bf16 shard-by-shard save)
heretic-python scripts/export_31b.py
Requirements
| Component | Version | Notes |
|---|---|---|
transformers | >= 5.10.1 for 12B (5.5.0 ok for the other 4) | gemma4_unified arch was added in 5.10.1; tested on 5.12.0 |
torch | 2.11.0+cu130 (tested) | — |
heretic-llm | git HEAD (reports 1.2.0) | PyPI pin breaks on Gemma 4 tokenizer; install from git |
| llama.cpp (GGUF) | build >= 2026-06-04 | Gemma4Unified GGUF support added in PR #24118; converter refactored into a conversion/ package. Earlier builds fail with Gemma4UnifiedForConditionalGeneration is not supported. Tested at commit c34b922. |
The original four models (E2B/E4B/26B-A4B/31B) were produced on transformers 5.5.0 and the pre-refactor llama.cpp converter. Only the 12B Unified model needs the newer toolchain above.
Scripts
| Script | Purpose |
|---|---|
abliterate.py | Experiment driver — Optuna search and biprojection modes |
ega.py | Expert-Granular Abliteration for MoE models |
export.py | Save weights, convert GGUF, push to HF |
export_31b.py | Memory-efficient 31B export (4-bit directions + bf16 shards) |
multi_eval.py | Cross-dataset validation (686 prompts, 4 datasets) |
dashboard.py | Scatter plot + bar chart of all experiment results |
sanity_check.py | Baseline vs abliterated quality comparison |
task_vector.py | Task vector negation (tested, ruled out) |
Key Findings
- Biprojection + EGA covers dense, MoE, and Unified — sub-1% refusal rate across all models
- Larger models absorb abliteration better — E4B KL=0.07 vs E2B KL=0.35; 12B is cleanest at KL=0.056
- MoE experts carry most refusal signal — dense-only gets 29/100, EGA gets 3/100
- Default refusal markers are broken — "illegal", "harmful" etc. match disclaimers, not refusals
- Task vector negation doesn't work — sharp phase transition, no usable middle ground
- 4-bit directions ≈ bf16 directions — mean cosine similarity 0.935, fine for abliteration
- The Unified arch needs care — refusal signal in upper layers only (abliterate 70%, not 100%); reserved-token
-inflogits NaN a naive KL (mask them); needstransformers >= 5.10.1and a recent llama.cpp for GGUF
Repo Structure
├── ABLITERATION.md    # Full research doc with tables and references
├── STATE.md           # Current best results per model
├── IDEAS.md           # Prioritized technique backlog
├── REDTEAM.md         # Red team benchmark survey
├── scripts/           # All experiment and export scripts
├── experiments/       # JSON results from every experiment
├── prompts/           # Eval datasets (150 iteration + 686 full)
├── models/            # Saved weights (gitignored)
└── checkpoints/       # Heretic Optuna checkpoints (gitignored)
License
Apache 2.0 (same as base Gemma 4 models).
Similar repos
Significant stargazers
282 followers · starred Jun 2026
Languages
Python
100.0%