RLLaVA is a user-friendly framework for multi-modal RL research and optimized for resource-constrained teams.
Python
57
45 commits
updated Oct 14, 2026
 Arxiv(RLLaVA) |
🤗 Models(RLLaVA) |
Blog(RLLaVA)
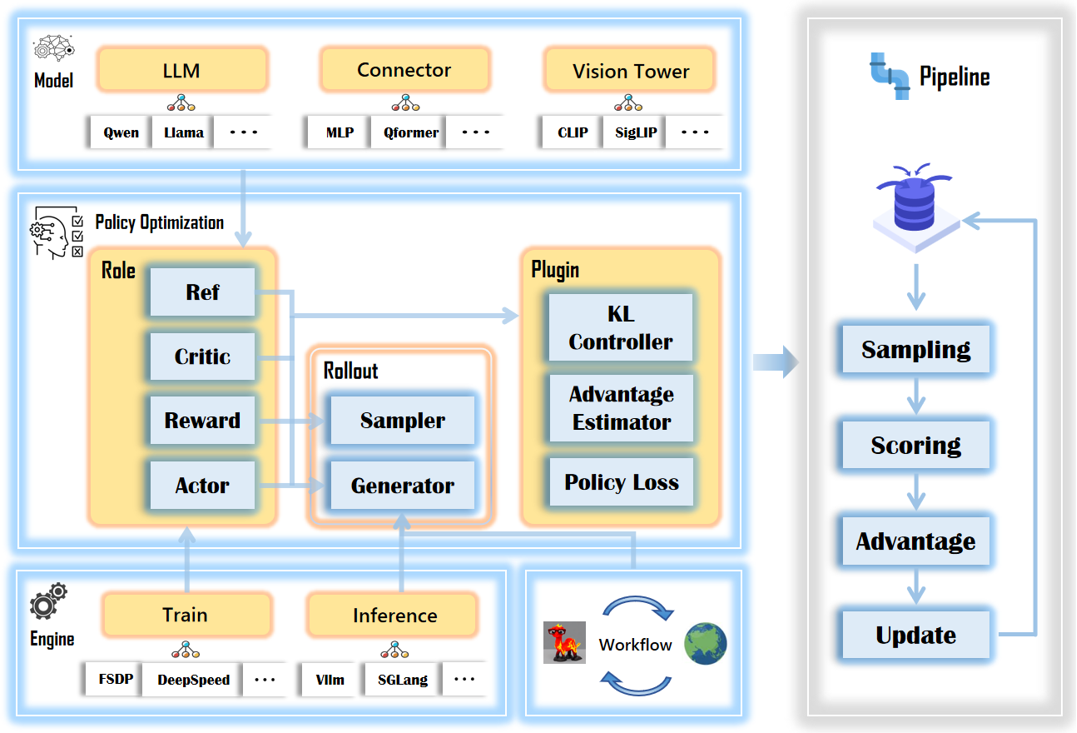
RLLaVA is a user-friendly framework for multi-modal RL. It features an RL-central design that decouples algorithm logic from distributed execution, enables modular customization of algorithms, models, and engines, and is optimized for resource-constrained setups to make advanced RL research more accessible.
git clone https://github.com/TinyLoopX/RLLaVA && cd RLLaVA

conda create -n rllava python==3.12 && conda activate rllava

bash ./install.sh
We provide ready-to-run scripts for various algorithms and tasks in the examples/ directory.
# Example: Train with GRPO
bash examples/algorithms/qwen2_5_vl_3b_geoqa3k_grpo.sh
You can explore more examples in the directory structure:
examples/
├── algorithms/      # Algorithm comparisons and ablations (GRPO, RLOO, DAPO, etc.)
└── tasks/           # End-to-end task scripts:
    ├── math/        # Geometry, reasoning, and equation solving
    ├── counting/    # Object counting and compositional queries
    ├── grounding/   # Visual grounding and detection-style tasks
    ├── agent_search/# Web search–augmented agents
    ├── agent_code/  # Code-generation agents with tool use
    └── ...          # More real-world multi-modal benchmarks
RLLaVA makes it easy to define custom tasks. You only need 3 files:
examples/reward_function/your_task.pyexamples/format_prompt/your_task.jinjatorchrun -m rllava.train.pipeline.rlvr \
config=examples/config.yaml \
data.train_files=your_org/dataset@train \
data.format_prompt=./examples/format_prompt/your_task.jinja \
reward.reward_function=./examples/reward_function/your_task.py:compute_score \
algorithm.adv_estimator=grpo # Switch algorithms here (rloo, remax, ppo, etc.)
For detailed usage instructions, please refer to examples/README.md
We support a broad family of RL methods, enabled by simple config switches:
Models:
Backends:
We welcome contributions! We're especially interested in new RL algorithms, multi-modal tasks, and resource-constrained improvements. Have questions? Join our WeChat group:
Our RL algorithms and distributed training implementation draw inspiration from the open-source community, particularly veRL, EasyR1, and AReaL.
@misc{zhao2025rllavarlcentralframeworklanguage,
      title={RLLaVA: An RL-central Framework for Language and Vision Assistants},
      author={Lei Zhao and Zihao Ma and Boyu Lin and Yuhe Liu and Wenjun Wu and Lei Huang},
      year={2025},
      eprint={2512.21450},
      archivePrefix={arXiv},
      primaryClass={cs.LG},
      url={https://arxiv.org/abs/2512.21450},
}
83 followers · starred Jan 2026
RLLaVA is a user-friendly framework for multi-modal RL research and optimized for resource-constrained teams.
Python
57
45 commits
updated Oct 14, 2026
Arxiv(RLLaVA) |
🤗 Models(RLLaVA) |
Blog(RLLaVA)
RLLaVA is a user-friendly framework for multi-modal RL. It features an RL-central design that decouples algorithm logic from distributed execution, enables modular customization of algorithms, models, and engines, and is optimized for resource-constrained setups to make advanced RL research more accessible.
git clone https://github.com/TinyLoopX/RLLaVA && cd RLLaVA

conda create -n rllava python==3.12 && conda activate rllava

bash ./install.sh
We provide ready-to-run scripts for various algorithms and tasks in the examples/ directory.
# Example: Train with GRPO
bash examples/algorithms/qwen2_5_vl_3b_geoqa3k_grpo.sh
You can explore more examples in the directory structure:
examples/
├── algorithms/      # Algorithm comparisons and ablations (GRPO, RLOO, DAPO, etc.)
└── tasks/           # End-to-end task scripts:
    ├── math/        # Geometry, reasoning, and equation solving
    ├── counting/    # Object counting and compositional queries
    ├── grounding/   # Visual grounding and detection-style tasks
    ├── agent_search/# Web search–augmented agents
    ├── agent_code/  # Code-generation agents with tool use
    └── ...          # More real-world multi-modal benchmarks
RLLaVA makes it easy to define custom tasks. You only need 3 files:
examples/reward_function/your_task.pyexamples/format_prompt/your_task.jinjatorchrun -m rllava.train.pipeline.rlvr \
config=examples/config.yaml \
data.train_files=your_org/dataset@train \
data.format_prompt=./examples/format_prompt/your_task.jinja \
reward.reward_function=./examples/reward_function/your_task.py:compute_score \
algorithm.adv_estimator=grpo # Switch algorithms here (rloo, remax, ppo, etc.)
For detailed usage instructions, please refer to examples/README.md
We support a broad family of RL methods, enabled by simple config switches:
Models:
Backends:
We welcome contributions! We're especially interested in new RL algorithms, multi-modal tasks, and resource-constrained improvements. Have questions? Join our WeChat group:
Our RL algorithms and distributed training implementation draw inspiration from the open-source community, particularly veRL, EasyR1, and AReaL.
@misc{zhao2025rllavarlcentralframeworklanguage,
      title={RLLaVA: An RL-central Framework for Language and Vision Assistants},
      author={Lei Zhao and Zihao Ma and Boyu Lin and Yuhe Liu and Wenjun Wu and Lei Huang},
      year={2025},
      eprint={2512.21450},
      archivePrefix={arXiv},
      primaryClass={cs.LG},
      url={https://arxiv.org/abs/2512.21450},
}
83 followers · starred Jan 2026



