[CVPR2026]🚀🚀🚀Official code for the paper "YOLO-Master: MOE-Accelerated with Specialized Transformers for Enhanced Real-time Detection." *(YOLO = You Only Look Once)* 🔥🔥🔥
See the code




YOLO-Master: MOE-Accelerated with Specialized Transformers for Enhanced Real-time Detection.
Xu Lin1*,
Jinlong Peng1*,
Zhenye Gan1,
Jiawen Zhu2,
Jun Liu1
1Tencent Youtu Lab 2Singapore Management University
*Equal Contribution
YOLO-Master is a YOLO-style framework tailored for Real-Time Object Detection (RTOD). It marks the first deep integration of Mixture-of-Experts (MoE) into the YOLO architecture for general datasets. By leveraging Efficient Sparse MoE (ES-MoE) and lightweight Dynamic Routing, the framework achieves instance-conditional adaptive computation. This "compute-on-demand" paradigm allows the model to allocate FLOPs based on scene complexity, reaching a superior Pareto frontier between high precision and ultra-low latency.
Key Highlights:
diagnose_model / prune_moe_model), CW-NMS, and Sparse SAHI inference modes."Exploring the frontiers of Dynamic Intelligence in YOLO."
This work represents our passionate exploration into the evolution of Real-Time Object Detection (RTOD). To the best of our knowledge, YOLO-Master is the first work to deeply integrate Mixture-of-Experts (MoE) with the YOLO architecture on general-purpose datasets.
Most existing YOLO models rely on static, dense computation—allocating the same computational budget to a simple sky background as they do to a complex, crowded intersection. We believe detection models should be more "adaptive", much like the human visual system. While this initial exploration may be not perfect, it demonstrates the significant potential of Efficient Sparse MoE (ES-MoE) in balancing high precision with ultra-low latency. We are committed to continuous iteration and optimization to refine this approach further.
Looking forward, we draw inspiration from the transformative advancements in LLMs and VLMs. We are committed to refining this approach and extending these insights to fundamental vision tasks, with the ultimate goal of tackling more ambitious frontiers like Open-Vocabulary Detection and Open-Set Segmentation.
To overcome this limitation, we propose YOLO-Master, a novel YOLO-like framework that introduces instance-conditional adaptive computation for RTOD. This is achieved through an Efficient Sparse Mixture-of-Experts (ES-MoE) block that dynamically allocates computational resources to each input according to its scene complexity. At its core, a lightweight dynamic routing network guides expert specialization during training through a diversity enhancing objective, encouraging complementary expertise among experts. Additionally, the routing network adaptively learns to activate only the most relevant experts, thereby improving detection performance while minimizing computational overhead during inference.
Comprehensive experiments on five large-scale benchmarks demonstrate the superiority of YOLO-Master. On MS COCO, our model achieves 42.4% AP with 1.62ms latency, outperforming YOLOv13-N by +0.8% mAP and 17.8% faster inference. Notably, the gains are most pronounced on challenging dense scenes, while the model preserves efficiency on typical inputs and maintains real-time inference speed. Code: Tencent/YOLO-Master
YOLO-Master introduces ES-MoE blocks to achieve "compute-on-demand" via dynamic routing.
For a deep dive into the design philosophy of MoE modules, detailed routing mechanisms, and optimization guides for deployment on various hardware (GPU/CPU/NPU), please refer to our Wiki: 👉 Wiki: MoE Modules Explained
reports/yolo-peft-2608.07051-anchor.json; verify with python scripts/reproduce_yolo_peft_paper.py --check-anchor.yolo-master-agent Skill with 50/50 test cases passing across 8 suites (quick / fast-smoke / cli-smoke / dry-run / contract / deep-smoke / extended / all). Fixed AttributeError from missing end2end field in default.yaml. Verified complete training → validation → inference pipeline with MPS auto-selection and workers=0 auto-completion. Skill runners: yolo.train, yolo.val, yolo.predict, yolo.benchmark, yolo.export, yolo.lora.diagnose, yolo.eval.peft_compare, yolo.multimodal.infer, yolo.system.doctor.ultralytics/cfg/models/master/v0_1/.C2fMoA wrapper and NeckMoAFusion cross-scale FPN/PAN fusion.yolo-master-agent Skill Bundle with SKILL.md, autotrain validation suite (50+ cases), multimodal evaluation, async evaluation, MPS auto-selection, dry-run/contract/smoke tiered validation, and VLM/LLM cooperative inference (OpenAI / DashScope compatible).
- diagnose_model: Visualize expert utilization and routing behavior to identify redundant experts.
- prune_moe_model: Physically excise redundant experts and reconstruct routers for efficient inference without retraining.
cluster: False # (bool) cluster NMS (MoE optimized)
Epoch GPU_mem box_loss cls_loss dfl_loss moe_loss Instances Size
Split MoE script into separate modules (routers, experts)
YOLO-Master introduces the first deep integration of Mixture-of-Experts into the YOLO architecture, enabling instance-conditional adaptive computation.
Core Components:
| Component | Description | Implementation |
|---|---|---|
| MoE Loss (MoELoss) | Load balancing loss + Z-Loss for stable training | ultralytics/nn/modules/moe/loss.py |
| MoE Pruning (MoEPruner) | Auto-prune low-utilization experts (20-30% speedup) | ultralytics/nn/modules/moe/pruning.py |
| Modular Architecture | Decoupled routers, experts, and gating mechanisms | ultralytics/nn/modules/moe/ |
Usage:
from ultralytics import YOLO

# Load MoE configuration
model = YOLO("ultralytics/cfg/models/master/v0_1/det/yolo-master-n.yaml")

# Training with MoE
results = model.train(
    data="coco8.yaml",
    epochs=100,
    imgsz=640,
    batch=16,
    moe_num_experts=8,      # Number of experts
    moe_top_k=2,            # Experts activated per token
    moe_balance_loss=0.01,  # Load balancing loss weight
)

# Expert utilization analysis & pruning
model.prune_experts(threshold=0.15)
💡 Looking for a plug-and-play ES-MoE module for all YOLO versions?
If you are seeking a convenient, pluggable
ES-MoEmodule integration for the full YOLO family, please refer to the community library: Lfan-ke/ES-MoE, ES-MoE for PyPI.
Architecture-agnostic LoRA adaptation with zero architectural overhead — enabled purely through configuration, no model surgery required.
LoRA vs Full SFT vs DoRA vs LoHa: Training curves comparison on YOLOv11-s (COCO val2017, 300 epochs)
Key Advantages:
Supported Models:
| Model Family | Architecture Type | LoRA Integration | Changes Required |
|---|---|---|---|
| YOLOv3 / v5 / v6 | CNN | Configuration-only | None ✅ |
| YOLOv8 / v9 / v10 | CNN | Configuration-only | None ✅ |
| YOLO11 / YOLO12 | CNN / Hybrid | Configuration-only | None ✅ |
| RT-DETR | Transformer-based | Configuration-only | None ✅ |
| YOLO-World | Multi-modal | Configuration-only | None ✅ |
| YOLO-Master | MoE | Configuration-only | None ✅ |
Usage:
from ultralytics import YOLO

model = YOLO("yolo11s.pt")

# LoRA training (one-click activation)
results = model.train(
    data="coco8.yaml",
    epochs=300,
    imgsz=640,
    batch=32,
    lora_r=16,                # rank=16, best cost-effectiveness
    lora_alpha=32,            # alpha = 2×r
    lora_dropout=0.1,
    lora_gradient_checkpointing=True,
)

# Save only LoRA adapters (~4.1MB for YOLO11s) to a directory
model.save_lora_only("yolo11s_lora_r16")
YOLO11 Series (LoRA rank=8):
| Model | Base Params (M) | LoRA Params | Base Size (MB) | Adapter Size (MB) | Param Ratio (%) |
|---|---|---|---|---|---|
| YOLO11n | 2.6 | 527,536 | 5.6 | 2.1 | 20.29% |
| YOLO11s | 9.4 | 1,016,240 | 19.3 | 4.1 | 10.81% |
| YOLO11m | 20.1 | 1,639,856 | 40.7 | 6.6 | 8.16% |
| YOLO11l | 25.3 | 2,350,512 | 51.4 | 9.4 | 9.29% |
| YOLO11x | 56.9 | 3,525,552 | 114.6 | 14.1 | 6.20% |
YOLO12 Series (LoRA rank=8):
| Model | Base Params (M) | LoRA Params | Base Size (MB) | Adapter Size (MB) | Param Ratio (%) |
|---|---|---|---|---|---|
| YOLO12n | 2.6 | 632,752 | 5.6 | 2.3 | 24.34% |
| YOLO12s | 9.3 | 1,077,680 | 19.0 | 4.3 | 11.59% |
| YOLO12m | 20.2 | 1,684,912 | 40.9 | 6.8 | 8.34% |
| YOLO12l | 26.4 | 2,442,160 | 53.7 | 9.8 | 9.25% |
| YOLO12x | 59.1 | 3,662,768 | 119.3 | 14.7 | 6.20% |
Practical Deployment Significance (YOLO11-X):
To verify the performance and resource consumption of the YOLO-Master LoRA framework across different downstream tasks, we conducted a cross-Rank matrix benchmark on the RTX 5070 Ti hardware platform using two typical scenarios (lightweight vs. extreme complexity).
| Evaluation Scenario (Dataset) | LoRA Rank | Trainable Params Ratio * | Total Training Time (Minutes) | Peak VRAM | mAP50 | mAP50-95 |
|---|---|---|---|---|---|---|
| Brain Tumor (Sparse, Small Dataset) | 4 | ~0.45% | 6.80 min | 1.01 GB | 0.5232 | 0.3863 |
| Brain Tumor (Sparse, Small Dataset) | 8 | ~0.89% | 6.58 min | 1.03 GB | 0.5133 | 0.3692 |
| Brain Tumor (Sparse, Small Dataset) | 16 | ~1.76% | 6.89 min | 1.08 GB | 0.4989 | 0.3744 |
| 📊 VisDrone (Dense, Extreme Scenario) | 4 | ~0.45% | 14.45 min | 7.92 GB | 0.1312 | 0.0679 |
| 📊 VisDrone (Dense, Extreme Scenario) | 8 | ~0.89% | 14.06 min | 7.95 GB | 0.1476 | 0.0781 |
| 📊 VisDrone (Dense, Extreme Scenario) | 16 | ~1.76% | 15.45 min | 8.01 GB | 0.1646 | 0.0872 |
* Note: The trainable parameter ratio is a theoretical estimate relative to the backbone's total parameters. Since Ultralytics automatically resets the gradient graph and triggers weight fusion after the training lifecycle ends, the runtime dynamic statistics remain silent.
** Selection Suggestions & Pitfalls to Avoid:**
ch=1 convolution configurations.rect: true during training. Furthermore, include both the Backbone's dimensionality reduction layers and MoE Experts' MLPs in lora_target_modules to provide sufficient degrees of freedom for spatial local features.Sparse Slicing Aided Hyper-Inference — a revolutionary optimization for ultra-large image (4K/8K) detection, achieving 3-5x speedup by intelligently skipping blank regions.
Sparse SAHI pipeline: Objectness Mask → Adaptive Slicing → High-Resolution Inference → CW-NMS Merging
Left: Skip ratio analysis across different scenes. Right: Real-world detection example.
How it works:
Usage:
from ultralytics import YOLO

model = YOLO("yolov8n.pt")

results = model.predict(
    source="large_aerial_image.jpg",
    sparse_sahi=True,
    slice_size=640,
    overlap_ratio=0.2,
    objectness_threshold=0.15,
)
Cluster-based detection box fusion algorithm using Gaussian-weighted averaging instead of hard suppression, significantly improving localization accuracy.
CW-NMS vs Traditional NMS vs Soft-NMS: Performance comparison on dense scenes
| Method | Strategy | Pros | Cons |
|---|---|---|---|
| Traditional NMS | Direct discard | Fast | May lose accurate localization |
| Soft-NMS | Confidence decay | Preserves candidates | Parameter-sensitive |
| CW-NMS | Gaussian-weighted fusion | High accuracy, robust | Slight computational increase |
from ultralytics import YOLO

model = YOLO("yolov8n.pt")
results = model.predict(
    source="dense_objects.jpg",
    cluster=True,     # Enable CW-NMS
    sigma=0.1,        # Gaussian weight σ
)
5️⃣ Mixture-of-Attention (MoA) Support
YOLO-Master introduces Mixture-of-Attention (MoA), a CNN-native multi-scale attention fusion mechanism. A lightweight 1×1 conv router assigns soft probabilities to each spatial token across three attention head groups with different receptive fields: Local (depthwise-3×3), Regional (pooled-stride=2), and Global (linear-attention). Zero sequence-dimension reshape, fully Flash-Attention compatible.
Key Features:
[B,C,H,W] → [B,C,H,W], no seq-dim reshape, compatible with all YOLO backbonesC2fMoA wrapper for direct C2f/C3k2 replacement; NeckMoAFusion for cross-scale FPN/PAN fusionUsage:
from ultralytics import YOLO

# Load MoA configuration
model = YOLO("ultralytics/cfg/models/master/v0_1/det/yolo-master-n.yaml")

# Training with MoA
results = model.train(
    data="coco8.yaml",
    epochs=100,
    imgsz=640,
    batch=16,
)
6️⃣ Mixture-of-Transformers (MoT) Support
YOLO-Master introduces Mixture-of-Transformers (MoT), a content-aware routing module that distributes tokens to specialized Transformer experts.
Three Expert Architectures:
Key Features:
Usage:
from ultralytics import YOLO

# Load MoT configuration
model = YOLO("ultralytics/cfg/models/master/v0_1/det/yolo-master-n.yaml")

# Training with MoT
results = model.train(
    data="coco8.yaml",
    epochs=100,
    imgsz=640,
    batch=16,
)
7️⃣ Agent Skill System
YOLO-Master introduces the yolo-master-agent Skill Bundle, enabling AI agents to orchestrate training, validation, inference, and evaluation through a structured Skill interface.
Key Features:
yolo.train, yolo.val, yolo.predict, yolo.benchmark, yolo.export, yolo.lora.diagnose, yolo.eval.peft_compare, yolo.multimodal.infer, yolo.system.doctorUsage:
# Via Python API
from ultralytics import YOLO
model = YOLO("yolo11n.pt")
results = model.train(data="coco8.yaml", epochs=1, imgsz=640)

# Via Skill CLI
python agent/scripts/run_yolo_master_skill.py \
    --json '{"skill":"yolo.train","inputs":{"model":"yolo11n.pt","data":"coco8.yaml"},"params":{"epochs":1,"imgsz":640}}'
Table 1. Comparison with state-of-the-art Nano-scale detectors across five benchmarks.
| Dataset | COCO | PASCAL VOC | VisDrone | KITTI | SKU-110K | Efficiency | |||||
|---|---|---|---|---|---|---|---|---|---|---|---|
| Method | mAP (%) | mAP50 (%) | mAP (%) | mAP50 (%) | mAP (%) | mAP50 (%) | mAP (%) | mAP50 (%) | mAP (%) | mAP50 (%) | Latency (ms) |
| YOLOv10 | 38.5 | 53.8 | 60.6 | 80.3 | 18.7 | 32.4 | 66.0 | 88.3 | 57.4 | 90.0 | 1.84 |
| YOLOv11-N | 39.4 | 55.3 | 61.0 | 81.2 | 18.5 | 32.2 | 67.8 | 89.8 | 57.4 | 90.0 | 1.50 |
| YOLOv12-N | 40.6 | 56.7 | 60.7 | 80.8 | 18.3 | 31.7 | 67.6 | 89.3 | 57.4 | 90.0 | 1.64 |
| YOLOv13-N | 41.6 | 57.8 | 60.7 | 80.3 | 17.5 | 30.6 | 67.7 | 90.6 | 57.5 | 90.3 | 1.97 |
| YOLO-Master-N | 42.4 | 59.2 | 62.1 | 81.9 | 19.6 | 33.7 | 69.2 | 91.3 | 58.2 | 90.6 | 1.62 |
| Model | Size | mAPbox (%) | mAPmask (%) | Gain (mAPmask) |
|---|---|---|---|---|
| YOLOv11-seg-N | 640 | 38.9 | 32.0 | - |
| YOLOv12-seg-N | 640 | 39.9 | 32.8 | Baseline |
| YOLO-Master-seg-N | 640 | 42.9 | 35.6 | +2.8% 🚀 |
| Model | Dataset | Input Size | Top-1 Acc (%) | Top-5 Acc (%) | Comparison |
|---|---|---|---|---|---|
| YOLOv11-cls-N | ImageNet | 224 | 70.0 | 89.4 | Baseline |
| YOLOv12-cls-N | ImageNet | 224 | 71.7 | 90.5 | +1.7% Top-1 |
| YOLO-Master-cls-N | ImageNet | 224 | 76.6 | 93.4 | +4.9% Top-1 🔥 |
Pretrained
.ptweights are synced from the YOLO-Master-v26.02 release.
| Model | Weights | Params(M) | GFLOPs(G) | Box(P) | R | mAP50 | mAP50-95 | Speed (4090 TRT) FPS |
|---|---|---|---|---|---|---|---|---|
| YOLO-Master-EsMoE-N | Weights | 2.68 | 8.7 | 0.684 | 0.536 | 0.587 | 0.427 | 640.18 |
| YOLO-Master-EsMoE-S | Weights | 9.69 | 29.1 | 0.699 | 0.603 | 0.603 | 0.489 | 423.87 |
| YOLO-Master-EsMoE-M | Weights | 34.88 | 97.4 | 0.737 | 0.640 | 0.697 | 0.530 | 243.79 |
| YOLO-Master-EsMoE-L | - | 🔥training | TBD | TBD | TBD | TBD | TBD | TBD |
| YOLO-Master-EsMoE-X | - | 🔥training | TBD | TBD | TBD | TBD | TBD | TBD |
| Model | Weights | Params(M) | GFLOPs(G) | Box(P) | R | mAP50 | mAP50-95 | Speed (4090 TRT) FPS |
|---|---|---|---|---|---|---|---|---|
| YOLO-Master-v0.1-N | Weights | 7.54 | 10.1 | 0.684 | 0.542 | 0.592 | 0.429 | 528.84 |
| YOLO-Master-v0.1-S | Weights | 29.15 | 36.0 | 0.724 | 0.607 | 0.662 | 0.489 | 345.24 |
| YOLO-Master-v0.1-M | Weights | 52.17 | 116.7 | 0.729 | 0.641 | 0.696 | 0.528 | 170.72 |
| YOLO-Master-v0.1-L | Weights | 58.41 | 138.1 | 0.739 | 0.646 | 0.705 | 0.539 | 149.86 |
| YOLO-Master-v0.1-X | - | 🔥training | TBD | TBD | TBD | TBD | TBD | TBD |
| Detection | | |
| Segmentation | | |
YOLO-Master builds upon the robust Ultralytics framework, inheriting support for various computer vision tasks. While our research primarily focuses on Real-Time Object Detection, the codebase is capable of supporting:
| Task | Status | Description |
|---|---|---|
| Object Detection | ✅ | Real-time object detection with ES-MoE acceleration. |
| Instance Segmentation | ✅ | Experimental support (inherited from Ultralytics). |
| Pose Estimation | 🚧 | Experimental support (inherited from Ultralytics). |
| OBB Detection | 🚧 | Experimental support (inherited from Ultralytics). |
| Classification | ✅ | Image classification support. |
# 1. Create and activate a new environment
conda create -n yolo_master python=3.11 -y
conda activate yolo_master

# 2. Clone the repository
git clone https://github.com/Tencent/YOLO-Master
cd YOLO-Master

# 3. Install dependencies
pip install -r requirements.txt
pip install -e .

# 4. Optional: Install FlashAttention for faster training (CUDA required)
pip install flash_attn
Validate the model accuracy on the COCO dataset.
from ultralytics import YOLO

# Load the pretrained model
model = YOLO("yolo_master_n.pt")

# Run validation
metrics = model.val(data="coco.yaml", save_json=True)
print(metrics.box.map)  # map50-95
Train a new model on your custom dataset or COCO.
from ultralytics import YOLO

# Load a model
model = YOLO('cfg/models/master/v0/det/yolo-master-n.yaml')  # build a new model from YAML

# Train the model
results = model.train(
    data='coco.yaml',
    epochs=600,
    batch=256,
    imgsz=640,
    device="0,1,2,3", # Use multiple GPUs
    scale=0.5,
    mosaic=1.0,
    mixup=0.0,
    copy_paste=0.1
)
Run inference on images or videos.
Python:
from ultralytics import YOLO

model = YOLO("yolo_master_n.pt")
results = model("path/to/image.jpg")
results[0].show()
CLI:
yolo predict model=yolo_master_n.pt source='path/to/image.jpg' show=True
Export the model to other formats for deployment (TensorRT, ONNX, etc.).
from ultralytics import YOLO

model = YOLO("yolo_master_n.pt")
model.export(format="engine", half=True)  # Export to TensorRT
# formats: onnx, openvino, engine, coreml, saved_model, pb, tflite, edgetpu, tfjs
Launch a local web interface to test the model interactively. This application provides a user-friendly Gradio dashboard for model inference, supporting automatic model scanning, task switching (Detection, Segmentation, Classification), and real-time visualization.
python start_studio.py
# Open http://127.0.0.1:7860 in your browser
This recommended launcher starts both the FastAPI Studio Job API and the Gradio WebUI. For manual two-process startup,
run python main_engine.py first and then python app.py in a second terminal. python app.py remains a Gradio-only
entrypoint and requires the API configured by F1_STUDIO_API_URL (default: http://127.0.0.1:8000).
We welcome contributions! Please check out our Contribution Guidelines for details on how to get involved.
This project is licensed under the GNU Affero General Public License v3.0 (AGPL-3.0).
This work builds upon the excellent Ultralytics framework. Huge thanks to the community for contributions, deployments, and tutorials!
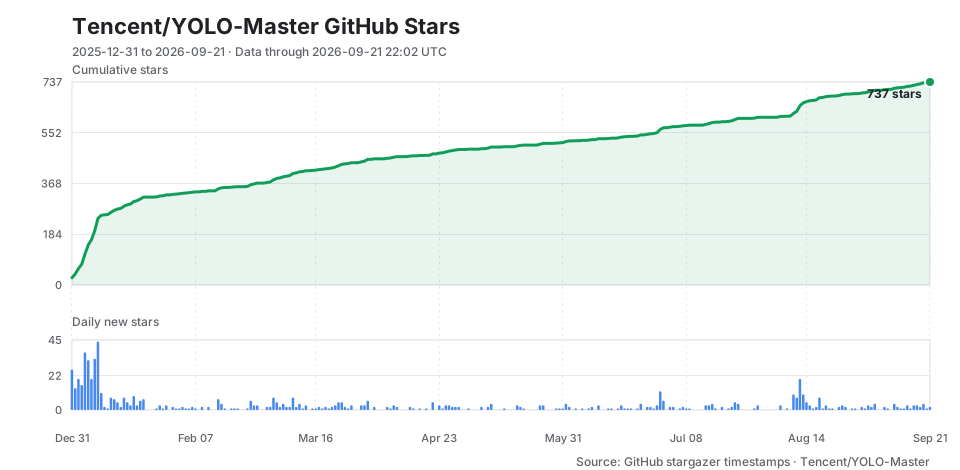
If you use YOLO-Master in your research, please cite our paper:
@inproceedings{lin2026yolomaster,
  title={{YOLO-Master}: MOE-Accelerated with Specialized Transformers for Enhanced Real-time Detection},
  author={Lin, Xu and Peng, Jinlong and Gan, Zhenye and Zhu, Jiawen and Liu, Jun},
  booktitle={Proceedings of the IEEE/CVF Conference on Computer Vision and Pattern Recognition (CVPR)},
  year={2026}
}
For the parameter-efficient fine-tuning work, please also cite:
@misc{lin2026yolopeft,
  title={YOLO-PEFT: Parameter-Efficient Fine-Tuning on YOLO Family},
  author={Lin, Xu and Nie, WenJie and Peng, Jinlong and Fu, Weifu and Ma, YueXiao and Zheng, Xiawu and Liu, Yong},
  year={2026},
  eprint={2608.07051},
  archivePrefix={arXiv},
  primaryClass={cs.CV},
  url={https://arxiv.org/abs/2608.07051}
}
⭐ If you find this work useful, please star the repository!
427 followers · starred Aug 2026
487 followers · starred Dec 2025
1,109 followers · starred Jan 2026
9,331 followers · starred Apr 2026
[CVPR2026]🚀🚀🚀Official code for the paper "YOLO-Master: MOE-Accelerated with Specialized Transformers for Enhanced Real-time Detection." *(YOLO = You Only Look Once)* 🔥🔥🔥
See the code
YOLO-Master: MOE-Accelerated with Specialized Transformers for Enhanced Real-time Detection.
Xu Lin1*,
Jinlong Peng1*,
Zhenye Gan1,
Jiawen Zhu2,
Jun Liu1
1Tencent Youtu Lab 2Singapore Management University
*Equal Contribution
YOLO-Master is a YOLO-style framework tailored for Real-Time Object Detection (RTOD). It marks the first deep integration of Mixture-of-Experts (MoE) into the YOLO architecture for general datasets. By leveraging Efficient Sparse MoE (ES-MoE) and lightweight Dynamic Routing, the framework achieves instance-conditional adaptive computation. This "compute-on-demand" paradigm allows the model to allocate FLOPs based on scene complexity, reaching a superior Pareto frontier between high precision and ultra-low latency.
Key Highlights:
diagnose_model / prune_moe_model), CW-NMS, and Sparse SAHI inference modes."Exploring the frontiers of Dynamic Intelligence in YOLO."
This work represents our passionate exploration into the evolution of Real-Time Object Detection (RTOD). To the best of our knowledge, YOLO-Master is the first work to deeply integrate Mixture-of-Experts (MoE) with the YOLO architecture on general-purpose datasets.
Most existing YOLO models rely on static, dense computation—allocating the same computational budget to a simple sky background as they do to a complex, crowded intersection. We believe detection models should be more "adaptive", much like the human visual system. While this initial exploration may be not perfect, it demonstrates the significant potential of Efficient Sparse MoE (ES-MoE) in balancing high precision with ultra-low latency. We are committed to continuous iteration and optimization to refine this approach further.
Looking forward, we draw inspiration from the transformative advancements in LLMs and VLMs. We are committed to refining this approach and extending these insights to fundamental vision tasks, with the ultimate goal of tackling more ambitious frontiers like Open-Vocabulary Detection and Open-Set Segmentation.
To overcome this limitation, we propose YOLO-Master, a novel YOLO-like framework that introduces instance-conditional adaptive computation for RTOD. This is achieved through an Efficient Sparse Mixture-of-Experts (ES-MoE) block that dynamically allocates computational resources to each input according to its scene complexity. At its core, a lightweight dynamic routing network guides expert specialization during training through a diversity enhancing objective, encouraging complementary expertise among experts. Additionally, the routing network adaptively learns to activate only the most relevant experts, thereby improving detection performance while minimizing computational overhead during inference.
Comprehensive experiments on five large-scale benchmarks demonstrate the superiority of YOLO-Master. On MS COCO, our model achieves 42.4% AP with 1.62ms latency, outperforming YOLOv13-N by +0.8% mAP and 17.8% faster inference. Notably, the gains are most pronounced on challenging dense scenes, while the model preserves efficiency on typical inputs and maintains real-time inference speed. Code: Tencent/YOLO-Master
YOLO-Master introduces ES-MoE blocks to achieve "compute-on-demand" via dynamic routing.
For a deep dive into the design philosophy of MoE modules, detailed routing mechanisms, and optimization guides for deployment on various hardware (GPU/CPU/NPU), please refer to our Wiki: 👉 Wiki: MoE Modules Explained
reports/yolo-peft-2608.07051-anchor.json; verify with python scripts/reproduce_yolo_peft_paper.py --check-anchor.yolo-master-agent Skill with 50/50 test cases passing across 8 suites (quick / fast-smoke / cli-smoke / dry-run / contract / deep-smoke / extended / all). Fixed AttributeError from missing end2end field in default.yaml. Verified complete training → validation → inference pipeline with MPS auto-selection and workers=0 auto-completion. Skill runners: yolo.train, yolo.val, yolo.predict, yolo.benchmark, yolo.export, yolo.lora.diagnose, yolo.eval.peft_compare, yolo.multimodal.infer, yolo.system.doctor.ultralytics/cfg/models/master/v0_1/.C2fMoA wrapper and NeckMoAFusion cross-scale FPN/PAN fusion.yolo-master-agent Skill Bundle with SKILL.md, autotrain validation suite (50+ cases), multimodal evaluation, async evaluation, MPS auto-selection, dry-run/contract/smoke tiered validation, and VLM/LLM cooperative inference (OpenAI / DashScope compatible).
- diagnose_model: Visualize expert utilization and routing behavior to identify redundant experts.
- prune_moe_model: Physically excise redundant experts and reconstruct routers for efficient inference without retraining.
cluster: False # (bool) cluster NMS (MoE optimized)
Epoch GPU_mem box_loss cls_loss dfl_loss moe_loss Instances Size
Split MoE script into separate modules (routers, experts)
YOLO-Master introduces the first deep integration of Mixture-of-Experts into the YOLO architecture, enabling instance-conditional adaptive computation.
Core Components:
| Component | Description | Implementation |
|---|---|---|
| MoE Loss (MoELoss) | Load balancing loss + Z-Loss for stable training | ultralytics/nn/modules/moe/loss.py |
| MoE Pruning (MoEPruner) | Auto-prune low-utilization experts (20-30% speedup) | ultralytics/nn/modules/moe/pruning.py |
| Modular Architecture | Decoupled routers, experts, and gating mechanisms | ultralytics/nn/modules/moe/ |
Usage:
from ultralytics import YOLO

# Load MoE configuration
model = YOLO("ultralytics/cfg/models/master/v0_1/det/yolo-master-n.yaml")

# Training with MoE
results = model.train(
    data="coco8.yaml",
    epochs=100,
    imgsz=640,
    batch=16,
    moe_num_experts=8,      # Number of experts
    moe_top_k=2,            # Experts activated per token
    moe_balance_loss=0.01,  # Load balancing loss weight
)

# Expert utilization analysis & pruning
model.prune_experts(threshold=0.15)
💡 Looking for a plug-and-play ES-MoE module for all YOLO versions?
If you are seeking a convenient, pluggable
ES-MoEmodule integration for the full YOLO family, please refer to the community library: Lfan-ke/ES-MoE, ES-MoE for PyPI.
Architecture-agnostic LoRA adaptation with zero architectural overhead — enabled purely through configuration, no model surgery required.
LoRA vs Full SFT vs DoRA vs LoHa: Training curves comparison on YOLOv11-s (COCO val2017, 300 epochs)
Key Advantages:
Supported Models:
| Model Family | Architecture Type | LoRA Integration | Changes Required |
|---|---|---|---|
| YOLOv3 / v5 / v6 | CNN | Configuration-only | None ✅ |
| YOLOv8 / v9 / v10 | CNN | Configuration-only | None ✅ |
| YOLO11 / YOLO12 | CNN / Hybrid | Configuration-only | None ✅ |
| RT-DETR | Transformer-based | Configuration-only | None ✅ |
| YOLO-World | Multi-modal | Configuration-only | None ✅ |
| YOLO-Master | MoE | Configuration-only | None ✅ |
Usage:
from ultralytics import YOLO

model = YOLO("yolo11s.pt")

# LoRA training (one-click activation)
results = model.train(
    data="coco8.yaml",
    epochs=300,
    imgsz=640,
    batch=32,
    lora_r=16,                # rank=16, best cost-effectiveness
    lora_alpha=32,            # alpha = 2×r
    lora_dropout=0.1,
    lora_gradient_checkpointing=True,
)

# Save only LoRA adapters (~4.1MB for YOLO11s) to a directory
model.save_lora_only("yolo11s_lora_r16")
YOLO11 Series (LoRA rank=8):
| Model | Base Params (M) | LoRA Params | Base Size (MB) | Adapter Size (MB) | Param Ratio (%) |
|---|---|---|---|---|---|
| YOLO11n | 2.6 | 527,536 | 5.6 | 2.1 | 20.29% |
| YOLO11s | 9.4 | 1,016,240 | 19.3 | 4.1 | 10.81% |
| YOLO11m | 20.1 | 1,639,856 | 40.7 | 6.6 | 8.16% |
| YOLO11l | 25.3 | 2,350,512 | 51.4 | 9.4 | 9.29% |
| YOLO11x | 56.9 | 3,525,552 | 114.6 | 14.1 | 6.20% |
YOLO12 Series (LoRA rank=8):
| Model | Base Params (M) | LoRA Params | Base Size (MB) | Adapter Size (MB) | Param Ratio (%) |
|---|---|---|---|---|---|
| YOLO12n | 2.6 | 632,752 | 5.6 | 2.3 | 24.34% |
| YOLO12s | 9.3 | 1,077,680 | 19.0 | 4.3 | 11.59% |
| YOLO12m | 20.2 | 1,684,912 | 40.9 | 6.8 | 8.34% |
| YOLO12l | 26.4 | 2,442,160 | 53.7 | 9.8 | 9.25% |
| YOLO12x | 59.1 | 3,662,768 | 119.3 | 14.7 | 6.20% |
Practical Deployment Significance (YOLO11-X):
To verify the performance and resource consumption of the YOLO-Master LoRA framework across different downstream tasks, we conducted a cross-Rank matrix benchmark on the RTX 5070 Ti hardware platform using two typical scenarios (lightweight vs. extreme complexity).
| Evaluation Scenario (Dataset) | LoRA Rank | Trainable Params Ratio * | Total Training Time (Minutes) | Peak VRAM | mAP50 | mAP50-95 |
|---|---|---|---|---|---|---|
| Brain Tumor (Sparse, Small Dataset) | 4 | ~0.45% | 6.80 min | 1.01 GB | 0.5232 | 0.3863 |
| Brain Tumor (Sparse, Small Dataset) | 8 | ~0.89% | 6.58 min | 1.03 GB | 0.5133 | 0.3692 |
| Brain Tumor (Sparse, Small Dataset) | 16 | ~1.76% | 6.89 min | 1.08 GB | 0.4989 | 0.3744 |
| 📊 VisDrone (Dense, Extreme Scenario) | 4 | ~0.45% | 14.45 min | 7.92 GB | 0.1312 | 0.0679 |
| 📊 VisDrone (Dense, Extreme Scenario) | 8 | ~0.89% | 14.06 min | 7.95 GB | 0.1476 | 0.0781 |
| 📊 VisDrone (Dense, Extreme Scenario) | 16 | ~1.76% | 15.45 min | 8.01 GB | 0.1646 | 0.0872 |
* Note: The trainable parameter ratio is a theoretical estimate relative to the backbone's total parameters. Since Ultralytics automatically resets the gradient graph and triggers weight fusion after the training lifecycle ends, the runtime dynamic statistics remain silent.
** Selection Suggestions & Pitfalls to Avoid:**
ch=1 convolution configurations.rect: true during training. Furthermore, include both the Backbone's dimensionality reduction layers and MoE Experts' MLPs in lora_target_modules to provide sufficient degrees of freedom for spatial local features.Sparse Slicing Aided Hyper-Inference — a revolutionary optimization for ultra-large image (4K/8K) detection, achieving 3-5x speedup by intelligently skipping blank regions.
Sparse SAHI pipeline: Objectness Mask → Adaptive Slicing → High-Resolution Inference → CW-NMS Merging
Left: Skip ratio analysis across different scenes. Right: Real-world detection example.
How it works:
Usage:
from ultralytics import YOLO

model = YOLO("yolov8n.pt")

results = model.predict(
    source="large_aerial_image.jpg",
    sparse_sahi=True,
    slice_size=640,
    overlap_ratio=0.2,
    objectness_threshold=0.15,
)
Cluster-based detection box fusion algorithm using Gaussian-weighted averaging instead of hard suppression, significantly improving localization accuracy.
CW-NMS vs Traditional NMS vs Soft-NMS: Performance comparison on dense scenes
| Method | Strategy | Pros | Cons |
|---|---|---|---|
| Traditional NMS | Direct discard | Fast | May lose accurate localization |
| Soft-NMS | Confidence decay | Preserves candidates | Parameter-sensitive |
| CW-NMS | Gaussian-weighted fusion | High accuracy, robust | Slight computational increase |
from ultralytics import YOLO

model = YOLO("yolov8n.pt")
results = model.predict(
    source="dense_objects.jpg",
    cluster=True,     # Enable CW-NMS
    sigma=0.1,        # Gaussian weight σ
)
5️⃣ Mixture-of-Attention (MoA) Support
YOLO-Master introduces Mixture-of-Attention (MoA), a CNN-native multi-scale attention fusion mechanism. A lightweight 1×1 conv router assigns soft probabilities to each spatial token across three attention head groups with different receptive fields: Local (depthwise-3×3), Regional (pooled-stride=2), and Global (linear-attention). Zero sequence-dimension reshape, fully Flash-Attention compatible.
Key Features:
[B,C,H,W] → [B,C,H,W], no seq-dim reshape, compatible with all YOLO backbonesC2fMoA wrapper for direct C2f/C3k2 replacement; NeckMoAFusion for cross-scale FPN/PAN fusionUsage:
from ultralytics import YOLO

# Load MoA configuration
model = YOLO("ultralytics/cfg/models/master/v0_1/det/yolo-master-n.yaml")

# Training with MoA
results = model.train(
    data="coco8.yaml",
    epochs=100,
    imgsz=640,
    batch=16,
)
6️⃣ Mixture-of-Transformers (MoT) Support
YOLO-Master introduces Mixture-of-Transformers (MoT), a content-aware routing module that distributes tokens to specialized Transformer experts.
Three Expert Architectures:
Key Features:
Usage:
from ultralytics import YOLO

# Load MoT configuration
model = YOLO("ultralytics/cfg/models/master/v0_1/det/yolo-master-n.yaml")

# Training with MoT
results = model.train(
    data="coco8.yaml",
    epochs=100,
    imgsz=640,
    batch=16,
)
7️⃣ Agent Skill System
YOLO-Master introduces the yolo-master-agent Skill Bundle, enabling AI agents to orchestrate training, validation, inference, and evaluation through a structured Skill interface.
Key Features:
yolo.train, yolo.val, yolo.predict, yolo.benchmark, yolo.export, yolo.lora.diagnose, yolo.eval.peft_compare, yolo.multimodal.infer, yolo.system.doctorUsage:
# Via Python API
from ultralytics import YOLO
model = YOLO("yolo11n.pt")
results = model.train(data="coco8.yaml", epochs=1, imgsz=640)

# Via Skill CLI
python agent/scripts/run_yolo_master_skill.py \
    --json '{"skill":"yolo.train","inputs":{"model":"yolo11n.pt","data":"coco8.yaml"},"params":{"epochs":1,"imgsz":640}}'
Table 1. Comparison with state-of-the-art Nano-scale detectors across five benchmarks.
| Dataset | COCO | PASCAL VOC | VisDrone | KITTI | SKU-110K | Efficiency | |||||
|---|---|---|---|---|---|---|---|---|---|---|---|
| Method | mAP (%) | mAP50 (%) | mAP (%) | mAP50 (%) | mAP (%) | mAP50 (%) | mAP (%) | mAP50 (%) | mAP (%) | mAP50 (%) | Latency (ms) |
| YOLOv10 | 38.5 | 53.8 | 60.6 | 80.3 | 18.7 | 32.4 | 66.0 | 88.3 | 57.4 | 90.0 | 1.84 |
| YOLOv11-N | 39.4 | 55.3 | 61.0 | 81.2 | 18.5 | 32.2 | 67.8 | 89.8 | 57.4 | 90.0 | 1.50 |
| YOLOv12-N | 40.6 | 56.7 | 60.7 | 80.8 | 18.3 | 31.7 | 67.6 | 89.3 | 57.4 | 90.0 | 1.64 |
| YOLOv13-N | 41.6 | 57.8 | 60.7 | 80.3 | 17.5 | 30.6 | 67.7 | 90.6 | 57.5 | 90.3 | 1.97 |
| YOLO-Master-N | 42.4 | 59.2 | 62.1 | 81.9 | 19.6 | 33.7 | 69.2 | 91.3 | 58.2 | 90.6 | 1.62 |
| Model | Size | mAPbox (%) | mAPmask (%) | Gain (mAPmask) |
|---|---|---|---|---|
| YOLOv11-seg-N | 640 | 38.9 | 32.0 | - |
| YOLOv12-seg-N | 640 | 39.9 | 32.8 | Baseline |
| YOLO-Master-seg-N | 640 | 42.9 | 35.6 | +2.8% 🚀 |
| Model | Dataset | Input Size | Top-1 Acc (%) | Top-5 Acc (%) | Comparison |
|---|---|---|---|---|---|
| YOLOv11-cls-N | ImageNet | 224 | 70.0 | 89.4 | Baseline |
| YOLOv12-cls-N | ImageNet | 224 | 71.7 | 90.5 | +1.7% Top-1 |
| YOLO-Master-cls-N | ImageNet | 224 | 76.6 | 93.4 | +4.9% Top-1 🔥 |
Pretrained
.ptweights are synced from the YOLO-Master-v26.02 release.
| Model | Weights | Params(M) | GFLOPs(G) | Box(P) | R | mAP50 | mAP50-95 | Speed (4090 TRT) FPS |
|---|---|---|---|---|---|---|---|---|
| YOLO-Master-EsMoE-N | Weights | 2.68 | 8.7 | 0.684 | 0.536 | 0.587 | 0.427 | 640.18 |
| YOLO-Master-EsMoE-S | Weights | 9.69 | 29.1 | 0.699 | 0.603 | 0.603 | 0.489 | 423.87 |
| YOLO-Master-EsMoE-M | Weights | 34.88 | 97.4 | 0.737 | 0.640 | 0.697 | 0.530 | 243.79 |
| YOLO-Master-EsMoE-L | - | 🔥training | TBD | TBD | TBD | TBD | TBD | TBD |
| YOLO-Master-EsMoE-X | - | 🔥training | TBD | TBD | TBD | TBD | TBD | TBD |
| Model | Weights | Params(M) | GFLOPs(G) | Box(P) | R | mAP50 | mAP50-95 | Speed (4090 TRT) FPS |
|---|---|---|---|---|---|---|---|---|
| YOLO-Master-v0.1-N | Weights | 7.54 | 10.1 | 0.684 | 0.542 | 0.592 | 0.429 | 528.84 |
| YOLO-Master-v0.1-S | Weights | 29.15 | 36.0 | 0.724 | 0.607 | 0.662 | 0.489 | 345.24 |
| YOLO-Master-v0.1-M | Weights | 52.17 | 116.7 | 0.729 | 0.641 | 0.696 | 0.528 | 170.72 |
| YOLO-Master-v0.1-L | Weights | 58.41 | 138.1 | 0.739 | 0.646 | 0.705 | 0.539 | 149.86 |
| YOLO-Master-v0.1-X | - | 🔥training | TBD | TBD | TBD | TBD | TBD | TBD |
| Detection | | |
| Segmentation | | |
YOLO-Master builds upon the robust Ultralytics framework, inheriting support for various computer vision tasks. While our research primarily focuses on Real-Time Object Detection, the codebase is capable of supporting:
| Task | Status | Description |
|---|---|---|
| Object Detection | ✅ | Real-time object detection with ES-MoE acceleration. |
| Instance Segmentation | ✅ | Experimental support (inherited from Ultralytics). |
| Pose Estimation | 🚧 | Experimental support (inherited from Ultralytics). |
| OBB Detection | 🚧 | Experimental support (inherited from Ultralytics). |
| Classification | ✅ | Image classification support. |
# 1. Create and activate a new environment
conda create -n yolo_master python=3.11 -y
conda activate yolo_master

# 2. Clone the repository
git clone https://github.com/Tencent/YOLO-Master
cd YOLO-Master

# 3. Install dependencies
pip install -r requirements.txt
pip install -e .

# 4. Optional: Install FlashAttention for faster training (CUDA required)
pip install flash_attn
Validate the model accuracy on the COCO dataset.
from ultralytics import YOLO

# Load the pretrained model
model = YOLO("yolo_master_n.pt")

# Run validation
metrics = model.val(data="coco.yaml", save_json=True)
print(metrics.box.map)  # map50-95
Train a new model on your custom dataset or COCO.
from ultralytics import YOLO

# Load a model
model = YOLO('cfg/models/master/v0/det/yolo-master-n.yaml')  # build a new model from YAML

# Train the model
results = model.train(
    data='coco.yaml',
    epochs=600,
    batch=256,
    imgsz=640,
    device="0,1,2,3", # Use multiple GPUs
    scale=0.5,
    mosaic=1.0,
    mixup=0.0,
    copy_paste=0.1
)
Run inference on images or videos.
Python:
from ultralytics import YOLO

model = YOLO("yolo_master_n.pt")
results = model("path/to/image.jpg")
results[0].show()
CLI:
yolo predict model=yolo_master_n.pt source='path/to/image.jpg' show=True
Export the model to other formats for deployment (TensorRT, ONNX, etc.).
from ultralytics import YOLO

model = YOLO("yolo_master_n.pt")
model.export(format="engine", half=True)  # Export to TensorRT
# formats: onnx, openvino, engine, coreml, saved_model, pb, tflite, edgetpu, tfjs
Launch a local web interface to test the model interactively. This application provides a user-friendly Gradio dashboard for model inference, supporting automatic model scanning, task switching (Detection, Segmentation, Classification), and real-time visualization.
python start_studio.py
# Open http://127.0.0.1:7860 in your browser
This recommended launcher starts both the FastAPI Studio Job API and the Gradio WebUI. For manual two-process startup,
run python main_engine.py first and then python app.py in a second terminal. python app.py remains a Gradio-only
entrypoint and requires the API configured by F1_STUDIO_API_URL (default: http://127.0.0.1:8000).
We welcome contributions! Please check out our Contribution Guidelines for details on how to get involved.
This project is licensed under the GNU Affero General Public License v3.0 (AGPL-3.0).
This work builds upon the excellent Ultralytics framework. Huge thanks to the community for contributions, deployments, and tutorials!
If you use YOLO-Master in your research, please cite our paper:
@inproceedings{lin2026yolomaster,
  title={{YOLO-Master}: MOE-Accelerated with Specialized Transformers for Enhanced Real-time Detection},
  author={Lin, Xu and Peng, Jinlong and Gan, Zhenye and Zhu, Jiawen and Liu, Jun},
  booktitle={Proceedings of the IEEE/CVF Conference on Computer Vision and Pattern Recognition (CVPR)},
  year={2026}
}
For the parameter-efficient fine-tuning work, please also cite:
@misc{lin2026yolopeft,
  title={YOLO-PEFT: Parameter-Efficient Fine-Tuning on YOLO Family},
  author={Lin, Xu and Nie, WenJie and Peng, Jinlong and Fu, Weifu and Ma, YueXiao and Zheng, Xiawu and Liu, Yong},
  year={2026},
  eprint={2608.07051},
  archivePrefix={arXiv},
  primaryClass={cs.CV},
  url={https://arxiv.org/abs/2608.07051}
}
⭐ If you find this work useful, please star the repository!
427 followers · starred Aug 2026
487 followers · starred Dec 2025
1,109 followers · starred Jan 2026
9,331 followers · starred Apr 2026