
[AAAI 2025] More Text, Less Point: Towards 3D Data-Efficient Point-Language Understanding
28
7 commits
updated Mar 20, 2026
README
More Text, Less Point: Towards 3D Data-Efficient Point-Language Understanding
Yuan Tang* Xu Han* Xianzhi Li✝ Qiao Yu Jinfeng Xu Yixue Hao Long Hu Min Chen
Huazhong University of Science and Technology South China University of Technology

📋 Contents
🔍 Overview
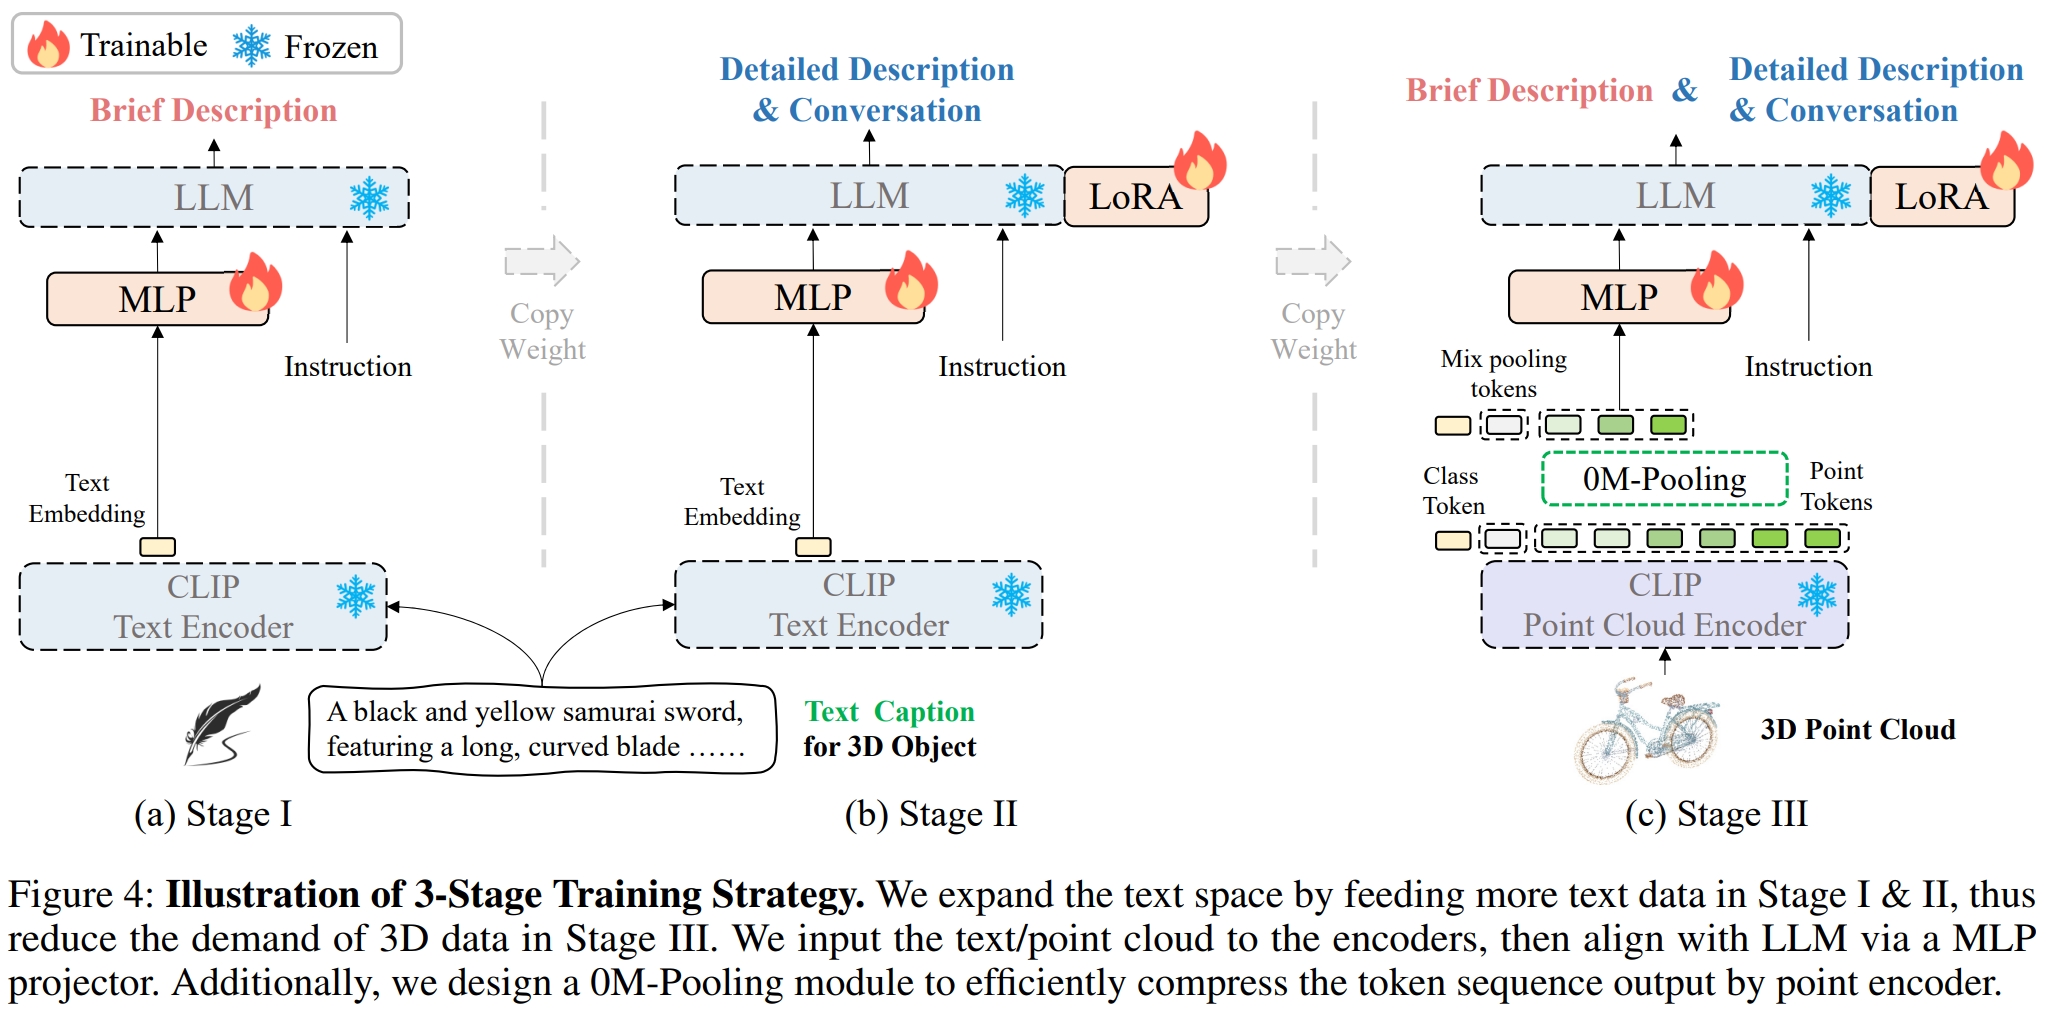
- We introduce a new task of 3D data-efficient point-language understanding, aiming to enable LLMs to achieve robust 3D understanding with minimal 3D data.
- We propose GreenPLM to tackle this 3D data-limited task from a novel perspective, enhancing point-LLM alignment with more free-text data.
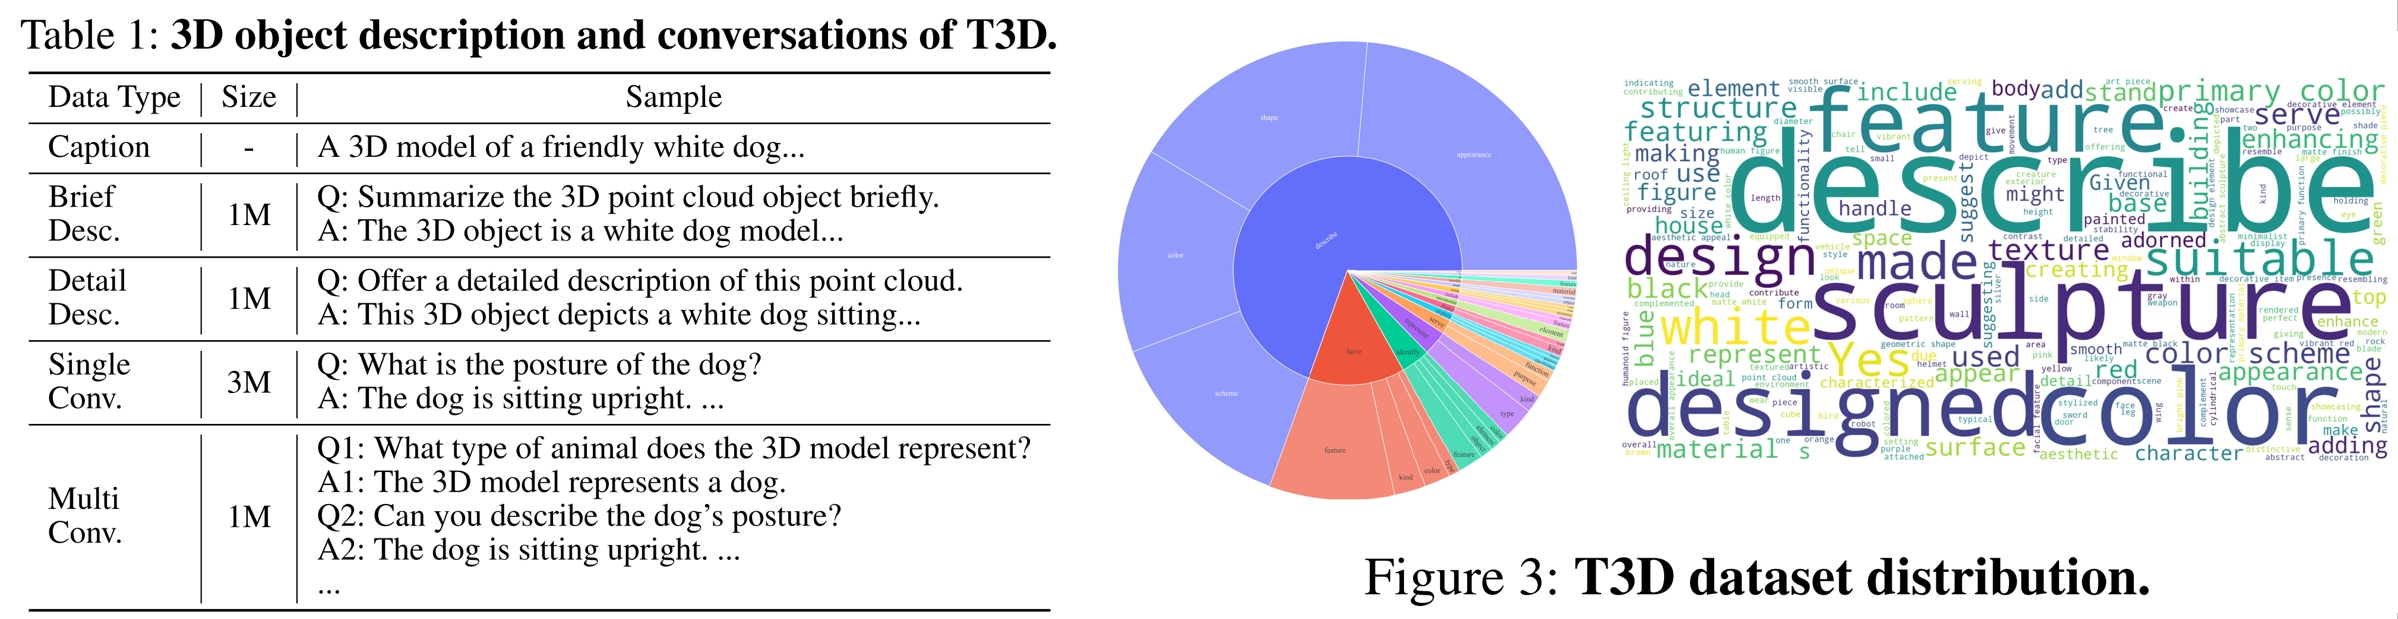
- we introduce a 6M T3D dataset, design a 3-stage training strategy, and present a 0M-Pooling module for token pooling.
- We introduce the Accuracy-to-3D-Data Ratio (A3DR) to measure the efficiency of 3D data usage and establish an evaluation benchmark based on open-source LLMs.
- GreenPLM outperforms previous models using only 12% of 3D data and even surpasses GPT4Point (660K 3D data) using only text, demonstrating superior 3D data efficiency.
📦 Training-and-Evaluation
Download project
The code, weights, and dataset of the project have already been uploaded to Hugging Face. Simply download them once to get started with the project.
Install Environment
Enter the project directory and execute the following command:
conda create -n greenplm python=3.10 -y
conda activate greenplm
bash  envInstall.sh
Project Directory Introduction
./greenplm/releasecontains the paper's weights, training scripts, and testing scripts../pretrained_weightstores the pre-trained weights required for the training and testing phases of the project../lava-vicuna_2024_4_Phi-3-mini-4k-instructis the weight directory for Phi-3../dataset/T3Dis the 6M T3D dataset proposed in this project../dataset/T3D/stage_1/brief_1M_caption.jsonis the dataset from T3D for Stage I../dataset/T3D/stage_2/stage_2_data_210k.jsonis the dataset from T3D for Stage II.
Dataset Preparation
./dataset/Objaverse/8192_npy.zip contains the point cloud data from Objaverse that is required for this project. To unzip the dataset:
unzip ./dataset/Objaverse/8192_npy.zip -d ./dataset/Objaverse/
Inference
Paper Weights
GreenPLM-0
The model trained only on text data, i.e., (Stage I & Stage II).
bash ./release/paper/scripts/test/release_stage_2.sh
The output JSON results are saved in ./release/paper/result_json/stage_2.
GreenPLM
The model trained on a small amount of 3D data, i.e., (Stage I & Stage II & Stage III).
bash ./release/paper/scripts/test/release_stage_3.sh
The output JSON results are saved in ./release/paper/result_json/stage_3.
Weights Using All T3D Dataset
We also provide weights trained using the entire T3D dataset, meaning we use 5M data from T3D in Stage II, instead of just 210k as in our paper. (click to expand)
GreenPLM-0
The model trained only on text data, i.e., (Stage I & Stage II).
bash ./release/5M_data_seting/scripts/test/release_5M_stage_2.sh
The output JSON results are saved in ./release/5M_data_seting/result_json/stage_2.
GreenPLM
The model trained on a small amount of 3D data, i.e., (Stage I & Stage II & Stage III).
bash ./release/5M_data_seting/scripts/test/release_5M_stage_3.sh
The output JSON results are saved in ./release/5M_data_seting/result_json/stage_3.
Evaluation
Using LLM
- You can get the DASHSCOPE_API_KEY from aliyun. The evaluation may require 9 CNY (~ 1.3 USD).
- If you have enough GPU resources, you can also build your own Qwen2-72B-Instruct service, following the Qwen2. Then evaluate the results for free!
- Evaluate the open vocabulary classification on objaverse
export PYTHONPATH=$PWD
export DASHSCOPE_API_KEY=sk-xxx
python ./pointllm/eval/evaluator_opensource_llm_QwenAPI.py  \
        --results_path /path/to/evaluation/PointLLM_brief_description_val_200_GT_Objaverse_classification_prompt0.json  \
        --eval_type open-free-form-classification  \
        --model_type qwen2-72b-instruct \
        --parallel --num_workers 4
export PYTHONPATH=$PWD
export DASHSCOPE_API_KEY=sk-xxx
python ./pointllm/eval/evaluator_opensource_llm_QwenAPI.py  \
        --results_path /path/to/evaluation/PointLLM_brief_description_val_200_GT_Objaverse_classification_prompt1.json  \
        --eval_type open-free-form-classification  \
        --model_type qwen2-72b-instruct \
        --parallel --num_workers 4
- Evaluate the close-set zero-shot classification on ModelNet40
export PYTHONPATH=$PWD
export DASHSCOPE_API_KEY=sk-xxx
python ./pointllm/eval/evaluator_opensource_llm_QwenAPI.py  \
    --results_path /path/to/evaluation/ModelNet_classification_prompt0.json  \
    --eval_type modelnet-close-set-classification  \
    --model_type qwen2-72b-instruct \
    --parallel --num_workers 4
export PYTHONPATH=$PWD
export DASHSCOPE_API_KEY=sk-xxx
python ./pointllm/eval/evaluator_opensource_llm_QwenAPI.py  \
    --results_path /path/to/evaluation/ModelNet_classification_prompt1.json  \
    --eval_type modelnet-close-set-classification  \
    --model_type qwen2-72b-instruct \
    --parallel --num_workers 4
- Evaluate the object captioning on objaverse
export PYTHONPATH=$PWD
export DASHSCOPE_API_KEY=sk-xxx
python ./pointllm/eval/evaluator_opensource_llm_QwenAPI.py  \
        --results_path /path/to/evaluation/PointLLM_brief_description_val_200_GT_Objaverse_captioning_prompt2.json  \
        --eval_type object-captioning  \
        --model_type qwen2-72b-instruct \
        --parallel --num_workers 4
Traditional Metric Evaluation
For the object captioning task, run the following command to evaluate model outputs with traditional metrics Sentence-BERT and SimCSE.
CUDA_VISIBLE_DEVICES=0 python pointllm/eval/traditional_evaluator.py --results_path /path/to/evaluation/PointLLM_brief_description_val_200_GT_Objaverse_captioning_prompt2.json
Training
Stage I
bash ./release/paper/scripts/train/1.sh
Stage II: GreenPLM-0
bash ./release/paper/scripts/train/2.sh
Stage III: GreenPLM
bash ./release/paper/scripts/train/3.sh
We also provide training scripts using the entire T3D dataset, meaning we use 5M data from T3D in Stage II, instead of just 210k as in our paper. (click to expand)
Stage II: GreenPLM-0
bash ./release/5M_data_seting/scripts/train/2.sh
Stage III: GreenPLM
bash ./release/5M_data_seting/scripts/train/3.sh
Note: You can modify the --output_dir argument in the scripts to set the output directory for the trained weights.
🔗 Citation
If you find our work helpful, please consider citing:
@inproceedings{tang2025more,
  title={More text, less point: Towards 3d data-efficient point-language understanding},
  author={Tang, Yuan and Han, Xu and Li, Xianzhi and Yu, Qiao and Xu, Jinfeng and Hao, Yixue and Hu, Long and Chen, Min},
  booktitle={Proceedings of the AAAI Conference on Artificial Intelligence},
  volume={39},
  number={7},
  pages={7284--7292},
  year={2025}
}
📄 License

This work is under the Creative Commons Attribution-NonCommercial-ShareAlike 4.0 International License.
📚 Related Work
Together, Let's make LLM for 3D great!
- Point-Bind & Point-LLM: aligns point clouds with Image-Bind to reason multi-modality input without 3D-instruction data training.
- 3D-LLM: employs 2D foundation models to encode multi-view images of 3D point clouds.
- PointLLM: employs 3D point clouds with LLaVA.
- ShapeLLM: combines a powerful point cloud encoder with LLM for embodied scenes.
- MiniGPT-3D : takes the first step toward efficient 3D-LLM, requiring only a single RTX 3090 GPU and one day of training time.
🌟 Star History
👏 Acknowledgements
We would like to thank the authors of PointLLM, Uni3D, Phi-3, and LLaVA-pp for their great works and repos.
Similar repos


[AAAI 2025] More Text, Less Point: Towards 3D Data-Efficient Point-Language Understanding
28
7 commits
updated Mar 20, 2026
README
More Text, Less Point: Towards 3D Data-Efficient Point-Language Understanding
Yuan Tang* Xu Han* Xianzhi Li✝ Qiao Yu Jinfeng Xu Yixue Hao Long Hu Min Chen
Huazhong University of Science and Technology South China University of Technology
📋 Contents
🔍 Overview
- We introduce a new task of 3D data-efficient point-language understanding, aiming to enable LLMs to achieve robust 3D understanding with minimal 3D data.
- We propose GreenPLM to tackle this 3D data-limited task from a novel perspective, enhancing point-LLM alignment with more free-text data.
- we introduce a 6M T3D dataset, design a 3-stage training strategy, and present a 0M-Pooling module for token pooling.
- We introduce the Accuracy-to-3D-Data Ratio (A3DR) to measure the efficiency of 3D data usage and establish an evaluation benchmark based on open-source LLMs.
- GreenPLM outperforms previous models using only 12% of 3D data and even surpasses GPT4Point (660K 3D data) using only text, demonstrating superior 3D data efficiency.
📦 Training-and-Evaluation
Download project
The code, weights, and dataset of the project have already been uploaded to Hugging Face. Simply download them once to get started with the project.
Install Environment
Enter the project directory and execute the following command:
conda create -n greenplm python=3.10 -y
conda activate greenplm
bash  envInstall.sh
Project Directory Introduction
./greenplm/releasecontains the paper's weights, training scripts, and testing scripts../pretrained_weightstores the pre-trained weights required for the training and testing phases of the project../lava-vicuna_2024_4_Phi-3-mini-4k-instructis the weight directory for Phi-3../dataset/T3Dis the 6M T3D dataset proposed in this project../dataset/T3D/stage_1/brief_1M_caption.jsonis the dataset from T3D for Stage I../dataset/T3D/stage_2/stage_2_data_210k.jsonis the dataset from T3D for Stage II.
Dataset Preparation
./dataset/Objaverse/8192_npy.zip contains the point cloud data from Objaverse that is required for this project. To unzip the dataset:
unzip ./dataset/Objaverse/8192_npy.zip -d ./dataset/Objaverse/
Inference
Paper Weights
GreenPLM-0
The model trained only on text data, i.e., (Stage I & Stage II).
bash ./release/paper/scripts/test/release_stage_2.sh
The output JSON results are saved in ./release/paper/result_json/stage_2.
GreenPLM
The model trained on a small amount of 3D data, i.e., (Stage I & Stage II & Stage III).
bash ./release/paper/scripts/test/release_stage_3.sh
The output JSON results are saved in ./release/paper/result_json/stage_3.
Weights Using All T3D Dataset
We also provide weights trained using the entire T3D dataset, meaning we use 5M data from T3D in Stage II, instead of just 210k as in our paper. (click to expand)
GreenPLM-0
The model trained only on text data, i.e., (Stage I & Stage II).
bash ./release/5M_data_seting/scripts/test/release_5M_stage_2.sh
The output JSON results are saved in ./release/5M_data_seting/result_json/stage_2.
GreenPLM
The model trained on a small amount of 3D data, i.e., (Stage I & Stage II & Stage III).
bash ./release/5M_data_seting/scripts/test/release_5M_stage_3.sh
The output JSON results are saved in ./release/5M_data_seting/result_json/stage_3.
Evaluation
Using LLM
- You can get the DASHSCOPE_API_KEY from aliyun. The evaluation may require 9 CNY (~ 1.3 USD).
- If you have enough GPU resources, you can also build your own Qwen2-72B-Instruct service, following the Qwen2. Then evaluate the results for free!
- Evaluate the open vocabulary classification on objaverse
export PYTHONPATH=$PWD
export DASHSCOPE_API_KEY=sk-xxx
python ./pointllm/eval/evaluator_opensource_llm_QwenAPI.py  \
        --results_path /path/to/evaluation/PointLLM_brief_description_val_200_GT_Objaverse_classification_prompt0.json  \
        --eval_type open-free-form-classification  \
        --model_type qwen2-72b-instruct \
        --parallel --num_workers 4
export PYTHONPATH=$PWD
export DASHSCOPE_API_KEY=sk-xxx
python ./pointllm/eval/evaluator_opensource_llm_QwenAPI.py  \
        --results_path /path/to/evaluation/PointLLM_brief_description_val_200_GT_Objaverse_classification_prompt1.json  \
        --eval_type open-free-form-classification  \
        --model_type qwen2-72b-instruct \
        --parallel --num_workers 4
- Evaluate the close-set zero-shot classification on ModelNet40
export PYTHONPATH=$PWD
export DASHSCOPE_API_KEY=sk-xxx
python ./pointllm/eval/evaluator_opensource_llm_QwenAPI.py  \
    --results_path /path/to/evaluation/ModelNet_classification_prompt0.json  \
    --eval_type modelnet-close-set-classification  \
    --model_type qwen2-72b-instruct \
    --parallel --num_workers 4
export PYTHONPATH=$PWD
export DASHSCOPE_API_KEY=sk-xxx
python ./pointllm/eval/evaluator_opensource_llm_QwenAPI.py  \
    --results_path /path/to/evaluation/ModelNet_classification_prompt1.json  \
    --eval_type modelnet-close-set-classification  \
    --model_type qwen2-72b-instruct \
    --parallel --num_workers 4
- Evaluate the object captioning on objaverse
export PYTHONPATH=$PWD
export DASHSCOPE_API_KEY=sk-xxx
python ./pointllm/eval/evaluator_opensource_llm_QwenAPI.py  \
        --results_path /path/to/evaluation/PointLLM_brief_description_val_200_GT_Objaverse_captioning_prompt2.json  \
        --eval_type object-captioning  \
        --model_type qwen2-72b-instruct \
        --parallel --num_workers 4
Traditional Metric Evaluation
For the object captioning task, run the following command to evaluate model outputs with traditional metrics Sentence-BERT and SimCSE.
CUDA_VISIBLE_DEVICES=0 python pointllm/eval/traditional_evaluator.py --results_path /path/to/evaluation/PointLLM_brief_description_val_200_GT_Objaverse_captioning_prompt2.json
Training
Stage I
bash ./release/paper/scripts/train/1.sh
Stage II: GreenPLM-0
bash ./release/paper/scripts/train/2.sh
Stage III: GreenPLM
bash ./release/paper/scripts/train/3.sh
We also provide training scripts using the entire T3D dataset, meaning we use 5M data from T3D in Stage II, instead of just 210k as in our paper. (click to expand)
Stage II: GreenPLM-0
bash ./release/5M_data_seting/scripts/train/2.sh
Stage III: GreenPLM
bash ./release/5M_data_seting/scripts/train/3.sh
Note: You can modify the --output_dir argument in the scripts to set the output directory for the trained weights.
🔗 Citation
If you find our work helpful, please consider citing:
@inproceedings{tang2025more,
  title={More text, less point: Towards 3d data-efficient point-language understanding},
  author={Tang, Yuan and Han, Xu and Li, Xianzhi and Yu, Qiao and Xu, Jinfeng and Hao, Yixue and Hu, Long and Chen, Min},
  booktitle={Proceedings of the AAAI Conference on Artificial Intelligence},
  volume={39},
  number={7},
  pages={7284--7292},
  year={2025}
}
📄 License
This work is under the Creative Commons Attribution-NonCommercial-ShareAlike 4.0 International License.
📚 Related Work
Together, Let's make LLM for 3D great!
- Point-Bind & Point-LLM: aligns point clouds with Image-Bind to reason multi-modality input without 3D-instruction data training.
- 3D-LLM: employs 2D foundation models to encode multi-view images of 3D point clouds.
- PointLLM: employs 3D point clouds with LLaVA.
- ShapeLLM: combines a powerful point cloud encoder with LLM for embodied scenes.
- MiniGPT-3D : takes the first step toward efficient 3D-LLM, requiring only a single RTX 3090 GPU and one day of training time.
🌟 Star History
👏 Acknowledgements
We would like to thank the authors of PointLLM, Uni3D, Phi-3, and LLaVA-pp for their great works and repos.