SAM-PT: Extending SAM to zero-shot video segmentation with point-based tracking.
See the codeSegment Anything Meets Point Tracking
Frano Rajič, Lei Ke, Yu-Wing Tai, Chi-Keung Tang, Martin Danelljan, Fisher Yu
ETH Zürich, HKUST, EPFL
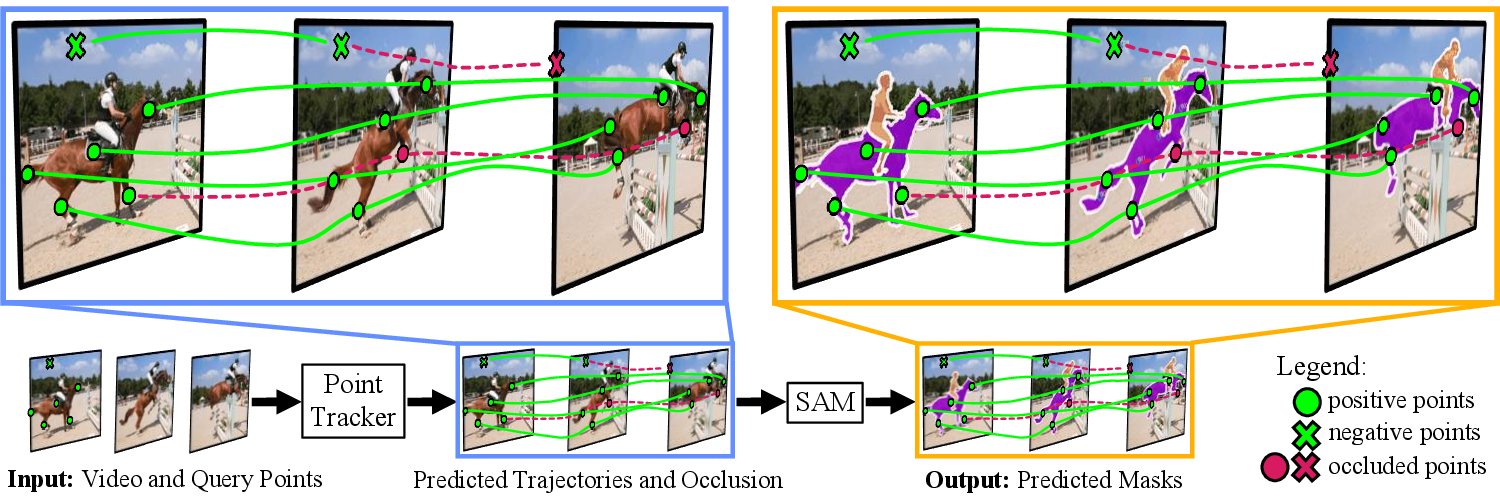
We propose SAM-PT, an extension of the Segment Anything Model (SAM) for zero-shot video segmentation. Our work offers a simple yet effective point-based perspective in video object segmentation research. For more details, refer to our paper.
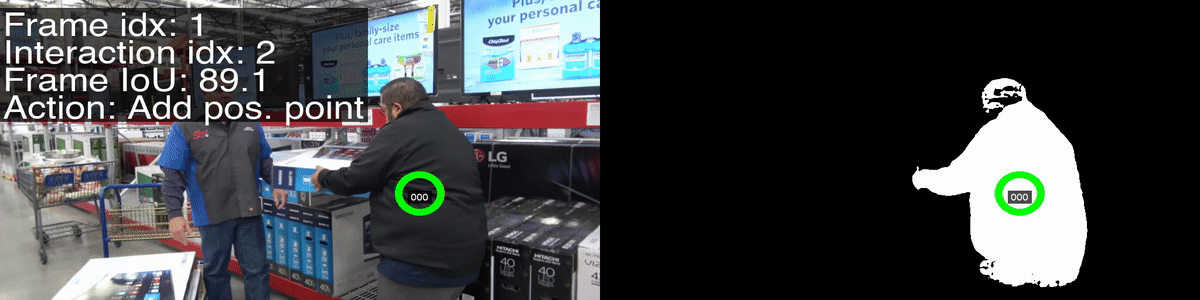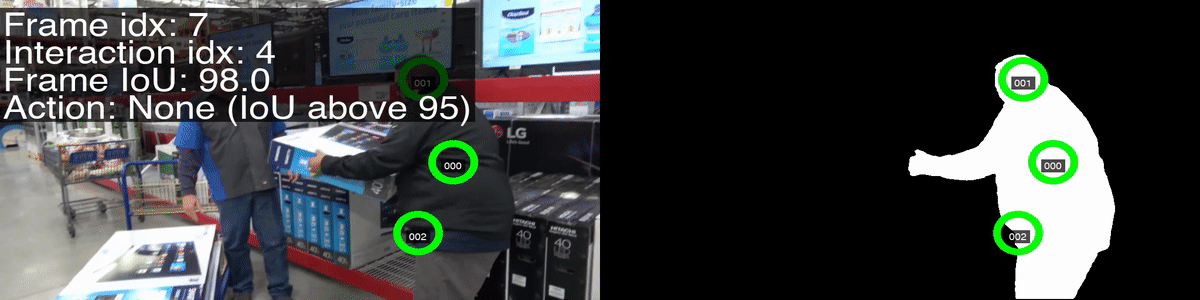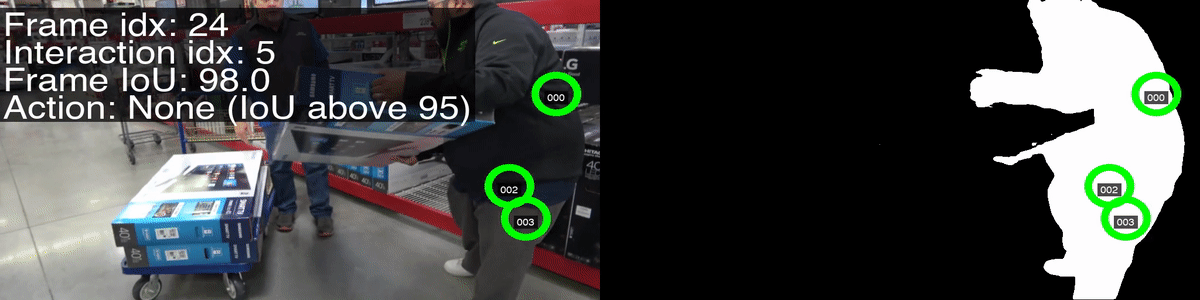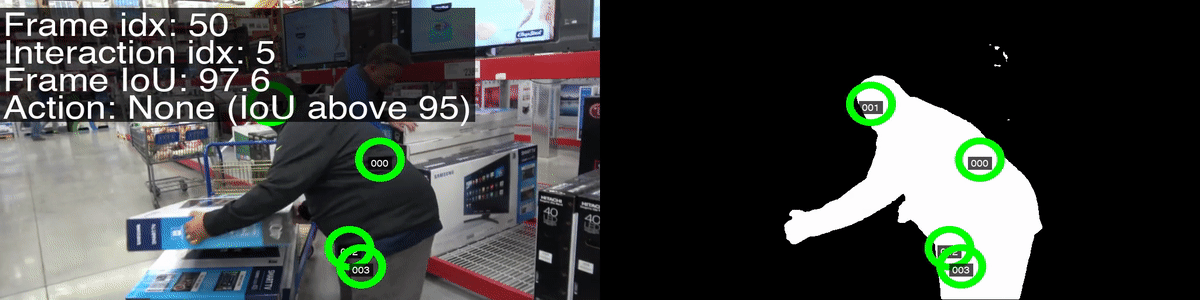
Annotators only provide a few points to denote the target object at the first video frame to get video segmentation results. Please visit our project page for more visualizations, including qualitative results on DAVIS 2017 videos and more Avatar clips.
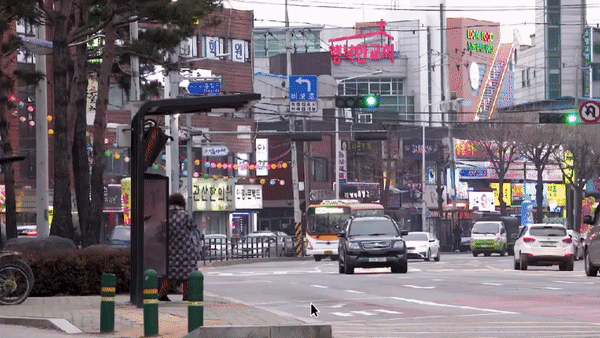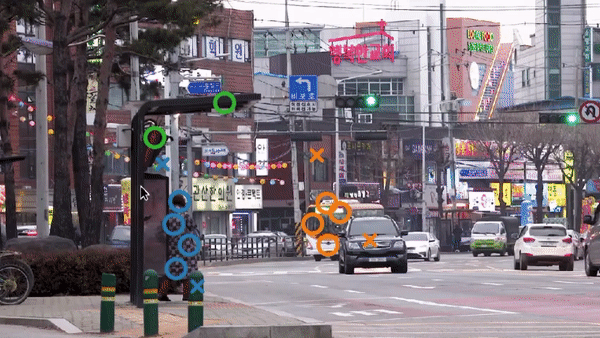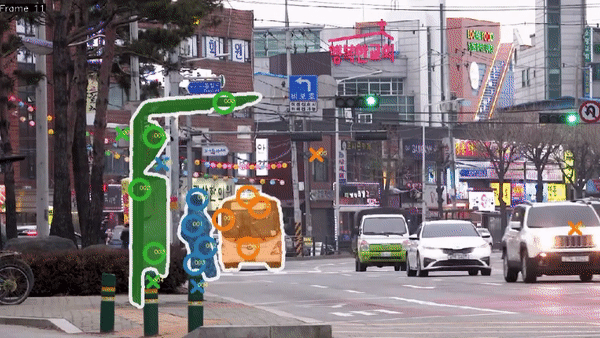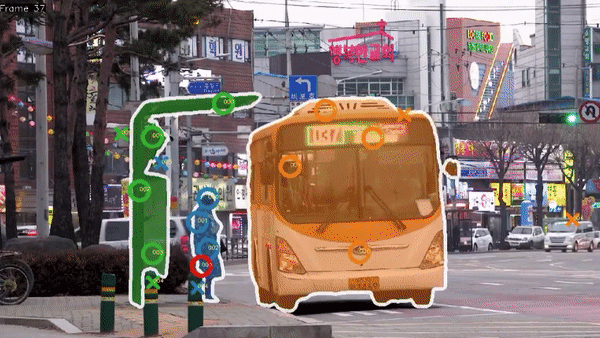
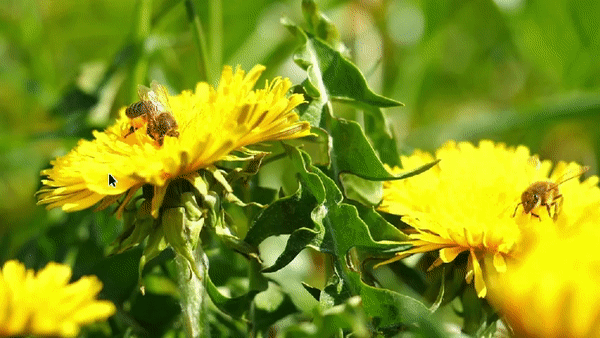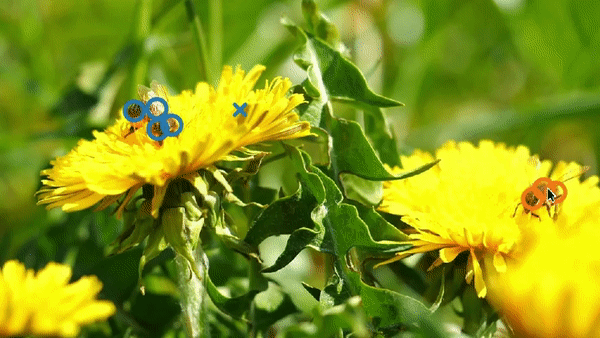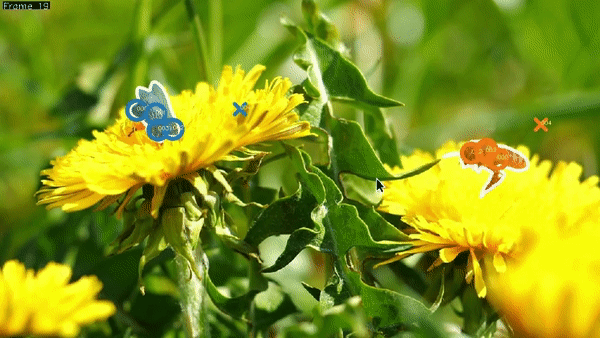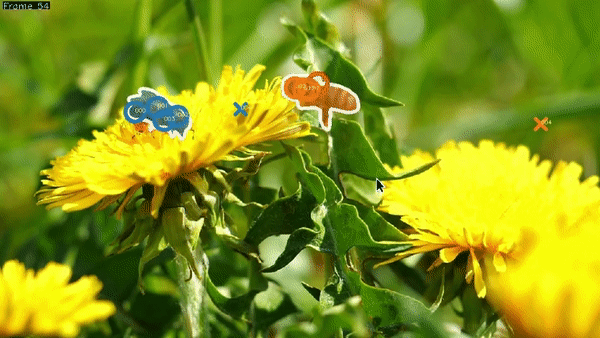
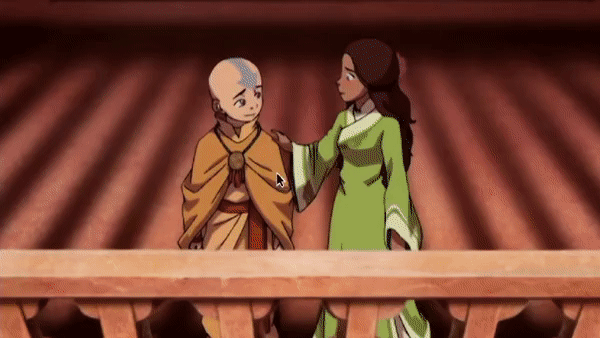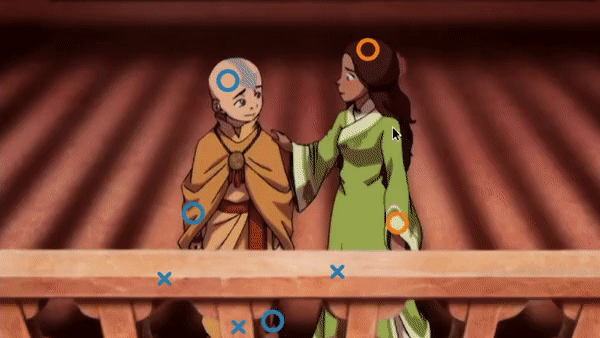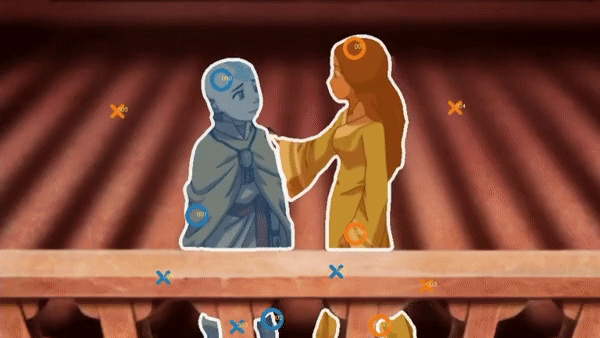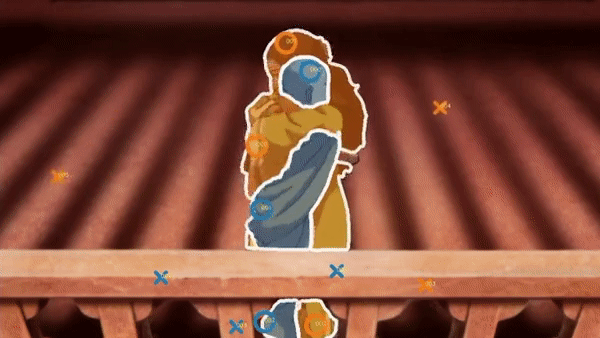
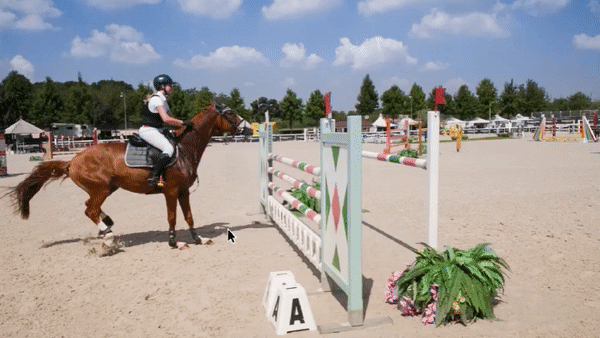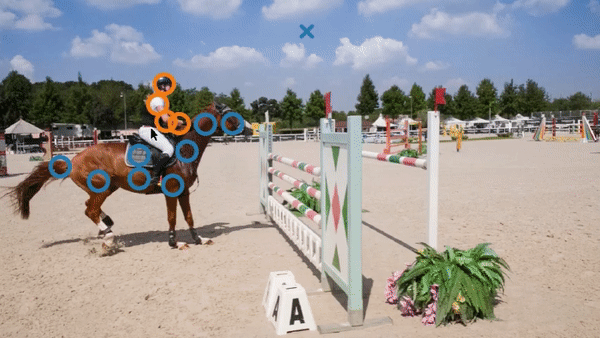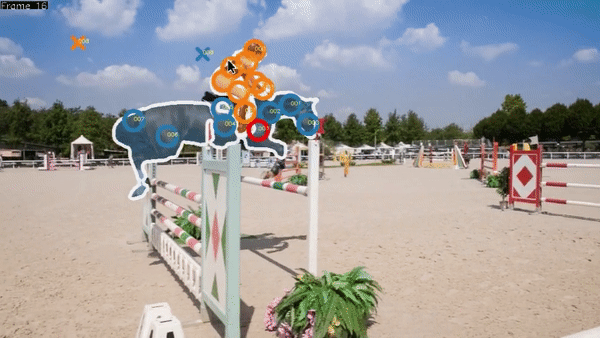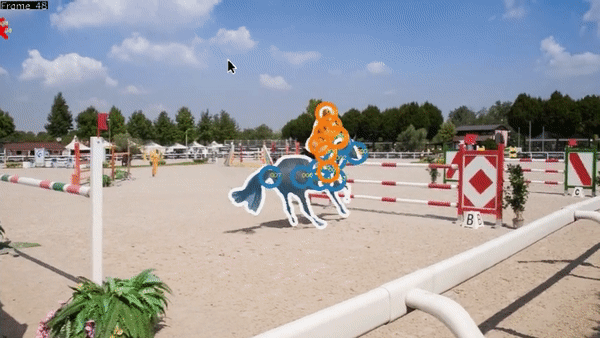
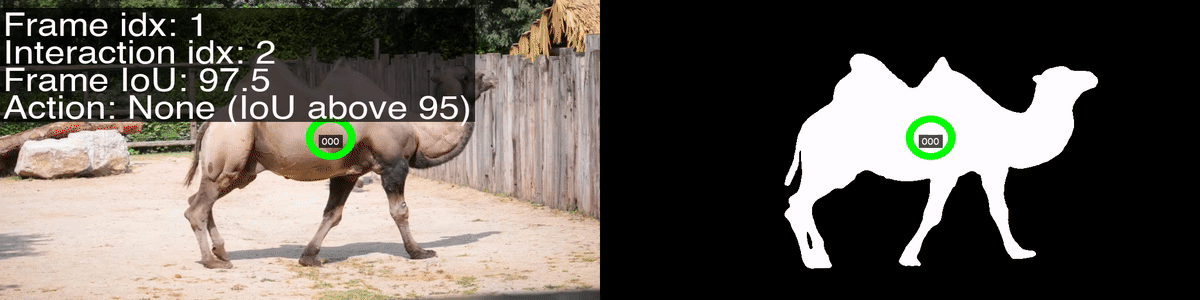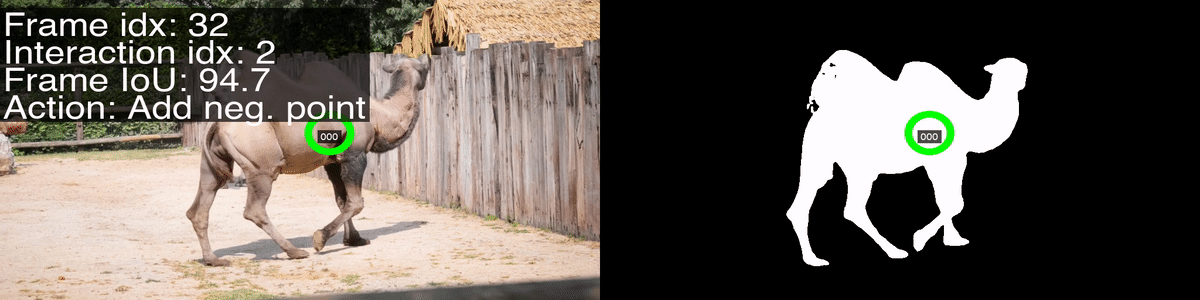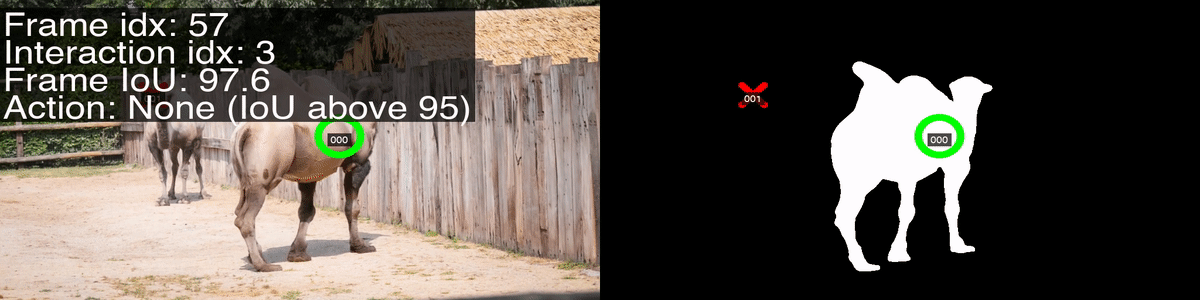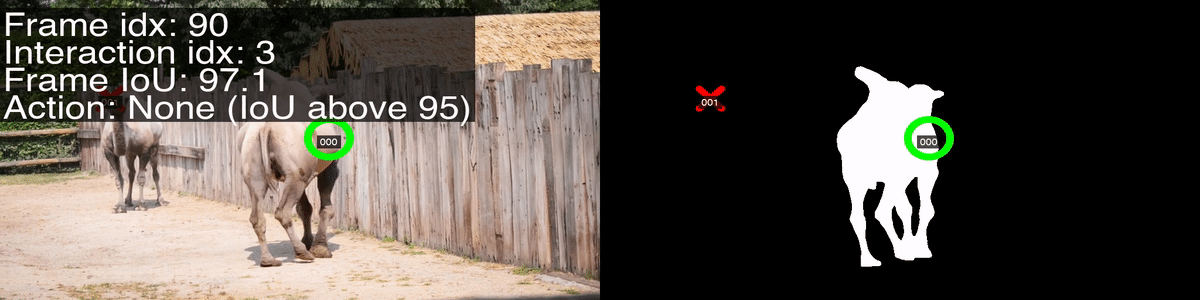
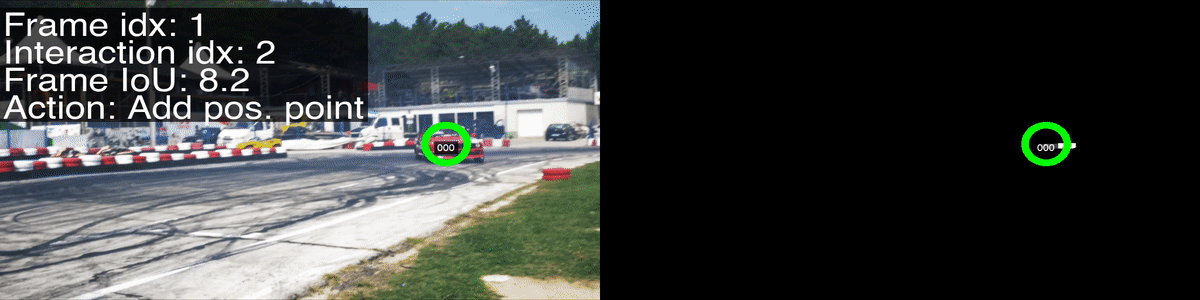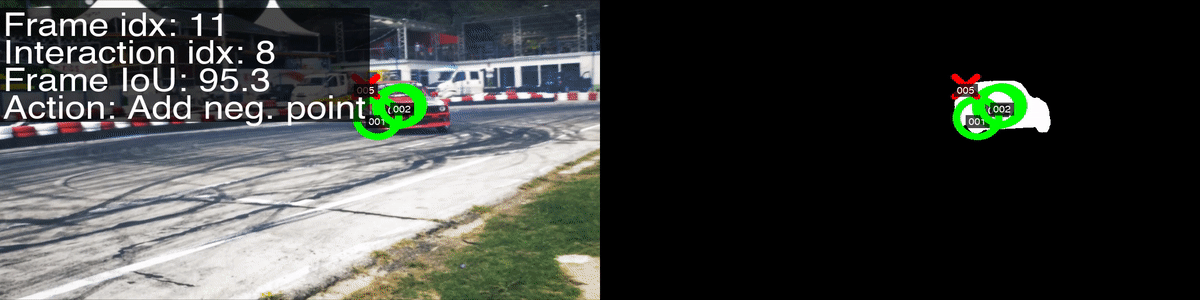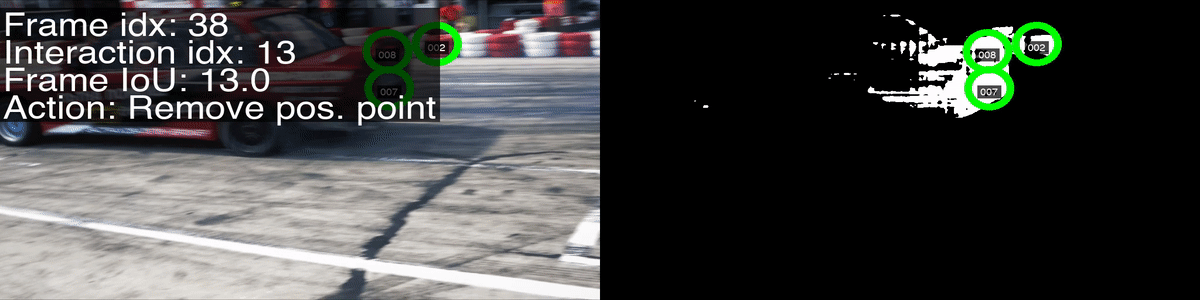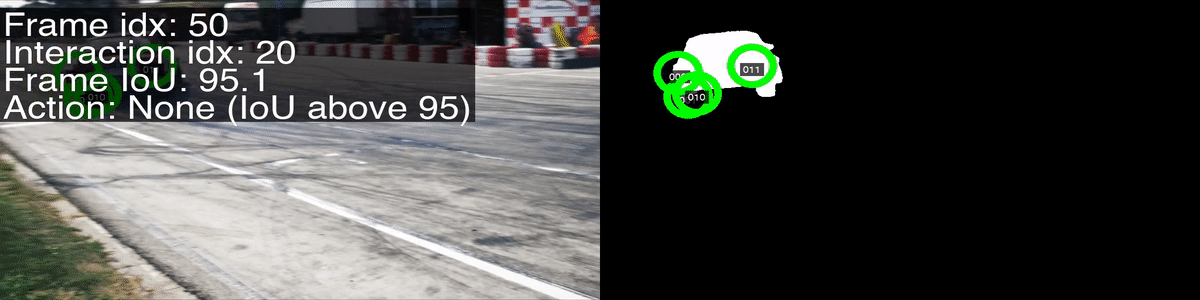
Annotators can interactively add or remove points to refine the segmentation results.
Explore our step-by-step guides to get up and running:
We want to thank SAM, PIPS, CoTracker, HQ-SAM, MobileSAM, XMem, and Mask2Former for publicly releasing their code and pretrained models.
If you find SAM-PT useful in your research or if you refer to the results mentioned in our work, please star ⭐ this repository and consider citing 📝:
@article{sam-pt,
  title   = {Segment Anything Meets Point Tracking},
  author  = {Rajič, Frano and Ke, Lei and Tai, Yu-Wing and Tang, Chi-Keung and Danelljan, Martin and Yu, Fisher},
  journal = {arXiv:2307.01197},
  year    = {2023}
}
98 followers · starred Feb 2024
174 followers · starred Jul 2023
201 followers · starred Nov 2023
501 followers · starred Nov 2023
SAM-PT: Extending SAM to zero-shot video segmentation with point-based tracking.
See the codeSegment Anything Meets Point Tracking
Frano Rajič, Lei Ke, Yu-Wing Tai, Chi-Keung Tang, Martin Danelljan, Fisher Yu
ETH Zürich, HKUST, EPFL
We propose SAM-PT, an extension of the Segment Anything Model (SAM) for zero-shot video segmentation. Our work offers a simple yet effective point-based perspective in video object segmentation research. For more details, refer to our paper.
Annotators only provide a few points to denote the target object at the first video frame to get video segmentation results. Please visit our project page for more visualizations, including qualitative results on DAVIS 2017 videos and more Avatar clips.
Annotators can interactively add or remove points to refine the segmentation results.
Explore our step-by-step guides to get up and running:
We want to thank SAM, PIPS, CoTracker, HQ-SAM, MobileSAM, XMem, and Mask2Former for publicly releasing their code and pretrained models.
If you find SAM-PT useful in your research or if you refer to the results mentioned in our work, please star ⭐ this repository and consider citing 📝:
@article{sam-pt,
  title   = {Segment Anything Meets Point Tracking},
  author  = {Rajič, Frano and Ke, Lei and Tai, Yu-Wing and Tang, Chi-Keung and Danelljan, Martin and Yu, Fisher},
  journal = {arXiv:2307.01197},
  year    = {2023}
}
98 followers · starred Feb 2024
174 followers · starred Jul 2023
201 followers · starred Nov 2023
501 followers · starred Nov 2023



