
Official implementation of the paper "Smoothed Energy Guidance: Guiding Diffusion Models with Reduced Energy Curvature of Attention" (NeurIPS`24)
Jupyter Notebook
138
13 commits
updated Oct 3, 2024
README
Smoothed Energy Guidance for SDXL (NeurIPS`24)
| SEG Paper | SEG | SEG+ControlNet |
|---|---|---|
 |  | |
Official implementation of Smoothed Energy Guidance: Guiding Diffusion Models with Reduced Energy Curvature of Attention by Susung Hong.
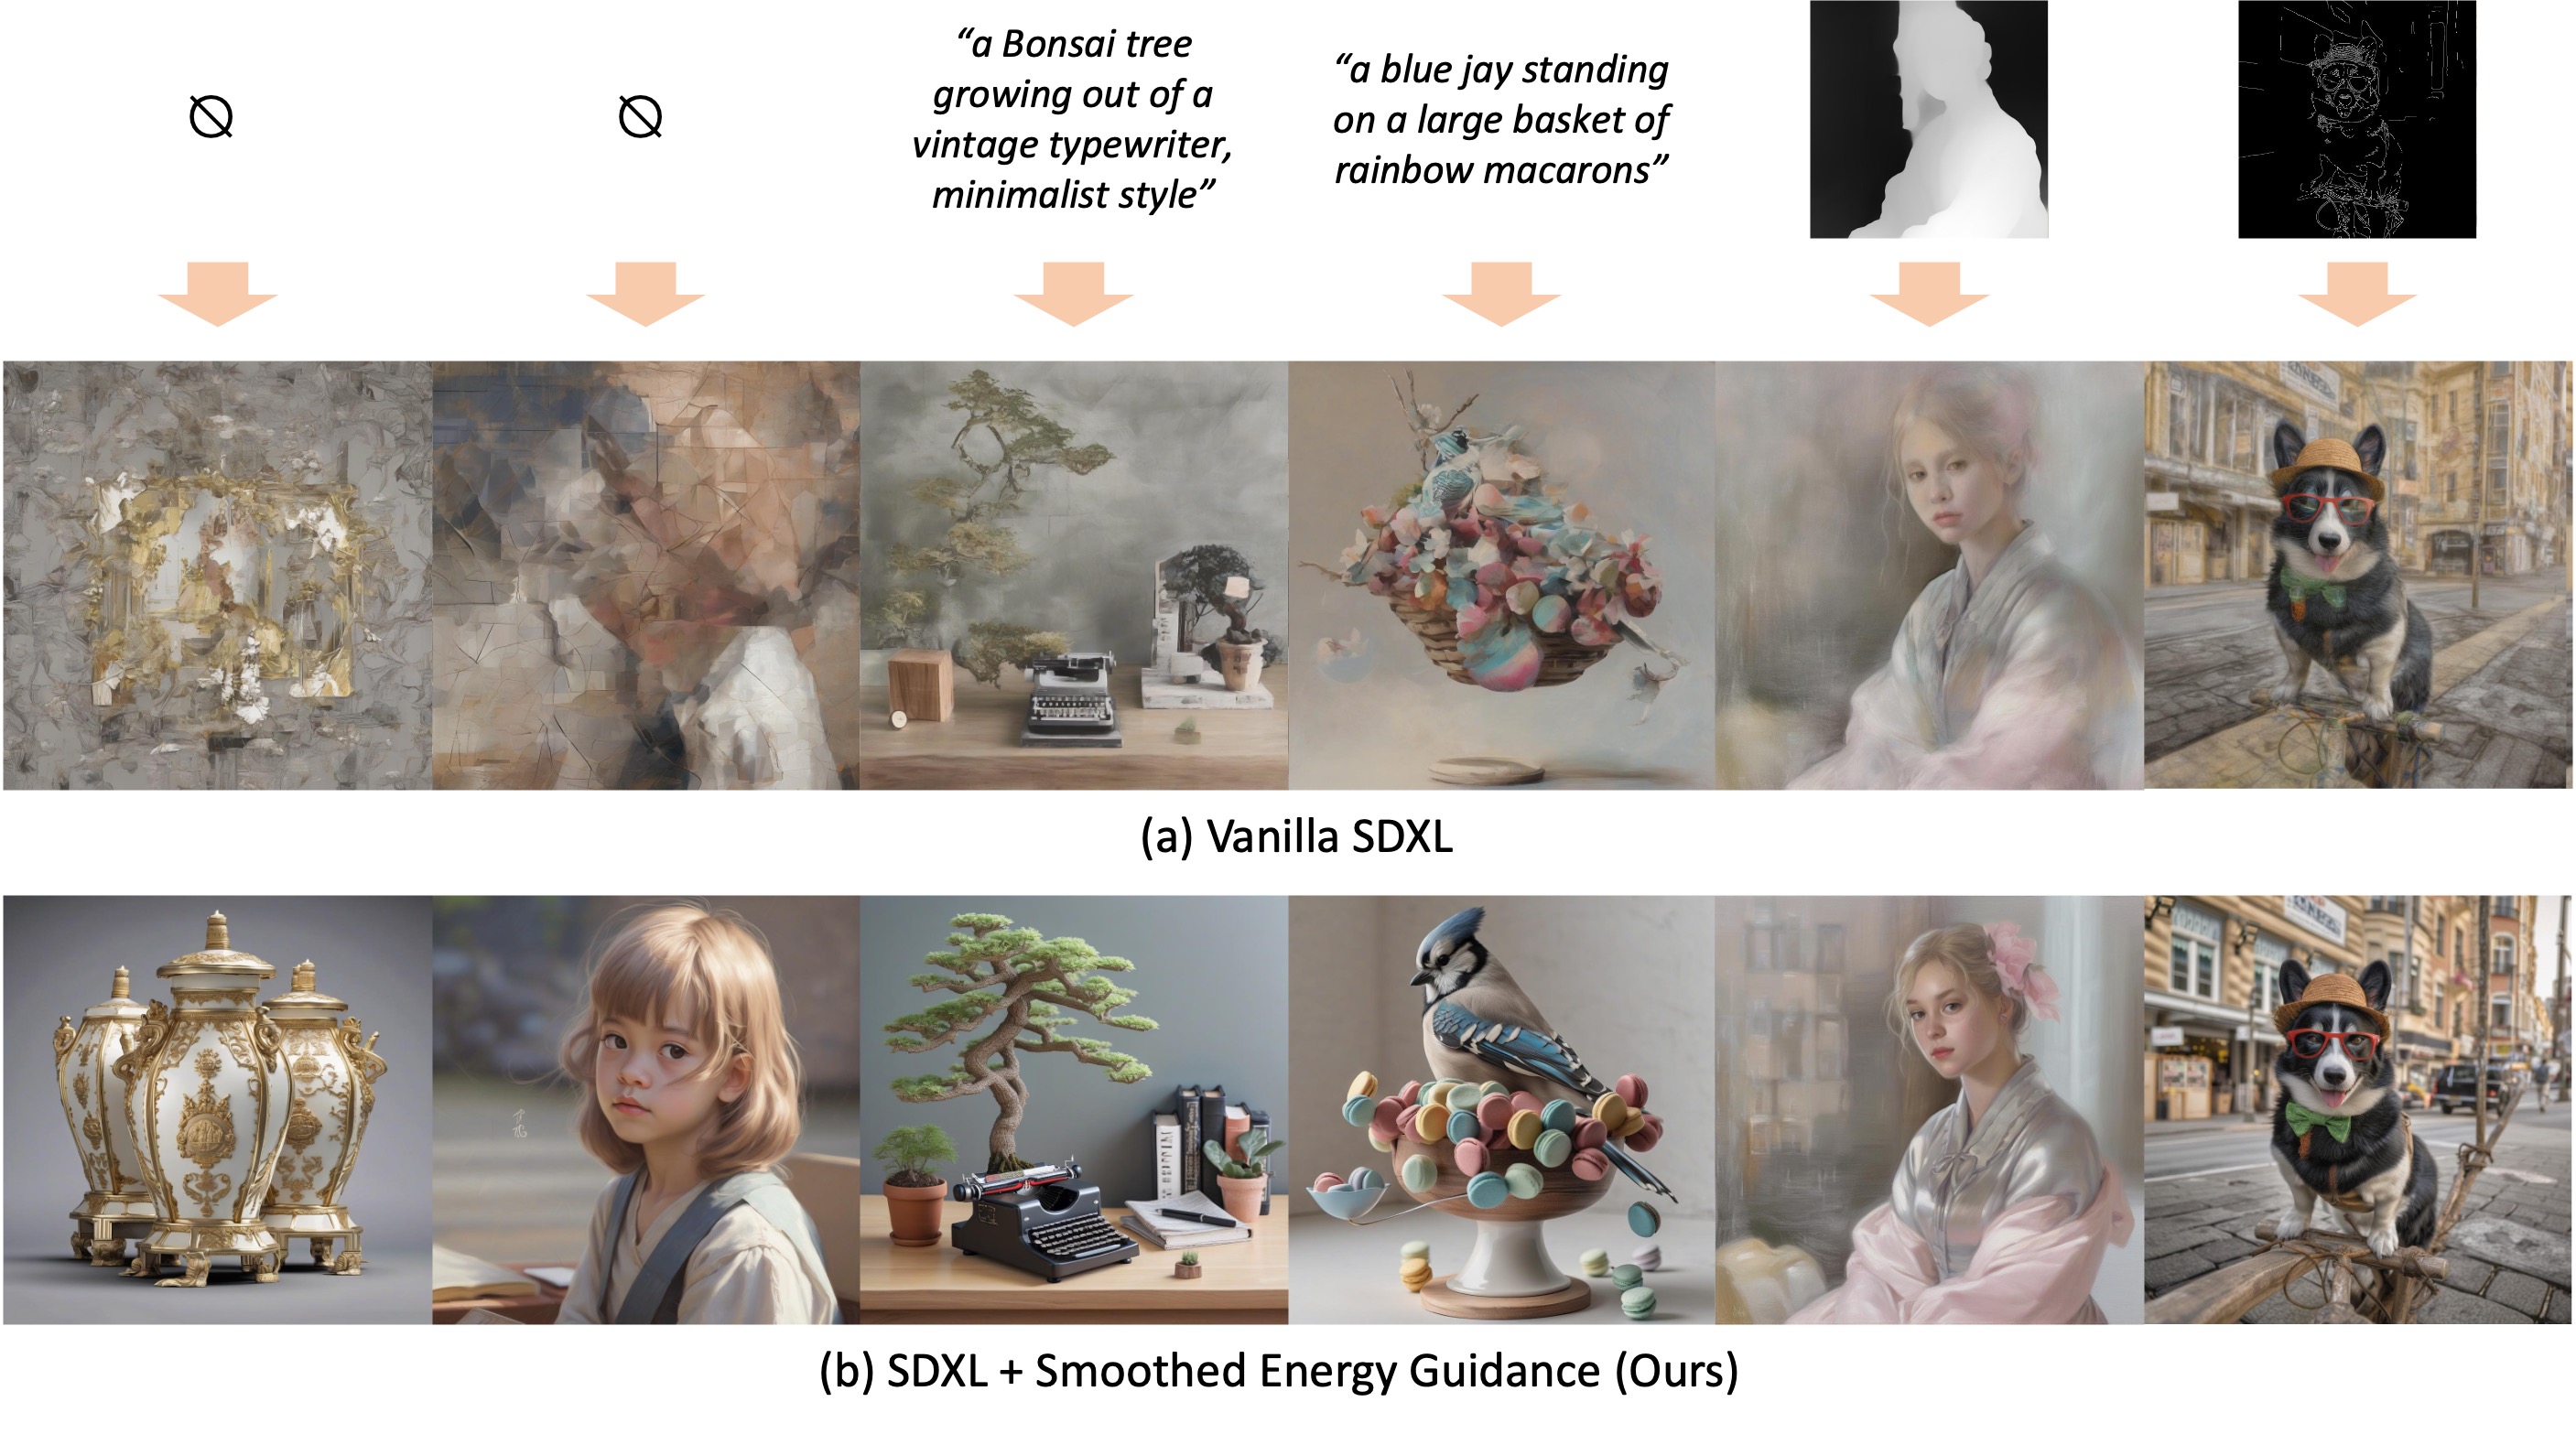
🏔️ What is Smoothed Energy Guidance? How does it work?
Smoothed Energy Guidance (SEG) is a training- and condition-free approach that leverages the energy-based perspective of the self-attention mechanism to improve image generation.
Key points:
- Does not rely on the guidance scale parameter that causes side effects when the value becomes large
- Allows continuous control of the original and maximally attenuated curvature of the energy landscape behind self-attention
- Introduces a query blurring method, equivalent to blurring the entire attention weights without significant computational cost
Please check our paper for details.
🔍 Comparison with other works
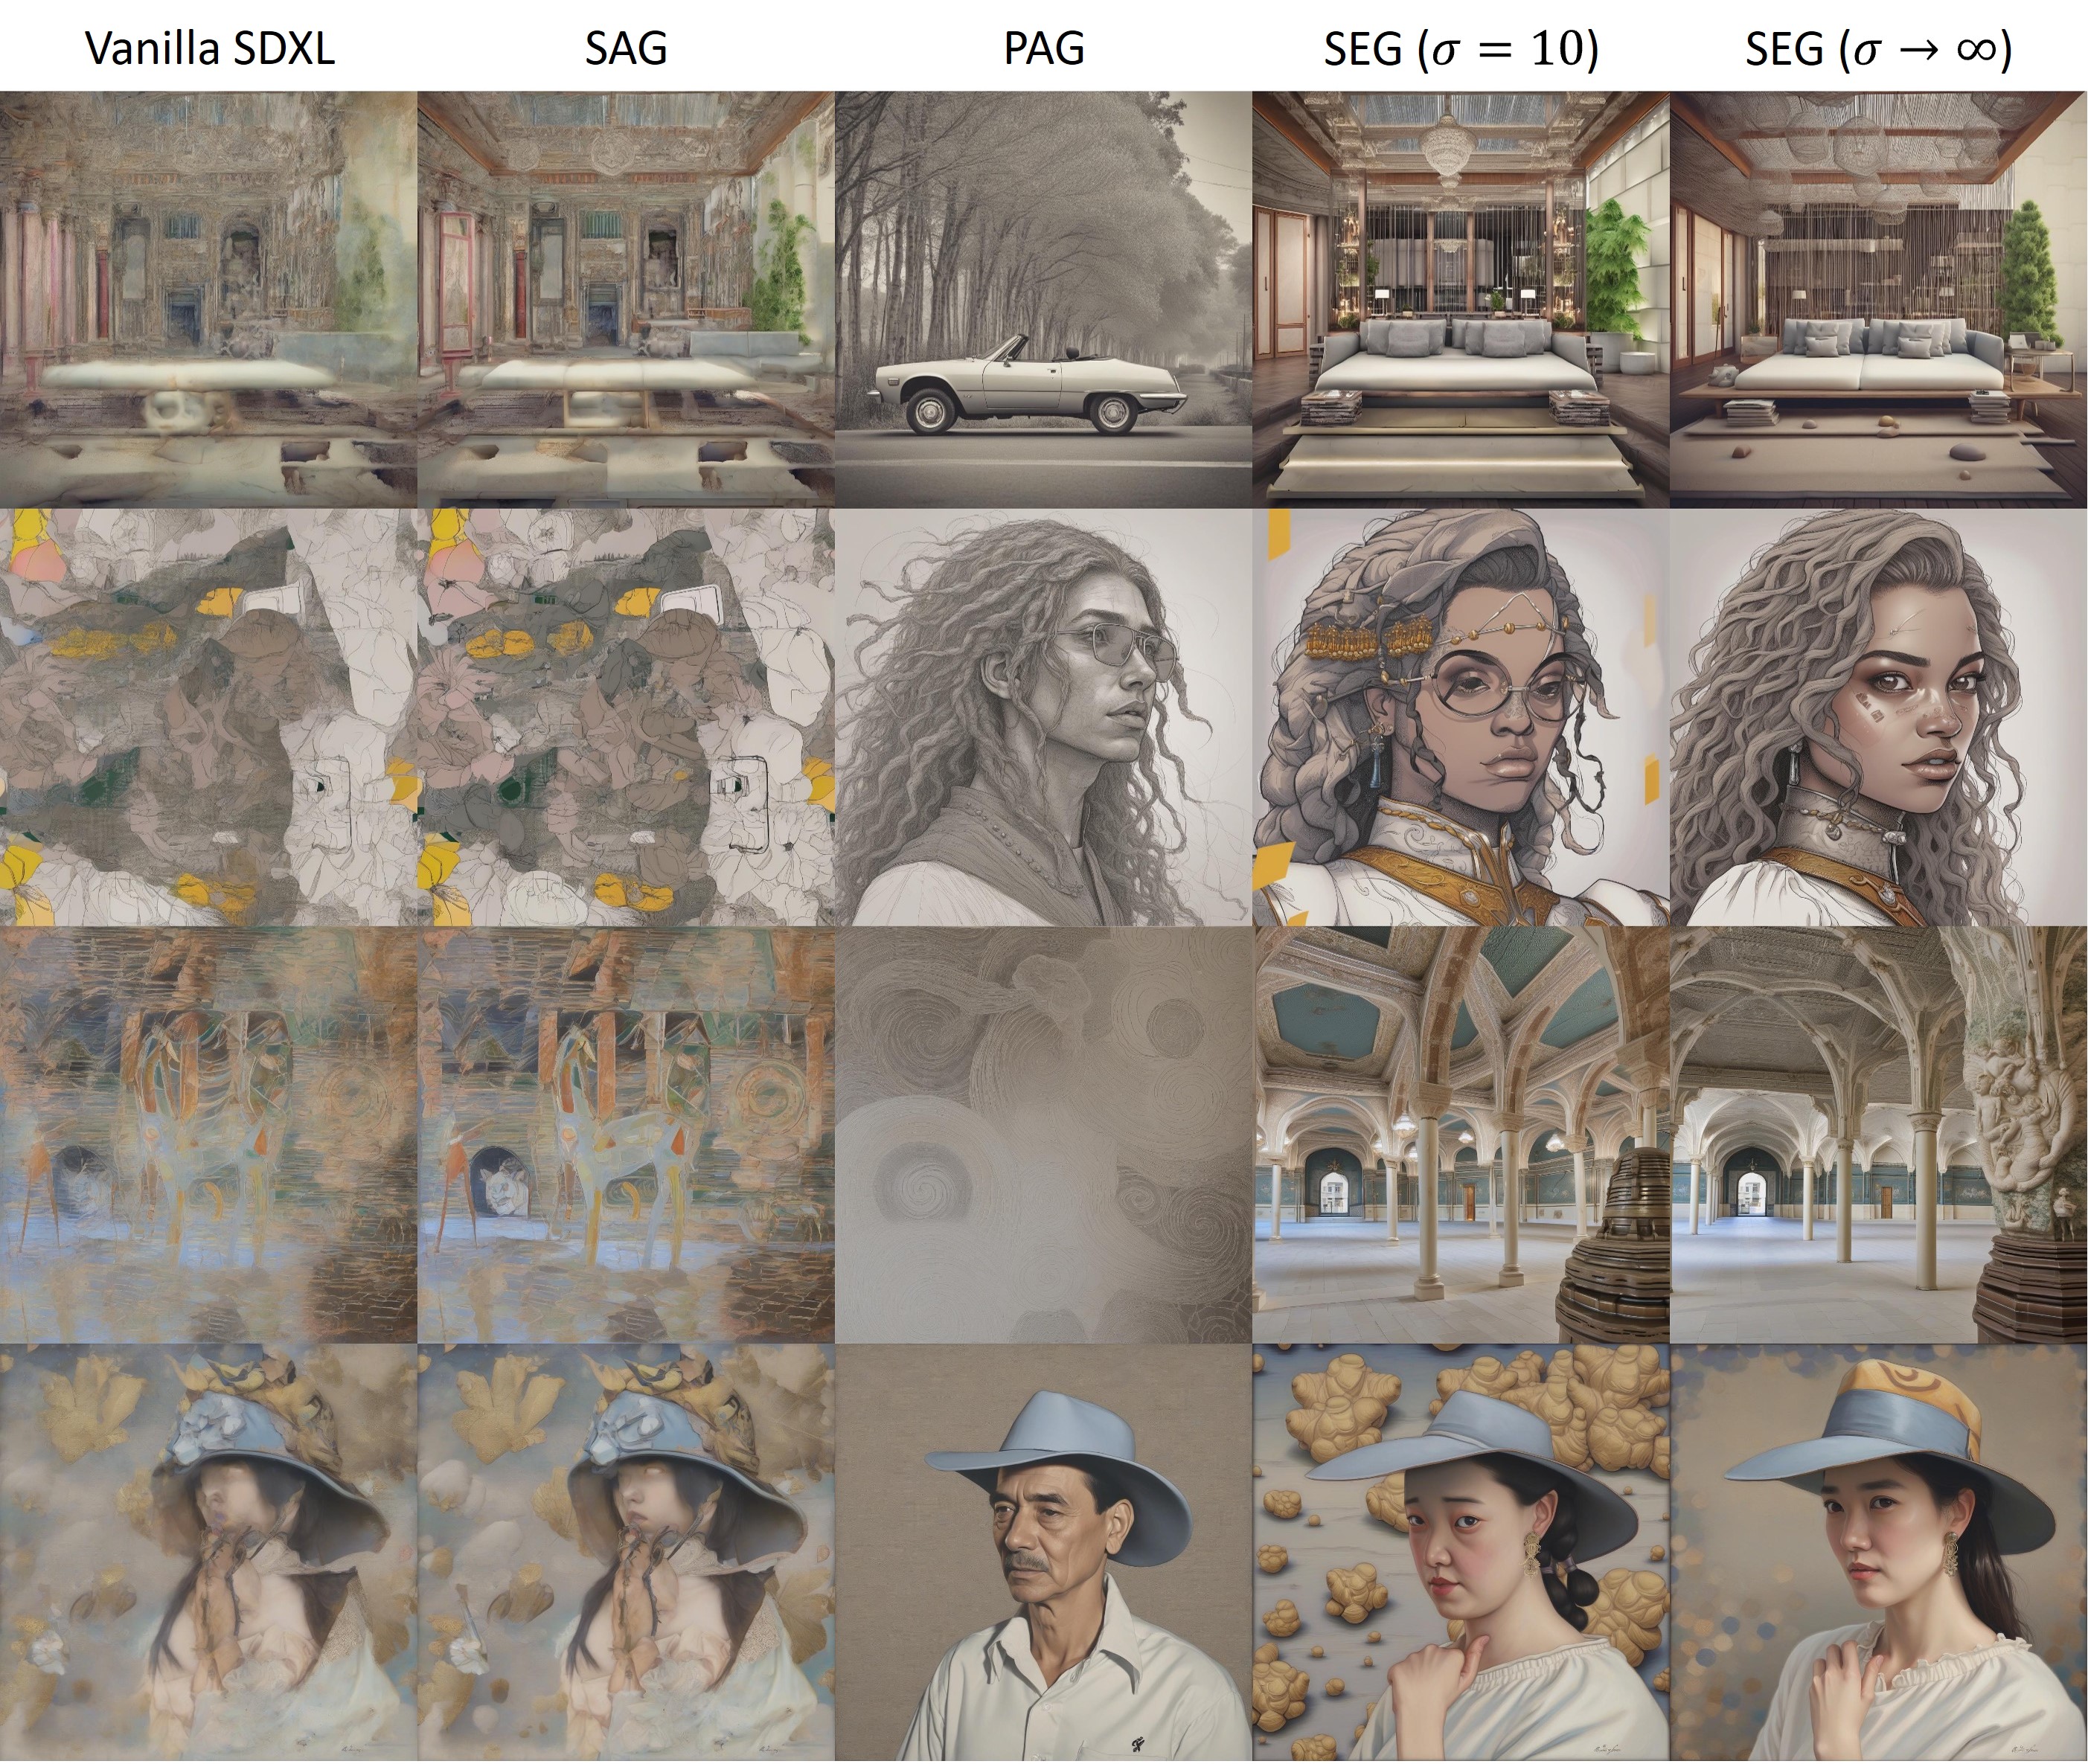
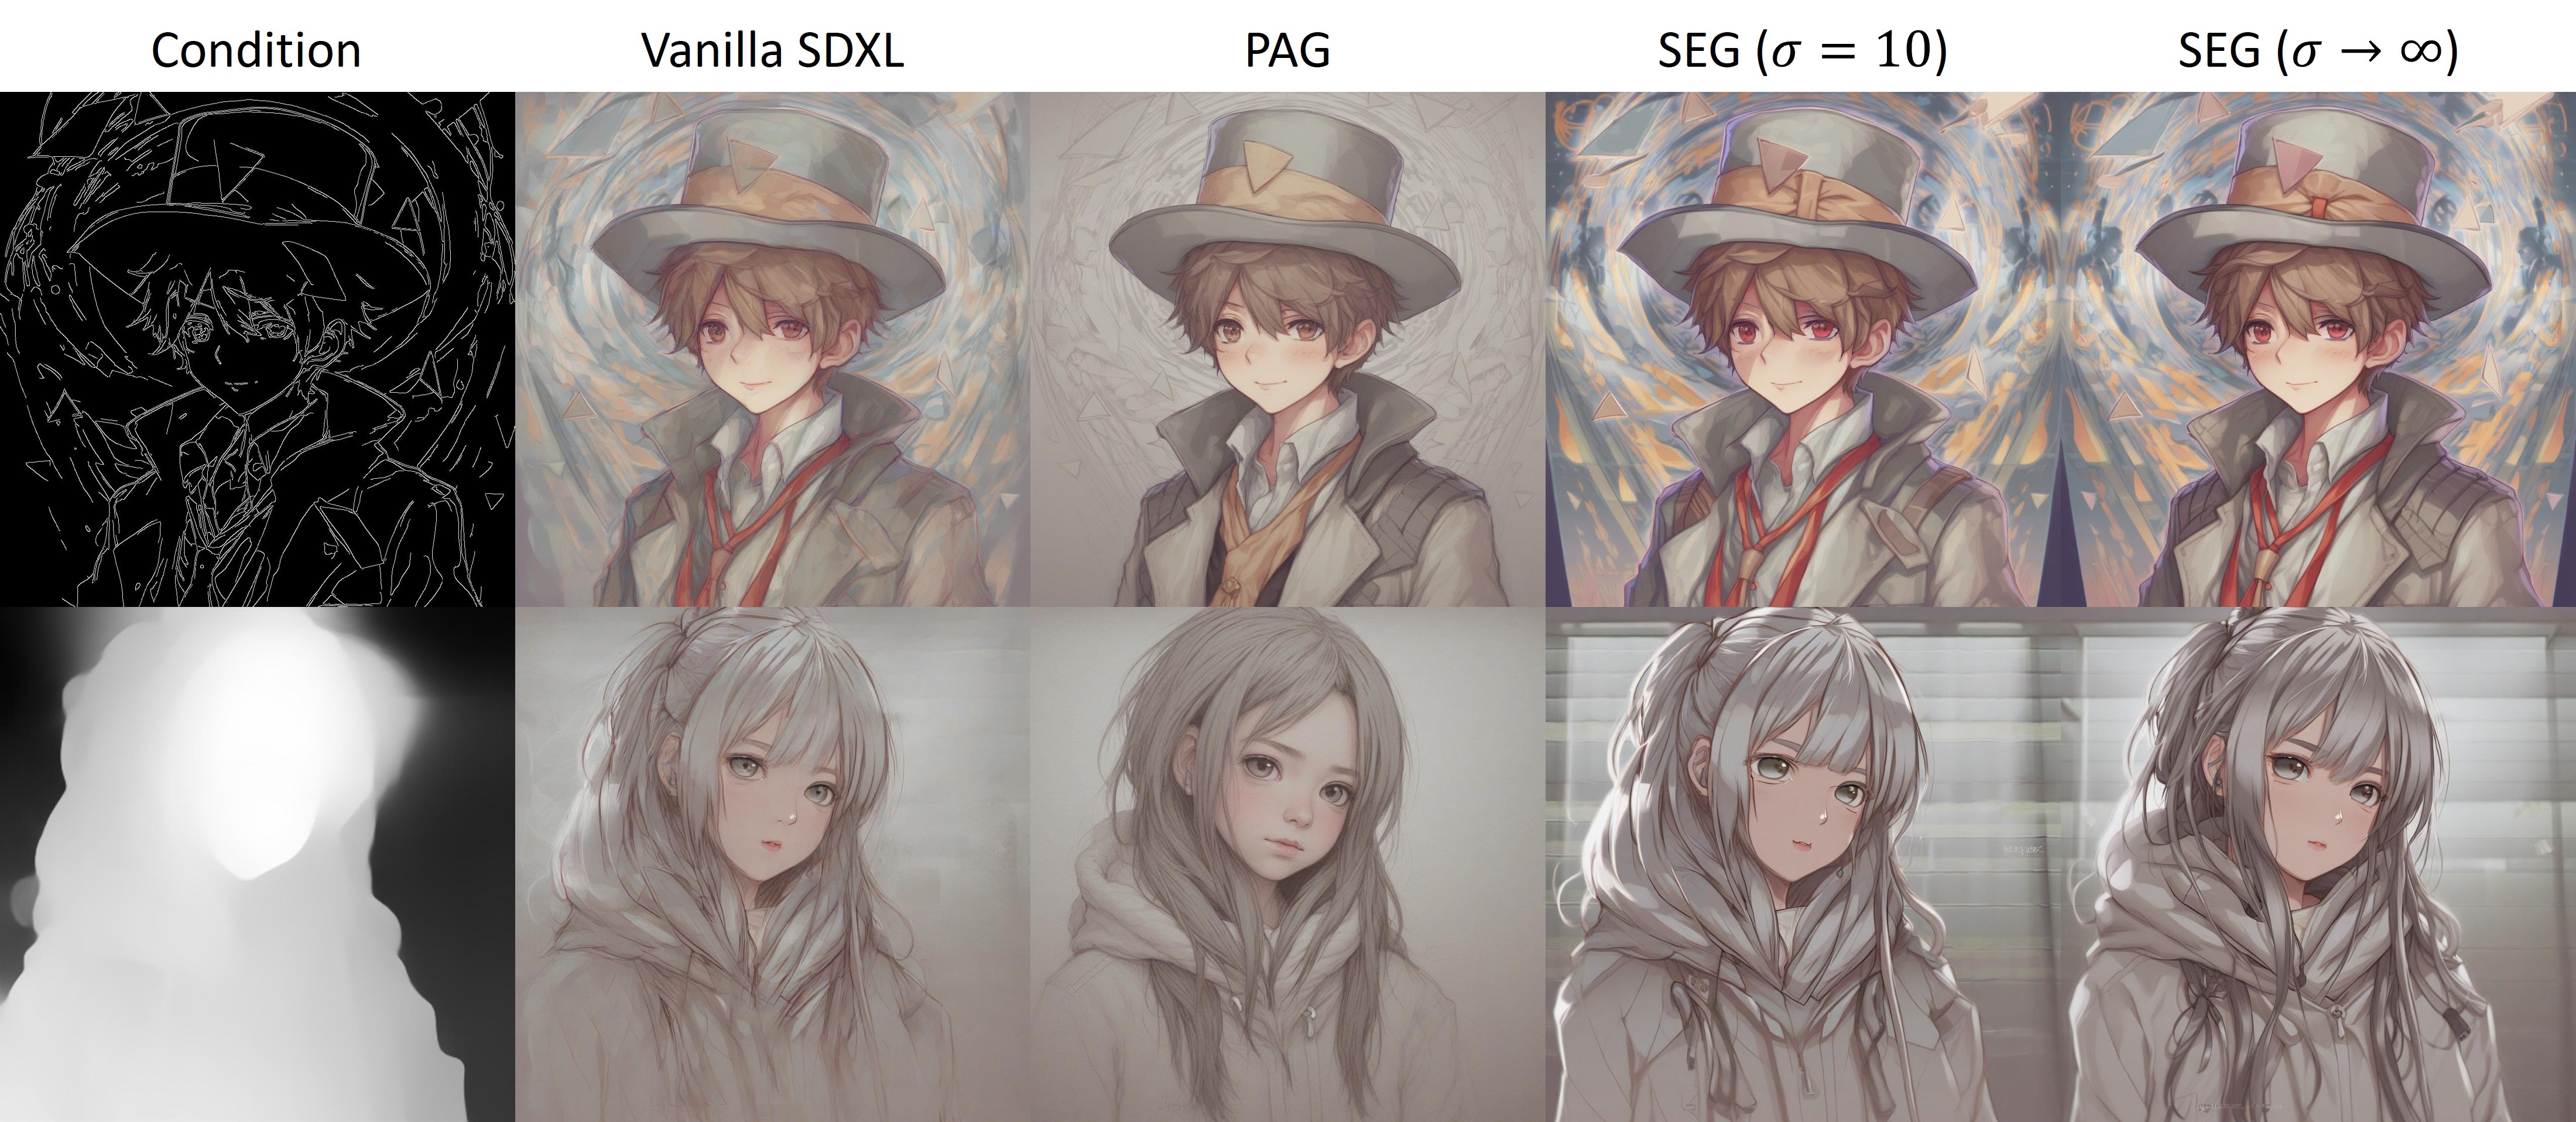
SEG does not severely suffer from side effects such as making the overall image grayish or significantly changing the original structure, while improving generation quality even without prompts.
Unconditional generation without prompts
ControlNet generation without prompts
🛠️ Installation
We use the following versions of torch and diffusers:
- torch 2.0.1
- diffusers 0.27.2
🚀 Quickstart
Get started with our Jupyter notebook demos:
sdxl_seg.ipynb: Basic usage with SDXLsdxl_controlnet_seg.ipynb: Integration with ControlNet
This is an example of a Python script:
from pipeline_seg import StableDiffusionXLSEGPipeline
pipe = StableDiffusionXLSEGPipeline.from_pretrained(
    "stabilityai/stable-diffusion-xl-base-1.0",
    torch_dtype=torch.float16
)

device = "cuda"
pipe = pipe.to(device)
prompts = [""]
seed = 10

generator = torch.Generator(device="cuda").manual_seed(seed)
output = pipe(
    prompts,
    num_inference_steps=25,
    guidance_scale=1.0,
    seg_scale=3.0,
    seg_blur_sigma=100.0,
    seg_applied_layers=['mid'],
    generator=generator,
).images
Parameters:
seg_scale: The scale of SEG. We generally fix this parameter to3.0. Please increase it if the result with infinite blur is still not satisfactory.seg_blur_sigma: The amount by which we blur the attention weights. Setting this value greater than 9999.0 results in infinite blur, which means uniform queries. Controlling it exponentially (e.g., 1, 4, 16, ...) is empirically effective.seg_applied_layers: The layer(s) in which we blur the attention weights. We use['mid']by default.
🙏 Acknowledgements
This project builds upon the excellent work of:
- Self-Attention Guidance (SAG)
- PAG for SDXL by Apolinário from multimodal AI art
- Perturbed Attention Guidance (PAG) by Ahn et al.
📚 Citation
If you use Smoothed Energy Guidance in your research or projects, please cite the following:
@article{hong2024smoothed,
  title={Smoothed Energy Guidance: Guiding Diffusion Models with Reduced Energy Curvature of Attention},
  author={Hong, Susung},
  journal={arXiv preprint arXiv:2408.00760},
  year={2024}
}
Contributors

13 commits
Similar repos





Languages
Jupyter Notebook
99.1%
Official implementation of the paper "Smoothed Energy Guidance: Guiding Diffusion Models with Reduced Energy Curvature of Attention" (NeurIPS`24)
Jupyter Notebook
138
13 commits
updated Oct 3, 2024
README
Smoothed Energy Guidance for SDXL (NeurIPS`24)
| SEG Paper | SEG | SEG+ControlNet |
|---|---|---|
| | |
Official implementation of Smoothed Energy Guidance: Guiding Diffusion Models with Reduced Energy Curvature of Attention by Susung Hong.
🏔️ What is Smoothed Energy Guidance? How does it work?
Smoothed Energy Guidance (SEG) is a training- and condition-free approach that leverages the energy-based perspective of the self-attention mechanism to improve image generation.
Key points:
- Does not rely on the guidance scale parameter that causes side effects when the value becomes large
- Allows continuous control of the original and maximally attenuated curvature of the energy landscape behind self-attention
- Introduces a query blurring method, equivalent to blurring the entire attention weights without significant computational cost
Please check our paper for details.
🔍 Comparison with other works
SEG does not severely suffer from side effects such as making the overall image grayish or significantly changing the original structure, while improving generation quality even without prompts.
Unconditional generation without prompts
ControlNet generation without prompts
🛠️ Installation
We use the following versions of torch and diffusers:
- torch 2.0.1
- diffusers 0.27.2
🚀 Quickstart
Get started with our Jupyter notebook demos:
sdxl_seg.ipynb: Basic usage with SDXLsdxl_controlnet_seg.ipynb: Integration with ControlNet
This is an example of a Python script:
from pipeline_seg import StableDiffusionXLSEGPipeline
pipe = StableDiffusionXLSEGPipeline.from_pretrained(
    "stabilityai/stable-diffusion-xl-base-1.0",
    torch_dtype=torch.float16
)

device = "cuda"
pipe = pipe.to(device)
prompts = [""]
seed = 10

generator = torch.Generator(device="cuda").manual_seed(seed)
output = pipe(
    prompts,
    num_inference_steps=25,
    guidance_scale=1.0,
    seg_scale=3.0,
    seg_blur_sigma=100.0,
    seg_applied_layers=['mid'],
    generator=generator,
).images
Parameters:
seg_scale: The scale of SEG. We generally fix this parameter to3.0. Please increase it if the result with infinite blur is still not satisfactory.seg_blur_sigma: The amount by which we blur the attention weights. Setting this value greater than 9999.0 results in infinite blur, which means uniform queries. Controlling it exponentially (e.g., 1, 4, 16, ...) is empirically effective.seg_applied_layers: The layer(s) in which we blur the attention weights. We use['mid']by default.
🙏 Acknowledgements
This project builds upon the excellent work of:
- Self-Attention Guidance (SAG)
- PAG for SDXL by Apolinário from multimodal AI art
- Perturbed Attention Guidance (PAG) by Ahn et al.
📚 Citation
If you use Smoothed Energy Guidance in your research or projects, please cite the following:
@article{hong2024smoothed,
  title={Smoothed Energy Guidance: Guiding Diffusion Models with Reduced Energy Curvature of Attention},
  author={Hong, Susung},
  journal={arXiv preprint arXiv:2408.00760},
  year={2024}
}
Similar repos
Contributors
13 commits
Languages
Jupyter Notebook
99.1%