
Official repository for ICML 2024 paper "MoRe Fine-Tuning with 10x Fewer Parameters"
Python
22
205 commits
updated Oct 14, 2025
README
MoRe Fine-Tuning with 10x Fewer Parameters
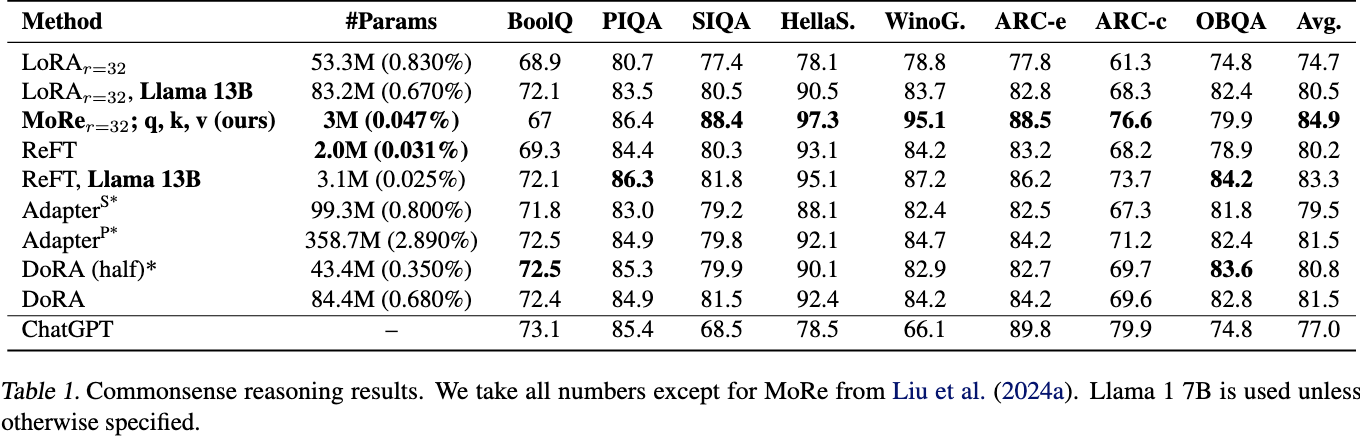
Official repository for ICML 2024 paper "MoRe Fine-Tuning with 10x Fewer Parameters". Using hardware efficient block-diagonal matrices, we surpass LoRA's performance with 10x fewer parameters on average, very little rank tuning and no alpha scaler. Our approach is also more memory and runtime efficient on standard reasoning tasks, with our Llama 7B beating LoRA-trained Llama 13B on Commonsense reasoning.
Paper: https://arxiv.org/abs/2408.17383
🚀 Main Results
📰 News
- [2024/06] Our paper is accepted by two ICML workshops: ES-FOMO and FM-wild!
- [2024/10] Release an optimized Triton Kernel(~%20 speed-up and 33% memory reduction compared to PyTorch) and a further-optimized PyTorch version!
🗝️ MoRe Implementation
src/models/layers/monarch_linear.pycontains the code for MoRe adapter.src/models/layers/blockdiag_butterfly_multiply.pycontains the code for block-diagonal monarch matmul, which is optimized over Hazy Research's version for less transpose and mem copy.- a basic usage of MoRe adapter can be found in
demos/monarch_demo.ipynb.
🛠️ Setup
We highly recommend using docker for stable environment building, but any decent PyTorch + Huggingface environment should work.
docker compose build; docker compose up -d
hostname > hostname.txt # to not confuse machines in wandb
docker attach peft
🦾 Usage
To reproduce results
- GLUE tasks:
python run_glue.py /fly/task_configs/monarch_roberta_glue/cola.json.\ - For reasoning tasks, first load datasets using
bash pyreft/loreft/load_datasets.sh. - Math reasoning:
cd pyreft/loreft; bash math_monarch.sh --blk_r=8 --all_linear. - Commonsense reasoning:
cd pyreft/loreft; bash common_sense_monarch.sh --blk_r=8 --all_linear.
You can manually modify the hyperparameters in task_configs/llama for reasoning tasks and
task_configs/monarch_roberta_glue for GLUE tasks.
🧐 Todo
We welcome contributions and suggestions to the list!
- Fused Triton kernel for Monarch
- MMLU results (including reproducing the QLoRA baselines)
- More ablations on rank tuning guidelines
- Explore MoRe as a general substitute for low-rank modules.
📑 Citation
If you use our adapter implementation, please cite our paper:
@misc{tan2024finetuning10xfewerparameters,
      title={MoRe Fine-Tuning with 10x Fewer Parameters},
      author={Wenxuan Tan and Nicholas Roberts and Tzu-Heng Huang and Jitian Zhao and John Cooper and Samuel Guo and Chengyu Duan and Frederic Sala},
      year={2024},
      eprint={2408.17383},
      archivePrefix={arXiv},
      primaryClass={cs.LG},
      url={https://arxiv.org/abs/2408.17383},
}


Similar repos


Languages
Python
58.2%
Jupyter Notebook
39.0%
Shell
2.3%
Official repository for ICML 2024 paper "MoRe Fine-Tuning with 10x Fewer Parameters"
Python
22
205 commits
updated Oct 14, 2025
README
MoRe Fine-Tuning with 10x Fewer Parameters
Official repository for ICML 2024 paper "MoRe Fine-Tuning with 10x Fewer Parameters". Using hardware efficient block-diagonal matrices, we surpass LoRA's performance with 10x fewer parameters on average, very little rank tuning and no alpha scaler. Our approach is also more memory and runtime efficient on standard reasoning tasks, with our Llama 7B beating LoRA-trained Llama 13B on Commonsense reasoning.
Paper: https://arxiv.org/abs/2408.17383
🚀 Main Results
📰 News
- [2024/06] Our paper is accepted by two ICML workshops: ES-FOMO and FM-wild!
- [2024/10] Release an optimized Triton Kernel(~%20 speed-up and 33% memory reduction compared to PyTorch) and a further-optimized PyTorch version!
🗝️ MoRe Implementation
src/models/layers/monarch_linear.pycontains the code for MoRe adapter.src/models/layers/blockdiag_butterfly_multiply.pycontains the code for block-diagonal monarch matmul, which is optimized over Hazy Research's version for less transpose and mem copy.- a basic usage of MoRe adapter can be found in
demos/monarch_demo.ipynb.
🛠️ Setup
We highly recommend using docker for stable environment building, but any decent PyTorch + Huggingface environment should work.
docker compose build; docker compose up -d
hostname > hostname.txt # to not confuse machines in wandb
docker attach peft
🦾 Usage
To reproduce results
- GLUE tasks:
python run_glue.py /fly/task_configs/monarch_roberta_glue/cola.json.\ - For reasoning tasks, first load datasets using
bash pyreft/loreft/load_datasets.sh. - Math reasoning:
cd pyreft/loreft; bash math_monarch.sh --blk_r=8 --all_linear. - Commonsense reasoning:
cd pyreft/loreft; bash common_sense_monarch.sh --blk_r=8 --all_linear.
You can manually modify the hyperparameters in task_configs/llama for reasoning tasks and
task_configs/monarch_roberta_glue for GLUE tasks.
🧐 Todo
We welcome contributions and suggestions to the list!
- Fused Triton kernel for Monarch
- MMLU results (including reproducing the QLoRA baselines)
- More ablations on rank tuning guidelines
- Explore MoRe as a general substitute for low-rank modules.
📑 Citation
If you use our adapter implementation, please cite our paper:
@misc{tan2024finetuning10xfewerparameters,
      title={MoRe Fine-Tuning with 10x Fewer Parameters},
      author={Wenxuan Tan and Nicholas Roberts and Tzu-Heng Huang and Jitian Zhao and John Cooper and Samuel Guo and Chengyu Duan and Frederic Sala},
      year={2024},
      eprint={2408.17383},
      archivePrefix={arXiv},
      primaryClass={cs.LG},
      url={https://arxiv.org/abs/2408.17383},
}
Similar repos
Languages
Python
58.2%
Jupyter Notebook
39.0%
Shell
2.3%