Repo for the paper "Defending Against Prompt Injection With a Few DefensiveTokens"
Python
19
6 commits
updated Nov 10, 2025
Sizhe Chen, Yizhu Wang, Nicholas Carlini, Chawin Sitawarin, David Wagner

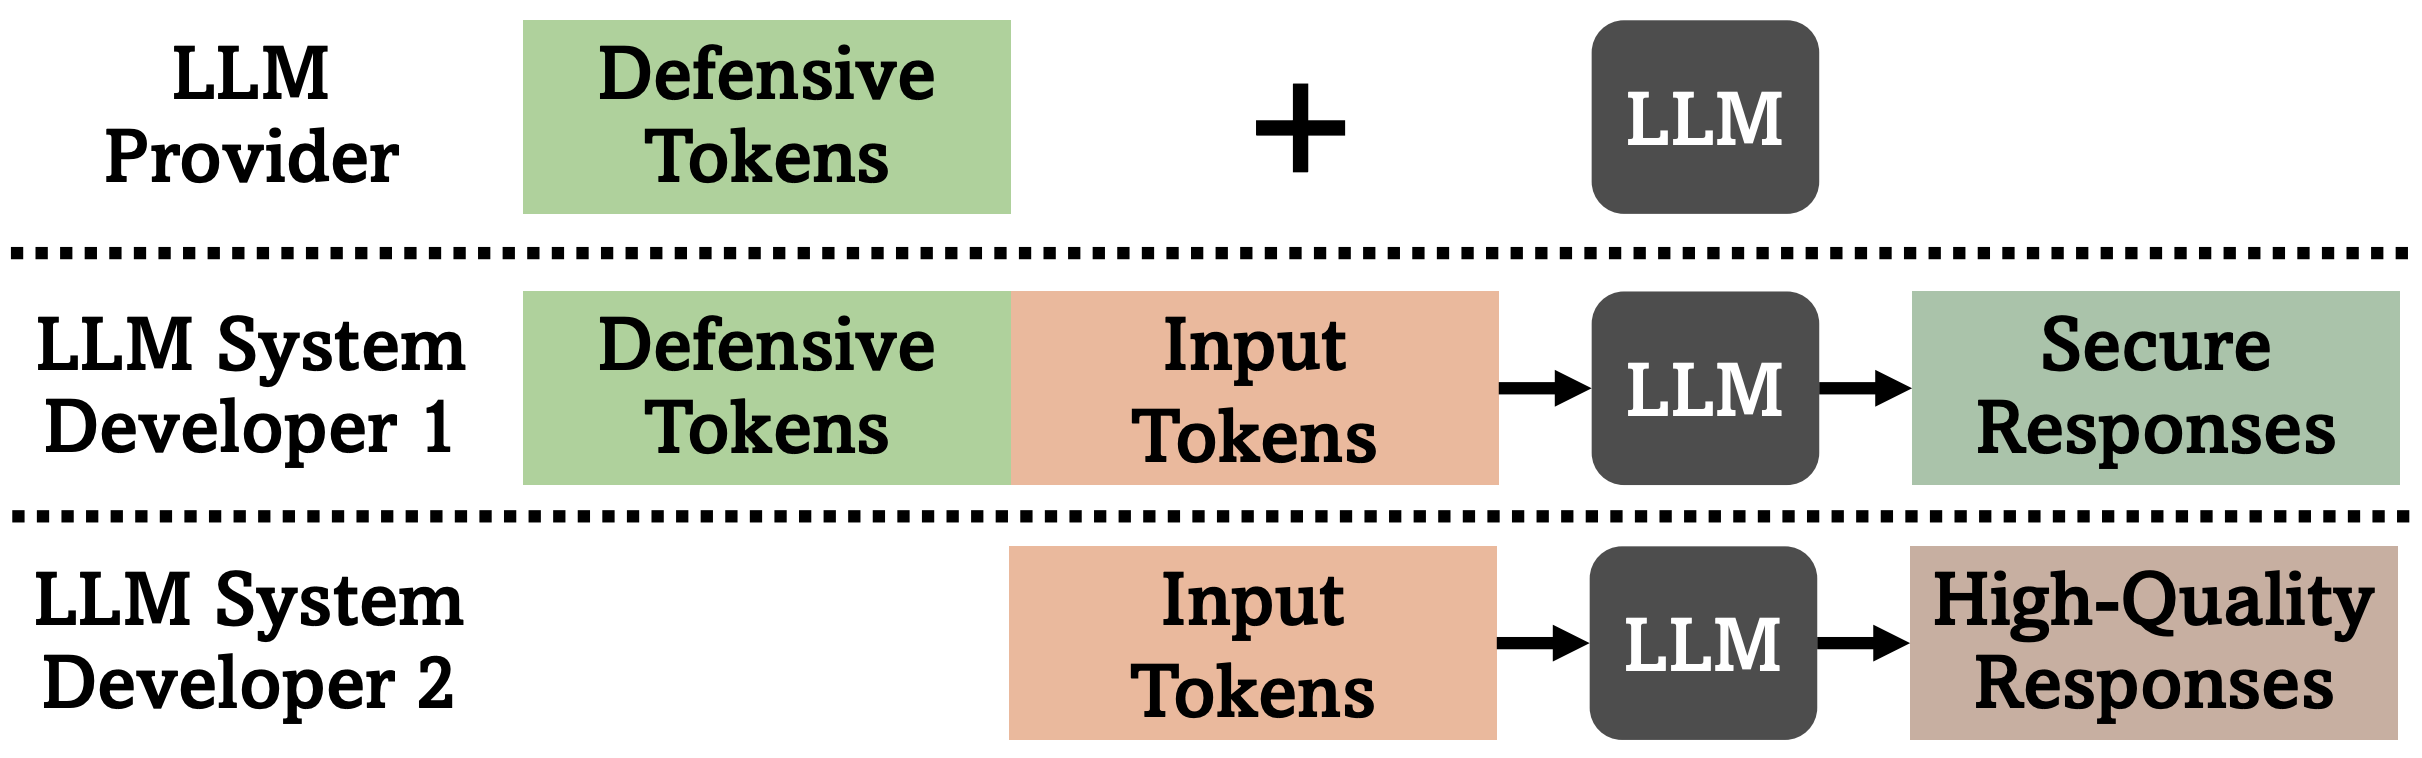
When large language model (LLM) systems interact with external data to perform complex tasks, a new attack, namely prompt injection, becomes a significant threat. By injecting instructions into the data accessed by the system, the attacker is able to override the initial user task with an arbitrary task directed by the attacker. To secure the system, test-time defenses, e.g., defensive prompting, have been proposed for system developers to attain security only when needed in a flexible manner. However, they are much less effective than training-time defenses that change the model parameters. Motivated by this, we propose DefensiveToken, a test-time defense with prompt injection robustness comparable to training-time alternatives. DefensiveTokens are newly inserted as special tokens, whose embeddings are optimized for security. In security-sensitive cases, system developers can append a few DefensiveTokens before the LLM input to achieve security with a minimal utility drop. In scenarios where security is less of a concern, developers can simply skip DefensiveTokens; the LLM system remains the same as there is no defense, generating high-quality responses. Thus, DefensiveTokens, if released alongside the model, allow a flexible switch between the state-of-the-art (SOTA) utility and almost-SOTA security at test time.
git clone https://github.com/Sizhe-Chen/DefensiveToken
cd DefensiveToken
uv venv defensivetoken --python 3.13
uv pip install transformers==4.57.1 torch==2.8.0
source defensivetoken/bin/activate
python setup.py
model_name with one of the meta-llama/Meta-Llama-3-8B-Instruct, meta-llama/Llama-3.1-8B-Instruct, tiiuae/Falcon3-7B-Instruct, Qwen/Qwen2.5-7B-Instruct for single-sample inferencepython demo.py [model_name]
-m model_path in Meta_SecAlign with model_name-5DefensiveTokens, e.g., meta-llama/Llama-3.1-8B-Instruct-5DefensiveTokens, which is generated by python setup.py."role": "system" for trusted instruction and "role": "user" for untrusted data, i.e., change Meta_SecAlign here, which uses "role": "user" for trusted instruction and "role": "input" for untrusted data.add_defensive_tokens=False when calling tokenizer.apply_chat_template, i.e., add it on Meta_SecAlign here.Repo for the paper "Defending Against Prompt Injection With a Few DefensiveTokens"
Python
19
6 commits
updated Nov 10, 2025
Sizhe Chen, Yizhu Wang, Nicholas Carlini, Chawin Sitawarin, David Wagner
When large language model (LLM) systems interact with external data to perform complex tasks, a new attack, namely prompt injection, becomes a significant threat. By injecting instructions into the data accessed by the system, the attacker is able to override the initial user task with an arbitrary task directed by the attacker. To secure the system, test-time defenses, e.g., defensive prompting, have been proposed for system developers to attain security only when needed in a flexible manner. However, they are much less effective than training-time defenses that change the model parameters. Motivated by this, we propose DefensiveToken, a test-time defense with prompt injection robustness comparable to training-time alternatives. DefensiveTokens are newly inserted as special tokens, whose embeddings are optimized for security. In security-sensitive cases, system developers can append a few DefensiveTokens before the LLM input to achieve security with a minimal utility drop. In scenarios where security is less of a concern, developers can simply skip DefensiveTokens; the LLM system remains the same as there is no defense, generating high-quality responses. Thus, DefensiveTokens, if released alongside the model, allow a flexible switch between the state-of-the-art (SOTA) utility and almost-SOTA security at test time.
git clone https://github.com/Sizhe-Chen/DefensiveToken
cd DefensiveToken
uv venv defensivetoken --python 3.13
uv pip install transformers==4.57.1 torch==2.8.0
source defensivetoken/bin/activate
python setup.py
model_name with one of the meta-llama/Meta-Llama-3-8B-Instruct, meta-llama/Llama-3.1-8B-Instruct, tiiuae/Falcon3-7B-Instruct, Qwen/Qwen2.5-7B-Instruct for single-sample inferencepython demo.py [model_name]
-m model_path in Meta_SecAlign with model_name-5DefensiveTokens, e.g., meta-llama/Llama-3.1-8B-Instruct-5DefensiveTokens, which is generated by python setup.py."role": "system" for trusted instruction and "role": "user" for untrusted data, i.e., change Meta_SecAlign here, which uses "role": "user" for trusted instruction and "role": "input" for untrusted data.add_defensive_tokens=False when calling tokenizer.apply_chat_template, i.e., add it on Meta_SecAlign here.


