
Official Repository of "[ICLR26] TRAPO: A Semi-Supervised Reinforcement Learning Framework for Boosting LLM Reasoning"
Python
29
10 commits
updated Feb 6, 2026
README
TRAPO: A Semi-Supervised Reinforcement Learning Framework for Boosting LLM Reasoning.
TRAPO is A Friend : )


📚 Overview
- 🎉 News
- 📖 Introduction
- ✨ Getting Started
- 🔧 Usage
- 📃 Evaluation
- 🎈 Citation
- 🌻 Acknowledgement
🎉News
- [2025/12/10] TRAPO codebase is released along with evaluation scripts. Try it out!
📖Introduction
TraPO is a semi-supervised reinforcement learning framework that bridges unlabeled and labeled samples for training large reasoning models (LRMs).
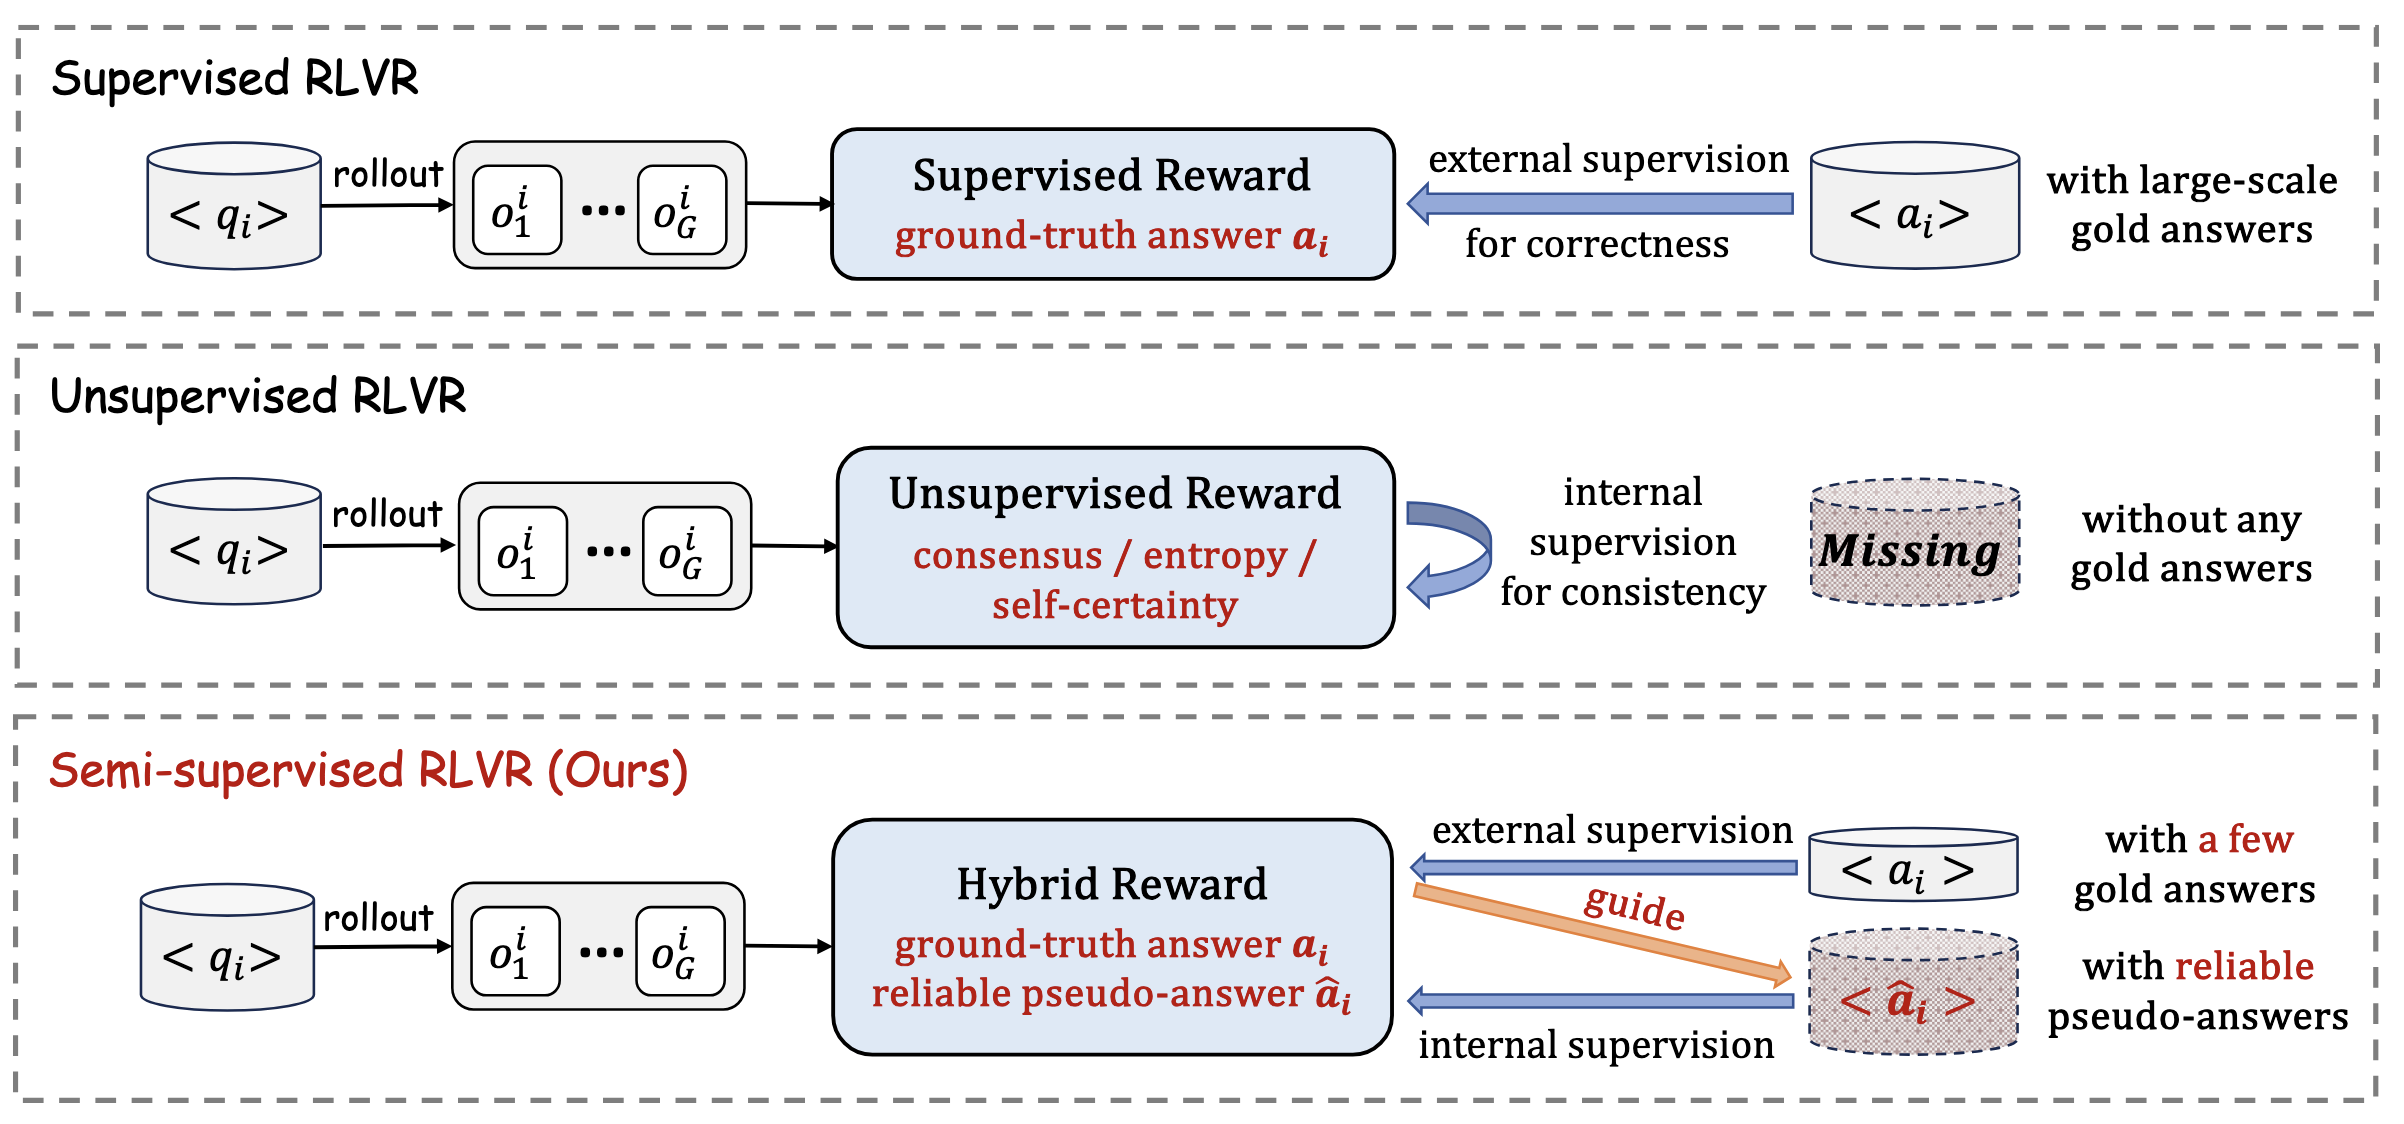
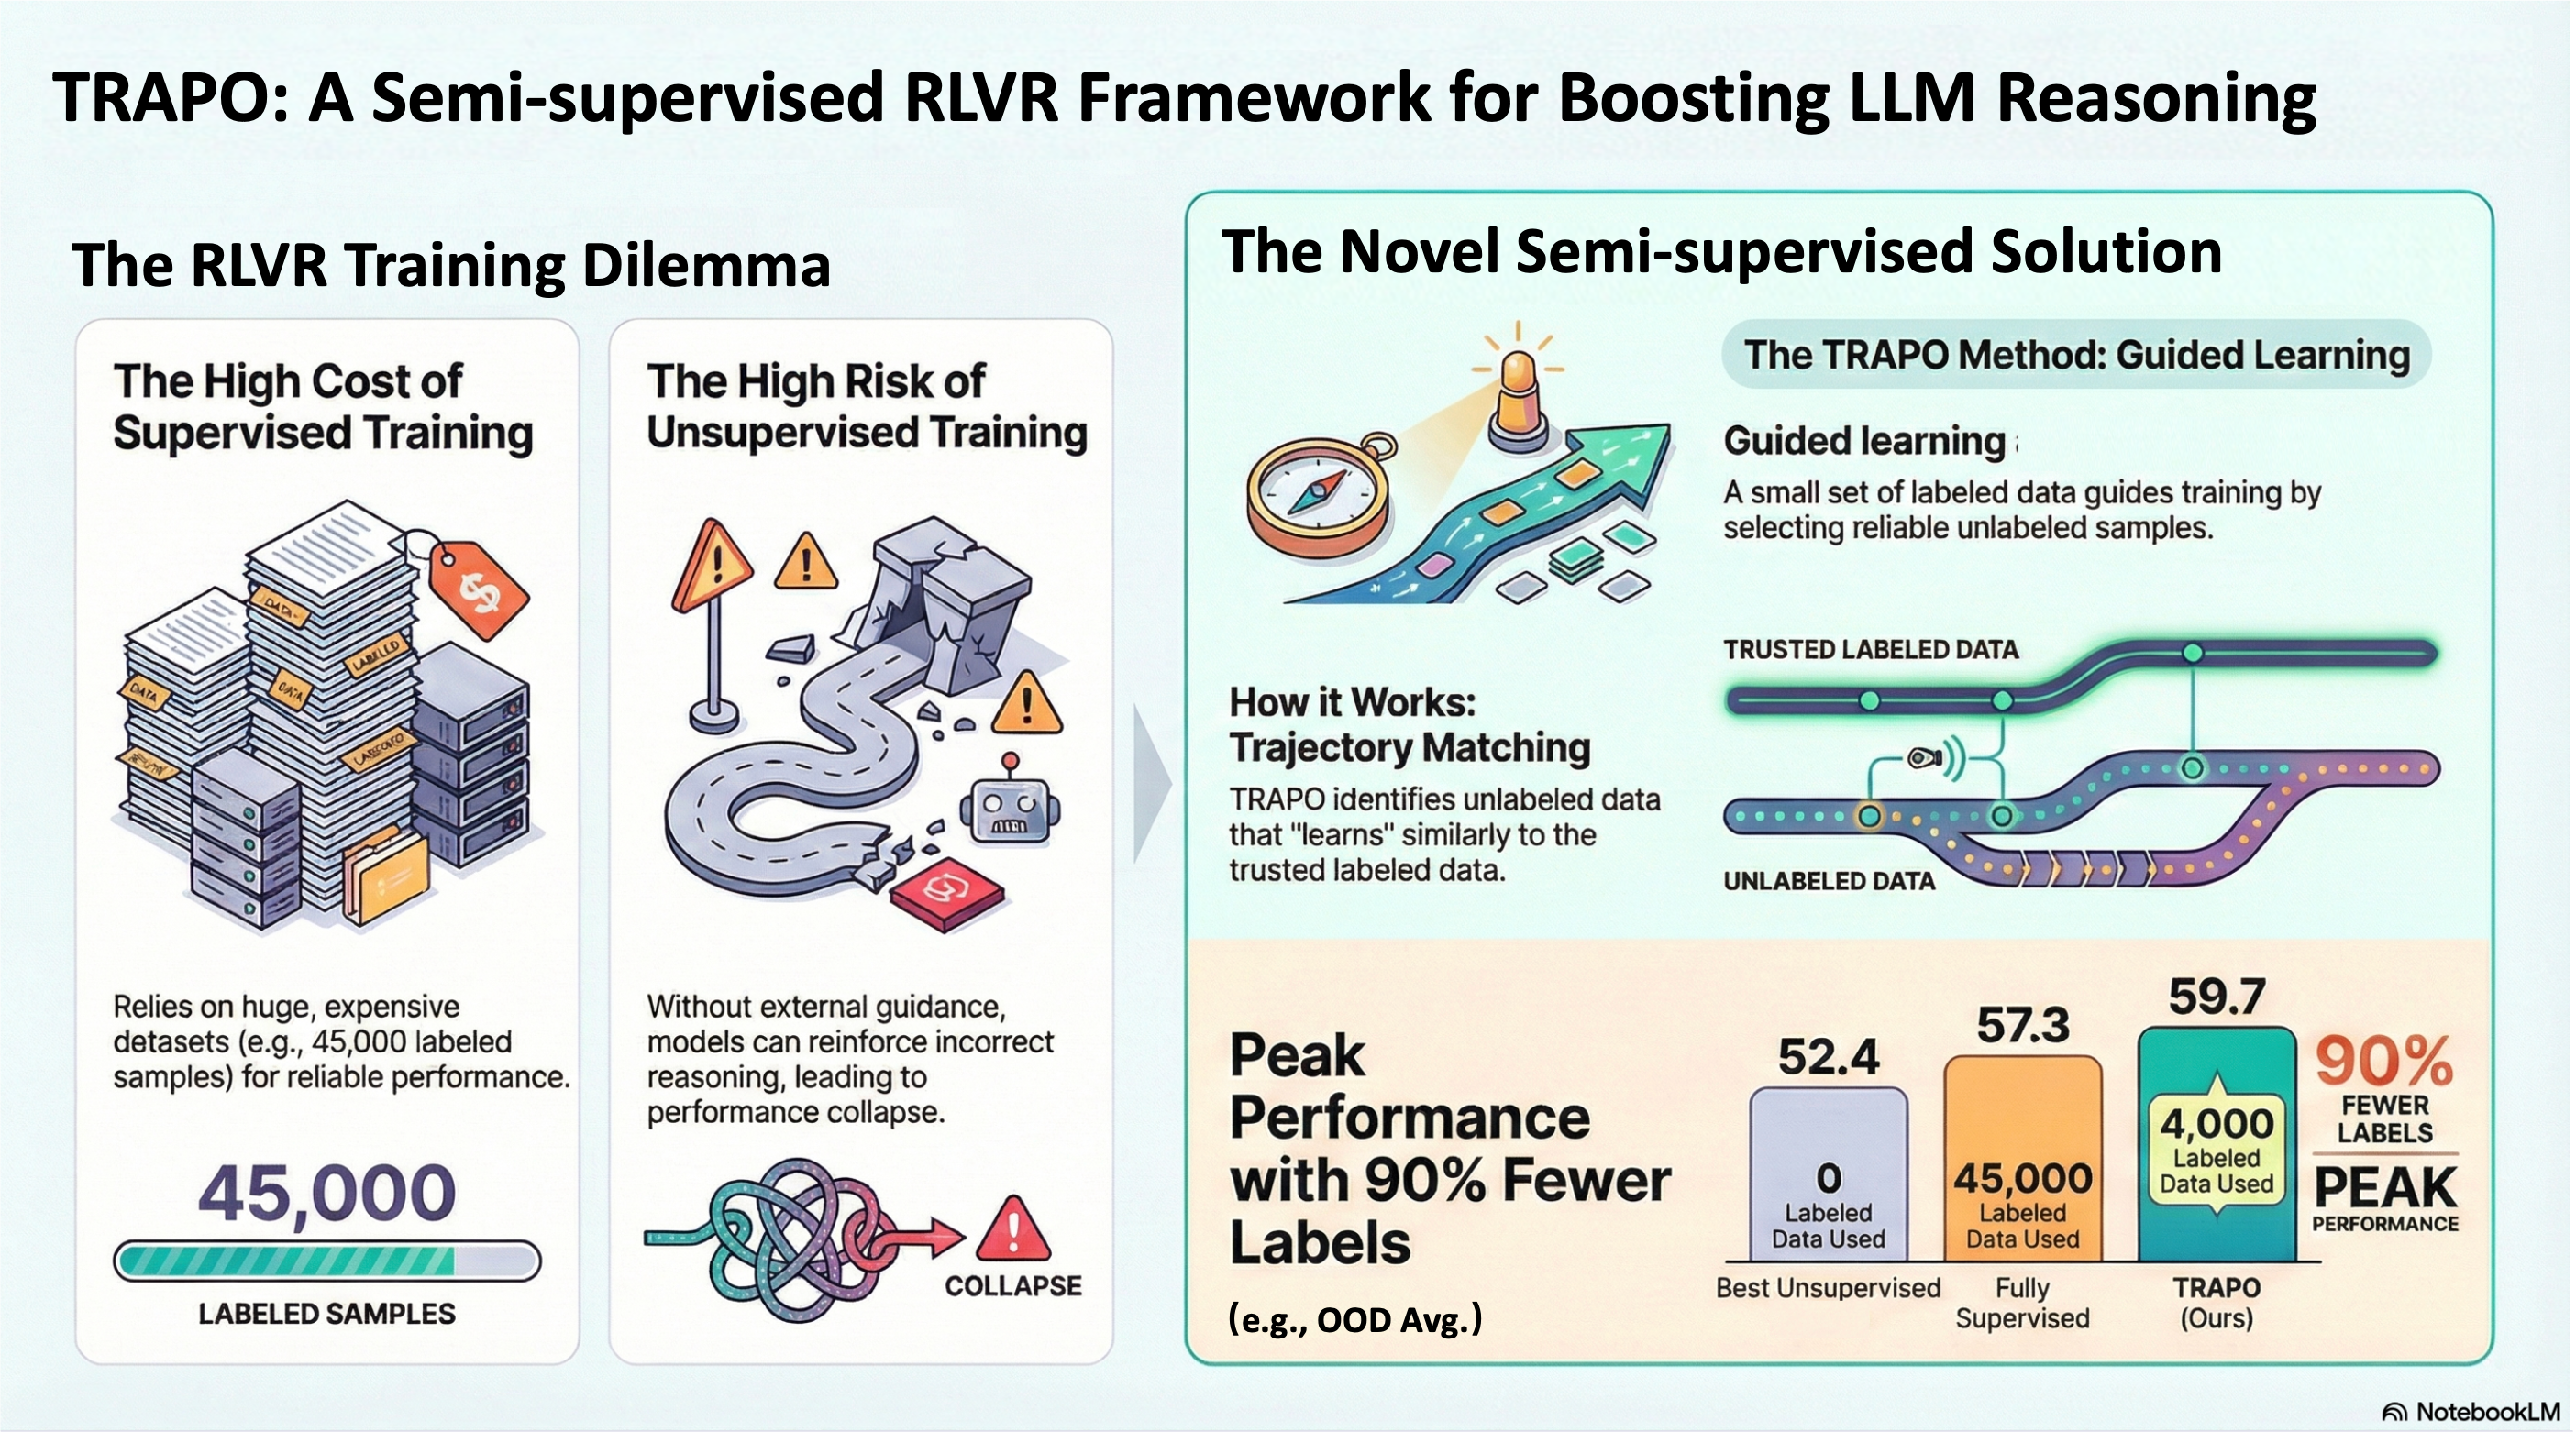
Built upon GRPO, TraPO leverages a small set of labeled examples to guide training on unlabeled data, ensuring that only reasoning patterns verified on labeled instances are reinforced. Its core component identifies reliable unlabeled samples by matching their learning trajectories to those of labeled ones, stabilizing consistency-based training and mitigating model collapse caused by unchecked self-reinforcement.
✨Getting Started
Installation
You can install TRAPO dependencies by running the following commands:
conda create -n trapo python=3.10
conda activate trapo
cd TRAPO
pip install -r requirements.txt
pip3 install -e .[vllm]
pip3 install math-verify==0.8.0
Repo Structure
This repository includes:
Weakly_Supervised: [Recommended] In this folder, we provide a more flexible and concise implementation interface for TraPO.initial/original_TraPO: Codes for reproduce our experiment results in the paper.
🔧Usage
Data Preparation
To run TraPO for semi-supervised RLVR training, you only need to annotate whether each sample is labeled or not in the extra_info field, in addition to your regular data. For details, please refer to the file ./data/code/merge_and_label.py.
For the data required to reproduce the experiments in the paper, please follow the instructions in initial/original_TraPO/README.md.
Training
We provide an example script to train TraPO in Weakly_Supervised/scripts/run:
bash run_semi.sh
Models
The model weights will be uploaded to HuggingFace later.
📃Evaluation
Reproducing the Results
We currently support automated evaluation on six widely used mathematical reasoning benchmarks (AIME24/25, AMC, MATH-500, Minerva, and Olympiad) and three out-of-distribution tasks (ARC-c, GPQA-diamond, and MMLU-pro).
ROOT=YourRootPath
TASK=math # math arc_c gpqa mmlu_pro
CKPT=labeled_1k_unlabeled_1k_ood

DATA=$ROOT/data/valid.$TASK.parquet
OUTPUT_DIR=$ROOT/results/$CKPT-$TASK/
mkdir -p $OUTPUT_DIR

# If you want to evaluate other models, you can change the model path and name.
MODEL_PATH=YourModelPath

if [ $MODEL_NAME == "eurus-2-7b-prime-zero" ]; then
  TEMPLATE=prime
elif [ $MODEL_NAME == "simple-rl-zero" ]; then
  TEMPLATE=qwen
else
  TEMPLATE=own
fi

CUDA_VISIBLE_DEVICES=0,1,2,3 python $ROOT/Weakly_Supervised/scripts/eval/generate_vllm.py \
  --model_path $MODEL_PATH \
  --input_file $DATA \
  --remove_system True \
  --add_oat_evaluate True \
  --output_file $OUTPUT_DIR/$MODEL_NAME.jsonl \
  --template $TEMPLATE > $OUTPUT_DIR/$MODEL_NAME.log
Citation
If you find our code useful, please kindly cite our paper:
@article{yang2025trapo,
  title={TraPO: A Semi-Supervised Reinforcement Learning Framework for Boosting LLM Reasoning},
  author={Yang, Shenzhi and Zhu, Guangcheng and Zheng, Xing and MA, Yingfan and Chen, Zhongqi and Song, Bowen and Wang, Weiqiang and Zhao, Junbo and Chen, Gang and Wang, Haobo},
  journal={arXiv preprint arXiv:2512.13106},
  year={2025}
}
🌻Acknowledgement
TRAPO builds upon LUFFY, veRL and deepscaler, and utilizes vLLM for inference. We utilize Math-Verify for math reasoning evaluation. We thank the open-source community for datasets and backbones, including DeepMath, NuminaMath, OpenR1-Math-220k, Qwen2.5-Math, and DeepSeek-R1 model. Lastly, we would like to express our gratitude to NotebookLM for creating the illustrative diagram of TRAPO.
📬 Contact
For questions, feedback, or collaboration opportunities, feel free to reach out:
- Shenzhi Yang: yangshenzhi@zju.edu.cn
Contributors

10 commits
Similar repos


Languages
Python
89.8%
Shell
6.1%
Jupyter Notebook
4.0%
Official Repository of "[ICLR26] TRAPO: A Semi-Supervised Reinforcement Learning Framework for Boosting LLM Reasoning"
Python
29
10 commits
updated Feb 6, 2026
README
TRAPO: A Semi-Supervised Reinforcement Learning Framework for Boosting LLM Reasoning.
TRAPO is A Friend : )
📚 Overview
- 🎉 News
- 📖 Introduction
- ✨ Getting Started
- 🔧 Usage
- 📃 Evaluation
- 🎈 Citation
- 🌻 Acknowledgement
🎉News
- [2025/12/10] TRAPO codebase is released along with evaluation scripts. Try it out!
📖Introduction
TraPO is a semi-supervised reinforcement learning framework that bridges unlabeled and labeled samples for training large reasoning models (LRMs).
Built upon GRPO, TraPO leverages a small set of labeled examples to guide training on unlabeled data, ensuring that only reasoning patterns verified on labeled instances are reinforced. Its core component identifies reliable unlabeled samples by matching their learning trajectories to those of labeled ones, stabilizing consistency-based training and mitigating model collapse caused by unchecked self-reinforcement.
✨Getting Started
Installation
You can install TRAPO dependencies by running the following commands:
conda create -n trapo python=3.10
conda activate trapo
cd TRAPO
pip install -r requirements.txt
pip3 install -e .[vllm]
pip3 install math-verify==0.8.0
Repo Structure
This repository includes:
Weakly_Supervised: [Recommended] In this folder, we provide a more flexible and concise implementation interface for TraPO.initial/original_TraPO: Codes for reproduce our experiment results in the paper.
🔧Usage
Data Preparation
To run TraPO for semi-supervised RLVR training, you only need to annotate whether each sample is labeled or not in the extra_info field, in addition to your regular data. For details, please refer to the file ./data/code/merge_and_label.py.
For the data required to reproduce the experiments in the paper, please follow the instructions in initial/original_TraPO/README.md.
Training
We provide an example script to train TraPO in Weakly_Supervised/scripts/run:
bash run_semi.sh
Models
The model weights will be uploaded to HuggingFace later.
📃Evaluation
Reproducing the Results
We currently support automated evaluation on six widely used mathematical reasoning benchmarks (AIME24/25, AMC, MATH-500, Minerva, and Olympiad) and three out-of-distribution tasks (ARC-c, GPQA-diamond, and MMLU-pro).
ROOT=YourRootPath
TASK=math # math arc_c gpqa mmlu_pro
CKPT=labeled_1k_unlabeled_1k_ood

DATA=$ROOT/data/valid.$TASK.parquet
OUTPUT_DIR=$ROOT/results/$CKPT-$TASK/
mkdir -p $OUTPUT_DIR

# If you want to evaluate other models, you can change the model path and name.
MODEL_PATH=YourModelPath

if [ $MODEL_NAME == "eurus-2-7b-prime-zero" ]; then
  TEMPLATE=prime
elif [ $MODEL_NAME == "simple-rl-zero" ]; then
  TEMPLATE=qwen
else
  TEMPLATE=own
fi

CUDA_VISIBLE_DEVICES=0,1,2,3 python $ROOT/Weakly_Supervised/scripts/eval/generate_vllm.py \
  --model_path $MODEL_PATH \
  --input_file $DATA \
  --remove_system True \
  --add_oat_evaluate True \
  --output_file $OUTPUT_DIR/$MODEL_NAME.jsonl \
  --template $TEMPLATE > $OUTPUT_DIR/$MODEL_NAME.log
Citation
If you find our code useful, please kindly cite our paper:
@article{yang2025trapo,
  title={TraPO: A Semi-Supervised Reinforcement Learning Framework for Boosting LLM Reasoning},
  author={Yang, Shenzhi and Zhu, Guangcheng and Zheng, Xing and MA, Yingfan and Chen, Zhongqi and Song, Bowen and Wang, Weiqiang and Zhao, Junbo and Chen, Gang and Wang, Haobo},
  journal={arXiv preprint arXiv:2512.13106},
  year={2025}
}
🌻Acknowledgement
TRAPO builds upon LUFFY, veRL and deepscaler, and utilizes vLLM for inference. We utilize Math-Verify for math reasoning evaluation. We thank the open-source community for datasets and backbones, including DeepMath, NuminaMath, OpenR1-Math-220k, Qwen2.5-Math, and DeepSeek-R1 model. Lastly, we would like to express our gratitude to NotebookLM for creating the illustrative diagram of TRAPO.
📬 Contact
For questions, feedback, or collaboration opportunities, feel free to reach out:
- Shenzhi Yang: yangshenzhi@zju.edu.cn
Similar repos
Contributors
10 commits
Languages
Python
89.8%
Shell
6.1%
Jupyter Notebook
4.0%