

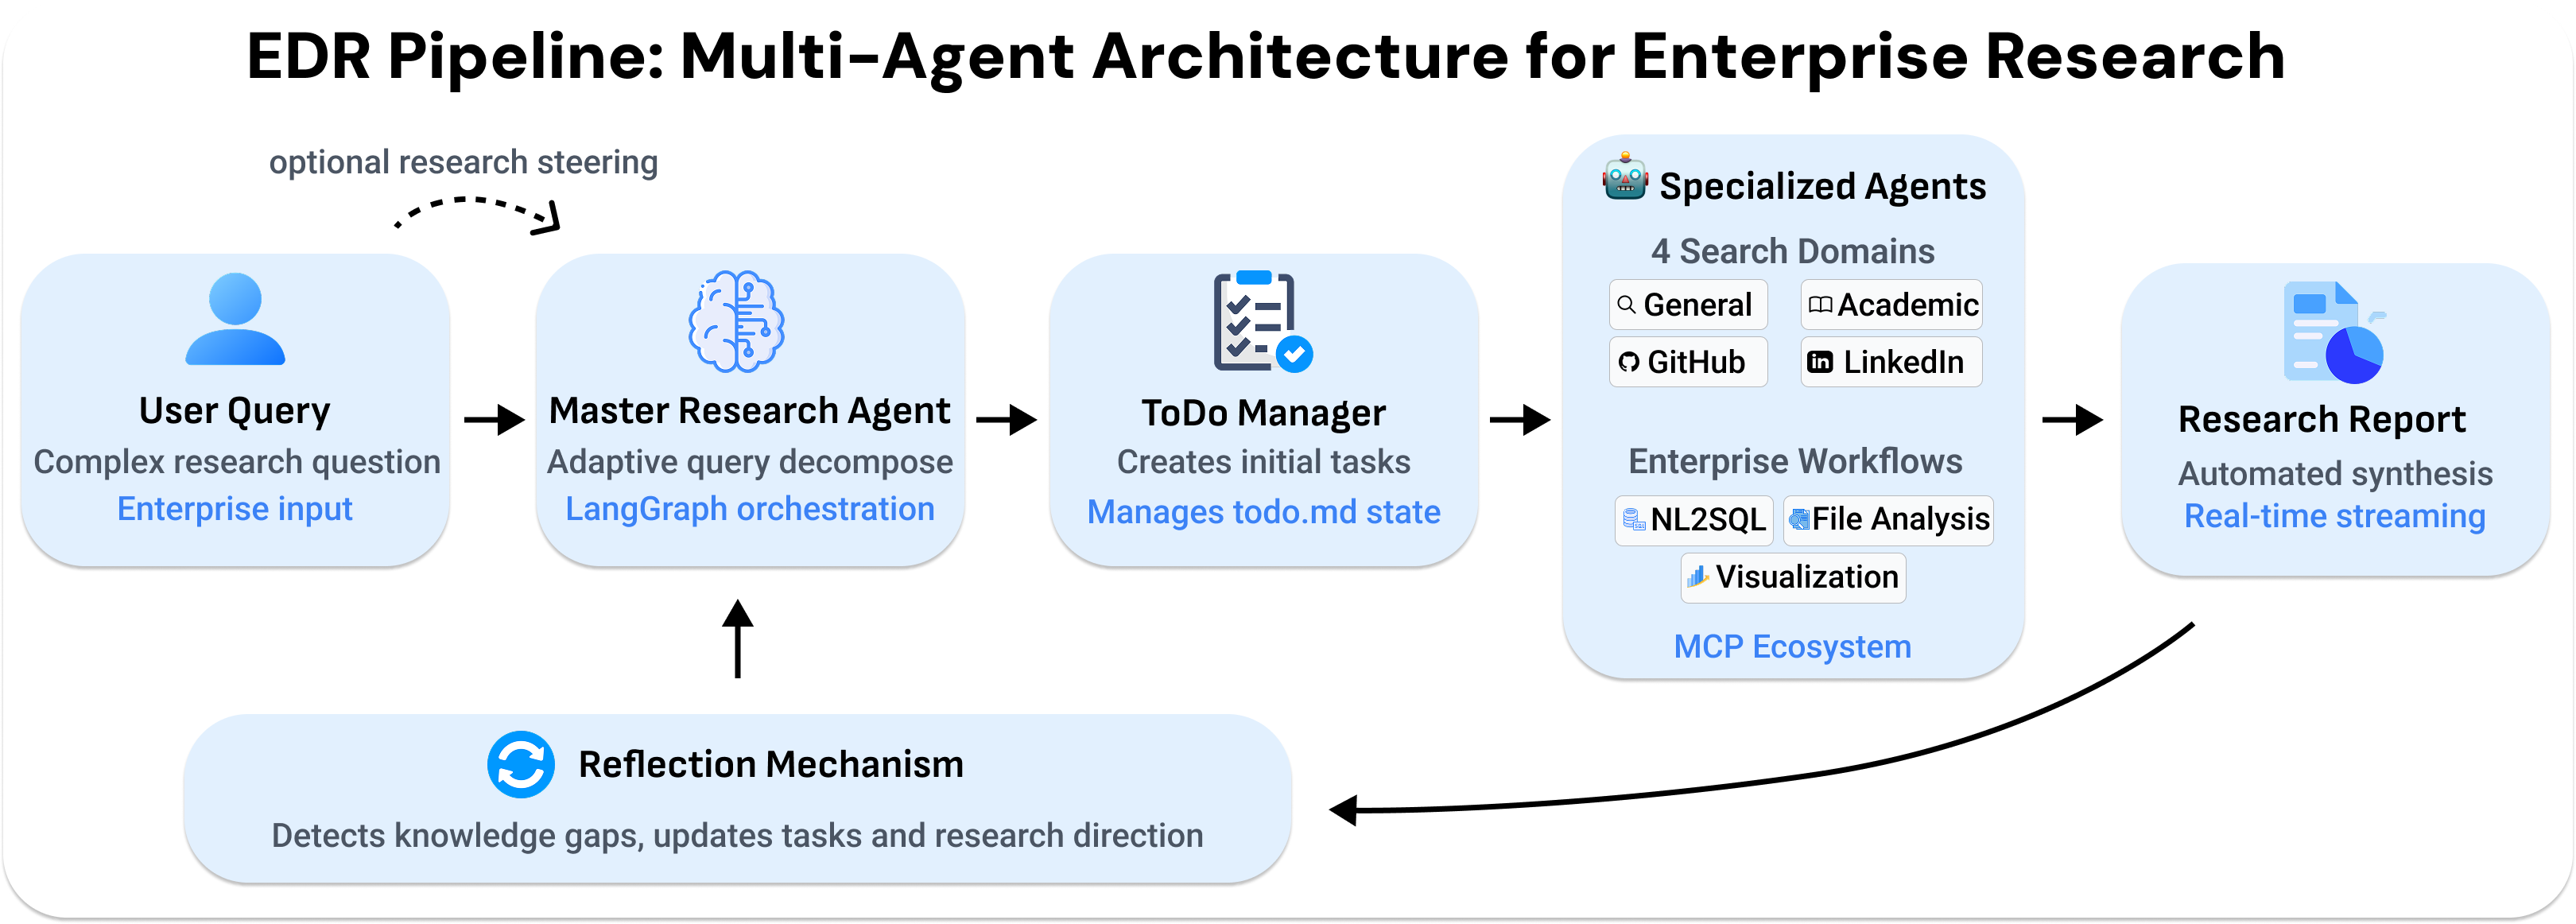
We present Enterprise Deep Research (EDR), a multi-agent system that integrate:
[!Note] These components enable automated report generation, real-time streaming, and seamless enterprise deployment, as validated on internal datasets.
We present a video demo of using EDR in web application for enterprise deep data analysis.
https://github.com/user-attachments/assets/b40b6131-3b7c-4e5f-8de3-91a4047ade58
[!Note] Multi-provider LLM support • Slack agent • Real-time streaming • Document analysis • Citation management • Parallel processing • Specialized benchmarking • Human-in-the-loop steering
Requirements: Python 3.11+ • Node.js 20.9.0+
# Clone and setup
git clone https://github.com/SalesforceAIResearch/enterprise-deep-research.git
cd enterprise-deep-research

# Python environment
python -m venv venv
source venv/bin/activate  # Windows: venv\Scripts\activate
pip install -r requirements.txt

# Configure environment
cp .env.sample .env
# Edit .env with your API keys

# Frontend setup
cd ai-research-assistant && npm install && npm run build && cd ..
Required Variables:
TAVILY_API_KEY - Tavily search API keyOPENAI_API_KEY - OpenAI API keyANTHROPIC_API_KEY - Anthropic API keyGROQ_API_KEY - Groq API keyGOOGLE_CLOUD_PROJECT - Google Cloud project IDSAMBNOVA_API_KEY - SambaNova API keyOptional Settings:
LLM_PROVIDER - Default provider (default: openai)LLM_MODEL - Model name (provider-specific defaults)MAX_WEB_RESEARCH_LOOPS - Max iterations (default: 10)| Provider | Default Model | Available Models |
|---|---|---|
| OpenAI | o4-mini | o4-mini, o4-mini-high, o3-mini, o3-mini-reasoning, gpt-4o |
| Anthropic | claude-sonnet-4 | claude-sonnet-4, claude-sonnet-4-thinking, claude-3-7-sonnet, claude-3-7-sonnet-thinking |
gemini-2.5-pro | gemini-2.5-pro, gemini-1.5-pro-latest, gemini-1.5-flash-latest | |
| Groq | deepseek-r1-distill-llama-70b | deepseek-r1-distill-llama-70b, llama-3.3-70b-versatile, llama3-70b-8192 |
| SambaNova | DeepSeek-V3-0324 | DeepSeek-V3-0324 |
Full Stack (Recommended) - Single Command:
python -m uvicorn app:app --host 0.0.0.0 --port 8000
The application will serve both the backend API and pre-built frontend at http://localhost:8000
Backend API Documentation: http://localhost:8000/docs
python benchmarks/run_research.py "Your research question" \
  --provider openai --model o3-mini --max-loops 3
Navigate to http://localhost:8000 for interactive research with real-time progress tracking.
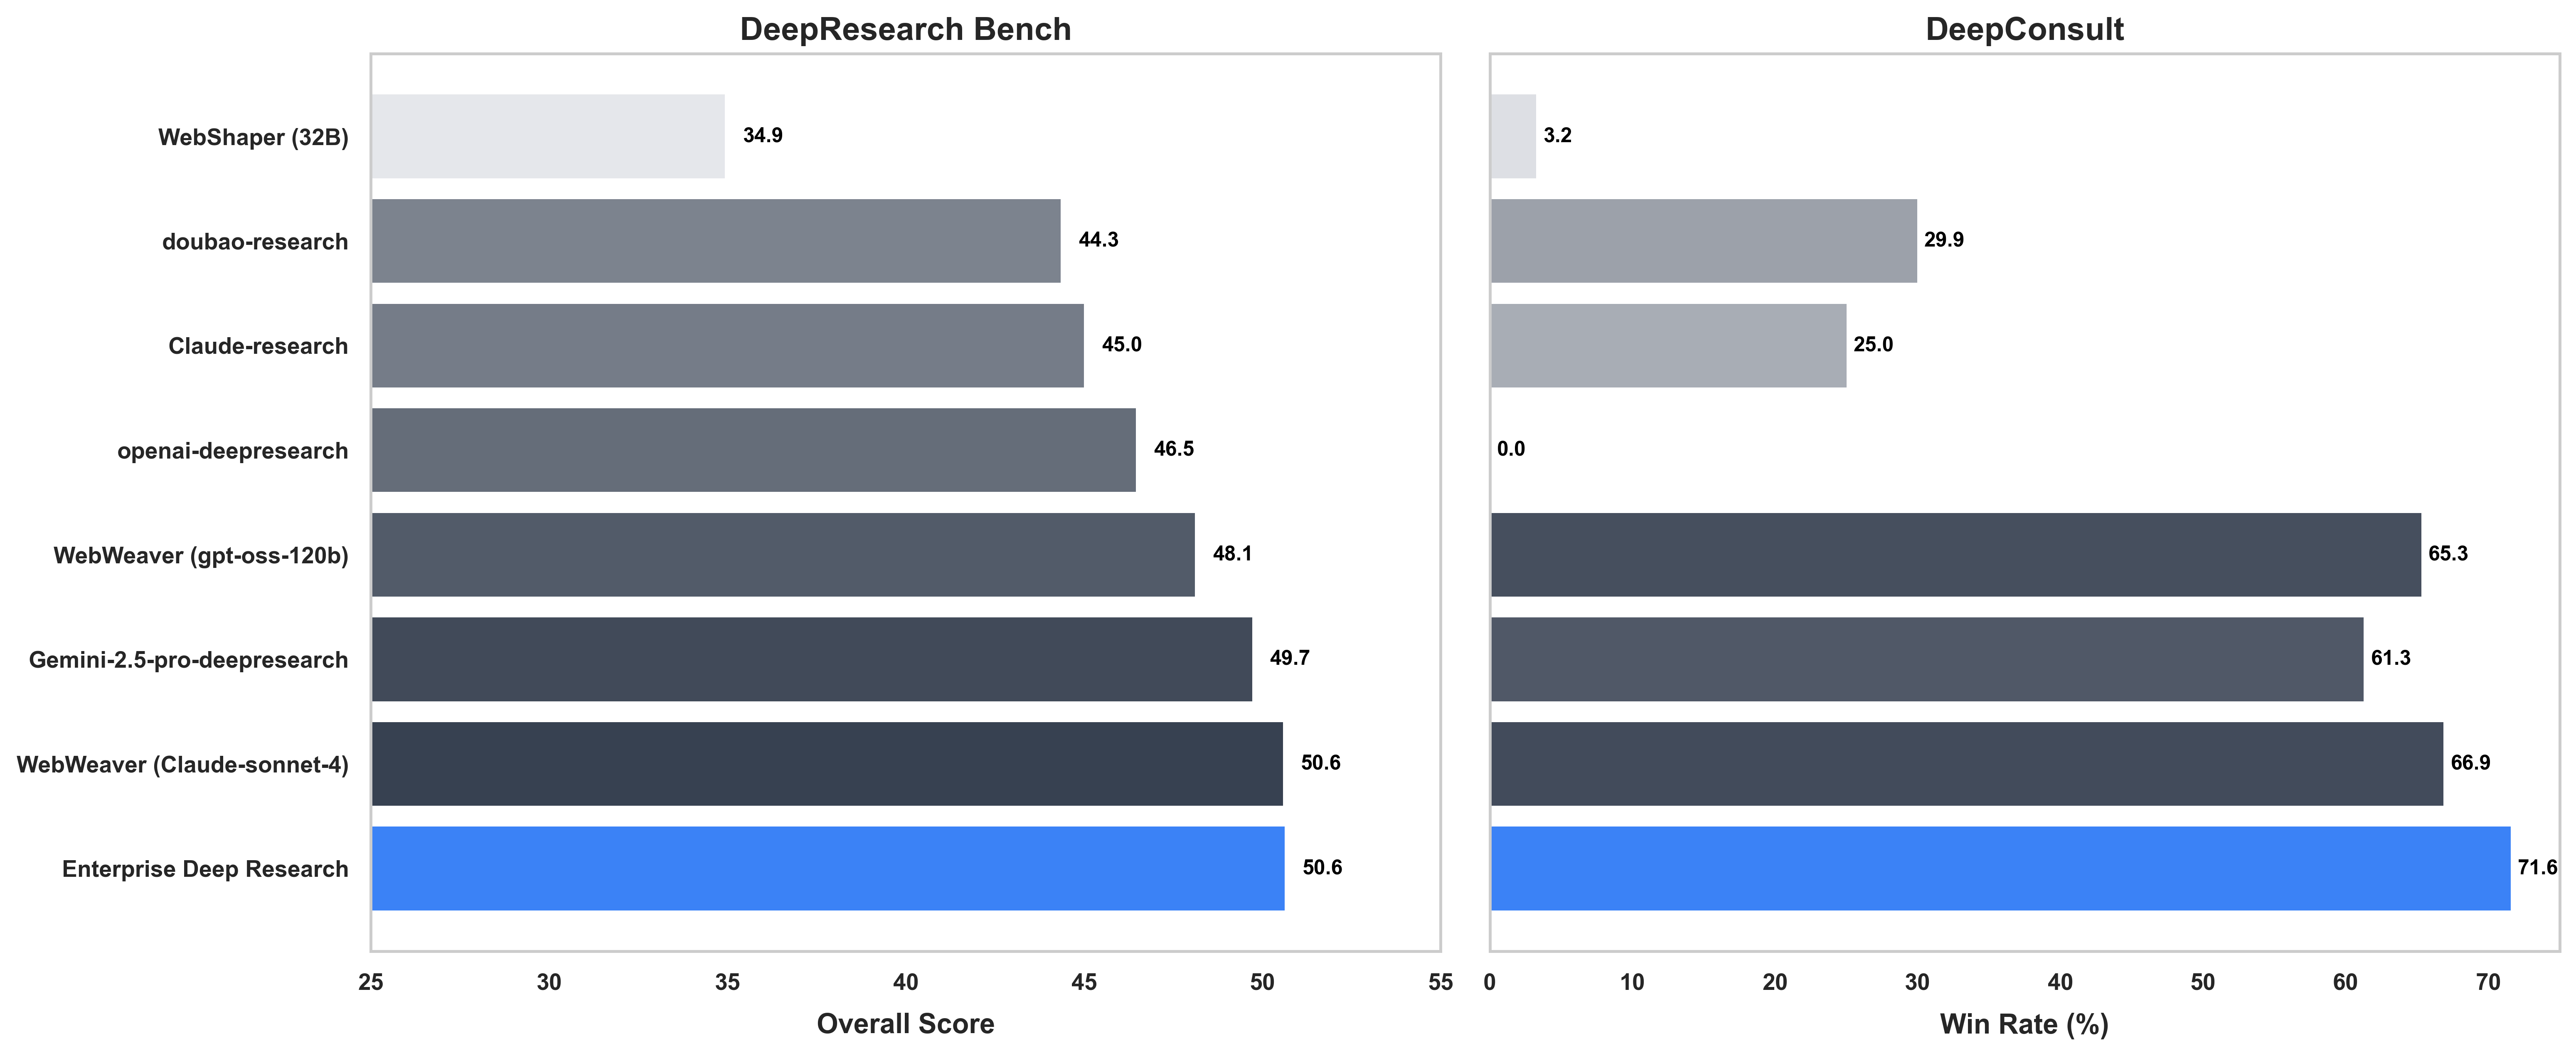
The EDR-200 dataset contains 201 complete agentic research trajectories generated by Enterprise Deep Research—99 queries from DeepResearch Bench and 102 queries from DeepConsult. Unlike prior benchmarks that only capture final outputs, these trajectories expose the full reasoning process across search, reflection, and synthesis steps, enabling fine-grained analysis of agentic planning and decision-making dynamics.
Refer to our detailed benchmarking guide.
# Testing
python -m pytest tests/
python test_agents.py

# Code quality
black src/ services/ benchmarks/
mypy src/ services/
flake8 src/ services/ benchmarks/

# Development server
python -m uvicorn app:app --reload --host 0.0.0.0 --port 8000
cd ai-research-assistant && npm run dev
enterprise-deep-research/
├── ai-research-assistant/       # React frontend
├── benchmarks/                  # Evaluation framework
├── src/                        # Core research engine
│   ├── agent_architecture.py   # Multi-agent orchestration
│   ├── graph.py               # LangGraph workflow definitions
│   ├── state.py               # Research state management
│   ├── simple_steering.py     # Steering & task management
│   ├── steering_integration.py # Steering integration layer
│   ├── prompts.py             # Agent prompts & templates
│   ├── configuration.py       # Agent configuration
│   ├── utils.py               # Utility functions
│   ├── visualization_agent.py # Visualization generation
│   └── tools/                 # Research tools & MCP integration
├── services/                   # Backend services (research, analysis, parsing)
├── routers/                    # FastAPI endpoints
├── models/                     # Data schemas
├── app.py                      # Main FastAPI application
├── llm_clients.py              # LLM provider clients
├── session_store.py            # Session management
└── requirements.txt            # Python dependencies
Licensed under Apache 2.0.
@article{prabhakar2025enterprisedeepresearch,
  title={Enterprise Deep Research: Steerable Multi-Agent Deep Research for Enterprise Analytics},
  author={Prabhakar, Akshara and Ram, Roshan and Chen, Zixiang and Savarese, Silvio and Wang, Frank and Xiong, Caiming and Wang, Huan and Yao, Weiran},
  journal={arXiv preprint arXiv:2510.17797},
  year={2025}
}
We would love to hear from the broader AI community, and we welcome any contributions, pull requests, or issues! Please refer to contributing guidelines.
For questions, suggestions, or contributions, please contact: Akshara Prabhakar
Acknowledgments: Built on LangGraph, Tavily, React, Tailwind CSS, and FastAPI.
177 followers · starred Feb 2026
169 followers · starred Feb 2026
4,415 followers · starred Oct 2025
176 followers · starred Dec 2025
We present Enterprise Deep Research (EDR), a multi-agent system that integrate:
[!Note] These components enable automated report generation, real-time streaming, and seamless enterprise deployment, as validated on internal datasets.
We present a video demo of using EDR in web application for enterprise deep data analysis.
https://github.com/user-attachments/assets/b40b6131-3b7c-4e5f-8de3-91a4047ade58
[!Note] Multi-provider LLM support • Slack agent • Real-time streaming • Document analysis • Citation management • Parallel processing • Specialized benchmarking • Human-in-the-loop steering
Requirements: Python 3.11+ • Node.js 20.9.0+
# Clone and setup
git clone https://github.com/SalesforceAIResearch/enterprise-deep-research.git
cd enterprise-deep-research

# Python environment
python -m venv venv
source venv/bin/activate  # Windows: venv\Scripts\activate
pip install -r requirements.txt

# Configure environment
cp .env.sample .env
# Edit .env with your API keys

# Frontend setup
cd ai-research-assistant && npm install && npm run build && cd ..
Required Variables:
TAVILY_API_KEY - Tavily search API keyOPENAI_API_KEY - OpenAI API keyANTHROPIC_API_KEY - Anthropic API keyGROQ_API_KEY - Groq API keyGOOGLE_CLOUD_PROJECT - Google Cloud project IDSAMBNOVA_API_KEY - SambaNova API keyOptional Settings:
LLM_PROVIDER - Default provider (default: openai)LLM_MODEL - Model name (provider-specific defaults)MAX_WEB_RESEARCH_LOOPS - Max iterations (default: 10)| Provider | Default Model | Available Models |
|---|---|---|
| OpenAI | o4-mini | o4-mini, o4-mini-high, o3-mini, o3-mini-reasoning, gpt-4o |
| Anthropic | claude-sonnet-4 | claude-sonnet-4, claude-sonnet-4-thinking, claude-3-7-sonnet, claude-3-7-sonnet-thinking |
gemini-2.5-pro | gemini-2.5-pro, gemini-1.5-pro-latest, gemini-1.5-flash-latest | |
| Groq | deepseek-r1-distill-llama-70b | deepseek-r1-distill-llama-70b, llama-3.3-70b-versatile, llama3-70b-8192 |
| SambaNova | DeepSeek-V3-0324 | DeepSeek-V3-0324 |
Full Stack (Recommended) - Single Command:
python -m uvicorn app:app --host 0.0.0.0 --port 8000
The application will serve both the backend API and pre-built frontend at http://localhost:8000
Backend API Documentation: http://localhost:8000/docs
python benchmarks/run_research.py "Your research question" \
  --provider openai --model o3-mini --max-loops 3
Navigate to http://localhost:8000 for interactive research with real-time progress tracking.
The EDR-200 dataset contains 201 complete agentic research trajectories generated by Enterprise Deep Research—99 queries from DeepResearch Bench and 102 queries from DeepConsult. Unlike prior benchmarks that only capture final outputs, these trajectories expose the full reasoning process across search, reflection, and synthesis steps, enabling fine-grained analysis of agentic planning and decision-making dynamics.
Refer to our detailed benchmarking guide.
# Testing
python -m pytest tests/
python test_agents.py

# Code quality
black src/ services/ benchmarks/
mypy src/ services/
flake8 src/ services/ benchmarks/

# Development server
python -m uvicorn app:app --reload --host 0.0.0.0 --port 8000
cd ai-research-assistant && npm run dev
enterprise-deep-research/
├── ai-research-assistant/       # React frontend
├── benchmarks/                  # Evaluation framework
├── src/                        # Core research engine
│   ├── agent_architecture.py   # Multi-agent orchestration
│   ├── graph.py               # LangGraph workflow definitions
│   ├── state.py               # Research state management
│   ├── simple_steering.py     # Steering & task management
│   ├── steering_integration.py # Steering integration layer
│   ├── prompts.py             # Agent prompts & templates
│   ├── configuration.py       # Agent configuration
│   ├── utils.py               # Utility functions
│   ├── visualization_agent.py # Visualization generation
│   └── tools/                 # Research tools & MCP integration
├── services/                   # Backend services (research, analysis, parsing)
├── routers/                    # FastAPI endpoints
├── models/                     # Data schemas
├── app.py                      # Main FastAPI application
├── llm_clients.py              # LLM provider clients
├── session_store.py            # Session management
└── requirements.txt            # Python dependencies
Licensed under Apache 2.0.
@article{prabhakar2025enterprisedeepresearch,
  title={Enterprise Deep Research: Steerable Multi-Agent Deep Research for Enterprise Analytics},
  author={Prabhakar, Akshara and Ram, Roshan and Chen, Zixiang and Savarese, Silvio and Wang, Frank and Xiong, Caiming and Wang, Huan and Yao, Weiran},
  journal={arXiv preprint arXiv:2510.17797},
  year={2025}
}
We would love to hear from the broader AI community, and we welcome any contributions, pull requests, or issues! Please refer to contributing guidelines.
For questions, suggestions, or contributions, please contact: Akshara Prabhakar
Acknowledgments: Built on LangGraph, Tavily, React, Tailwind CSS, and FastAPI.
177 followers · starred Feb 2026
169 followers · starred Feb 2026
4,415 followers · starred Oct 2025
176 followers · starred Dec 2025



