
[ICCV 2025] MM-IFEngine: Towards Multimodal Instruction Following
See the codeREADME
MM-IFEngine: Towards Multimodal Instruction Following
[📃Paper] [🌐Project Page] [🤗Hugging Face] [🛠️Evaluation]
📣 What's New
- ✨ Several prominent multimodal models have adopted MM-IFEngine / MM-IFEval either for benchmarking their multimodal instruction-following performance or for leveraging MM-IFEngine-generated datasets for training, including:
- [2025.12.10] We have released the data filter script and instructions in data_gen/data_filter, feel free to use it!
- [2025.9.16] We have released the v2 dataset (annotated mainly by GPT-4o) in ChrisDing1105/MMIF-23k, feel free to use it!
- [2025.4.26] We have included both the SFT and DPO data in ChrisDing1105/MMIF-23k as part of version 1.0 of the dataset. Feel free to download it! We are also planning to release version 1.1 soon, scheduled for May! 🎉🎉🎉
- [2025.4.24] MM-IFEval has been merged into VLMEvalkit. You can directly evaluate your model on MM-IFEval with it! Usage see Evaluation using VLMEvalkit or more on the Official repo of VLMEvalkit! 🎉🎉🎉
- [2025.4.11] Our MM-IFEngine Paper is released! Check it at 📃Arxiv: MM-IFEngine ! Our Dataset will be open-sourced soon! 🎉🎉🎉
🌟 Highlights
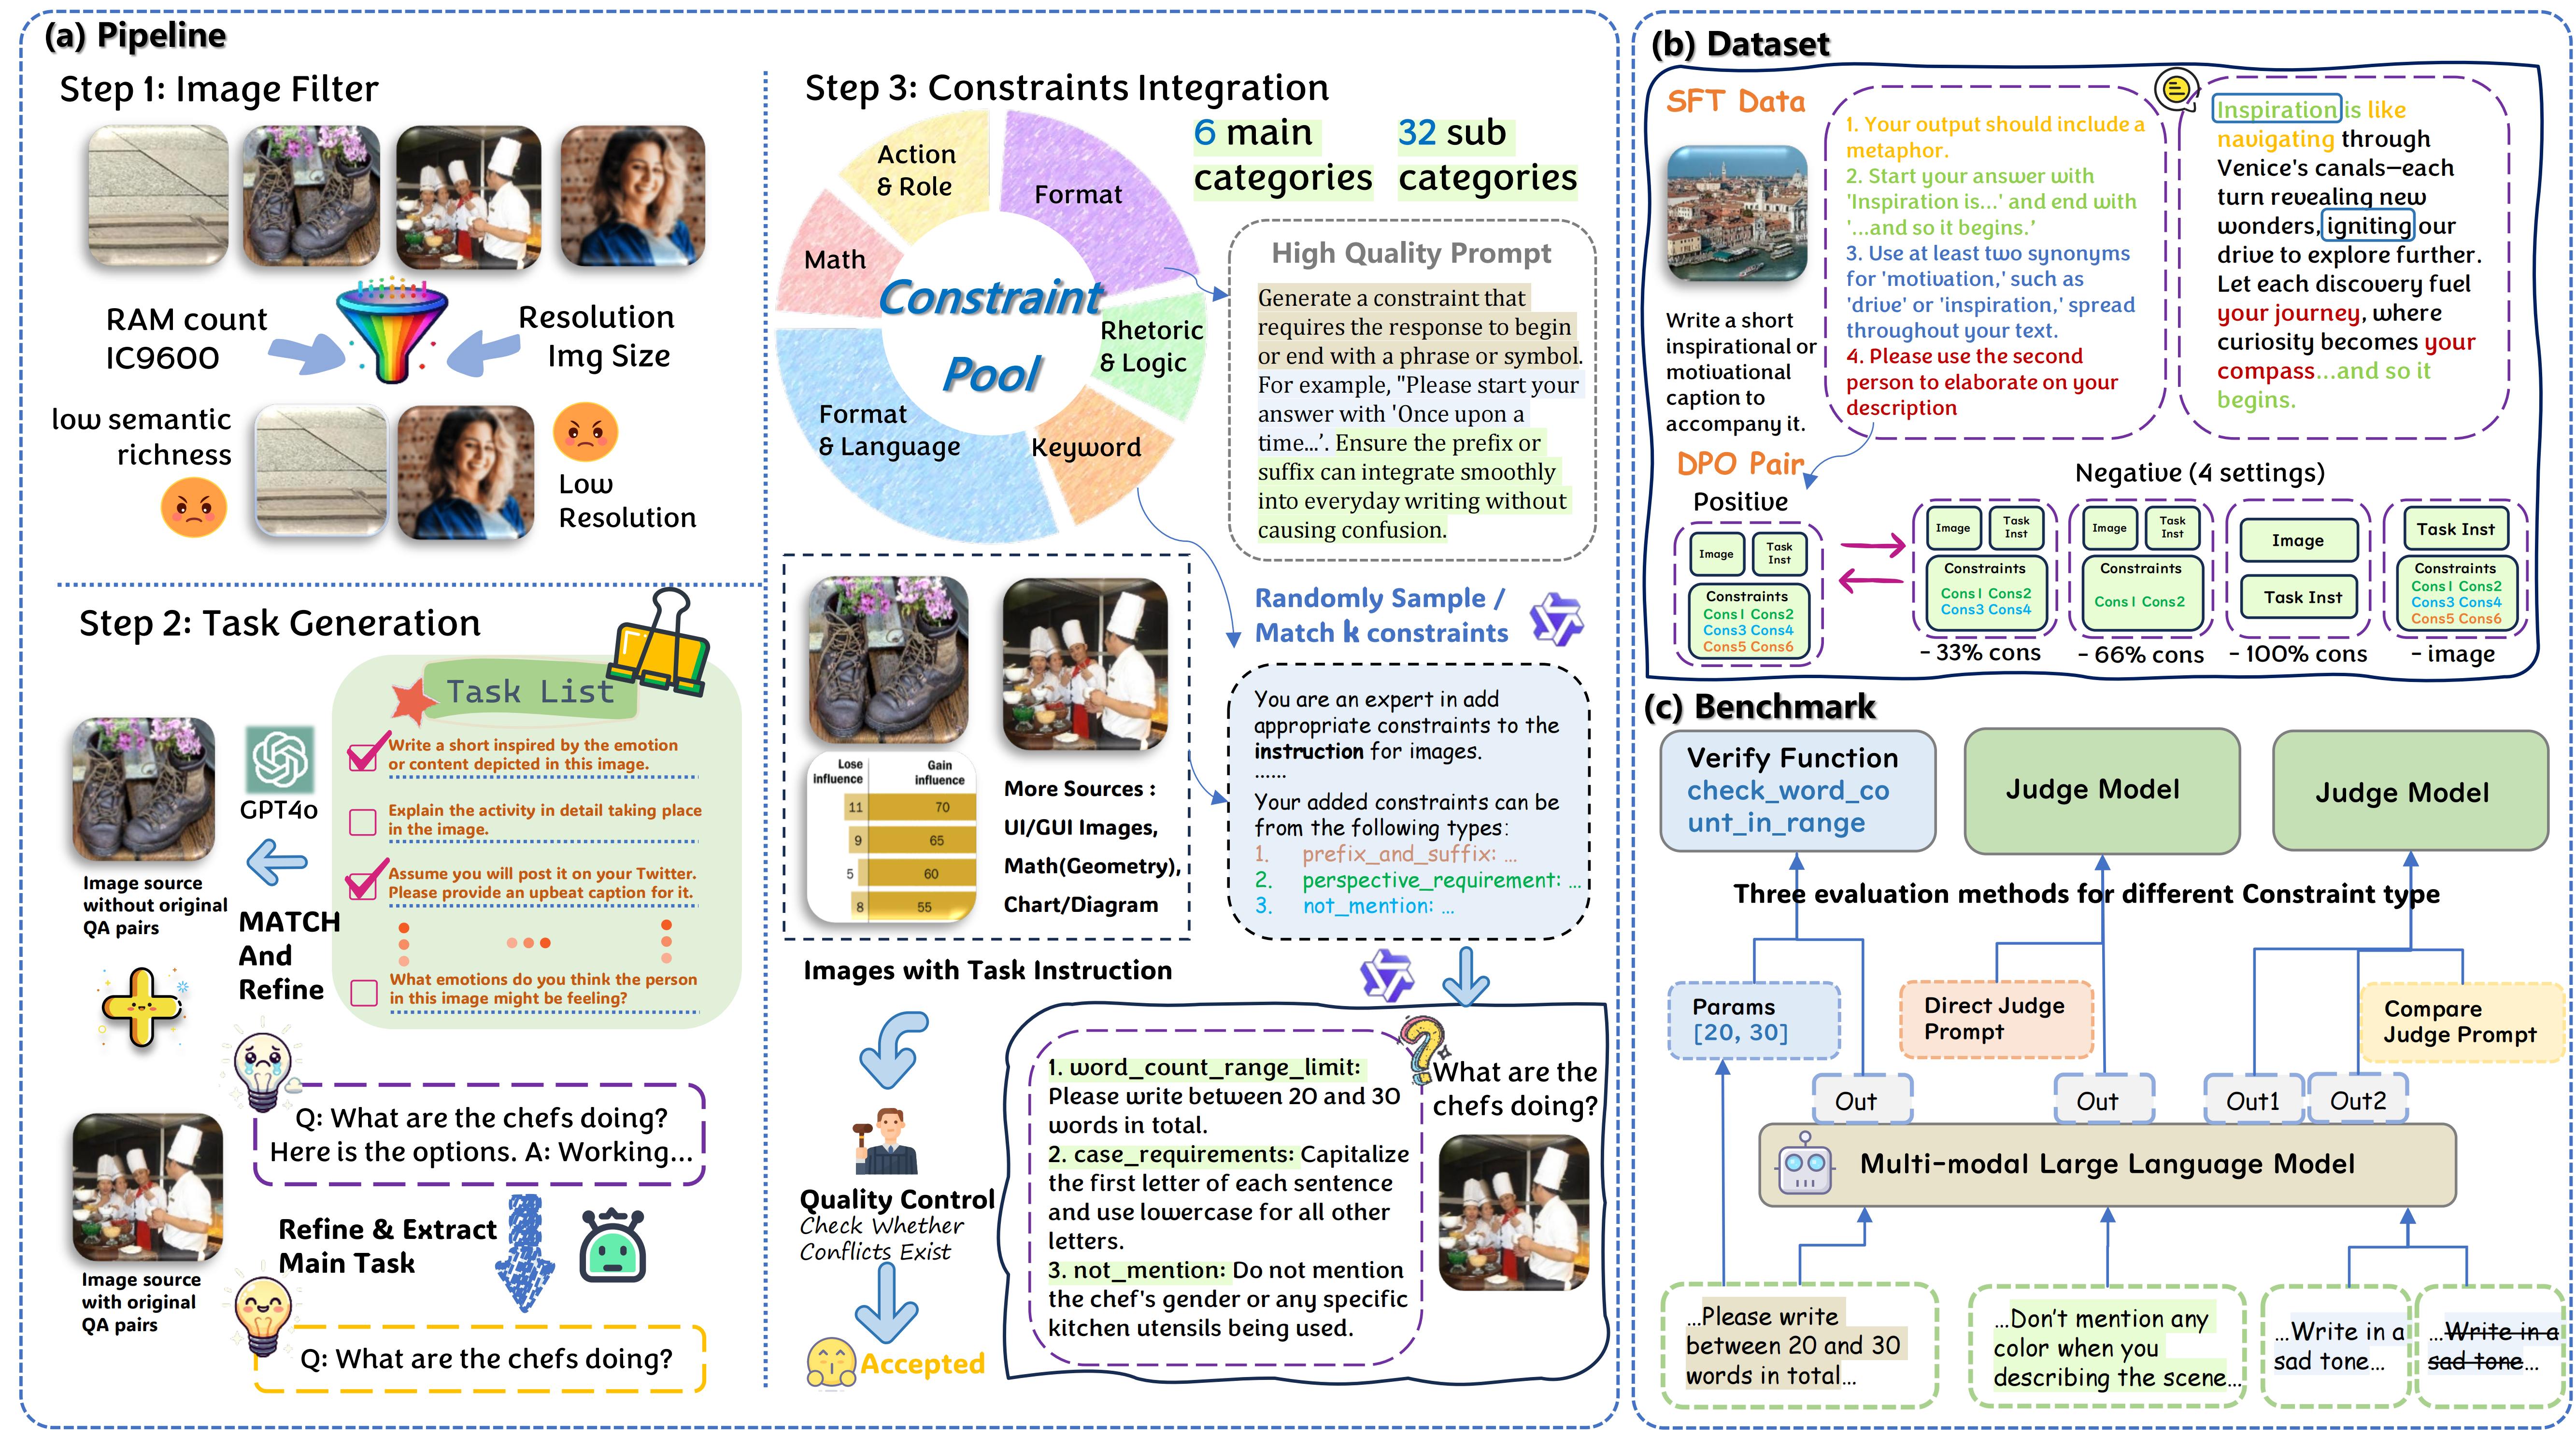
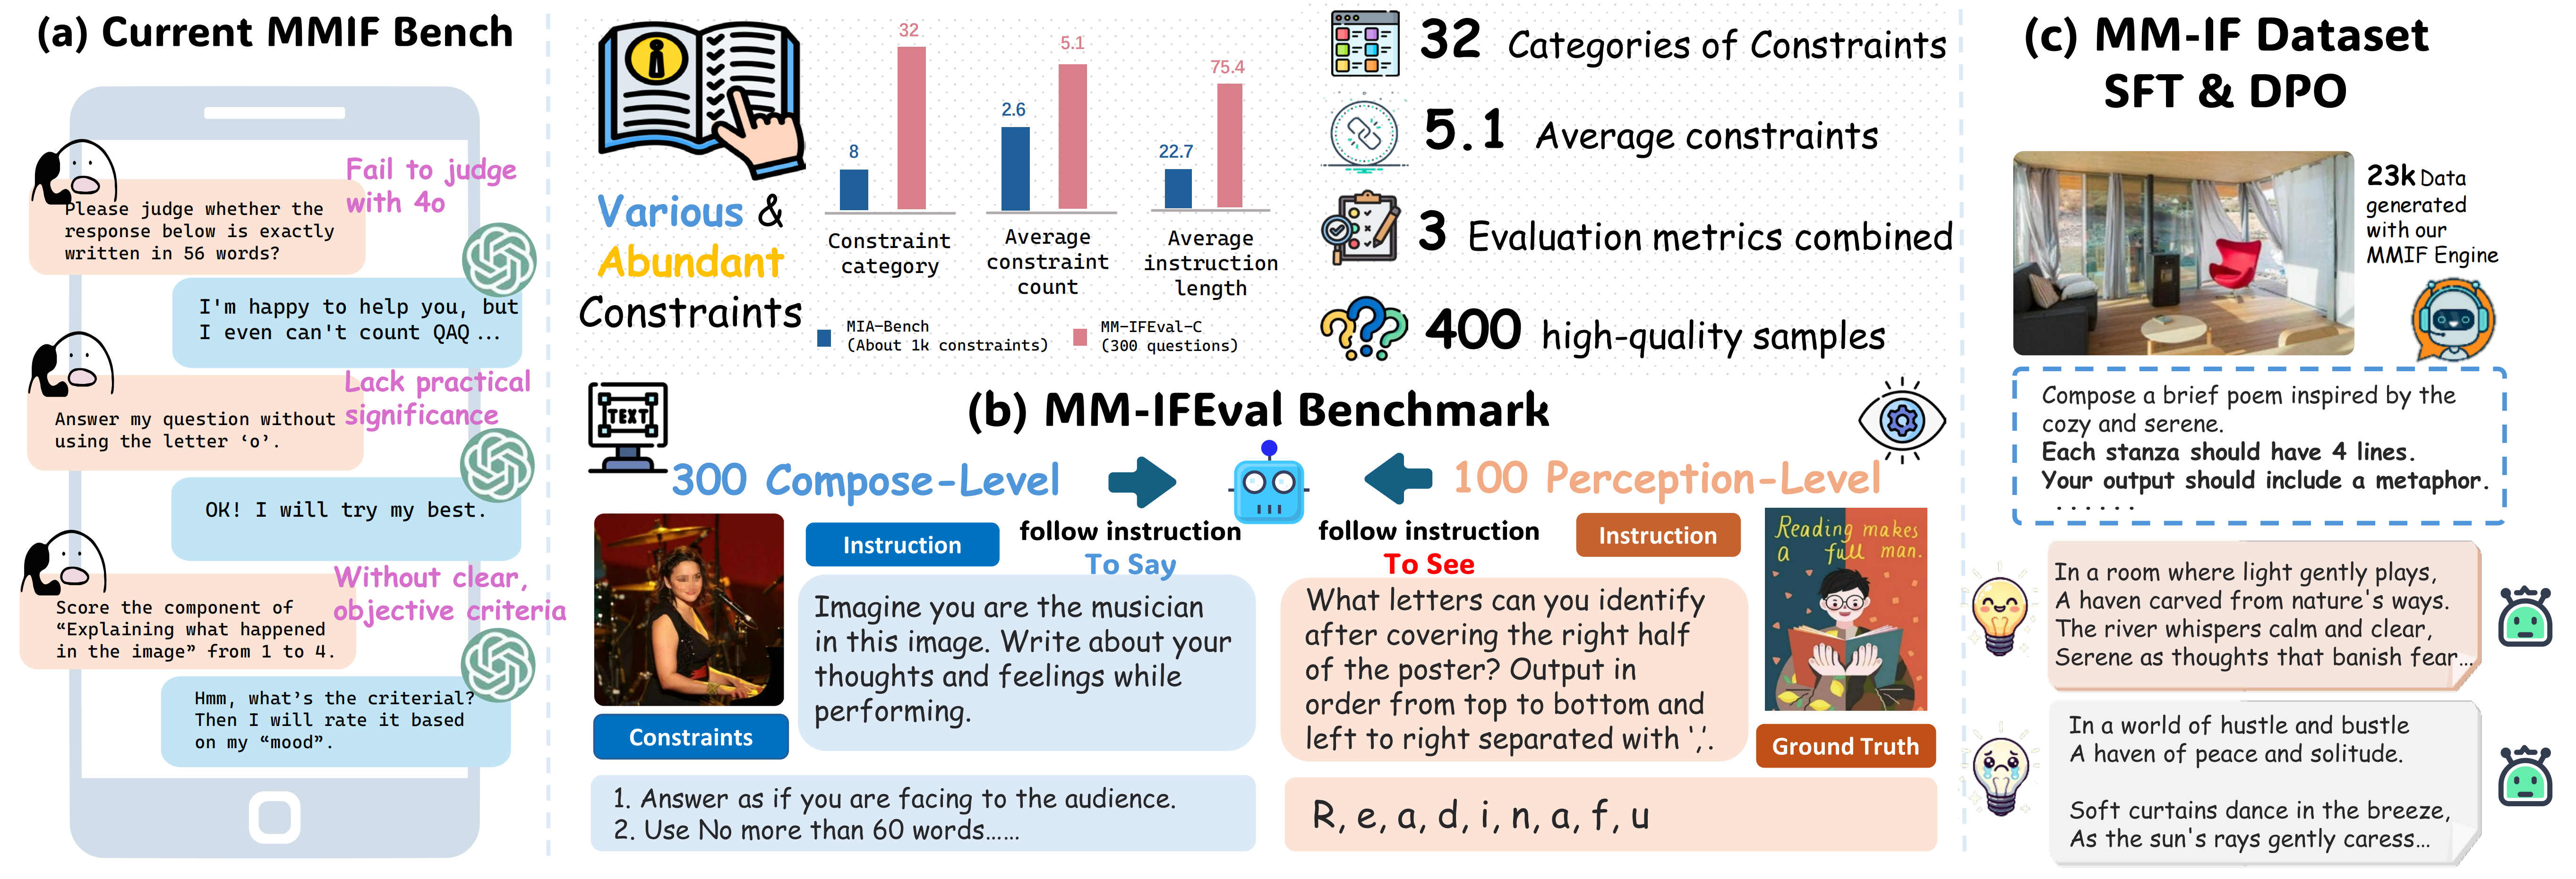
- An MM-IFEngine pipeline for generating multimodal constraint-rich image-instruction pairs;
- A large-scale training dataset MM-IFInstruct-23k and preference optimization dataset MM-IFDPO-23k de- rived from MM-IFEngine;
- A challenging multimodal instruction following benchmark MM-IFEval with diverse constraints and comprehensive evaluation approaches;
- Empirical evidence showing significant performance gains on both our MM-IFEval and existing benchmarks when training MLLMs on MM-IFInstruct-23k via SFT and MM-IFDPO-23k via DPO.
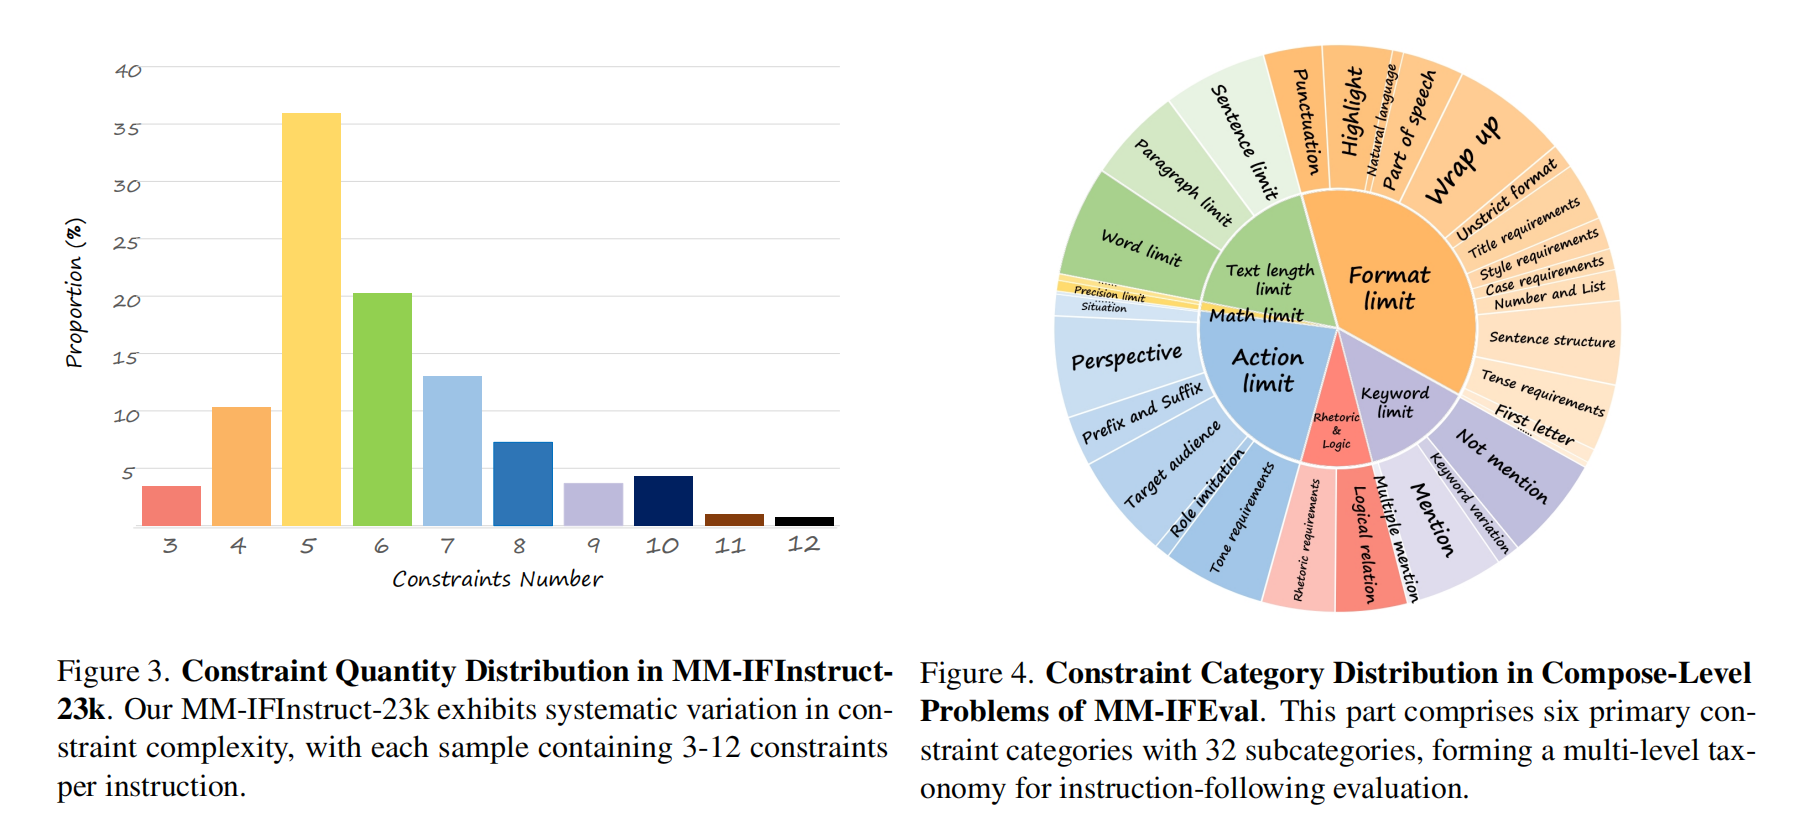
📚 Dataset Statistics
🏆 MM-IFEval Leaderboard
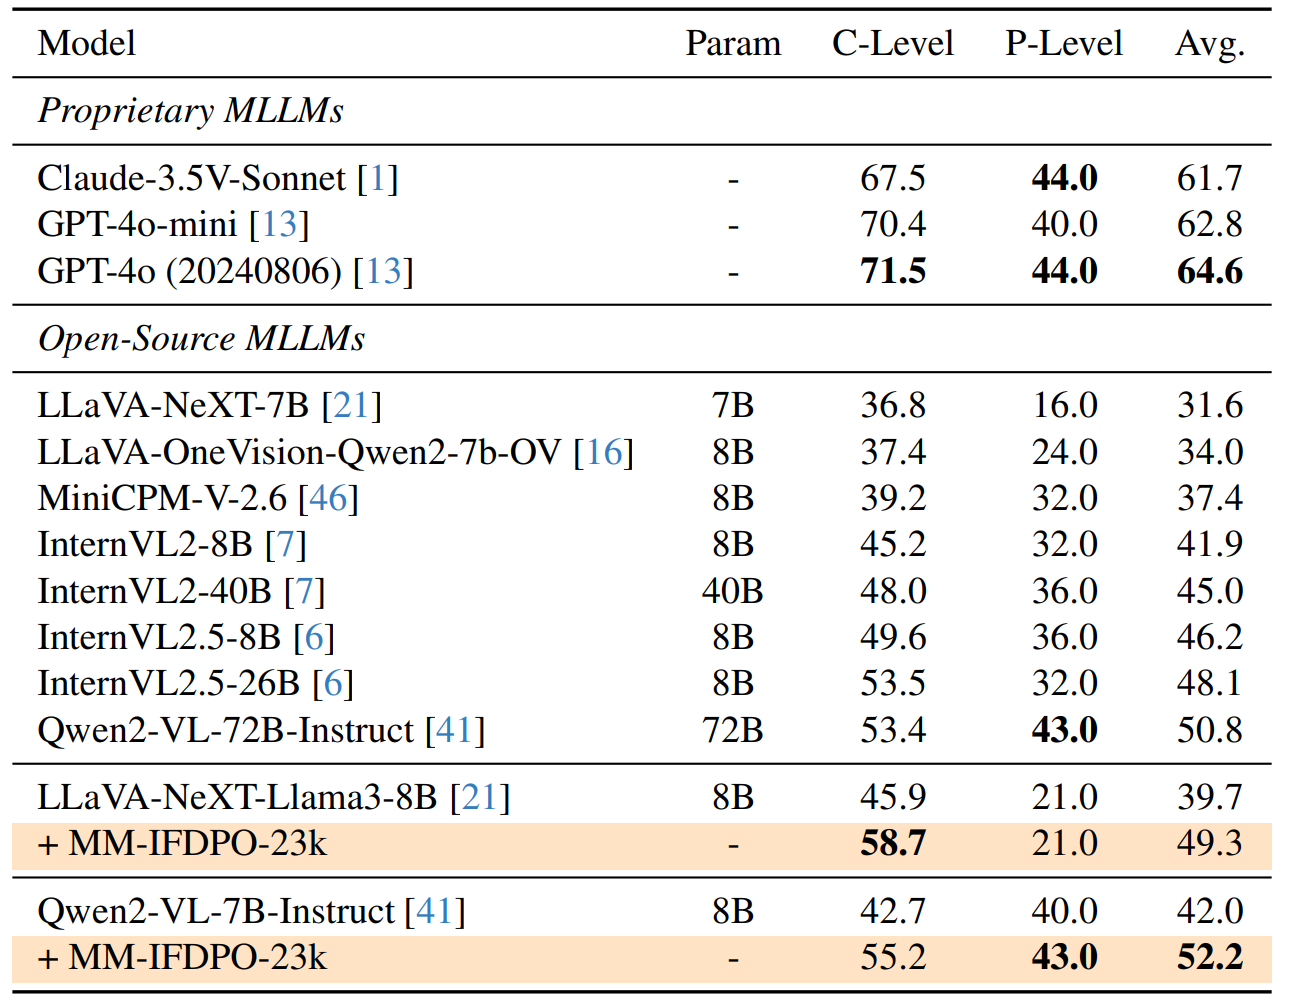
Performance of existing MLLMs on MM-IFEval. We report the accuracy of easy and difficult problems and the average accuracy across all problems. The C-Level and P-Level refer to the compose-level and perception-level problems, respectively. The best performance in each section is highlighted in bold.
🚀 Evaluate on MM-IFEval
Option 1 (Recommended): Evaluation using VLMEvalkit
# Note: Default snapshot of judge model (gpt-4o) in VLMEvalkit is currently gpt-4o-2024-05-13.

# When running with `python`, only one VLM instance is instantiated.
# API MODEL
python run.py --data MM-IFEval --model GPT4o_MINI --reuse --verbose --api-nproc 8
# HF MODEL
python run.py --data MM-IFEval --model Qwen2.5-VL-7B-Instruct --reuse --verbose --api-nproc 8


# When running with `torchrun`, one VLM instance is instantiated on each GPU. It can speed up the inference.
# HF MODEL
torchrun --nproc-per-node=2 run.py --data MM-IFEval --model Qwen2.5-VL-7B-Instruct --reuse --verbose --api-nproc 8
# Set custom judge model and work-dir
torchrun --nproc-per-node=2 run.py --data MM-IFEval --model Qwen2-VL-7B-Instruct --judge gpt-4.1 --reuse --verbose --api-nproc 8 --work-dir ./outputs_gpt_4_1
Option 2: Evaluation using this repo
1. Environment Setup
see requirements.txt
2. Run Evaluation Script
# Step1: finish the config below in eval_MM-IFEval/sh_scripts/multi_run_inf_and_score.sh
# <---- param settings ---->
PROJECT_DIR=
CONDA_ACTIVATE_PATH=
export HF_HOME=
model_bench_pairs=(
    "Qwen2-VL-7B-Instruct C-Level 8 qwen_vl HF"
    "Qwen2-VL-7B-Instruct P-Level 8 qwen_vl HF"
)
# <---- param settings ---->

# Step2: run the script
zsh eval_MM-IFEval/sh_scripts/multi_run_inf_and_score.sh
📝 Citation
@article{ding2025mm,
  title={MM-IFEngine: Towards Multimodal Instruction Following},
  author={Ding, Shengyuan and Wu, Shenxi and Zhao, Xiangyu and Zang, Yuhang and Duan, Haodong and Dong, Xiaoyi and Zhang, Pan and Cao, Yuhang and Lin, Dahua and Wang, Jiaqi},
  journal={arXiv preprint arXiv:2504.07957},
  year={2025}
}
Contributors

16 commits
Similar repos


Languages
Python
92.3%
Shell
4.2%
Dockerfile
3.4%
[ICCV 2025] MM-IFEngine: Towards Multimodal Instruction Following
See the codeREADME
MM-IFEngine: Towards Multimodal Instruction Following
[📃Paper] [🌐Project Page] [🤗Hugging Face] [🛠️Evaluation]
📣 What's New
- ✨ Several prominent multimodal models have adopted MM-IFEngine / MM-IFEval either for benchmarking their multimodal instruction-following performance or for leveraging MM-IFEngine-generated datasets for training, including:
- [2025.12.10] We have released the data filter script and instructions in data_gen/data_filter, feel free to use it!
- [2025.9.16] We have released the v2 dataset (annotated mainly by GPT-4o) in ChrisDing1105/MMIF-23k, feel free to use it!
- [2025.4.26] We have included both the SFT and DPO data in ChrisDing1105/MMIF-23k as part of version 1.0 of the dataset. Feel free to download it! We are also planning to release version 1.1 soon, scheduled for May! 🎉🎉🎉
- [2025.4.24] MM-IFEval has been merged into VLMEvalkit. You can directly evaluate your model on MM-IFEval with it! Usage see Evaluation using VLMEvalkit or more on the Official repo of VLMEvalkit! 🎉🎉🎉
- [2025.4.11] Our MM-IFEngine Paper is released! Check it at 📃Arxiv: MM-IFEngine ! Our Dataset will be open-sourced soon! 🎉🎉🎉
🌟 Highlights
- An MM-IFEngine pipeline for generating multimodal constraint-rich image-instruction pairs;
- A large-scale training dataset MM-IFInstruct-23k and preference optimization dataset MM-IFDPO-23k de- rived from MM-IFEngine;
- A challenging multimodal instruction following benchmark MM-IFEval with diverse constraints and comprehensive evaluation approaches;
- Empirical evidence showing significant performance gains on both our MM-IFEval and existing benchmarks when training MLLMs on MM-IFInstruct-23k via SFT and MM-IFDPO-23k via DPO.
📚 Dataset Statistics
🏆 MM-IFEval Leaderboard
Performance of existing MLLMs on MM-IFEval. We report the accuracy of easy and difficult problems and the average accuracy across all problems. The C-Level and P-Level refer to the compose-level and perception-level problems, respectively. The best performance in each section is highlighted in bold.
🚀 Evaluate on MM-IFEval
Option 1 (Recommended): Evaluation using VLMEvalkit
# Note: Default snapshot of judge model (gpt-4o) in VLMEvalkit is currently gpt-4o-2024-05-13.

# When running with `python`, only one VLM instance is instantiated.
# API MODEL
python run.py --data MM-IFEval --model GPT4o_MINI --reuse --verbose --api-nproc 8
# HF MODEL
python run.py --data MM-IFEval --model Qwen2.5-VL-7B-Instruct --reuse --verbose --api-nproc 8


# When running with `torchrun`, one VLM instance is instantiated on each GPU. It can speed up the inference.
# HF MODEL
torchrun --nproc-per-node=2 run.py --data MM-IFEval --model Qwen2.5-VL-7B-Instruct --reuse --verbose --api-nproc 8
# Set custom judge model and work-dir
torchrun --nproc-per-node=2 run.py --data MM-IFEval --model Qwen2-VL-7B-Instruct --judge gpt-4.1 --reuse --verbose --api-nproc 8 --work-dir ./outputs_gpt_4_1
Option 2: Evaluation using this repo
1. Environment Setup
see requirements.txt
2. Run Evaluation Script
# Step1: finish the config below in eval_MM-IFEval/sh_scripts/multi_run_inf_and_score.sh
# <---- param settings ---->
PROJECT_DIR=
CONDA_ACTIVATE_PATH=
export HF_HOME=
model_bench_pairs=(
    "Qwen2-VL-7B-Instruct C-Level 8 qwen_vl HF"
    "Qwen2-VL-7B-Instruct P-Level 8 qwen_vl HF"
)
# <---- param settings ---->

# Step2: run the script
zsh eval_MM-IFEval/sh_scripts/multi_run_inf_and_score.sh
📝 Citation
@article{ding2025mm,
  title={MM-IFEngine: Towards Multimodal Instruction Following},
  author={Ding, Shengyuan and Wu, Shenxi and Zhao, Xiangyu and Zang, Yuhang and Duan, Haodong and Dong, Xiaoyi and Zhang, Pan and Cao, Yuhang and Lin, Dahua and Wang, Jiaqi},
  journal={arXiv preprint arXiv:2504.07957},
  year={2025}
}
Similar repos
Contributors
16 commits
Languages
Python
92.3%
Shell
4.2%
Dockerfile
3.4%