Command Line interface for STILTS. Built on a fine tunned STILTS trained LLM.
Python
7
97 commits
updated Jan 23, 2026


STILTS (accesable via the command stilts in the terminal.) This only limits the execution of the generated command.
STILTS-NLI can be installed via pip with atleast python 3.12. It is recomended this is done in a virtual environment or conda environment.
pip install stilts-nli
We can then run the command.
stilts-nli
When first starting up the tool. It will download the models. This may take a few minutes.
Transformers has support for apple silicon's mps device, allowing for inference on apples GPU. This has joint memory with the CPU so be careful you have enough memory. The STILTS only model is executable, using this command:
stilts-nli --device mps --stilts_model_only
Alternatively it can be installed manually through conda.
git clone [email protected]:RhysAlfShaw/stilts-nli.git
cd stilts-nli
Using anaconda, create and activate the stilts-agent environment:
conda env create -f environment.yml
conda activate stilts-agent
Test with this worked:
python -m stilts_nli
To use the 8bit and 4bit models with transformers then you also need to install bitsandbytes. This package required a cuda device, so if you have limited memory use llama_cpp_python for inference on use only the stilts model.
If you run into trouble installing llama_cpp_python and are on a linux machine it is likely a problem with C compilers. A work around is installing (with conda and also installing packages gcc and gxx).
If you dont want to or cannot install locally then use the local dockerfile to use the tool. You can do this by cloning this directory.
git clone https://github.com/RhysAlfShaw/stilts-nli.git
cd stilts-nli
Now build the container
docker compose up -d
Lets go into the running container and lanch stilts-nli
docker exec -it stilts-nli /bin/bash -c "stilts-nli"
When you are finished rememeber to stop the container.
docker compose down
To start STILTS-NLI with default f16 precision with a Cuda device.
stilts-nli
To start STILTS-NLI with 5 cores f16 precision on a CPU using llama_cpp for inference.
stilts-nli --num_proc 5 --device cpu --inference_library llama_cpp
To just ask directly to the finetuned model on the GPU.
stilts-nli --stilts_model_only
Here is an example of a conversation with STILTS-NLI.
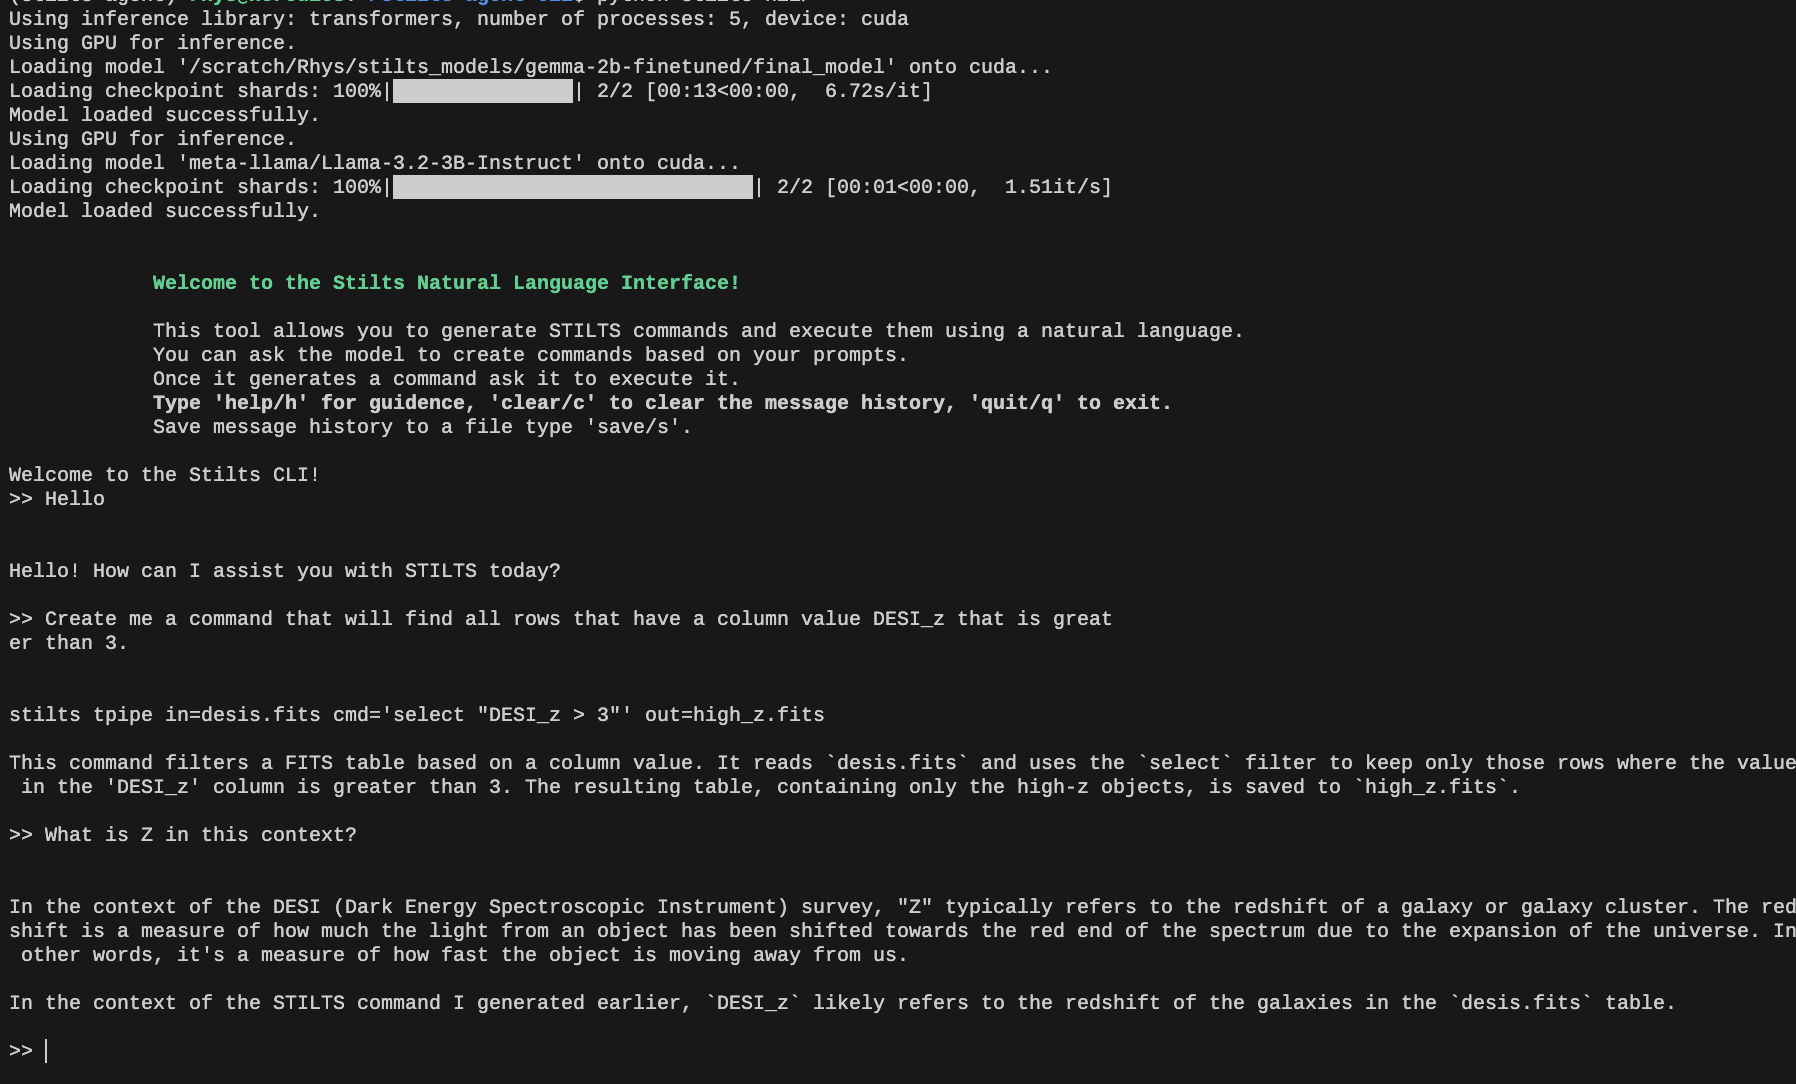
On startup different arguments can be parsed to change which models will be used and what resources you want to allocate to the program. These include:
Once all models have loaded successfully, you will be greeted with the following.
Welcome to the Stilts Natural Language Interface!
This tool allows you to generate STILTS commands and execute them using a
natural language. You can ask the model to create commands based on your
prompts. Once it generates a command ask it to execute it.
Type ’help/h’ for guidence, ’clear/c’ to clear the message history,
’quit/q’ to exit. Save message history to a file type ’save/s’.
Welcome to the Stilts CLI!
>> |
From here you are now interacting with the general model, view the generated stilts command, and do any of the additional options. These are asking for help (examples on how to use the tool). Clear the message history so you can start again. Quit the sessions and return to the terminal. And save the message history. When a stilts command is generated the model is also prompted to explain what it is doing.
>> Can you make me an example stilts command that will match two catalogues based on the
column value OBJECT_ID?

stilts tmatch2 in1=catalogue1.fits in2=catalogue2.fits out=id_match.fits matcher=exact
values1=OBJECT_ID values2=OBJECT_ID

This command performs a simple object matching operation. It reads two FITS tables,
‘catalogue1.fits‘ and ‘catalogue2.fits‘, and uses the ‘match2‘ algorithm to find
all objects from the first catalogue that have an exact match in the ’ID’ column
from the second catalogue. The result is a new FITS table containing only the ID
columns from both the input tables, named ‘ID_match.fits‘.
Low precision versions of both models are (or will be) avalible which will allow inference on low memory GPUs or lower spec laptops. These are: STILTSgen model.
Gen model (Llama-3.2-3B-Instruct):
For full precision of both models you require a minimum of ~18GB of GPU or CPU RAM.
Command Line interface for STILTS. Built on a fine tunned STILTS trained LLM.
Python
7
97 commits
updated Jan 23, 2026
STILTS (accesable via the command stilts in the terminal.) This only limits the execution of the generated command.
STILTS-NLI can be installed via pip with atleast python 3.12. It is recomended this is done in a virtual environment or conda environment.
pip install stilts-nli
We can then run the command.
stilts-nli
When first starting up the tool. It will download the models. This may take a few minutes.
Transformers has support for apple silicon's mps device, allowing for inference on apples GPU. This has joint memory with the CPU so be careful you have enough memory. The STILTS only model is executable, using this command:
stilts-nli --device mps --stilts_model_only
Alternatively it can be installed manually through conda.
git clone [email protected]:RhysAlfShaw/stilts-nli.git
cd stilts-nli
Using anaconda, create and activate the stilts-agent environment:
conda env create -f environment.yml
conda activate stilts-agent
Test with this worked:
python -m stilts_nli
To use the 8bit and 4bit models with transformers then you also need to install bitsandbytes. This package required a cuda device, so if you have limited memory use llama_cpp_python for inference on use only the stilts model.
If you run into trouble installing llama_cpp_python and are on a linux machine it is likely a problem with C compilers. A work around is installing (with conda and also installing packages gcc and gxx).
If you dont want to or cannot install locally then use the local dockerfile to use the tool. You can do this by cloning this directory.
git clone https://github.com/RhysAlfShaw/stilts-nli.git
cd stilts-nli
Now build the container
docker compose up -d
Lets go into the running container and lanch stilts-nli
docker exec -it stilts-nli /bin/bash -c "stilts-nli"
When you are finished rememeber to stop the container.
docker compose down
To start STILTS-NLI with default f16 precision with a Cuda device.
stilts-nli
To start STILTS-NLI with 5 cores f16 precision on a CPU using llama_cpp for inference.
stilts-nli --num_proc 5 --device cpu --inference_library llama_cpp
To just ask directly to the finetuned model on the GPU.
stilts-nli --stilts_model_only
Here is an example of a conversation with STILTS-NLI.
On startup different arguments can be parsed to change which models will be used and what resources you want to allocate to the program. These include:
Once all models have loaded successfully, you will be greeted with the following.
Welcome to the Stilts Natural Language Interface!
This tool allows you to generate STILTS commands and execute them using a
natural language. You can ask the model to create commands based on your
prompts. Once it generates a command ask it to execute it.
Type ’help/h’ for guidence, ’clear/c’ to clear the message history,
’quit/q’ to exit. Save message history to a file type ’save/s’.
Welcome to the Stilts CLI!
>> |
From here you are now interacting with the general model, view the generated stilts command, and do any of the additional options. These are asking for help (examples on how to use the tool). Clear the message history so you can start again. Quit the sessions and return to the terminal. And save the message history. When a stilts command is generated the model is also prompted to explain what it is doing.
>> Can you make me an example stilts command that will match two catalogues based on the
column value OBJECT_ID?

stilts tmatch2 in1=catalogue1.fits in2=catalogue2.fits out=id_match.fits matcher=exact
values1=OBJECT_ID values2=OBJECT_ID

This command performs a simple object matching operation. It reads two FITS tables,
‘catalogue1.fits‘ and ‘catalogue2.fits‘, and uses the ‘match2‘ algorithm to find
all objects from the first catalogue that have an exact match in the ’ID’ column
from the second catalogue. The result is a new FITS table containing only the ID
columns from both the input tables, named ‘ID_match.fits‘.
Low precision versions of both models are (or will be) avalible which will allow inference on low memory GPUs or lower spec laptops. These are: STILTSgen model.
Gen model (Llama-3.2-3B-Instruct):
For full precision of both models you require a minimum of ~18GB of GPU or CPU RAM.



