Winnow: separate the grain from the chaff in your coding agent's tool output. A task-aware pruner for Headroom, powered by Squeez models.
See the code
Separate the grain from the chaff in your coding agent's tool output.
A task-aware pruner for Headroom, powered by Squeez models.




Coding agents spend most of their context on tool output: test runs, builds, grep hits, logs. Usually only a handful of those lines matter for the agent's next step. Winnow plugs a small model trained on real agent traces into Headroom's compression pipeline. It keeps the lines the task needs, never drops an error or a traceback, and turns everything else into retrievable markers.
41% fewer tokens with 0.85 gold-line recall, zero lost error lines, and 0.29 s median latency on a consumer GPU. At equal compression it keeps 15-27 points more of the relevant lines than Headroom's built-in
relevance_split. Full results →
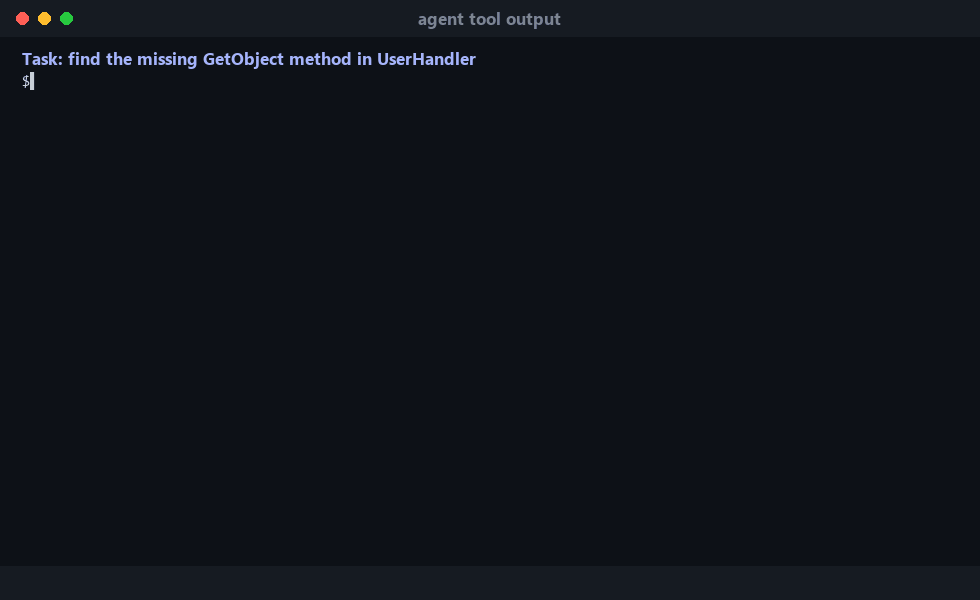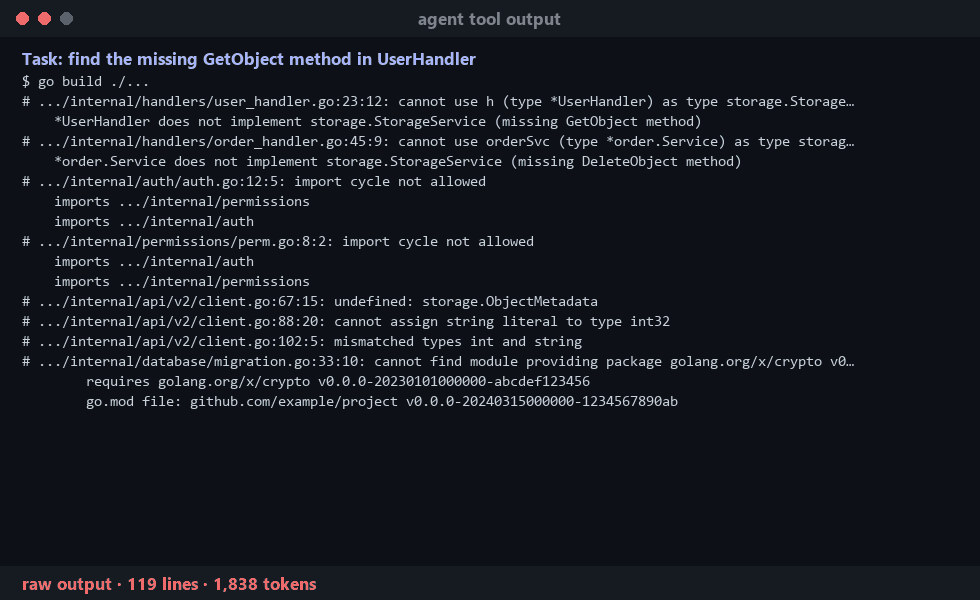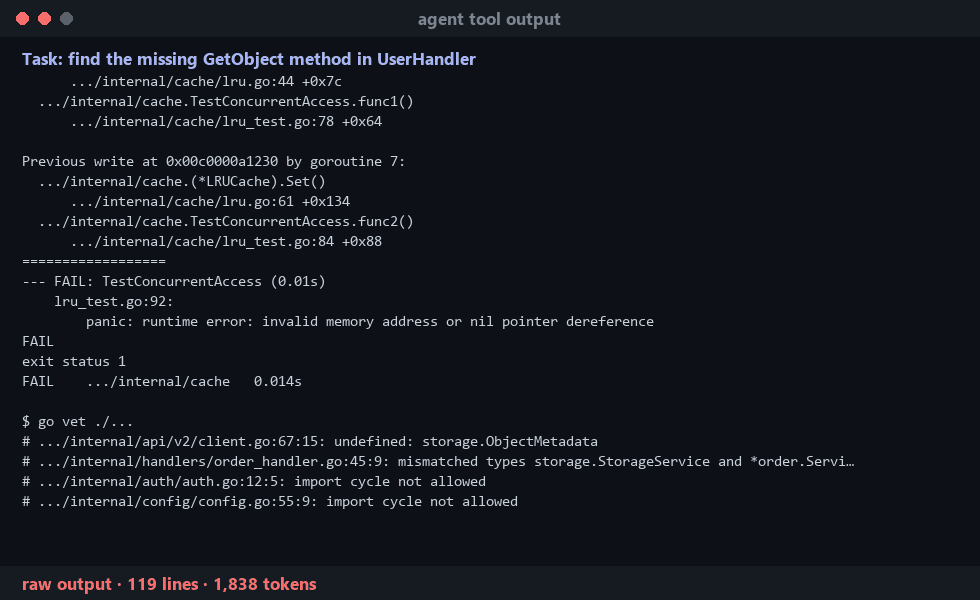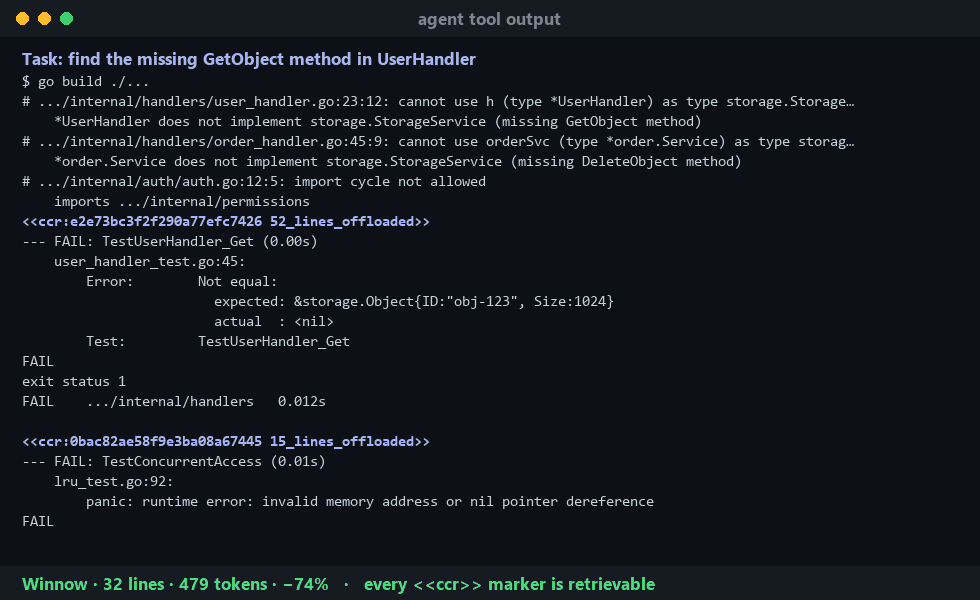
The agent asks "Find the build output block that reports the missing
GetObject method in the UserHandler implementation of
storage.StorageService" and runs go build ./...:
| Before: 119 lines, 1,838 tokens | After: 32 lines, 479 tokens (−74%) |
|---|---|
|
|
The block the agent asked for is kept verbatim, every failure line survives,
and each <<ccr:…>> marker can be expanded through Headroom's retrieval tool if
the agent needs the dropped lines after all. (Real model output on an example
from the Squeez test set; long paths and lines shortened to fit.)
flowchart LR
    A[Agent tool call] --> B[Headroom proxy]
    B --> C{Content router}
    C -- "log / search / diff / text" --> D[WinnowCompressor]
    C -- "JSON / code / HTML" --> E[Headroom built-ins]
    D --> F[Span model<br/>which lines matter?]
    F --> G[Safety rules<br/>errors, tracebacks,<br/>±2 context, edges]
    G --> H[Render<br/>kept lines verbatim +<br/>ccr markers]
    H --> I[(CCR store<br/>hash → original)]
    H --> J[Pruned context to LLM]
    D -. "no query / too short /<br/>too large / low savings" .-> E
E
details are always kept, as are whole Python tracebacks, two neighbours of
every kept line, and the first and last two lines.<<ccr:HASH N_lines_offloaded>> marker whose original text goes into the
CCR store. Hashes are deterministic, so identical input yields identical
output and prompt caches stay warm.The plugin never raises. Any failure (missing torch, model download error, inference error) falls back to Headroom's own path.
pip install "headroom-winnow[model]"
Installing changes nothing until you opt in:
headroom proxy --compressor winnow
or in Python:
from headroom.transforms.content_router import ContentRouter, ContentRouterConfig

router = ContentRouter(ContentRouterConfig(active_external_compressors=["winnow"]))
On first use Winnow downloads its model,
rbk4209/winnow-pooled-32m
(128 MB), from the Hugging Face Hub at a pinned commit. A GPU is strongly
recommended; on CPU Winnow only scores shorter outputs and leaves the rest to
Headroom.
| Backend | Model | When to use |
|---|---|---|
pooled (default) | rbk4209/winnow-pooled-32m, 32M line classifier trained for Winnow | Fast enough to score any tool output on a GPU |
highlighter | KRLabsOrg/verbatim-rag-modern-bert-v2, 150M span model | Squeez's original extractive model; slower, so limited to short outputs |
| Variable | Default | Meaning |
|---|---|---|
HEADROOM_WINNOW_BACKEND | pooled | pooled or highlighter |
HEADROOM_WINNOW_MODEL | the backend's published model | Hub id or local path |
HEADROOM_WINNOW_REVISION | pinned commit of the default model | Model revision |
HEADROOM_WINNOW_DEVICE | auto | auto (CUDA if available), cuda or cpu |
HEADROOM_WINNOW_DTYPE | float32 | float16 is faster only on GPUs with tensor cores |
HEADROOM_WINNOW_MAX_TOKENS | per backend and device | Largest output the model scores; larger ones go to Headroom |
On the 618-example test split of the Squeez dataset:
| Method | Recall | Token reduction | Error lines lost | p50 latency |
|---|---|---|---|---|
Headroom relevance_split (BM25) | 0.725 | 58.6%¹ | 7,953 | 1 ms |
Headroom relevance_split (hybrid) | 0.753 | 57.6%¹ | 7,771 | 2.2 s |
| Winnow (32M pooled) | 0.847 | 41.4% | 0 | 0.29 s |
¹ Upper bound: the dropped tail is Kompressed inside Headroom, not removed.
At equal compression (50 / 70 / 90% of lines dropped) the pooled model keeps
0.89 / 0.84 / 0.68 of the gold lines, against 0.73 / 0.63 / 0.46 for
relevance_split. Details, the 150M highlighter numbers and reproduction
commands are in benchmarks/RESULTS.md.
training/kaggle_train_pooled.ipynb
trains the 32M pooled classifier on a free Kaggle T4 in about six hours. It
uses Squeez's own training code at a
pinned commit and evaluates on the same test split as the benchmark. Swap
--base-model to try other encoders.
headroom_winnow/
  compressor.py    WinnowCompressor: the headroom.compressor contract, gates, fail-open
  selection.py     spans → lines, safety rules, rendering with markers
  markers.py       CCR marker format and deterministic hashes
  backends.py      highlighter and pooled backends: lazy, pinned, device-aware
benchmarks/        compare.py and RESULTS.md
training/          Kaggle notebook for the pooled model
upstream/          patch proposed to Headroom (see below)
tests/             unit tests with a fake model, router end-to-end, real-model tests
relevance_split) before the external
compressor hook and returns early when either succeeds, so such blocks never
reach this plugin. See tests/test_router.py::test_known_gap_lossless_fold_preempts_external.upstream/router-respect-passthrough.patch;
the matching test is a strict xfail until it lands.pip install -e ".[dev,model]"
ruff check . && ruff format --check . && mypy headroom_winnow tests benchmarks
pytest # fast tests, no downloads
pytest -m slow # downloads and runs the real highlighter
Winnow: separate the grain from the chaff in your coding agent's tool output. A task-aware pruner for Headroom, powered by Squeez models.
See the code
Separate the grain from the chaff in your coding agent's tool output.
A task-aware pruner for Headroom, powered by Squeez models.
Coding agents spend most of their context on tool output: test runs, builds, grep hits, logs. Usually only a handful of those lines matter for the agent's next step. Winnow plugs a small model trained on real agent traces into Headroom's compression pipeline. It keeps the lines the task needs, never drops an error or a traceback, and turns everything else into retrievable markers.
41% fewer tokens with 0.85 gold-line recall, zero lost error lines, and 0.29 s median latency on a consumer GPU. At equal compression it keeps 15-27 points more of the relevant lines than Headroom's built-in
relevance_split. Full results →
The agent asks "Find the build output block that reports the missing
GetObject method in the UserHandler implementation of
storage.StorageService" and runs go build ./...:
| Before: 119 lines, 1,838 tokens | After: 32 lines, 479 tokens (−74%) |
|---|---|
|
|
The block the agent asked for is kept verbatim, every failure line survives,
and each <<ccr:…>> marker can be expanded through Headroom's retrieval tool if
the agent needs the dropped lines after all. (Real model output on an example
from the Squeez test set; long paths and lines shortened to fit.)
flowchart LR
    A[Agent tool call] --> B[Headroom proxy]
    B --> C{Content router}
    C -- "log / search / diff / text" --> D[WinnowCompressor]
    C -- "JSON / code / HTML" --> E[Headroom built-ins]
    D --> F[Span model<br/>which lines matter?]
    F --> G[Safety rules<br/>errors, tracebacks,<br/>±2 context, edges]
    G --> H[Render<br/>kept lines verbatim +<br/>ccr markers]
    H --> I[(CCR store<br/>hash → original)]
    H --> J[Pruned context to LLM]
    D -. "no query / too short /<br/>too large / low savings" .-> E
E
details are always kept, as are whole Python tracebacks, two neighbours of
every kept line, and the first and last two lines.<<ccr:HASH N_lines_offloaded>> marker whose original text goes into the
CCR store. Hashes are deterministic, so identical input yields identical
output and prompt caches stay warm.The plugin never raises. Any failure (missing torch, model download error, inference error) falls back to Headroom's own path.
pip install "headroom-winnow[model]"
Installing changes nothing until you opt in:
headroom proxy --compressor winnow
or in Python:
from headroom.transforms.content_router import ContentRouter, ContentRouterConfig

router = ContentRouter(ContentRouterConfig(active_external_compressors=["winnow"]))
On first use Winnow downloads its model,
rbk4209/winnow-pooled-32m
(128 MB), from the Hugging Face Hub at a pinned commit. A GPU is strongly
recommended; on CPU Winnow only scores shorter outputs and leaves the rest to
Headroom.
| Backend | Model | When to use |
|---|---|---|
pooled (default) | rbk4209/winnow-pooled-32m, 32M line classifier trained for Winnow | Fast enough to score any tool output on a GPU |
highlighter | KRLabsOrg/verbatim-rag-modern-bert-v2, 150M span model | Squeez's original extractive model; slower, so limited to short outputs |
| Variable | Default | Meaning |
|---|---|---|
HEADROOM_WINNOW_BACKEND | pooled | pooled or highlighter |
HEADROOM_WINNOW_MODEL | the backend's published model | Hub id or local path |
HEADROOM_WINNOW_REVISION | pinned commit of the default model | Model revision |
HEADROOM_WINNOW_DEVICE | auto | auto (CUDA if available), cuda or cpu |
HEADROOM_WINNOW_DTYPE | float32 | float16 is faster only on GPUs with tensor cores |
HEADROOM_WINNOW_MAX_TOKENS | per backend and device | Largest output the model scores; larger ones go to Headroom |
On the 618-example test split of the Squeez dataset:
| Method | Recall | Token reduction | Error lines lost | p50 latency |
|---|---|---|---|---|
Headroom relevance_split (BM25) | 0.725 | 58.6%¹ | 7,953 | 1 ms |
Headroom relevance_split (hybrid) | 0.753 | 57.6%¹ | 7,771 | 2.2 s |
| Winnow (32M pooled) | 0.847 | 41.4% | 0 | 0.29 s |
¹ Upper bound: the dropped tail is Kompressed inside Headroom, not removed.
At equal compression (50 / 70 / 90% of lines dropped) the pooled model keeps
0.89 / 0.84 / 0.68 of the gold lines, against 0.73 / 0.63 / 0.46 for
relevance_split. Details, the 150M highlighter numbers and reproduction
commands are in benchmarks/RESULTS.md.
training/kaggle_train_pooled.ipynb
trains the 32M pooled classifier on a free Kaggle T4 in about six hours. It
uses Squeez's own training code at a
pinned commit and evaluates on the same test split as the benchmark. Swap
--base-model to try other encoders.
headroom_winnow/
  compressor.py    WinnowCompressor: the headroom.compressor contract, gates, fail-open
  selection.py     spans → lines, safety rules, rendering with markers
  markers.py       CCR marker format and deterministic hashes
  backends.py      highlighter and pooled backends: lazy, pinned, device-aware
benchmarks/        compare.py and RESULTS.md
training/          Kaggle notebook for the pooled model
upstream/          patch proposed to Headroom (see below)
tests/             unit tests with a fake model, router end-to-end, real-model tests
relevance_split) before the external
compressor hook and returns early when either succeeds, so such blocks never
reach this plugin. See tests/test_router.py::test_known_gap_lossless_fold_preempts_external.upstream/router-respect-passthrough.patch;
the matching test is a strict xfail until it lands.pip install -e ".[dev,model]"
ruff check . && ruff format --check . && mypy headroom_winnow tests benchmarks
pytest # fast tests, no downloads
pytest -m slow # downloads and runs the real highlighter



