
(NIPS 2025) OpenOmni: Official implementation of Advancing Open-Source Omnimodal Large Language Models with Progressive Multimodal Alignment and Real-Time Self-Aware Emotional Speech Synthesis
Python
144
71 commits
updated May 9, 2026
README
OpenOmni: Advancing Open-Source Omnimodal Large Language Models with Progressive Multimodal Alignment and Real-Time Self-Aware Emotional Speech Synthesis
OpenOmni is the end-to-end fully open-sourced pioneering method that successfully incorporates image,speech and text into the omni large language model. OpenOmni's design for speech generation through language bridging and text-guided speech can be quickly trained in situations where omni-modal data and VRAM resources are scarce. OpenOmni not only supports omni-modal nderstanding, but also supports two real-time emotional speech generation modes, CTC mode and AR mode, so that users can flexibly choose according to their needs to achieve a balance between generation speed and quality. The flexible framework design allows OpenOmni to be easily and quickly applied to a variety of downstream tasks, such as speech embodied navigation, multi-role-playing speech dialogue, etc. Everyone is welcome to come and experience it now!🔥 Update
- [2025/09/22]🔥After a year of community evaluation, our work has been accepted by NIPS 2025. Congratulations!
- [2025/05/26]🔥Our [OmniCharacter]—built on MMEvol and OpenOmni series—has been accepted to the main track of ACL 2025. You’re all welcome to give it a try!
- [2025/05/15]🔥Two paper has beed accepted by ACL 2025 main based on our findings (LLaMA-Omin2 and OmniCharacter). We warmly welcome everyone to use our work.
- [2025/05/05]🔥Our gate fusion technology for more acurrate speech content generation is adopted by LLaMA-Omni2
- [2025/02/12]🔥Add some missing file and fix all possible bug
- [2025/01/13]🔥OpenOmni is coming! We release the code, model and data
- [2025/01/09]🔥After two months of company audit! We release the paper
- [2024/11/14]🔥We submit the paper for peer review openreview
- [2024/09/15]🔥We write the first line of OpenOmni project for fully open-sourced pioneering OmniLLM in end-to-end manner.
👀 Contents
- Setup
- Model
- Preparation
- Train
- Evaluation
- Example
- Citation
📷 Setup
Please follow the instructions below to install the required packages.
- Clone this repository
git clone https://github.com/RainBowLuoCS/OpenOmni.git
cd OpenOmni
- Install Package
conda create -n openomni python=3.10 -y
conda activate openomni
pip install --upgrade pip  # enable PEP 660 support
pip install -e ".[train]"
pip install -r requirements.txt
- Install additional packages for training
pip install flash-attn --no-build-isolation
🔥 Fast Usage
After downloading the weights and configuring the paths properly. Two open-sourced speech tokenizer are needed for speech discretization and reconstruction with different vocabulary size! CosVoice for 6K CTC Mode and GLM4Voice for 16K AR Mode
Fast inference for omnimodal input (speech,text,image and video)
python inference.py
Fast interation for omnimodal input (speech,text,image and video)
python demo.py
Model
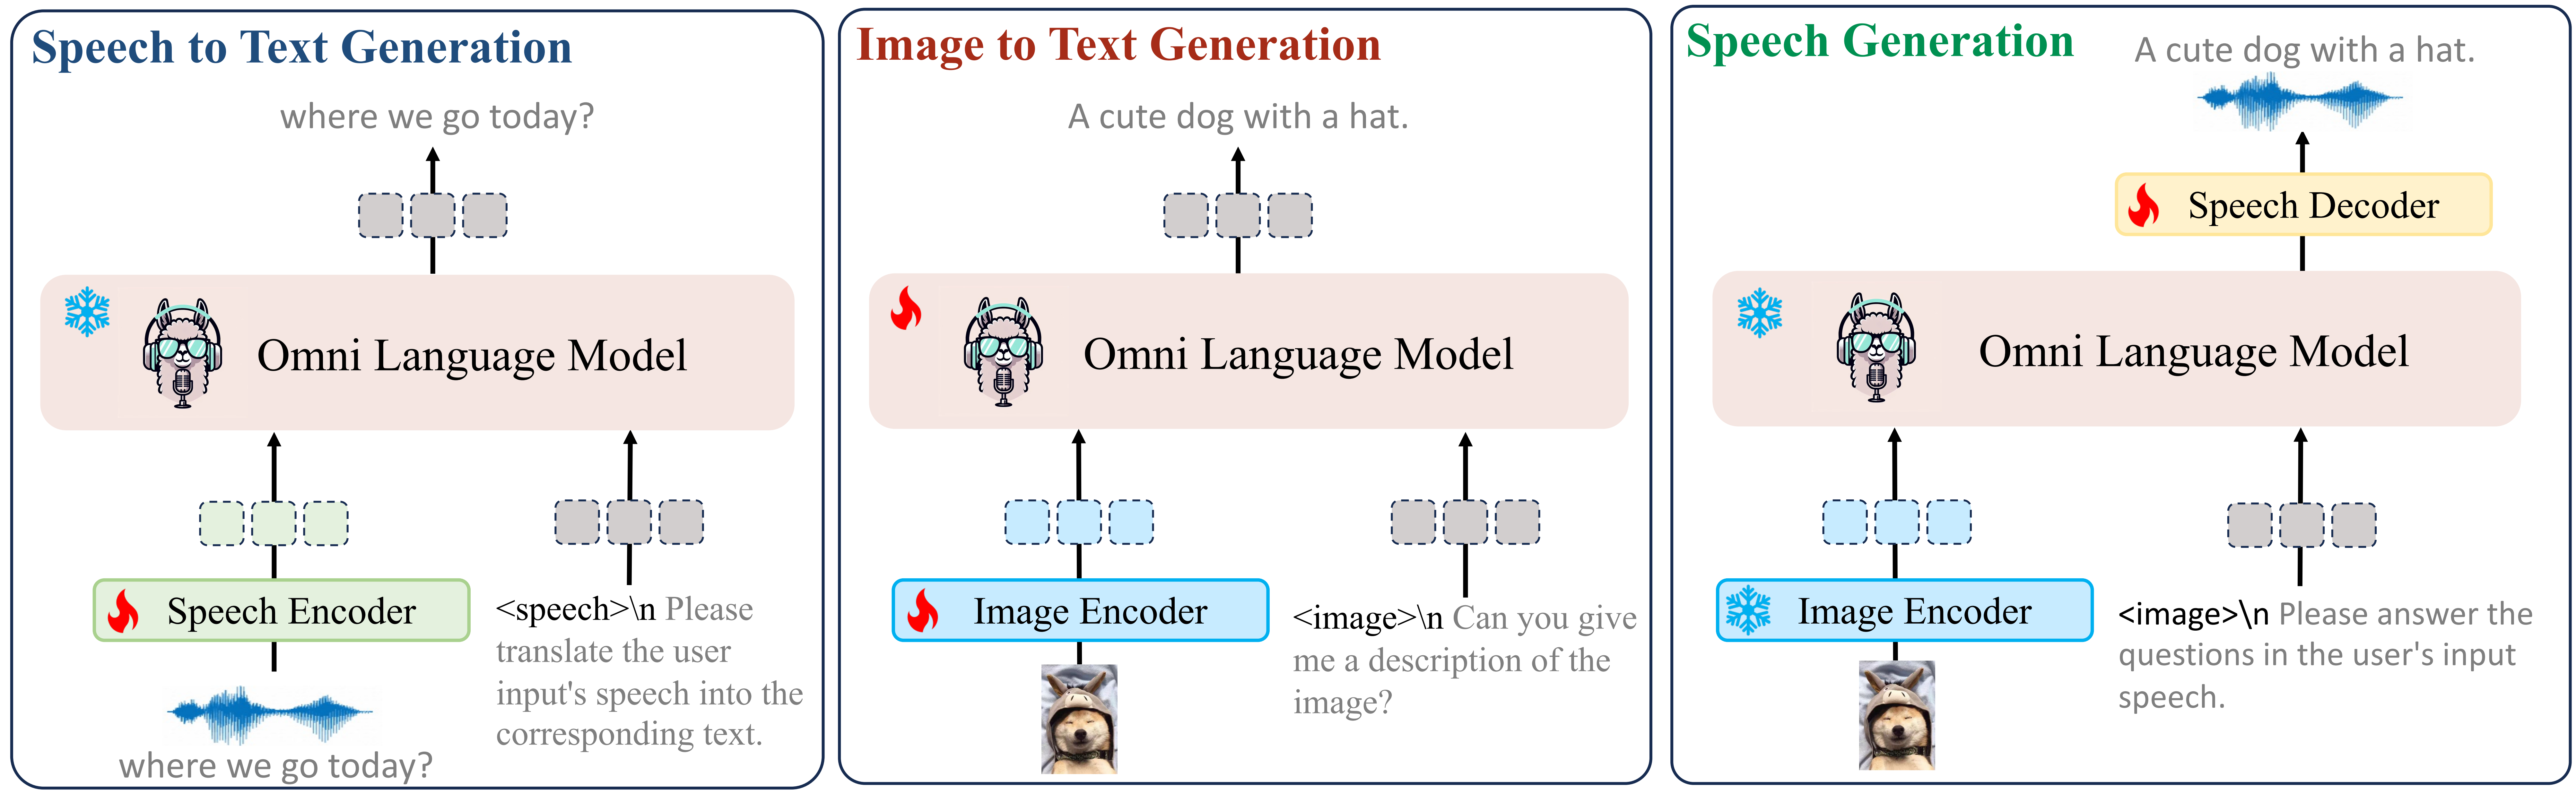
Here are the pretrained weights and instruction tuning weights
| Stage | Model | Speech Projector | Image Projector | IT Data | Download |
|---|---|---|---|---|---|
| 1-1 | OpenOMNI-Qwen2-7B-Stage1-1 | ckpt | ckpt | openomni_stage1-1.json | ckpt |
| 2-1 | OpenOMNI-Qwen2-7B-Stage2-1 | ckpt | ckpt | openomni_stage2-1.json | ckpt |
| 2-2 | OpenOMNI-Qwen2-7B-Stage2-2 | ckpt | ckpt | openomni_stage2-2.json | ckpt |
| 3-1 | OpenOMNI-Qwen2-7B-Stage3-1 | ckpt | ckpt | openomni_stage3-1.json | ckpt |
| 3-2 | OpenOMNI-Qwen2-7B-Stage3-2 | ckpt | ckpt | openomni_stage3-2.json | ckpt |
Preparation
Dataset
Please follow MMEvol to prepare the corresponding images-text datasets. Here we only provide the details of speech-text datasets.
The following is the data directory tree of OpenOmni
data structure
datasets
├── json # data receipe
│   ├── openomni_stage1-1.json # speech2text pretraining
│   ├── openomni_stage2-1.json # image2text pretraining
│   ├── openomni_stage2-2.json # image2text instruction tuning
│   ├── openomni_stage3-1.json # text2speech pretraining
│   ├── openomni_stage3-2.json # text2speech emotional injection
├── asr # classic bilingual speech corpus
│   ├── AISHELL-4
│   ├── LibriSPeech
│   ├── WeNetSpeech
├── audio_en # synthetic english speech corpus for question
├── audio_llava # synthetic bilingual speech corpus for answer
├── audio_zh # synthetic chinese speech corpus for question
├── audio_unit # synthetic bilingual speech corpus for answer
├── audio_prefer # synthetic emotional bilingual speech corpus for answer
├── audio_reject # synthetic emotional bilingual speech corpus for answer
├── audio_ultrachat # synthetic bilingual speech corpus for answer
├── ai2d
│   ├── abc_images
│   ├── annotations
│   ├── images
│   ├── questions
│   └── categories.json
......
- All file/path starting with "audio" are self-synthesized.
- DPO contains approximately 9k entries for "prefer" and "reject," covering 9 types of emotions.
More details about data curation can be found in our paper.
Train
Speech2Text Pretrain
Please download the MMEvol, AIShell-4, LibriSPeech, WeNetSpeech, OpenOmni Data and organize the data following Preparation before training . Make sure set up the corresponding train script with correct setting (data path, weight path, and hyper-paramaters)
bash scripts/train/llama3/speech2text_pretrain.sh
bash scripts/train/qwen2/speech2text_pretrain.sh
Image2Text Pretrain
Please make sure you download and organize the data following Preparation before training. Make sure set up the corresponding train script with correct setting (data path, weight path, and hyper-paramaters)
bash scripts/train/llama3/image2text_pretrain.sh
bash scripts/train/qwen2/image2text_pretrain.sh
Image2Text Instruction Tuning
Please make sure you download and organize the data following Preparation before training. Make sure set up the corresponding train script with correct setting (data path, weight path, and hyper-paramaters)
bash scripts/train/llama3/image2text_finetune.sh
bash scripts/train/qwen2/image2text_finetue.sh
Text2Speech Pretrain
Please make sure you download and organize the data following Preparation before training. Make sure set up the corresponding train script with correct setting (data path, weight path, and hyper-paramaters)
bash scripts/train/llama3/text2speech_ pretrain.sh
bash scripts/train/qwen2/text2speech_ pretrain.sh
Text2Speech Emotional DPO Tuning
Please make sure you download and organize the data following Preparation before training. Make sure set up the corresponding train script with correct setting (data path, weight path, and hyper-paramaters)
bash scripts/train/llama3/text2speech_ dpo.sh
bash scripts/train/qwen2/text2speech_ dpo.sh
Evaluation
Dataset
Ensure that your api_base, key and dataset are correctly configured before evaluation.
data structure
datasets
├── json # data receipe
│   ├── aishell2_eval.jsonl # aishell evaluation
│   ├── librispeech_eval.jsonl # image2text pretraining
│   ├── wenetspeech_eval.json # image2text instruction tuning
│   ├── openomni_emotion_val.json
├── OmniBench # OmniBench
│   ├── mmdata
│   ├── dataset
│   		├── eval.json
├── Ov-Odyssey # Ov-Odyssey Bench
│   ├── av_odyssey_part1.parquet
│   ├── av_odyssey_part2.parquet
│   ├── av_odyssey_part3.parquet
│   ├── av_odyssey_part4.parquet
│   ├── av_odyssey_part5.parquet
Speech-Text Evaluation
Make sure set up the corresponding train script with correct setting (data path, weight path, and hyper-paramaters)
python openomni/eval/llama3/asr_eavl.py
python openomni/eval/qwen2/asr_eavl.py
| Model | LibriSpeech-test-clean | LibriSpeech-test-other | AIShell2-dev | AIShell2-test | WeNetSpeech-testnet | WeNetSpeech-testmeeting |
|---|---|---|---|---|---|---|
| VITA | 8.1 | 18.4 | 12.2 | 16.5 | ||
| EMOVA | 4.0 | 8.6 | 10.6 | 10.3 | ||
| MINI-OMNI | 4.5 | 9.7 | ||||
| Freeze-Omni | 3.29 | 7.4 | 8.57 | 10.09 | ||
| ours | 2.57 | 5.6 | 6.81 | 6.87 | 7.63 |
Image-Text Evaluation
Refer to MMEvol for detailed OpenCampass Vision Language Evaluation
# run on all 9 datasets
./script/run_inference.sh OpenOmni-Qwen "MME MMMU_DEV_VAL MathVista_MINI LLaVABench RealWorldQA MMStar MMVet AI2D_TEST OCRBench HallusionBench POPE BLINK" all

# The following are instructions for running on a single dataset
# MME
./script/run_inference.sh OpenOmni-Qwen MME all
# MMMU_DEV_VAL
./script/run_inference.sh OpenOmni-Qwen MMMU_DEV_VAL all
# MathVista_MINI
./script/run_inference.sh OpenOmni-Qwen MathVista_MINI all
.....
Speech-Text-Image Evaluation
Please download OmniBench and run the following command
python openomni/eval/llama3/omni_eavl.py
python openomni/eval/qwen2/omni_eavl.py
Speech-Text-Image-Video Evaluation
Please download Ov-Odyssey and run the following command
python openomni/eval/llama3/ov_odyssey_eavl.py
python openomni/eval/qwen2/ov_odyssey_eavl.py
Text-Speech Evaluation
python openomni/eval/llama3/t2s_eavl.py
python openomni/eval/qwen2/t2s_eavl.py
Emotional Text-Speech Evaluation
python openomni/eval/llama3/et2s_eavl.py
python openomni/eval/qwen2/et2s_eavl.py
📌 Cases of the text to speech
|
四是四,十是十,十四是十四,四十是四十。 |
黑化肥发灰,灰化肥发黑,黑化肥发灰会挥发,灰化肥挥发会发黑。 |
吃葡萄不吐葡萄皮,不吃葡萄倒吐葡萄皮。 |
|
八百标兵奔北坡,炮兵并排北边跑,炮兵怕把标兵碰,标兵怕碰炮兵炮。 |
红凤凰,黄凤凰,粉红凤凰,花凤凰。 |
牛郎年年恋刘娘,刘娘念念恋牛郎。 |
|
She sells seashells by the seashore. |
Peter Piper picked a peck of pickled peppers. |
Six slippery snails slid slowly seaward. |
|
Six sleek swans swam swiftly southwards. |
I saw Susie sitting in a shoeshine shop. |
Can you can a can as a canner can can a can? |
📌 Cases of the text to emotional speech
|
I am so sad. |
why are you doing this to me. |
what a nice day. |
i am very scared. |
|
我真的很难过. |
你为什么要这样,我真的很生气. |
今天天气真好. |
我真有点害怕. |
📚Video Demo
https://github.com/user-attachments/assets/cd679b7c-9f9d-4631-a1f5-96b1428a8ad4
📚Citation
If you find this repo useful for your research, please consider citing the paper
@article{luo2025openomni,
  title={Openomni: Advancing open-source omnimodal large language models with progressive multimodal alignment and real-time self-aware emotional speech synthesis},
  author={Luo, Run and Lin, Ting-En and Zhang, Haonan and Wu, Yuchuan and Liu, Xiong and Yang, Min and Li, Yongbin and Chen, Longze and Li, Jiaming and Zhang, Lei and others},
  journal={arXiv preprint arXiv:2501.04561},
  year={2025}
}
@article{luo2024mmevol,
  title={Mmevol: Empowering multimodal large language models with evol-instruct},
  author={Luo, Run and Zhang, Haonan and Chen, Longze and Lin, Ting-En and Liu, Xiong and Wu, Yuchuan and Yang, Min and Wang, Minzheng and Zeng, Pengpeng and Gao, Lianli and others},
  journal={ACL 2025},
  year={2024}
}
@article{zhang2025omnicharacter,
  title={OmniCharacter: Towards Immersive Role-Playing Agents with Seamless Speech-Language Personality Interaction},
  author={Zhang, Haonan and Luo, Run and Liu, Xiong and Wu, Yuchuan and Lin, Ting-En and Zeng, Pengpeng and Qu, Qiang and Fang, Feiteng and Yang, Min and Gao, Lianli and others},
  journal={ACL 2025},
  year={2025}
}
@article{zhang2025omnicharacter++,
  title   = {OmniCharacter++: Towards Comprehensive Benchmark for Realistic Role-Playing Agents},
  author  = {Haonan Zhang},
  journal = {TPAMI 2026},
  year = {2026}
}
📧 Contact
if you have any question, please consider following concat for help
-
Run Luo — r.luo@siat.ac.cn
-
Haonan Zhang — zchiowal@gmail.com
Acknowledgement
- LLaVA and LLaVA-Omni: the codebase we built upon. Thanks for their brilliant contributions to the community! We just can't wait to use OpenOmni.
- VLMEvalKit: the amazing open-sourced suit for evaluating various LMMs!
- CosVoice: the amazing open-sourced speech tokenizer for speech discretization and reconstruction with 6k vocabulary size!
- GLM4Voice: the amazing open-sourced speech tokenizer for speech discretization and reconstruction with 16k vocabulary size!
Contributors

66 commits

5 commits
Languages
Python
96.2%
Shell
3.8%
(NIPS 2025) OpenOmni: Official implementation of Advancing Open-Source Omnimodal Large Language Models with Progressive Multimodal Alignment and Real-Time Self-Aware Emotional Speech Synthesis
Python
144
71 commits
updated May 9, 2026
README
OpenOmni: Advancing Open-Source Omnimodal Large Language Models with Progressive Multimodal Alignment and Real-Time Self-Aware Emotional Speech Synthesis
OpenOmni is the end-to-end fully open-sourced pioneering method that successfully incorporates image,speech and text into the omni large language model. OpenOmni's design for speech generation through language bridging and text-guided speech can be quickly trained in situations where omni-modal data and VRAM resources are scarce. OpenOmni not only supports omni-modal nderstanding, but also supports two real-time emotional speech generation modes, CTC mode and AR mode, so that users can flexibly choose according to their needs to achieve a balance between generation speed and quality. The flexible framework design allows OpenOmni to be easily and quickly applied to a variety of downstream tasks, such as speech embodied navigation, multi-role-playing speech dialogue, etc. Everyone is welcome to come and experience it now!🔥 Update
- [2025/09/22]🔥After a year of community evaluation, our work has been accepted by NIPS 2025. Congratulations!
- [2025/05/26]🔥Our [OmniCharacter]—built on MMEvol and OpenOmni series—has been accepted to the main track of ACL 2025. You’re all welcome to give it a try!
- [2025/05/15]🔥Two paper has beed accepted by ACL 2025 main based on our findings (LLaMA-Omin2 and OmniCharacter). We warmly welcome everyone to use our work.
- [2025/05/05]🔥Our gate fusion technology for more acurrate speech content generation is adopted by LLaMA-Omni2
- [2025/02/12]🔥Add some missing file and fix all possible bug
- [2025/01/13]🔥OpenOmni is coming! We release the code, model and data
- [2025/01/09]🔥After two months of company audit! We release the paper
- [2024/11/14]🔥We submit the paper for peer review openreview
- [2024/09/15]🔥We write the first line of OpenOmni project for fully open-sourced pioneering OmniLLM in end-to-end manner.
👀 Contents
- Setup
- Model
- Preparation
- Train
- Evaluation
- Example
- Citation
📷 Setup
Please follow the instructions below to install the required packages.
- Clone this repository
git clone https://github.com/RainBowLuoCS/OpenOmni.git
cd OpenOmni
- Install Package
conda create -n openomni python=3.10 -y
conda activate openomni
pip install --upgrade pip  # enable PEP 660 support
pip install -e ".[train]"
pip install -r requirements.txt
- Install additional packages for training
pip install flash-attn --no-build-isolation
🔥 Fast Usage
After downloading the weights and configuring the paths properly. Two open-sourced speech tokenizer are needed for speech discretization and reconstruction with different vocabulary size! CosVoice for 6K CTC Mode and GLM4Voice for 16K AR Mode
Fast inference for omnimodal input (speech,text,image and video)
python inference.py
Fast interation for omnimodal input (speech,text,image and video)
python demo.py
Model
Here are the pretrained weights and instruction tuning weights
| Stage | Model | Speech Projector | Image Projector | IT Data | Download |
|---|---|---|---|---|---|
| 1-1 | OpenOMNI-Qwen2-7B-Stage1-1 | ckpt | ckpt | openomni_stage1-1.json | ckpt |
| 2-1 | OpenOMNI-Qwen2-7B-Stage2-1 | ckpt | ckpt | openomni_stage2-1.json | ckpt |
| 2-2 | OpenOMNI-Qwen2-7B-Stage2-2 | ckpt | ckpt | openomni_stage2-2.json | ckpt |
| 3-1 | OpenOMNI-Qwen2-7B-Stage3-1 | ckpt | ckpt | openomni_stage3-1.json | ckpt |
| 3-2 | OpenOMNI-Qwen2-7B-Stage3-2 | ckpt | ckpt | openomni_stage3-2.json | ckpt |
Preparation
Dataset
Please follow MMEvol to prepare the corresponding images-text datasets. Here we only provide the details of speech-text datasets.
The following is the data directory tree of OpenOmni
data structure
datasets
├── json # data receipe
│   ├── openomni_stage1-1.json # speech2text pretraining
│   ├── openomni_stage2-1.json # image2text pretraining
│   ├── openomni_stage2-2.json # image2text instruction tuning
│   ├── openomni_stage3-1.json # text2speech pretraining
│   ├── openomni_stage3-2.json # text2speech emotional injection
├── asr # classic bilingual speech corpus
│   ├── AISHELL-4
│   ├── LibriSPeech
│   ├── WeNetSpeech
├── audio_en # synthetic english speech corpus for question
├── audio_llava # synthetic bilingual speech corpus for answer
├── audio_zh # synthetic chinese speech corpus for question
├── audio_unit # synthetic bilingual speech corpus for answer
├── audio_prefer # synthetic emotional bilingual speech corpus for answer
├── audio_reject # synthetic emotional bilingual speech corpus for answer
├── audio_ultrachat # synthetic bilingual speech corpus for answer
├── ai2d
│   ├── abc_images
│   ├── annotations
│   ├── images
│   ├── questions
│   └── categories.json
......
- All file/path starting with "audio" are self-synthesized.
- DPO contains approximately 9k entries for "prefer" and "reject," covering 9 types of emotions.
More details about data curation can be found in our paper.
Train
Speech2Text Pretrain
Please download the MMEvol, AIShell-4, LibriSPeech, WeNetSpeech, OpenOmni Data and organize the data following Preparation before training . Make sure set up the corresponding train script with correct setting (data path, weight path, and hyper-paramaters)
bash scripts/train/llama3/speech2text_pretrain.sh
bash scripts/train/qwen2/speech2text_pretrain.sh
Image2Text Pretrain
Please make sure you download and organize the data following Preparation before training. Make sure set up the corresponding train script with correct setting (data path, weight path, and hyper-paramaters)
bash scripts/train/llama3/image2text_pretrain.sh
bash scripts/train/qwen2/image2text_pretrain.sh
Image2Text Instruction Tuning
Please make sure you download and organize the data following Preparation before training. Make sure set up the corresponding train script with correct setting (data path, weight path, and hyper-paramaters)
bash scripts/train/llama3/image2text_finetune.sh
bash scripts/train/qwen2/image2text_finetue.sh
Text2Speech Pretrain
Please make sure you download and organize the data following Preparation before training. Make sure set up the corresponding train script with correct setting (data path, weight path, and hyper-paramaters)
bash scripts/train/llama3/text2speech_ pretrain.sh
bash scripts/train/qwen2/text2speech_ pretrain.sh
Text2Speech Emotional DPO Tuning
Please make sure you download and organize the data following Preparation before training. Make sure set up the corresponding train script with correct setting (data path, weight path, and hyper-paramaters)
bash scripts/train/llama3/text2speech_ dpo.sh
bash scripts/train/qwen2/text2speech_ dpo.sh
Evaluation
Dataset
Ensure that your api_base, key and dataset are correctly configured before evaluation.
data structure
datasets
├── json # data receipe
│   ├── aishell2_eval.jsonl # aishell evaluation
│   ├── librispeech_eval.jsonl # image2text pretraining
│   ├── wenetspeech_eval.json # image2text instruction tuning
│   ├── openomni_emotion_val.json
├── OmniBench # OmniBench
│   ├── mmdata
│   ├── dataset
│   		├── eval.json
├── Ov-Odyssey # Ov-Odyssey Bench
│   ├── av_odyssey_part1.parquet
│   ├── av_odyssey_part2.parquet
│   ├── av_odyssey_part3.parquet
│   ├── av_odyssey_part4.parquet
│   ├── av_odyssey_part5.parquet
Speech-Text Evaluation
Make sure set up the corresponding train script with correct setting (data path, weight path, and hyper-paramaters)
python openomni/eval/llama3/asr_eavl.py
python openomni/eval/qwen2/asr_eavl.py
| Model | LibriSpeech-test-clean | LibriSpeech-test-other | AIShell2-dev | AIShell2-test | WeNetSpeech-testnet | WeNetSpeech-testmeeting |
|---|---|---|---|---|---|---|
| VITA | 8.1 | 18.4 | 12.2 | 16.5 | ||
| EMOVA | 4.0 | 8.6 | 10.6 | 10.3 | ||
| MINI-OMNI | 4.5 | 9.7 | ||||
| Freeze-Omni | 3.29 | 7.4 | 8.57 | 10.09 | ||
| ours | 2.57 | 5.6 | 6.81 | 6.87 | 7.63 |
Image-Text Evaluation
Refer to MMEvol for detailed OpenCampass Vision Language Evaluation
# run on all 9 datasets
./script/run_inference.sh OpenOmni-Qwen "MME MMMU_DEV_VAL MathVista_MINI LLaVABench RealWorldQA MMStar MMVet AI2D_TEST OCRBench HallusionBench POPE BLINK" all

# The following are instructions for running on a single dataset
# MME
./script/run_inference.sh OpenOmni-Qwen MME all
# MMMU_DEV_VAL
./script/run_inference.sh OpenOmni-Qwen MMMU_DEV_VAL all
# MathVista_MINI
./script/run_inference.sh OpenOmni-Qwen MathVista_MINI all
.....
Speech-Text-Image Evaluation
Please download OmniBench and run the following command
python openomni/eval/llama3/omni_eavl.py
python openomni/eval/qwen2/omni_eavl.py
Speech-Text-Image-Video Evaluation
Please download Ov-Odyssey and run the following command
python openomni/eval/llama3/ov_odyssey_eavl.py
python openomni/eval/qwen2/ov_odyssey_eavl.py
Text-Speech Evaluation
python openomni/eval/llama3/t2s_eavl.py
python openomni/eval/qwen2/t2s_eavl.py
Emotional Text-Speech Evaluation
python openomni/eval/llama3/et2s_eavl.py
python openomni/eval/qwen2/et2s_eavl.py
📌 Cases of the text to speech
|
四是四,十是十,十四是十四,四十是四十。 |
黑化肥发灰,灰化肥发黑,黑化肥发灰会挥发,灰化肥挥发会发黑。 |
吃葡萄不吐葡萄皮,不吃葡萄倒吐葡萄皮。 |
|
八百标兵奔北坡,炮兵并排北边跑,炮兵怕把标兵碰,标兵怕碰炮兵炮。 |
红凤凰,黄凤凰,粉红凤凰,花凤凰。 |
牛郎年年恋刘娘,刘娘念念恋牛郎。 |
|
She sells seashells by the seashore. |
Peter Piper picked a peck of pickled peppers. |
Six slippery snails slid slowly seaward. |
|
Six sleek swans swam swiftly southwards. |
I saw Susie sitting in a shoeshine shop. |
Can you can a can as a canner can can a can? |
📌 Cases of the text to emotional speech
|
I am so sad. |
why are you doing this to me. |
what a nice day. |
i am very scared. |
|
我真的很难过. |
你为什么要这样,我真的很生气. |
今天天气真好. |
我真有点害怕. |
📚Video Demo
https://github.com/user-attachments/assets/cd679b7c-9f9d-4631-a1f5-96b1428a8ad4
📚Citation
If you find this repo useful for your research, please consider citing the paper
@article{luo2025openomni,
  title={Openomni: Advancing open-source omnimodal large language models with progressive multimodal alignment and real-time self-aware emotional speech synthesis},
  author={Luo, Run and Lin, Ting-En and Zhang, Haonan and Wu, Yuchuan and Liu, Xiong and Yang, Min and Li, Yongbin and Chen, Longze and Li, Jiaming and Zhang, Lei and others},
  journal={arXiv preprint arXiv:2501.04561},
  year={2025}
}
@article{luo2024mmevol,
  title={Mmevol: Empowering multimodal large language models with evol-instruct},
  author={Luo, Run and Zhang, Haonan and Chen, Longze and Lin, Ting-En and Liu, Xiong and Wu, Yuchuan and Yang, Min and Wang, Minzheng and Zeng, Pengpeng and Gao, Lianli and others},
  journal={ACL 2025},
  year={2024}
}
@article{zhang2025omnicharacter,
  title={OmniCharacter: Towards Immersive Role-Playing Agents with Seamless Speech-Language Personality Interaction},
  author={Zhang, Haonan and Luo, Run and Liu, Xiong and Wu, Yuchuan and Lin, Ting-En and Zeng, Pengpeng and Qu, Qiang and Fang, Feiteng and Yang, Min and Gao, Lianli and others},
  journal={ACL 2025},
  year={2025}
}
@article{zhang2025omnicharacter++,
  title   = {OmniCharacter++: Towards Comprehensive Benchmark for Realistic Role-Playing Agents},
  author  = {Haonan Zhang},
  journal = {TPAMI 2026},
  year = {2026}
}
📧 Contact
if you have any question, please consider following concat for help
-
Run Luo — r.luo@siat.ac.cn
-
Haonan Zhang — zchiowal@gmail.com
Acknowledgement
- LLaVA and LLaVA-Omni: the codebase we built upon. Thanks for their brilliant contributions to the community! We just can't wait to use OpenOmni.
- VLMEvalKit: the amazing open-sourced suit for evaluating various LMMs!
- CosVoice: the amazing open-sourced speech tokenizer for speech discretization and reconstruction with 6k vocabulary size!
- GLM4Voice: the amazing open-sourced speech tokenizer for speech discretization and reconstruction with 16k vocabulary size!
Contributors
66 commits
5 commits
Languages
Python
96.2%
Shell
3.8%