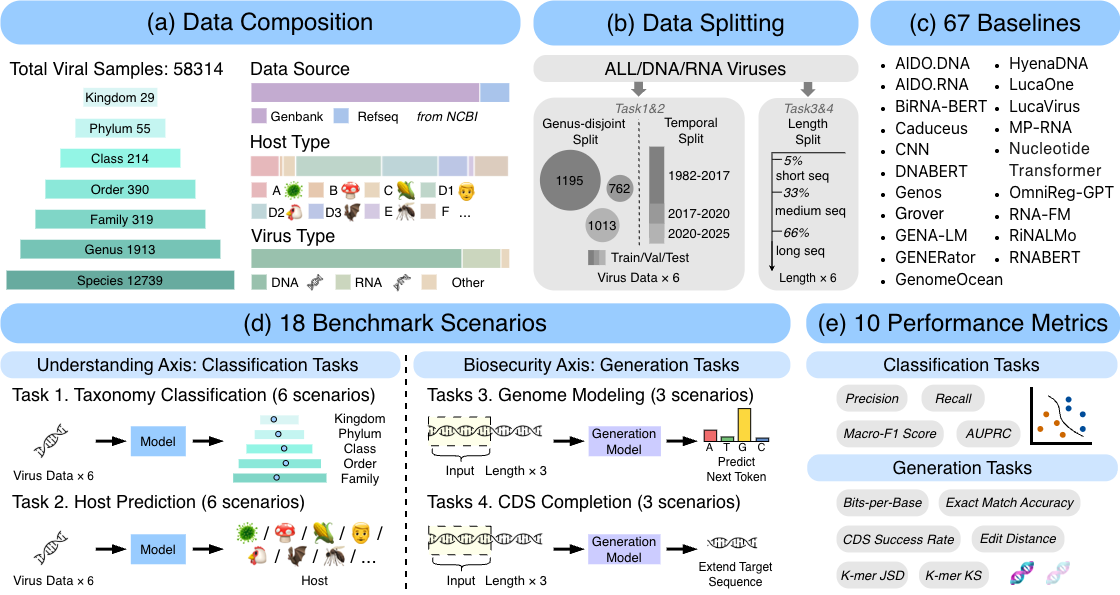
ViroBench is a dual-axis diagnostic benchmark for viral sequence modeling, designed to evaluate both:
Key stats
This repository provides a unified, reproducible evaluation pipeline and diagnostic protocols for viral nucleotide foundation models (NFMs).
Two stringent split axes for realistic generalization
Length-bucketed generation diagnostics
Unified protocol
Targets
Split strategies
Metrics
The dataset is available at YDXX/ViroBench. To download it with Git Xet:
# Install Git Xet: https://hf.co/docs/hub/git-xet
brew install git-xet
git xet install

# Clone the dataset repository
git clone https://huggingface.co/datasets/YDXX/ViroBench
To clone only the repository pointers without downloading the large files:
GIT_LFS_SKIP_SMUDGE=1 git clone https://huggingface.co/datasets/YDXX/ViroBench
Alternatively, install the Hugging Face CLI and download the dataset directly:
curl -LsSf https://hf.co/cli/install.sh | bash
hf download YDXX/ViroBench --repo-type=dataset
We adopt a unified evaluation protocol where the backbone is frozen and only a lightweight head is trained:
The benchmark includes NFMs and conventional baselines (e.g., CNN) across diverse design families and tokenization strategies.
git clone https://github.com/QIANJINYDX/ViroBench
cd ViroBench
For model-specific setup (e.g. Evo2, HyenaDNA), please refer to each model’s official documentation.
Data is provided under data/all_viral/: classification splits in data/all_viral/cls_data/, generation data in data/all_viral/gen_data/ (e.g. genome_gen/, CDS buckets). Adjust paths in the scripts if you use a custom layout.
# Example: genus-disjoint taxonomy (all NA types)
python script/run_all.py \
  --model_name evo2_1b_base \
  --dataset_name ALL-taxon-genus

# Other tasks: DNA-taxon-genus, RNA-host-times, ALL-host-genus, etc.
# Format: {DNA|RNA|ALL}-{taxon|host}-{genus|times}
Genome modeling (BPB)
python script/run_all_ppl.py \
  --model_name evo2_1b_base \
  --dataset_name genome-long
# Buckets: genome-short, genome-medium, genome-long
CDS completion (k-mer + similarity + CSR)
python script/run_all_gen.py \
  --model_name evo2_1b_base \
  --dataset_name cds-medium
# Buckets: cds-short, cds-medium, cds-long
To add a new model, implement:
encode(): maps input sequence → fixed-dimensional embedding (for classification).generate() / score(): support generation (CDS completion) and/or likelihood scoring (genome modeling).Then wire the model in the codebase (e.g. in script/run_all.py, script/run_all_gen.py, script/run_all_ppl.py and in models/) so the pipeline can run it across tasks and splits consistently.
results/tables/ and generate plots in results/figures/.This benchmark includes generation diagnostics intended for risk measurement and model safety research.