
A reproduction of the Deepseek-OCR model including training
Python
211
10 commits
updated Nov 21, 2025
README
DeepOCR
A reproduction of the Deepseek-OCR model based on the VILA codebase. DeepOCR explores context optical compression through vision-text token compression, achieving competitive OCR performance with minimal vision tokens.
✨ Highlights
- Token Efficiency: Achieves competitive OCR performance using ~250 vision tokens
- Open Source Implementation: Complete reproduction of DeepSeek-OCR's innovative optical compression architecture using the VILA framework
- Novel DeepEncoder: Combines SAM (window attention) + CLIP (global attention) with 16× convolutional compression for efficient high-resolution processing (1024×1024+)
- Production Ready: Includes complete training pipeline, evaluation scripts, and pre-trained checkpoints for immediate use
📄 Paper Overview
Deepseek-OCR: Contexts Optical Compression
arXiv Paper
Key Features
- Vision-Text Compression: Compresses text into visual representations at 7-20× ratios while maintaining high OCR accuracy
- DeepEncoder Architecture: Novel encoder combining SAM (80M) + CLIP (300M) with 16× convolutional compressor
🏗️ Architecture
┌─────────────────────────────────────────────────────┐
│                   DeepOCR                           │
├─────────────────────────────────────────────────────┤
│                                                     │
│  ┌─────────────────────────────────────────────┐    │
│  │           DeepEncoder (380M)                │    │
│  │                                             │    │
│  │  ┌──────────────┐   ┌─────────┐  ┌────────┐ │    │
│  │  │  SAM-base    │───│ Conv    │──│ CLIP   │ │    │
│  │  │  (80M)       │   │ 16×     │  │ (300M) │ │    │
│  │  │ Window Attn  │   │Compress │  │ Global │ │    │
│  │  └──────────────┘   └─────────┘  └────────┘ │    │
│  │                                             │    │
│  └─────────────────────────────────────────────┘    │
│                        ↓                            │
│  ┌─────────────────────────────────────────────┐    │
│  │      Linear Projector (2048 → LLM dim)      │    │
│  └─────────────────────────────────────────────┘    │
│                        ↓                            │
│  ┌─────────────────────────────────────────────┐    │
│  │               Qwen 2-7B                     │    │
│  └─────────────────────────────────────────────┘    │
│                                                     │
└─────────────────────────────────────────────────────┘
🚀 Installation
# Clone the repository
git clone https://github.com/pkulium/DeepOCR
cd DeepOCR

# Set up environment
./environment_setup.sh deeporc
conda activate deeporc

# Install additional dependencies for OCR
pip install safetensors einops easydict mupdf
📦 Model Checkpoints
Download required checkpoints:
# SAM and CLIP checkpoints (combined in one file)
# Place at: checkpoints/sam_clip_ckpt/model_cache/model-00001-of-000001.safetensors
huggingface-cli download  pkulium/sam_clip_ckpt

# Base LLM (Qwen2-7B-Instruct)
huggingface-cli download Efficient-Large-Model/Qwen2-VL-7B-Instruct
🎯 Training
Stage 1: Alignment (Projector Training)
Trains the vision-to-text projector while freezing vision encoder and LLM:
bash scripts/NVILA-Lite/align_ocr.sh \
    Efficient-Large-Model/Qwen2-VL-7B-Instruct \
    llava_15_mix \
    runs/train/ocr-qwen2-vl-8b-align
Key parameters:
- Batch size: 512
- Learning rate: 1e-3
- Epochs: 1
- Data: LLaVA-CC3M-Pretrain-595K
- Trainable: Projector only
Stage 2: Pretraining
Full model training with OCR data:
bash scripts/NVILA-Lite/pretrain_ocr.sh \
    runs/train/ocr-qwen2-vl-8b-align/model \
    olmOCR-mix-pretrain \
    runs/train/ocr-qwen2-vl-8b-pretrain
Key parameters:
- Batch size: 32
- Learning rate: 5e-5
- Epochs: 1
- Data: allenai/olmOCR-mix-1025
- Trainable: Projector + LLM
Data Preparation
The model requires three types of data across two training stages:
Stage 1: Initialize Projector
- Dataset: CC3M (Conceptual Captions 3M)
Stage 2: Model Pretrain
- Data sources: PDF documents and images
- Dataset:
allenai/olmOCR-mix-1025
🔬 Evaluation
OmniDocBench/Olm_bench Evaluation
bash scripts/eval/all.sh
Custom Document OCR
python llava/eval/omini_doc_bench.py \
  --model-path <model_path> \
  --input-folder <input_images> \
  --output-folder <output_markdown> \
  --text "Free OCR."
Available prompts:
"<image>\nFree OCR."- Plain text extraction"<image>\n<|grounding|>Convert the document to markdown."- With layout"<image>\nParse the figure."- Chart/figure parsing"<image>\nDescribe this image in detail."- General description
Batch Evaluation with VILA-eval
vila-eval \
    --model-name NVILA-8B-OCR \
    --model-path runs/train/ocr-qwen2-vl-8b-pretrain/model \
    --conv-mode auto \
    --tags-include local
📊 Key Implementation Details
1. DeepEncoder (llava/model/multimodal_encoder/sam_clip/)
Core Components:
-
deepencoder.py: Implements SAM and CLIP vision towersbuild_sam_vit_b(): SAM-base with 768-dim, 12 layers, window attentionbuild_clip_l(): CLIP-large with 1024-dim, 24 layers, global attentionMlpProjector: Token compression module
-
modeling_sam_clip.py: Main SAMCLIP wrapper- Handles multi-resolution input processing
- Dynamic tile-based processing for high-res images
- Token concatenation:
[CLIP_cls, CLIP_patches, SAM_features]
Token Flow:
Input (1024×1024) → SAM (4096 tokens) → Conv16× (256 tokens)
                                      ↓
                  CLIP (256 tokens) → Concat → 2048-dim features
2. Image Processing (image_process.py)
# Dynamic resolution preprocessing
def dynamic_preprocess(image, min_num=2, max_num=6, image_size=640):
    """
    Splits image into tiles based on aspect ratio
    Returns: List of tile images + crop ratio
    """
Processing modes:
- Single image: Resize or pad to base size (1024×1024)
- Cropping enabled: Dynamic tiling (2-6 tiles per dimension)
- Output: Global view (1024×1024) + Local tiles (640×640 each)
3. Multimodal Projector (base_projector.py)
class MultimodalProjector:
    def __init__(self):
        self.layers = nn.Linear(2048, llm_hidden_size)
        self.image_newline = nn.Parameter(...)  # Token separator
        self.view_seperator = nn.Parameter(...)  # View separator
Token formatting:
[Local_Tiles] + [Image_Newline] + [Global_View] + [View_Separator]
4. Configuration (config.py)
Key settings:
BASE_SIZE = 1024        # Global view size
IMAGE_SIZE = 640        # Tile size
CROP_MODE = True        # Enable dynamic tiling
MIN_CROPS = 2           # Min tiles per dimension
MAX_CROPS = 6           # Max tiles per dimension
MAX_CONCURRENCY = 100   # Batch processing limit
🎨 Usage Examples
Quick Start
First, download the model from Hugging Face:
huggingface-cli download pkulium/easy_deepocr --local-dir ./easy_deepocr_sam_clip
Then use the model:
vila-infer \
    --model-path ./easy_deepocr_sam_clip \
    --conv-mode auto \
    --text "Free OCR." \
    --media "./assets/test.png"
Document with Layout
import llava

# Load model
model = llava.load("./easy_deepocr_sam_clip")

prompt = [
    Image("document.pdf"),
    "<|grounding|>Convert the document to markdown."
]
response = model.generate_content(prompt)
Chart Parsing
prompt = [Image("chart.png"), "Parse the figure."]
response = model.generate_content(prompt)
# Returns: HTML table or structured data
📈 Performance Benchmarks
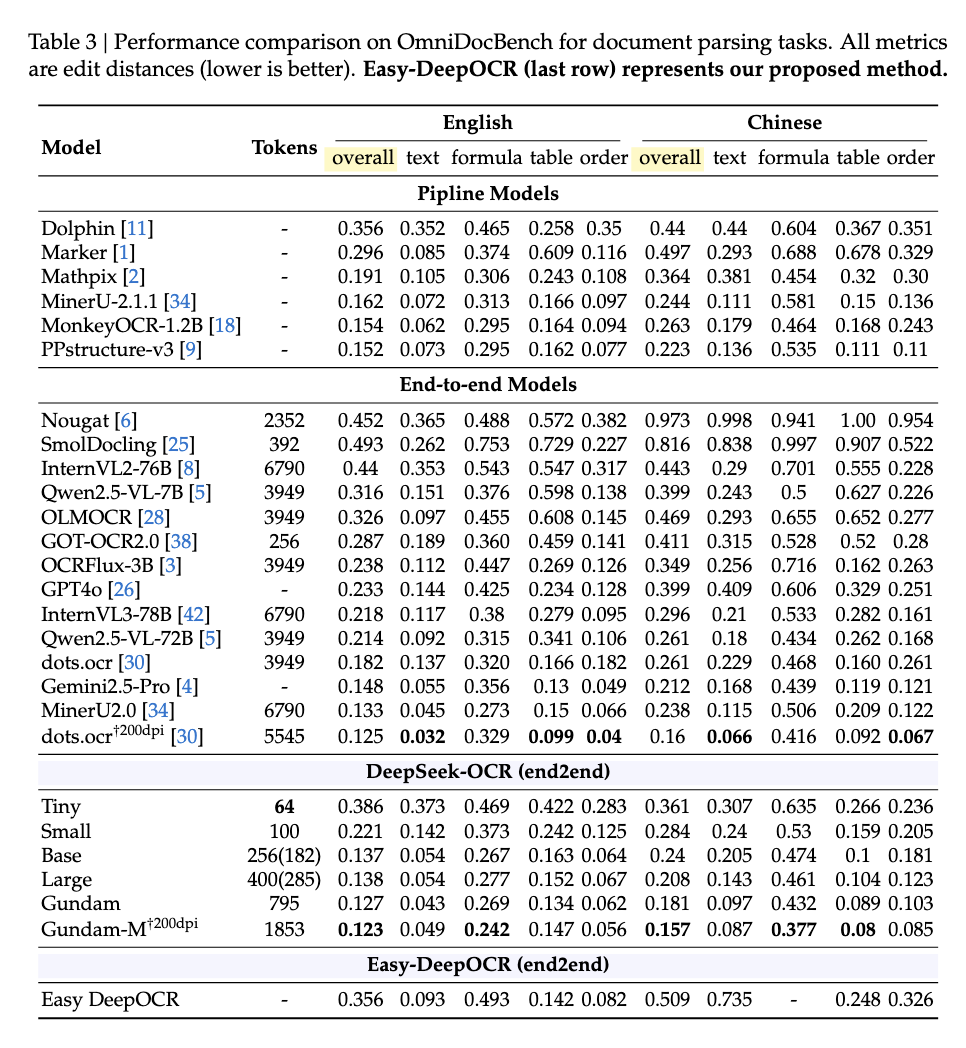
OmniDocBench Results
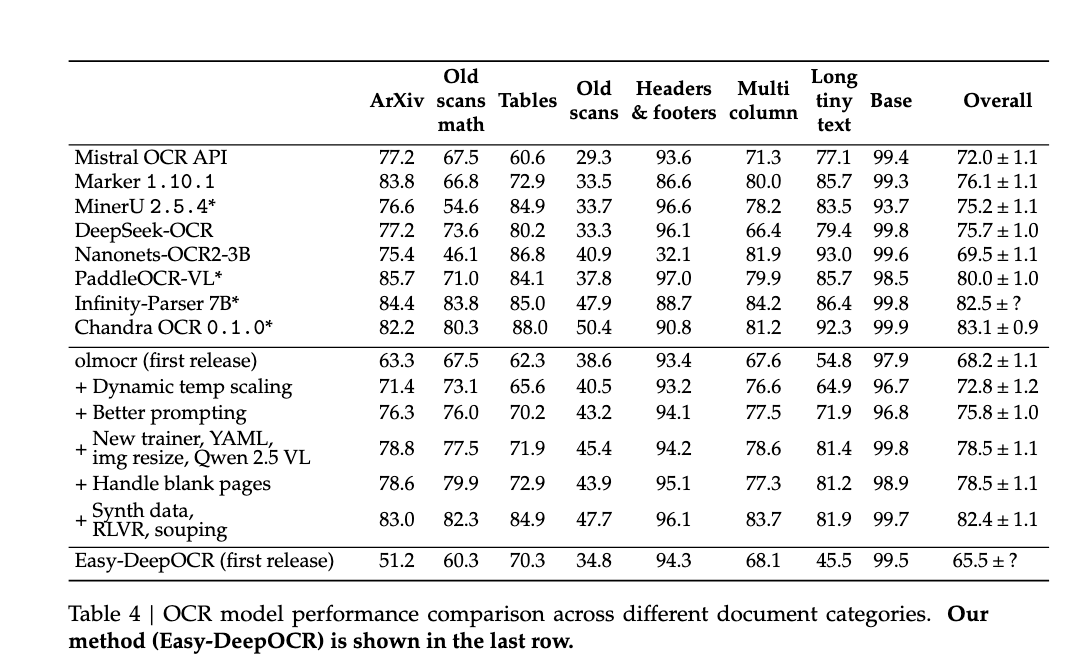
olmOCR-Bench Results
🔧 Troubleshooting
Common Issues
-
CUDA OOM during training
# Reduce batch size or enable gradient checkpointing --per_device_train_batch_size 1 \ --gradient_accumulation_steps 16 \ --gradient_checkpointing True -
NCCL timeout in multi-GPU training
export NCCL_TIMEOUT=1800 export NCCL_IB_TIMEOUT=22 -
Position_ids buffer device mismatch
- Fixed in
deepencoder.pyby reinitializing position_ids after checkpoint loading
- Fixed in
-
Distributed training hangs
- Ensure all processes take same conditional branches (see
modeling_sam_clip.pyfix)
- Ensure all processes take same conditional branches (see
📝 Key Differences from Original Paper
This reproduction is based on the VILA codebase and has some adaptations:
- LLM Decoder: Uses Qwen2-VL-7B instead of Deepseek-3B-MoE
- Training Framework: VILA's training pipeline instead of Deepseek's custom framework
- Data Loading: Adapted to VILA's data format and preprocessing
- Multi-resolution: Simplified implementation with preset modes
🎯 Future Work
- Implement needle-in-a-haystack tests for context compression
- Add support for digital-optical text interleaved pretraining
- Optimize inference with TensorRT/vLLM
- Add LoRA fine-tuning support for domain adaptation
- Implement forgetting mechanism experiments
📚 Citation
If you find our work helpful, please consider citing it:
 @misc{DeepOCR,
  title        = {DeepOCR},
  year         = {2025},
  howpublished = {\url{https://github.com/pkulium/DeepOCR}},
  note         = {Accessed: 2025-11-04}
}
📄 License
- Code: Apache 2.0 License
- Model weights: CC-BY-NC-SA-4.0 License
- For commercial use, please contact the authors
🙏 Acknowledgments
- Original Deepseek-OCR paper and team
- VILA codebase and NVIDIA team
- SAM (Segment Anything Model) from Meta
- CLIP from OpenAI
- Qwen2 from Qwen team
Note: This is a research reproduction. For production deployment, consider the official Deepseek-OCR implementation.
Contributors

10 commits
Similar repos





Languages
Python
96.4%
Shell
1.9%
Cuda
1.5%
A reproduction of the Deepseek-OCR model including training
Python
211
10 commits
updated Nov 21, 2025
README
DeepOCR
A reproduction of the Deepseek-OCR model based on the VILA codebase. DeepOCR explores context optical compression through vision-text token compression, achieving competitive OCR performance with minimal vision tokens.
✨ Highlights
- Token Efficiency: Achieves competitive OCR performance using ~250 vision tokens
- Open Source Implementation: Complete reproduction of DeepSeek-OCR's innovative optical compression architecture using the VILA framework
- Novel DeepEncoder: Combines SAM (window attention) + CLIP (global attention) with 16× convolutional compression for efficient high-resolution processing (1024×1024+)
- Production Ready: Includes complete training pipeline, evaluation scripts, and pre-trained checkpoints for immediate use
📄 Paper Overview
Deepseek-OCR: Contexts Optical Compression
arXiv Paper
Key Features
- Vision-Text Compression: Compresses text into visual representations at 7-20× ratios while maintaining high OCR accuracy
- DeepEncoder Architecture: Novel encoder combining SAM (80M) + CLIP (300M) with 16× convolutional compressor
🏗️ Architecture
┌─────────────────────────────────────────────────────┐
│                   DeepOCR                           │
├─────────────────────────────────────────────────────┤
│                                                     │
│  ┌─────────────────────────────────────────────┐    │
│  │           DeepEncoder (380M)                │    │
│  │                                             │    │
│  │  ┌──────────────┐   ┌─────────┐  ┌────────┐ │    │
│  │  │  SAM-base    │───│ Conv    │──│ CLIP   │ │    │
│  │  │  (80M)       │   │ 16×     │  │ (300M) │ │    │
│  │  │ Window Attn  │   │Compress │  │ Global │ │    │
│  │  └──────────────┘   └─────────┘  └────────┘ │    │
│  │                                             │    │
│  └─────────────────────────────────────────────┘    │
│                        ↓                            │
│  ┌─────────────────────────────────────────────┐    │
│  │      Linear Projector (2048 → LLM dim)      │    │
│  └─────────────────────────────────────────────┘    │
│                        ↓                            │
│  ┌─────────────────────────────────────────────┐    │
│  │               Qwen 2-7B                     │    │
│  └─────────────────────────────────────────────┘    │
│                                                     │
└─────────────────────────────────────────────────────┘
🚀 Installation
# Clone the repository
git clone https://github.com/pkulium/DeepOCR
cd DeepOCR

# Set up environment
./environment_setup.sh deeporc
conda activate deeporc

# Install additional dependencies for OCR
pip install safetensors einops easydict mupdf
📦 Model Checkpoints
Download required checkpoints:
# SAM and CLIP checkpoints (combined in one file)
# Place at: checkpoints/sam_clip_ckpt/model_cache/model-00001-of-000001.safetensors
huggingface-cli download  pkulium/sam_clip_ckpt

# Base LLM (Qwen2-7B-Instruct)
huggingface-cli download Efficient-Large-Model/Qwen2-VL-7B-Instruct
🎯 Training
Stage 1: Alignment (Projector Training)
Trains the vision-to-text projector while freezing vision encoder and LLM:
bash scripts/NVILA-Lite/align_ocr.sh \
    Efficient-Large-Model/Qwen2-VL-7B-Instruct \
    llava_15_mix \
    runs/train/ocr-qwen2-vl-8b-align
Key parameters:
- Batch size: 512
- Learning rate: 1e-3
- Epochs: 1
- Data: LLaVA-CC3M-Pretrain-595K
- Trainable: Projector only
Stage 2: Pretraining
Full model training with OCR data:
bash scripts/NVILA-Lite/pretrain_ocr.sh \
    runs/train/ocr-qwen2-vl-8b-align/model \
    olmOCR-mix-pretrain \
    runs/train/ocr-qwen2-vl-8b-pretrain
Key parameters:
- Batch size: 32
- Learning rate: 5e-5
- Epochs: 1
- Data: allenai/olmOCR-mix-1025
- Trainable: Projector + LLM
Data Preparation
The model requires three types of data across two training stages:
Stage 1: Initialize Projector
- Dataset: CC3M (Conceptual Captions 3M)
Stage 2: Model Pretrain
- Data sources: PDF documents and images
- Dataset:
allenai/olmOCR-mix-1025
🔬 Evaluation
OmniDocBench/Olm_bench Evaluation
bash scripts/eval/all.sh
Custom Document OCR
python llava/eval/omini_doc_bench.py \
  --model-path <model_path> \
  --input-folder <input_images> \
  --output-folder <output_markdown> \
  --text "Free OCR."
Available prompts:
"<image>\nFree OCR."- Plain text extraction"<image>\n<|grounding|>Convert the document to markdown."- With layout"<image>\nParse the figure."- Chart/figure parsing"<image>\nDescribe this image in detail."- General description
Batch Evaluation with VILA-eval
vila-eval \
    --model-name NVILA-8B-OCR \
    --model-path runs/train/ocr-qwen2-vl-8b-pretrain/model \
    --conv-mode auto \
    --tags-include local
📊 Key Implementation Details
1. DeepEncoder (llava/model/multimodal_encoder/sam_clip/)
Core Components:
-
deepencoder.py: Implements SAM and CLIP vision towersbuild_sam_vit_b(): SAM-base with 768-dim, 12 layers, window attentionbuild_clip_l(): CLIP-large with 1024-dim, 24 layers, global attentionMlpProjector: Token compression module
-
modeling_sam_clip.py: Main SAMCLIP wrapper- Handles multi-resolution input processing
- Dynamic tile-based processing for high-res images
- Token concatenation:
[CLIP_cls, CLIP_patches, SAM_features]
Token Flow:
Input (1024×1024) → SAM (4096 tokens) → Conv16× (256 tokens)
                                      ↓
                  CLIP (256 tokens) → Concat → 2048-dim features
2. Image Processing (image_process.py)
# Dynamic resolution preprocessing
def dynamic_preprocess(image, min_num=2, max_num=6, image_size=640):
    """
    Splits image into tiles based on aspect ratio
    Returns: List of tile images + crop ratio
    """
Processing modes:
- Single image: Resize or pad to base size (1024×1024)
- Cropping enabled: Dynamic tiling (2-6 tiles per dimension)
- Output: Global view (1024×1024) + Local tiles (640×640 each)
3. Multimodal Projector (base_projector.py)
class MultimodalProjector:
    def __init__(self):
        self.layers = nn.Linear(2048, llm_hidden_size)
        self.image_newline = nn.Parameter(...)  # Token separator
        self.view_seperator = nn.Parameter(...)  # View separator
Token formatting:
[Local_Tiles] + [Image_Newline] + [Global_View] + [View_Separator]
4. Configuration (config.py)
Key settings:
BASE_SIZE = 1024        # Global view size
IMAGE_SIZE = 640        # Tile size
CROP_MODE = True        # Enable dynamic tiling
MIN_CROPS = 2           # Min tiles per dimension
MAX_CROPS = 6           # Max tiles per dimension
MAX_CONCURRENCY = 100   # Batch processing limit
🎨 Usage Examples
Quick Start
First, download the model from Hugging Face:
huggingface-cli download pkulium/easy_deepocr --local-dir ./easy_deepocr_sam_clip
Then use the model:
vila-infer \
    --model-path ./easy_deepocr_sam_clip \
    --conv-mode auto \
    --text "Free OCR." \
    --media "./assets/test.png"
Document with Layout
import llava

# Load model
model = llava.load("./easy_deepocr_sam_clip")

prompt = [
    Image("document.pdf"),
    "<|grounding|>Convert the document to markdown."
]
response = model.generate_content(prompt)
Chart Parsing
prompt = [Image("chart.png"), "Parse the figure."]
response = model.generate_content(prompt)
# Returns: HTML table or structured data
📈 Performance Benchmarks
OmniDocBench Results
olmOCR-Bench Results
🔧 Troubleshooting
Common Issues
-
CUDA OOM during training
# Reduce batch size or enable gradient checkpointing --per_device_train_batch_size 1 \ --gradient_accumulation_steps 16 \ --gradient_checkpointing True -
NCCL timeout in multi-GPU training
export NCCL_TIMEOUT=1800 export NCCL_IB_TIMEOUT=22 -
Position_ids buffer device mismatch
- Fixed in
deepencoder.pyby reinitializing position_ids after checkpoint loading
- Fixed in
-
Distributed training hangs
- Ensure all processes take same conditional branches (see
modeling_sam_clip.pyfix)
- Ensure all processes take same conditional branches (see
📝 Key Differences from Original Paper
This reproduction is based on the VILA codebase and has some adaptations:
- LLM Decoder: Uses Qwen2-VL-7B instead of Deepseek-3B-MoE
- Training Framework: VILA's training pipeline instead of Deepseek's custom framework
- Data Loading: Adapted to VILA's data format and preprocessing
- Multi-resolution: Simplified implementation with preset modes
🎯 Future Work
- Implement needle-in-a-haystack tests for context compression
- Add support for digital-optical text interleaved pretraining
- Optimize inference with TensorRT/vLLM
- Add LoRA fine-tuning support for domain adaptation
- Implement forgetting mechanism experiments
📚 Citation
If you find our work helpful, please consider citing it:
 @misc{DeepOCR,
  title        = {DeepOCR},
  year         = {2025},
  howpublished = {\url{https://github.com/pkulium/DeepOCR}},
  note         = {Accessed: 2025-11-04}
}
📄 License
- Code: Apache 2.0 License
- Model weights: CC-BY-NC-SA-4.0 License
- For commercial use, please contact the authors
🙏 Acknowledgments
- Original Deepseek-OCR paper and team
- VILA codebase and NVIDIA team
- SAM (Segment Anything Model) from Meta
- CLIP from OpenAI
- Qwen2 from Qwen team
Note: This is a research reproduction. For production deployment, consider the official Deepseek-OCR implementation.
Similar repos
Contributors
10 commits
Languages
Python
96.4%
Shell
1.9%
Cuda
1.5%