
Official implementation of "X-CoT: Explainable Text-to-Video Retrieval via LLM-based Chain-of-Thought Reasoning (EMNLP 2025)"
See the codeREADME
X-CoT: Explainable Text-to-Video Retrieval via LLM-based Chain-of-Thought Reasoning

This is the official code for the EMNLP 2025 paper "X-CoT: Explainable Text-to-Video Retrieval via LLM-based Chain-of-Thought Reasoning" by Prasanna Reddy Pulakurthi, Jiamian Wang, Majid Rabbani, Sohail Dianat, Raghuveer Rao, and Zhiqiang Tao.
Overview
X‑CoT (Explainable Chain‑of‑Thought reranking) takes as input:
- Initial retrieval results (top‑K retrieved video indices).
- Video breakdowns JSONL (summaries, objects, actions, scene tags, frame captions per video).
It then prompts an LLM to compare pairs of candidate videos against the query, using the breakdowns for grounded, interpretable signals. The pairwise outcomes are aggregated via a lightweight sorting and Bradley‑Terry fit to produce a re‑ranked list with improved recall.
Quick Start
Run in Google Colab
python xcot.py --exp_name=MSRVTT --dataset_name=MSRVTT --topk=20 --topk_retrieval_method=xpool
Detailed Local Setup
Step 1: Obtain Initial Retriever Results
Option 1
Download the provided initial retrieval results from the [Hugging Face] link and place them at: outputs/<dataset>/<method>_ranking_<mode>.jsonl
Option 2
Prepare Datasets:
- To download the MSRVTT, MSVD, LSMDC, and DiDeMo datasets, please refer to [CLIP4Clip repo].
- Once downloaded, provide the videos directory via
--videos_dirwhen generating initial retrievals.
Dependencies:
- To run Clip and Xpool, please take a look at the [XPool repo] for the dependencies.
- To run VLM2Vec, refer to the [VLM2Vec repo] for the dependencies.
Run the initial retrievers:
See initial_retrievers_cmds.sh for examples of CLI commands.
python xpool_ranking.py --test_mode=benchmark --exp_name=MSRVTT --videos_dir=data/MSRVTT/videos/all --batch_size=32 --huggingface --load_epoch=-1 --dataset_name=MSRVTT --retrieve_topk --topk=20 --topk_retrieval_method=xpool
- The pretrained X-Pool weights are automatically downloaded from [Google Drive] and placed in
outputs/<dataset>/model_best.pth - Initial retriever results will be saved in
outputs/<dataset>/<method>_ranking_<mode>.jsonl.
Step 2: Install Dependencies to Run X-CoT
-
Clone this repository.
git clone https://github.com/PrasannaPulakurthi/X-CoT.git cd X-CoT -
Python 3.9+, CUDA‑enabled, PyTorch (GPU): https://pytorch.org/get-started/locally/
Example (CUDA 12.x): pip install torch --index-url https://download.pytorch.org/whl/cu121
-
Install additional packages to run X‑CoT using the following command.
pip install -r requirements.txt
Step 3: Run X-CoT
-
Obtain video breakdowns.
- Download the provided JSONL files from the [Hugging Face] link above and place them at:
outputs/<dataset>/video_breakdowns_<mode>.jsonl
- Download the provided JSONL files from the [Hugging Face] link above and place them at:
-
Make sure to have the initial retriever results at
outputs/<dataset>/<method>_ranking_<mode>.jsonlby following Step 1. -
Run X‑CoT reranking.
python xcot.py --exp_name=MSRVTT --dataset_name=MSRVTT --topk=20 --topk_retrieval_method=xpool
This reads the initial rankings and breakdowns, queries the LLM (default: Qwen/Qwen2.5-7B-Instruct-1M), and logs recall metrics. Logs are written under logs/<exp_name>/<timestamp>/. See xcot_cmds.sh for the full list of CLI commands.
Results
| X-CoT vs CLIP (R@1) | X-CoT vs VLM2Vec (R@1) | X-CoT vs X-Pool (R@1) |
|---|---|---|
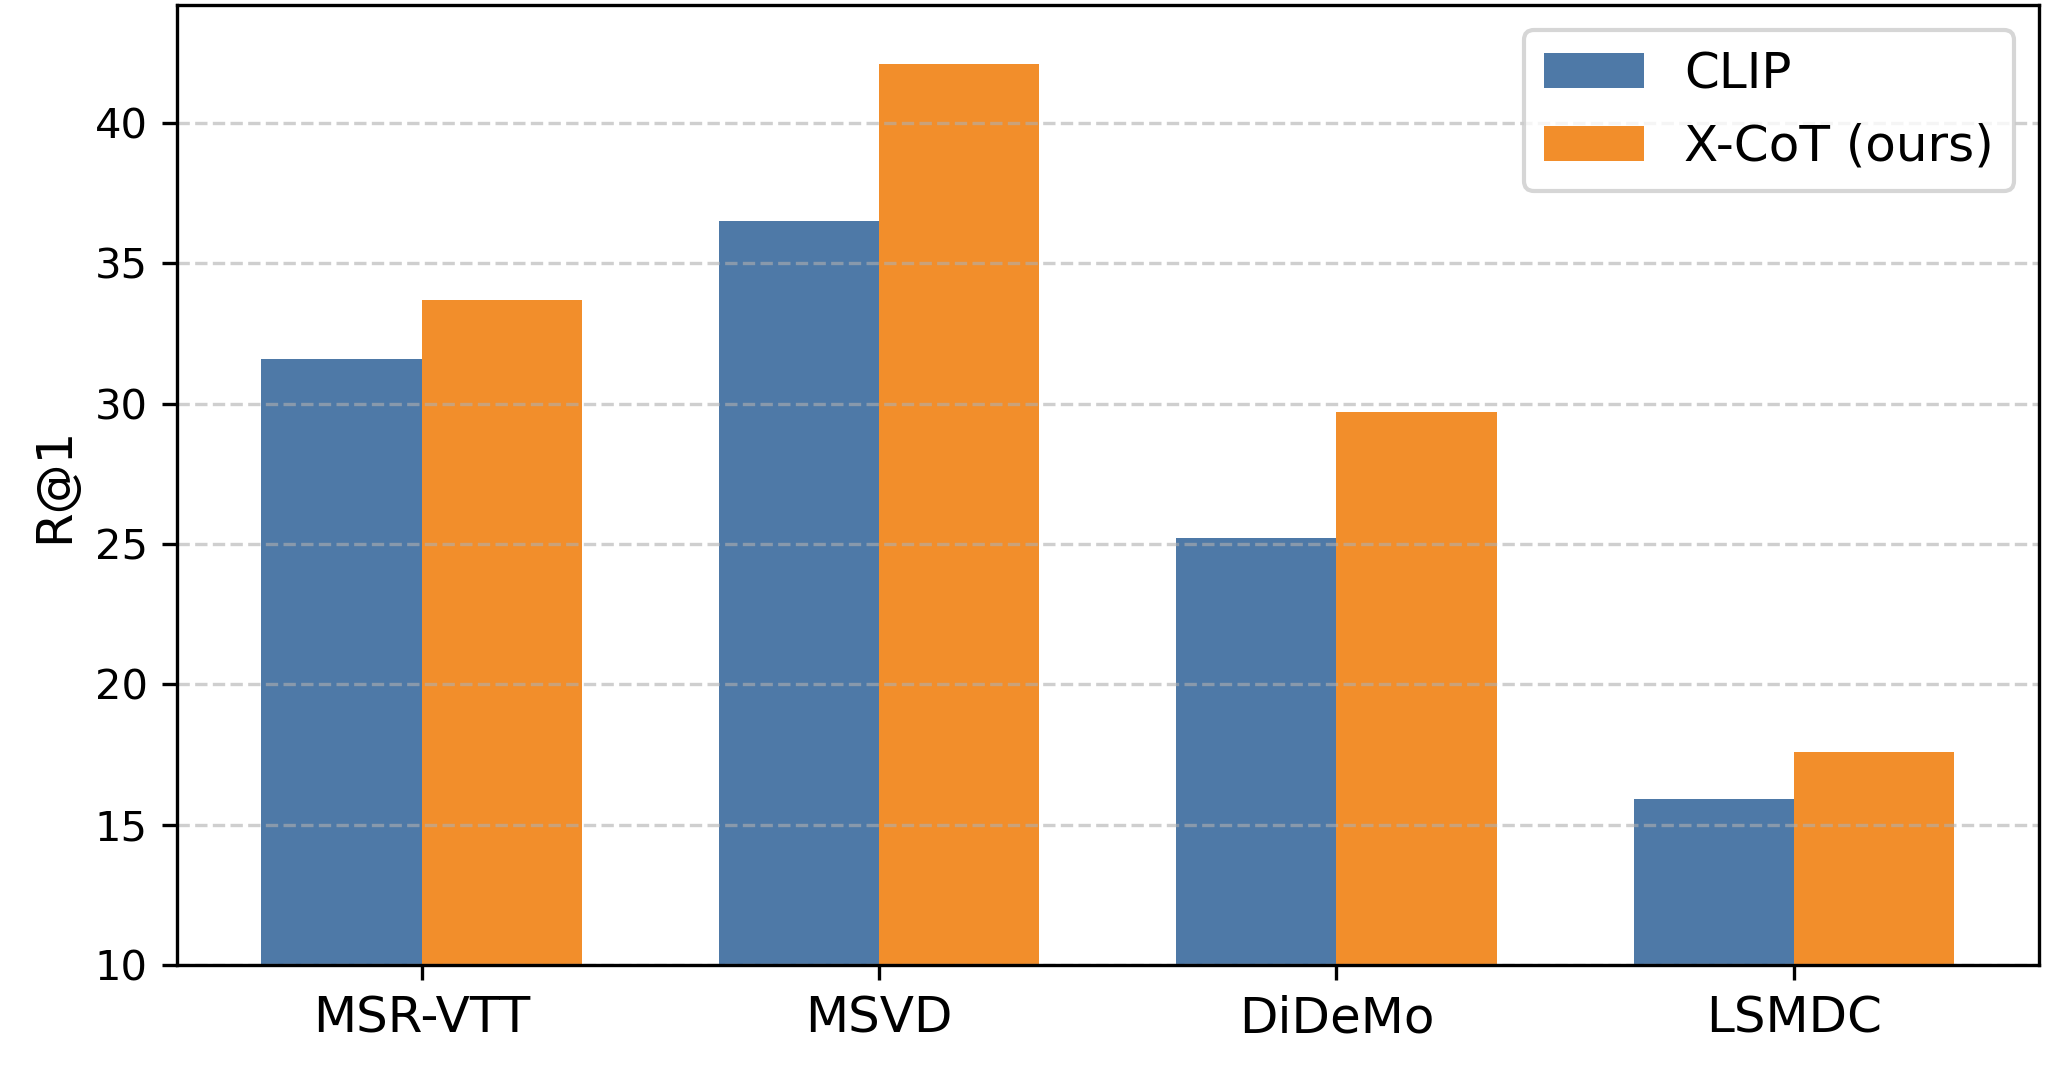 | 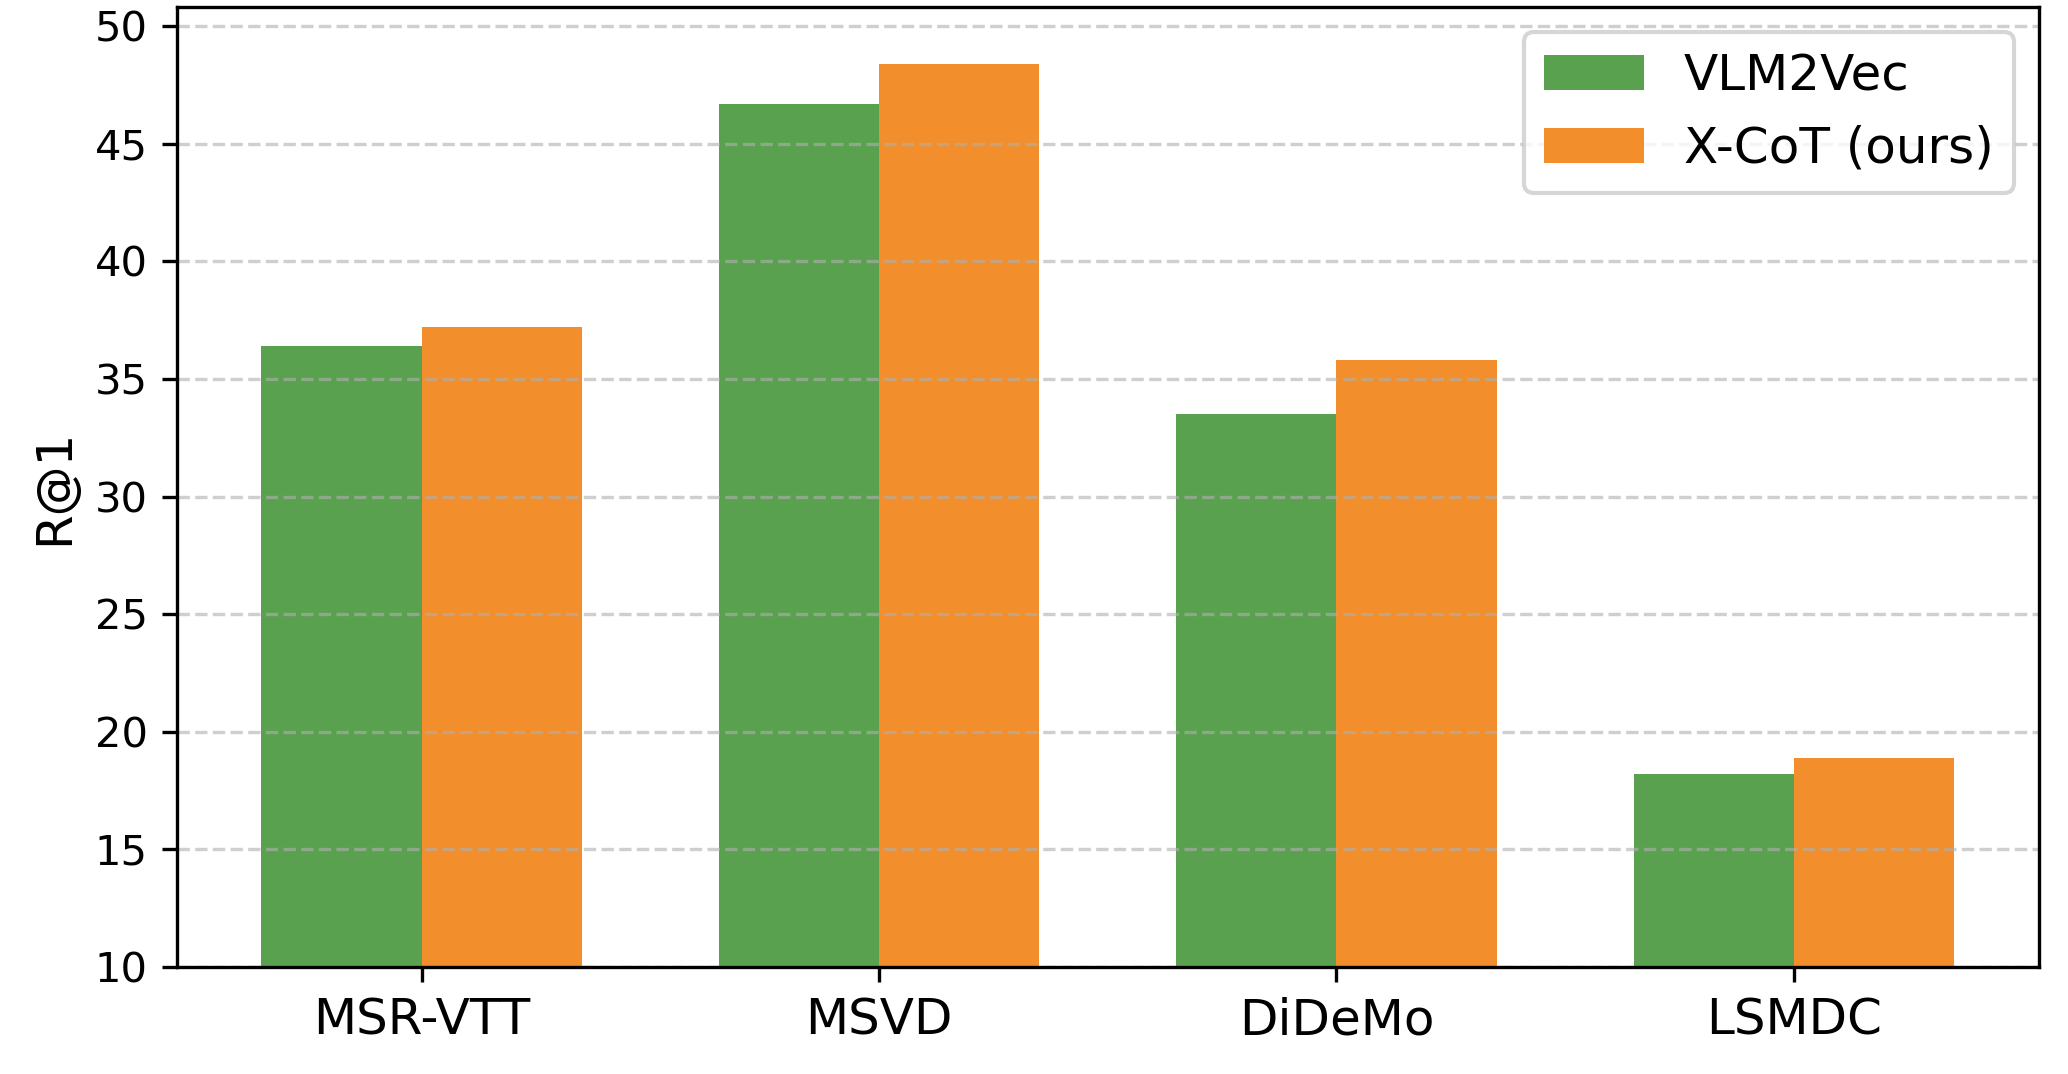 | 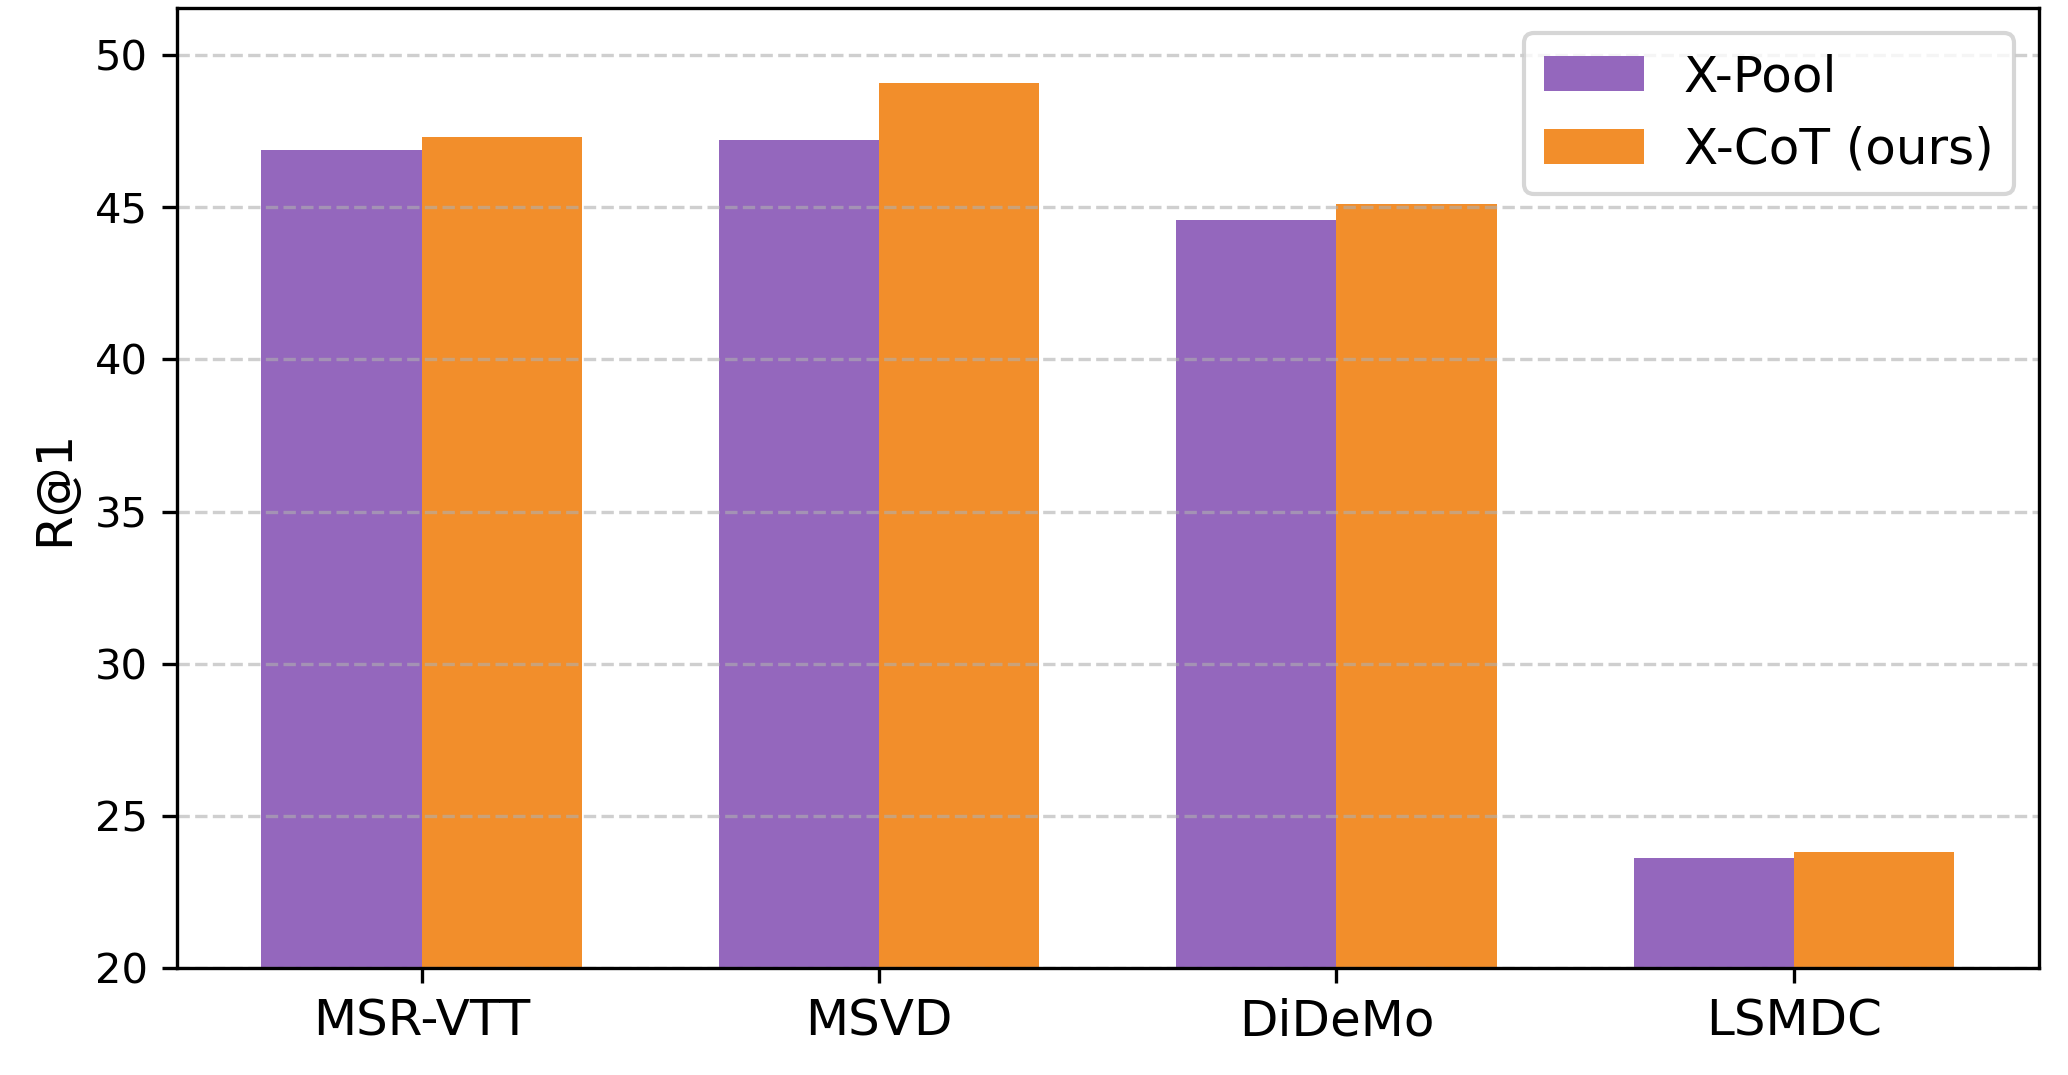 |
Citation
If you find this work valuable for your research, we kindly request that you cite the following paper:
@inproceedings{pulakurthi2025x,
  title={X-CoT: Explainable Text-to-Video Retrieval via LLM-based Chain-of-Thought Reasoning},
  author={Pulakurthi, Prasanna Reddy and Wang, Jiamian and Rabbani, Majid and Dianat, Sohail and Rao, Raghuveer and Tao, Zhiqiang},
  booktitle={Proceedings of the 2025 Conference on Empirical Methods in Natural Language Processing},
  pages={31172--31183},
  year={2025}
}
Acknowledgements


Contributors

19 commits
Similar repos


Languages
Python
99.3%
Official implementation of "X-CoT: Explainable Text-to-Video Retrieval via LLM-based Chain-of-Thought Reasoning (EMNLP 2025)"
See the codeREADME
X-CoT: Explainable Text-to-Video Retrieval via LLM-based Chain-of-Thought Reasoning
This is the official code for the EMNLP 2025 paper "X-CoT: Explainable Text-to-Video Retrieval via LLM-based Chain-of-Thought Reasoning" by Prasanna Reddy Pulakurthi, Jiamian Wang, Majid Rabbani, Sohail Dianat, Raghuveer Rao, and Zhiqiang Tao.
Overview
X‑CoT (Explainable Chain‑of‑Thought reranking) takes as input:
- Initial retrieval results (top‑K retrieved video indices).
- Video breakdowns JSONL (summaries, objects, actions, scene tags, frame captions per video).
It then prompts an LLM to compare pairs of candidate videos against the query, using the breakdowns for grounded, interpretable signals. The pairwise outcomes are aggregated via a lightweight sorting and Bradley‑Terry fit to produce a re‑ranked list with improved recall.
Quick Start
Run in Google Colab
python xcot.py --exp_name=MSRVTT --dataset_name=MSRVTT --topk=20 --topk_retrieval_method=xpool
Detailed Local Setup
Step 1: Obtain Initial Retriever Results
Option 1
Download the provided initial retrieval results from the [Hugging Face] link and place them at: outputs/<dataset>/<method>_ranking_<mode>.jsonl
Option 2
Prepare Datasets:
- To download the MSRVTT, MSVD, LSMDC, and DiDeMo datasets, please refer to [CLIP4Clip repo].
- Once downloaded, provide the videos directory via
--videos_dirwhen generating initial retrievals.
Dependencies:
- To run Clip and Xpool, please take a look at the [XPool repo] for the dependencies.
- To run VLM2Vec, refer to the [VLM2Vec repo] for the dependencies.
Run the initial retrievers:
See initial_retrievers_cmds.sh for examples of CLI commands.
python xpool_ranking.py --test_mode=benchmark --exp_name=MSRVTT --videos_dir=data/MSRVTT/videos/all --batch_size=32 --huggingface --load_epoch=-1 --dataset_name=MSRVTT --retrieve_topk --topk=20 --topk_retrieval_method=xpool
- The pretrained X-Pool weights are automatically downloaded from [Google Drive] and placed in
outputs/<dataset>/model_best.pth - Initial retriever results will be saved in
outputs/<dataset>/<method>_ranking_<mode>.jsonl.
Step 2: Install Dependencies to Run X-CoT
-
Clone this repository.
git clone https://github.com/PrasannaPulakurthi/X-CoT.git cd X-CoT -
Python 3.9+, CUDA‑enabled, PyTorch (GPU): https://pytorch.org/get-started/locally/
Example (CUDA 12.x): pip install torch --index-url https://download.pytorch.org/whl/cu121
-
Install additional packages to run X‑CoT using the following command.
pip install -r requirements.txt
Step 3: Run X-CoT
-
Obtain video breakdowns.
- Download the provided JSONL files from the [Hugging Face] link above and place them at:
outputs/<dataset>/video_breakdowns_<mode>.jsonl
- Download the provided JSONL files from the [Hugging Face] link above and place them at:
-
Make sure to have the initial retriever results at
outputs/<dataset>/<method>_ranking_<mode>.jsonlby following Step 1. -
Run X‑CoT reranking.
python xcot.py --exp_name=MSRVTT --dataset_name=MSRVTT --topk=20 --topk_retrieval_method=xpool
This reads the initial rankings and breakdowns, queries the LLM (default: Qwen/Qwen2.5-7B-Instruct-1M), and logs recall metrics. Logs are written under logs/<exp_name>/<timestamp>/. See xcot_cmds.sh for the full list of CLI commands.
Results
| X-CoT vs CLIP (R@1) | X-CoT vs VLM2Vec (R@1) | X-CoT vs X-Pool (R@1) |
|---|---|---|
| | |
Citation
If you find this work valuable for your research, we kindly request that you cite the following paper:
@inproceedings{pulakurthi2025x,
  title={X-CoT: Explainable Text-to-Video Retrieval via LLM-based Chain-of-Thought Reasoning},
  author={Pulakurthi, Prasanna Reddy and Wang, Jiamian and Rabbani, Majid and Dianat, Sohail and Rao, Raghuveer and Tao, Zhiqiang},
  booktitle={Proceedings of the 2025 Conference on Empirical Methods in Natural Language Processing},
  pages={31172--31183},
  year={2025}
}
Acknowledgements
Similar repos
Contributors
19 commits
Languages
Python
99.3%