
HuMo: Human-Centric Video Generation via Collaborative Multi-Modal Conditioning
See the codeREADME
HuMo: Human-Centric Video Generation via Collaborative Multi-Modal Conditioning



Liyang Chen * , Tianxiang Ma * , Jiawei Liu, Bingchuan Li † ,
Zhuowei Chen, Lijie Liu, Xu He, Gen Li, Qian He, Zhiyong Wu §
* Equal contribution, † Project lead, § Corresponding author
Tsinghua University | Intelligent Creation Team, ByteDance
🔥 Latest News
- Dec 23, 2025. 🔥🔥 We release HuMoSet dataset containing 670K video samples with diverse reference images, dense video captions, and strict audio-visual synchronization.
- Oct 19, 2025: A HuggingFace Space is provided for convenient test. Thank OutofAi for the update.
- Oct 15, 2025: OpenBayes provides 3 hours of free GPU computation for testing the 1.7B and 17B models. You can easily get started by following the tutorial. We welcome you to give it a try.
- Sep 30, 2025: We release the Stage-1 dataset for training subject preservation.
- Sep 17, 2025: ComfyUI officially supports HuMo-1.7B!
- Sep 16, 2025: We release the 1.7B weights, which generate a 480P video in 8 minutes on a 32G GPU. The visual quality is lower than that of the 17B model, but the audio-visual sync remains nearly unaffected.
- Sep 13, 2025: The 17B model is merged into ComfyUI-Wan, which can be run on a NVIDIA 3090 GPU. Thank kijai for the update!
- Sep 10, 2025: We release the 17B weights and inference codes.
- Sep 9, 2025: We release the Project Page and Technique Report of HuMo.
✨ Key Features
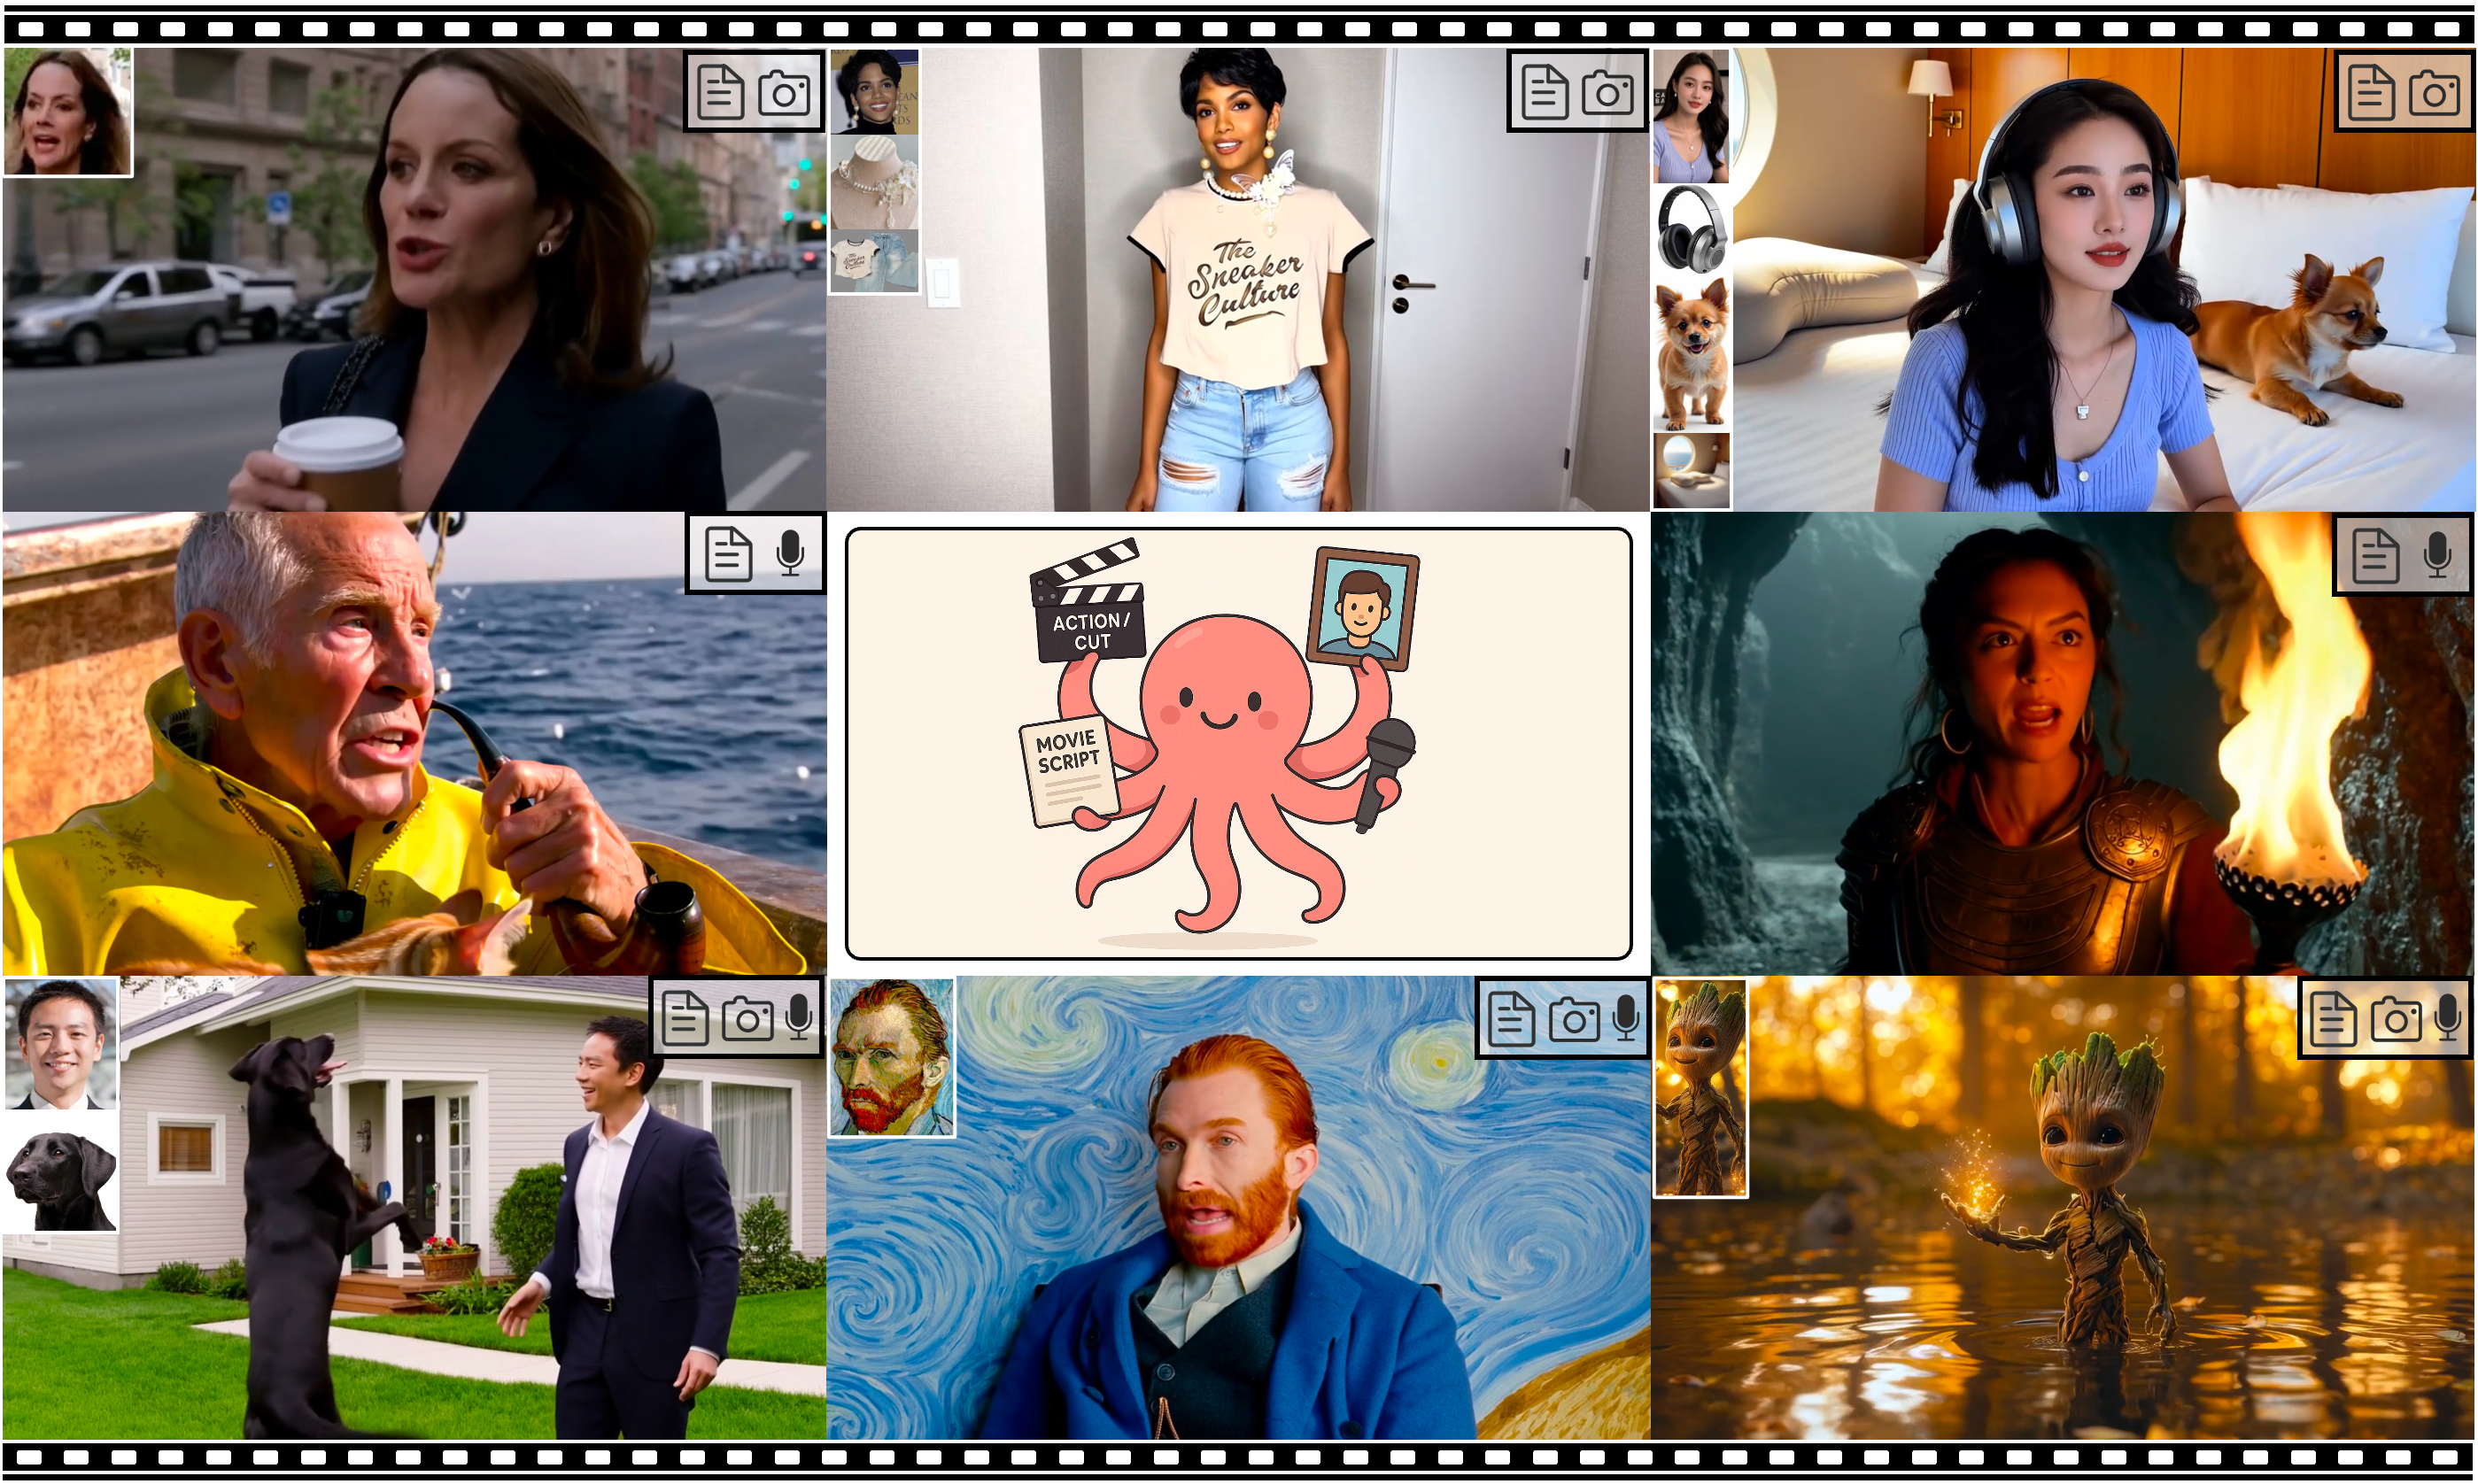
HuMo is a unified, human-centric video generation framework designed to produce high-quality, fine-grained, and controllable human videos from multimodal inputs—including text, images, and audio. It supports strong text prompt following, consistent subject preservation, synchronized audio-driven motion.
- VideoGen from Text-Image - Customize character appearance, clothing, makeup, props, and scenes using text prompts combined with reference images.
- VideoGen from Text-Audio - Generate audio-synchronized videos solely from text and audio inputs, removing the need for image references and enabling greater creative freedom.
- VideoGen from Text-Image-Audio - Achieve the higher level of customization and control by combining text, image, and audio guidance.
📑 Todo List
- Release Paper
- Checkpoint of HuMo-17B
- Checkpoint of HuMo-1.7B
- Inference Codes
[ ] Text-Image Input- Text-Audio Input
- Text-Image-Audio Input
- Multi-GPU Inference
- Best-Practice Guide of HuMo for Movie-Level Generation
- Checkpoint for Longer Generation
- Prompts to Generate Demo of Faceless Thrones
- Training Data
⚡️ Quickstart
Installation
conda create -n humo python=3.11
conda activate humo
pip install torch==2.5.1 torchvision==0.20.1 torchaudio==2.5.1 --index-url https://download.pytorch.org/whl/cu124
pip install flash_attn==2.6.3
pip install -r requirements.txt
conda install -c conda-forge ffmpeg
Model Preparation
| Models | Download Link | Notes |
|---|---|---|
| HuMo-17B | 🤗 Huggingface | Supports 480P & 720P |
| HuMo-1.7B | 🤗 Huggingface | Lightweight on 32G GPU |
| HuMo-Longer | 🤗 Huggingface | Longer generation to be released in Oct. |
| Wan-2.1 | 🤗 Huggingface | VAE & Text encoder |
| Whisper-large-v3 | 🤗 Huggingface | Audio encoder |
| Audio separator | 🤗 Huggingface | Remove background noise (optional) |
Download models using huggingface-cli:
huggingface-cli download Wan-AI/Wan2.1-T2V-1.3B --local-dir ./weights/Wan2.1-T2V-1.3B
huggingface-cli download bytedance-research/HuMo --local-dir ./weights/HuMo
huggingface-cli download openai/whisper-large-v3 --local-dir ./weights/whisper-large-v3
huggingface-cli download huangjackson/Kim_Vocal_2 --local-dir ./weights/audio_separator
Run Multimodal-Condition-to-Video Generation
Our model is compatible with both 480P and 720P resolutions. 720P inference will achieve much better quality.
Some tips
- Please prepare your text, reference images and audio as described in test_case.json.
- We support Multi-GPU inference using FSDP + Sequence Parallel.
- The model is trained on 97-frame videos at 25 FPS. Generating video longer than 97 frames may degrade the performance. We will provide a new checkpoint for longer generation.
Configure HuMo
HuMo’s behavior and output can be customized by modifying generate.yaml configuration file.
The following parameters control generation length, video resolution, and how text, image, and audio inputs are balanced:
generation:
  frames: <int>                 # Number of frames for the generated video.
  scale_a: <float>              # Strength of audio guidance. Higher = better audio-motion sync.
  scale_t: <float>              # Strength of text guidance. Higher = better adherence to text prompts.
  mode: "TA"                    # Input mode: "TA" for text+audio; "TIA" for text+image+audio.
  height: 720                   # Video height (e.g., 720 or 480).
  width: 1280                   # Video width (e.g., 1280 or 832).

dit:
  sp_size: <int>                # Sequence parallelism size. Set this equal to the number of used GPUs.

diffusion:
  timesteps:
    sampling:
      steps: 50                 # Number of denoising steps. Lower (30–40) = faster generation.
1. Text-Audio Input
git pull  # always remember to pull latest codes!
bash scripts/infer_ta.sh  # infer with 17B model
bash scripts/infer_ta_1_7B.sh  # infer with 1.7B model
2. Text-Image-Audio Input
git pull  # always remember to pull latest codes!
bash scripts/infer_tia.sh  # infer with 17B model
bash scripts/infer_tia_1_7B.sh  # infer with 1.7B model
🎞️ HuMoSet Dataset
Although the HuMo paper utilizes this dataset primarily for stage 2 training, it is fully capable of supporting training on top of existing video foundation models for a wide range of applications, including but not limited to:
- Talking Human Models: Training highly realistic talking head generation systems.
- Multimodal Control: Developing models like HuMo with precise multimodal conditional control capabilities, supporting inputs such as text, reference images, and audio.
- Customized Video Generation: Creating advanced generative models (e.g., Sora 2-level capabilities) that support customized identity and voice preservation.
Key Features
- Diverse Reference Images: For every video sample, we provide a corresponding reference image featuring the same identity (ID) but with distinct variations in clothing, accessories, background, and hairstyle. This diversity is crucial for robust identity preservation training.
- Dense Video Descriptions: We utilize Qwen2.5-VL to generate dense, high-quality descriptive captions for each video, enabling fine-grained text-to-video capabilities.
- Audio-Visual Synchronization: All video samples are strictly processed to ensure perfect synchronization between audio and visual tracks.
- Open Source Origin: All videos and reference images are curated exclusively from open-source datasets (such as OpenHumanVid). No internal or proprietary company data is included.
Demonstration
The reference image of the person in the video is displayed in the top-left corner, while the video description is shown below the video. Please scroll right on the table below to view more cases.
| A middle-aged man with short, graying hair sits upright in a dimly lit home setting, facing the camera. He wears a purple-and-white plaid shirt, remains mostly still, and speaks with a serious, concerned expression. | In an office-like setting, a blonde woman in a black leather jacket faces a man in a dark suit seen from behind. She remains still, maintains eye contact, and displays a serious, focused expression, suggesting determination. | Against a gray stone wall, a woman in a tan military uniform stands upright, speaking with a serious, focused expression. A similarly dressed man stands behind her holding a rifle, remaining still and attentive. | In a dimly lit office with bookshelves, a man wearing glasses and a vest sits facing a woman, holding and gesturing with a plaid shirt as he speaks earnestly. The woman, mostly still and seen from the side, listens attentively. |
| In a wood-paneled office, a man in a tweed jacket and tie sits upright and speaks with a serious, thoughtful expression to someone in a dark suit seen from behind. | Outdoors in front of a brick house, a red-haired woman wearing gardening gloves holds pruning shears and faces the camera, appearing focused as she explains something. | In a store or office setting, a man in a maroon sweater sits facing another person, maintaining steady eye contact with a neutral, slightly focused expression while the other listens from off-camera. | In a dim, bluish environment, a young boy in a red jacket leans against a large marine creature. He opens his eyes and shifts from calm to concerned, showing fear and vulnerability as the creature gently rests a hand on his shoulder in comfort. |
Download
You can download the dataset by cloning the repository from ModelScope:
# Option 1: Using ModelScope. Much faster for users in the Chinese Mainland
pip install modelscope[framework]
modelscope download --dataset leoniuschen/HuMoSet --local_dir ./HuMoSet

# Option 2: Using Git
git lfs install
git clone https://modelscope.cn/datasets/leoniuschen/HuMoSet.git
Dataset Structure:
video/: This folder contains the target video files.reference_image/: This folder stores the corresponding reference image for each video.video_caption.parquet: A metadata file containing the dense descriptions for all videos.
👍 Acknowledgements
Our work builds upon and is greatly inspired by several outstanding open-source projects, including Wan2.1, Phantom, SeedVR, MEMO, Hallo3, OpenHumanVid, OpenS2V-Nexus, ConsisID, Qwen2.5-VL and Whisper. We sincerely thank the authors and contributors of these projects for generously sharing their excellent codes and ideas.
⭐ Citation
If HuMo is helpful, please help to ⭐ the repo.
If you find this project useful for your research, please consider citing our paper.
BibTeX
@misc{chen2025humo,
      title={HuMo: Human-Centric Video Generation via Collaborative Multi-Modal Conditioning},
      author={Liyang Chen and Tianxiang Ma and Jiawei Liu and Bingchuan Li and Zhuowei Chen and Lijie Liu and Xu He and Gen Li and Qian He and Zhiyong Wu},
      year={2025},
      eprint={2509.08519},
      archivePrefix={arXiv},
      primaryClass={cs.CV},
      url={https://arxiv.org/abs/2509.08519},
}
📧 Contact
If you have any comments or questions regarding this open-source project, please open a new issue or contact Liyang Chen and Tianxiang Ma.
Contributors


Similar repos




Languages
Python
98.5%
Shell
1.5%
HuMo: Human-Centric Video Generation via Collaborative Multi-Modal Conditioning
See the codeREADME
HuMo: Human-Centric Video Generation via Collaborative Multi-Modal Conditioning
Liyang Chen * , Tianxiang Ma * , Jiawei Liu, Bingchuan Li † ,
Zhuowei Chen, Lijie Liu, Xu He, Gen Li, Qian He, Zhiyong Wu §
* Equal contribution, † Project lead, § Corresponding author
Tsinghua University | Intelligent Creation Team, ByteDance
🔥 Latest News
- Dec 23, 2025. 🔥🔥 We release HuMoSet dataset containing 670K video samples with diverse reference images, dense video captions, and strict audio-visual synchronization.
- Oct 19, 2025: A HuggingFace Space is provided for convenient test. Thank OutofAi for the update.
- Oct 15, 2025: OpenBayes provides 3 hours of free GPU computation for testing the 1.7B and 17B models. You can easily get started by following the tutorial. We welcome you to give it a try.
- Sep 30, 2025: We release the Stage-1 dataset for training subject preservation.
- Sep 17, 2025: ComfyUI officially supports HuMo-1.7B!
- Sep 16, 2025: We release the 1.7B weights, which generate a 480P video in 8 minutes on a 32G GPU. The visual quality is lower than that of the 17B model, but the audio-visual sync remains nearly unaffected.
- Sep 13, 2025: The 17B model is merged into ComfyUI-Wan, which can be run on a NVIDIA 3090 GPU. Thank kijai for the update!
- Sep 10, 2025: We release the 17B weights and inference codes.
- Sep 9, 2025: We release the Project Page and Technique Report of HuMo.
✨ Key Features
HuMo is a unified, human-centric video generation framework designed to produce high-quality, fine-grained, and controllable human videos from multimodal inputs—including text, images, and audio. It supports strong text prompt following, consistent subject preservation, synchronized audio-driven motion.
- VideoGen from Text-Image - Customize character appearance, clothing, makeup, props, and scenes using text prompts combined with reference images.
- VideoGen from Text-Audio - Generate audio-synchronized videos solely from text and audio inputs, removing the need for image references and enabling greater creative freedom.
- VideoGen from Text-Image-Audio - Achieve the higher level of customization and control by combining text, image, and audio guidance.
📑 Todo List
- Release Paper
- Checkpoint of HuMo-17B
- Checkpoint of HuMo-1.7B
- Inference Codes
[ ] Text-Image Input- Text-Audio Input
- Text-Image-Audio Input
- Multi-GPU Inference
- Best-Practice Guide of HuMo for Movie-Level Generation
- Checkpoint for Longer Generation
- Prompts to Generate Demo of Faceless Thrones
- Training Data
⚡️ Quickstart
Installation
conda create -n humo python=3.11
conda activate humo
pip install torch==2.5.1 torchvision==0.20.1 torchaudio==2.5.1 --index-url https://download.pytorch.org/whl/cu124
pip install flash_attn==2.6.3
pip install -r requirements.txt
conda install -c conda-forge ffmpeg
Model Preparation
| Models | Download Link | Notes |
|---|---|---|
| HuMo-17B | 🤗 Huggingface | Supports 480P & 720P |
| HuMo-1.7B | 🤗 Huggingface | Lightweight on 32G GPU |
| HuMo-Longer | 🤗 Huggingface | Longer generation to be released in Oct. |
| Wan-2.1 | 🤗 Huggingface | VAE & Text encoder |
| Whisper-large-v3 | 🤗 Huggingface | Audio encoder |
| Audio separator | 🤗 Huggingface | Remove background noise (optional) |
Download models using huggingface-cli:
huggingface-cli download Wan-AI/Wan2.1-T2V-1.3B --local-dir ./weights/Wan2.1-T2V-1.3B
huggingface-cli download bytedance-research/HuMo --local-dir ./weights/HuMo
huggingface-cli download openai/whisper-large-v3 --local-dir ./weights/whisper-large-v3
huggingface-cli download huangjackson/Kim_Vocal_2 --local-dir ./weights/audio_separator
Run Multimodal-Condition-to-Video Generation
Our model is compatible with both 480P and 720P resolutions. 720P inference will achieve much better quality.
Some tips
- Please prepare your text, reference images and audio as described in test_case.json.
- We support Multi-GPU inference using FSDP + Sequence Parallel.
- The model is trained on 97-frame videos at 25 FPS. Generating video longer than 97 frames may degrade the performance. We will provide a new checkpoint for longer generation.
Configure HuMo
HuMo’s behavior and output can be customized by modifying generate.yaml configuration file.
The following parameters control generation length, video resolution, and how text, image, and audio inputs are balanced:
generation:
  frames: <int>                 # Number of frames for the generated video.
  scale_a: <float>              # Strength of audio guidance. Higher = better audio-motion sync.
  scale_t: <float>              # Strength of text guidance. Higher = better adherence to text prompts.
  mode: "TA"                    # Input mode: "TA" for text+audio; "TIA" for text+image+audio.
  height: 720                   # Video height (e.g., 720 or 480).
  width: 1280                   # Video width (e.g., 1280 or 832).

dit:
  sp_size: <int>                # Sequence parallelism size. Set this equal to the number of used GPUs.

diffusion:
  timesteps:
    sampling:
      steps: 50                 # Number of denoising steps. Lower (30–40) = faster generation.
1. Text-Audio Input
git pull  # always remember to pull latest codes!
bash scripts/infer_ta.sh  # infer with 17B model
bash scripts/infer_ta_1_7B.sh  # infer with 1.7B model
2. Text-Image-Audio Input
git pull  # always remember to pull latest codes!
bash scripts/infer_tia.sh  # infer with 17B model
bash scripts/infer_tia_1_7B.sh  # infer with 1.7B model
🎞️ HuMoSet Dataset
Although the HuMo paper utilizes this dataset primarily for stage 2 training, it is fully capable of supporting training on top of existing video foundation models for a wide range of applications, including but not limited to:
- Talking Human Models: Training highly realistic talking head generation systems.
- Multimodal Control: Developing models like HuMo with precise multimodal conditional control capabilities, supporting inputs such as text, reference images, and audio.
- Customized Video Generation: Creating advanced generative models (e.g., Sora 2-level capabilities) that support customized identity and voice preservation.
Key Features
- Diverse Reference Images: For every video sample, we provide a corresponding reference image featuring the same identity (ID) but with distinct variations in clothing, accessories, background, and hairstyle. This diversity is crucial for robust identity preservation training.
- Dense Video Descriptions: We utilize Qwen2.5-VL to generate dense, high-quality descriptive captions for each video, enabling fine-grained text-to-video capabilities.
- Audio-Visual Synchronization: All video samples are strictly processed to ensure perfect synchronization between audio and visual tracks.
- Open Source Origin: All videos and reference images are curated exclusively from open-source datasets (such as OpenHumanVid). No internal or proprietary company data is included.
Demonstration
The reference image of the person in the video is displayed in the top-left corner, while the video description is shown below the video. Please scroll right on the table below to view more cases.
| A middle-aged man with short, graying hair sits upright in a dimly lit home setting, facing the camera. He wears a purple-and-white plaid shirt, remains mostly still, and speaks with a serious, concerned expression. | In an office-like setting, a blonde woman in a black leather jacket faces a man in a dark suit seen from behind. She remains still, maintains eye contact, and displays a serious, focused expression, suggesting determination. | Against a gray stone wall, a woman in a tan military uniform stands upright, speaking with a serious, focused expression. A similarly dressed man stands behind her holding a rifle, remaining still and attentive. | In a dimly lit office with bookshelves, a man wearing glasses and a vest sits facing a woman, holding and gesturing with a plaid shirt as he speaks earnestly. The woman, mostly still and seen from the side, listens attentively. |
| In a wood-paneled office, a man in a tweed jacket and tie sits upright and speaks with a serious, thoughtful expression to someone in a dark suit seen from behind. | Outdoors in front of a brick house, a red-haired woman wearing gardening gloves holds pruning shears and faces the camera, appearing focused as she explains something. | In a store or office setting, a man in a maroon sweater sits facing another person, maintaining steady eye contact with a neutral, slightly focused expression while the other listens from off-camera. | In a dim, bluish environment, a young boy in a red jacket leans against a large marine creature. He opens his eyes and shifts from calm to concerned, showing fear and vulnerability as the creature gently rests a hand on his shoulder in comfort. |
Download
You can download the dataset by cloning the repository from ModelScope:
# Option 1: Using ModelScope. Much faster for users in the Chinese Mainland
pip install modelscope[framework]
modelscope download --dataset leoniuschen/HuMoSet --local_dir ./HuMoSet

# Option 2: Using Git
git lfs install
git clone https://modelscope.cn/datasets/leoniuschen/HuMoSet.git
Dataset Structure:
video/: This folder contains the target video files.reference_image/: This folder stores the corresponding reference image for each video.video_caption.parquet: A metadata file containing the dense descriptions for all videos.
👍 Acknowledgements
Our work builds upon and is greatly inspired by several outstanding open-source projects, including Wan2.1, Phantom, SeedVR, MEMO, Hallo3, OpenHumanVid, OpenS2V-Nexus, ConsisID, Qwen2.5-VL and Whisper. We sincerely thank the authors and contributors of these projects for generously sharing their excellent codes and ideas.
⭐ Citation
If HuMo is helpful, please help to ⭐ the repo.
If you find this project useful for your research, please consider citing our paper.
BibTeX
@misc{chen2025humo,
      title={HuMo: Human-Centric Video Generation via Collaborative Multi-Modal Conditioning},
      author={Liyang Chen and Tianxiang Ma and Jiawei Liu and Bingchuan Li and Zhuowei Chen and Lijie Liu and Xu He and Gen Li and Qian He and Zhiyong Wu},
      year={2025},
      eprint={2509.08519},
      archivePrefix={arXiv},
      primaryClass={cs.CV},
      url={https://arxiv.org/abs/2509.08519},
}
📧 Contact
If you have any comments or questions regarding this open-source project, please open a new issue or contact Liyang Chen and Tianxiang Ma.
Similar repos
Contributors
Languages
Python
98.5%
Shell
1.5%