This is the codebase of the paper "Text2VQL: Teaching a Model Query Language to Open-Source Language Models with ChatGPT".
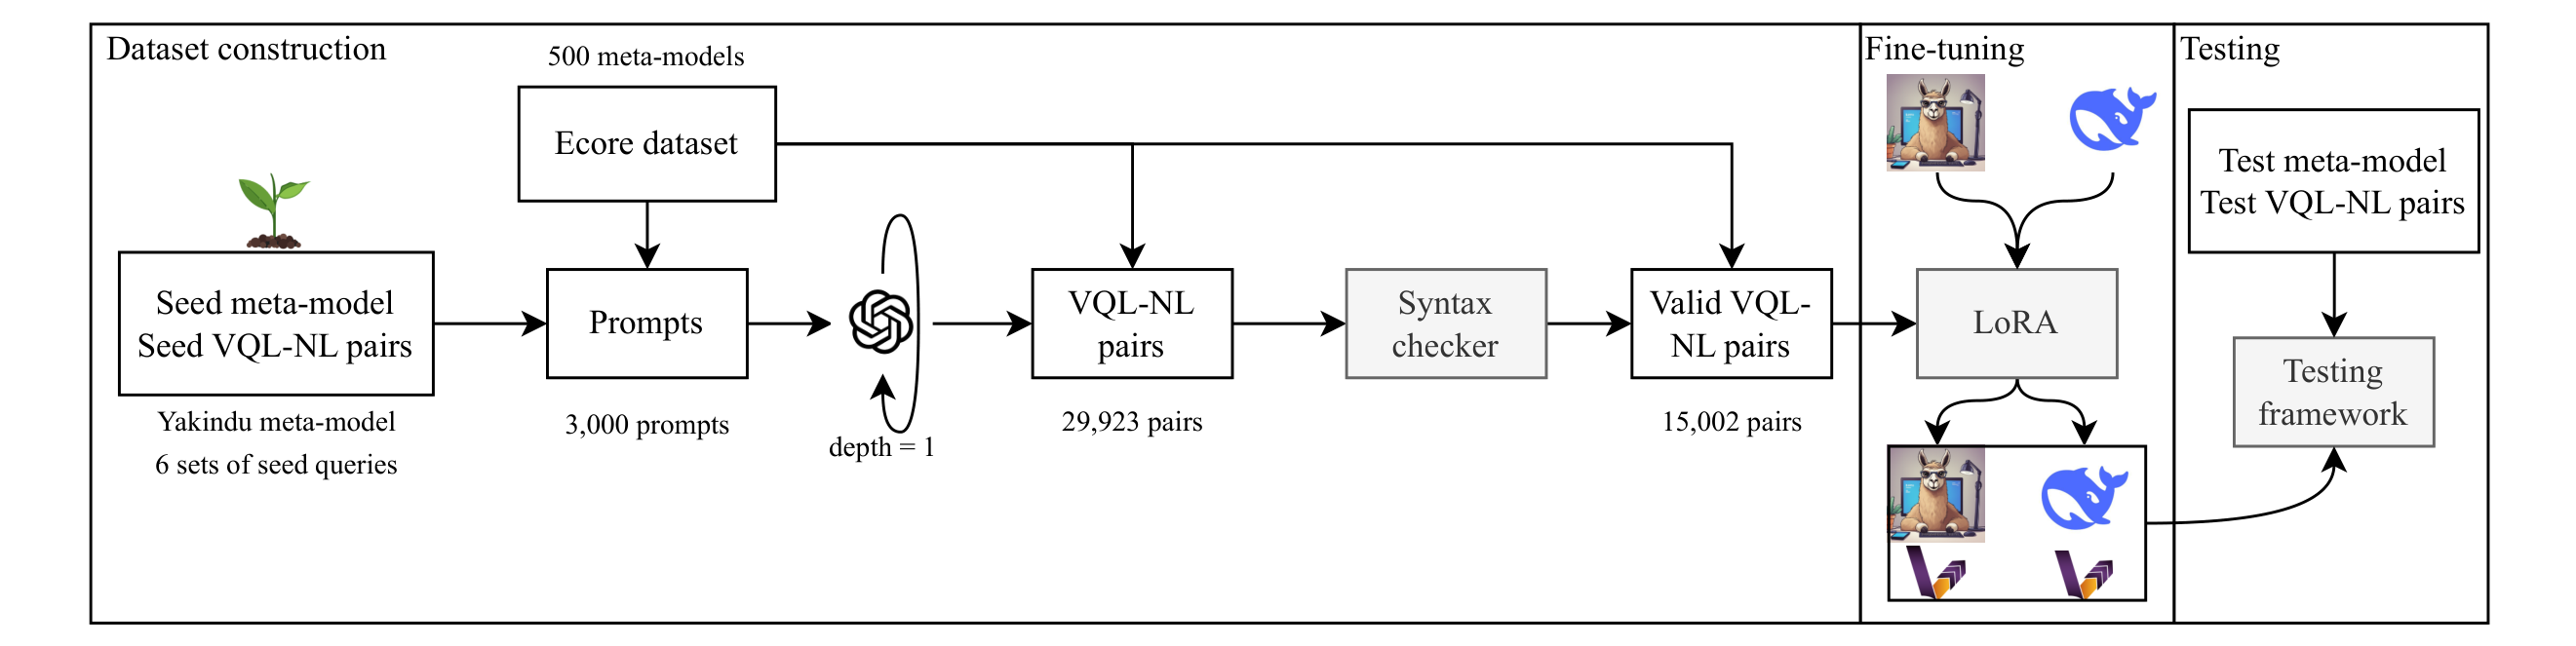
The repository is structured as follows:
dataset_construction contains all the procedures to generate the synthetic dataset of VQL-NL pairs.training folder contains all the scripts to fine-tune open-source LLMs using the synthetic dataset.results contains the results presented in the paper and the scripts needed to execute the testing framework.eclipse-rdp folder contains the docker set-up for the Java scripts.To reproduce the full paper, the order is the following:
eclipse-rdp to build the docker image and run the container.dataset_construction.training.results.For each phase/folder, you have to move the working directory to the associated folder (e.g., cd eclipse-rdp).
Each phase/folder has its own README.md (e.g., eclipse-rdp/README.md, dataset_construction/README.md, etc.) explaining all the requirements and steps.
The results folder contains not only the scripts used to answer all the RQs but also
the data associated to the paper. Therefore, if you start running all the scripts from the very first phase,
you will eventually overwrite all this data.
The hardware and software requirements are the following.
environment.yml specifying the Python version and the required Python libraries. These yml
files will be read by conda to generate a new environment with all the dependencies.The code of this repository is under the MIT LICENSE (LICENSE-CODE). The models and dataset associated to the paper
(uploaded to HuggingFace) are under a research-only LICENSE (LICENSE-MODEL-DATA).
The repository includes a modified copy of refinery under eclipse-rdp/refinery
which is provided under Eclipse Public License - v 2.0.
This is the codebase of the paper "Text2VQL: Teaching a Model Query Language to Open-Source Language Models with ChatGPT".
The repository is structured as follows:
dataset_construction contains all the procedures to generate the synthetic dataset of VQL-NL pairs.training folder contains all the scripts to fine-tune open-source LLMs using the synthetic dataset.results contains the results presented in the paper and the scripts needed to execute the testing framework.eclipse-rdp folder contains the docker set-up for the Java scripts.To reproduce the full paper, the order is the following:
eclipse-rdp to build the docker image and run the container.dataset_construction.training.results.For each phase/folder, you have to move the working directory to the associated folder (e.g., cd eclipse-rdp).
Each phase/folder has its own README.md (e.g., eclipse-rdp/README.md, dataset_construction/README.md, etc.) explaining all the requirements and steps.
The results folder contains not only the scripts used to answer all the RQs but also
the data associated to the paper. Therefore, if you start running all the scripts from the very first phase,
you will eventually overwrite all this data.
The hardware and software requirements are the following.
environment.yml specifying the Python version and the required Python libraries. These yml
files will be read by conda to generate a new environment with all the dependencies.The code of this repository is under the MIT LICENSE (LICENSE-CODE). The models and dataset associated to the paper
(uploaded to HuggingFace) are under a research-only LICENSE (LICENSE-MODEL-DATA).
The repository includes a modified copy of refinery under eclipse-rdp/refinery
which is provided under Eclipse Public License - v 2.0.



