
A curated list and taxonomy of test-time robot learning: RL post-training, policy steering, test-time adaptation and training, test-time scaling, in-context learning, and policy self-improvement.
Python
25
12 commits
updated Sep 30, 2026
README
🤖 Awesome Test-Time Robot Learning


A curated research map of how robot policies improve after pre-training and task-level post-training, using context, test-time computation, deployment experience, or online interaction.
🎯 Scope
We use test-time robot learning as a broad deployment-stage umbrella: a post-trained robot policy encounters a concrete environment and improves within an inference call, an episode, or a sequence of online interactions. The list is centered on manipulation, while including general robot-learning methods when their test-time mechanism transfers directly.
A paper belongs here when it changes deployment context; action sampling, guidance, or selection; candidate generation and verification; a fast state, memory, or representation; or policy-side parameters using deployment data. Routine pre-training, ordinary task fine-tuning with a fixed offline dataset, and planning without a learned robot policy are outside the main scope.
🗺️ Research Map
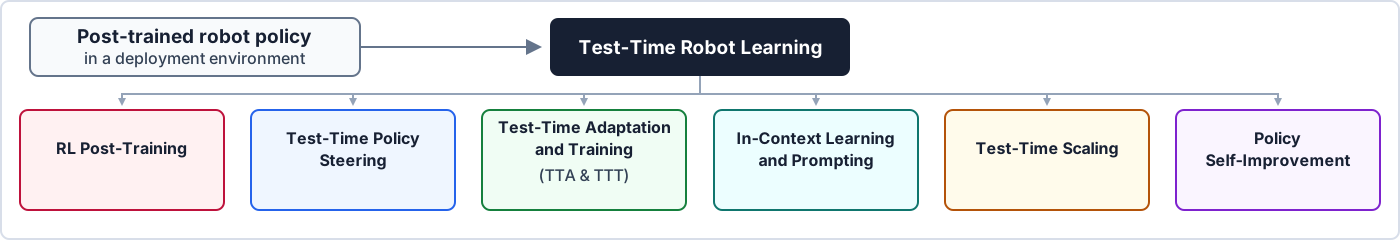
The six lines are organized by their primary deployment-time mechanism and supervision source. Hybrid methods are expected; each paper is assigned to the line that best captures its central contribution.
Compare the six lines
| Line | Core mechanism | Deployment signal | Expected effect | Main limitation |
|---|---|---|---|---|
| RL Post-Training | RL optimization after task-level post-training | Rewards, success labels, interventions, online rollouts | Produces an RL-improved policy, adapter, residual controller, or latent interface | Interaction cost, resets, safety, and reward design |
| Test-Time Policy Steering | Guides sampling, denoising, flow, or action selection at execution | Value functions, VLM rewards, dynamics, constraints | Improves action generation or selection for the current setting | Candidate coverage, guidance quality, and inference latency |
| Test-Time Adaptation and Training (TTA & TTT) | Adapts restricted parameters, state, or representations from deployment data | Self-supervised losses, feedback, predictive objectives, trajectory history | Responds to distribution shift, temporal context, or model mismatch | Objective alignment, stability, and forgetting |
| In-Context Learning and Prompting | Conditions a policy on demonstrations, video, language, or sensorimotor context | Prompt examples supplied at deployment | Uses demonstrations and instructions without a gradient update | Requires a policy trained to interpret the prompt modality |
| Test-Time Scaling | Allocates more inference compute to reasoning, sampling, search, prediction, refinement, or verification | Internal confidence, value, predicted outcomes, self-consistency, or reasoning traces | Improves decisions within the current inference call without collecting new demonstrations | Gains depend on useful candidate diversity or reasoning; latency grows with compute |
| Policy Self-Improvement | Repeats deployment data collection and model updates | Rollouts, failures, corrections, rewards, or model-generated experience | Improves behavior across deployment iterations | Requires safe collection, reliable feedback, resets, and control of policy or model drift |
📚 Contents
- 🧪 RL Post-Training
- 🧭 Test-Time Policy Steering
- 🧠 Test-Time Adaptation and Training (TTA & TTT)
- 🎬 In-Context Learning and Prompting
- 📈 Test-Time Scaling
- 🔄 Policy Self-Improvement
- 🤝 Contributing
Papers are sorted by their first public release date, from oldest to newest. Venue denotes the latest known publication venue; otherwise it is listed as arXiv.
1. 🧪 RL Post-Training
These methods use reinforcement learning after task-level post-training to improve a policy, adapter, residual controller, or latent interface from reward-bearing interaction.
Typical mechanism: Policy-wide or restricted parameter optimization, residual control, latent-space optimization, or online actor-critic updates.
Core advantage: Can improve state-action associations using rewards and interaction beyond behavior cloning.
Main limitation: Interaction cost, resets, safety, reward design, and stability of online optimization.
Papers (15)
2. 🧭 Test-Time Policy Steering
These methods keep the base policy frozen and intervene in its action-generation process by re-ranking candidates, guiding denoising or flow trajectories, optimizing noise, or applying external value and constraint signals.
Typical mechanism: The sampling process, candidate action, noise variable, denoising or flow trajectory, or execution-time controller around a frozen policy.
Core advantage: It is modular and often data-light, making it attractive when the desired behavior already exists in the policy distribution.
Main limitation: It usually cannot repair missing support; guidance quality, repeated sampling, and external models can also add substantial latency.
Papers (12)
| Date | Paper | Venue | Resources | Tags |
|---|---|---|---|---|
| 2024-10-18 | Steering Your Generalists: Improving Robotic Foundation Models via Value Guidance | CoRL 2024 | - | Value Guidance, Action Re-Ranking, Offline RL, Black-Box Steering |
| 2025-06-16 | DynaGuide: Steering Diffusion Policies with Active Dynamic Guidance | NeurIPS 2025 | - | Diffusion Guidance, Latent Dynamics, Model-Based Control |
| 2025-08-08 | Latent Policy Barrier: Learning Robust Visuomotor Policies by Staying In-Distribution | NeurIPS 2025 | - | Diffusion Policy, Latent Dynamics, OOD Detection, Recovery |
| 2025-11-18 | Towards Deploying VLA without Fine-Tuning: Plug-and-Play Inference-Time VLA Policy Steering via Embodied Evolutionary Diffusion | RA-L 2026 | Project | VLA, Evolutionary Diffusion, VLM Reward, Training-Free |
| 2026-02-03 | VLS: Steering Pretrained Robot Policies via Vision-Language Models | arXiv | - | VLM, Reward-Guided Denoising, Diffusion Policy, Flow Matching |
| 2026-03-09 | OmniGuide: Universal Guidance Fields for Enhancing Generalist Robot Policies | arXiv | - | Guidance Field, VLA, Human Demonstrations, Flow Matching |
| 2026-05-12 | Retrieve-then-Steer | arXiv | - | Retrieval, Test-Time Memory, Frozen Policy, Flow Policy |
| 2026-06-09 | Test-Time Gradient Guidance of Flow Policies in Reinforcement Learning | arXiv | Code | Flow Matching, Q-Guidance, Offline RL, Frozen Policy |
| 2026-06-12 | Improving Robotic Generalist Policies via Flow Reversal Steering | arXiv | - | Flow Matching, Flow Inversion, VLM Guidance, Noise-Space Policy |
| 2026-07-02 | Guided Action Flow: Q-Guided Inference for Flow-Matching Vision-Language-Action Policies | arXiv | - | VLA, Flow Matching, Q-Guidance, Real Robot |
| 2026-09-08 | Proxy Policy Steering | CoRL 2026 | - | Proxy Policies, Velocity-Space Guidance, Flow Matching, Frozen Policy |
| 2026-09-18 | Latent Policy Steering: An Efficient and Flexible Framework for Cross-Embodiment Transfer | arXiv | - | Cross-Embodiment, World Model, Latent-Space Search, Frozen Policy |
3. 🧠 Test-Time Adaptation and Training (TTA & TTT)
These methods adapt a policy, representation, or temporal state from deployment data. They include gradient-based self-supervised adaptation, feedback-driven test-time optimization, fast-weight updates, and adaptive memories.
Typical mechanism: Model parameters or restricted adapters, fast weights, adaptive memory, temporal state, or perception and control representations.
Core advantage: Can respond to visual changes, temporal context, feedback, or model mismatch without a dedicated offline adaptation dataset for each deployment setting.
Main limitation: The deployment objective or feedback signal may not track task success, and continual updates can drift, forget, or destabilize control.
Papers (11)
| Date | Paper | Venue | Resources | Tags |
|---|---|---|---|---|
| 2018-03-30 | Learning to Adapt in Dynamic, Real-World Environments Through Meta-Reinforcement Learning | ICLR 2019 | - | Meta-Reinforcement Learning, Model-Based RL, Online Adaptation, Dynamics Model, MPC |
| 2020-07-08 | Self-Supervised Policy Adaptation during Deployment | ICLR 2021 | - | Self-Supervised Learning, Inverse Dynamics, Visual Shift, Policy Adaptation |
| 2023-07-03 | MoVie: Visual Model-Based Policy Adaptation for View Generalization | NeurIPS 2023 | - | Test-Time Adaptation, View Generalization, Model-Based RL, Forward Dynamics |
| 2023-11-22 | Fast-Slow Test-Time Adaptation for Online Vision-and-Language Navigation | ICML 2024 | - | Test-Time Adaptation, Vision-Language Navigation, Entropy Minimization, Online Adaptation |
| 2023-12-24 | ManipLLM: Embodied Multimodal Large Language Model for Object-Centric Robotic Manipulation | CVPR 2024 | - | Test-Time Adaptation, Robot Manipulation, Multimodal LLM, Affordance |
| 2024-02-04 | Fast Peer Adaptation with Context-aware Exploration | ICML 2024 | Project | Online Adaptation, Context-Aware Policy, Multi-Episode History, Active Exploration |
| 2025-05-28 | Communication-Efficient Desire Alignment for Proactive Embodied Human–Agent Interaction | ACL 2026 (Main, Oral) | - | Embodied Human–Agent Interaction, Online Desire Adaptation, Reflection-Based Communication, Persistent Memory |
| 2025-07-13 | Test-Time Adaptation for Online Vision-Language Navigation with Feedback-based Reinforcement Learning | ICML 2025 | - | Test-Time Adaptation, Vision-Language Navigation, Feedback-Based RL, REINFORCE |
| 2026-07-01 | FAR: Failure-Aware Retry for Test-Time Recovery and Continual Policy Improvement | CoRL 2026 | - | Failure Recovery, Preference Adaptation, Continual Policy Improvement, Action Perturbation |
| 2026-07-08 | WAM-TTT: Steering World-Action Models by Watching Human Play at Test Time | arXiv | - | World-Action Model, Human Video, Fast Weights, Test-Time Training |
| 2026-07-16 | RoboTTT: Context Scaling for Robot Policies | arXiv | - | Long Context, Fast Weights, VLA, Human Video |
4. 🎬 In-Context Learning and Prompting
These methods use demonstrations, videos, language, or sensorimotor trajectories in the deployment-time context to specify robot behavior. The direct in-context imitation subset predicts actions from task examples without task-specific parameter updates; the broader prompting subset studies compatible task interfaces such as human video and multimodal instructions.
Typical mechanism: The deployment-time context sequence; policy parameters are usually unchanged.
Core advantage: A user can specify a task, behavior, or constraint through examples without a task-specific gradient update or online reward optimization.
Main limitation: The policy must be trained to read the prompt modality, and reliable prompting does not guarantee the required low-level behavior is in the policy's learned repertoire.
Papers (20)
| Date | Paper | Venue | Resources | Tags |
|---|---|---|---|---|
| 2017-03-21 | One-Shot Imitation Learning | NeurIPS 2017 | - | Meta-Imitation, One-Shot Learning, Demonstration Conditioning, Attention |
| 2021-05-13 | Coarse-to-Fine Imitation Learning: Robot Manipulation from a Single Demonstration | ICRA 2021 | Project | Single Demonstration, Human Video, Visual Servoing, Trajectory Replay |
| 2022-02-04 | BC-Z: Zero-Shot Task Generalization with Robotic Imitation Learning | CoRL 2021 | Project | Human Video Prompt, Task Embedding, Multi-Task Imitation, Real Robot |
| 2022-10-06 | VIMA: General Robot Manipulation with Multimodal Prompts | ICML 2023 | Project | Multimodal Prompt, One-Shot Video Imitation, Cross-Attention, Simulation Benchmark |
| 2023-01-18 | Human-Timescale Adaptation in an Open-Ended Task Space | ICML 2023 | - | Meta-RL, Attention Memory, Embodied 3D, Demonstration Prompt |
| 2024-03-19 | Vid2Robot: End-to-End Video-Conditioned Policy Learning with Cross-Attention Transformers | RSS 2024 | Project | Human Video Prompt, Cross-Embodiment, Cross-Attention, Paired Data |
| 2024-08-28 | In-Context Imitation Learning via Next-Token Prediction (ICRT) | ICRA 2025 | - | Sensorimotor Prompt, Next-Token Prediction, Transformer, In-Context Learning |
| 2024-11-19 | Instant Policy: In-Context Imitation Learning via Graph Diffusion | ICLR 2025 | - | Graph Diffusion, One-Shot Imitation, 3D Representation, Pseudo-Demonstrations |
| 2025-05-27 | Learning Generalizable Robot Policy with Human Demonstration Video as a Prompt | ICRA 2026 | - | Human Video Prompt, Cross-Embodiment, In-Context Learning |
| 2025-05-27 | Hierarchical Instruction-aware Embodied Visual Tracking | FCS 2026 | Project | Language-Conditioned Policy, LLM Spatial Reasoning, RAG Goal Correction, Embodied Visual Tracking |
| 2025-05-28 | Behavior-agnostic Task Inference for Robust Offline In-context Reinforcement Learning | ICML 2025 | Project | Offline In-Context RL, Task Inference, Context Trajectories, Distribution Shift |
| 2025-06-18 | Robust Instant Policy: Leveraging Student's t-Regression Model for Robust In-context Imitation Learning of Robot Manipulation | IROS 2025 | Project | In-Context Imitation, Trajectory Aggregation, Uncertainty, Real Robot |
| 2025-12-08 | See Once, Then Act: VLA Task Learning from One-Shot Video Demonstrations (ViVLA) | arXiv | - | Human Video Prompt, Cross-Embodiment, Latent Action, VLA |
| 2026-04-22 | AdaTracker: Learning Adaptive In-Context Policy for Cross-Embodiment Active Visual Tracking | RA-L 2026 | - | Cross-Embodiment, Active Visual Tracking, In-Context Policy, Zero-Shot Adaptation |
| 2026-06-02 | Instant-Fold: In-Context Imitation Learning for Deformable Object Manipulation | CoRL 2026 | - | Deformable Manipulation, Human Demonstration, Flow Matching, 3D Tokens |
| 2026-06-06 | SynthICL: Scalable In-context Imitation Learning with Synthetic Data | CoRL 2026 | Project | Synthetic Data, RGB-Only, Flow Matching, One-Shot Imitation |
| 2026-06-29 | Behavior Prompting Policy: Demonstrations as Prompts for Manipulation | CoRL 2026 | Project | Sensorimotor Prompt, Robot Demonstration, Behavior Prompting |
| 2026-08-18 | Introducing S1: In-Context Learning for Robotics | Skild AI Blog | - | In-Context Learning, Video Prompt, Cross-Embodiment, Long-Horizon Manipulation |
| 2026-08-19 | GEN-1.5: Embodied Foundation Models are One-Shot Learners | Generalist AI Blog | - | Physical Prompting, Continuous Pretraining, Long Context, Few-Step Adaptation |
| 2026-08-26 | RA-VLA: Retrieval-Augmented VLA for Test-Time Adaptation | arXiv | - | VLA, In-Context Imitation, Behavior-Aligned Retrieval, Flow Matching |
5. 📈 Test-Time Scaling
These methods allocate additional inference compute to reason, sample, search, predict outcomes, refine actions, or verify candidates before execution. Verification is one mechanism within this broader line rather than a separate category.
Typical mechanism: Reasoning depth, candidate count, search depth, world-model rollouts, refinement steps, verifier calls, or an adaptively allocated inference budget.
Core advantage: Can improve a fixed policy at deployment and expose a measurable compute-performance trade-off without collecting new demonstrations.
Main limitation: More computation helps only when reasoning, candidate diversity, predictive models, or selection scores contain useful signal; latency and hardware cost increase with the budget.
Papers (12)
| Date | Paper | Venue | Resources | Tags |
|---|---|---|---|---|
| 2024-07-11 | Robotic Control via Embodied Chain-of-Thought Reasoning | CoRL 2024 | Project / Code | VLA, Embodied Chain-of-Thought, Grounded Reasoning, Intermediate Computation |
| 2025-05-27 | Hume: Introducing System-2 Thinking in Visual-Language-Action Model | arXiv | Project | VLA, Value-Guided Sampling, Best-of-N, Cascaded Denoising |
| 2025-06-21 | RoboMonkey: Scaling Test-Time Sampling and Verification for Vision-Language-Action Models | RSS 2025 OOD Workshop | Project | VLA, Test-Time Sampling, Action Verification, Inference Scaling Law |
| 2025-08-17 | Improving Pre-Trained Vision-Language-Action Policies with Model-Based Search | CoRL 2025 Workshop | - | VLA, MCTS, Model-Based Search, Inference-Time Planning |
| 2025-09-26 | VLA-Reasoner: Empowering Vision-Language-Action Models with Reasoning via Online Monte Carlo Tree Search | ICRA 2026 | Project | VLA, MCTS, World Model, Value-Guided Search |
| 2025-10-07 | Verifier-free Test-Time Sampling for Vision-Language-Action Models | ICLR 2026 | Project / Code | VLA, Verifier-Free Selection, Condition Masking, Best-of-N |
| 2025-10-13 | RoVer: Robot Reward Model as Test-Time Verifier for Vision-Language-Action Model | arXiv | - | VLA, Process Reward Model, Candidate Refinement, Test-Time Verification |
| 2025-12-02 | Steering Vision-Language-Action Models as Anti-Exploration: A Test-Time Scaling Approach | arXiv | - | VLA, Flow Matching, Pseudo-Count Verifier, Best-of-N |
| 2026-02-12 | Scaling Verification Can Be More Effective than Scaling Policy Learning for Vision-Language-Action Alignment | arXiv | - | Test-Time Scaling, Action Verification, VLA Alignment, Best-of-N |
| 2026-04-21 | FASTER: Value-Guided Sampling for Fast RL | arXiv | Project / Code | Diffusion Policy, Value-Guided Sampling, Early Candidate Filtering, Denoising MDP |
| 2026-05-31 | τ0-WM: A Unified Video-Action World Model for Robotic Manipulation | arXiv | Project | World Model, Adaptive Test-Time Compute, Imagined Rollouts, Action Rectification |
| 2026-08-17 | τ0-VLA: a Hierarchical Robot Foundation Model with World-Model-Guided Test-Time Computation | arXiv | Project | Hierarchical VLA, World Model, Test-Time Compute, Subtask Verification |
6. 🔄 Policy Self-Improvement
These methods use deployment rollouts, failures, corrections, or model-generated experience to improve future behavior across successive data-collection and update rounds.
Typical mechanism: The base policy, residual policy, critic, world model, recovery behavior, or data-generation loop between deployment iterations.
Core advantage: Turns autonomous experience and intervention data into better future behavior, reducing dependence on repeated full demonstrations.
Main limitation: Requires reliable rewards or success labels, safe data collection, practical resets, and controls against policy drift or errors in model-generated data.
Papers (8)
| Date | Paper | Venue | Resources | Tags |
|---|---|---|---|---|
| 2023-06-20 | RoboCat: A Self-Improving Generalist Agent for Robotic Manipulation | TMLR 2024 | - | Generalist Policy, Self-Generated Data, Iterative Training, Multi-Embodiment |
| 2025-05-28 | VLM Can Be a Good Assistant: Enhancing Embodied Visual Tracking with Self-Improving Vision-Language Models | IROS 2025 | Project | Embodied Visual Tracking, Failure Recovery, Memory-Augmented Self-Reflection, Iterative Recovery Improvement |
| 2025-09-09 | RaC: Robot Learning for Long-Horizon Tasks by Scaling Recovery and Correction | arXiv | Project | Long-Horizon Manipulation, Human Intervention, Recovery Data, Iterative Imitation Learning |
| 2025-10-30 | Self-Improving Vision-Language-Action Models with Data Generation via Residual RL | ICLR 2026 | Project | VLA, Residual RL, Deployment-Aligned Data, Policy Distillation |
| 2026-02-12 | VLAW: Iterative Co-Improvement of Vision-Language-Action Policy and World Model | arXiv | Project | VLA, World Model, Synthetic Rollouts, Iterative Co-Improvement |
| 2026-03-17 | DreamPlan: Efficient Reinforcement Fine-Tuning of Vision-Language Planners via Video World Models | arXiv | Project | Vision-Language Planner, Video World Model, Synthetic Rollouts, Reinforcement Fine-Tuning |
| 2026-05-06 | When Life Gives You BC, Make Q-functions: Extracting Q-values from Behavior Cloning for On-Robot Reinforcement Learning | arXiv | Project | Offline-to-Online RL, Q-Estimation, Q-Gating, On-Robot Learning |
| 2026-08-21 | Beyond Imitation: Self-Improving Robot Policies via Off-Policy Q-Planning | CoRL 2026 | Project / Code | Frozen BC Policy, Off-Policy Q-Learning, Failure Rollouts, Value-Guided Planning |
🤝 Contributing
Paper additions and corrections are welcome. Please read CONTRIBUTING.md, edit data/papers.json, and run:
python3 scripts/validate_data.py
python3 scripts/build_readme.py --check
You can also use the Add a paper issue template.
🙏 Acknowledgements
The repository structure draws inspiration from community-maintained collections such as Awesome World Models for Robotics, Awesome VLA Post-Training, and Awesome VLA.
📄 License
This repository is released under the MIT License.
Similar repos


Languages
Python
100.0%
A curated list and taxonomy of test-time robot learning: RL post-training, policy steering, test-time adaptation and training, test-time scaling, in-context learning, and policy self-improvement.
Python
25
12 commits
updated Sep 30, 2026
README
🤖 Awesome Test-Time Robot Learning
A curated research map of how robot policies improve after pre-training and task-level post-training, using context, test-time computation, deployment experience, or online interaction.
🎯 Scope
We use test-time robot learning as a broad deployment-stage umbrella: a post-trained robot policy encounters a concrete environment and improves within an inference call, an episode, or a sequence of online interactions. The list is centered on manipulation, while including general robot-learning methods when their test-time mechanism transfers directly.
A paper belongs here when it changes deployment context; action sampling, guidance, or selection; candidate generation and verification; a fast state, memory, or representation; or policy-side parameters using deployment data. Routine pre-training, ordinary task fine-tuning with a fixed offline dataset, and planning without a learned robot policy are outside the main scope.
🗺️ Research Map
The six lines are organized by their primary deployment-time mechanism and supervision source. Hybrid methods are expected; each paper is assigned to the line that best captures its central contribution.
Compare the six lines
| Line | Core mechanism | Deployment signal | Expected effect | Main limitation |
|---|---|---|---|---|
| RL Post-Training | RL optimization after task-level post-training | Rewards, success labels, interventions, online rollouts | Produces an RL-improved policy, adapter, residual controller, or latent interface | Interaction cost, resets, safety, and reward design |
| Test-Time Policy Steering | Guides sampling, denoising, flow, or action selection at execution | Value functions, VLM rewards, dynamics, constraints | Improves action generation or selection for the current setting | Candidate coverage, guidance quality, and inference latency |
| Test-Time Adaptation and Training (TTA & TTT) | Adapts restricted parameters, state, or representations from deployment data | Self-supervised losses, feedback, predictive objectives, trajectory history | Responds to distribution shift, temporal context, or model mismatch | Objective alignment, stability, and forgetting |
| In-Context Learning and Prompting | Conditions a policy on demonstrations, video, language, or sensorimotor context | Prompt examples supplied at deployment | Uses demonstrations and instructions without a gradient update | Requires a policy trained to interpret the prompt modality |
| Test-Time Scaling | Allocates more inference compute to reasoning, sampling, search, prediction, refinement, or verification | Internal confidence, value, predicted outcomes, self-consistency, or reasoning traces | Improves decisions within the current inference call without collecting new demonstrations | Gains depend on useful candidate diversity or reasoning; latency grows with compute |
| Policy Self-Improvement | Repeats deployment data collection and model updates | Rollouts, failures, corrections, rewards, or model-generated experience | Improves behavior across deployment iterations | Requires safe collection, reliable feedback, resets, and control of policy or model drift |
📚 Contents
- 🧪 RL Post-Training
- 🧭 Test-Time Policy Steering
- 🧠 Test-Time Adaptation and Training (TTA & TTT)
- 🎬 In-Context Learning and Prompting
- 📈 Test-Time Scaling
- 🔄 Policy Self-Improvement
- 🤝 Contributing
Papers are sorted by their first public release date, from oldest to newest. Venue denotes the latest known publication venue; otherwise it is listed as arXiv.
1. 🧪 RL Post-Training
These methods use reinforcement learning after task-level post-training to improve a policy, adapter, residual controller, or latent interface from reward-bearing interaction.
Typical mechanism: Policy-wide or restricted parameter optimization, residual control, latent-space optimization, or online actor-critic updates.
Core advantage: Can improve state-action associations using rewards and interaction beyond behavior cloning.
Main limitation: Interaction cost, resets, safety, reward design, and stability of online optimization.
Papers (15)
2. 🧭 Test-Time Policy Steering
These methods keep the base policy frozen and intervene in its action-generation process by re-ranking candidates, guiding denoising or flow trajectories, optimizing noise, or applying external value and constraint signals.
Typical mechanism: The sampling process, candidate action, noise variable, denoising or flow trajectory, or execution-time controller around a frozen policy.
Core advantage: It is modular and often data-light, making it attractive when the desired behavior already exists in the policy distribution.
Main limitation: It usually cannot repair missing support; guidance quality, repeated sampling, and external models can also add substantial latency.
Papers (12)
| Date | Paper | Venue | Resources | Tags |
|---|---|---|---|---|
| 2024-10-18 | Steering Your Generalists: Improving Robotic Foundation Models via Value Guidance | CoRL 2024 | - | Value Guidance, Action Re-Ranking, Offline RL, Black-Box Steering |
| 2025-06-16 | DynaGuide: Steering Diffusion Policies with Active Dynamic Guidance | NeurIPS 2025 | - | Diffusion Guidance, Latent Dynamics, Model-Based Control |
| 2025-08-08 | Latent Policy Barrier: Learning Robust Visuomotor Policies by Staying In-Distribution | NeurIPS 2025 | - | Diffusion Policy, Latent Dynamics, OOD Detection, Recovery |
| 2025-11-18 | Towards Deploying VLA without Fine-Tuning: Plug-and-Play Inference-Time VLA Policy Steering via Embodied Evolutionary Diffusion | RA-L 2026 | Project | VLA, Evolutionary Diffusion, VLM Reward, Training-Free |
| 2026-02-03 | VLS: Steering Pretrained Robot Policies via Vision-Language Models | arXiv | - | VLM, Reward-Guided Denoising, Diffusion Policy, Flow Matching |
| 2026-03-09 | OmniGuide: Universal Guidance Fields for Enhancing Generalist Robot Policies | arXiv | - | Guidance Field, VLA, Human Demonstrations, Flow Matching |
| 2026-05-12 | Retrieve-then-Steer | arXiv | - | Retrieval, Test-Time Memory, Frozen Policy, Flow Policy |
| 2026-06-09 | Test-Time Gradient Guidance of Flow Policies in Reinforcement Learning | arXiv | Code | Flow Matching, Q-Guidance, Offline RL, Frozen Policy |
| 2026-06-12 | Improving Robotic Generalist Policies via Flow Reversal Steering | arXiv | - | Flow Matching, Flow Inversion, VLM Guidance, Noise-Space Policy |
| 2026-07-02 | Guided Action Flow: Q-Guided Inference for Flow-Matching Vision-Language-Action Policies | arXiv | - | VLA, Flow Matching, Q-Guidance, Real Robot |
| 2026-09-08 | Proxy Policy Steering | CoRL 2026 | - | Proxy Policies, Velocity-Space Guidance, Flow Matching, Frozen Policy |
| 2026-09-18 | Latent Policy Steering: An Efficient and Flexible Framework for Cross-Embodiment Transfer | arXiv | - | Cross-Embodiment, World Model, Latent-Space Search, Frozen Policy |
3. 🧠 Test-Time Adaptation and Training (TTA & TTT)
These methods adapt a policy, representation, or temporal state from deployment data. They include gradient-based self-supervised adaptation, feedback-driven test-time optimization, fast-weight updates, and adaptive memories.
Typical mechanism: Model parameters or restricted adapters, fast weights, adaptive memory, temporal state, or perception and control representations.
Core advantage: Can respond to visual changes, temporal context, feedback, or model mismatch without a dedicated offline adaptation dataset for each deployment setting.
Main limitation: The deployment objective or feedback signal may not track task success, and continual updates can drift, forget, or destabilize control.
Papers (11)
| Date | Paper | Venue | Resources | Tags |
|---|---|---|---|---|
| 2018-03-30 | Learning to Adapt in Dynamic, Real-World Environments Through Meta-Reinforcement Learning | ICLR 2019 | - | Meta-Reinforcement Learning, Model-Based RL, Online Adaptation, Dynamics Model, MPC |
| 2020-07-08 | Self-Supervised Policy Adaptation during Deployment | ICLR 2021 | - | Self-Supervised Learning, Inverse Dynamics, Visual Shift, Policy Adaptation |
| 2023-07-03 | MoVie: Visual Model-Based Policy Adaptation for View Generalization | NeurIPS 2023 | - | Test-Time Adaptation, View Generalization, Model-Based RL, Forward Dynamics |
| 2023-11-22 | Fast-Slow Test-Time Adaptation for Online Vision-and-Language Navigation | ICML 2024 | - | Test-Time Adaptation, Vision-Language Navigation, Entropy Minimization, Online Adaptation |
| 2023-12-24 | ManipLLM: Embodied Multimodal Large Language Model for Object-Centric Robotic Manipulation | CVPR 2024 | - | Test-Time Adaptation, Robot Manipulation, Multimodal LLM, Affordance |
| 2024-02-04 | Fast Peer Adaptation with Context-aware Exploration | ICML 2024 | Project | Online Adaptation, Context-Aware Policy, Multi-Episode History, Active Exploration |
| 2025-05-28 | Communication-Efficient Desire Alignment for Proactive Embodied Human–Agent Interaction | ACL 2026 (Main, Oral) | - | Embodied Human–Agent Interaction, Online Desire Adaptation, Reflection-Based Communication, Persistent Memory |
| 2025-07-13 | Test-Time Adaptation for Online Vision-Language Navigation with Feedback-based Reinforcement Learning | ICML 2025 | - | Test-Time Adaptation, Vision-Language Navigation, Feedback-Based RL, REINFORCE |
| 2026-07-01 | FAR: Failure-Aware Retry for Test-Time Recovery and Continual Policy Improvement | CoRL 2026 | - | Failure Recovery, Preference Adaptation, Continual Policy Improvement, Action Perturbation |
| 2026-07-08 | WAM-TTT: Steering World-Action Models by Watching Human Play at Test Time | arXiv | - | World-Action Model, Human Video, Fast Weights, Test-Time Training |
| 2026-07-16 | RoboTTT: Context Scaling for Robot Policies | arXiv | - | Long Context, Fast Weights, VLA, Human Video |
4. 🎬 In-Context Learning and Prompting
These methods use demonstrations, videos, language, or sensorimotor trajectories in the deployment-time context to specify robot behavior. The direct in-context imitation subset predicts actions from task examples without task-specific parameter updates; the broader prompting subset studies compatible task interfaces such as human video and multimodal instructions.
Typical mechanism: The deployment-time context sequence; policy parameters are usually unchanged.
Core advantage: A user can specify a task, behavior, or constraint through examples without a task-specific gradient update or online reward optimization.
Main limitation: The policy must be trained to read the prompt modality, and reliable prompting does not guarantee the required low-level behavior is in the policy's learned repertoire.
Papers (20)
| Date | Paper | Venue | Resources | Tags |
|---|---|---|---|---|
| 2017-03-21 | One-Shot Imitation Learning | NeurIPS 2017 | - | Meta-Imitation, One-Shot Learning, Demonstration Conditioning, Attention |
| 2021-05-13 | Coarse-to-Fine Imitation Learning: Robot Manipulation from a Single Demonstration | ICRA 2021 | Project | Single Demonstration, Human Video, Visual Servoing, Trajectory Replay |
| 2022-02-04 | BC-Z: Zero-Shot Task Generalization with Robotic Imitation Learning | CoRL 2021 | Project | Human Video Prompt, Task Embedding, Multi-Task Imitation, Real Robot |
| 2022-10-06 | VIMA: General Robot Manipulation with Multimodal Prompts | ICML 2023 | Project | Multimodal Prompt, One-Shot Video Imitation, Cross-Attention, Simulation Benchmark |
| 2023-01-18 | Human-Timescale Adaptation in an Open-Ended Task Space | ICML 2023 | - | Meta-RL, Attention Memory, Embodied 3D, Demonstration Prompt |
| 2024-03-19 | Vid2Robot: End-to-End Video-Conditioned Policy Learning with Cross-Attention Transformers | RSS 2024 | Project | Human Video Prompt, Cross-Embodiment, Cross-Attention, Paired Data |
| 2024-08-28 | In-Context Imitation Learning via Next-Token Prediction (ICRT) | ICRA 2025 | - | Sensorimotor Prompt, Next-Token Prediction, Transformer, In-Context Learning |
| 2024-11-19 | Instant Policy: In-Context Imitation Learning via Graph Diffusion | ICLR 2025 | - | Graph Diffusion, One-Shot Imitation, 3D Representation, Pseudo-Demonstrations |
| 2025-05-27 | Learning Generalizable Robot Policy with Human Demonstration Video as a Prompt | ICRA 2026 | - | Human Video Prompt, Cross-Embodiment, In-Context Learning |
| 2025-05-27 | Hierarchical Instruction-aware Embodied Visual Tracking | FCS 2026 | Project | Language-Conditioned Policy, LLM Spatial Reasoning, RAG Goal Correction, Embodied Visual Tracking |
| 2025-05-28 | Behavior-agnostic Task Inference for Robust Offline In-context Reinforcement Learning | ICML 2025 | Project | Offline In-Context RL, Task Inference, Context Trajectories, Distribution Shift |
| 2025-06-18 | Robust Instant Policy: Leveraging Student's t-Regression Model for Robust In-context Imitation Learning of Robot Manipulation | IROS 2025 | Project | In-Context Imitation, Trajectory Aggregation, Uncertainty, Real Robot |
| 2025-12-08 | See Once, Then Act: VLA Task Learning from One-Shot Video Demonstrations (ViVLA) | arXiv | - | Human Video Prompt, Cross-Embodiment, Latent Action, VLA |
| 2026-04-22 | AdaTracker: Learning Adaptive In-Context Policy for Cross-Embodiment Active Visual Tracking | RA-L 2026 | - | Cross-Embodiment, Active Visual Tracking, In-Context Policy, Zero-Shot Adaptation |
| 2026-06-02 | Instant-Fold: In-Context Imitation Learning for Deformable Object Manipulation | CoRL 2026 | - | Deformable Manipulation, Human Demonstration, Flow Matching, 3D Tokens |
| 2026-06-06 | SynthICL: Scalable In-context Imitation Learning with Synthetic Data | CoRL 2026 | Project | Synthetic Data, RGB-Only, Flow Matching, One-Shot Imitation |
| 2026-06-29 | Behavior Prompting Policy: Demonstrations as Prompts for Manipulation | CoRL 2026 | Project | Sensorimotor Prompt, Robot Demonstration, Behavior Prompting |
| 2026-08-18 | Introducing S1: In-Context Learning for Robotics | Skild AI Blog | - | In-Context Learning, Video Prompt, Cross-Embodiment, Long-Horizon Manipulation |
| 2026-08-19 | GEN-1.5: Embodied Foundation Models are One-Shot Learners | Generalist AI Blog | - | Physical Prompting, Continuous Pretraining, Long Context, Few-Step Adaptation |
| 2026-08-26 | RA-VLA: Retrieval-Augmented VLA for Test-Time Adaptation | arXiv | - | VLA, In-Context Imitation, Behavior-Aligned Retrieval, Flow Matching |
5. 📈 Test-Time Scaling
These methods allocate additional inference compute to reason, sample, search, predict outcomes, refine actions, or verify candidates before execution. Verification is one mechanism within this broader line rather than a separate category.
Typical mechanism: Reasoning depth, candidate count, search depth, world-model rollouts, refinement steps, verifier calls, or an adaptively allocated inference budget.
Core advantage: Can improve a fixed policy at deployment and expose a measurable compute-performance trade-off without collecting new demonstrations.
Main limitation: More computation helps only when reasoning, candidate diversity, predictive models, or selection scores contain useful signal; latency and hardware cost increase with the budget.
Papers (12)
| Date | Paper | Venue | Resources | Tags |
|---|---|---|---|---|
| 2024-07-11 | Robotic Control via Embodied Chain-of-Thought Reasoning | CoRL 2024 | Project / Code | VLA, Embodied Chain-of-Thought, Grounded Reasoning, Intermediate Computation |
| 2025-05-27 | Hume: Introducing System-2 Thinking in Visual-Language-Action Model | arXiv | Project | VLA, Value-Guided Sampling, Best-of-N, Cascaded Denoising |
| 2025-06-21 | RoboMonkey: Scaling Test-Time Sampling and Verification for Vision-Language-Action Models | RSS 2025 OOD Workshop | Project | VLA, Test-Time Sampling, Action Verification, Inference Scaling Law |
| 2025-08-17 | Improving Pre-Trained Vision-Language-Action Policies with Model-Based Search | CoRL 2025 Workshop | - | VLA, MCTS, Model-Based Search, Inference-Time Planning |
| 2025-09-26 | VLA-Reasoner: Empowering Vision-Language-Action Models with Reasoning via Online Monte Carlo Tree Search | ICRA 2026 | Project | VLA, MCTS, World Model, Value-Guided Search |
| 2025-10-07 | Verifier-free Test-Time Sampling for Vision-Language-Action Models | ICLR 2026 | Project / Code | VLA, Verifier-Free Selection, Condition Masking, Best-of-N |
| 2025-10-13 | RoVer: Robot Reward Model as Test-Time Verifier for Vision-Language-Action Model | arXiv | - | VLA, Process Reward Model, Candidate Refinement, Test-Time Verification |
| 2025-12-02 | Steering Vision-Language-Action Models as Anti-Exploration: A Test-Time Scaling Approach | arXiv | - | VLA, Flow Matching, Pseudo-Count Verifier, Best-of-N |
| 2026-02-12 | Scaling Verification Can Be More Effective than Scaling Policy Learning for Vision-Language-Action Alignment | arXiv | - | Test-Time Scaling, Action Verification, VLA Alignment, Best-of-N |
| 2026-04-21 | FASTER: Value-Guided Sampling for Fast RL | arXiv | Project / Code | Diffusion Policy, Value-Guided Sampling, Early Candidate Filtering, Denoising MDP |
| 2026-05-31 | τ0-WM: A Unified Video-Action World Model for Robotic Manipulation | arXiv | Project | World Model, Adaptive Test-Time Compute, Imagined Rollouts, Action Rectification |
| 2026-08-17 | τ0-VLA: a Hierarchical Robot Foundation Model with World-Model-Guided Test-Time Computation | arXiv | Project | Hierarchical VLA, World Model, Test-Time Compute, Subtask Verification |
6. 🔄 Policy Self-Improvement
These methods use deployment rollouts, failures, corrections, or model-generated experience to improve future behavior across successive data-collection and update rounds.
Typical mechanism: The base policy, residual policy, critic, world model, recovery behavior, or data-generation loop between deployment iterations.
Core advantage: Turns autonomous experience and intervention data into better future behavior, reducing dependence on repeated full demonstrations.
Main limitation: Requires reliable rewards or success labels, safe data collection, practical resets, and controls against policy drift or errors in model-generated data.
Papers (8)
| Date | Paper | Venue | Resources | Tags |
|---|---|---|---|---|
| 2023-06-20 | RoboCat: A Self-Improving Generalist Agent for Robotic Manipulation | TMLR 2024 | - | Generalist Policy, Self-Generated Data, Iterative Training, Multi-Embodiment |
| 2025-05-28 | VLM Can Be a Good Assistant: Enhancing Embodied Visual Tracking with Self-Improving Vision-Language Models | IROS 2025 | Project | Embodied Visual Tracking, Failure Recovery, Memory-Augmented Self-Reflection, Iterative Recovery Improvement |
| 2025-09-09 | RaC: Robot Learning for Long-Horizon Tasks by Scaling Recovery and Correction | arXiv | Project | Long-Horizon Manipulation, Human Intervention, Recovery Data, Iterative Imitation Learning |
| 2025-10-30 | Self-Improving Vision-Language-Action Models with Data Generation via Residual RL | ICLR 2026 | Project | VLA, Residual RL, Deployment-Aligned Data, Policy Distillation |
| 2026-02-12 | VLAW: Iterative Co-Improvement of Vision-Language-Action Policy and World Model | arXiv | Project | VLA, World Model, Synthetic Rollouts, Iterative Co-Improvement |
| 2026-03-17 | DreamPlan: Efficient Reinforcement Fine-Tuning of Vision-Language Planners via Video World Models | arXiv | Project | Vision-Language Planner, Video World Model, Synthetic Rollouts, Reinforcement Fine-Tuning |
| 2026-05-06 | When Life Gives You BC, Make Q-functions: Extracting Q-values from Behavior Cloning for On-Robot Reinforcement Learning | arXiv | Project | Offline-to-Online RL, Q-Estimation, Q-Gating, On-Robot Learning |
| 2026-08-21 | Beyond Imitation: Self-Improving Robot Policies via Off-Policy Q-Planning | CoRL 2026 | Project / Code | Frozen BC Policy, Off-Policy Q-Learning, Failure Rollouts, Value-Guided Planning |
🤝 Contributing
Paper additions and corrections are welcome. Please read CONTRIBUTING.md, edit data/papers.json, and run:
python3 scripts/validate_data.py
python3 scripts/build_readme.py --check
You can also use the Add a paper issue template.
🙏 Acknowledgements
The repository structure draws inspiration from community-maintained collections such as Awesome World Models for Robotics, Awesome VLA Post-Training, and Awesome VLA.
📄 License
This repository is released under the MIT License.
Similar repos
Languages
Python
100.0%