
README
PixelDiT & PixelDiT2
Pixel-space diffusion transformers for image generation
NVIDIA · University of Rochester
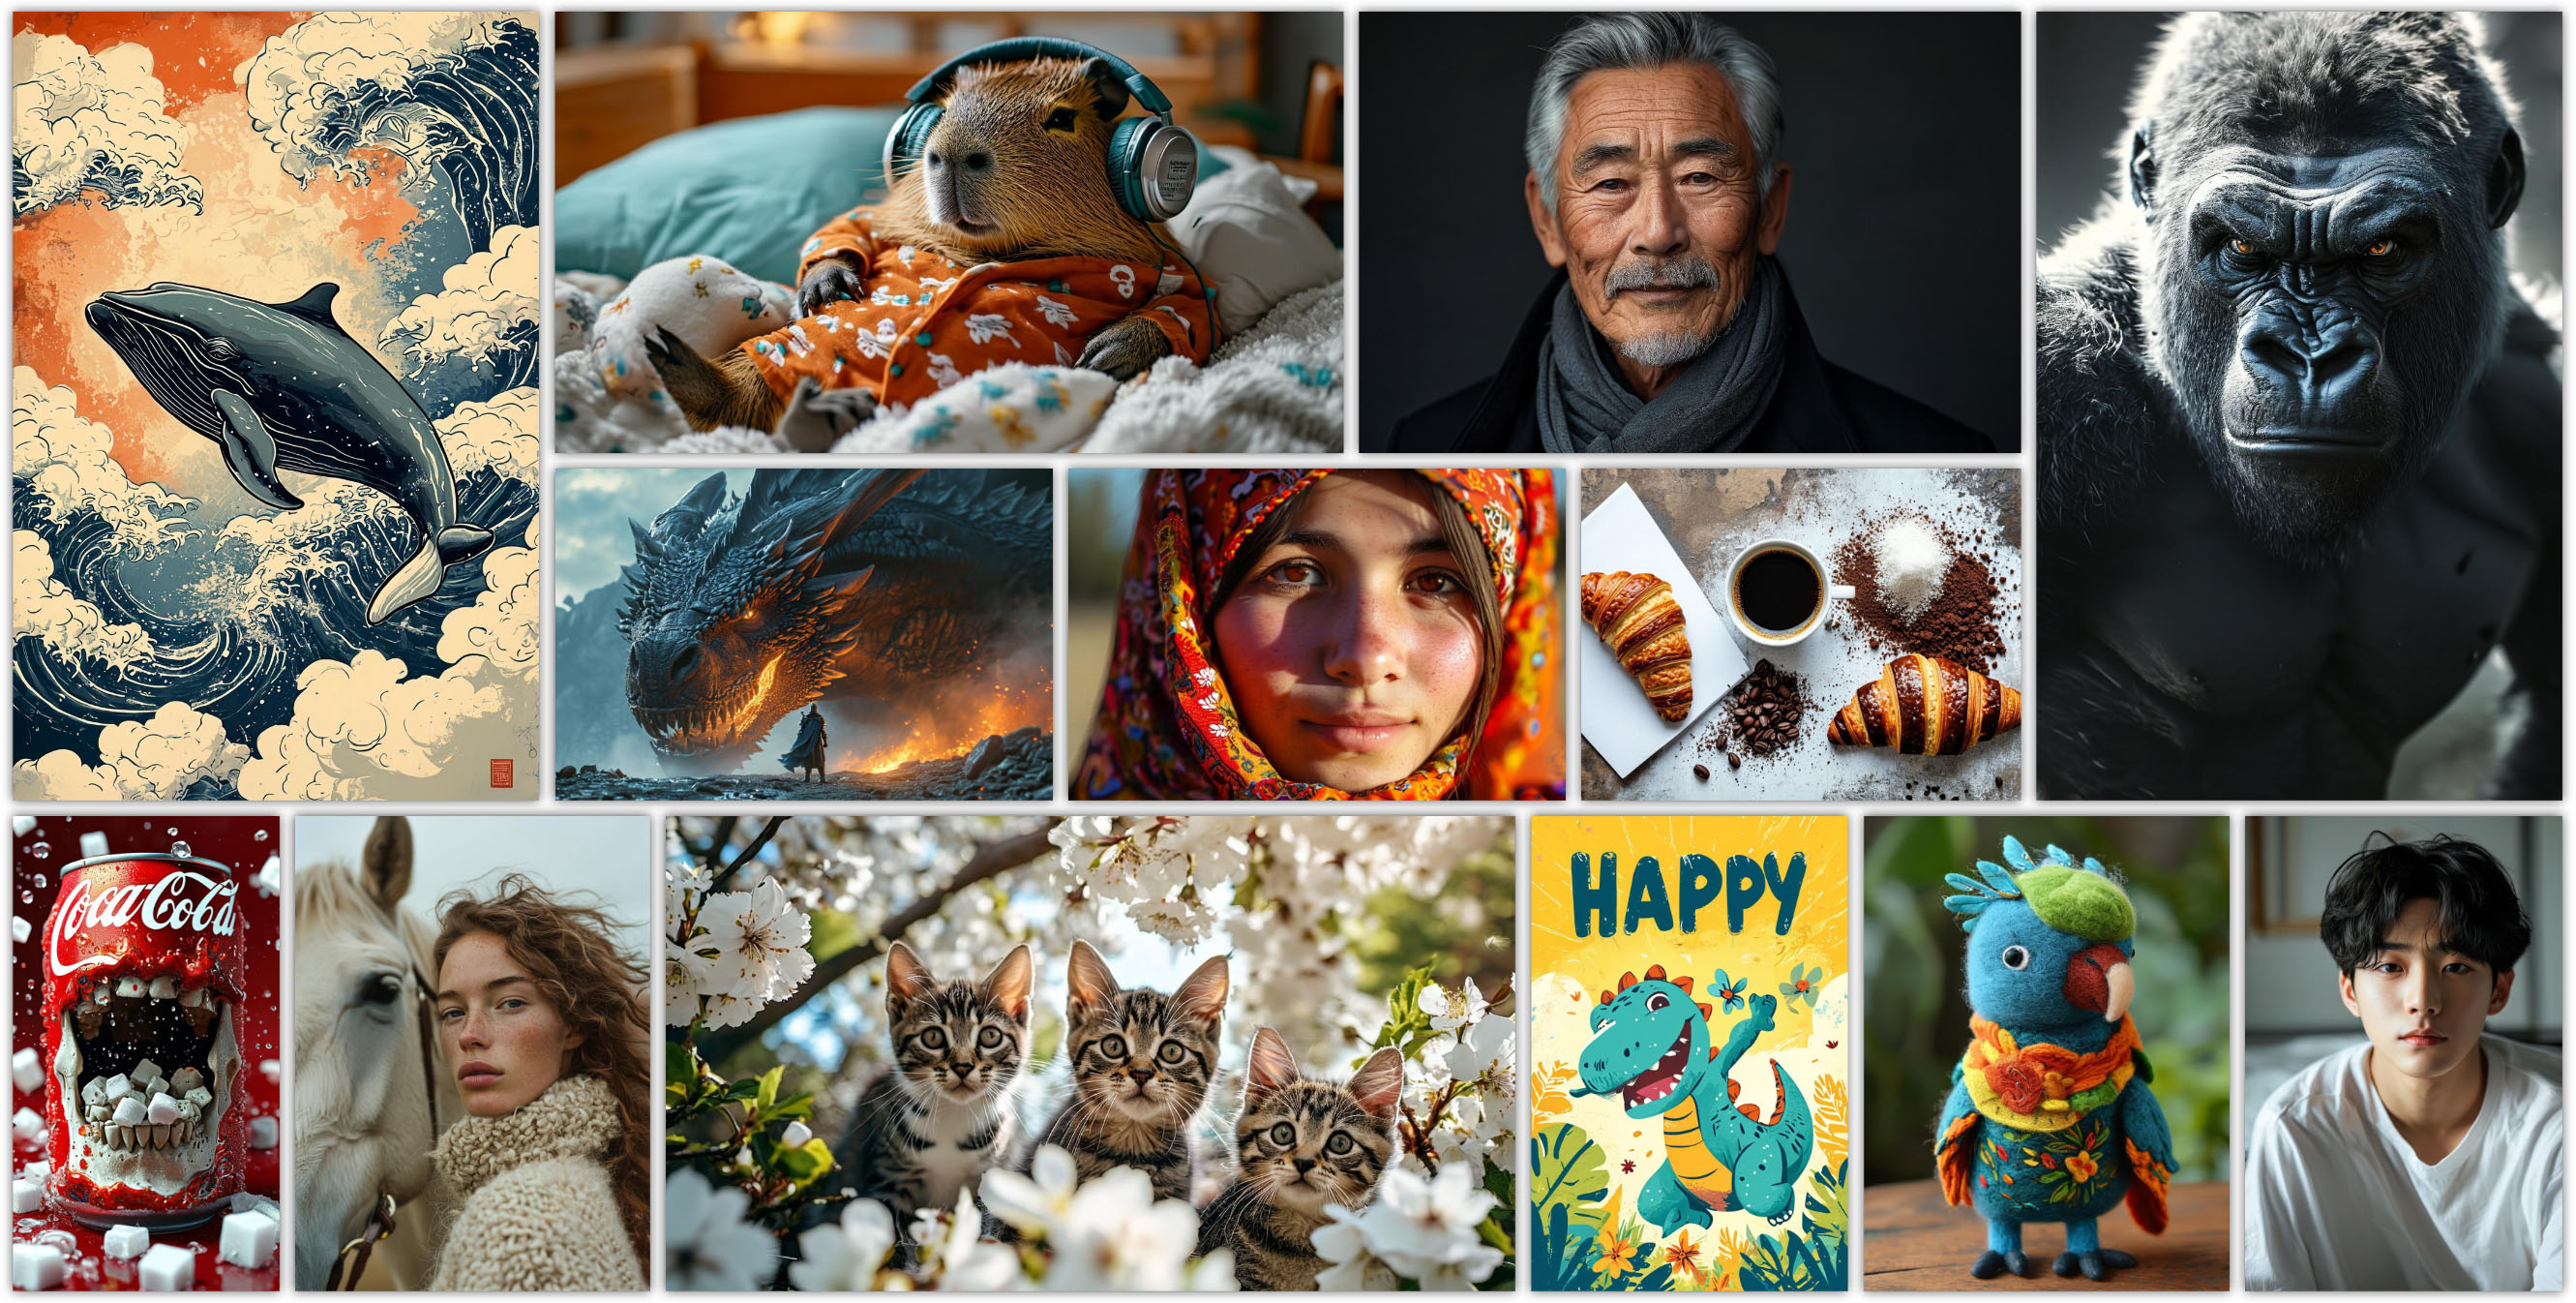
Papers and Resources
| Work | Publication | Resources |
|---|---|---|
| PixelDiT2: Representation-Grounded Pixel Diffusion Transformers | NeurIPS 2026 |    |
| PixelDiT: Pixel Diffusion Transformers for Image Generation | CVPR 2026 Oral |   |
Authors
PixelDiT2
Yongsheng Yu · Wei Xiong · Yichen Sheng · Shiqiu Liu · Jiebo Luo
PixelDiT
Yongsheng Yu · Wei Xiong · Weili Nie · Yichen Sheng · Shiqiu Liu · Jiebo Luo
NVIDIA · University of Rochester. Project lead and main advisor: Wei Xiong.
News
- 2026/09 — PixelDiT2 is accepted to NeurIPS 2026.
- 2026/06 — PixelDiT is a CVPR 2026 Best Paper Finalist.
- 2026/06 — Added post-modulation for PiT blocks to improve training stability.
- 2026/04 — PixelDiT training and inference code, and pretrained models, are released.
- 2026/02 — PixelDiT is accepted to CVPR 2026 Oral.
- 2025/11 — The PixelDiT paper is released.
Models and results
Note: Our models are resumed every 4 hours, using the timestamp as the random seed each time. As a result, the final training outcome may have a slight gap compared to a continuous run without intermediate resumes.
Class-to-image · ImageNet
| Model | Resolution | Epochs | FID ↓ | IS ↑ |
|---|---|---|---|---|
| PixelDiT2-H/16 | 256×256 | 600 | 1.46 | 301.6 |
| PixelDiT2-H/16 | 512×512 | 680 | 1.48 | 295.7 |
| PixelDiT-XL | 256×256 | 320 | 1.61 | — |
| PixelDiT-XL | 512×512 | 850 | 1.81 | — |
Results use 50,000 samples. PixelDiT2 uses Heun with 50 steps; PixelDiT uses FlowDPMSolver with 100 steps. The class-to-image guide lists all checkpoints and the corresponding sampling commands.
Text-to-image · PixelDiT-T2I
| Resolution | GenEval ↑ | DPG-Bench ↑ |
|---|---|---|
| 512×512 | 0.78 | 83.7 |
| 1024×1024 | 0.74 | 83.5 |
See the text-to-image guide for training and inference.
ComfyUI. PixelDiT-T2I is also available in ComfyUI. The Comfy-Org/PixelDiT repository provides repackaged weights (bf16 and mxfp8) and a ready-to-use text-to-image workflow. The repository also hosts PiD.
Quick start
Install the requirements for the model family you want to use, in separate Python environments:
| Model family | Install from the repository root | Setup guide |
|---|---|---|
| PixelDiT2 | python -m pip install -r requirements-pixeldit2.txt | PixelDiT2 environment |
| PixelDiT (C2I / T2I) | python -m pip install -r requirements-pixeldit1.txt | PixelDiT environment |
PixelDiT2 uses Python 3.10 and pinned PyTorch/CUDA dependencies. The PixelDiT
file retains the original dependency specification; requirements.txt remains
its compatibility entrypoint. C2I evaluation also differs: PixelDiT2 uses the
LTH14 torch-fidelity fork with JiT statistics, while PixelDiT uses ADM in a
separate evaluation environment. See the guides for details.
For class-to-image generation, both model families use c2i/main.py.
Choose a matching checkpoint and configuration in the
model list, then follow the shared
inference or
training workflow.
| Model family | Class-to-image configurations | Guide |
|---|---|---|
| PixelDiT2 | pixeldit2_h16_in256.yaml, pixeldit2_h16_in512.yaml | Inference |
| PixelDiT | pix256_xl.yaml, pix512_xl.yaml | Inference |
Repository Structure
├── pixdit_core/      # Shared model definitions
│   ├── pixeldit2_c2i.py   # PixelDiT2  (single-path patch DiT + grounding)
│   ├── grounding.py       # PixelDiT2  frozen DINOv3 encoder and projection P_g
│   ├── pixeldit_c2i.py    # PixelDiT   (dual-level: patch DiT + pixel PiT)
│   └── pixeldit_t2i.py    # PixelDiT   text-to-image
├── tools/            # Checkpoint download, evaluation and GFLOPs computation
├── c2i/              # Class-to-image (PixelDiT and PixelDiT2)
└── t2i/              # Text-to-image
Compute model GFLOPs
Compute GFLOPs
Measure single-forward-pass GFLOPs for any model in this repository (run from project root). For PixelDiT2 the count includes the frozen grounding encoder.
# PixelDiT2 (ImageNet 256x256 and 512x512)
python tools/compute_flops.py --config c2i/configs/pixeldit2_h16_in256.yaml
python tools/compute_flops.py --config c2i/configs/pixeldit2_h16_in512.yaml --height 512 --width 512
# PixelDiT C2I (ImageNet 256x256, default resolution)
python tools/compute_flops.py --config c2i/configs/pix256_xl.yaml
# PixelDiT T2I at 1024x1024
python tools/compute_flops.py --config t2i/configs/PixelDiT_1024px_pixel_diffusion_stage3.yaml --height 1024 --width 1024
Acknowledgements
We would like to thank the authors of PixNerd and SANA for sharing their code. We also thank the SANA team for sharing their text-to-image training data.
Citation
If you find this work useful, please cite:
@inproceedings{yu2026pixeldit2,
      title={PixelDiT2: Representation-Grounded Pixel Diffusion Transformers},
      author={Yongsheng Yu and Wei Xiong and Yichen Sheng and Shiqiu Liu and Jiebo Luo},
      booktitle={Conference on Neural Information Processing Systems (NeurIPS)},
      year={2026},
}

@inproceedings{yu2026pixeldit,
      title={PixelDiT: Pixel Diffusion Transformers for Image Generation},
      author={Yongsheng Yu and Wei Xiong and Weili Nie and Yichen Sheng and Shiqiu Liu and Jiebo Luo},
      booktitle={Proceedings of the IEEE/CVF Conference on Computer Vision and Pattern Recognition (CVPR)},
      year={2026},
}
Significant stargazers

143 followers · starred Apr 2026

136 followers · starred Jun 2026

16 followers · starred Jun 2026
Similar repos



Languages
Python
99.6%
README
PixelDiT & PixelDiT2
Pixel-space diffusion transformers for image generation
NVIDIA · University of Rochester
Papers and Resources
| Work | Publication | Resources |
|---|---|---|
| PixelDiT2: Representation-Grounded Pixel Diffusion Transformers | NeurIPS 2026 | |
| PixelDiT: Pixel Diffusion Transformers for Image Generation | CVPR 2026 Oral | |
Authors
PixelDiT2
Yongsheng Yu · Wei Xiong · Yichen Sheng · Shiqiu Liu · Jiebo Luo
PixelDiT
Yongsheng Yu · Wei Xiong · Weili Nie · Yichen Sheng · Shiqiu Liu · Jiebo Luo
NVIDIA · University of Rochester. Project lead and main advisor: Wei Xiong.
News
- 2026/09 — PixelDiT2 is accepted to NeurIPS 2026.
- 2026/06 — PixelDiT is a CVPR 2026 Best Paper Finalist.
- 2026/06 — Added post-modulation for PiT blocks to improve training stability.
- 2026/04 — PixelDiT training and inference code, and pretrained models, are released.
- 2026/02 — PixelDiT is accepted to CVPR 2026 Oral.
- 2025/11 — The PixelDiT paper is released.
Models and results
Note: Our models are resumed every 4 hours, using the timestamp as the random seed each time. As a result, the final training outcome may have a slight gap compared to a continuous run without intermediate resumes.
Class-to-image · ImageNet
| Model | Resolution | Epochs | FID ↓ | IS ↑ |
|---|---|---|---|---|
| PixelDiT2-H/16 | 256×256 | 600 | 1.46 | 301.6 |
| PixelDiT2-H/16 | 512×512 | 680 | 1.48 | 295.7 |
| PixelDiT-XL | 256×256 | 320 | 1.61 | — |
| PixelDiT-XL | 512×512 | 850 | 1.81 | — |
Results use 50,000 samples. PixelDiT2 uses Heun with 50 steps; PixelDiT uses FlowDPMSolver with 100 steps. The class-to-image guide lists all checkpoints and the corresponding sampling commands.
Text-to-image · PixelDiT-T2I
| Resolution | GenEval ↑ | DPG-Bench ↑ |
|---|---|---|
| 512×512 | 0.78 | 83.7 |
| 1024×1024 | 0.74 | 83.5 |
See the text-to-image guide for training and inference.
ComfyUI. PixelDiT-T2I is also available in ComfyUI. The Comfy-Org/PixelDiT repository provides repackaged weights (bf16 and mxfp8) and a ready-to-use text-to-image workflow. The repository also hosts PiD.
Quick start
Install the requirements for the model family you want to use, in separate Python environments:
| Model family | Install from the repository root | Setup guide |
|---|---|---|
| PixelDiT2 | python -m pip install -r requirements-pixeldit2.txt | PixelDiT2 environment |
| PixelDiT (C2I / T2I) | python -m pip install -r requirements-pixeldit1.txt | PixelDiT environment |
PixelDiT2 uses Python 3.10 and pinned PyTorch/CUDA dependencies. The PixelDiT
file retains the original dependency specification; requirements.txt remains
its compatibility entrypoint. C2I evaluation also differs: PixelDiT2 uses the
LTH14 torch-fidelity fork with JiT statistics, while PixelDiT uses ADM in a
separate evaluation environment. See the guides for details.
For class-to-image generation, both model families use c2i/main.py.
Choose a matching checkpoint and configuration in the
model list, then follow the shared
inference or
training workflow.
| Model family | Class-to-image configurations | Guide |
|---|---|---|
| PixelDiT2 | pixeldit2_h16_in256.yaml, pixeldit2_h16_in512.yaml | Inference |
| PixelDiT | pix256_xl.yaml, pix512_xl.yaml | Inference |
Repository Structure
├── pixdit_core/      # Shared model definitions
│   ├── pixeldit2_c2i.py   # PixelDiT2  (single-path patch DiT + grounding)
│   ├── grounding.py       # PixelDiT2  frozen DINOv3 encoder and projection P_g
│   ├── pixeldit_c2i.py    # PixelDiT   (dual-level: patch DiT + pixel PiT)
│   └── pixeldit_t2i.py    # PixelDiT   text-to-image
├── tools/            # Checkpoint download, evaluation and GFLOPs computation
├── c2i/              # Class-to-image (PixelDiT and PixelDiT2)
└── t2i/              # Text-to-image
Compute model GFLOPs
Compute GFLOPs
Measure single-forward-pass GFLOPs for any model in this repository (run from project root). For PixelDiT2 the count includes the frozen grounding encoder.
# PixelDiT2 (ImageNet 256x256 and 512x512)
python tools/compute_flops.py --config c2i/configs/pixeldit2_h16_in256.yaml
python tools/compute_flops.py --config c2i/configs/pixeldit2_h16_in512.yaml --height 512 --width 512
# PixelDiT C2I (ImageNet 256x256, default resolution)
python tools/compute_flops.py --config c2i/configs/pix256_xl.yaml
# PixelDiT T2I at 1024x1024
python tools/compute_flops.py --config t2i/configs/PixelDiT_1024px_pixel_diffusion_stage3.yaml --height 1024 --width 1024
Acknowledgements
We would like to thank the authors of PixNerd and SANA for sharing their code. We also thank the SANA team for sharing their text-to-image training data.
Citation
If you find this work useful, please cite:
@inproceedings{yu2026pixeldit2,
      title={PixelDiT2: Representation-Grounded Pixel Diffusion Transformers},
      author={Yongsheng Yu and Wei Xiong and Yichen Sheng and Shiqiu Liu and Jiebo Luo},
      booktitle={Conference on Neural Information Processing Systems (NeurIPS)},
      year={2026},
}

@inproceedings{yu2026pixeldit,
      title={PixelDiT: Pixel Diffusion Transformers for Image Generation},
      author={Yongsheng Yu and Wei Xiong and Weili Nie and Yichen Sheng and Shiqiu Liu and Jiebo Luo},
      booktitle={Proceedings of the IEEE/CVF Conference on Computer Vision and Pattern Recognition (CVPR)},
      year={2026},
}
Similar repos
Significant stargazers
143 followers · starred Apr 2026
136 followers · starred Jun 2026
16 followers · starred Jun 2026
Languages
Python
99.6%