MoBA: Mixture of Block Attention for Long-Context LLMs
Python
2,191
2 commits
updated Apr 3, 2025

🚀 Introducing MoBA --- Mixture of Block Attention
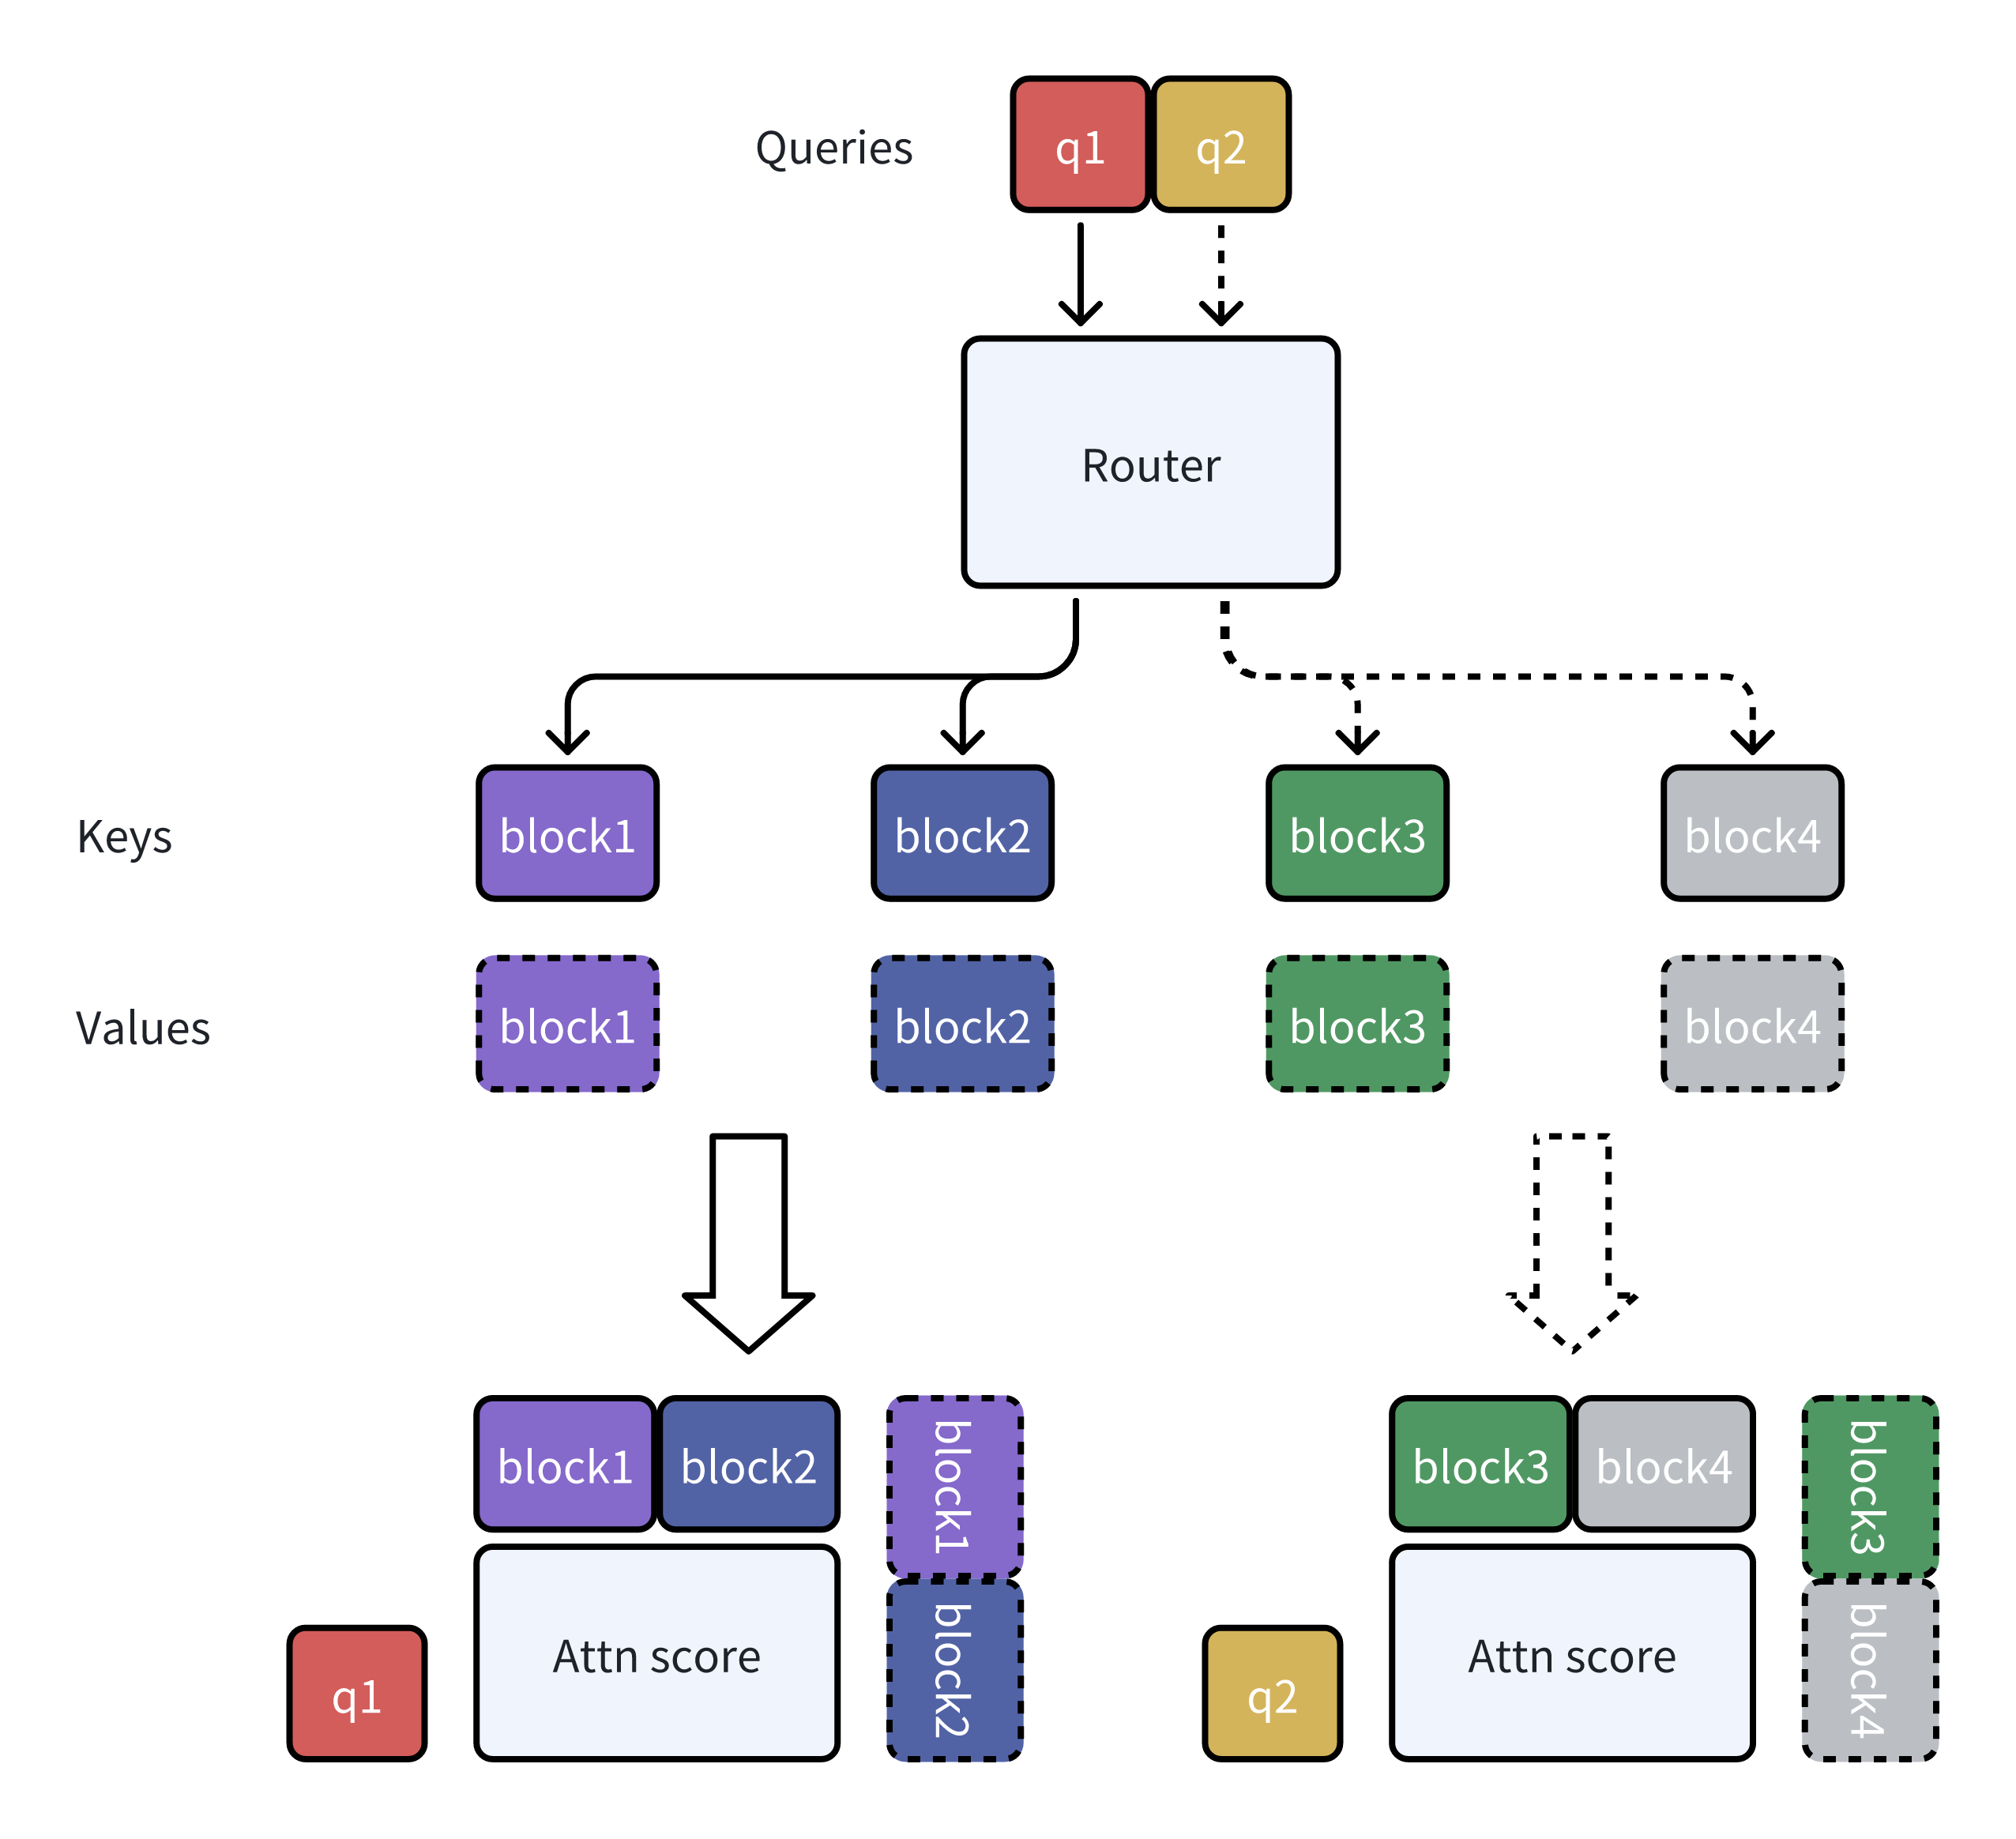
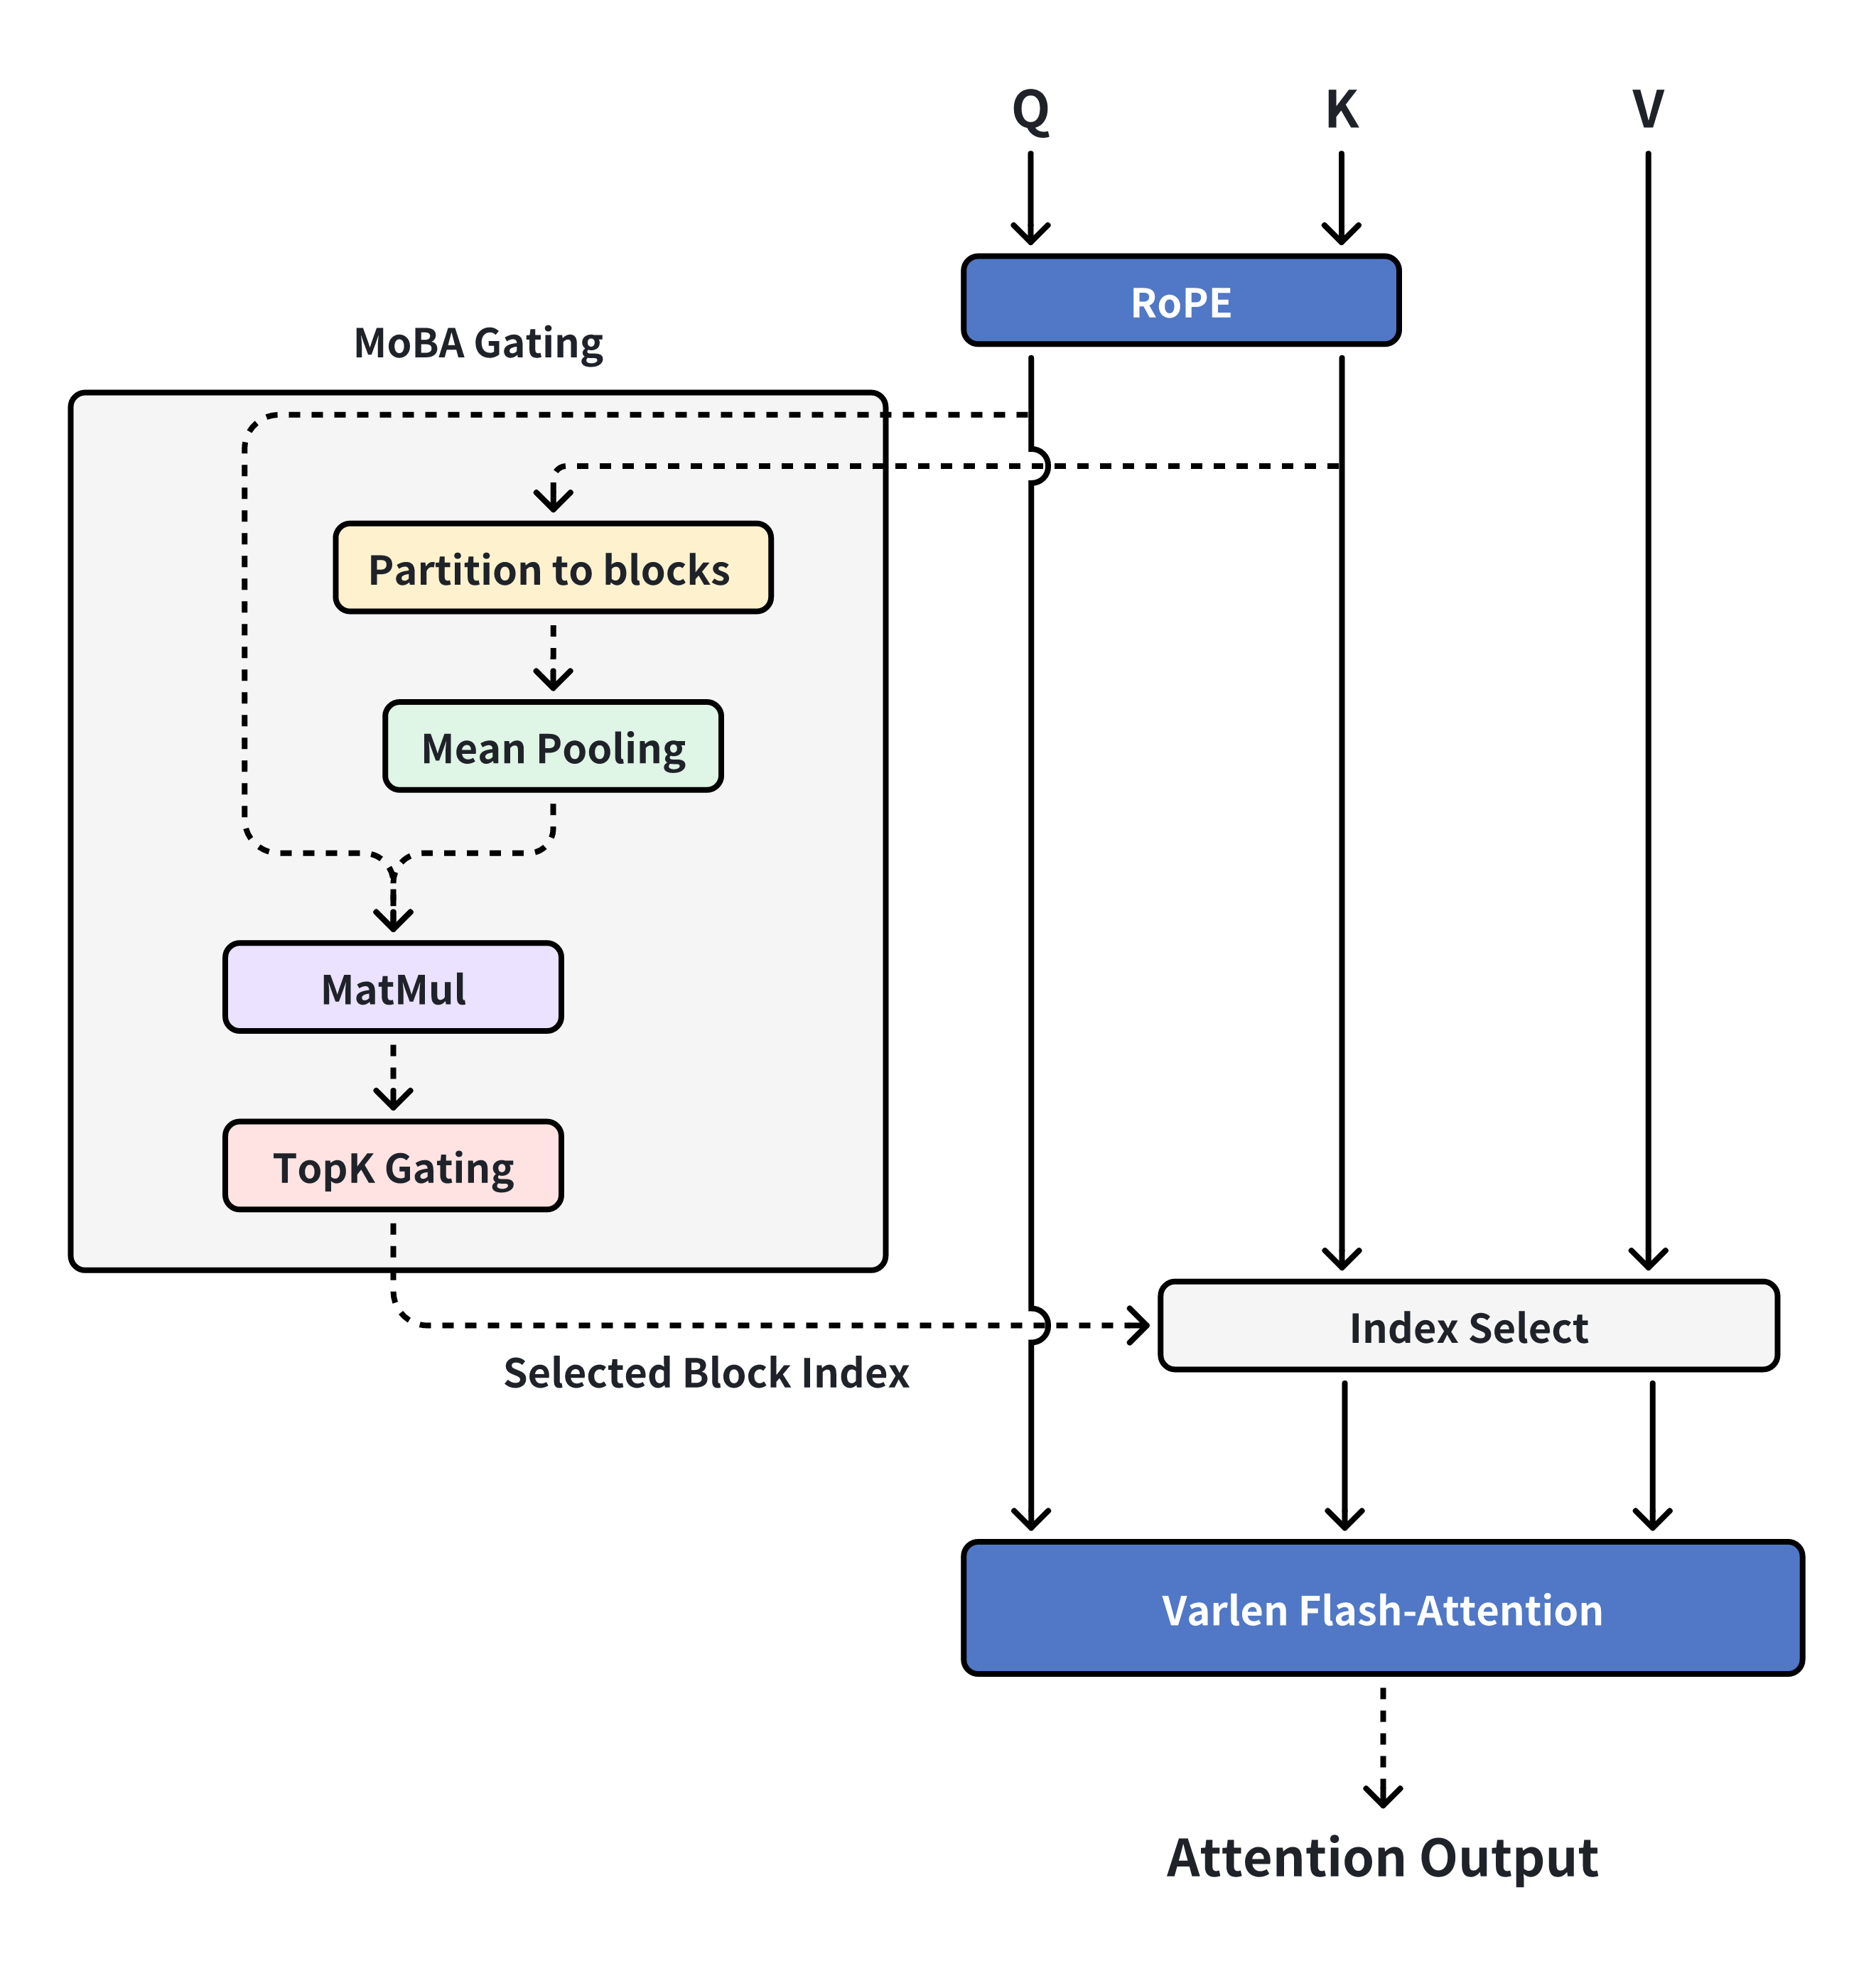
Note: MoBA requires continue training of existing models to achieve its acceleration benefits. It is not a drop-in sparse attention solution that can be directly applied to pretrained models without additional training.
Scaling the effective context length is essential for advancing large language models (LLMs) toward artificial general intelligence (AGI). However, the quadratic increase in computational complexity inherent in traditional attention mechanisms presents a prohibitive overhead. Existing approaches either impose strongly biased structures, such as sink or window attention which are task-specific, or radically modify the attention mechanism into linear approximations, whose performance in complex reasoning tasks remains inadequately explored.
In this work, we propose a solution that adheres to the “less structure” principle, allowing the model to autonomously determine where to attend, rather than introducing predefined biases. We introduce Mixture of Block Attention (MoBA), an innovative approach that applies the principles of Mixture of Experts (MoE) to the attention mechanism. This novel architecture demonstrates superior performance on long-context tasks while offering a key advantage: the ability to seamlessly transition between full and sparse attention, enhancing efficiency without the risk of compromising performance. MoBA has already been deployed to support Kimi’s long-context requests and demonstrates significant advancements in efficient attention computation for LLMs.
Our code is available at MoonshotAI/MoBA.
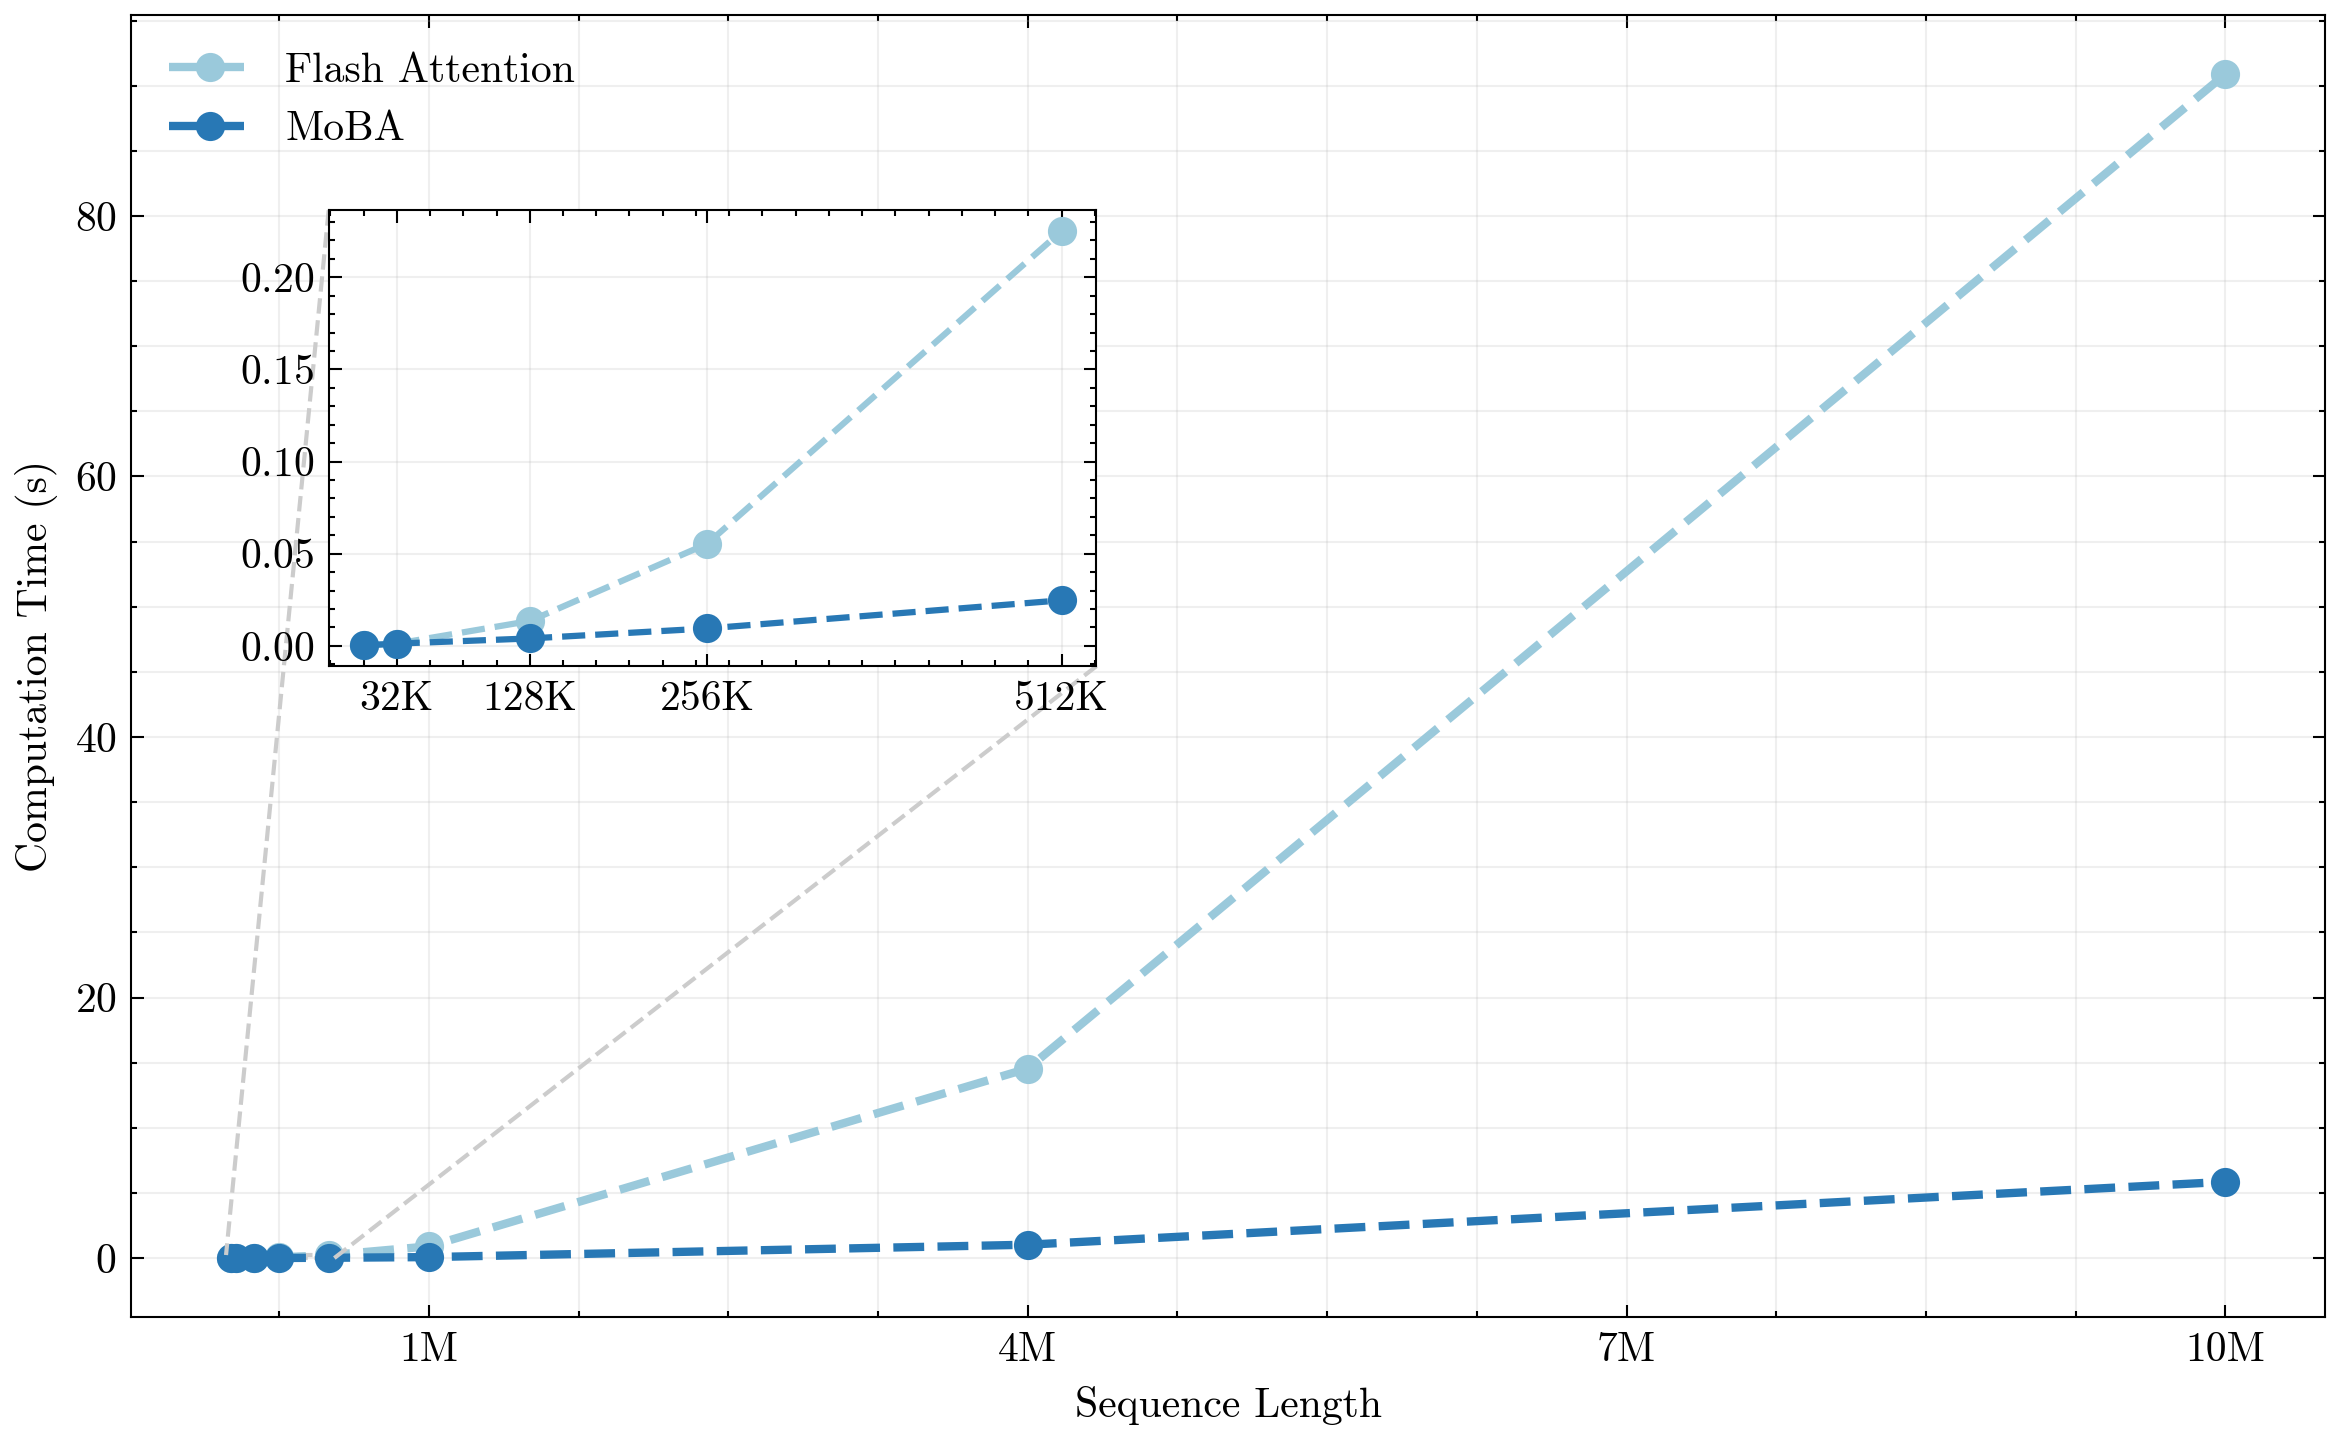
Note that current kernel implementations rely on flash-attn==2.6.3 and torch >= 2.1.0
conda create -n moba python=3.10
conda activate moba
pip install .
We provide a transformers-friendly implementation for MoBA.
Feel free to choose attention backends by --attn between moba and moba_naive.
python3 examples/llama.py --model meta-llama/Llama-3.1-8B --attn moba
pytest tests/test_moba_attn.py
If you find MoBA is useful or want to use in your projects, please kindly cite our paper:
@article{lu2025mobamixtureblockattention,
  author = {Enzhe Lu and Zhejun Jiang and Jingyuan Liu and Yulun Du and Tao Jiang and Chao Hong and Shaowei Liu and Weiran He and Enming Yuan and Yuzhi Wang and Zhiqi Huang and Huan Yuan and Suting Xu and Xinran Xu and Guokun Lai and Yanru Chen and Huabin Zheng and Junjie Yan and Jianlin Su and Yuxin Wu and Yutao Zhang and Zhilin Yang and Xinyu Zhou and Mingxing Zhang and Jiezhong Qiu},
  title = {MoBA: Mixture of Block Attention for Long-Context LLMs},
  journal={arXiv preprint arXiv:2502.13189},
  year={2025}
}
(top 24 of 30)
99 followers · starred Feb 2025
946 followers · starred Feb 2025
3,385 followers · starred Feb 2025
151 followers · starred Mar 2025
MoBA: Mixture of Block Attention for Long-Context LLMs
Python
2,191
2 commits
updated Apr 3, 2025
🚀 Introducing MoBA --- Mixture of Block Attention
Note: MoBA requires continue training of existing models to achieve its acceleration benefits. It is not a drop-in sparse attention solution that can be directly applied to pretrained models without additional training.
Scaling the effective context length is essential for advancing large language models (LLMs) toward artificial general intelligence (AGI). However, the quadratic increase in computational complexity inherent in traditional attention mechanisms presents a prohibitive overhead. Existing approaches either impose strongly biased structures, such as sink or window attention which are task-specific, or radically modify the attention mechanism into linear approximations, whose performance in complex reasoning tasks remains inadequately explored.
In this work, we propose a solution that adheres to the “less structure” principle, allowing the model to autonomously determine where to attend, rather than introducing predefined biases. We introduce Mixture of Block Attention (MoBA), an innovative approach that applies the principles of Mixture of Experts (MoE) to the attention mechanism. This novel architecture demonstrates superior performance on long-context tasks while offering a key advantage: the ability to seamlessly transition between full and sparse attention, enhancing efficiency without the risk of compromising performance. MoBA has already been deployed to support Kimi’s long-context requests and demonstrates significant advancements in efficient attention computation for LLMs.
Our code is available at MoonshotAI/MoBA.
Note that current kernel implementations rely on flash-attn==2.6.3 and torch >= 2.1.0
conda create -n moba python=3.10
conda activate moba
pip install .
We provide a transformers-friendly implementation for MoBA.
Feel free to choose attention backends by --attn between moba and moba_naive.
python3 examples/llama.py --model meta-llama/Llama-3.1-8B --attn moba
pytest tests/test_moba_attn.py
If you find MoBA is useful or want to use in your projects, please kindly cite our paper:
@article{lu2025mobamixtureblockattention,
  author = {Enzhe Lu and Zhejun Jiang and Jingyuan Liu and Yulun Du and Tao Jiang and Chao Hong and Shaowei Liu and Weiran He and Enming Yuan and Yuzhi Wang and Zhiqi Huang and Huan Yuan and Suting Xu and Xinran Xu and Guokun Lai and Yanru Chen and Huabin Zheng and Junjie Yan and Jianlin Su and Yuxin Wu and Yutao Zhang and Zhilin Yang and Xinyu Zhou and Mingxing Zhang and Jiezhong Qiu},
  title = {MoBA: Mixture of Block Attention for Long-Context LLMs},
  journal={arXiv preprint arXiv:2502.13189},
  year={2025}
}
(top 24 of 30)
99 followers · starred Feb 2025
946 followers · starred Feb 2025
3,385 followers · starred Feb 2025
151 followers · starred Mar 2025


 Full Report