
Persist and reuse KV Cache to speedup your LLM.
See the codeREADME

Unified KV Cache management for LLM inference
Documentation · Quickstart · Website · 中文

What is UCM?
Unified Cache Manager (UCM) is a unified KV Cache layer between inference engines and storage. It manages cache reuse, placement, and movement so that compatible requests and inference instances can reuse existing computation.
Agent workflows, multi-turn conversations, and multimodal applications often revisit the same context. UCM makes reusable KV Cache available beyond an individual inference process and extends cache capacity through external storage. This helps reduce repeated computation and the pressure on accelerator memory.
Engine adapters, cache mechanisms, and storage backends can evolve independently through pluggable interfaces.
Architecture
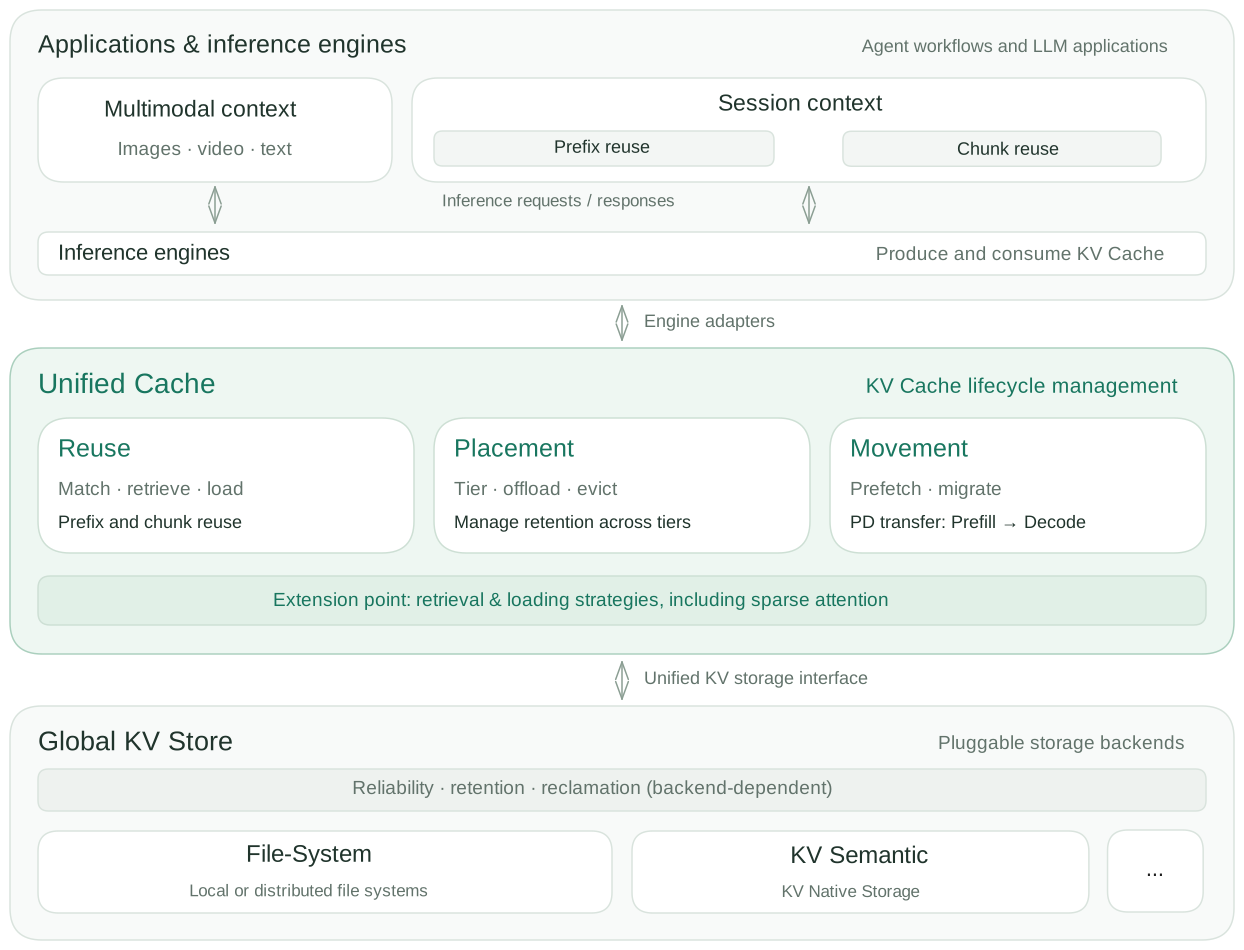
- Applications and inference engines produce and consume KV Cache. Reuse patterns include multimodal context, shared prefixes, and cached chunks used by mechanisms such as KV Bridge.
- Unified Cache manages the cache's usage lifecycle: what to reuse, where to retain it, and when to move it. Prefill/decode (PD) transfer is one form of cache movement. Pluggable retrieval and loading strategies also support sparse attention.
- Global KV Store provides a common storage abstraction over file systems, memory pools, and other backends. Store implementations handle retention, reclamation, and reliability according to their capabilities.
Feature availability and storage guarantees depend on the selected engine, model, platform, and backend; see supported configurations.
Getting Started
- Check the support matrix for a compatible configuration.
- Follow the Quickstart to select installation artifacts, configure storage, and run an engine with UCM.
- Use the operations guide to verify cache reuse and inspect runtime behavior.
Installation commands, image tags, engine versions, and configuration examples are maintained in the documentation. For deployment problems, see troubleshooting.
Contributing & Community
Contributions to engine adapters, storage backends, cache mechanisms, tests, and documentation are welcome.
- Start with the Contributing Guide.
- Add a backend with Extending Store.
- Report bugs and propose features through GitHub Issues.
License
UCM is licensed under the MIT license with additional conditions. Read LICENSE for the full terms.


Similar repos


Languages
C++
56.7%
Python
38.7%
CMake
1.9%
Persist and reuse KV Cache to speedup your LLM.
See the codeREADME
Unified KV Cache management for LLM inference
Documentation · Quickstart · Website · 中文
What is UCM?
Unified Cache Manager (UCM) is a unified KV Cache layer between inference engines and storage. It manages cache reuse, placement, and movement so that compatible requests and inference instances can reuse existing computation.
Agent workflows, multi-turn conversations, and multimodal applications often revisit the same context. UCM makes reusable KV Cache available beyond an individual inference process and extends cache capacity through external storage. This helps reduce repeated computation and the pressure on accelerator memory.
Engine adapters, cache mechanisms, and storage backends can evolve independently through pluggable interfaces.
Architecture
- Applications and inference engines produce and consume KV Cache. Reuse patterns include multimodal context, shared prefixes, and cached chunks used by mechanisms such as KV Bridge.
- Unified Cache manages the cache's usage lifecycle: what to reuse, where to retain it, and when to move it. Prefill/decode (PD) transfer is one form of cache movement. Pluggable retrieval and loading strategies also support sparse attention.
- Global KV Store provides a common storage abstraction over file systems, memory pools, and other backends. Store implementations handle retention, reclamation, and reliability according to their capabilities.
Feature availability and storage guarantees depend on the selected engine, model, platform, and backend; see supported configurations.
Getting Started
- Check the support matrix for a compatible configuration.
- Follow the Quickstart to select installation artifacts, configure storage, and run an engine with UCM.
- Use the operations guide to verify cache reuse and inspect runtime behavior.
Installation commands, image tags, engine versions, and configuration examples are maintained in the documentation. For deployment problems, see troubleshooting.
Contributing & Community
Contributions to engine adapters, storage backends, cache mechanisms, tests, and documentation are welcome.
- Start with the Contributing Guide.
- Add a backend with Extending Store.
- Report bugs and propose features through GitHub Issues.
License
UCM is licensed under the MIT license with additional conditions. Read LICENSE for the full terms.
Similar repos
Significant stargazers
Languages
C++
56.7%
Python
38.7%
CMake
1.9%