
README
TemMed-Bench: Evaluating Temporal Medical Image Reasoning in Vision-Language Models
🌐 Homepage | 🤗 Dataset | 📖 Paper
✨ News
- 🔥 Evaluation template code is released.
- 🔥 Code for loading TemMed-Bench is released.
🚀 Intro
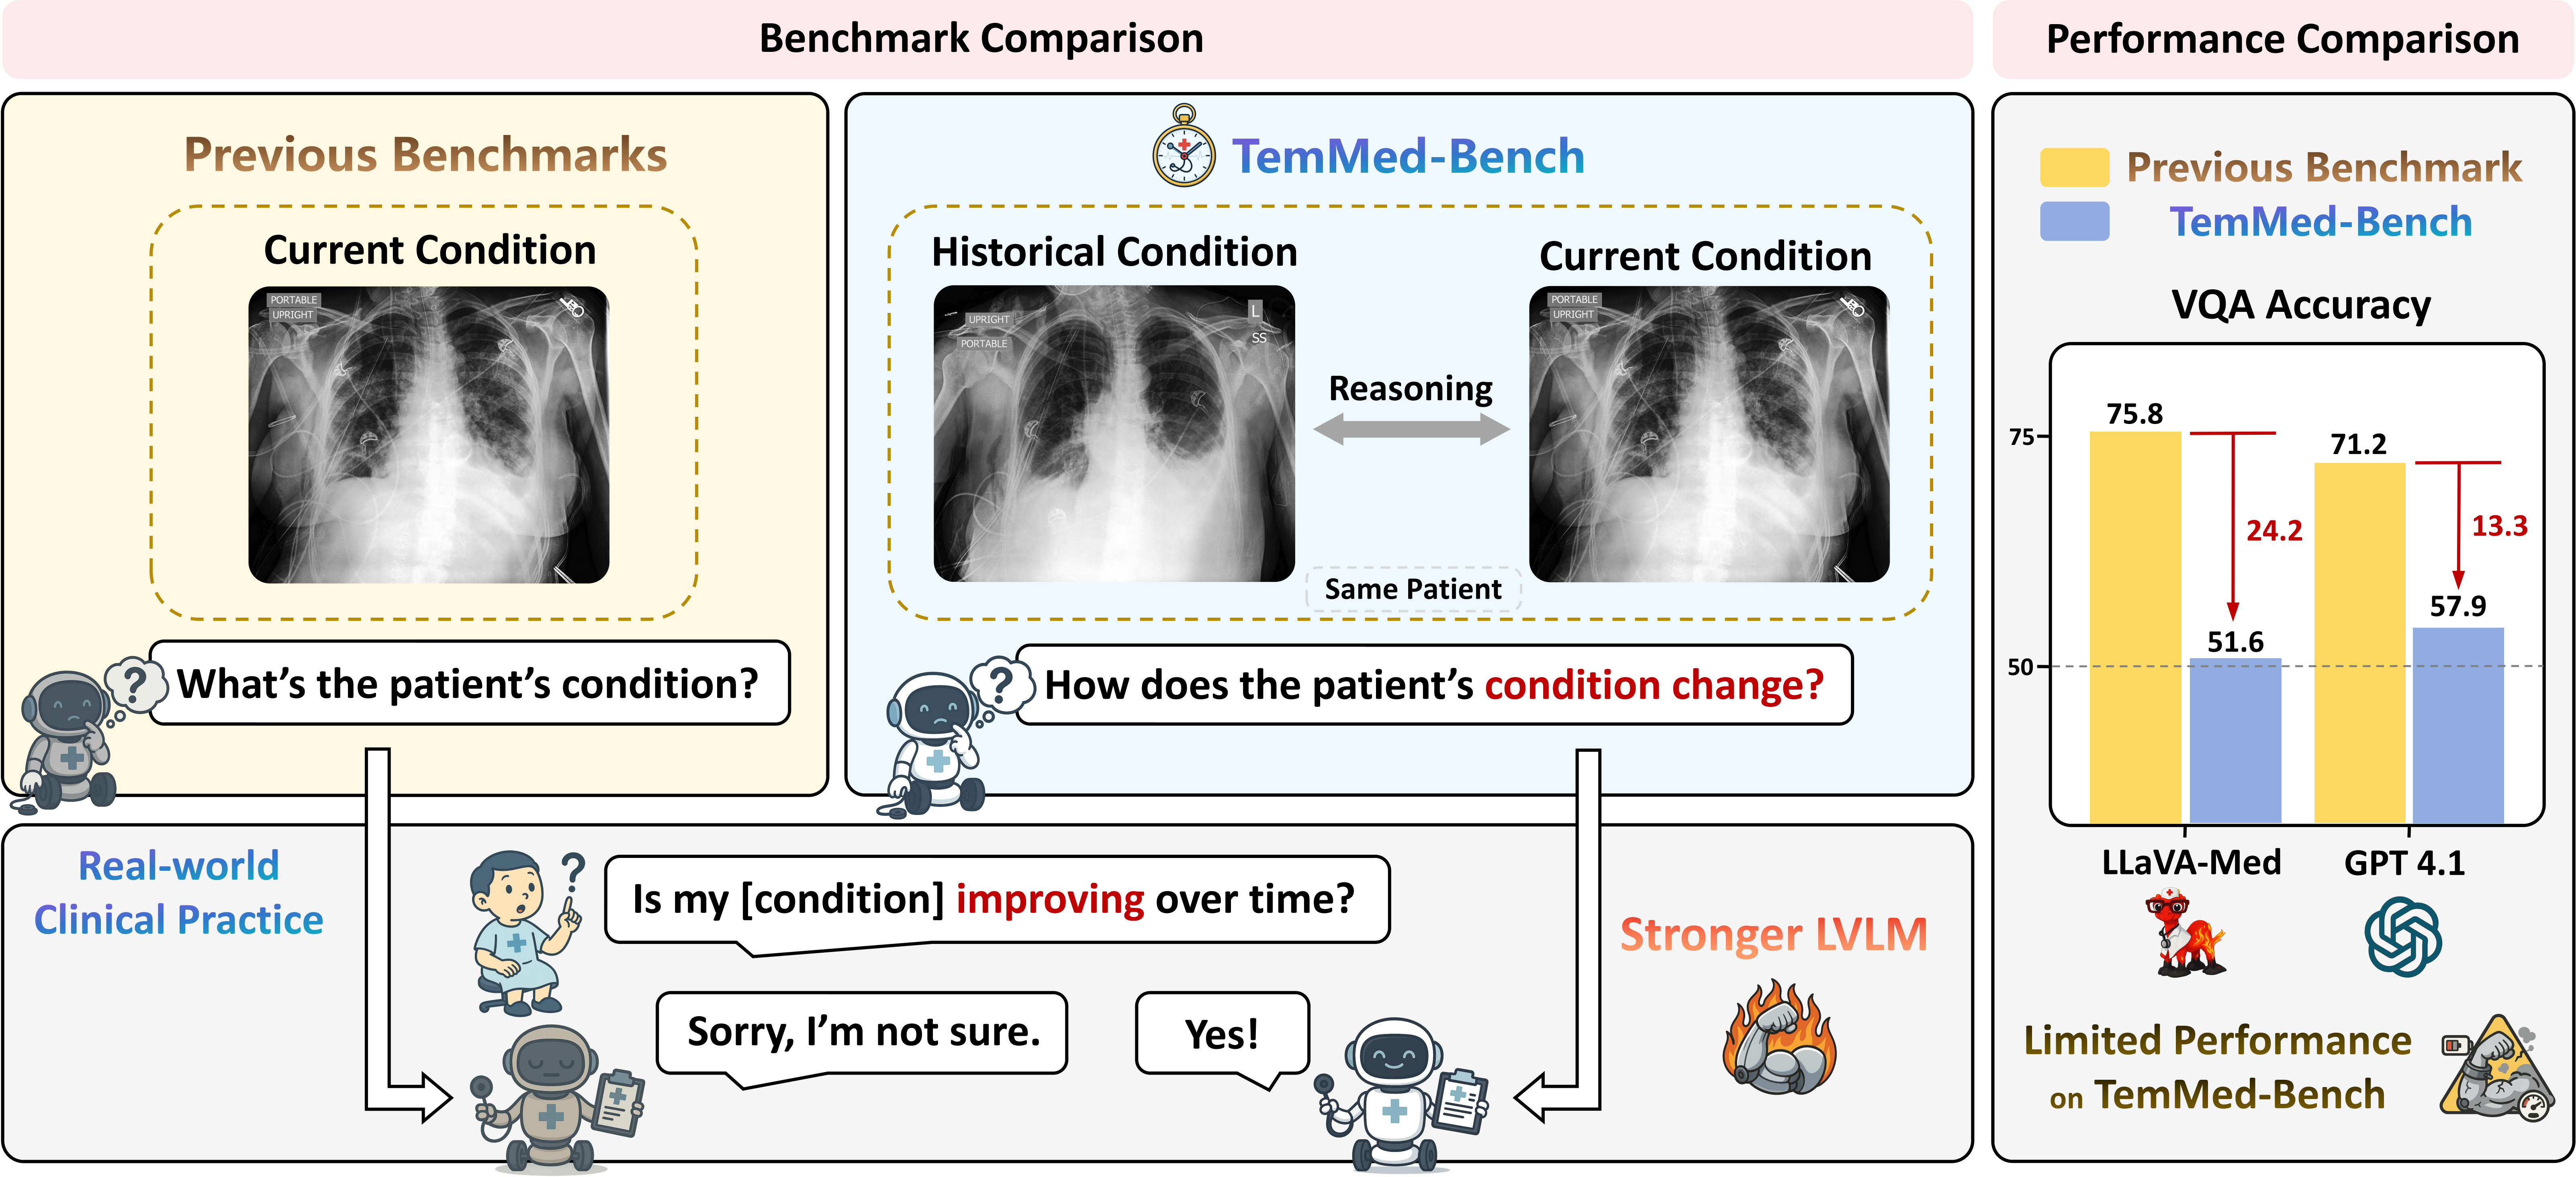
TemMed-Bench features three primary highlights.
- Temporal reasoning focus: Each sample in TemMed-Bench includes historical condition information, which challenges models to analyze changes in patient conditions over time.
- Multi-image input: Each sample in TemMed-Bench contains multiple images from different visits as input, emphasizing the need for models to process and reason over multiple images.
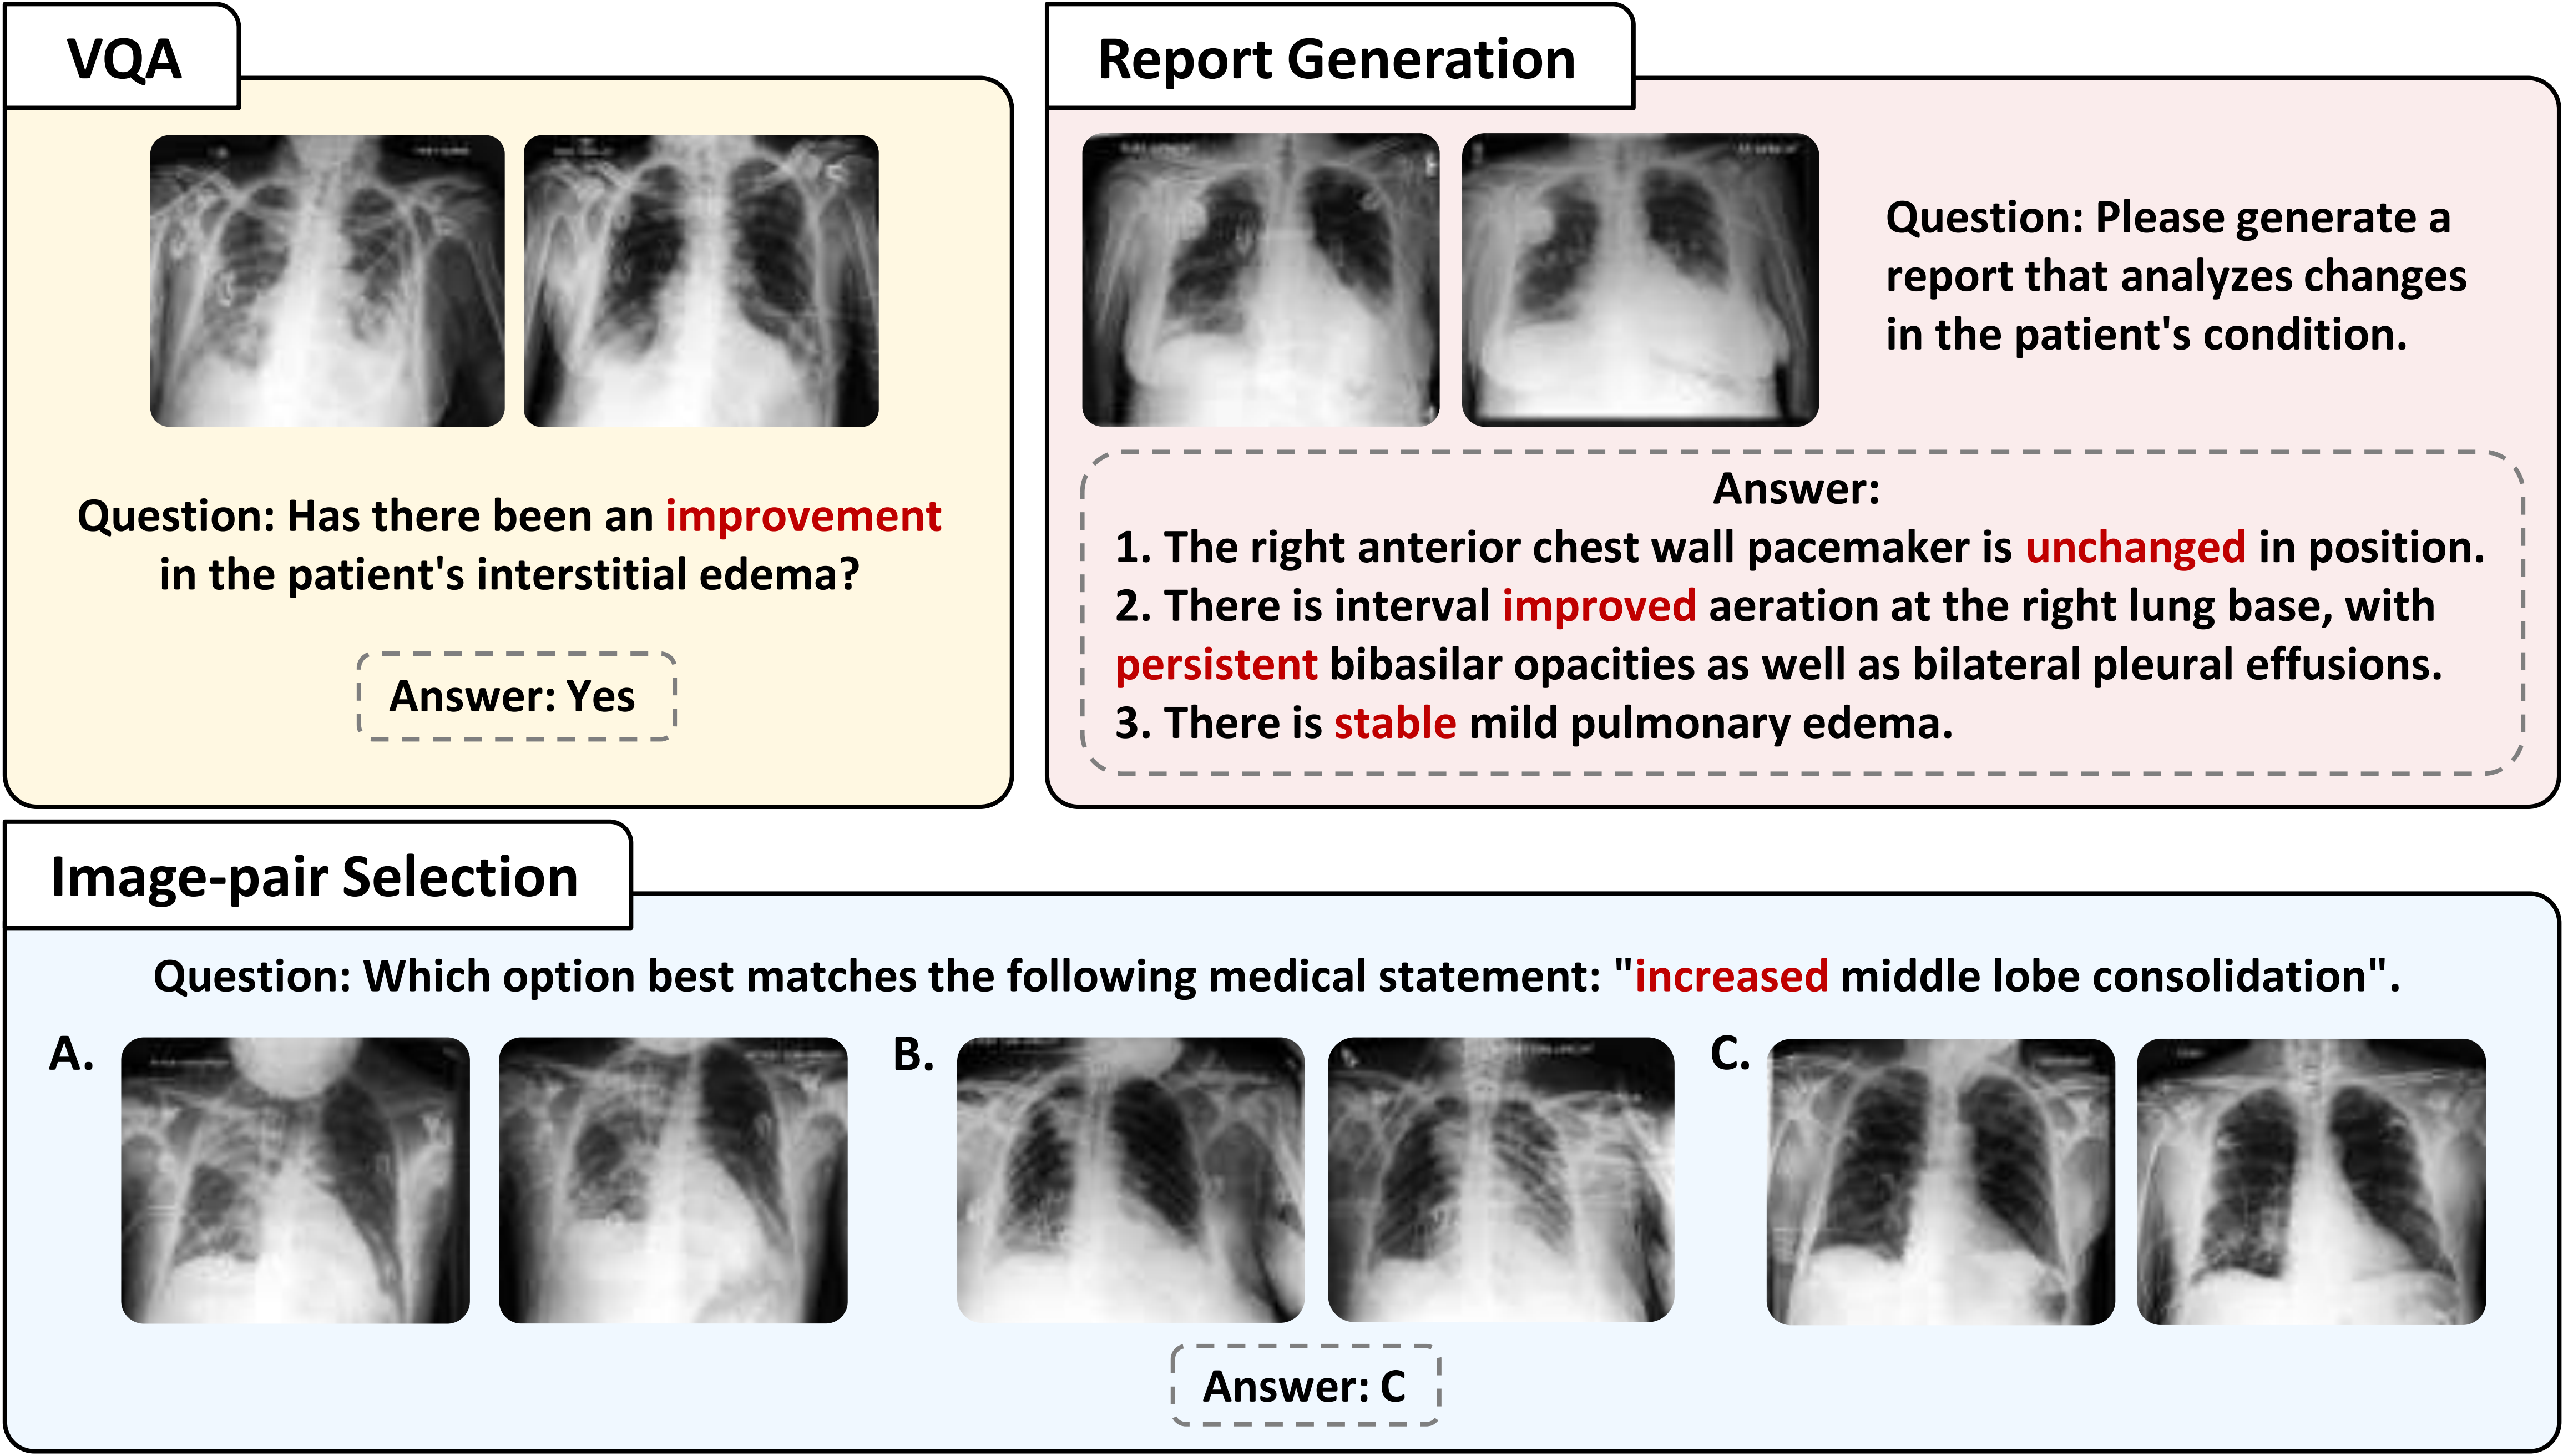
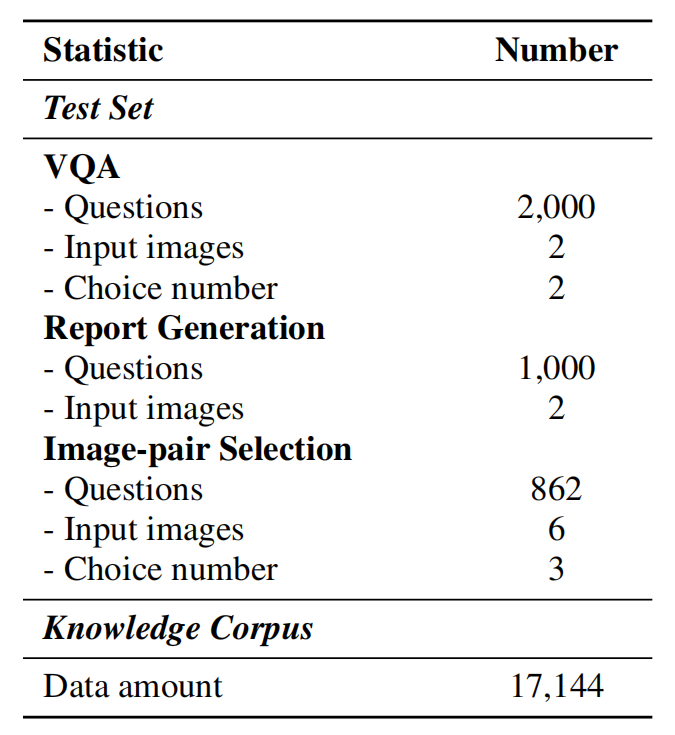
- Diverse task suite: TemMed-Bench comprises three tasks, including VQA, report generation, and image-pair selection. Additionally, TemMed-Bench includes a knowledge corpus with more than 17,000 instances to support retrieval-augmented generation (RAG).
🧩 Benchmark Overview
- Examples of the three tasks in TemMed-Bench:
- Key statistics of TemMed-Bench:
📍 Load Dataset
✅ Step 1:
-
Download the source data files from the Stanford AIMI dataset page (Due to the dataset's license agreement, the images and reports from the CheXpert Plus dataset cannot be redistributed.)
-
Save the files to the following path:
TemMed-Bench/
├── PNG/
└── df_chexpert_plus_240401.csv
✅ Step 2:
-
Download the TemMed-Bench data files from 🤗 Dataset
-
Save the files to the following path:
TemMed-Bench/
├── Get_Data/
    ├── TestSet_ImagePairSelection.json
    ├── TestSet_SelectedVQA_2000.json
    ├── TestSet_VQA_ReportGeneration.json
    └── TrainSet_KnowledgeCorpus.json
✅ Step 3:
-
Run
Get_Report_TestSet.ipynbandGet_Report_TrainSet.ipynbto get the corresponding reports for each sample in TemMed-Bench. -
The final files and directory structure are as follows:
TemMed-Bench/ ├── Get_Data/ ├── TestSet_ImagePairSelection.json ├── TestSet_SelectedVQA_2000.json ├── TestSet_VQA_ReportGeneration_Final.json └── TrainSet_KnowledgeCorpus_Final.jsonTestSet_VQA_ReportGeneration_Final.json: Data for the Report Generation and VQA tasks.TestSet_SelectedVQA_2000.json: A random subset of 2,000 VQA samples for evaluation.TestSet_ImagePairSelection.json: Data for the Image-Pair Selection task.TrainSet_KnowledgeCorpus_Final.json: The data corpus for retrieval or training.
🔬 Evaluation
-
The evaluation templates are in the
TemMed-Bench/Evalfolder. You can evaluate other models by following the evaluation procedure provided in the code. -
Run the corresponding Python script and ensure the data file path is set correctly. For example:
python VQA_GPT_RAG_imgReport.py
📧 Contact
- Junyi Zhang: JunyiZhang2002@g.ucla.edu
Citation
@misc{zhang2025temmedbenchevaluatingtemporalmedical,
      title={TemMed-Bench: Evaluating Temporal Medical Image Reasoning in Vision-Language Models},
      author={Junyi Zhang and Jia-Chen Gu and Wenbo Hu and Yu Zhou and Robinson Piramuthu and Nanyun Peng},
      year={2025},
      eprint={2509.25143},
      archivePrefix={arXiv},
      primaryClass={cs.CV},
      url={https://arxiv.org/abs/2509.25143},
}
Similar repos



Languages
Python
50.7%
Jupyter Notebook
49.3%
README
TemMed-Bench: Evaluating Temporal Medical Image Reasoning in Vision-Language Models
🌐 Homepage | 🤗 Dataset | 📖 Paper
✨ News
- 🔥 Evaluation template code is released.
- 🔥 Code for loading TemMed-Bench is released.
🚀 Intro
TemMed-Bench features three primary highlights.
- Temporal reasoning focus: Each sample in TemMed-Bench includes historical condition information, which challenges models to analyze changes in patient conditions over time.
- Multi-image input: Each sample in TemMed-Bench contains multiple images from different visits as input, emphasizing the need for models to process and reason over multiple images.
- Diverse task suite: TemMed-Bench comprises three tasks, including VQA, report generation, and image-pair selection. Additionally, TemMed-Bench includes a knowledge corpus with more than 17,000 instances to support retrieval-augmented generation (RAG).
🧩 Benchmark Overview
- Examples of the three tasks in TemMed-Bench:
- Key statistics of TemMed-Bench:
📍 Load Dataset
✅ Step 1:
-
Download the source data files from the Stanford AIMI dataset page (Due to the dataset's license agreement, the images and reports from the CheXpert Plus dataset cannot be redistributed.)
-
Save the files to the following path:
TemMed-Bench/
├── PNG/
└── df_chexpert_plus_240401.csv
✅ Step 2:
-
Download the TemMed-Bench data files from 🤗 Dataset
-
Save the files to the following path:
TemMed-Bench/
├── Get_Data/
    ├── TestSet_ImagePairSelection.json
    ├── TestSet_SelectedVQA_2000.json
    ├── TestSet_VQA_ReportGeneration.json
    └── TrainSet_KnowledgeCorpus.json
✅ Step 3:
-
Run
Get_Report_TestSet.ipynbandGet_Report_TrainSet.ipynbto get the corresponding reports for each sample in TemMed-Bench. -
The final files and directory structure are as follows:
TemMed-Bench/ ├── Get_Data/ ├── TestSet_ImagePairSelection.json ├── TestSet_SelectedVQA_2000.json ├── TestSet_VQA_ReportGeneration_Final.json └── TrainSet_KnowledgeCorpus_Final.jsonTestSet_VQA_ReportGeneration_Final.json: Data for the Report Generation and VQA tasks.TestSet_SelectedVQA_2000.json: A random subset of 2,000 VQA samples for evaluation.TestSet_ImagePairSelection.json: Data for the Image-Pair Selection task.TrainSet_KnowledgeCorpus_Final.json: The data corpus for retrieval or training.
🔬 Evaluation
-
The evaluation templates are in the
TemMed-Bench/Evalfolder. You can evaluate other models by following the evaluation procedure provided in the code. -
Run the corresponding Python script and ensure the data file path is set correctly. For example:
python VQA_GPT_RAG_imgReport.py
📧 Contact
- Junyi Zhang: JunyiZhang2002@g.ucla.edu
Citation
@misc{zhang2025temmedbenchevaluatingtemporalmedical,
      title={TemMed-Bench: Evaluating Temporal Medical Image Reasoning in Vision-Language Models},
      author={Junyi Zhang and Jia-Chen Gu and Wenbo Hu and Yu Zhou and Robinson Piramuthu and Nanyun Peng},
      year={2025},
      eprint={2509.25143},
      archivePrefix={arXiv},
      primaryClass={cs.CV},
      url={https://arxiv.org/abs/2509.25143},
}
Similar repos
Languages
Python
50.7%
Jupyter Notebook
49.3%