
README
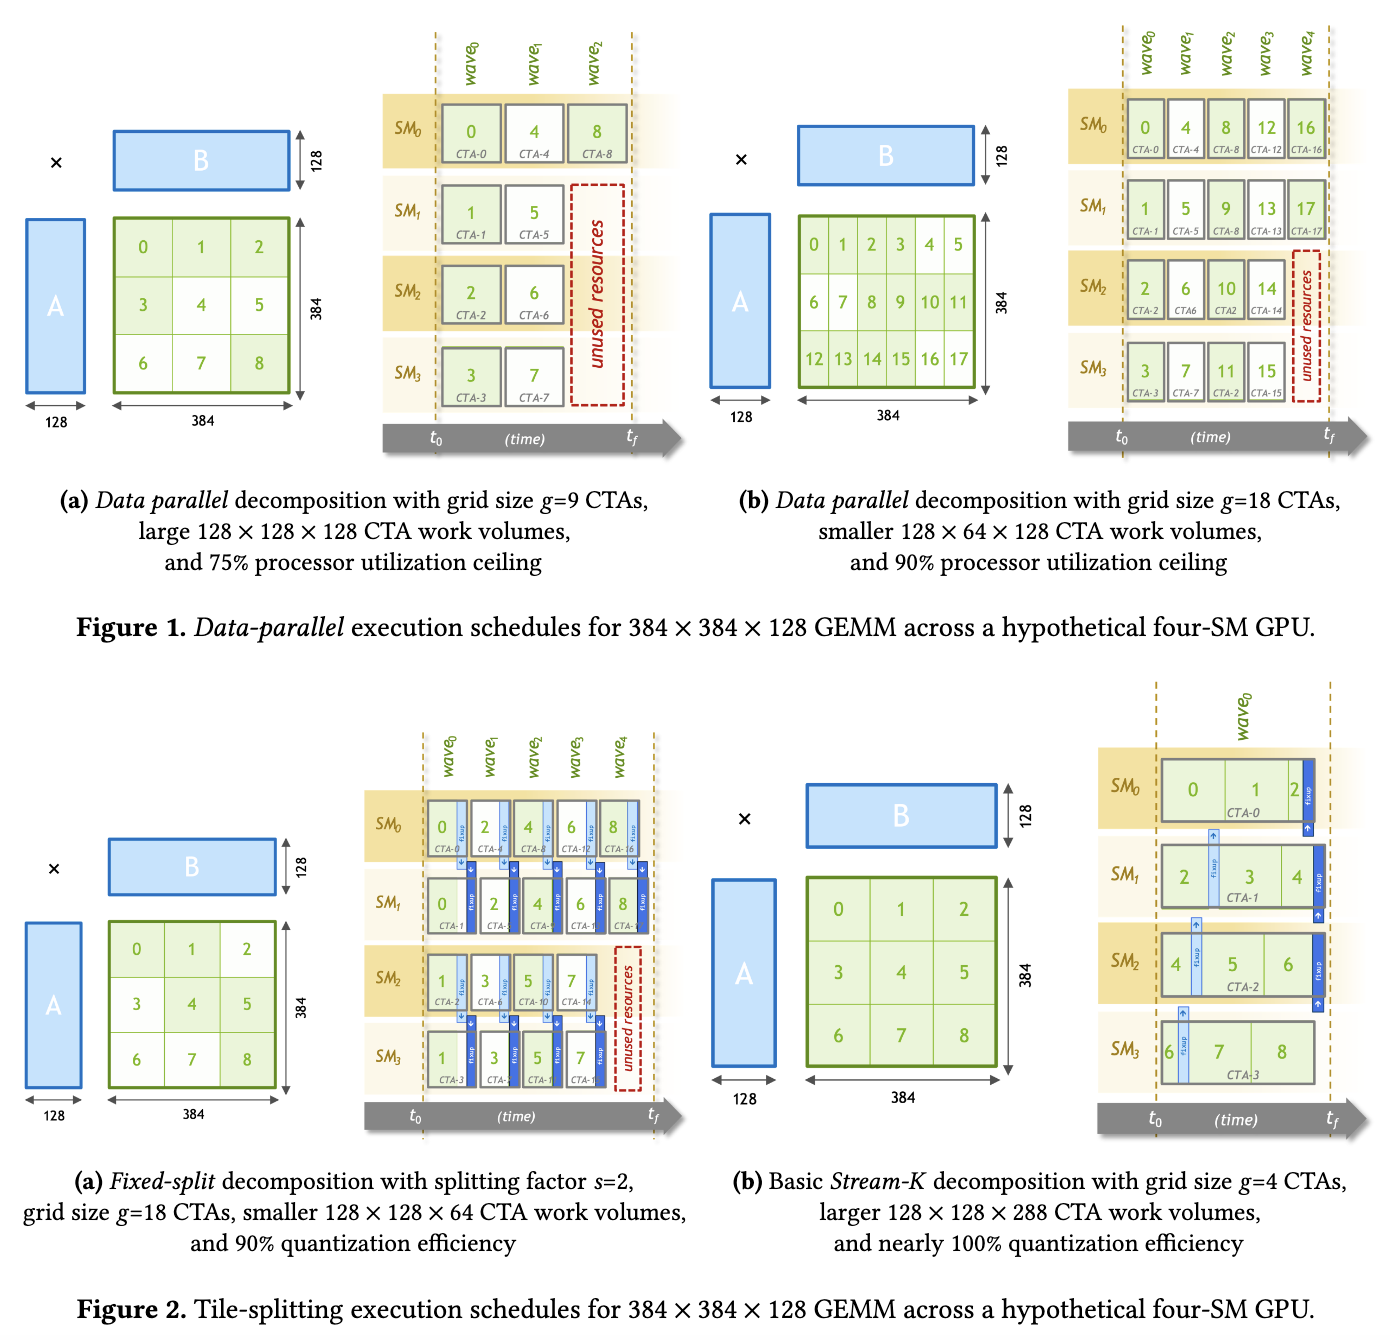
Reproduce the PPoPP'23 Paper Stream-K: Work-centric Parallel Decomposition for Dense Matrix-Matrix Multiplication on the GPU with TVM TIR and TL, which could be helpful for us to optimize the performance for small shapes.
Dependencies:
pip install git+https://github.com/microsoft/BitBLAS.git
TODO Items:
- Implement Float16 Tensor Core.
- With Vectorized AtomicAdd.
- Implement Auto Tune.
- With BlockReduction.
- With Ladder Layout Propagation.
- Apply Padding when the tile shape is not aligned for Swizzling.
- Implement Q4.
- Implement with BitBLAS Fast Dequantize.
- Enhance TL Thread Level mma Abstraction.
- Implement Dequantize template and integrate with BitBLAS.
Contributors

LeiWang1999
35 commits
Similar repos


Languages
Python
99.9%
README
Reproduce the PPoPP'23 Paper Stream-K: Work-centric Parallel Decomposition for Dense Matrix-Matrix Multiplication on the GPU with TVM TIR and TL, which could be helpful for us to optimize the performance for small shapes.
Dependencies:
pip install git+https://github.com/microsoft/BitBLAS.git
TODO Items:
- Implement Float16 Tensor Core.
- With Vectorized AtomicAdd.
- Implement Auto Tune.
- With BlockReduction.
- With Ladder Layout Propagation.
- Apply Padding when the tile shape is not aligned for Swizzling.
- Implement Q4.
- Implement with BitBLAS Fast Dequantize.
- Enhance TL Thread Level mma Abstraction.
- Implement Dequantize template and integrate with BitBLAS.
Similar repos
Contributors
LeiWang1999
35 commits
Languages
Python
99.9%