Official Repository of Absolute Zero Reasoner
See the code


⚠️WARNING⚠️: New Qwen3 base models have untrained token embeddings, we used
python absolute_zero_reasoner/utils/remove_think_qwen3_tokenizer.py --model_name <Qwen3ModelName>to remove these tokens or else the model produces nonsense.
🚧UNDER TESTING🚧 This new merge to
mainis still under testing. Use thepaperbranch to replicate results from original paper.
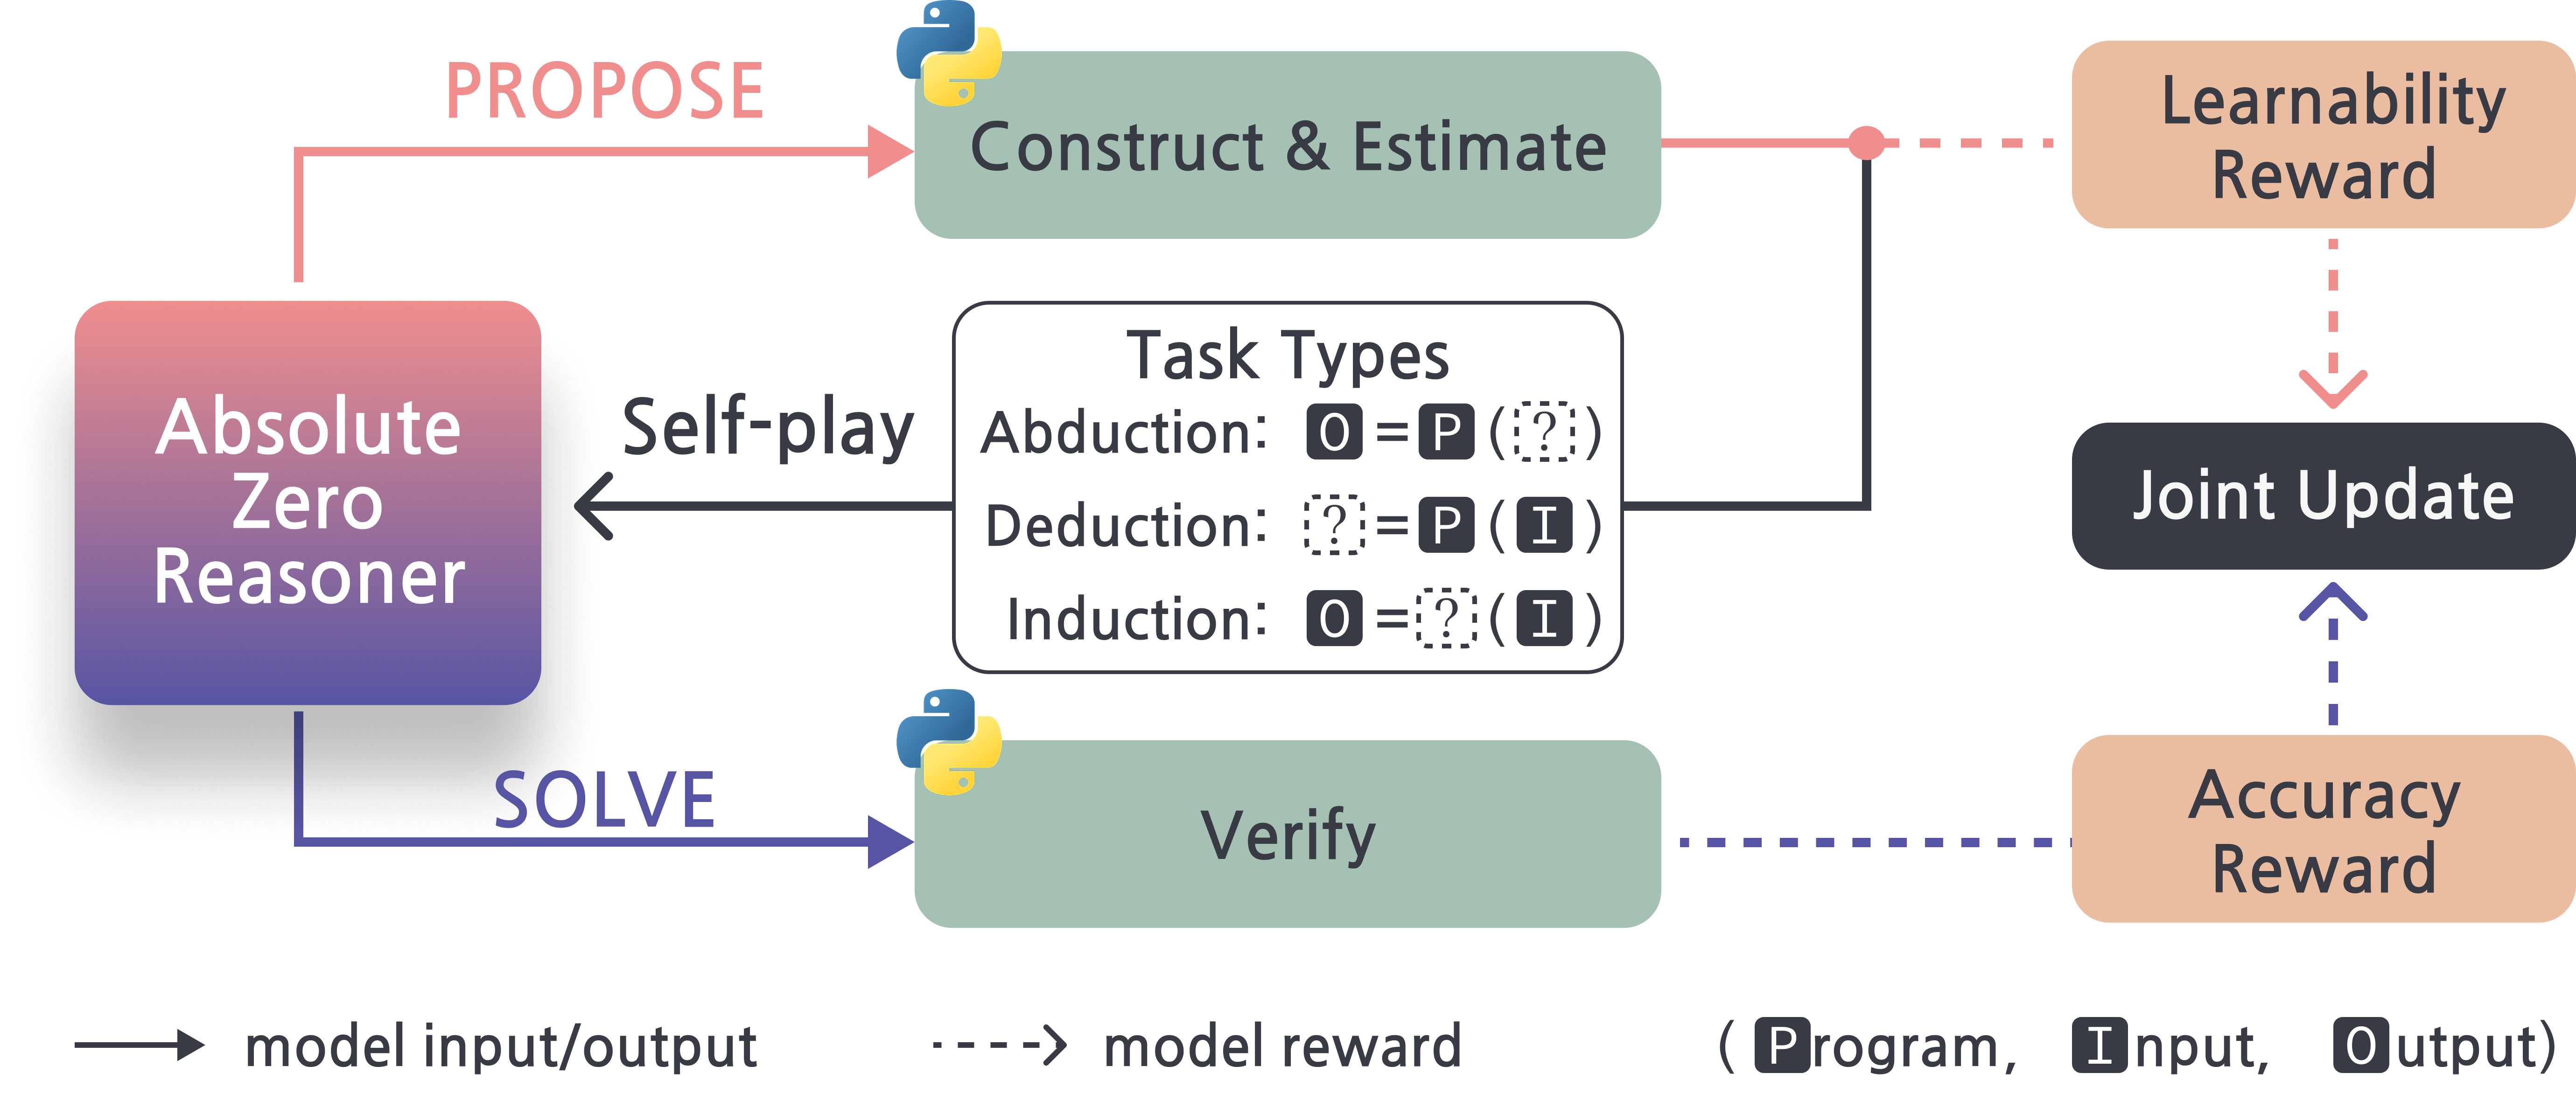
azr.executor=sandboxfusion in training configs. Officially completed our initial roadmap.paper branch to reproduce the paper results with static copy of veRL. The main branch will now be regularly updated with the latest veRL versions.Our approach centers on a repeated iterative process of the following two steps:
PROPOSE: The model generates reasoning tasks from abduction, deduction, and induction types. Tasks are validated with Python execution and assigned a learnability reward.
SOLVE: The model then attempts to solve these self-generated tasks. Solutions are verified through Python execution, receiving an accuracy reward.
The model continuously improves through both phases using TRR++, creating a self-evolving loop that strengthens reasoning without external training data.
Our approach achieves strong performance across both code and math reasoning benchmarks without using any external data:
| Model | Base | #data | Code Avg | Math Avg | Total Avg |
|---|---|---|---|---|---|
| Base Models | |||||
| Qwen2.5-7B | - | - | 52.0 | 27.5 | 39.8 |
| Qwen2.5-7B-Ins | - | - | 56.3 | 37.0 | 46.7 |
| Qwen2.5-7B-Coder | - | - | 56.6 | 23.9 | 40.2 |
| Reasoners Trained on Curated Code Data | |||||
| AceCoder-RM | Ins | 22k | 58.3 | 37.4 | 47.9 |
| AceCoder-RM | Coder | 22k | 57.3 | 27.5 | 42.4 |
| AceCoder-Rule | Ins | 22k | 55.4 | 36.9 | 46.2 |
| AceCoder-Rule | Coder | 22k | 60.0 | 28.5 | 44.3 |
| CodeR1-LC2k | Ins | 2k | 60.5 | 35.6 | 48.0 |
| CodeR1-12k | Ins | 10k | 61.3 | 33.5 | 47.4 |
| Reasoners Trained on Curated Math Data | |||||
| PRIME-Zero | Coder | 484k | 37.2 | 45.8 | 41.5 |
| SimpleRL-Zoo | Base | 8.5k | 54.0 | 38.5 | 46.3 |
| Oat-Zero | Math | 8.5k | 45.4 | 44.3 | 44.9 |
| ORZ | Base | 57k | 55.6 | 41.6 | 48.6 |
| Absolute Zero Training w/ No Curated Data (Ours) | |||||
| AZR (Ours) | Base | 0 | 55.2 +3.2 | 38.4 +10.9 | 46.8 +7.0 |
| AZR (Ours) | Coder | 0 | 61.6 +5.0 | 39.1 +15.2 | 50.4 +10.2 |
AZR shows consistent improvements across model sizes and types:
| Model Family | Variant | Code Avg | Math Avg | Total Avg |
|---|---|---|---|---|
| Llama3.1-8b | 28.5 | 3.4 | 16.0 | |
| Llama3.1-8b | + AZR (Ours) | 31.6 +3.1 | 6.8 +3.4 | 19.2 +3.2 |
| Qwen2.5-3B Coder | 51.2 | 18.8 | 35.0 | |
| Qwen2.5-3B Coder | + AZR (Ours) | 54.9 +3.7 | 26.5 +7.7 | 40.7 +5.7 |
| Qwen2.5-7B Coder | 56.6 | 23.9 | 40.2 | |
| Qwen2.5-7B Coder | + AZR (Ours) | 61.6 +5.0 | 39.1 +15.2 | 50.4 +10.2 |
| Qwen2.5-14B Coder | 60.0 | 20.2 | 40.1 | |
| Qwen2.5-14B Coder | + AZR (Ours) | 63.6 +3.6 | 43.0 +22.8 | 53.3 +13.2 |
conda env create -f azr_env.yml
conda activate azr
pip install -r flashattn_requirements.txt
python -m absolute_zero_reasoner.data_construction.process_code_reasoning_data
⚠️WARNING⚠️: The Python executor in this repository is very raw and intended for research purposes only. It is not secure for production environments. We plan to update our executor to more secure implementations in the future. Your use of our code is at your own discretion and risk.
We provide the seed datasets we collected by prompting each model in data/. If you want to create your own seed data, use the following script:
export OUTPUT_SEED_PATH=data/<new_ded_abd_seed_data_name>.jsonl
export OUTPUT_CODE_F_SEED_PATH=data/<new_ind_seed_data_name>.jsonl
bash scripts/seeding/<7b|14b|coder3b|coder7b|coder14b|llama>.sh
3b models need 2 X 80gb GPUs, 7/8b models need 4 X 80gb, 14b requires 8 X 80gb
bash scripts/selfplay/<7b|14b|coder3b|coder7b|coder14b|llama>.sh
If you want to use your own ded/abd or ind seed dataset:
export OUTPUT_SEED_PATH=data/<your_ded_abd_seed_data_name>.jsonl
export OUTPUT_CODE_F_SEED_PATH=data/<your_ind_seed_data_name>.jsonl
bash scripts/selfplay/<7b|14b|coder3b|coder7b|coder14b|llama>.sh
For using the newly supported sandbox-fusion executor, use docker and set azr.executor=sandboxfusion.
When resuming runs, put the original run wandb id into the script, i.e., trainer.wandb_run_id=<run_id>.
python -m absolute_zero_reasoner.utils.convert2hf \
  <veRL_ckpt_path>/actor \
  <veRL_ckpt_path>/actor/huggingface/ \
  <hf_ckpt_path>
In configs, just add your own rewards to azr.reward.generation_reward_config, check the ones already implemented such as diversity and complexity rewards. Be Creative!
We use the Deepseek R1 & tags as prompt template:
A conversation between User and Assistant. The user asks a question, and the Assistant solves it. The assistant first thinks about the reasoning process in the mind and then provides the user with the answer. The reasoning process and answer are enclosed within <think> </think> and <answer> </answer> tags, respectively, i.e., <think> reasoning process here </think> <answer> answer here </answer>. User: {question}\nAssistant: <think>
Setup: LCB needs to first download the data
git clone https://hf-mirror.com/datasets/livecodebench/code_generation_lite evaluation/code_eval/coding/LiveCodeBench/code_generation_lite
Evaluation:
bash evaluation/code_eval/scripts/run_lcb_gen.sh --model <andrewzh/Absolute_Zero_Reasoner-Coder-3b>
New conda env is neede for evalplus
conda create -n evalplus python=3.11
pip install --upgrade "evalplus[vllm] @ git+https://github.com/evalplus/evalplus@d362e933265c3e7e3df8101c930a89c3c470cd9f"
Evaluation:
```bash
condda activate evalplus
bash evaluation/code_eval/scripts/run_evalplus.sh 0 <humaneval|mbpp> <andrewzh/Absolute_Zero_Reasoner-Coder-3b>
Please refer to evaluation/math_eval/README.md for math evaluation.
If you find Absolute Zero Reasoner helpful, please cite us.
@misc{zhao2025absolutezeroreinforcedselfplay,
      title={Absolute Zero: Reinforced Self-play Reasoning with Zero Data},
      author={Andrew Zhao and Yiran Wu and Yang Yue and Tong Wu and Quentin Xu and Yang Yue and Matthieu Lin and Shenzhi Wang and Qingyun Wu and Zilong Zheng and Gao Huang},
      year={2025},
      eprint={2505.03335},
      archivePrefix={arXiv},
      primaryClass={cs.LG},
      url={https://arxiv.org/abs/2505.03335},
}
Our reinforcement learning training codebase is a fork of the veRL framework. For rollouts, we used vLLM. The Python executor components are adapted from the QwQ Repository. Additionally, we borrowed our README structure from PRIME. Many thanks to the authors of these projects for their excellent contributions!
Feel free to contact Andrew Zhao via email: zqc21@mails.tsinghua.edu.cn
5,095 followers · starred May 2025
164 followers · starred May 2025
373 followers · starred May 2025
830 followers · starred May 2025
Official Repository of Absolute Zero Reasoner
See the code
⚠️WARNING⚠️: New Qwen3 base models have untrained token embeddings, we used
python absolute_zero_reasoner/utils/remove_think_qwen3_tokenizer.py --model_name <Qwen3ModelName>to remove these tokens or else the model produces nonsense.
🚧UNDER TESTING🚧 This new merge to
mainis still under testing. Use thepaperbranch to replicate results from original paper.
azr.executor=sandboxfusion in training configs. Officially completed our initial roadmap.paper branch to reproduce the paper results with static copy of veRL. The main branch will now be regularly updated with the latest veRL versions.Our approach centers on a repeated iterative process of the following two steps:
PROPOSE: The model generates reasoning tasks from abduction, deduction, and induction types. Tasks are validated with Python execution and assigned a learnability reward.
SOLVE: The model then attempts to solve these self-generated tasks. Solutions are verified through Python execution, receiving an accuracy reward.
The model continuously improves through both phases using TRR++, creating a self-evolving loop that strengthens reasoning without external training data.
Our approach achieves strong performance across both code and math reasoning benchmarks without using any external data:
| Model | Base | #data | Code Avg | Math Avg | Total Avg |
|---|---|---|---|---|---|
| Base Models | |||||
| Qwen2.5-7B | - | - | 52.0 | 27.5 | 39.8 |
| Qwen2.5-7B-Ins | - | - | 56.3 | 37.0 | 46.7 |
| Qwen2.5-7B-Coder | - | - | 56.6 | 23.9 | 40.2 |
| Reasoners Trained on Curated Code Data | |||||
| AceCoder-RM | Ins | 22k | 58.3 | 37.4 | 47.9 |
| AceCoder-RM | Coder | 22k | 57.3 | 27.5 | 42.4 |
| AceCoder-Rule | Ins | 22k | 55.4 | 36.9 | 46.2 |
| AceCoder-Rule | Coder | 22k | 60.0 | 28.5 | 44.3 |
| CodeR1-LC2k | Ins | 2k | 60.5 | 35.6 | 48.0 |
| CodeR1-12k | Ins | 10k | 61.3 | 33.5 | 47.4 |
| Reasoners Trained on Curated Math Data | |||||
| PRIME-Zero | Coder | 484k | 37.2 | 45.8 | 41.5 |
| SimpleRL-Zoo | Base | 8.5k | 54.0 | 38.5 | 46.3 |
| Oat-Zero | Math | 8.5k | 45.4 | 44.3 | 44.9 |
| ORZ | Base | 57k | 55.6 | 41.6 | 48.6 |
| Absolute Zero Training w/ No Curated Data (Ours) | |||||
| AZR (Ours) | Base | 0 | 55.2 +3.2 | 38.4 +10.9 | 46.8 +7.0 |
| AZR (Ours) | Coder | 0 | 61.6 +5.0 | 39.1 +15.2 | 50.4 +10.2 |
AZR shows consistent improvements across model sizes and types:
| Model Family | Variant | Code Avg | Math Avg | Total Avg |
|---|---|---|---|---|
| Llama3.1-8b | 28.5 | 3.4 | 16.0 | |
| Llama3.1-8b | + AZR (Ours) | 31.6 +3.1 | 6.8 +3.4 | 19.2 +3.2 |
| Qwen2.5-3B Coder | 51.2 | 18.8 | 35.0 | |
| Qwen2.5-3B Coder | + AZR (Ours) | 54.9 +3.7 | 26.5 +7.7 | 40.7 +5.7 |
| Qwen2.5-7B Coder | 56.6 | 23.9 | 40.2 | |
| Qwen2.5-7B Coder | + AZR (Ours) | 61.6 +5.0 | 39.1 +15.2 | 50.4 +10.2 |
| Qwen2.5-14B Coder | 60.0 | 20.2 | 40.1 | |
| Qwen2.5-14B Coder | + AZR (Ours) | 63.6 +3.6 | 43.0 +22.8 | 53.3 +13.2 |
conda env create -f azr_env.yml
conda activate azr
pip install -r flashattn_requirements.txt
python -m absolute_zero_reasoner.data_construction.process_code_reasoning_data
⚠️WARNING⚠️: The Python executor in this repository is very raw and intended for research purposes only. It is not secure for production environments. We plan to update our executor to more secure implementations in the future. Your use of our code is at your own discretion and risk.
We provide the seed datasets we collected by prompting each model in data/. If you want to create your own seed data, use the following script:
export OUTPUT_SEED_PATH=data/<new_ded_abd_seed_data_name>.jsonl
export OUTPUT_CODE_F_SEED_PATH=data/<new_ind_seed_data_name>.jsonl
bash scripts/seeding/<7b|14b|coder3b|coder7b|coder14b|llama>.sh
3b models need 2 X 80gb GPUs, 7/8b models need 4 X 80gb, 14b requires 8 X 80gb
bash scripts/selfplay/<7b|14b|coder3b|coder7b|coder14b|llama>.sh
If you want to use your own ded/abd or ind seed dataset:
export OUTPUT_SEED_PATH=data/<your_ded_abd_seed_data_name>.jsonl
export OUTPUT_CODE_F_SEED_PATH=data/<your_ind_seed_data_name>.jsonl
bash scripts/selfplay/<7b|14b|coder3b|coder7b|coder14b|llama>.sh
For using the newly supported sandbox-fusion executor, use docker and set azr.executor=sandboxfusion.
When resuming runs, put the original run wandb id into the script, i.e., trainer.wandb_run_id=<run_id>.
python -m absolute_zero_reasoner.utils.convert2hf \
  <veRL_ckpt_path>/actor \
  <veRL_ckpt_path>/actor/huggingface/ \
  <hf_ckpt_path>
In configs, just add your own rewards to azr.reward.generation_reward_config, check the ones already implemented such as diversity and complexity rewards. Be Creative!
We use the Deepseek R1 & tags as prompt template:
A conversation between User and Assistant. The user asks a question, and the Assistant solves it. The assistant first thinks about the reasoning process in the mind and then provides the user with the answer. The reasoning process and answer are enclosed within <think> </think> and <answer> </answer> tags, respectively, i.e., <think> reasoning process here </think> <answer> answer here </answer>. User: {question}\nAssistant: <think>
Setup: LCB needs to first download the data
git clone https://hf-mirror.com/datasets/livecodebench/code_generation_lite evaluation/code_eval/coding/LiveCodeBench/code_generation_lite
Evaluation:
bash evaluation/code_eval/scripts/run_lcb_gen.sh --model <andrewzh/Absolute_Zero_Reasoner-Coder-3b>
New conda env is neede for evalplus
conda create -n evalplus python=3.11
pip install --upgrade "evalplus[vllm] @ git+https://github.com/evalplus/evalplus@d362e933265c3e7e3df8101c930a89c3c470cd9f"
Evaluation:
```bash
condda activate evalplus
bash evaluation/code_eval/scripts/run_evalplus.sh 0 <humaneval|mbpp> <andrewzh/Absolute_Zero_Reasoner-Coder-3b>
Please refer to evaluation/math_eval/README.md for math evaluation.
If you find Absolute Zero Reasoner helpful, please cite us.
@misc{zhao2025absolutezeroreinforcedselfplay,
      title={Absolute Zero: Reinforced Self-play Reasoning with Zero Data},
      author={Andrew Zhao and Yiran Wu and Yang Yue and Tong Wu and Quentin Xu and Yang Yue and Matthieu Lin and Shenzhi Wang and Qingyun Wu and Zilong Zheng and Gao Huang},
      year={2025},
      eprint={2505.03335},
      archivePrefix={arXiv},
      primaryClass={cs.LG},
      url={https://arxiv.org/abs/2505.03335},
}
Our reinforcement learning training codebase is a fork of the veRL framework. For rollouts, we used vLLM. The Python executor components are adapted from the QwQ Repository. Additionally, we borrowed our README structure from PRIME. Many thanks to the authors of these projects for their excellent contributions!
Feel free to contact Andrew Zhao via email: zqc21@mails.tsinghua.edu.cn
5,095 followers · starred May 2025
164 followers · starred May 2025
373 followers · starred May 2025
830 followers · starred May 2025



