
[CVPR 2026] IOMM: Fast Pre-training of Unified Multimodal Models without Text-Image Pairs
Python
26
6 commits
updated Apr 11, 2026
README
Rethinking UMM Visual Generation: Masked Modeling for Efficient Image-Only Pre-training
Peng Sun1,3,* · Jun Xie1,2,3,* · Tao Lin3
1Zhejiang University 2Shanghai Innovation Institute 3Westlake University
:robot: Models
:page_facing_up: Paper
:label: BibTeX
Official PyTorch implementation of IOMM: :trophy: A data-efficient training (both pre-training and fine-tuning) paradigm for Unified Multimodal Models.
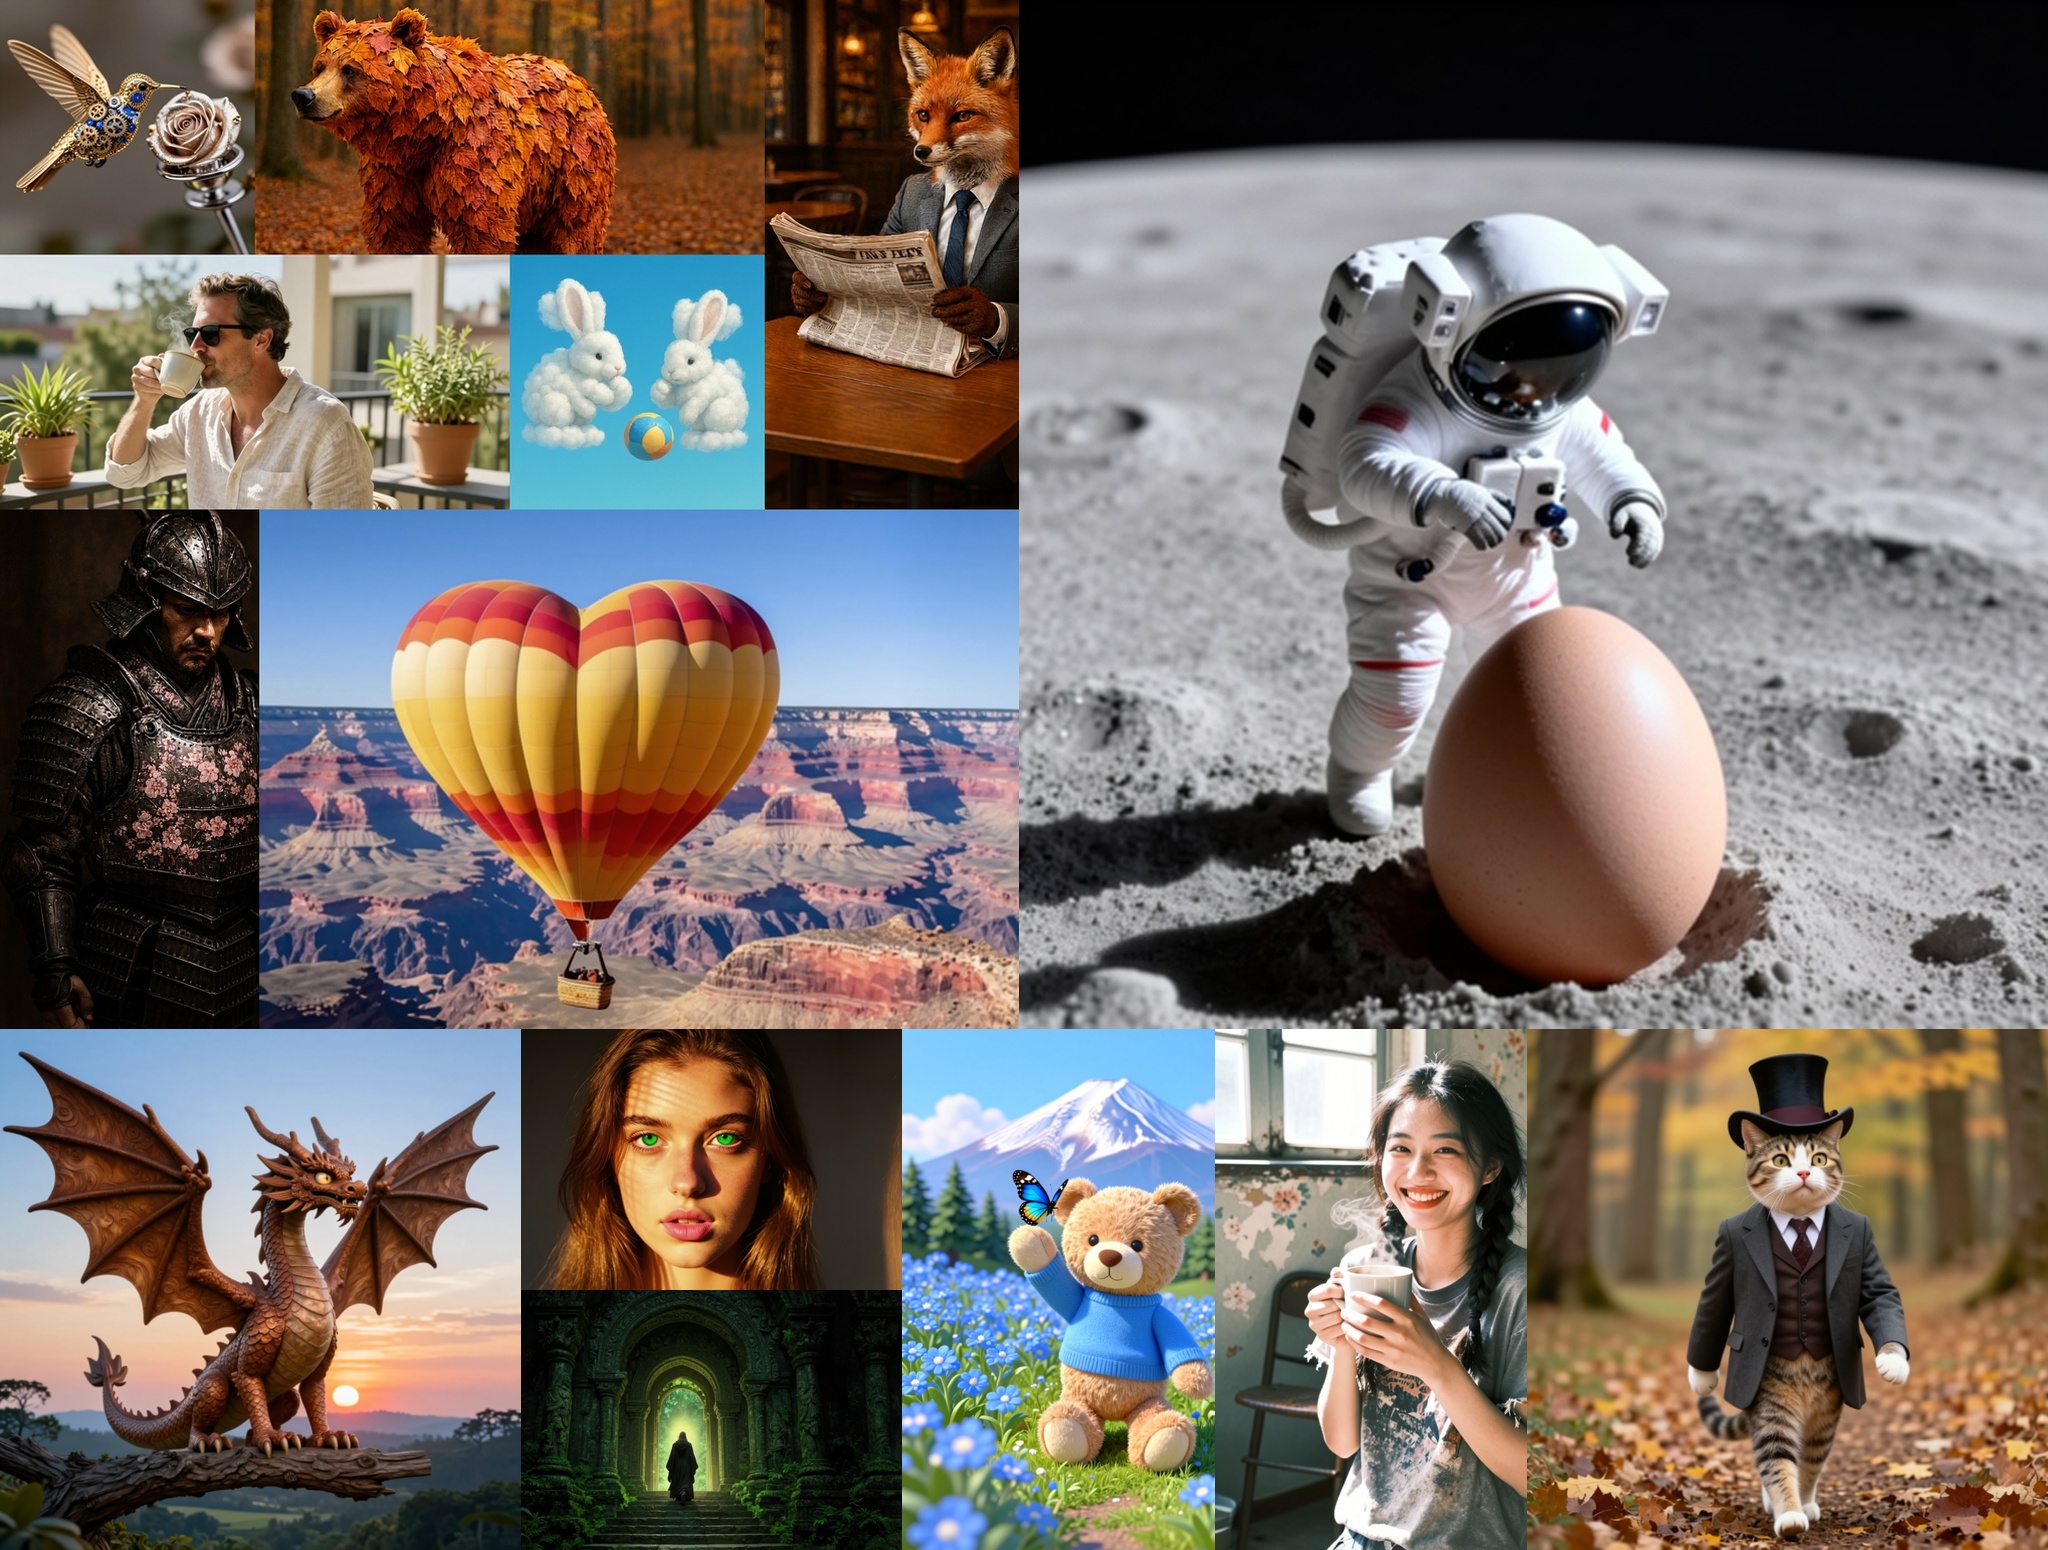
Generation results of our IOMM-XL
:construction: TODOs
[✅] Release the paper.
[✅] Release IOMM-B.
[✅] Release inference code.
[ ] Update the paper.
[ ] Release training code.
:sparkles: Features
:rocket: Image-only Pre-training:
- :white_check_mark: No need for high-quality text-image pair datasets
- :white_check_mark: Achieve GenEval=0.89 at 10 epoch under 11 million data
- :white_check_mark: Gain editing ability under zero-shot settings
:zap: Mixed Data Fine-tuning:
-
:white_check_mark: GenEval = 0.89 and WISE = 0.63 for Qwen-Image-20B
-
:bar_chart: Extended results for additional tuned models are available here
:book: Check more detailed features in our paper!
:gear: Inference Demo
Download the pre-trained IOMM-B model from Hugging Face.
After downloading the models, please change the checkpoint_path in inference.py:42 to the path of the downloaded IOMM-B model.
Install dependencies and run the inference demo:
# using python 3.11
pip install -r requirements.txt
python ./inference.py
:rocket: Generalization to open-source UMMs
Our mixed data fine-tuning paradigm also achieves notable performance enhancement in those open-source Unified Multimodal Models (UMMs), even for the powerful baseline Qwen-Image-20B.
| METHOD | Res. | NFE | GenEval | WISE |
|---|---|---|---|---|
| OpenUni-L | 512 | 20 $\times$ 2 | 0.85 | 0.52 |
| $\quad \boldsymbol{\oplus}$ Pair finetuning | 512 | 20 $\times$ 2 | 0.88 | 0.62 |
| $\quad \boldsymbol{\oplus}$ Mix finetuning | 512 | 20 $\times$ 2 | 0.88 | 0.59 |
| Qwen-Image-20B | 512 | 50 $\times$ 2 | 0.85 | - |
| $\quad \boldsymbol{\oplus}$ Pair finetuning | 512 | 50 $\times$ 2 | 0.88 | 0.63 |
| $\quad \boldsymbol{\oplus}$ Mix finetuning | 512 | 50 $\times$ 2 | 0.89 | 0.63 |
| Qwen-Image-20B | 1024 | 50 $\times$ 2 | 0.87 | 0.62 |
| $\quad \boldsymbol{\oplus}$ Pair finetuning | 1024 | 50 $\times$ 2 | 0.88 | 0.63 |
| $\quad \boldsymbol{\oplus}$ Mix finetuning | 1024 | 50 $\times$ 2 | 0.89 | 0.63 |
:label: Bibliography
If you find this repository helpful for your project, please consider citing our work:
@inproceedings{sun2026rethinking,
  title={Rethinking UMM Visual Generation: Masked Modeling for Efficient Image-Only Pre-training},
  author={Sun, Peng and Xie, Jun and Lin, Tao},
  booktitle={Proceedings of the IEEE/CVF Conference on Computer Vision and Pattern Recognition (CVPR)},
  year={2026}
}
:page_facing_up: License
Apache License 2.0 - See LICENSE for details.
Contributors

5 commits
1 commits
Similar repos


Languages
Python
100.0%
[CVPR 2026] IOMM: Fast Pre-training of Unified Multimodal Models without Text-Image Pairs
Python
26
6 commits
updated Apr 11, 2026
README
Rethinking UMM Visual Generation: Masked Modeling for Efficient Image-Only Pre-training
Peng Sun1,3,* · Jun Xie1,2,3,* · Tao Lin3
1Zhejiang University 2Shanghai Innovation Institute 3Westlake University
:robot: Models
:page_facing_up: Paper
:label: BibTeX
Official PyTorch implementation of IOMM: :trophy: A data-efficient training (both pre-training and fine-tuning) paradigm for Unified Multimodal Models.
Generation results of our IOMM-XL
:construction: TODOs
[✅] Release the paper.
[✅] Release IOMM-B.
[✅] Release inference code.
[ ] Update the paper.
[ ] Release training code.
:sparkles: Features
:rocket: Image-only Pre-training:
- :white_check_mark: No need for high-quality text-image pair datasets
- :white_check_mark: Achieve GenEval=0.89 at 10 epoch under 11 million data
- :white_check_mark: Gain editing ability under zero-shot settings
:zap: Mixed Data Fine-tuning:
-
:white_check_mark: GenEval = 0.89 and WISE = 0.63 for Qwen-Image-20B
-
:bar_chart: Extended results for additional tuned models are available here
:book: Check more detailed features in our paper!
:gear: Inference Demo
Download the pre-trained IOMM-B model from Hugging Face.
After downloading the models, please change the checkpoint_path in inference.py:42 to the path of the downloaded IOMM-B model.
Install dependencies and run the inference demo:
# using python 3.11
pip install -r requirements.txt
python ./inference.py
:rocket: Generalization to open-source UMMs
Our mixed data fine-tuning paradigm also achieves notable performance enhancement in those open-source Unified Multimodal Models (UMMs), even for the powerful baseline Qwen-Image-20B.
| METHOD | Res. | NFE | GenEval | WISE |
|---|---|---|---|---|
| OpenUni-L | 512 | 20 $\times$ 2 | 0.85 | 0.52 |
| $\quad \boldsymbol{\oplus}$ Pair finetuning | 512 | 20 $\times$ 2 | 0.88 | 0.62 |
| $\quad \boldsymbol{\oplus}$ Mix finetuning | 512 | 20 $\times$ 2 | 0.88 | 0.59 |
| Qwen-Image-20B | 512 | 50 $\times$ 2 | 0.85 | - |
| $\quad \boldsymbol{\oplus}$ Pair finetuning | 512 | 50 $\times$ 2 | 0.88 | 0.63 |
| $\quad \boldsymbol{\oplus}$ Mix finetuning | 512 | 50 $\times$ 2 | 0.89 | 0.63 |
| Qwen-Image-20B | 1024 | 50 $\times$ 2 | 0.87 | 0.62 |
| $\quad \boldsymbol{\oplus}$ Pair finetuning | 1024 | 50 $\times$ 2 | 0.88 | 0.63 |
| $\quad \boldsymbol{\oplus}$ Mix finetuning | 1024 | 50 $\times$ 2 | 0.89 | 0.63 |
:label: Bibliography
If you find this repository helpful for your project, please consider citing our work:
@inproceedings{sun2026rethinking,
  title={Rethinking UMM Visual Generation: Masked Modeling for Efficient Image-Only Pre-training},
  author={Sun, Peng and Xie, Jun and Lin, Tao},
  booktitle={Proceedings of the IEEE/CVF Conference on Computer Vision and Pattern Recognition (CVPR)},
  year={2026}
}
:page_facing_up: License
Apache License 2.0 - See LICENSE for details.
Similar repos
Contributors
5 commits
1 commits
Languages
Python
100.0%