[Paper] [Hugging Face] [Model] [BibTeX]
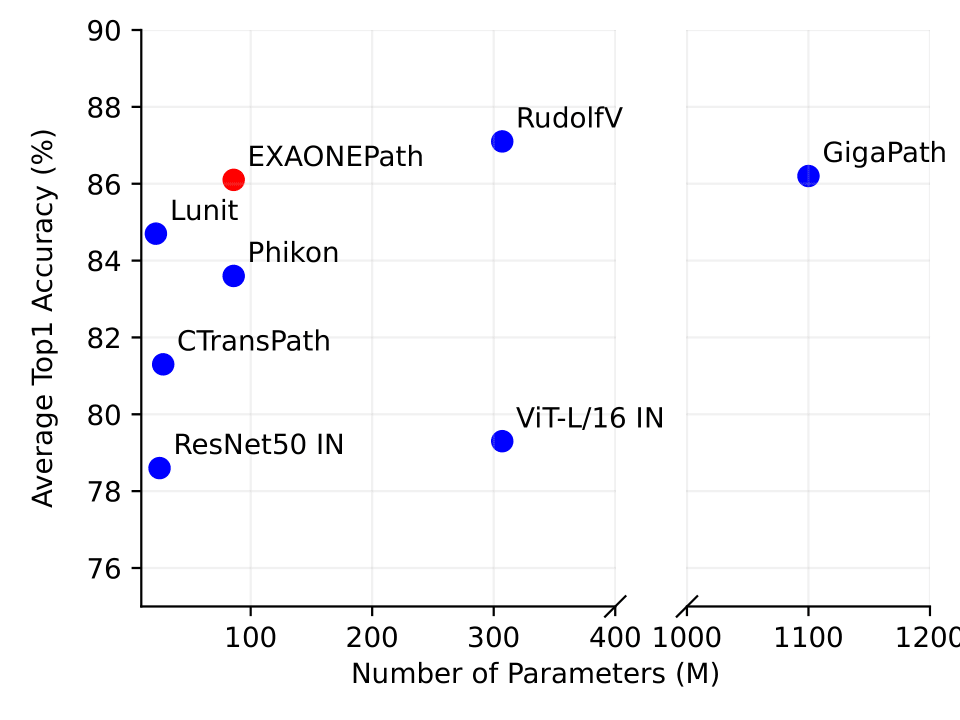
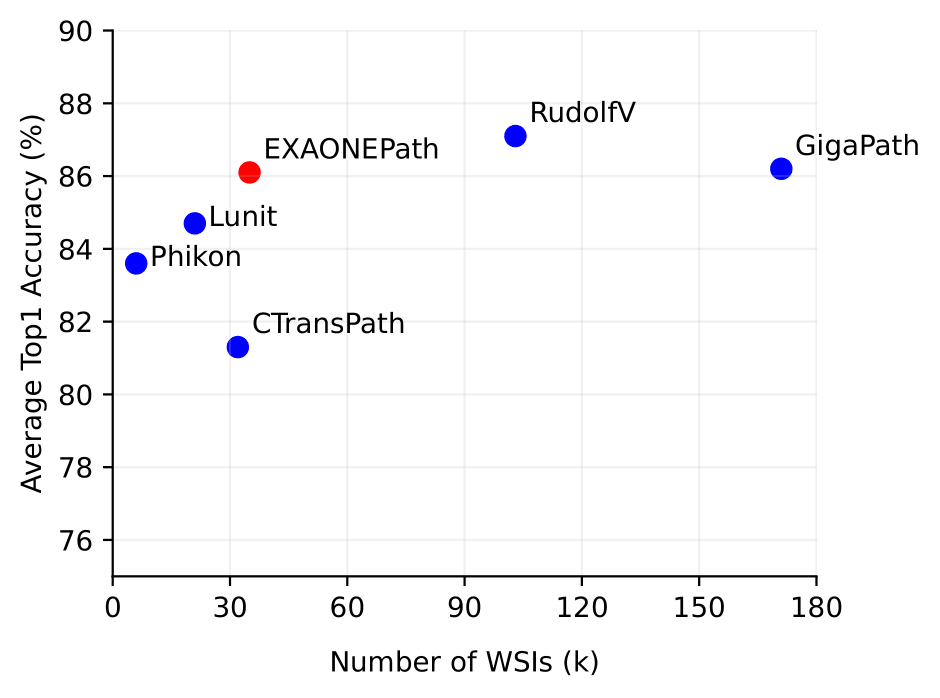
We introduce EXAONEPath, a patch-level pathology pretrained model with 86 million parameters. The model was pretrained on 285,153,903 patches extracted from a total of 34,795 WSIs. EXAONEPath demonstrates superior performance considering the number of WSIs used and the model's parameter count.
Load EXAONEPath and run inference on tile-level images.
Note: This implementation requires NVIDIA GPU and drivers. The provided environment setup specifically uses CUDA-enabled PyTorch, making NVIDIA GPU mandatory for running the model.
First, install Conda if you haven't already. You can find installation instructions here. Then create and activate the environment using the provided configuration:
git clone https://github.com/LG-AI-EXAONE/EXAONEPath.git
cd EXAONEPath
conda env create -f environment.yaml
conda activate exaonepath
import torch
from PIL import Image
from macenko import macenko_normalizer
import torchvision.transforms as transforms
from vision_transformer import VisionTransformer

hf_token = "YOUR_HUGGING_FACE_ACCESS_TOKEN"
model = VisionTransformer.from_pretrained("LGAI-EXAONE/EXAONEPath", use_auth_token=hf_token)

transform = transforms.Compose(
    [
        transforms.Resize(256, interpolation=transforms.InterpolationMode.BICUBIC),
        transforms.CenterCrop(224),
        transforms.Normalize(mean=(0.485, 0.456, 0.406), std=(0.229, 0.224, 0.225)),
    ]
)

normalizer = macenko_normalizer()
img_path = "images/MHIST_aaa.png"
image = Image.open(img_path).convert("RGB")
image_macenko = normalizer(image)

sample_input = transform(image_macenko).unsqueeze(0)
model.cuda()
model.eval()

features = model(sample_input.cuda())
First, download the EXAONEPath model checkpoint from here
import torch
from PIL import Image
from macenko import macenko_normalizer
import torchvision.transforms as transforms
from vision_transformer import vit_base

file_path = "MODEL_CHECKPOINT_PATH"
checkpoint = torch.load(file_path, map_location=torch.device('cpu'))
state_dict = checkpoint['state_dict']
model = vit_base(patch_size=16, num_classes=0)
msg = model.load_state_dict(state_dict, strict=False)
print(f'Pretrained weights found at {file_path} and loaded with msg: {msg}')

transform = transforms.Compose(
    [
        transforms.Resize(256, interpolation=transforms.InterpolationMode.BICUBIC),
        transforms.CenterCrop(224),
        transforms.Normalize(mean=(0.485, 0.456, 0.406), std=(0.229, 0.224, 0.225)),
    ]
)

normalizer = macenko_normalizer()
img_path = "images/MHIST_aaa.png"
image = Image.open(img_path).convert("RGB")
image_macenko = normalizer(image)

sample_input = transform(image_macenko).unsqueeze(0)
model.cuda()
model.eval()

features = model(sample_input.cuda())
We report linear evaluation result on six downstream tasks. Top-1 accuracy is shown, with values for models other than Gigapath taken from the RudolfV paper.
| Model | PCAM | MHIST | CRC-100K | TIL Det. | MSI CRC | MSI STAD | Avg |
|---|---|---|---|---|---|---|---|
| ResNet50 ImageNet | 0.833 | 0.806 | 0.849 | 0.915 | 0.653 | 0.664 | 0.787 |
| ViT-L/16 ImageNet | 0.852 | 0.796 | 0.847 | 0.924 | 0.669 | 0.671 | 0.793 |
| Lunit | 0.918 | 0.771 | 0.949 | 0.943 | 0.745 | 0.756 | 0.847 |
| CTransPath | 0.872 | 0.817 | 0.840 | 0.930 | 0.694 | 0.726 | 0.813 |
| Phikon | 0.906 | 0.795 | 0.883 | 0.946 | 0.733 | 0.751 | 0.836 |
| Virchow | 0.933 | 0.834 | 0.968 | - | - | - | - |
| RudolfV | 0.944 | 0.821 | 0.973 | 0.943 | 0.755 | 0.788 | 0.871 |
| GigaPath (patch encoder) | 0.947 | 0.822 | 0.964 | 0.938 | 0.753 | 0.748 | 0.862 |
| EXAONEPath (ours) | 0.901 | 0.818 | 0.946 | 0.939 | 0.756 | 0.804 | 0.861 |
The model is licensed under EXAONEPath AI Model License Agreement 1.0 - NC
If you find EXAONEPath useful, please cite it using this BibTeX:
@article{yun2024exaonepath,
  title={EXAONEPath 1.0 Patch-level Foundation Model for Pathology},
  author={Yun, Juseung and Hu, Yi and Kim, Jinhyung and Jang, Jongseong and Lee, Soonyoung},
  journal={arXiv preprint arXiv:2408.00380},
  year={2024}
}
LG AI Research Technical Support: [email protected]
1,113 followers · starred Sep 2024
[Paper] [Hugging Face] [Model] [BibTeX]
We introduce EXAONEPath, a patch-level pathology pretrained model with 86 million parameters. The model was pretrained on 285,153,903 patches extracted from a total of 34,795 WSIs. EXAONEPath demonstrates superior performance considering the number of WSIs used and the model's parameter count.
Load EXAONEPath and run inference on tile-level images.
Note: This implementation requires NVIDIA GPU and drivers. The provided environment setup specifically uses CUDA-enabled PyTorch, making NVIDIA GPU mandatory for running the model.
First, install Conda if you haven't already. You can find installation instructions here. Then create and activate the environment using the provided configuration:
git clone https://github.com/LG-AI-EXAONE/EXAONEPath.git
cd EXAONEPath
conda env create -f environment.yaml
conda activate exaonepath
import torch
from PIL import Image
from macenko import macenko_normalizer
import torchvision.transforms as transforms
from vision_transformer import VisionTransformer

hf_token = "YOUR_HUGGING_FACE_ACCESS_TOKEN"
model = VisionTransformer.from_pretrained("LGAI-EXAONE/EXAONEPath", use_auth_token=hf_token)

transform = transforms.Compose(
    [
        transforms.Resize(256, interpolation=transforms.InterpolationMode.BICUBIC),
        transforms.CenterCrop(224),
        transforms.Normalize(mean=(0.485, 0.456, 0.406), std=(0.229, 0.224, 0.225)),
    ]
)

normalizer = macenko_normalizer()
img_path = "images/MHIST_aaa.png"
image = Image.open(img_path).convert("RGB")
image_macenko = normalizer(image)

sample_input = transform(image_macenko).unsqueeze(0)
model.cuda()
model.eval()

features = model(sample_input.cuda())
First, download the EXAONEPath model checkpoint from here
import torch
from PIL import Image
from macenko import macenko_normalizer
import torchvision.transforms as transforms
from vision_transformer import vit_base

file_path = "MODEL_CHECKPOINT_PATH"
checkpoint = torch.load(file_path, map_location=torch.device('cpu'))
state_dict = checkpoint['state_dict']
model = vit_base(patch_size=16, num_classes=0)
msg = model.load_state_dict(state_dict, strict=False)
print(f'Pretrained weights found at {file_path} and loaded with msg: {msg}')

transform = transforms.Compose(
    [
        transforms.Resize(256, interpolation=transforms.InterpolationMode.BICUBIC),
        transforms.CenterCrop(224),
        transforms.Normalize(mean=(0.485, 0.456, 0.406), std=(0.229, 0.224, 0.225)),
    ]
)

normalizer = macenko_normalizer()
img_path = "images/MHIST_aaa.png"
image = Image.open(img_path).convert("RGB")
image_macenko = normalizer(image)

sample_input = transform(image_macenko).unsqueeze(0)
model.cuda()
model.eval()

features = model(sample_input.cuda())
We report linear evaluation result on six downstream tasks. Top-1 accuracy is shown, with values for models other than Gigapath taken from the RudolfV paper.
| Model | PCAM | MHIST | CRC-100K | TIL Det. | MSI CRC | MSI STAD | Avg |
|---|---|---|---|---|---|---|---|
| ResNet50 ImageNet | 0.833 | 0.806 | 0.849 | 0.915 | 0.653 | 0.664 | 0.787 |
| ViT-L/16 ImageNet | 0.852 | 0.796 | 0.847 | 0.924 | 0.669 | 0.671 | 0.793 |
| Lunit | 0.918 | 0.771 | 0.949 | 0.943 | 0.745 | 0.756 | 0.847 |
| CTransPath | 0.872 | 0.817 | 0.840 | 0.930 | 0.694 | 0.726 | 0.813 |
| Phikon | 0.906 | 0.795 | 0.883 | 0.946 | 0.733 | 0.751 | 0.836 |
| Virchow | 0.933 | 0.834 | 0.968 | - | - | - | - |
| RudolfV | 0.944 | 0.821 | 0.973 | 0.943 | 0.755 | 0.788 | 0.871 |
| GigaPath (patch encoder) | 0.947 | 0.822 | 0.964 | 0.938 | 0.753 | 0.748 | 0.862 |
| EXAONEPath (ours) | 0.901 | 0.818 | 0.946 | 0.939 | 0.756 | 0.804 | 0.861 |
The model is licensed under EXAONEPath AI Model License Agreement 1.0 - NC
If you find EXAONEPath useful, please cite it using this BibTeX:
@article{yun2024exaonepath,
  title={EXAONEPath 1.0 Patch-level Foundation Model for Pathology},
  author={Yun, Juseung and Hu, Yi and Kim, Jinhyung and Jang, Jongseong and Lee, Soonyoung},
  journal={arXiv preprint arXiv:2408.00380},
  year={2024}
}
LG AI Research Technical Support: [email protected]
1,113 followers · starred Sep 2024