Official implementation of "AReA: Adaptive Receptive-Field Attention for Efficient High-Resolution Diffusion Transformers"
See the code



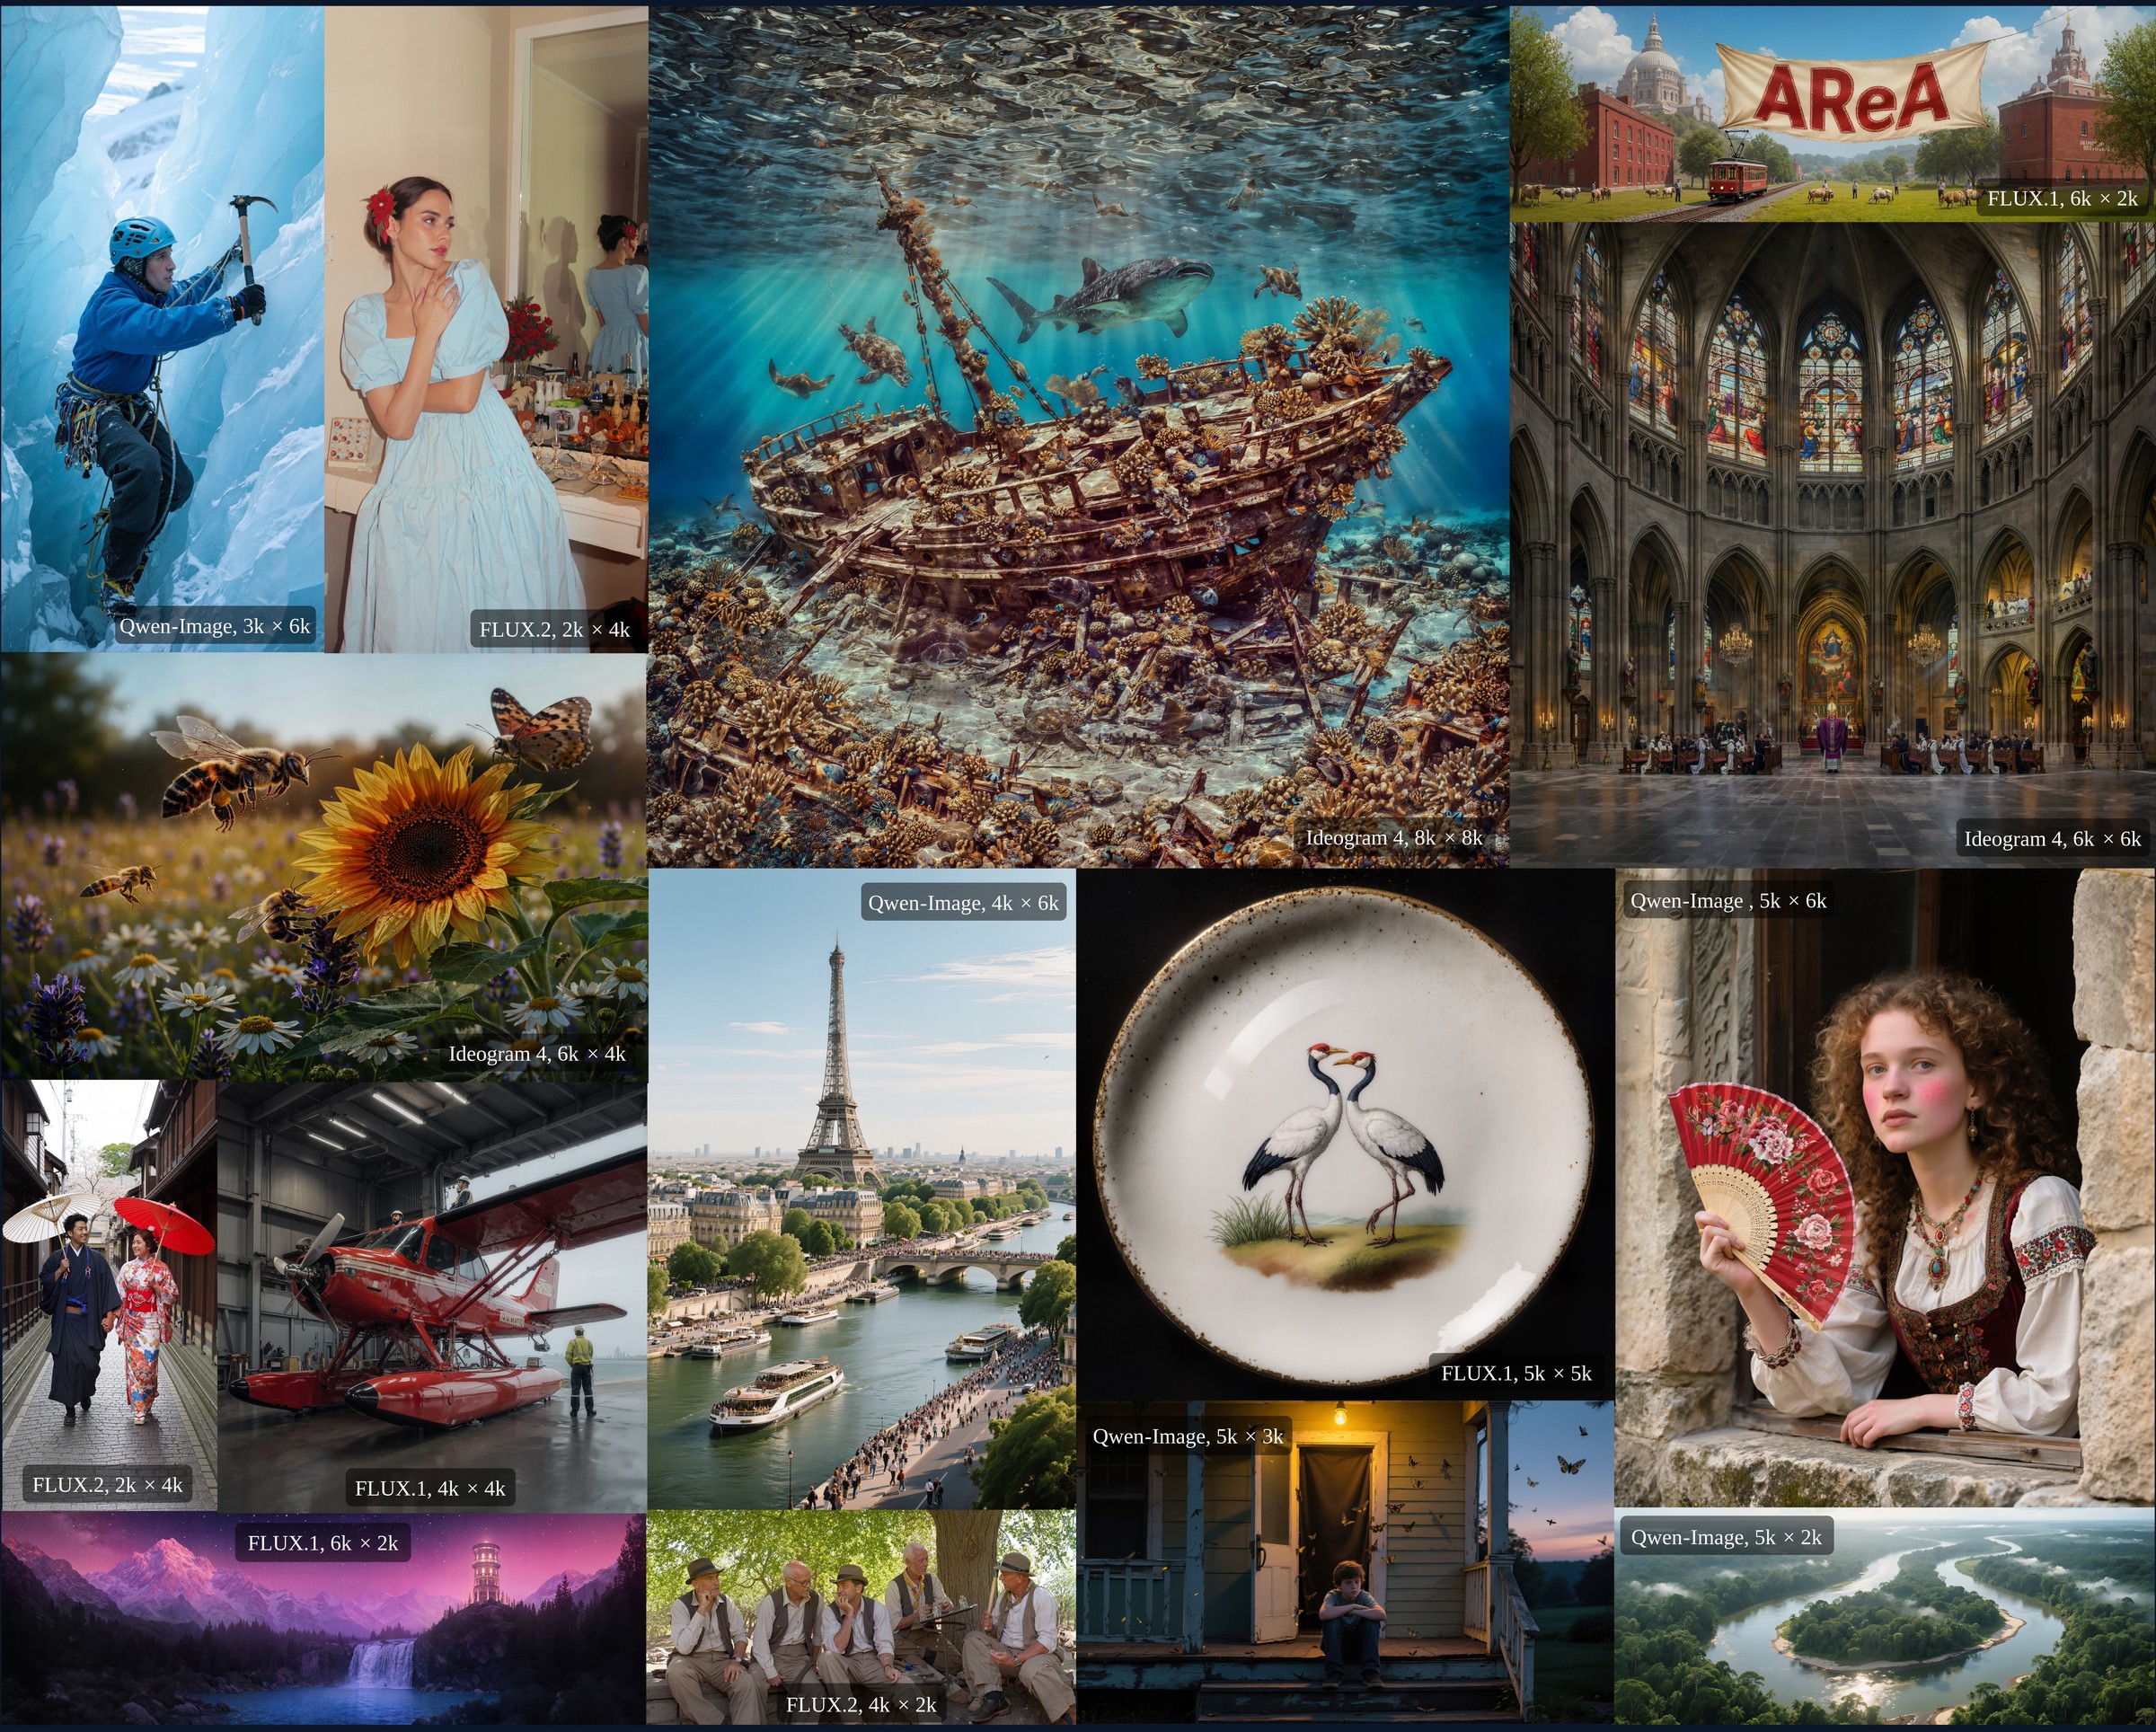
AReA is a training-free attention mechanism for generating images beyond the training resolution of diffusion transformers. Attention's effective receptive field narrows during denoising, from global in early steps that form structure to local in later steps that refine details. AReA follows this progression in two phases:
AReA never computes full attention at the target resolution and needs no RoPE extrapolation, extra parameters or fine-tuning. It is model agnostic, and its speedup over full attention grows with resolution, up to 3.2× in our experiments.
| Model | --model | Default checkpoint | Status |
|---|---|---|---|
| FLUX.1 | flux1 | black-forest-labs/FLUX.1-Krea-dev | Available |
| Qwen-Image | Coming soon | ||
| FLUX.2 | Coming soon | ||
| Ideogram 4 | Coming soon |
git clone https://github.com/KooroshRH/AReA.git
cd AReA

# Install PyTorch for your CUDA version first, then:
pip install -r requirements.txt
Model weights are downloaded from Hugging Face on first use. Some checkpoints are gated: accept their license on Hugging Face and log in with huggingface-cli login.
To try AReA without installing anything, use the Hugging Face demo (FLUX.1, 2K to 4K).
python generate.py --model flux1 \
  --prompt "A vibrant village with colorful houses and a picturesque castle is set against a backdrop of mountains and a clear blue sky" \
  --height 4096 --width 4096 --seed 0
The image is written to outputs/. --model selects the model (see Supported models), and each model runs with its own default checkpoint, number of steps and guidance scale. --checkpoint loads another checkpoint of the same model, given as a Hugging Face repo id or a local path:
python generate.py --model flux1 --checkpoint black-forest-labs/FLUX.1-dev \
  --prompt "..." --height 4096 --width 4096
On GPUs with less than 60 GB of memory, idle models are offloaded to the CPU automatically.
AReA attaches in place to a diffusers pipeline of a supported model: it replaces the transformer's attention processors and adds two hooks, and the pipeline is then called as usual. For example, with FLUX.1:
import torch
from diffusers import FluxPipeline
from area import AReA

pipe = FluxPipeline.from_pretrained("black-forest-labs/FLUX.1-Krea-dev", torch_dtype=torch.bfloat16)
pipe.vae.enable_tiling()
pipe.to("cuda")              # or pipe.enable_model_cpu_offload()

area = AReA(pipe)

image = pipe(
    "A vibrant village with colorful houses and a picturesque castle",
    height=4096,
    width=4096,
    num_inference_steps=28,
    guidance_scale=4.5,
    generator=torch.Generator("cuda").manual_seed(0),
).images[0]
image.save("village.png")

area.remove()                # back to the original attention
Canvases at or below the model's native resolution keep the original attention. Height and width must divide into whole patches, and the two patch counts must share a factor of at least 2, since Phase I pools f × f blocks.
AReA(...) argument | generate.py flag | Default | Description |
|---|---|---|---|
pooling | --pooling | subsample | Phase I: the token kept for each f × f block. subsample (block centre), mean, medoid or random. |
phase1_steps | --phase1-steps | per model | Number of Phase I steps; each model has its own default. |
halo | --halo | 8 | Largest Halo width δmax, in patches. |
bridge_ratio | --bridge-ratio | 0.5 | Global-KV bridge ratio ρ: each window of side w gets (ρw)² bridge tokens. |
seed | --seed | 0 | Seed for window boundary jitter, Halo widths and random pooling. generate.py uses the generation seed. |
Other generate.py flags: --model, --checkpoint, --height, --width, --steps, --guidance, --offload, --output-dir, and --prompt-file to generate a whole prompt list. Run python generate.py --help for details and defaults.
HRGen-1K/prompts.jsonl holds the 1,000 prompts of HRGen-1K, our benchmark for high-resolution generation. The prompts span natural scenes, built environments, people, animals, objects and imaginative worlds, and target failure modes that single-subject prompts rarely reveal: complex scenes with many interacting subjects, spatial relations, explicit object counts, reflections and transparency, and 125 text-rendering prompts. Prompt length ranges from 9 to 91 words (32.5 on average). Each line is a JSON object with an id and a prompt:
python generate.py --model flux1 --prompt-file HRGen-1K/prompts.jsonl --height 4096 --width 4096 --seed 0
AReA/
├── area/
│   ├── schedule.py      # Phase I pooling ramp and Phase II window sizes
│   ├── attention.py     # cross-scale coarse attention and windowed fine attention
│   ├── tiling.py        # base tiling, DWT detail map, splits, Halo, merge weights
│   ├── bridge.py        # global-KV bridge token selection
│   └── backbones/       # one adapter per model family
├── generate.py          # command-line generation
├── HRGen-1K/            # benchmark prompts
└── assets/
The method lives in the model-independent modules; a backbone adapter only describes how a model lays out its tokens and positions, so supporting a new model means adding one adapter.
AReA-Bootstrap is available for FLUX.1 only. It replaces Phase I with a generation at the native resolution, as multi-stage methods do: the native-resolution latent is upsampled to the target size, re-noised to the level at which Phase II begins, and denoised with Phase II.
python generate.py --model flux1 --prompt "..." --height 4096 --width 4096 --bootstrap
image = area.bootstrap("...", height=4096, width=4096, seed=0).images[0]
@misc{rajabi2026area,
      title={AReA: Adaptive Receptive-Field Attention for Efficient High-Resolution Diffusion Transformers},
      author={Javad Rajabi and Koorosh Roohi and David B. Lindell and Babak Taati},
      year={2026},
      eprint={2610.17227},
      archivePrefix={arXiv},
      primaryClass={cs.CV},
      url={https://arxiv.org/abs/2610.17227},
}
Official implementation of "AReA: Adaptive Receptive-Field Attention for Efficient High-Resolution Diffusion Transformers"
See the code
AReA is a training-free attention mechanism for generating images beyond the training resolution of diffusion transformers. Attention's effective receptive field narrows during denoising, from global in early steps that form structure to local in later steps that refine details. AReA follows this progression in two phases:
AReA never computes full attention at the target resolution and needs no RoPE extrapolation, extra parameters or fine-tuning. It is model agnostic, and its speedup over full attention grows with resolution, up to 3.2× in our experiments.
| Model | --model | Default checkpoint | Status |
|---|---|---|---|
| FLUX.1 | flux1 | black-forest-labs/FLUX.1-Krea-dev | Available |
| Qwen-Image | Coming soon | ||
| FLUX.2 | Coming soon | ||
| Ideogram 4 | Coming soon |
git clone https://github.com/KooroshRH/AReA.git
cd AReA

# Install PyTorch for your CUDA version first, then:
pip install -r requirements.txt
Model weights are downloaded from Hugging Face on first use. Some checkpoints are gated: accept their license on Hugging Face and log in with huggingface-cli login.
To try AReA without installing anything, use the Hugging Face demo (FLUX.1, 2K to 4K).
python generate.py --model flux1 \
  --prompt "A vibrant village with colorful houses and a picturesque castle is set against a backdrop of mountains and a clear blue sky" \
  --height 4096 --width 4096 --seed 0
The image is written to outputs/. --model selects the model (see Supported models), and each model runs with its own default checkpoint, number of steps and guidance scale. --checkpoint loads another checkpoint of the same model, given as a Hugging Face repo id or a local path:
python generate.py --model flux1 --checkpoint black-forest-labs/FLUX.1-dev \
  --prompt "..." --height 4096 --width 4096
On GPUs with less than 60 GB of memory, idle models are offloaded to the CPU automatically.
AReA attaches in place to a diffusers pipeline of a supported model: it replaces the transformer's attention processors and adds two hooks, and the pipeline is then called as usual. For example, with FLUX.1:
import torch
from diffusers import FluxPipeline
from area import AReA

pipe = FluxPipeline.from_pretrained("black-forest-labs/FLUX.1-Krea-dev", torch_dtype=torch.bfloat16)
pipe.vae.enable_tiling()
pipe.to("cuda")              # or pipe.enable_model_cpu_offload()

area = AReA(pipe)

image = pipe(
    "A vibrant village with colorful houses and a picturesque castle",
    height=4096,
    width=4096,
    num_inference_steps=28,
    guidance_scale=4.5,
    generator=torch.Generator("cuda").manual_seed(0),
).images[0]
image.save("village.png")

area.remove()                # back to the original attention
Canvases at or below the model's native resolution keep the original attention. Height and width must divide into whole patches, and the two patch counts must share a factor of at least 2, since Phase I pools f × f blocks.
AReA(...) argument | generate.py flag | Default | Description |
|---|---|---|---|
pooling | --pooling | subsample | Phase I: the token kept for each f × f block. subsample (block centre), mean, medoid or random. |
phase1_steps | --phase1-steps | per model | Number of Phase I steps; each model has its own default. |
halo | --halo | 8 | Largest Halo width δmax, in patches. |
bridge_ratio | --bridge-ratio | 0.5 | Global-KV bridge ratio ρ: each window of side w gets (ρw)² bridge tokens. |
seed | --seed | 0 | Seed for window boundary jitter, Halo widths and random pooling. generate.py uses the generation seed. |
Other generate.py flags: --model, --checkpoint, --height, --width, --steps, --guidance, --offload, --output-dir, and --prompt-file to generate a whole prompt list. Run python generate.py --help for details and defaults.
HRGen-1K/prompts.jsonl holds the 1,000 prompts of HRGen-1K, our benchmark for high-resolution generation. The prompts span natural scenes, built environments, people, animals, objects and imaginative worlds, and target failure modes that single-subject prompts rarely reveal: complex scenes with many interacting subjects, spatial relations, explicit object counts, reflections and transparency, and 125 text-rendering prompts. Prompt length ranges from 9 to 91 words (32.5 on average). Each line is a JSON object with an id and a prompt:
python generate.py --model flux1 --prompt-file HRGen-1K/prompts.jsonl --height 4096 --width 4096 --seed 0
AReA/
├── area/
│   ├── schedule.py      # Phase I pooling ramp and Phase II window sizes
│   ├── attention.py     # cross-scale coarse attention and windowed fine attention
│   ├── tiling.py        # base tiling, DWT detail map, splits, Halo, merge weights
│   ├── bridge.py        # global-KV bridge token selection
│   └── backbones/       # one adapter per model family
├── generate.py          # command-line generation
├── HRGen-1K/            # benchmark prompts
└── assets/
The method lives in the model-independent modules; a backbone adapter only describes how a model lays out its tokens and positions, so supporting a new model means adding one adapter.
AReA-Bootstrap is available for FLUX.1 only. It replaces Phase I with a generation at the native resolution, as multi-stage methods do: the native-resolution latent is upsampled to the target size, re-noised to the level at which Phase II begins, and denoised with Phase II.
python generate.py --model flux1 --prompt "..." --height 4096 --width 4096 --bootstrap
image = area.bootstrap("...", height=4096, width=4096, seed=0).images[0]
@misc{rajabi2026area,
      title={AReA: Adaptive Receptive-Field Attention for Efficient High-Resolution Diffusion Transformers},
      author={Javad Rajabi and Koorosh Roohi and David B. Lindell and Babak Taati},
      year={2026},
      eprint={2610.17227},
      archivePrefix={arXiv},
      primaryClass={cs.CV},
      url={https://arxiv.org/abs/2610.17227},
}





